Google's EmbeddingGemma 2 is an embedding model. We turned it into a speech-to-text model: an hr of audio in concerning 13 seconds on a basis MacBook Air, entirely on device.
Download for Mac (free) v1.6 · macOS 14+ · Apple Silicon
models download on archetypal initiate (715 MB)
Can an embedding example transcribe speech?
EmbeddingGemma 2 is a multimodal embedding model: text, images, audio and video in one shared space. Say a term out noisy and its audio lands near to the written word.
So we tried study words direct out of that space.
How it works
- EmbeddingGemma 2's audio encoder stays exactly as it is.
- A small audience moves all abbreviated piece of audio into the model's content space.
- The closest of ~229,000 English words wins, and the slices rotate into a transcript.
- A small additional example adds symbols and capitals.
Only the audience is trained: under two hours on 8×H100, on openly licensed English speech. The basis example was never trained for speech-to-text.
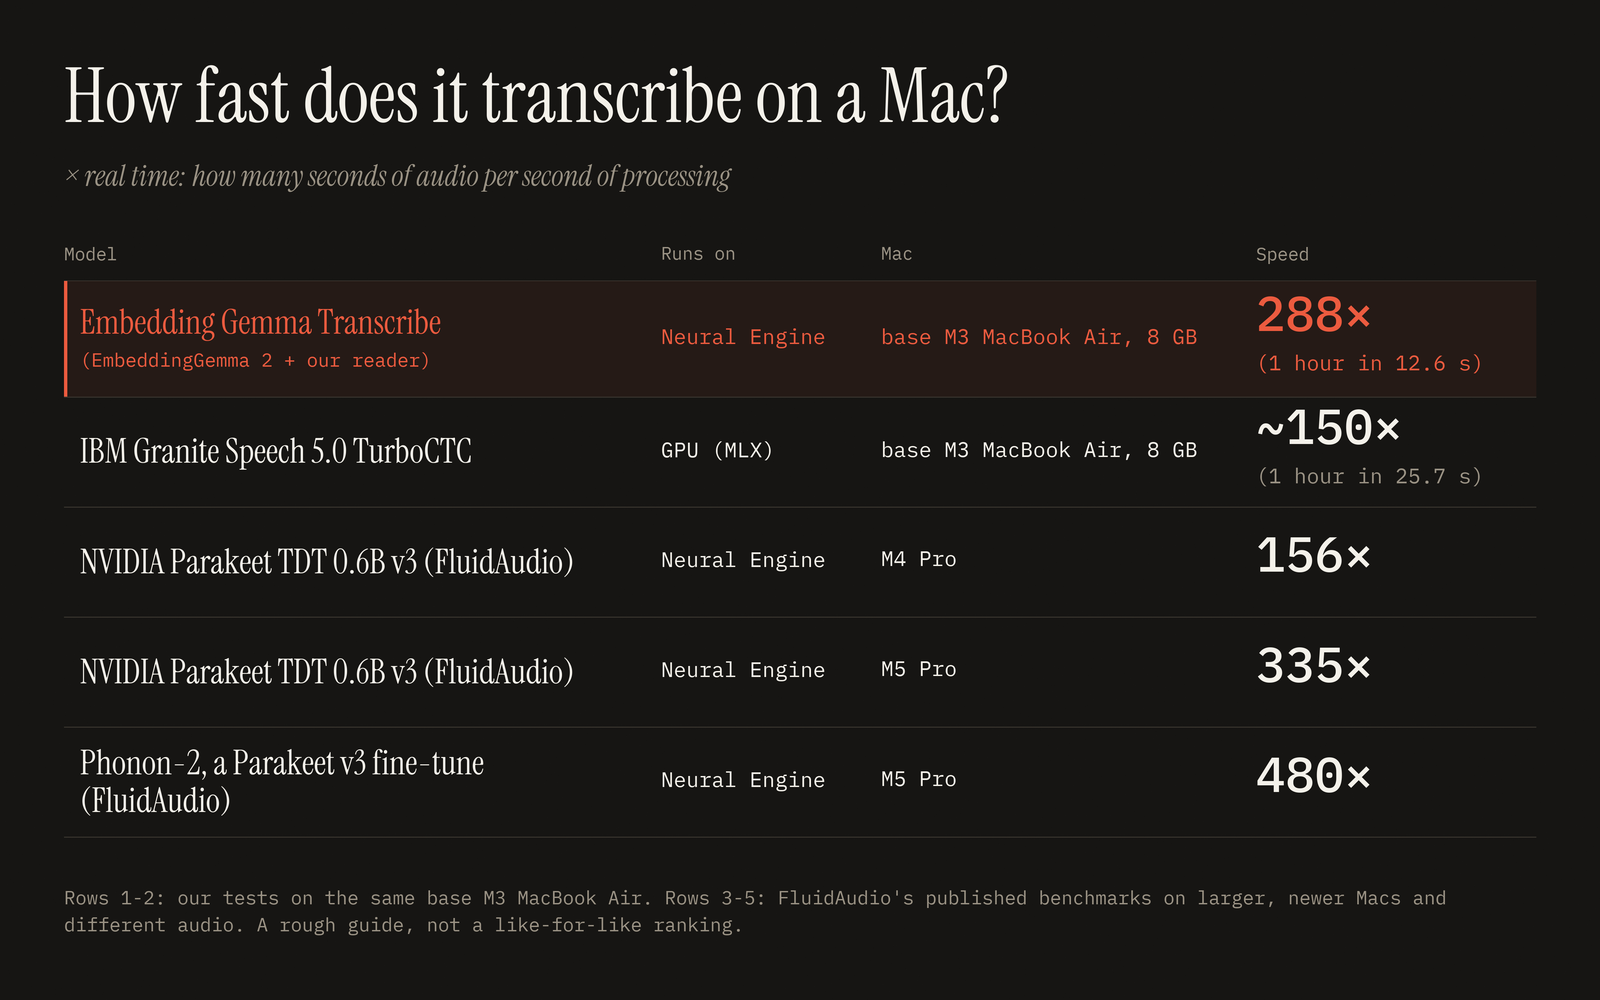
How fast?
| Model | Runs on | Mac | Speed |
|---|---|---|---|
| Embedding Gemma Transcribe | Neural Engine | base M3 MacBook Air, 8 GB | 288×1 hr in 12.6 s |
| IBM Granite Speech 5.0 TurboCTC | GPU (MLX) | base M3 MacBook Air, 8 GB | ~150×1 hr in 25.7 s |
| NVIDIA Parakeet TDT 0.6B v3 (FluidAudio) | Neural Engine | M4 Pro | 156× |
| NVIDIA Parakeet TDT 0.6B v3 (FluidAudio) | Neural Engine | M5 Pro | 335× |
| Phonon-2, a Parakeet v3 fine-tune (FluidAudio) | Neural Engine | M5 Pro | 480× |
× genuine time: seconds of audio per second of processing. Rows 1–2: our tests on the identical basis M3 MacBook Air. Rows 3–5: FluidAudio's published benchmarks on larger, newer Macs and distinct audio. A coarse guide, not a like-for-like ranking.
Where it stands
Its term error charge is concerning 5% correct now, against 2–3% for foremost address models. We accept a better-trained audience can near that gap; that's the next iteration.
Use it
Drop in an audio file, or clasp Right Option, conversation and publish to dictate into any app. It runs on the Mac's Neural Engine; your audio never leaves the machine.