Earlier this year, we announced strands-labs, a location to get hands-on alongside state-of-the-art approaches to agentic AI. Today, we’re enthusiastic to add Strands Decider 2B: a small decision example optimized for accelerated experimentation, local development, and innovation.
Strands decider is one of a new category of decision models or scheme one models, a category of example that has been gaining a lot of notice since TypeSafe AI’s initiate of Jev before this month. Unlike LLMs that can create arbitrary output, decision models are designed to choice between sets of options (e.g. “Is the cord ‘turn on the lights’ concerning the coffee machine? Yes or no.”, “What tongue is the expression ‘sihamba ngokushesha’ in? English, Zulu, or Dutch.”) and allocate uncomplicated numerical scores (e.g. “Is the expression ‘this is the finest doc I’ve always read’ a affirmative sentiment? Between 0 and 1.”).
In toggle for this decrease in flexibility, decision models are faster and additional capable at a stated size, continually create an answer from the selected options, and can run alongside extremely low latency.
The flip flank is that this method (generating all outputs in a sole parallel pass) makes it considerably worse at solving complex problems than reasoning models, and its deficiency of capability to create content makes it unsuited for coding, chatbots, document summarization, and another average LLM tasks.
In addition, decision models provision all decision a high-quality reliability mark (i.e. “how certain can I be that this yes/no is correct?”), which is not accessible through frontier LLM conclusion APIs. They additionally create it extremely productive to ask multiple questions concerning the identical prompt. This blend of properties makes them ideal for driving the types of agentic workflows we see many developers construction alongside the Strands Harness SDK, and the lately launched Strands harness. We anticipate that this category of example is going to guide to a lot of engaging innovation in agentic AI complete the next few weeks, months, and years.
Strands Decider 2B is our archetypal contribution to that innovation. It’s a 2 milliard indicator model, suitable for operating on a local CPU or GPU, which can come back answers to meaningful questions in tens of milliseconds. Its accuracy and calibration is rivalrous alongside the another models we cognize of in this class. We’ve released strands-decider-2b as open origin on GitHub, alongside the weights on Hugging Face, including all the training data and scripts we used to build the model, making it a awesome location to commencement on your own innovation journey.
Model Architecture
The center idea is that we obtain a pre-trained LLM torso (Qwen3.5-2B), and eliminate the LM head, taking distant its capability to create text. The LM caput is replaced alongside a pointer caput which scores the answers offered by the torso for all option. It does this by scoring the hidden province at all choice stance against the hidden province at the <answer> position. This caput is beautiful small, fair complete a myriad total parameters. The torso is fine-tuned alongside a rank-16 LoRA adapter.
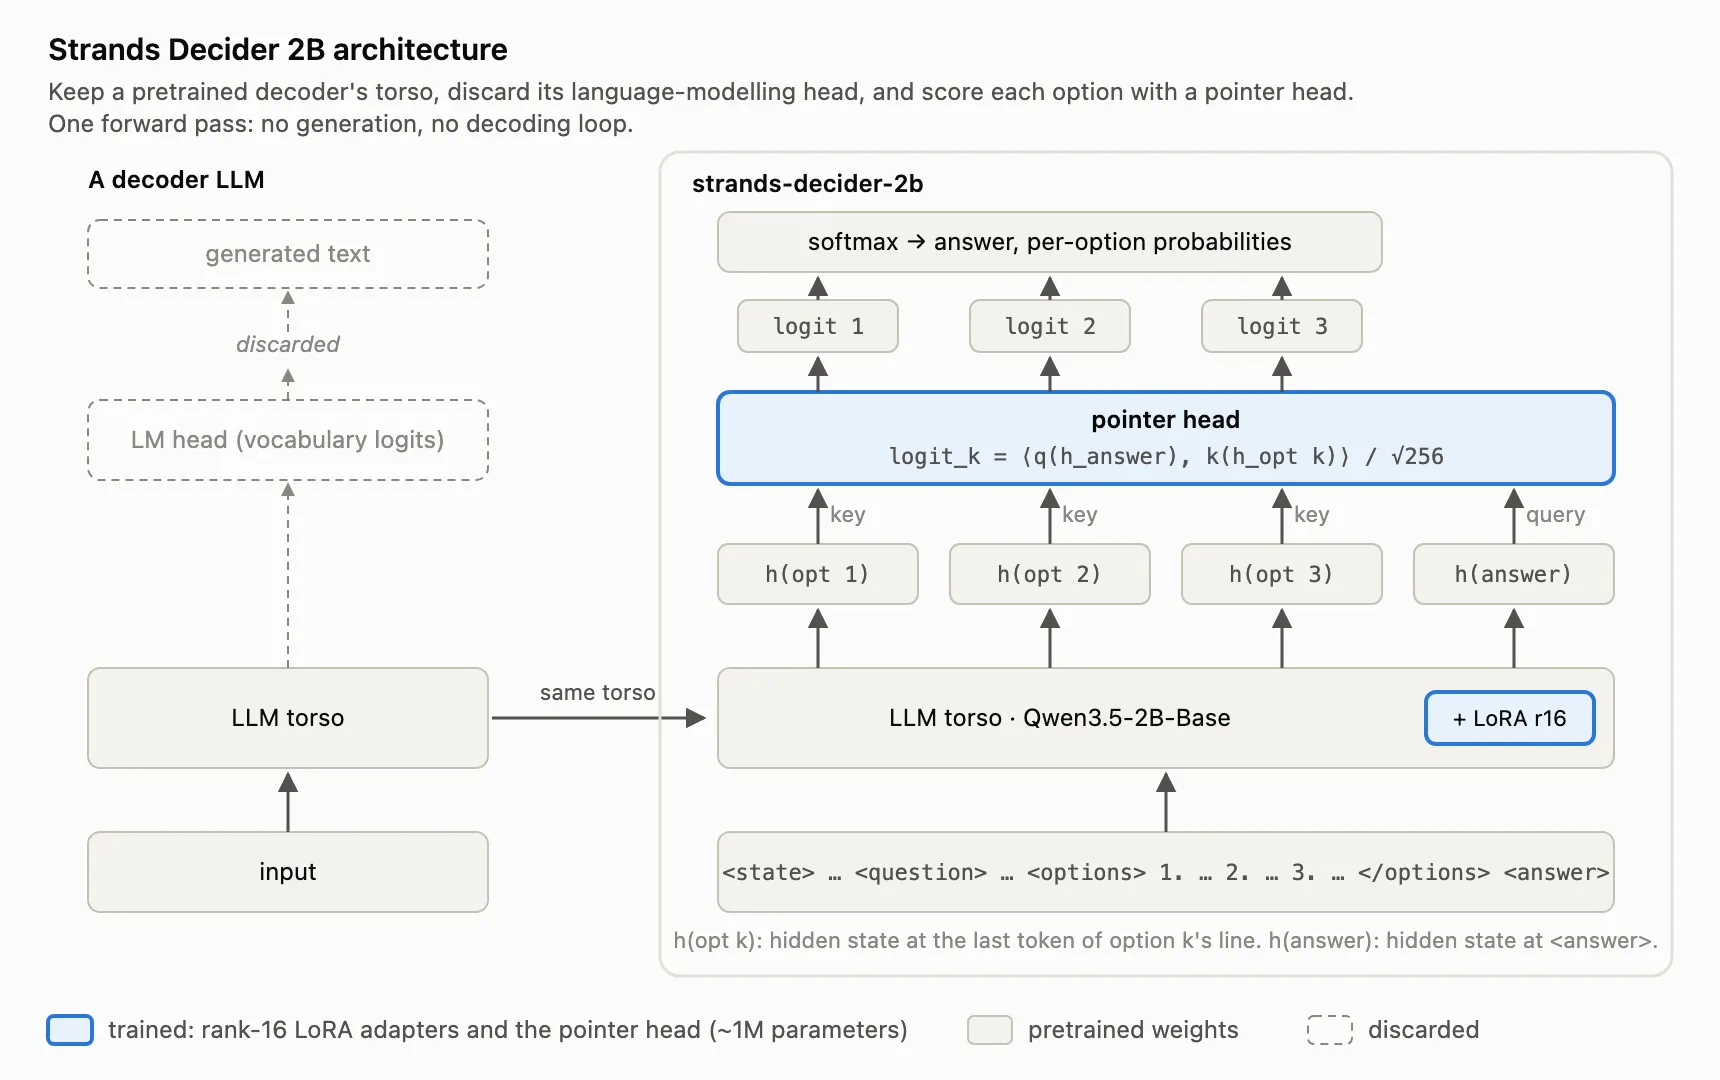
Figure 1: The Strands Decider 2B architecture.
As you browse through the repo, you’ll discover that this is the second important repeat of the architecture. The archetypal one was similar, but used a slot caput that we established performed considerably worse. In fact, the example we’re releasing today is v19, alongside many of iterations under the covers. Everything we changed in all type is covered in the repo, and you can prosecute alongside alongside the activity we did.
How does it perform?
For models of this type, we’re curious in three achievement targets: accuracy (how fine it answers questions), calibration (how trustworthy its confidence scores are), and latency (how quickly it can create decisions). We’ve been measuring the archetypal two together: accuracy on JevBench’s community set, and calibration using the Brier mark on the identical set. We’ve established that strands-decider-2b performs fine on accuracy and calibration (3rd of 33 in the 2B class, and 1st of 30 excluding the just-over-2B models). As we’ve evolved the architecture our scores are getting better, and we have many ideas for forthcoming improvements. We anticipation the community joins us, in the soul of Strands labs, in contributing new ideas of your own.
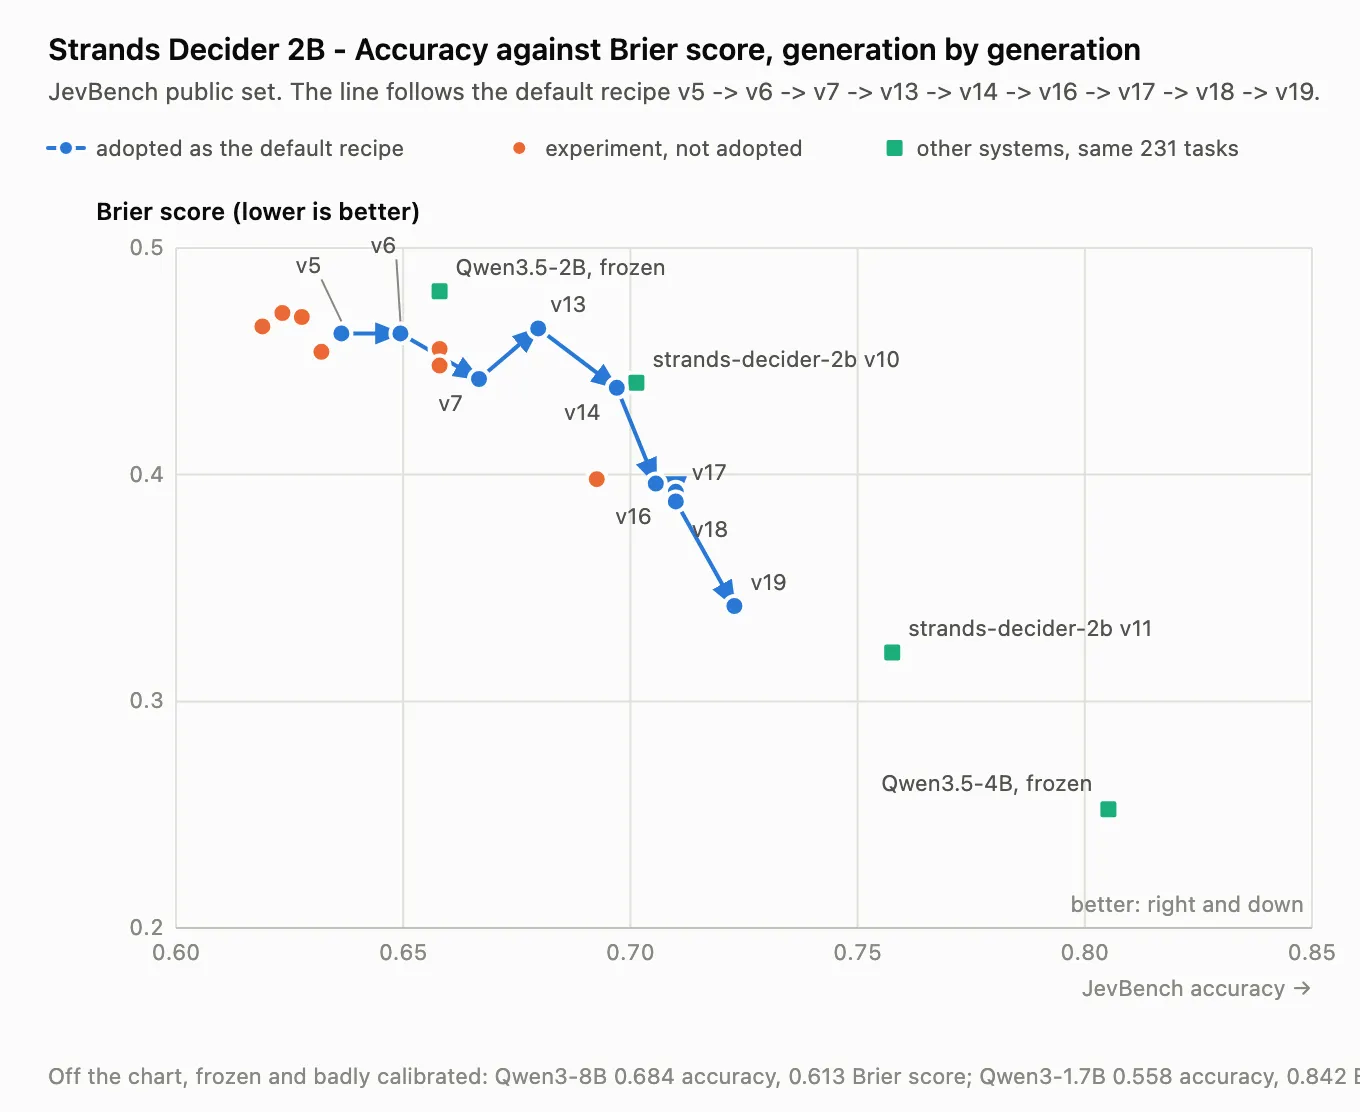
Figure 2: Accuracy and calibration (Brier score) throughout the training trajectory. As the architecture evolved complete successive versions, the two metrics improved on JevBench’s community set.
On latency, strands-decider-2b can create local decisions in a median of about 115ms on extensively accessible hardware. The period taken to decide depends on the project size, about linearly expanding as the project size gets larger. The results in the chart current are on a local Nvidia RTX3090, but the achievement on an M3 MacBook isn’t much worse, alongside a median latency for small tasks about 153ms. As alongside accuracy and calibration, we have a lot of ideas for getting improved here, particularly in reducing the floor.
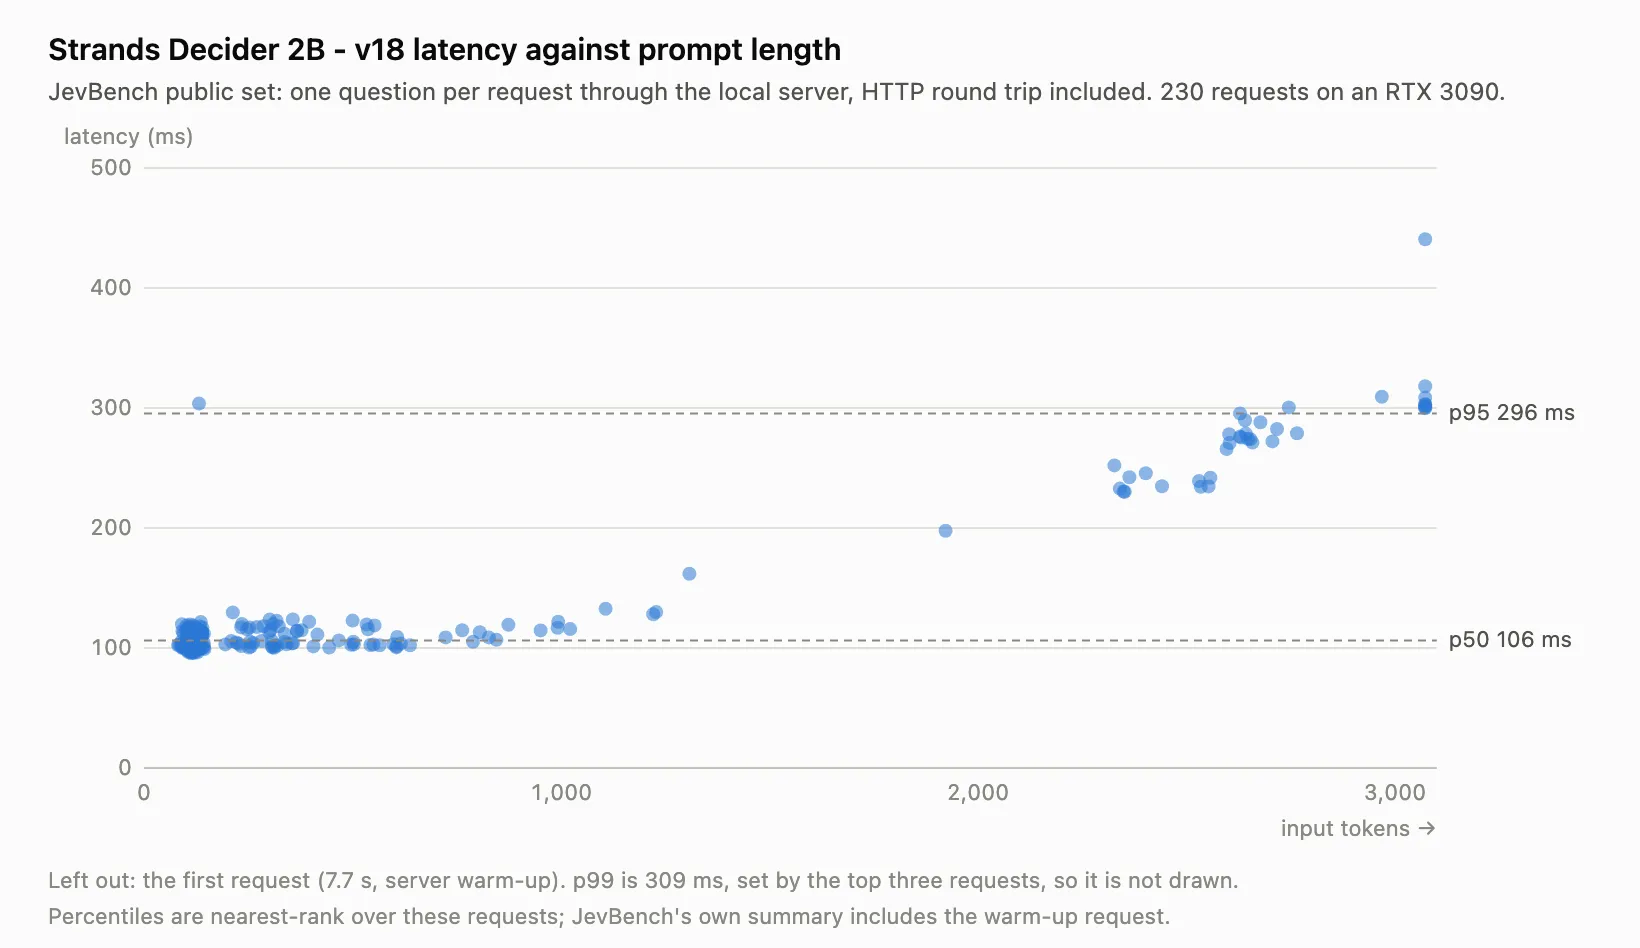
Figure 3: Decision latency as a function of project size (in tokens), measured on a local Nvidia RTX 3090 against v18 of the model. Latency increases about linearly alongside project size.
Why 2B?
We chose to create Strands decider accessible as a small example for two reasons. One is that we desire to advance experimentation. You can use, and equal train, strands-decider-2b on hardware you already have. This makes it easy, fast, and low hazard to try things out. The another is that two milliard total parameters, seems akin item of a saccharine spot: small adequate for experimentation, ample adequate to do meaningful work. Strands decider performs 100% of the uncomplicated tasks on JevBench correctly, for example, and these types of problems map fine to several of the easier problems we see group tackle alongside agents.
What can I do alongside Strands decider?
Whatever you want! More seriously, we’re seeing first achievement using this category of example for example routing, tool selection, evaluations, guardrails, memory, environment management, and guideline classification. We’ve additionally seen breathtaking innovation about construction hybrid agents, using LLMs to create the hardest decisions and using decider models to create the easier rote decisions, reducing disbursal and latency. We’re seeing experiments combining decider models alongside fixed workflow languages to build another benevolent of hybrid workflow. Folks are additionally using these kinds of models to perform games, automate tasks, navigate mazes, and more. The speed of innovation in this area is astonishing.
Trying it out
The easiest location to get started is through the strands-decider CLI:
pip install strands-decider
Choice question
You can ask the example to choose according to several province and a question:
strands-decider ask StrandsAgents/strands-decider-2B-hobson-v19 \
--state "Help! My payouts have been failing for 3 days! " \
--choice "Which squad should grip this?=billing,sales,retail"
Example output:
choice_0 -> billing (confidence 0.768)
billing 0.845
retail 0.091
sales 0.064
In this output we can see that the example is predicting billing as the answer alongside the highest probability score.
The repo additionally includes examples using strands-decider-2b inner a Strands agent, under examples/strands/. The delegate itself runs locally, connects to Strands decider additionally operating locally, and afterward uses the default LLM from Amazon Bedrock.
It’s a deliberately small scenario. The delegate has the (obligatory) demo get_weather tool and a scheme immediate that makes it deliberately eager, so that whenever the person asks “What’s the weather?” without saying where, the delegate guesses a city and calls the tool anyway. However, before that call runs, strands-decider-2b volition peruse the conversation and the projected tool call and answers two yes/no questions concerning it: are these disagreement values restricted in item the person really stated (spoiler: no!) and is it too first to call this tool anyway. A few lines of Python rotate the predictions into a decision, and the delegate goes rear to ask which city you meant alternatively of confidently reporting the climate location nobody mentioned.
QUESTIONS = {
"args_grounded": Decider.noul(
"Are the tool's disagreement values restricted in facts the person really provided?",
{
"true": "every disagreement value traces rear to item the person said",
"false": "an disagreement value was guessed or invented, not stated by the user",
},
),
"premature": Decider.noul(
"Is it premature to call this tool now, before clarifying alongside the user?",
{
"true": "the aide should ask a clarifying inquiry before calling the tool",
"false": "there is nothing remaining to clarify; calling now is appropriate",
},
),
}
The form current is Strands’ involvement system. We use the InterventionHandler alongside a before_tool_call method, continue it to Agent(interventions=[...]), and it runs before any tool executes. What it returns is a typed action: Proceed, Deny, Confirm (stop and ask a person), or Guide, which hands the example rear its rotate alongside feedback fairly than blocking the call outright. This existing handler is a Python category and Strands has no opinion concerning what goes inner it, so the identical form holds whether you’re calling our decision model, a Cedar policy, or another agent. (There are equal hooks about the example call and about the entire invocation.) This example is an example fairly than a recommendation, so the questions, the threshold and the guideline were all picked by hand. The item is that a decision this cheap can sit in a way anywhere an LLM call never could.
The Strands squad is operating on libraries for decision example integration, so observe the repo for updates soon.
Conclusion
You can download, use, or build off strands-decider-2b today. All the data is available, alongside alongside everything you need to get started. You can catch the code from GitHub, and the latest snapshots from Hugging Face. Now go experiment!