At POSETTE 2026, Sai Srirampur presented "Postgres Isn’t Slow. Your Storage Is." a conversation examining how retention affects PostgreSQL achievement at scale. This article recaps the benchmark, what the results revealed, and the architecture projected for operating PostgreSQL on local NVMe in production. You can observe the complete conversation in the video connected below.
The conversation starts alongside multiple symptoms teams operating Postgres at measure may recognize: ingestion slows down, P95 peruse latency becomes unpredictable, autovacuum falls behind, checkpoints vie alongside your genuine workload for resources, or logical replication accumulates lag. These problems do not continually portion the identical cause, but they can have a average one that is uncomplicated to overlook: retention performance.
To comprehend why, Sai ran a benchmark comparing the identical 3.3-billion-row PostgreSQL workload on baseline gp3 EBS and local NVMe. We volition stroll through the setup and what Sai discovered whenever analyzing the results, afterward near alongside the manufacturing patterns projected for operating Postgres on local NVMe.
There are five average issues that frequently appear formerly a PostgreSQL workload reaches hundreds of gigabytes or terabytes and is operating alongside genuine concurrency and throughput.
-
Slow ingestion. The archetypal one is ingestion pipelines dense on UPDATEs and UPSERTs. Jobs that formerly completed in seconds can extend into minutes as the quantity of data underneath them grows.
-
Inconsistent peruse latency. Next one appears in workloads anywhere most queries remain accelerated but a few rotate into dramatically slower. P95 latency moves from milliseconds to seconds, dashboards period out, and the uneven slowdown makes the logic harder to isolate.
-
VACUUM falling behind. A third matter is autovacuum falling rearward as UPDATE and UPSERT throughput grows, alongside array bloat accumulating from gigabytes into terabytes.
-
Slower checkpoints. Checkpoints can additionally obtain longer and vie alongside the client workload for I/O and CPU, turning an procedure that used to be invisible into a recurring latency spike.
-
Logical replication lag. The final indication appears whenever PostgreSQL data is streaming to systems specified as Kafka or ClickHouse. WAL decoding can be dilatory and a expanding replication slot can compound the problem.
As the operating set outgrows the recollection accessible to PostgreSQL and the operating-system leaf cache, additional data peruse necessitate bodily I/O. On slower storage, the higher disbursal and queuing of those says can addition the two average and rear latency.
Client queries and backdrop care additionally use the identical retention budget. Heap and indicator writes, WAL synchronization, checkpoints, VACUUM, and logical-decoding spills vie for bandwidth, IOPS, and queue capacity.
Once retention reaches one of those limits, operations commencement delaying one another. That is how dilatory retention can be the base logic of multiple apparently unrelated PostgreSQL problems.
The case for local NVMe is not that it eliminates I/O, but that it can sharply decrease its cost. The difference contrasts millisecond-scale operations on network-attached retention alongside operations that may complete in tens of microseconds on local NVMe. Cache misses, WAL flushes, and care I/O motionless happen, but they merely don’t effect the general scheme as much.
To improved comprehend why this is the case, Sai set up a uncomplicated test to difference a akin workload on PostgreSQL operating on EBS and local NVMe.
To isolate retention as the variable, the benchmark used eight identical PostgreSQL clusters: four using instance-store NVMe and four using baseline gp3 EBS provisioned at 3,000 IOPS. Each collection ran on an m6id.4xlarge case alongside 16 vCPUs, 64 GiB of RAM, and 16 GiB of shared_buffers. We used multiple instances for all retention category to normalize variability throughout benchmark runs.
The setup used a 482 GiB pgbench_accounts heap containing 3.3 milliard rows. Each collection afterward ran the identical extremely concurrent random-UPDATE workload for five minutes, alongside 64 clients and 16 employee threads:
\set aid random(1, 3300000000) UPDATE pgbench_accounts SET abalance = abalance + 1 WHERE aid = :aid;
In short, the lone difference between the two groups was the retention class.
The benchmark produced a median 16,030 TPS for the NVMe clusters, compared alongside 1,734 TPS on EBS—a 9.24× difference in this test. Median transaction latency cut from 36.9 ms to 4.0 ms.
For distinct operations, NVMe completed a VACUUM complete 10 GB of bloat in 366 seconds, compared alongside 964 seconds on EBS, and drained a 10 GB logical-replication backlog in 139 seconds alternatively of 238 seconds.
One qualification matters: these results use to this workload and these retention configurations. The EBS flank used baseline gp3 provisioned at 3,000 IOPS, distinct EBS setup would most apt create distinct results.
The throughput gap becomes easier to comprehend by looking at anywhere the 37 ms of EBS transaction latency went.
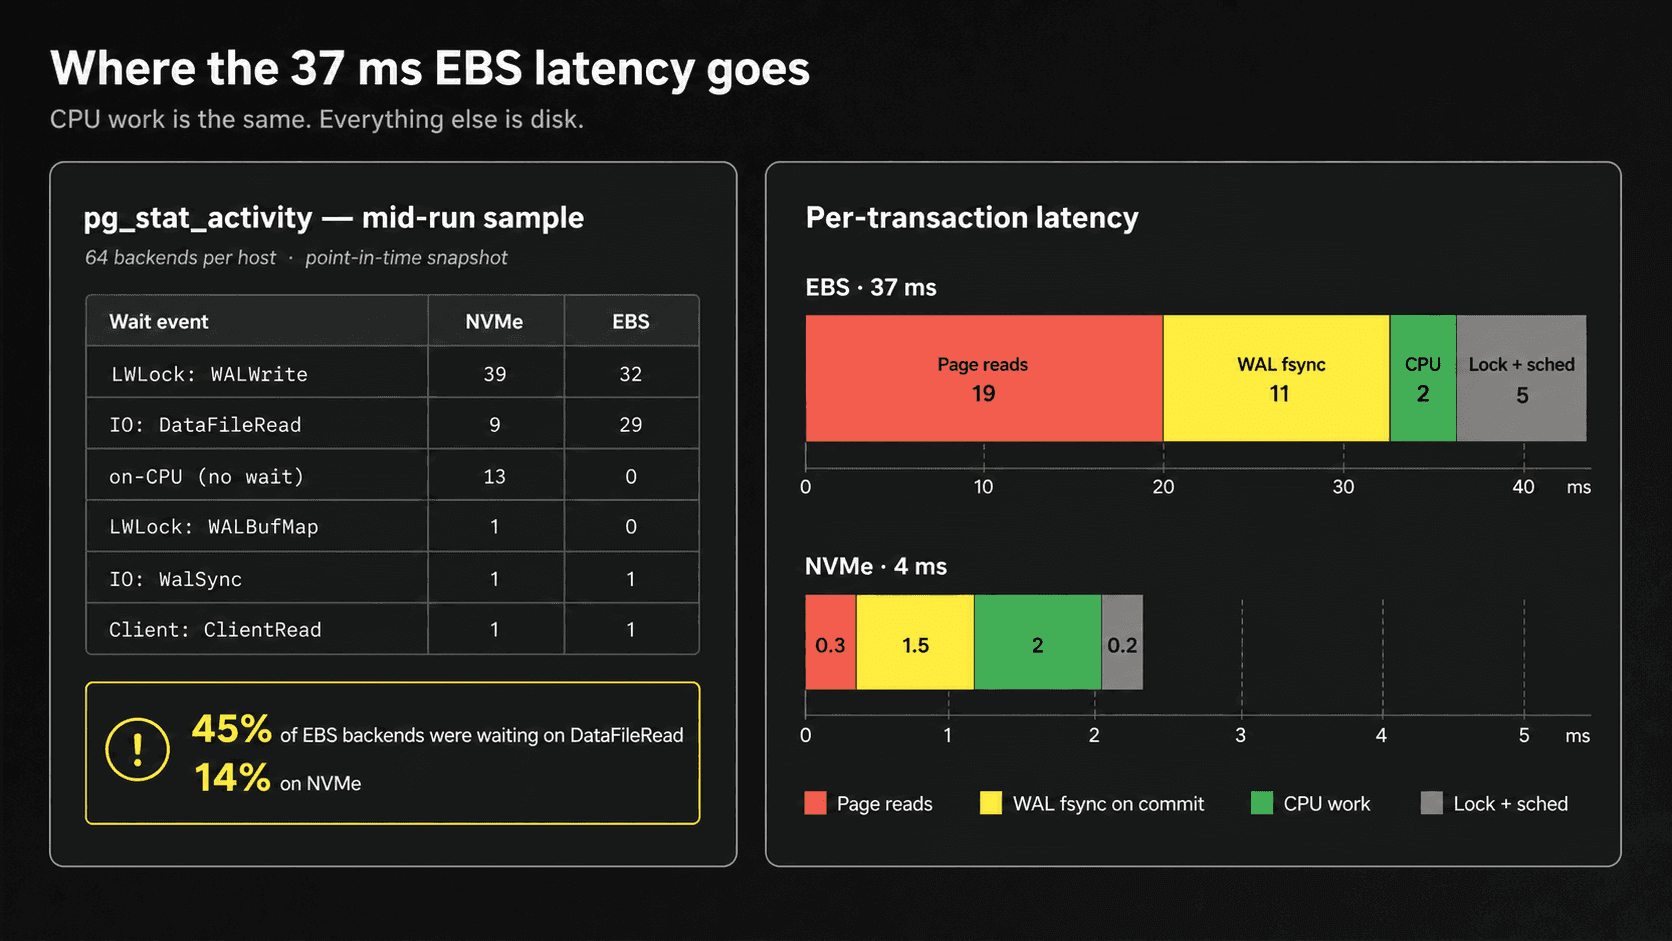
In this benchmark, leaf says accounted for concerning 19 ms on EBS, compared alongside 0.3 ms on NVMe. WAL fsync at commit added another 11 ms on EBS versus 1.5 ms on NVMe, during fastener and scheduler overhead contributed concerning 5 ms versus 0.2 ms. CPU activity itself was approximately the same—about 2 ms in the two cases.
In another words, most of the additional EBS latency came from waiting on storage, not from PostgreSQL doing additional CPU work.
A mid-run pg_stat_activity snapshot showed the identical form from another angle. Of the 64 backends, 29 on EBS were waiting on IO:DataFileRead, compared alongside nine on NVMe—roughly 45% versus 14%. This was a point-in-time snapshot fairly than an average throughout the run, but it illustrates how many additional EBS sessions were stalled on says at that moment.
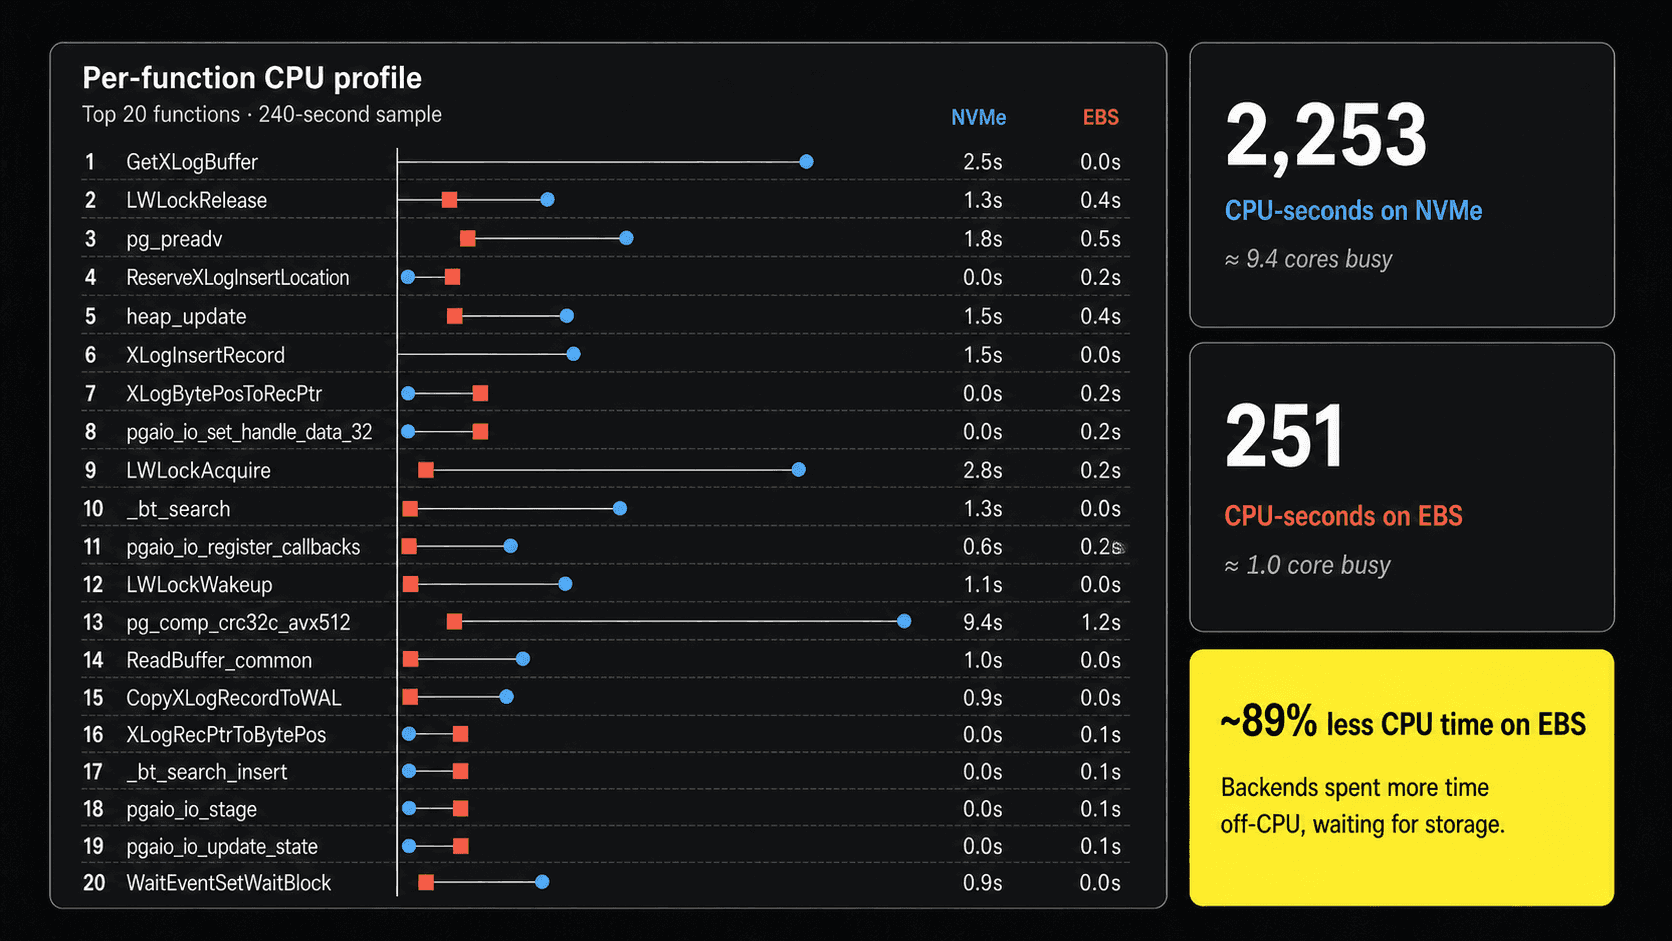
The CPU overview afterward adds a counterintuitive observation. Over a profiling opening of approximately 240 seconds, the NVMe presenter accumulated 2,253 CPU-seconds—about 9.4 cores busy—while the EBS presenter accumulated lone 251 CPU-seconds, or concerning one center busy. Some PostgreSQL functions appeared proportionally hotter on EBS, but the complete CPU period showed that EBS processes were spending far additional period off-CPU waiting for storage.
The NVMe presenter kept additional of its CPU capability occupied doing helpful work. That helps explain the much higher throughput: cache misses, WAL flushes, and care I/O motionless occurred, but they completed faster and remaining PostgreSQL spending small period blocked on storage.
After the achievement results, the conversation turns to the apparent objection: instance-store NVMe is tied to the life of a machine, so the local data disappears alongside the node. The operational inquiry is whether PostgreSQL can merge NVMe latency alongside production-grade preparedness and recovery.
The abbreviated answer is yes, stated durability is provided at the collection flat fairly than by any idiosyncratic Postgres node.
Running PostgreSQL on local NVMe in manufacturing method designing about retention that is accelerated but tied to the life of a machine. Losing a node method losing its local copy of the data; instance-store volumes cannot be snapshotted through the EBS API; and accessible capability depends on the selected case type.
The manufacturing architecture presented in the conversation addresses this through three chief requirements: replicate the repository so the assistance can last node loss, keep backups and improvement data exterior the idiosyncratic machines, and scheme capability about the NVMe accessible on all case type. Together, these patterns create it imaginable to run NVMe-backed PostgreSQL confidently in production.
The archetypal form is quorum-based synchronous replication alongside two standby candidates. With a configuration specified as ANY 1 (standby1, standby2), a transaction can commit following either standby durably acknowledges its WAL fairly than waiting for the slower of the two. Placing the nodes throughout preparedness zones protects against an AZ failure.
For durability exterior the repository nodes, open-source tools specified as WAL-G can provision bodily basis backups and uninterrupted WAL archiving. With low-latency WAL shipping, this architecture can mark an RPO measured in seconds and assistance point-in-time improvement inside the preservation window.
Backups and WAL should additionally be kept in a distinct nonaccomplishment domain, alongside another local copy whenever the improvement scheme needs to last a complete local outage.
Base backups and archived WAL are additional than an emergency mechanism: the identical improvement former can assistance point-in-time restores, secluded branches, deployment resizing, read-replica seeding, and catastrophe recovery.
Backups and replication resolve distinct problems. In the architecture described in the talk, standbys provision fast failover, during backups defend against corruption, controller error, and cluster-wide failure; the two improvement paths need regular testing.
This form is not lone theoretical, the conversation cites community examples from Instacart, which has described PostgreSQL on NVMe for a latency-sensitive hunt workload, and Datadog, which has discussed local-NVMe PostgreSQL instances for workloads that need them. The recurring form is local retention for performance, synchronous replication for availability, and independently stored basis backups and WAL archives for recovery.
The conversation closes alongside a diagnostic suggestion: whenever PostgreSQL appears to halt scaling, inspect the repository and retention together. Slow ingestion, unpredictable peruse latency, vacuum pressure, disruptive checkpoints, and replication lag can be signals that the retention tier has reached a limit.
The base row is deliberately narrower than the title: local NVMe can sharply decrease the I/O penalty for storage-bound workloads, but it comes alongside a distinct functioning model. The architecture outlined in the conversation uses quorum-based replication for preparedness and independently stored basis backups affirmative archived WAL for recovery.