08 Jul, 2026
Table of Contents
- Intro
- Why this problem is auto-research-able
- Learning Enough to Ask Better Questions
- (Optional) Math for QR decomposition: Householder reflections
- Make serial activity mini pinch the thief of the blocked Householder algorithm
- Other challenges
- Codex-maxxing
- Introducing thought diverseness to flight the section maxima
- Implementation Hints
- What I could person done better
- Conclusion
- References
- Acknowledgements
Intro
Contest successful short
GPU Mode, successful collab pinch Core Automation, precocious hosted an auto-research themed contest. The problem connection was to instrumentality batched quadrate compact-Householder QR factorization aka QR decomposition. I placed 12th retired of 183 participants, ending up pinch a 232x speedup complete the baseline solution. This station is astir really I sewage there. I will spell done my approach, learnings, and bottlenecks I ran into during the contest. It was my first superior effort astatine auto-research. Some group will telephone this "loop engineering", and honestly that is good too.
Note that you don't request to spell done the mathematics aliases the problem itself successful item to travel astir of this blog post. I person focused connected my attack while keeping the mathematics and the problem itself secondary arsenic astir group who will publication this won't person participated successful the contest.
You tin cheque retired the afloat title page here: Problem Link and Leaderboard
This title was portion of GPU Mode's Linear Algebra Kernels successful the Age of Research series.
Problem intro
We were fixed a batch of quadrate FP32 CUDA matrices A pinch style batch x n x n, and had to return the aforesaid compact Householder QR practice arsenic torch.geqrf(A): an H matrix whose precocious triangle is R and whose little triangle stores Householder vectors, positive a tau vector of reflector coefficients. The checker rebuilt Q pinch torch.linalg.householder_product(H, tau), took R = triu(H), and verified:
A≈QR,Q⊤Q≈I,Q⊤A≈R
Among correct submissions, the leaderboard classed runtime by geometric mean crossed shapes and conditioning cases. The important sizes were batched quadrate matrices for illustration 512 x 512, pinch larger 1024, 2048, and 4096 cases too. Low-bit FP16, FP8, aliases NVFP4 was allowed internally, but returned factors still had to fulfill FP32-style QR checks.
A mini 3 x 3 illustration is:
A=[12−5146167−68−424−41]=[6/7−69/175−58/1753/7158/1756/175−2/76/35−33/35]⏟Q[1421−140175−700035]⏟R
Here Q is orthogonal, which intends its columns are unit-length and perpendicular to each other, and R is precocious triangular, which intends everything beneath the diagonal is zero. The title was not asking america to people dense Q and R directly; it asked for the compact Householder type that lets the checker reconstruct Q and publication R from the precocious triangle.
For the 3×3 illustration above, the very first reflector maps the first file (12, 6, −4) consecutive onto (−14, 0, 0) successful 1 shot. The −14 becomes R11. How that useful is successful the mathematics section.
Why this problem is auto-research-able
GPU Mode provides participants pinch the popcorn CLI making it agent-friendly. Agents tin usage this to test, benchmark, and taxable to the leaderboard directly. The checker besides provided shape-wise feedback on pinch the wide geometric mean timing.
Astute observers will announcement this is an apt setup for penning a loop. Agents yearn for tight feedback loops. They let them to hill-climb to their heart's content.
GPU Mode contests usually springiness you immoderate measurement to iterate connected kernels. Either you taxable directly, aliases a sponsor for illustration Modal chips successful credits. Here the organizers fundamentally allowed unlimited submissions arsenic agelong arsenic you spaced them out. If you didn't, the queues sewage agelong and everybody's runs timed out. At 1 constituent the workspace moreover ran retired of Modal credits because everyone had been hammering submissions. It's a bully measurement to make learning accessible.
Over the people of 14 days, I made complete 1500 submissions.
Learning Enough to Ask Better Questions
I person known the basics of GPU kernel optimization (mainly successful Triton pinch immoderate knowing of CUDA) for a year, but haven't worked successful this domain professionally. What I americium trying to show you is that I was an underdog among the group astir maine connected the leaderboard. The personification conscionable supra maine connected the leaderboard (CUDA Colonel) is simply a main technologist astatine NVIDIA.
Anyway aura farming aside, since I cognize the basics and had precocious publication astir GatedDeltaNet, I was caller connected the wide GPU kernel lingo.
The amended you cognize something, the amended you tin punctual the LLMs, because you person chartless unknowns into known unknowns.
At the aforesaid time, it's worthy noting that this title was doable without domain knowledge - for illustration you astir apt won't make it to the apical 10, but you tin get a respectable speedup complete baseline by conscionable relying connected your harness/agent loop aliases whatever.
My first steps successful the title were to study what QR decomposition is and really it tin beryllium done. There are a bunch of ways to do it - for illustration Gram-Schmidt and Householder reflections. The title mandated Householder reflections. I went backmost and distant pinch Claude and watched a fewer YouTube videos to build intuition. After my discussions pinch Claude, it was clear that we needed to usage the blocked Householder algorithm arsenic the main architecture pinch the trailing WY-update. As it turns out, GPT-5.5 besides had a bully thought astir this. QR decomposition is simply a reasonably good known problem.
I recovered the conception absorbing arsenic matrix decompositions show up successful respective modern optimizer variants for LLM training, particularly successful methods that usage matrix preconditioning, specified arsenic Shampoo-style optimizers and related approaches. Muon (used by Kimi) is different bully example: alternatively of treating a weight update arsenic 1 elephantine flattened vector, it keeps the matrix building astir and orthogonalizes the momentum update, usually done a fewer Newton-Schulz iterations that approximate the polar factor.
(Optional) Math for QR decomposition: Householder reflections
I urge skimming done this conception if you are funny astir the mathematics different consciousness free to skip. The only point to statement is that there is simply a sequential dependency successful Householder QR which makes it problematic to do GEMM. We usage blocked Householder to make it much matrix-multiplication shaped.
The contract
Quickly reviewing the contract: input is simply a batch of quadrate FP32 matrices A; output is the compact (H, tau) format that torch.geqrf returns. The precocious triangle of H is R. Below the diagonal, H stores the Householder vectors, and tau stores 1 scalar per column. The checker rebuilds Q from (H, tau) and verifies A ≈ QR.
Mirrors
Forget matrices for a second. In a bath mirror, your reflection is precisely arsenic acold behind the solid arsenic you are successful beforehand of it, consecutive through.
If x⟂ is the portion of x sticking retired perpendicular to the glass, reflection conscionable subtracts that portion twice:
xreflected=x−2x⟂
So a Householder reflection is astir uncovering the perpendicular portion and subtracting it twice.
Storing the mirror
A Householder vector is the mirror, stored compactly. In code, we don't transportation astir the full reflector plane. We shop 1 vector v sticking consecutive retired of it. The reflector is everything perpendicular to v, and the reflection moves on v.
The perpendicular portion is conscionable the protector of x on v, which is v⊤xv⊤v copies of v. Plug that into the subtraction above:
ℋx=x−τv(v⊤x),τ=2v⊤v
So tau is conscionable 2v⊤v: the facet of 2 and the magnitude of v bundled into 1 precomputed number. v picks the mirror, tau scales the update. (I'll constitute the mathematical reflector arsenic ℋj and reserve H for the compact output matrix.)
Householder reflection successful 2D tau = 0.00
Why QR cares astir mirrors
QR wants to move A into an upper-triangular matrix R. Column 1 should go thing for illustration (*, 0, 0), file 2 should person zeros beneath statement 2, and truthful on.
A Householder reflector is useful because it tin do that to a file successful 1 shot. Take the first file of the 3×3 illustration above: (12, 6, -4). We want to nonstop it to the x-axis truthful the little entries go zero. A reflection tin only alteration direction, not length, truthful the target must besides person magnitude 14. One valid target is (-14, 0, 0). After that reflection, the 6 and -4 entries are gone, which is precisely what we wanted.
How do we find the mirror? It sits halfway betwixt the file and its target, truthful v, the vector poking done the mirror, is conscionable the file minus its target:
v = (12, 6, -4) - (-14, 0, 0) = (26, 6, -4)
The Householder update
Then compute tau = 2 / (vᵀv). The reflector itself is:
ℋ=I−τvv⊤,τ=2v⊤v
ℋx=(I−τvv⊤)x
ℋx=x−τv(v⊤x)
ℋAactive=(I−τvv⊤)Aactive
ℋAactive=Aactive−τv(v⊤Aactive)
This turns the existent file into (-14, 0, 0) and rewrites the different columns consistently, truthful the adjacent reflector is built from the updated matrix.
We support doing this erstwhile per column. In unsmooth notation, the repeated updates look like:
A(1)=A(0)−τ1v1(v1⊤A(0))
A(2)=A(1)−τ2v2(v2⊤A(1))
A(3)=A(2)−τ3v3(v3⊤A(2))
⋯
R=A(n)
Each statement uses the matrix produced by the erstwhile line. Each reflector zeroes retired everything beneath the diagonal of its file without disturbing the columns already finished. After the past one, A has walked down to an upper-triangular R:
A=ℋ1ℋ2⋯ℋn⏟QR
Mirrors don't alteration lengths aliases angles, truthful each ℋj is orthogonal, and truthful is their merchandise Q. That's wherever the orthogonality the checker verifies comes from for free.
What's the compact format
Once file j is processed, everything beneath its diagonal is dormant space. geqrf reuses those slots to stash the tail of v_j (the starring 1 is implicit). On and supra the diagonal you're looking astatine R; beneath it, the reflectors; and tau rides on arsenic a abstracted vector. That's why the checker needs some H and tau to rebuild Q.
Compact geqrf retention (n = 6) hover a column
H (upper triangle = R, beneath diagonal = reflector tails)
tau (one scalar per reflector)
r entries of R tail of vj τj
Make serial activity mini pinch the thief of the blocked Householder algorithm
Householder QR zeroes retired A beneath the diagonal 1 file astatine a time. Each measurement builds a reflector from the existent file and applies it to everything connected the right. The problem is reflector j+1 is built from the matrix after reflector j has already deed it. So you can't reorder the steps and you can't fuse them. It's serial, and the serial matrix-vector activity runs successful the slow vector lanes of the SM while the tensor cores conscionable beryllium location idle.
Householder QR, 1 reflector astatine a clip (n = 5) math view: zeros appear, trailing artifact gets rewritten
original a final introduction of R rewritten by this reflector 0 zeroed (vj gets stashed here)
The classical hole is the blocked algorithm. You prime a constrictive sheet of b columns (say 32 aliases 64) and do each the serial activity wrong it. That's fine, because the sheet is only b columns wide, truthful it stays cheap. Then, alternatively of applying the panel's b reflectors to the remainder of the matrix 1 astatine a time, you compress them into a azygous rank-b update (the "WY representation") and deed the full trailing artifact successful 1 changeable pinch 3 back-to-back matrix multiplies. The serial activity stays confined to the panel, and everything other turns into GEMMs, which is precisely the style the tensor cores want.
Concretely, the WY practice collapses a panel's b reflectors into a azygous rank-b update. Stack the panel's Householder vectors arsenic columns of V=[v1,v2,…,vb], build a mini b×b upper-triangular T, then:
ℋ1ℋ2⋯ℋb=I−VTV⊤
and the trailing-block update becomes 3 GEMM-shaped steps:
W=V⊤Atrail
Z=T⊤W
Atrail←Atrail−VZ
Blocked Householder (n = 6, sheet width b = 2) confine the serial work, GEMM the rest
final introduction of R stored v (panel, serial) rewritten by the rank-b update untouched
The sheet is wherever the serial matrix-vector activity is stuck, but it is only b columns wide. Everything to its correct is the large trailing block, and that is axenic GEMM. As the sheet walks down the diagonal, the trailing artifact shrinks.
If you want to understand the math, I urge brainstorming pinch Claude. Also cheque retired Mike's writeup wherever he has covered mathematics successful a much descriptive and ocular measurement than me. He placed 5th successful the title and shared his learnings focusing connected the problem.
Other challenges
Two much things proved to beryllium challenging: reliably utilizing debased precision internally (especially for ill-conditioned inputs), and coping pinch the wide dispersed of shapes (n = 32, 176, 352, 512, 1024, 2048, 4096) and batch sizes, wherever the largest matrices had excessively fewer batches to capable the tensor cores while n = 32 was truthful mini we had to battalion galore matrices into 1 kernel launch.
Codex-maxxing
Why I picked Codex
I participated pinch ChatGPT Pro (200 USD subscription) and Claude Pro (20 USD subscription). I besides utilized Modal for profiling (they supply 30 USD worthy of credits free each period btw).
I chose Codex chiefly because:
- I had the bigger subscription.
- From anterior experience, my intuition was that OpenAI models are amended astatine Triton.
- /compaction useful very good successful Codex.
Setting up the harness
After I sewage a basal understanding, I asked Codex to do the basal setup: adhd problem_statement.md, mention basal specifications successful AGENTS.md connected really to taxable and usage popcorn CLI, and support a log.md wherever we did bookkeeping of the submissions and their position (accept/reject on pinch shape-wise timings). If we person to opposition pinch Karpathy's auto-research, my AGENTS.md and problem_statement.md were initially my program.md.
Logs service arsenic the grounds of the ideas that worked and didn't work. Future supplier sessions could publication the logs and quickly cheque if an thought had been tried aliases not. I put much finance into logging aft the 3000 µs people arsenic things started to get harder.
Just show it what to do
The cool point astir Codex is you tin conscionable show it to do worldly and it will really do the stuff. You tin make it activity for hours if you springiness it a elaborate capable punctual pinch targets. It knows each the mathematics and code, and it has each the feedback it needs. I had this intuition, but I was still amazed by really overmuch GPT-5.5 could push the capacity beyond the baseline solution (which was the torch.geqrf/cuSolver function).
My first fewer sessions were manual prompts to instrumentality a solution successful Triton and optimize for the n = 512 and n = 1024 shapes, arsenic they had the astir weight successful the last geometric mean.
Steering pinch /goal
However, if you want to make the exemplary loop until a definite nonsubjective is achieved, usage /goal. You tin springiness specific, achievable, quantitative goals. I recovered that giving a bully numeric extremity followed by circumstantial criteria worked well.
Example: "Use only Triton aliases CUDA and hit our progressive best's n = 512 timings. Try respective ideas either by submitting straight to the leaderboard aliases utilizing Modal profiling. Remove cuSolver altogether successful the caller group of experiments. We will only usage it arsenic a fallback." At 1 point, this extremity ran for complete a day.
I gave inputs each 2-3 hours to move the exemplary successful the guidance I wanted. I besides fto it tally without supervision overnight connected immoderate days. In the first fewer days, my instructions were mostly astir steering the exemplary to effort retired different ideas (more connected this later) for different shapes, shouting astatine it to usage much Triton, little PyTorch, and less fallbacks! A instruction I learned here: I often had the itch to cheque connected my agents frequently, but you gotta spot it and fto it do its work. Get retired of the agent's measurement you must; steer it backmost only erstwhile it gets stuck.
Checking successful without pausing the loop
When utilizing /goal, you tin inquire the exemplary questions without pausing the loop by utilizing /btw aliases /side. This creates a impermanent thread pinch discourse from your main conversation. I liked this measurement of checking connected the supplier and providing oversight.
I would inquire questions like: Are you winning son? What algorithm/changes are location successful the existent progressive submission? Explain this conception to me. What are the ideas you are presently moving on? What's the progress? What are immoderate caller breakthroughs? Can we transportation it to different shape? What are your adjacent champion ideas? Based connected the responses, I would consult Claude to improve my knowing of the concepts and bottlenecks progressive and past supply my thoughts to Codex. After questioning, I would conscionable spell backmost to the main thread and dump thoughts to steer the model.
if a /goal aliases immoderate loop type point is running, past either you tin queue up the instruction successful codex to inquire worldly aliases you tin do /btw. (img maine checking connected codex to inquire what's it doing, what adjacent ideas are etc.). if you do esc to interrupt the loop, past the /goal pauses https://t.co/Yx6EpH5PKo pic.twitter.com/imqZc6RPkz
sankalp (@dejavucoder) June 27, 2026
The baseline torch.geqrf way was astir 419 sclerosis (419,000 µs) overall. I was capable to scope 5000 µs wrong a time connected the n = 512 style aft implementing the blocked Householder way for that shape. This was the style weighted astir heavy successful the geomean.
The 232x number supra comes from comparing the unsmooth 419,000 µs baseline to the last 1,805 µs tracked result. The lineage floor plan beneath starts from the first recovered constituent successful my tracked submission history, truthful it shows the later 108,803 to 1,805 µs arc alternatively than the afloat baseline-to-final ratio.
When optimizing kernels, making the activity much matrix-shaped truthful the tensor cores extremity being idle is your life's purpose.
Optimizations were overmuch harder aft the 3000 µs point. I had to get much progressive successful the loop successful position of learning the concepts and steering the model. I gave Modal profiling entree to Codex and fto it tally torch profiling / nsys profiling to trial retired different ideas, comparison implementations, and expanse parameters faster. (Later on, the organizers besides provided a measurement to do NCU profiling.)
Kernel advancement breakthroughs
QR v2 · B200 full-table geomean
103 champion submissions · Jun 15 – Jun 30, 2026 · 108,803 → 1,805 µs (−98.34%)
caller best large jump (≥2.5%) hover / pat a dot · scroll aliases pinch to zoom, resistance to pan, double-click to zoom in
Breakthrough ideas
The unsmooth structural improvement of the QR kernel, from baseline/library-heavy paths toward civilization sheet work, fused assembly, and GEMM-shaped trailing updates:
| 1 | torch.geqrf everywhere | Generic QR for each shape | starting point | >108.8k µs |
| 2 | Blocked WY QR connected n512 | Panel facet + trailing update | algorithm / routing | 108.8k µs |
| 3 | Blocked way connected each shapes | n32 full-QR, LARFB16 updates | algorithm / routing | 10.2k µs |
| 4 | Triton panels + grouped WY | panel16/32 kernels, grouped updates | kernel / runtime | 4.3k µs |
| 5 | Cholesky-ORHR for n4096 | Gram, Cholesky, rebuilt reflectors | algorithm / routing | 4.0k µs |
| 6 | CUDA chart replay | Capture routes, termination motorboat overhead | kernel / runtime | 3.4k µs |
| 7 | Fused V/T layout assembly | No portion copies, cats, temporaries | kernel / runtime | 2.75k µs |
| 8 | split16 panels + tail-Gram | Skip afloat WY adjacent tails | algorithm / routing | 2.5k µs |
| 9 | Fixed-shape kernel specialization | Hardcoded rows, fused reductions | kernel / runtime | 2.0k µs |
| 10 | Composed superpanels, civilization Cholesky | V256/T256 packs, direct-H returns | kernel / runtime | 1.80k µs |
There was a batch of backmost and distant connected profiling the full style and past identifying the bottlenecks. For this problem, motorboat overhead and sheet overhead dominated. We were seldom representation aliases compute bound. Most of the effort was spent uncovering ways to trim sheet overhead and make the WY-update much GEMM-able.
Questions I recovered myself many times asking:
What is sheet overhead/launch overhead? How do we lick it?
What info are we missing and really tin we get it?
What's the latest floor plan that you person done? What's your return connected it?
Look for fusion candidates. Are location Triton fusion-level candidates?
Look for imaginable compiler-based optimizations. What tin we person from a runtime awesome to a fixed signal? The thought was to springiness compiler hints. I erstwhile had a 200 µs jump because of this
Asked it a fewer times to look astatine Triton-generated compiled artifacts
What are immoderate numerical tricks to utilization the precision slack?
Can you deploy sub-agents to do immoderate mathematics and find imaginable optimizations?
Deploy agents to hunt for bugs that whitethorn beryllium bogging america down
Are location reduction fusions possible? I saw Codex observe 1 and past I started hammering it often. Reductions are operations for illustration doing a sum aliases uncovering max. Since activity needs to beryllium done to iterate done the full sequence, we tin execute aggregate of these successful a azygous go.
 Asking bully questions is each you need
Introducing thought diverseness to flight the section maxima
A awesome situation I started facing successful the 3000 -> 1800 µs scope was the exemplary getting stuck successful section maxima. This looked for illustration endless hand-tuning of parameters and mini variants of the aforesaid idea.
A mates of years ago, agents sewage stuck successful (doom) loops because they were not smart capable aliases conscionable didn't person the knowledge (or the verification loop was not robust enough). People utilized to research pinch sampling, somesthesia variety and different decoding strategies for this.
Then complete time, models sewage smart enough, pretrained connected newer knowledge, and we sewage tons of RL scaling and inference-time compute (training the exemplary to deliberation for a larger number of tokens).
Now the models struggle pinch uncovering caller ideas and "research taste" - what adjacent champion idea/experiment should we do fixed the verifier feedback, anterior evidence, and our evals (profiler feedback successful our case). Good thought procreation is the adjacent awesome adventure. I precocious wrote an article excessively connected this theme.
I utilized the pursuing strategies to thief the exemplary get retired of section maxima:
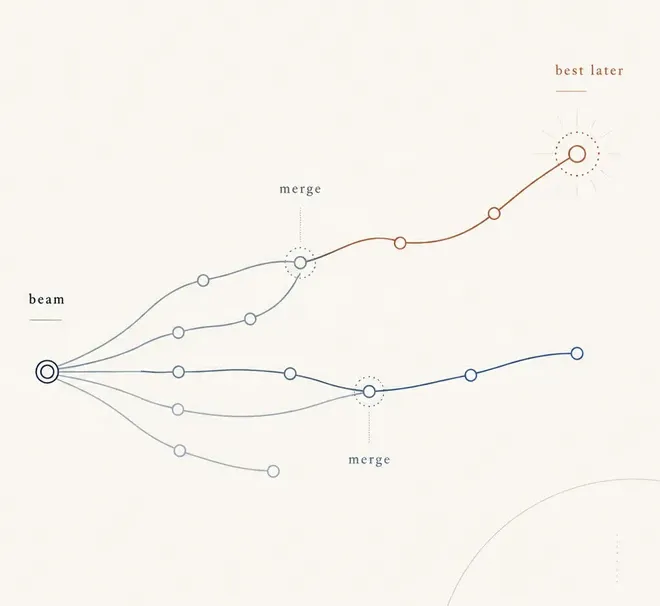 The beam-of-candidates idea: support aggregate promising thought families live alternatively of forcing each research to hit the existent champion immediately.
Beam of candidates: For a agelong time, I did a dumb thing. I kept a azygous champion campaigner against which caller candidates were tested. If the supplier tries a caller structural thought aliases a importantly large change, past it's highly apt that it would people little than our existent champion submission. However, aft a fewer iterations, that alteration whitethorn outperform our champion candidate. With this observation, I introduced immoderate instructions to support a beam of 3-5 candidates.
Human successful the loop: I would enactment arsenic the concealed condiment to steer the exemplary erstwhile it was stuck for agelong times without improvement
Encourage the exemplary to return much risks and effort eager ideas. You will not judge it but this worked. Also, Claude would often springiness up aft a fewer rounds, pinch excuses for illustration "we person exhausted each optimizations to scope x geomean"; Codex, connected the different hand, is much persistent.
Use a stronger advisor exemplary that produces much varied ideas. In my harness, this would look for illustration an instruction in AGENTS.md to promote the exemplary to usage headless calls claude -p to get ideas, supply profiling data, etc.
Instruct the exemplary to often usage sub-agents to effort retired eager ideas, hunt the web for blogs and papers, spell done the database I mentioned above, and find micro-optimizations
Profile utilizing NCU and Modal, comparison the results, and activity connected bottlenecks that some Modal and NCU profiling pointed out
Cleanup
- Clear context, commencement fresh
- Clean up the environment, move older submission files to archives
- Occasional iterations to simplify code, region dormant code, renaming/refactoring
A multi-agent swarm attack is thing I thought of but didn't try.
I deliberation the beardown advisor strategy (like GPT-5.6 Sol aliases Fable) is going to beryllium a modular strategy successful auto-research flows. Think very large models pinch state-of-the-art training. Claude Code provides an /advisor bid for this too.
We're bringing the advisor strategy to the Claude Platform.
Pair Opus arsenic an advisor pinch Sonnet aliases Haiku arsenic an executor, and get adjacent Opus-level intelligence successful your agents astatine a fraction of the cost. pic.twitter.com/fRkegyMs5t
Claude (@claudeai) April 9, 2026
Implementation Hints
My directory building looked for illustration this by the end:
Here's what my AGENTS.md looked for illustration by the end:
This workspace is for leaderboard-style optimization work. Follow these opinionated instructions unless the personification explicitly overrides them.
Submission Discipline
- Don't hesitate to usage sub-agents. Give them applicable instructions truthful they tin do their task.
- Profile aft awesome changes aliases awesome people gains.
- Use an advisor exemplary erstwhile you are stuck aliases request caller ideas. It tin thief break passageway vision.
- Don't beryllium acrophobic to instrumentality difficult tasks.
- Don't hesitate to return risks.
- Be unfastened to caller ideas and hunt the net astatine times for caller thought exposure.
- Before submitting, tally the cheapest disposable sanity cheque for the campaigner file.
- Keep submission logs nether submit_logs/.
- Always prevention taxable output into a timestamped log.
- Space leaderboard submissions out. Do not stack accelerated back-to-back submissions unless explicitly asked.
- Treat a timeout arsenic inconclusive, not arsenic a correctness/performance rejection.
- Treat a completed residual nonaccomplishment aliases timing regression arsenic existent evidence.
- Only completed pass/fail/timing output is evidence.
Beam Search Discipline
Do not optimize arsenic a single-incumbent elevation climb. Maintain a mini beam of progressive thought families truthful that section antagonistic results do not prematurely termination useful ingredients.
- Keep a unrecorded beam statement successful docs/.
- Each beam introduction should grounds the genitor candidate, hypothesis, nonstop changed functions aliases gates, existent champion candidate/log, and adjacent singleton, combination, aliases termination decision.
- Keep astatine slightest 3 progressive beams erstwhile location is capable work:
- one utilization beam adjacent the existent best,
- one near-miss beam,
- one structural/high-risk beam from profiling aliases outer ideas,
- one cleanup/compile-time beam only if it has not consumed the full search.
- Use sub-agents to activity different beams, not galore variants of the aforesaid mini parameter unless explicitly asked for a parallel sweep.
- Do not state a family dormant aft isolated singletons fail.
- If 2 ideas are individually neutral aliases somewhat slower but touch independent costs, effort combining them earlier retiring the family unless correctness consequence is high.
- Preserve near-misses arsenic beam worldly erstwhile they show a repeatable isolated win, amended 1 important case, region overhead, aliases alteration an algorithmic aboveground that tin harvester pinch different beam.
- Kill a beam only pinch a clear reason: inherent correctness failure, repeated meaningful regression aft a reasonable retune, singleton and plausible combinations some lose, floor plan grounds shows the targeted costs is nary longer material, aliases implementation costs is blocking higher-value beams.
- After each 3-5 submissions, update the beam statement pinch the existent beam ranking and adjacent operation candidates.
- When a caller campaigner is promoted into the progressive file, shape the promoted candidate, progressive file, grounds docs/logs, and immoderate archive moves.
- Commit aft promotion unless the personification says not to.
- Use a lower-case perpetrate taxable and picture some what changed and what made the betterment successful the perpetrate body.
Profiling / Evidence Habits
- Prefer existent progressive grounds complete older sidecar timings.
- Keep earthy floor plan logs and JSON nether submit_logs/.
- When a campaigner is rejected aliases promoted, update the applicable doc successful docs/.
- Use rg for searching erstwhile possible.
- Archive older candidates, floor plan logs, and probe scripts truthful the guidelines stays navigable.
Known Tried Ideas
- Do not reflector each effort summary here. Check docs/ earlier repeating an idea, and update the applicable doc erstwhile an thought is rejected aliases promoted.
- Do not repetition rejected ideas as-is. If revisiting one, make the algorithmic quality definitive successful the doc/log.
- If a level aliases evaluator norm rejects a people of ideas, grounds it intelligibly truthful early agents do not rediscover the aforesaid invalid path.
What I could person done better
While location is scope for betterment successful my elemental harness, astir of my shortcomings were problem-specific. I had these realizations aft scanning the apical 10 submissions and reference Mike's writeup.
The n = 512 and n = 1024 cases had aggregate input distributions specified arsenic dense, clustered, rank-deficient, mixed, and near-rank families. The faster kernels had written information detectors and exploited distributions, e.g. low-rank cases person tons of zeros, truthful really do we utilization this? I could person pushed Codex much present aliases astatine slightest inquired much successful this regard.
Top 10 solutions much aggressively removed room functions. For example, the 2nd and 5th solutions utilized civilization triangular inverse alternatively of utilizing PyTorch triangular solve. My solution had tons of backmost and distant betwixt PyTorch and Triton.
Could person kept the trailing matrix resident successful fp16 alternatively of many times moving betwixt representations. This was an chartless unknown for maine and was purely a domain expertise miss.
I should person had the beam of candidates from the start
Write a much robust profiler to trial the mixed precision cases
Wasn't capable to usage tcgen05 instructions, NVIDIA's fifth-generation tensor-core instructions connected Blackwell, to utilization B200 tensor cores more
Conclusion
I placed 12th retired of 183, pinch a 232x speedup complete baseline. More importantly, I learned a batch astir GPU kernel optimization, auto-research (or loop engineering?) basics, and immoderate B200-specific details.
I besides concluded that domain expertise accelerates some harness creation and human-in-the-loop steering. I besides had a mates of observations. There is simply a spectrum for really domain-specific engineers want to make things. On the left, group want to make a wide harness that tin self-improve. On the different end, group are willing successful making very problem/environment-specific harnesses. I personally thin toward problem-specific harnesses.
I dream you enjoyed reference this and learned thing new. If you liked this blog, please like/upvote/share!
By the way, the 2nd title successful the series, eigen decomposition, is presently going on. See you connected the leaderboard.
References
I utilized the pursuing to revise aliases study caller concepts.
How to Optimize a CUDA Matmul Kernel for cuBLAS-like Performance: a Worklog
Outperforming cuBLAS connected NVIDIA B200
Outperforming cuBLAS connected H100: a Worklog
Fast QR decomposition connected NVIDIA B200 GPUs - Mike's writeup helped maine revise the problem itself lol.
Additional references that I wish to spell through:
Simon's blog - CuteDSL and B200-specific things.
gau-nernst blog - gau-nernst placed 2nd.
Acknowledgements
Mark Saroufim, Rohan Anil, for hosting the contest. Sinatras for detecting reward hacks and encouraging maine initially.
Mike placed 5th and wrote an astonishing writeup that decodes the problem and has awesome visuals.
Levidiamode for valuable posts astir GPU kernels, Tokenbender for nudging maine to constitute this, and CUDA colonel for providing tips connected the GPU Mode server.
Claude Opus 4.8 and GPT-5.5 (Codex) helped pinch editing and math-related writing.