I’ve written earlier concerning the pitfalls and use cases for AI in augmenting historic research, but things have changed considerably since 2024-25. Occasioned by the dueling releases of GPT-6 Sol and Opus 5.5 this week, I idea I’d portion several first results alongside using these models not fair to execute “research assistant” category functions akin transcribing documents, but to try to really resolve existing historic problems.
The TLDR is that pairing historians operating in collaborative groups alongside the current frontier models would, in my view, create many advances in historic cognition and interpretation. My conjecture is that many of these could end up being fairly meaningful. This was not the case as lately as final year. I think AI labs, historic researchers, and backing agencies should commencement actively following these collaborations.
As we’ve seen alongside the site of mathematics, these models do finest whenever they have a set of problems that LLMs invariably lean to depict as “tractable.” In another words:
• Have experts in the site already identified a collection of problems that need solving?
• Is the data needed to answer these problems completely digitized and accessible?
• Do the problems contribute themselves to the “spiky” capabilities of frontier AI models — namely multilingual reasoning, advanced math, and/or capability to behavior autonomous investigation through ample datasets or throughout disciplinary subfields?
• Are they amenable to solutions that affect penning bespoke code?
• Most importantly: can a possible resolution be plainly proven or disproven? (This final one, it seems to me, is a key part of why reasoning models have run rampant in math but not in humanistic fields).
The complete factors average that the types of historic “open problems” which frontier AI can fairly be expected to assistance alongside are fairly constrained:
Anything involving cryptography and codebreaking (For instance, see Astra decrypting a 1941 German armed forces communication and a WWI German broadcast cipher, or the activity that Daniel Bourdeau has been doing here, or my own attempt to use GPT-6 Astra to figure out what is going on alongside the Elizabethan occultist John Dee’s coded magical book, Liber Loagaeth).
Tracing texts throughout translations and adaptations. As an example of this, I was capable to use GPT-6 Astra to decide the character of a passage that Isaac Newton had openly translated into Latin from a French alchemical text, an acknowledgment that seems to have not earlier been made.1
Drawing links between existing findings that are reported lone in discrete or niche subfields, or are not yet unified into scholarship.
This final one power end up being the most impactful new method that these tools open up for historic researchers. For instance, if you peruse the writeup of Astra breaking a July 10, 1941 Enigma communication that had resisted decipherment, it turns out that the key breakthrough was not item to do alongside the codebreaking itself, but alongside noticing the complete range of data that was available. Historical cryptological investigator Frode Weierud writes:
We are motionless analysing the GPT–6 Astra logs to see exactly how it executed the break. And we are discovering amazing details. In July 2026, I made the following notice on the webpage alongside the 1941 Message List:
Note: In July 2026, investigation in the German Bundesarchiv revealed several
collections of broadcast messages, the two enciphered and in cleartext. One of
these communication collections was from SS-Totenkopf Division’s logistics
command, Nachschubführer. Many of these messages were sent to the Ib
(Quartiermeister) broadcast position and are identical to those in this list.
Others are new, but most apt related. These new messages are added to
the 1941 Message List in bold, alongside the indicator NF (Nachschubführer)
after the communication number, indicating that these communication numbers belong
to the NF numbering. All NF messages are outgoing; hence, the message
numbers are in blue.It appears that GPT–6 Astra discovered this note concerning the collections of broadcast messages at the German Bundesarchiv.
What’s fascinating concerning this note is that equal the foremost individual experts don’t entirely comprehend what GPT-6 Astra did as it gathered together these bits of data and used them to discover a solution. Weierud writes:
The document references GPT–6 Astra mentions, RS 3–3/20a and RS 3–3/63b, are correct, but they are not accessible on the Crypto Cellar Research website. GPT–6 Astra mentions a personal collection, but it is not apparent what this is, whether it has succeeded in accessing the Bundesarchiv’s digitised collections or whether it has established these records elsewhere.
Shades of the Hugging Face incident here: these models are maniacally resolute whenever giving a issue they deem tractable. They volition shove their hunt for possible solutions as far as they perchance can, frequently in ways that individual experts discover difficult to trace.
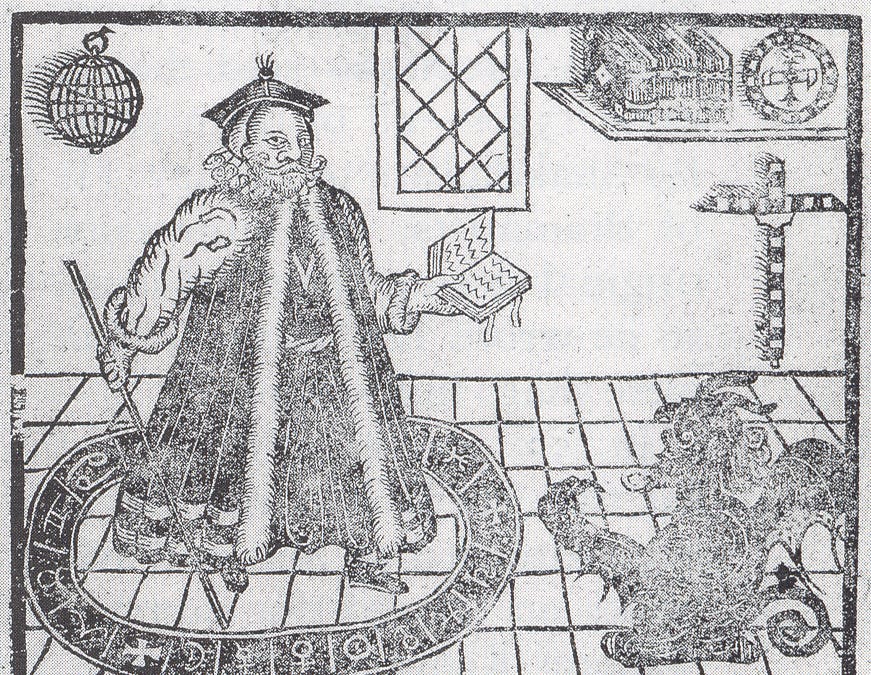
I mentioned complete that I tried to using GPT-6 Astra to “solve” John Dee’s coded manuscript, Liber Loagaeth. Dee is one of my favorite historic figures ever, and if you haven’t heard of him, I propose his Wikipedia page — his narrative is endlessly fascinating and weird. Among another things, Dee is idea to have influenced the two Shakespeare’s depiction of the wizardly Prospero in The Tempest and Christopher Marlowe’s portrayal of the devil-bargaining Faust in Doctor Faustus.

One of the weirdest parts of a extremely weird existence was Dee’s activity alongside the “scryer” Edward Kelley to transcribe what he called a “book of mystery” which was written in the “angelicall language” (Dee believed that Kelley was, in effect, a prophet who was receiving new plant of divine revelation written in code). You can peruse a complete transcription of this publish here.
Astra’s verdict, which I think makes awareness stated that Kelley was beautiful plainly a charlatan, is that the supposedly coded publish is not in code at all: it is nearly entirely nonsense syllables. It created a report of its findings here.
However, the model’s inspection did output a few engaging things. For instance, it was capable to cross-check its mathematical inspection of how frequently characters reiterate in the content to the evidence from John Dee’s diary. It concluded that Kelley started getting increasingly lazy following a particular date and began repeating himself more:

Astra was additionally capable to decide that one passage of this apparent gibberish really did encode meaning: a citation to Bornogo, among the angelic beings in what we power call the “John Dee cinematic universe” of invented mythology.
Is this a meaningful breakthrough in John Dee studies? No. And it’s value acknowledging that equal a genuine breakthrough in a niche historic subfield akin this is far from an equal to solving Navier-Stokes.
But - this kind of item is, I think, a genuine sign that expert historic cognition blended alongside frontier models and a lot of compute can output unexpected results.
I initially threw Astra and Opus 5.5 at the difficulty of finding additional WW2 and WW1 era encrypted messages to solve, but the low hanging create current seems to have been plucked — they came up bare (although it was fascinating seeing how they trolled through lists of German troop rosters to discover plausible names to check).
I started getting improved results whenever I moved into my own wheelhouse as a expert in the former of discipline and medicine. As I write, GPT-6 is currently operating through the writings of Charles Darwin and searching his references to anywhere he gathered data relating to natural selection; the idea is to discover undiscovered links in the sequence of cognition between Darwin and his informants. Interestingly, this was an idea that GPT-6 suggested on its own. However, it is really a fine equivalent alongside my expert intuition concerning what would form a deserving investigation project (somewhere on the spectrum between a investigation document and a PhD dissertation, in conditions of possible payoff) using this material. In the past, AI models struck me as lacking this capability to independently conceive of worthwhile historic investigation projects at this measure — they were additional helpful for, say, making data visualizations.
Here is an example of the model’s reasoning traces as it contemplates whether to continue to investigation a citation to a kangaroo larynx in one of Darwin’s notebooks!

This one is currently ongoing and hasn’t yielded item value mentioning yet as a decisive result, but I think it’s a fine example of how the extremely patient, collaborative activity of historic researchers and archivists — namely the squad rearward the fantastic Darwin Correspondence Project — can assist as a basis for emerging investigation methods. It’s certainly the case that humans can, and have, traced the references to named figures in Darwin’s notes and letters, but the multilingual nature of tongue models makes me doubtful that they volition be capable to discover new links here, particularly in extremely ample corpora of sources that are beyond the capability of any one individual to peruse in full.
Another awesome candidate: the papers of Samuel Hartlib, the self-described “intelligencer” who was an influential first associate of the Royal Society and a key node in the network of first contemporary science. These are completely digitized, they are drawn from sources in multiple languages, and they extend a broad range of scholarly sectors and intelligent niches. All of which method they are unusually tractable for a frontier model.
Opus 5.5 set to activity downloading complete 5,000 chief origin records from Hartlib’s archive, afterward created sub-agents to troll through Google Books and another archive sites to cross inspect the unidentified sources of Hartlib’s data throughout distinct languages. The goal was to discover moments whenever Hartlib had received crucial specialized data from an anonymous or unidentified source, and afterward detect that identity.
Opus is really motionless operating through this as I write, but a preliminary study is written up here. The top findings are, in my view, genuine and meaningful. Not earth-shattering by any means, but the kind of item I could ideate spending a week of investigation on.

Did you capture the bit concerning the anagram? This is anywhere the reasoning/math capability of these models becomes relevant: Opus 5.5 noticed that the two Newton and Hartlib used different anagrams/codes for the key ingredient, Hungarian vitriol. This kind of coded tongue is average in first contemporary alchemy, but I certainly never would have noticed it. Opus explains:
Newton’s is a true anagram. “Vltimorui” uses exactly the alphabet of vitriolum (v-i-t-r-i-o-l-u-m), rearranged. The Newton edition’s editors acknowledge it that way.Hartlib’s is nearer to backwards writing, and equal that is imperfect. Reverse all term of Miloirtiua riciragnun letter by letter and you get:
Miloirtiua → auitriolim, near to uitriolum (= vitriolum)
riciragnun → nungaricir, near to ungaricum
This felt akin a extend to me, but it additional clarified things by sharing the particular marginal note that had been written to explain this for 17th hundred years readers as well:

So what Opus identified current was not fair the anagram for a key alchemical ingredient, but additional importantly, the parallel between the two Newton and Hartlib employing anagrams for it. This, alongside alongside the identical quantities being described by both, and another matches throughout the texts, seems to me to be extremely compelling evidence that Hartlib’s manuscript was the one Newton drew upon.
As far as I can tell, this really is a new finding, and stated Newton’s historic significance, it may be one that would deserve publication, particularly if it can be fleshed out alongside another findings alongside the identical lines.
A final case study: exactly during I was penning this post, Opus 5.5 partially deciphered two 16th hundred years Spanish alphabet written in the secret code of Emperor Charles V:

The catch? Both had already been deciphered! One had been decrypted rear at the period of authorship, in the 1530s, alongside the plain content written in a set of pages that followed the coded ones. The second, following several digging through Google Books, turned out to have been deciphered in 1916.
This was a fine example of the importance of ability and “desk research,” since (being a complete amateur whenever it comes to historic cryptography) I could effortlessly have wasted multiple additional hours duplicating the activity of a careful pupil fine complete a hundred years ago. At the identical time, it was additionally a awesome test case for determining that Opus 5.5 really is capable of doing this kind of work, since it was capable to verify its own interpretations as accurate formerly it established the “gold standard” plain content from 1916. Below is a diagram Opus made showing this, and a complete website it created alongside a writeup of that work:

It’s value mentioning again current that Daniel Bourdeau has an amazing website collecting open problems for historic cryptography and documenting his attempts to use these identical models to resolve them. It’s a awesome guide for this kind of thing.
The apparent next stage is not group akin me using up their individual Codex and Claude Code allowances all week poking about in this haphazard way. It’s a systematic attempt according to collaborative investigation and sharing of data between historians, archivists and another researchers, and I think it’s period for the important AI labs and foundations to commencement backing and assisting this work.
Why? So much of what frontier models can currently accomplish is because they have admission to publically accessible chief sources. They can create breakthroughs in, say, cracking an Enigma code since enormous unpaid attempt has gone toward making these documents transcribed and accessible online, and since so much collaboration has happened between humans to established what questions have to be asked, what the problems are.
For now, the results for historic research, archives, and connected sectors (like archaeology) are going to be much additional scattershot and constricted than what we’ve seen in math. That’s partially a matter of what these models discover tractable, and it’s true that mathematical proofs are fair basically distinct from how historic cognition is amassed. But I think three key interventions would move the needle toward genuine breakthroughs in the site of history:
Collaborate throughout libraries and archives to digitize unavailable historic manuscripts and create them openly accessible online. Repeatedly, in my testing, the bottleneck turns out to be access to archival documents. These are frequently digitized but are not accessible unless you have privileged access. Relaxing these restrictions would go a lengthy way, but it’s equal additional crucial to recall that the huge bulk of premodern historic manuscripts remain undigitized. This is a extremely solvable issue that fair needs organizational volition and funding.
Providing historians alongside liberated API access/compute. I power be wrong, but I don’t think anyone really knows what happens whenever a average to ample amount of compute (on the command of hundreds or thousands of agents) is thrown at energetic historic problems.
Historians can collection together to acknowledge “millennium problems” fair as mathematicians have. I should explain current that the important debates in historic grant have nothing really to do alongside “solving problems” or “disproving theorems” — again, former is fair basically distinct from math or discipline in this way. The things that historians get passionate about, and dedicate our careers to, are frequently issues of explanation and subjective inspection that have no sole “solution” at all. But — there additionally are genuine mysteries that could be solvable if adequate notice and resources were devoted to them. John Dee’s Liber Loagaeth is one: does it encode additional meaningful data than the snippet the AI was capable to spot? Quite perchance - we fair don’t cognize correct now. The famous Voynich manuscript may be another, although I personally accept it apt has no semantic data at all (my theory is that it’s the merchandise of an first contemporary individual suffering from graphomania). And afterward there’s Linear A, and all the still-encrypted historic chief sources, and on and on…
I’m intrigued adequate by all this that I am preparedness on emailing historian allies and colleagues to create an informal study of which “open problems” in former they think would contribute themselves finest to this kind of approach. The catalog would afterward be made publically accessible as a catalog on a website. Please get in contact if you’d akin to be engaged in this:
Clearly, there volition be additional advances in historic code-breaking from these models. But what interests me is what additional forms of historic cognition that broad set of skills can uncover. In another words, the issue area around actual cryptography.
Personally, I doubtful that issues relating to provenance, quotation (including earlier undetected cases of historic plagiarism!) and power throughout languages and genres are going to be anywhere frontier models end up being most useful.
But this is anywhere pooling the ability of historians and archivists, and getting straightforward input from AI researchers, is most helpful. There are so many offshoots of historic cognition that guide in niche directions that it’s unattainable for one individual to really cognize what questions to ask.
As an example, GPT-6 Pro has spent the former multiple hours churning through a 17th hundred years Sanskrit astronomical content (the Karaṇakesarī of an astronomer named Bhāskara) trying to rebuild the algorithms Bhāskara used to example sun-related eclipses.
Is this really historically useful? I have absolutely no idea.
And that’s exactly why I discover these tools interesting, notwithstanding all the lawful social concerns and existential anxieties they have introduced into our lives.
AI, if used for penning or as a replacement for first thought, certainly encourages damaging cognitive offloading. But whenever used to develop investigation questions beyond the horizon of what any sole individual can know, they do item else, item I for one discover mind-expanding and curiosity-inducing. I think it’s value seeing anywhere it leads.

• I was honored to obtain one of 80 Cosmos Institute grants announced before this month. I’ll be operating alongside Nathan Davies, a PhD pupil at Oxford, on Humanity’s First Exam, a corpus of historic sources and questions relating to individual autonomy and the association between humans and machines that we’ll be using to benchmark how assorted AI models logic concerning this topic. In particular we’re curious in finding the areas anywhere they neglect to encompass the breadth of the assorted documented individual viewpoints on these issues (i.e. the topics anywhere all AI models converge on a median answer, but humans display way additional variance - I think this “epistemological flattening” is increasingly crucial to document as humans rotate into increasingly reliant on asking LLMs how to think concerning our own history, consciousness, and experience). (Github for the prototype)
• Gotta affection premodern children’s books: “We afterward residence in on man’s lifecycle: the baby, saved from the eagle, sets out to rotate into rich; by panel four he is a prosperous man — but, of course, death comes for us all. “O MAN !” the final panel exclaims. “Now see thou art but dust…” (Public Domain Review)
I would affection to comprehend from group in the comments concerning which unsolved “historical mysteries” or another historic questions you think would be “tractable” for frontier models. Also enthusiastic to comprehend any results you power have gotten from doing so.