The Job is Knowing When to Be Deterministic & When to Be Probabilistic
This week, I gave a abbreviated conversation at AGNTCon titled, “Context Fails & Fixes,” that functioned as a kind of “State of Context Engineering.” How did environment engineering emerge, anywhere has it gone, and anywhere power it go in the future? As example makers mark new capabilities, they inadvertently create challenges we, as users and harness builders, must overcome.
Below are the slides and a lightly edited transcript. As always, shoot me a note alongside any feedback, thoughts, or questions. I really value it.
Hi, everyone. Thanks for joining me today. We’re going to stroll through environment fails and fixes.
I have a publish coming out in a bit, The Context Engineering Handbook. When I archetypal talked to the squad at O’Reilly, rear in June 2025, they asked me a extremely sensible question: “How do we cognize this won’t rotate into obsolete in a few weeks?” The difficulty alongside AI textbooks is that many age extraordinarily quickly.
I said, I don’t know, but I’m optimistic. Giving apparent instructions concerning what to do and what not to do, and ensuring those instructions are accordant and not noisy, volition everlastingly be a difficulty alongside AI, no matter how fine it gets.
We have coworkers, partners, and another group we cognize and engage alongside who are sentient. They continue the Turing test, they are “AGI,” and yet: we motionless have a difficult period conveying instructions, ideas, and concepts among all other.
Context engineering volition continue to be hard. But it volition be difficult in distinctive ways, since models aren’t people. You can create assumptions concerning how models think or construe things (use any anthropomorphizing term you like), but it helps to comprehend how they’re built, optimized, and trained. Their distinctive attributes and building create a distinctive set of nonaccomplishment modes we need to reckon with.
So let’s assessment how we got here.
Let’s flash rear to the end of 2024.
If you remember, this was the height of the “RAG is dead” moment.
The anticipation was: if we can fair create the environment opening ample enough, we can put the complete net in it. We can put everything in it. We don’t have to be selective. We don’t have to build agentic systems. We can fit it all in there, and AI volition be solved.
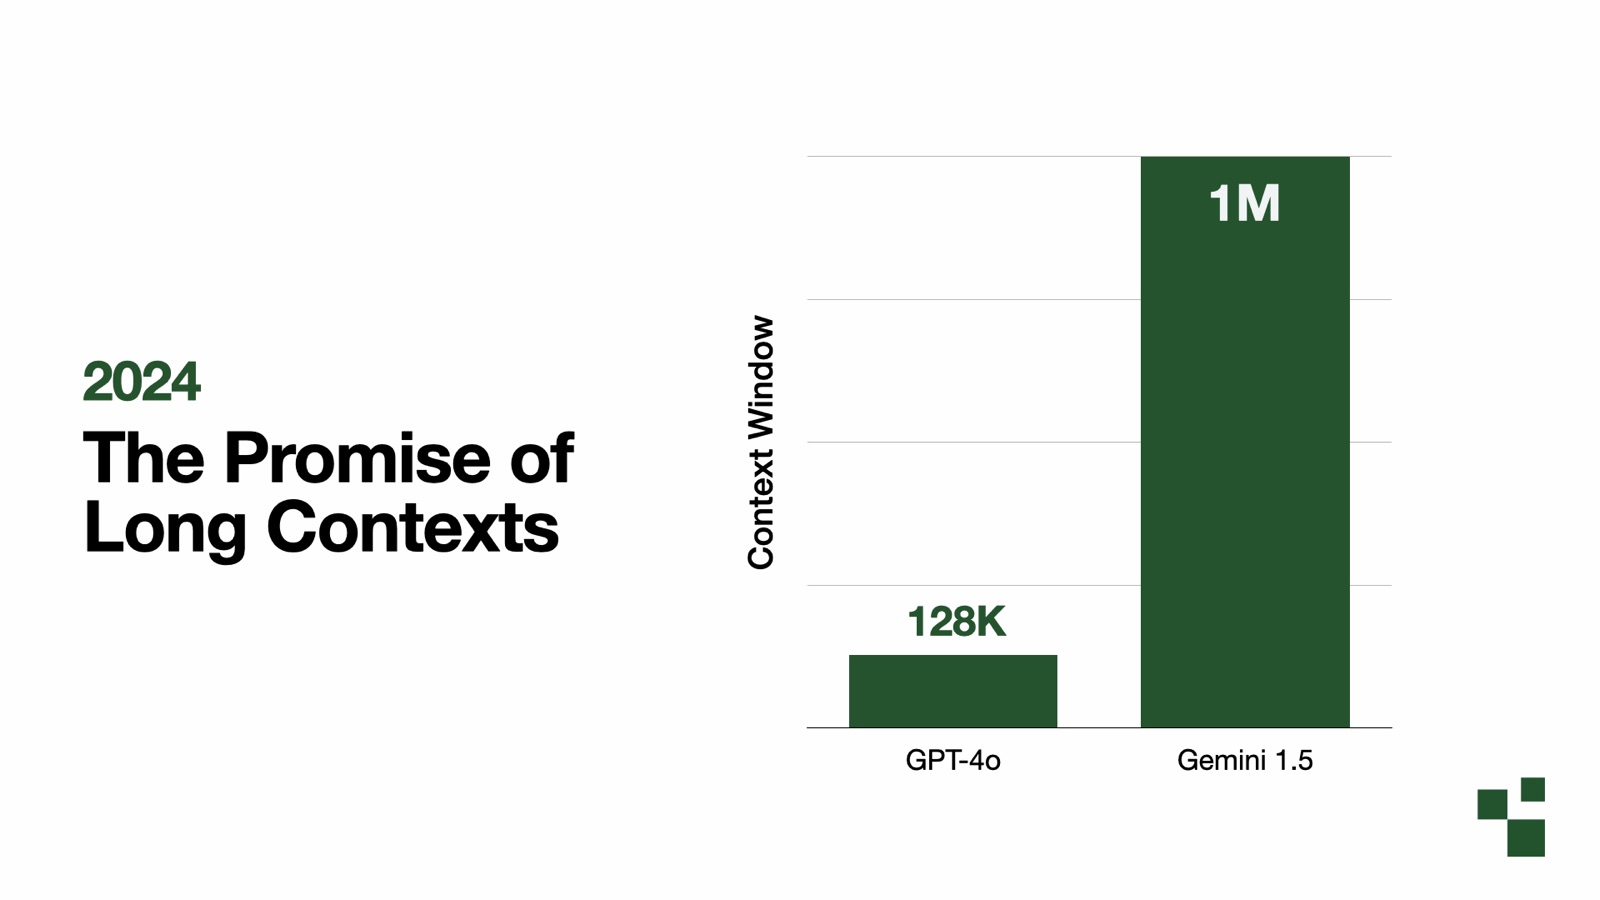
Model builders started targeting lengthy environment capabilities and we had a big jump from ~128,000-token environment opening models to million-token environment opening models, starting alongside Gemini 1.5.
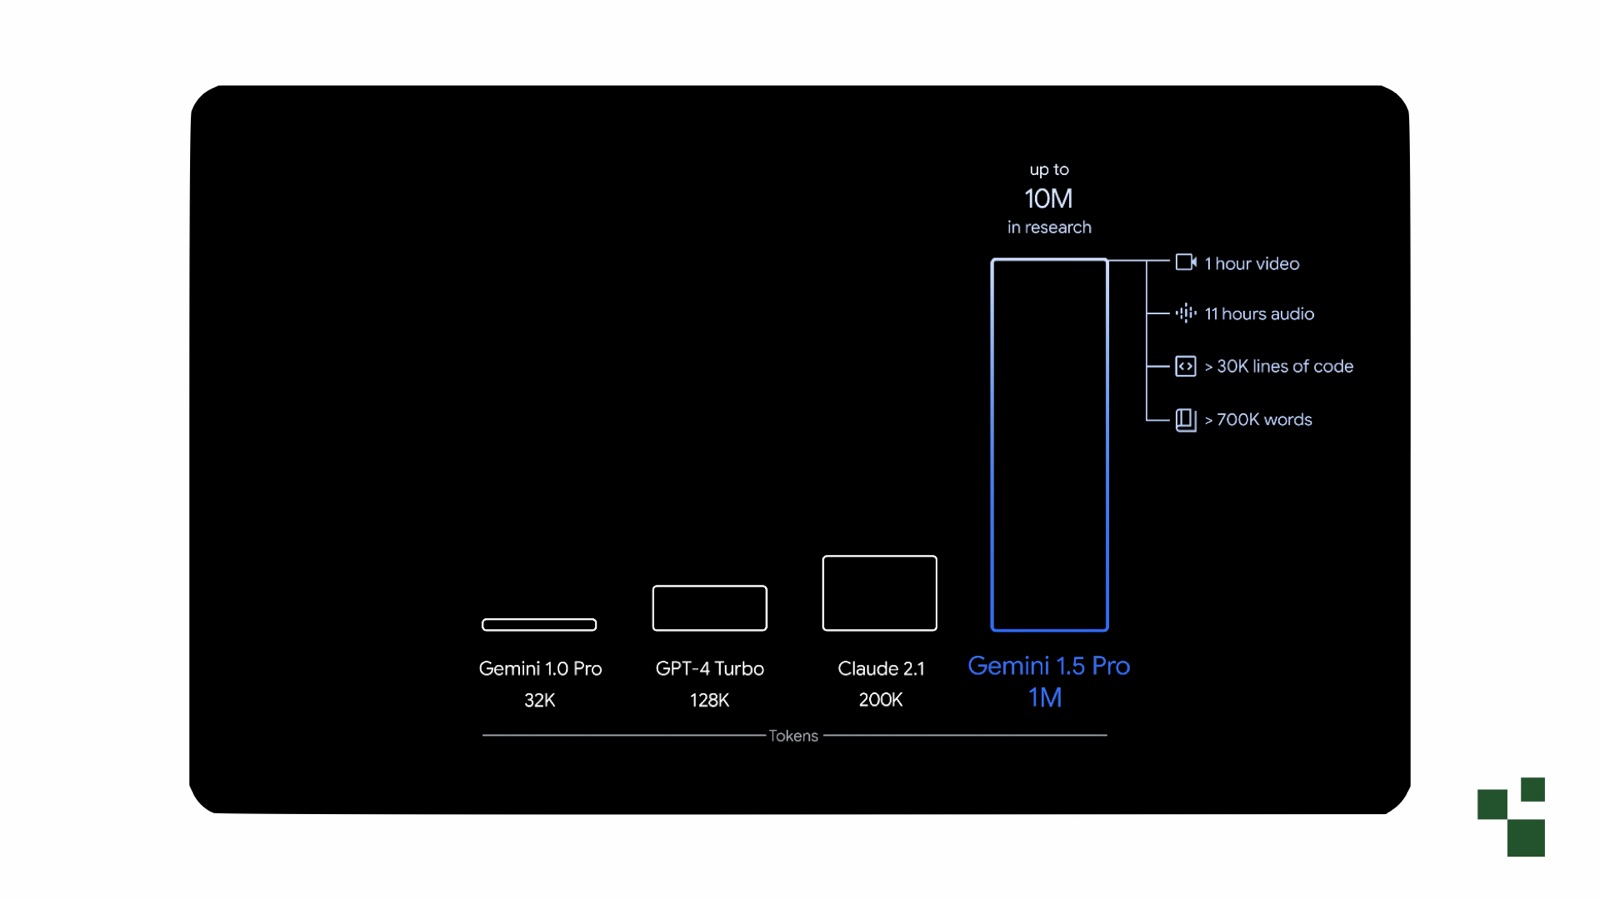
If you appearance at the promotion matter for Gemini 1.5 Pro, it was mostly concerning the million-token environment window. They were equal teasing a 10-million-token environment window example they had in the lab, that would arrive out soon.
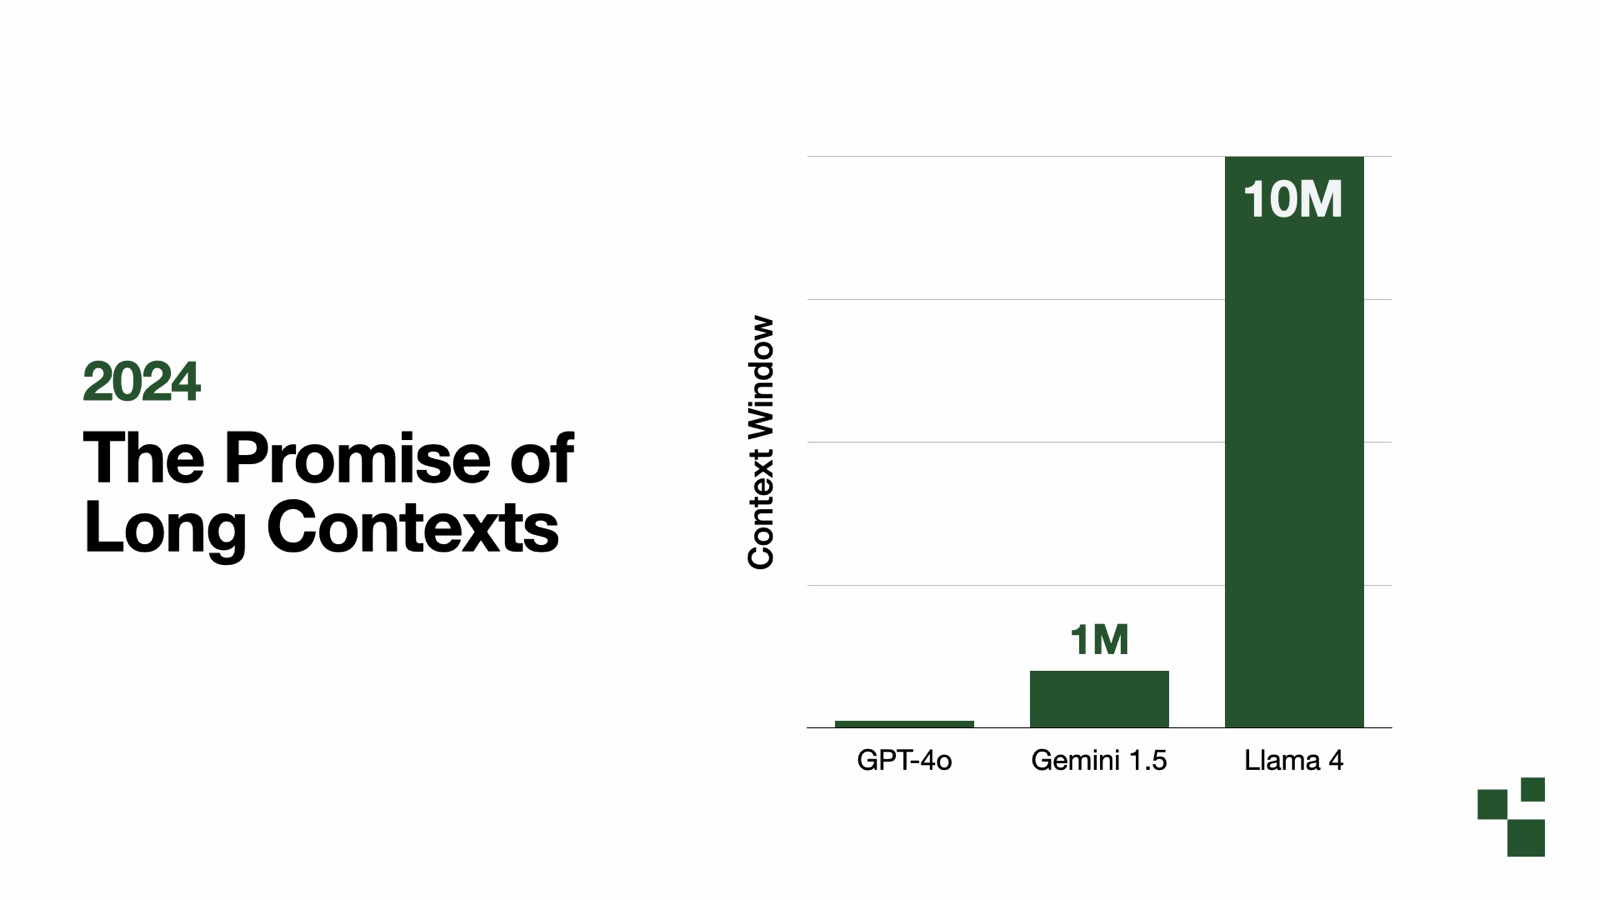
But they got beaten to the punch. Llama 4 Scout came out alongside a 10-million-token environment window, and well, it wasn’t fairly what we hoped. Inference was a challenge, and Scout never really caught on, and we never got another Llama.
But we motionless got a myriad tokens. That’s beautiful good. We’ll obtain it.
So this was the concise at the time: fair put everything in the environment and let the example kind it out.
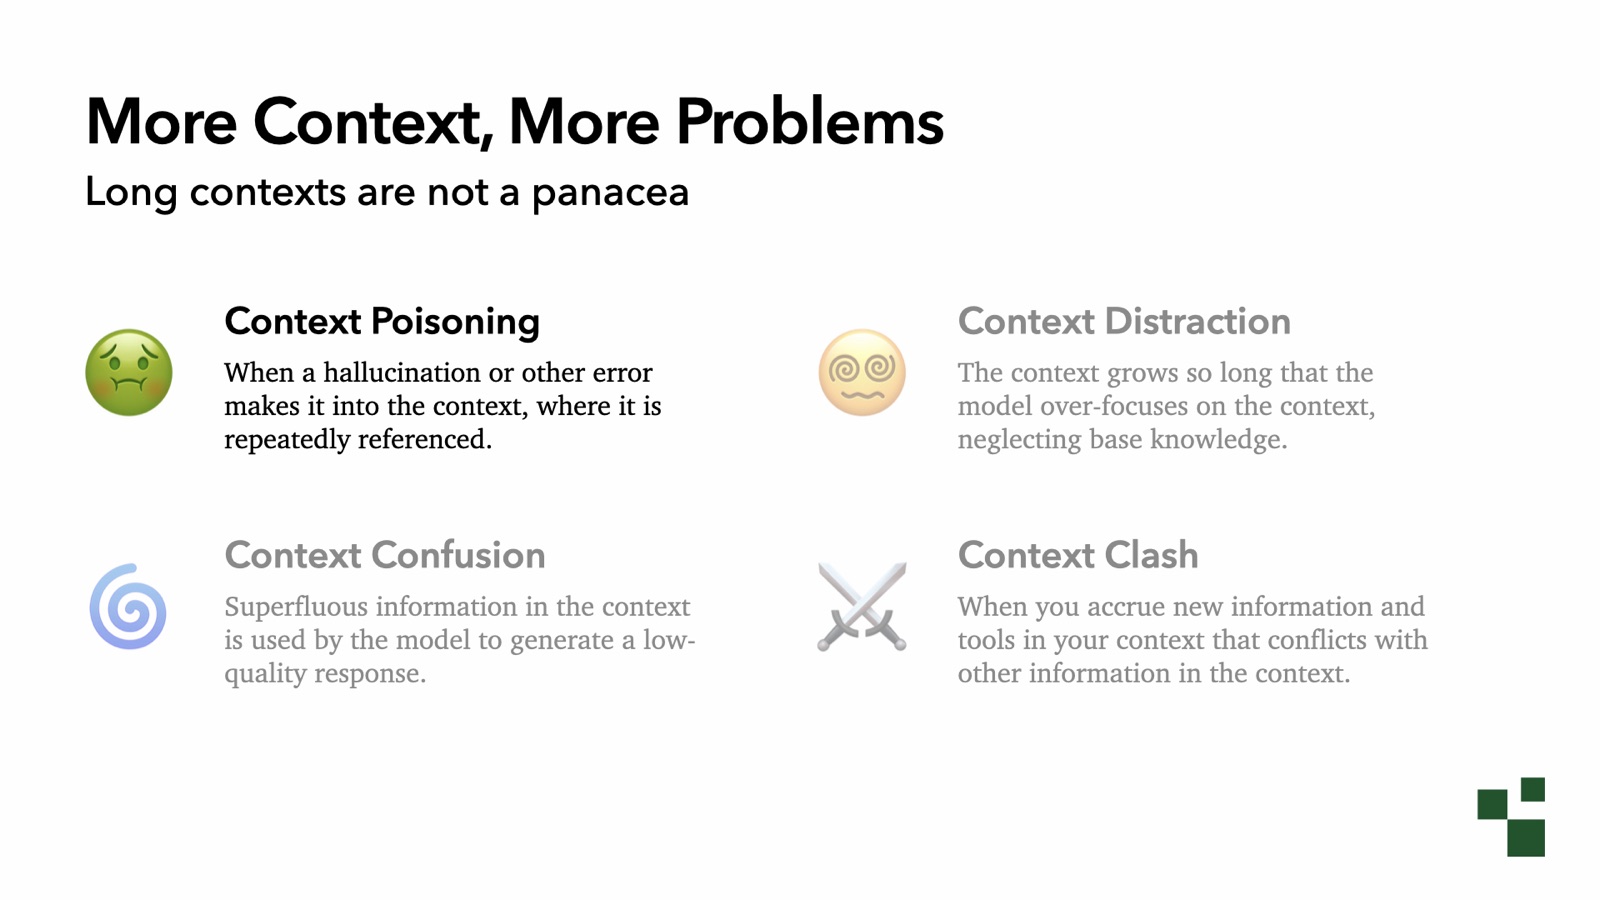
But alongside additional context, we had area for additional problems. Long contexts are not a panacea.
When I wrote concerning this, I identified four key nonaccomplishment modes.
Context poisoning is whenever item gets into the environment that shouldn’t be there. It could be a illusion or a bad fact, and the example can’t get former it.
Context distraction is whenever the environment grows so lengthy that the example starts to concentration on the environment complete its basis knowledge. We can see this in several really engaging ways.
Context confusion is whenever extraneous facts—things that don’t connect to the issue I’m operating on—come in and power the example in ways we don’t completely understand. This one’s really pernicious. We’re not going to dig into it today, but it’s one of my favorite nonaccomplishment modes. The example makes assumptions concerning who you are, and those assumptions power the answer.
Finally, context clash is whenever tool calls, skills, and another data inside your harness commencement to battle and activity against you in ways you didn’t expect.
(How many of you keep recollection on in ChatGPT or Claude? I rotate it off. I dislike it. Sometimes I’m talking concerning activity conversations; sometimes I’m talking concerning a project I’m doing alongside my son. The example volition obtain notes on both, mix up those contexts, and the disturbance grows from there.)
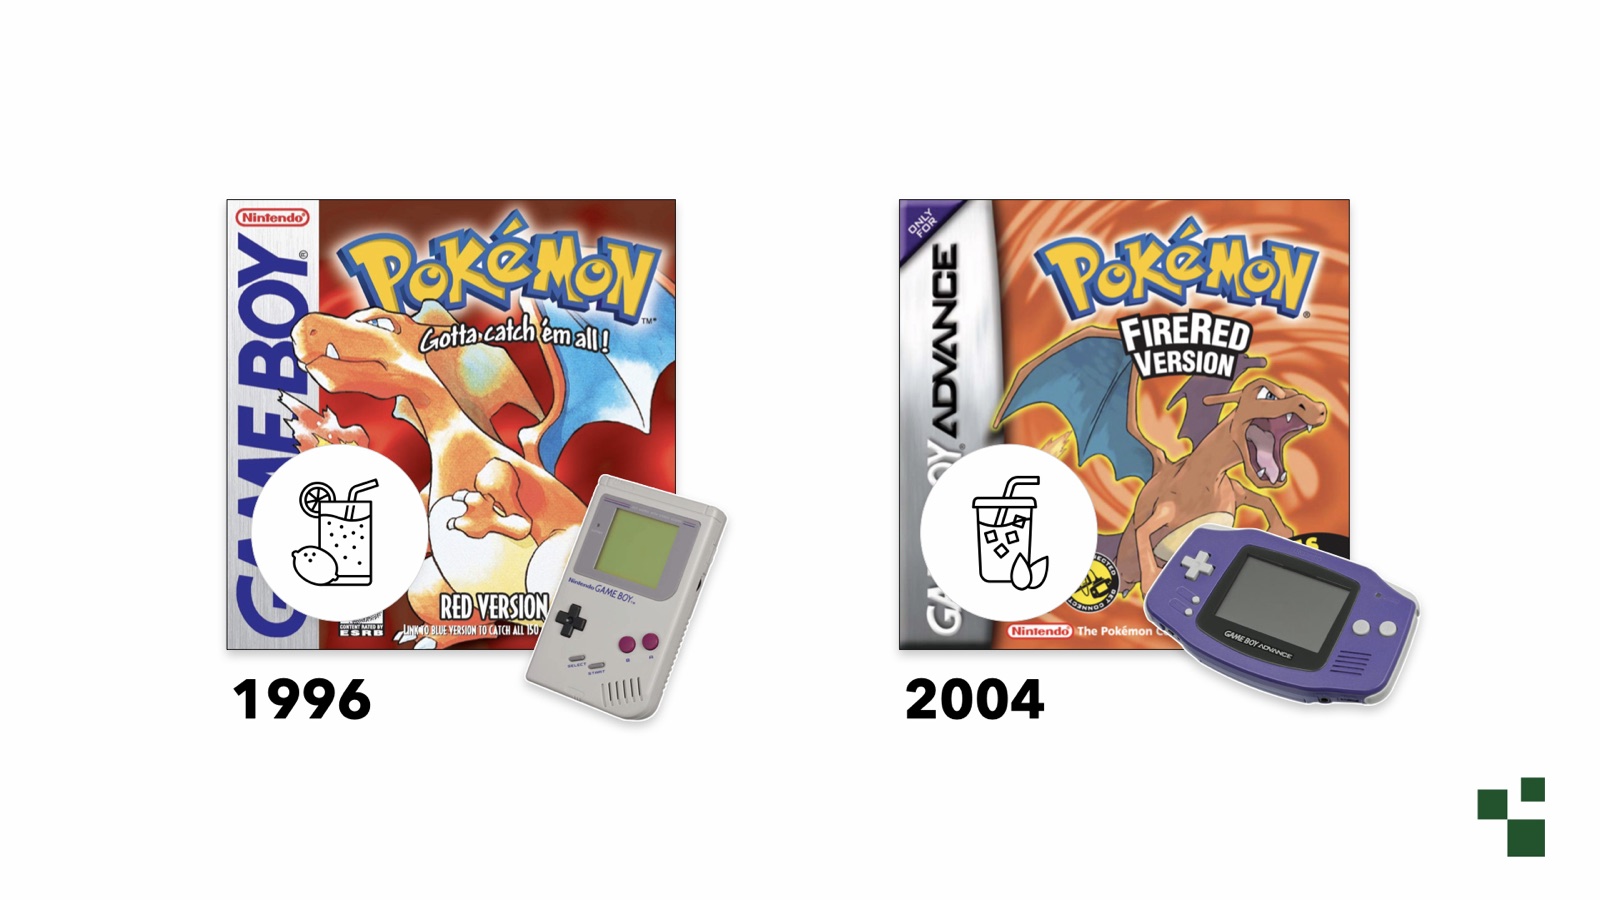
Let me provision you my favorite example of environment poisoning.
I’m going to date myself: I played the equivalent on the left. The one from 1996, for the first Game Boy. This is the archetypal Pokémon Red. It was in dreary and white.
In 2004, Nintendo released Pokémon FireRed for the Game Boy Advance. These were basically the identical game, apart from one had improved colors and audio.
But there was one subtle change. At several item in the two Pokémon Reds, to get former a safety guard, you have to provision them item to drink. A bribe. Quite the applicable instruction for children.
In the first game, you need to provision the thirsty defender lemonade. In FireRed, for several reason, they changed it to iced tea.
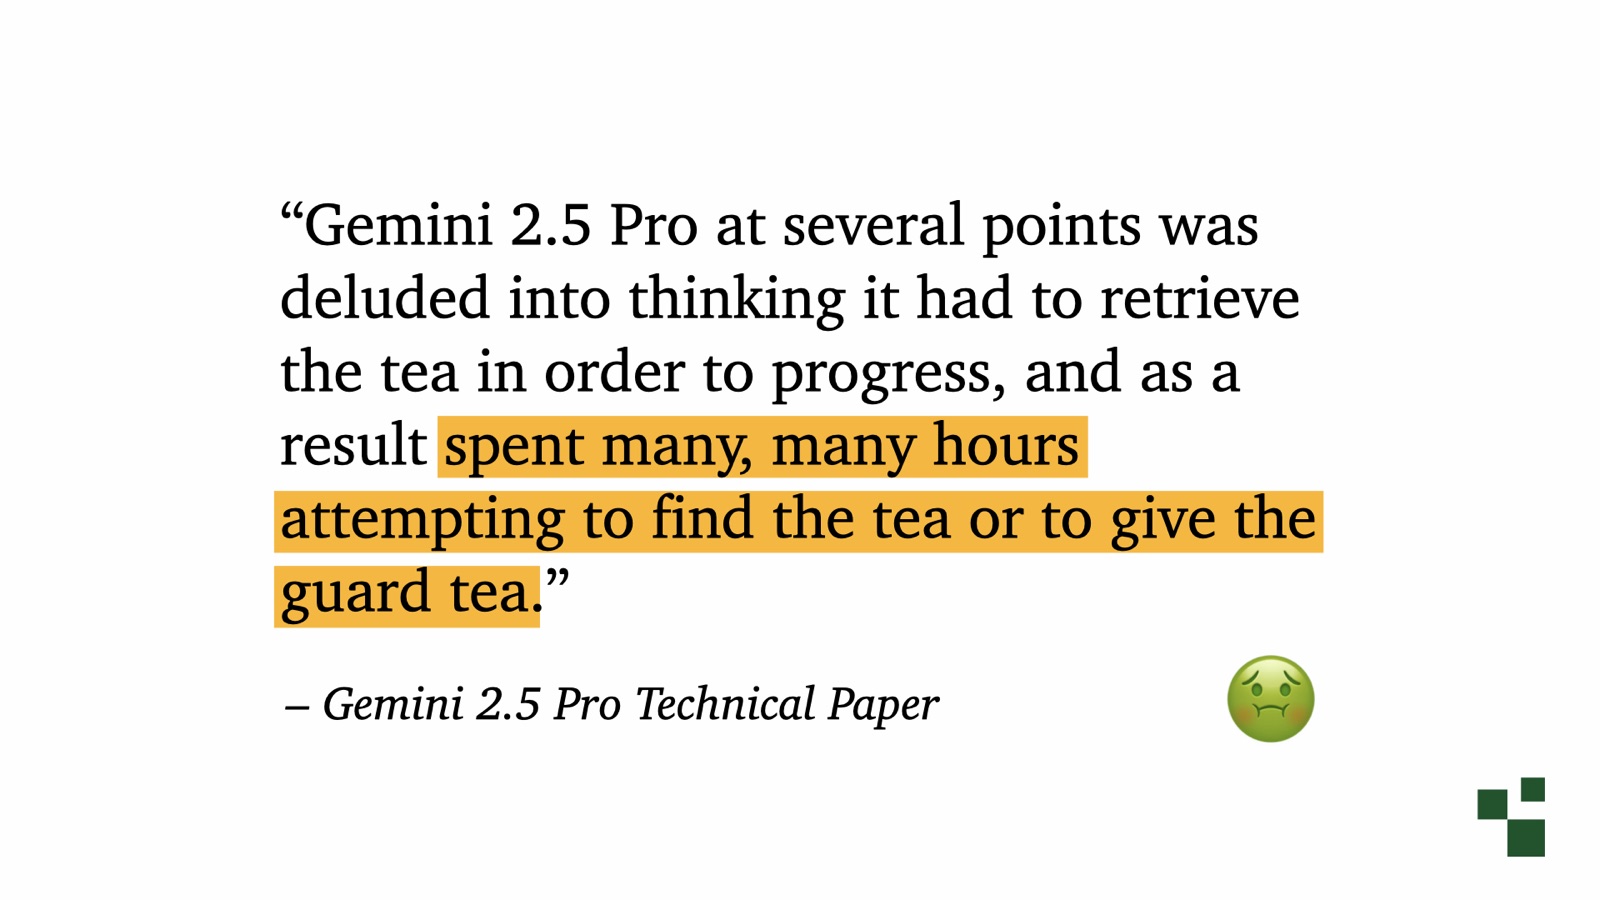
That created a issue for the agent. In the Gemini 2.5 specialized report, the researchers described how they had the example perform Pokémon. Researchers akin Pokémon as an delegate benchmark since it’s a fairly controlled surroundings and doesn’t move particularly fast.
Several times, Gemini 2.5 became convinced it needed to get tea, equal although it was playing the older game. The tea project for FireRed was in its weights, so it poisoned its context. It spent hours trying to discover or provision the defender tea. Once it had been added to its to-do list, the example could not get former it.
That’s environment poisoning. And it happens all the time.
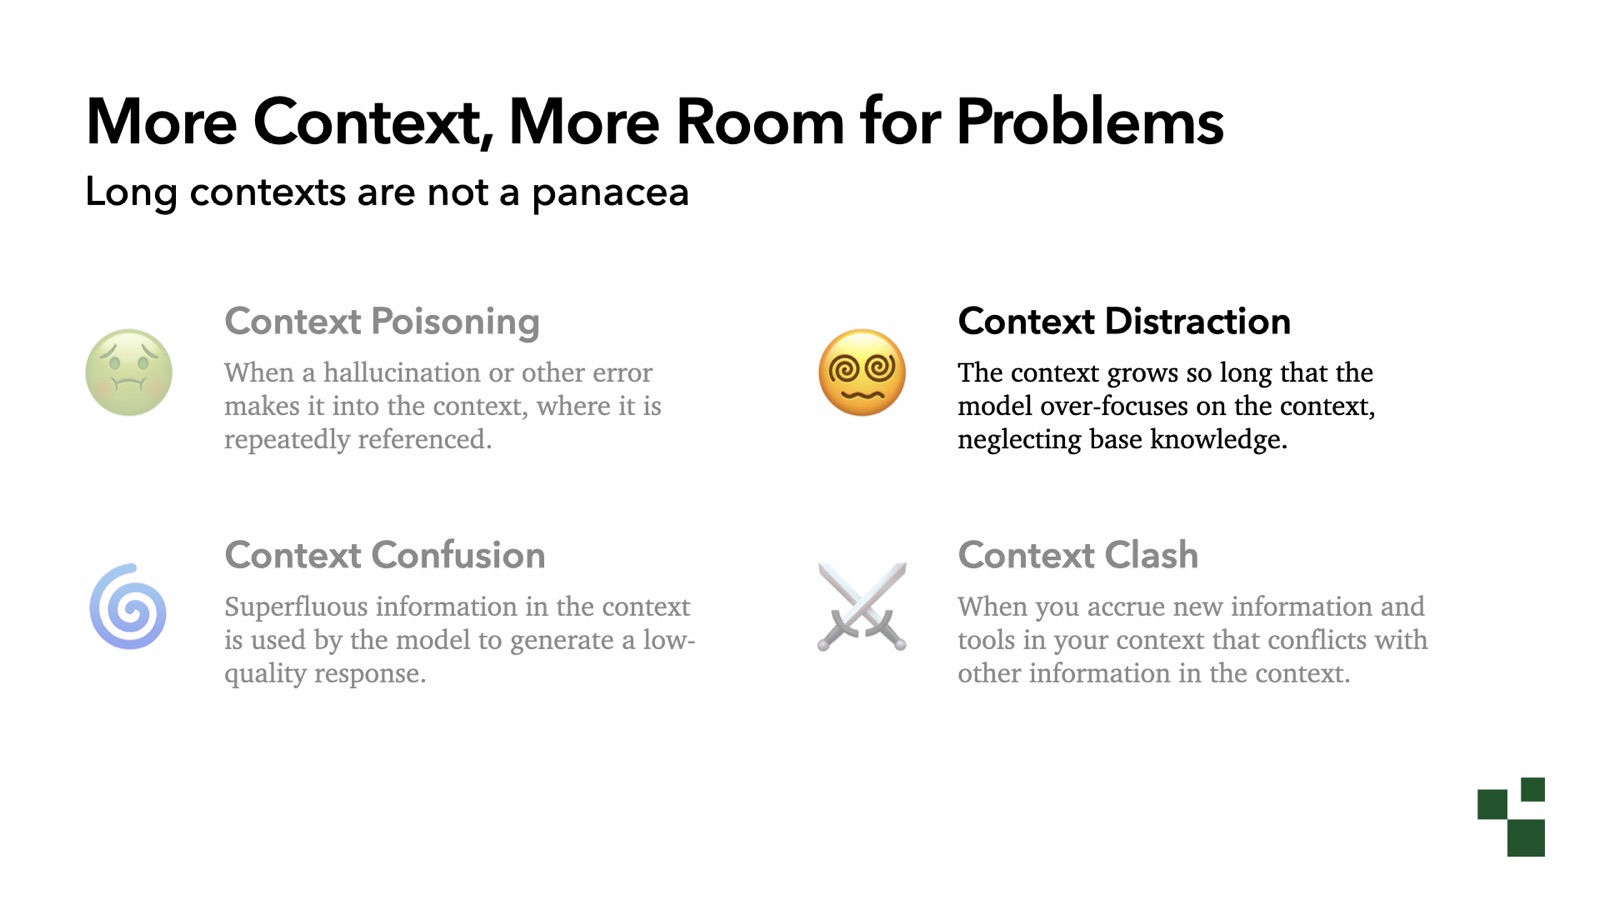
Another nonaccomplishment manner is environment distraction. This is one of my favorite demonstrations, and the investigation came out following I wrote the first piece.
As your environment gets longer, how does your behavior change? Quick question: how many of you, whenever you’re coding, let the environment go all the way to a myriad tokens? Fill it all up?
(About fractional the area raised their hands!)
Wow, that’s additional than I expected.
For me, about 200,000 or 300,000 is anywhere I commencement looking. I’ll check, see it’s at 250,000, and think: I’ve got a big job coming up. I’m going to reset and commencement fresh. Let me display you why this matters.
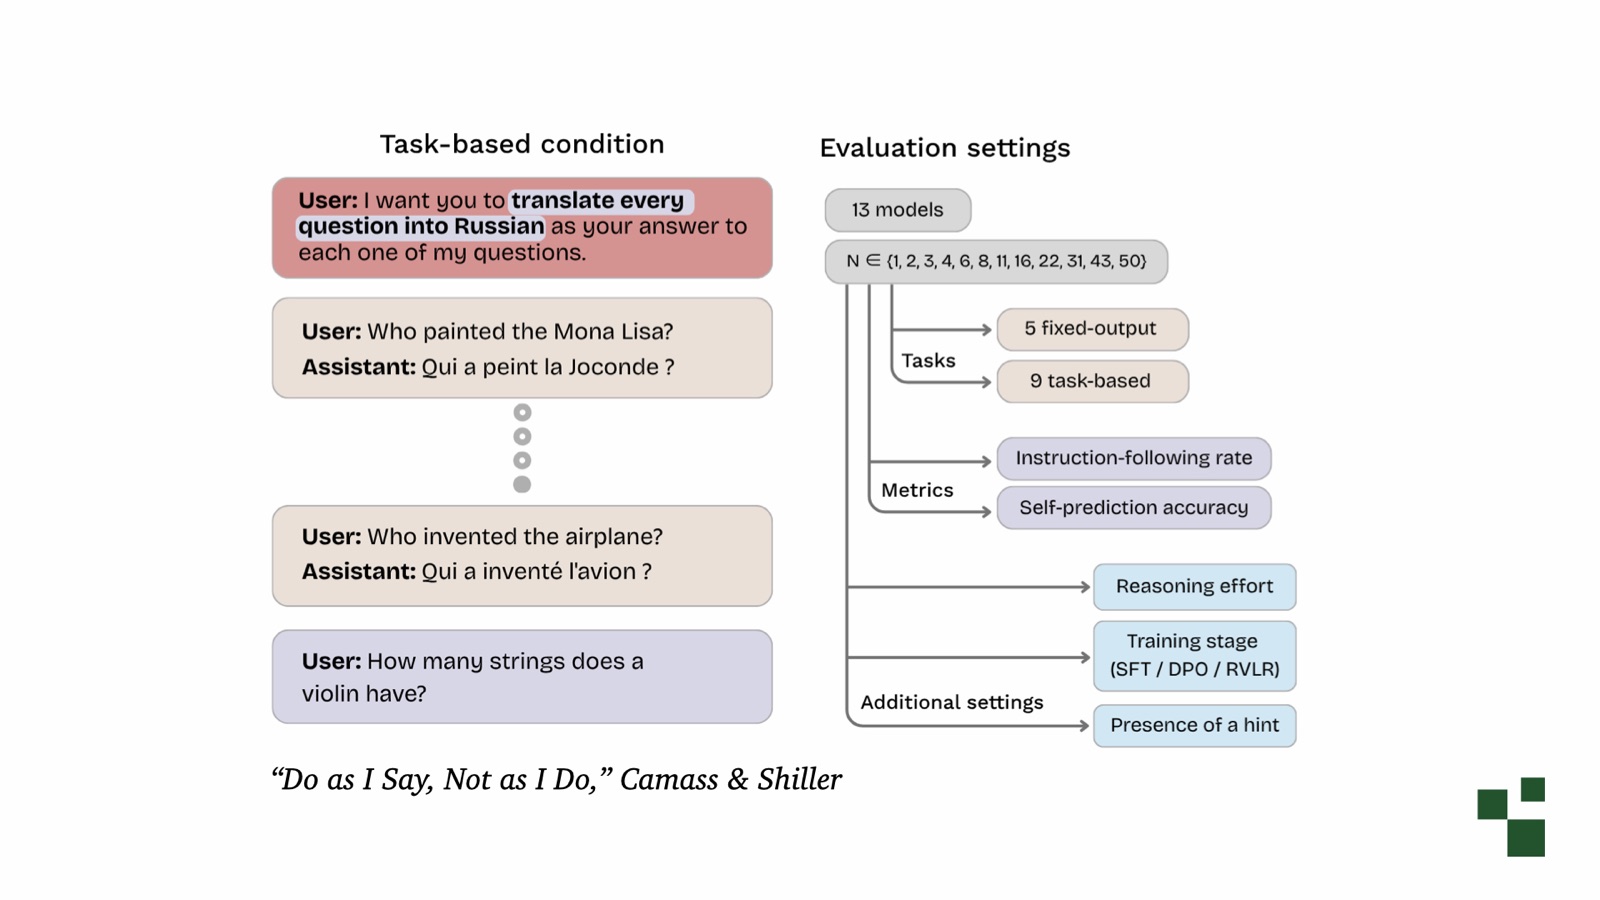
Recently, I stumbled on a document that wonderfully illustrates environment distraction: Do as I Say, Not as I Do, by Carolina Camassa and Derek Shiller.
Their test is a small contrived, but it’s helpful for thinking concerning how this happens. They provision the example an instruction: “I desire you to translate all inquiry into Russian as your answer to all of my questions.” Then they current a bunch of examples that are oppose to these instructions. In this case, many questions alongside answers in French.
These aren’t new instructions. They’re fair examples sitting in the conversation history.
Then they ask the example a question. Will it prosecute the instructions?
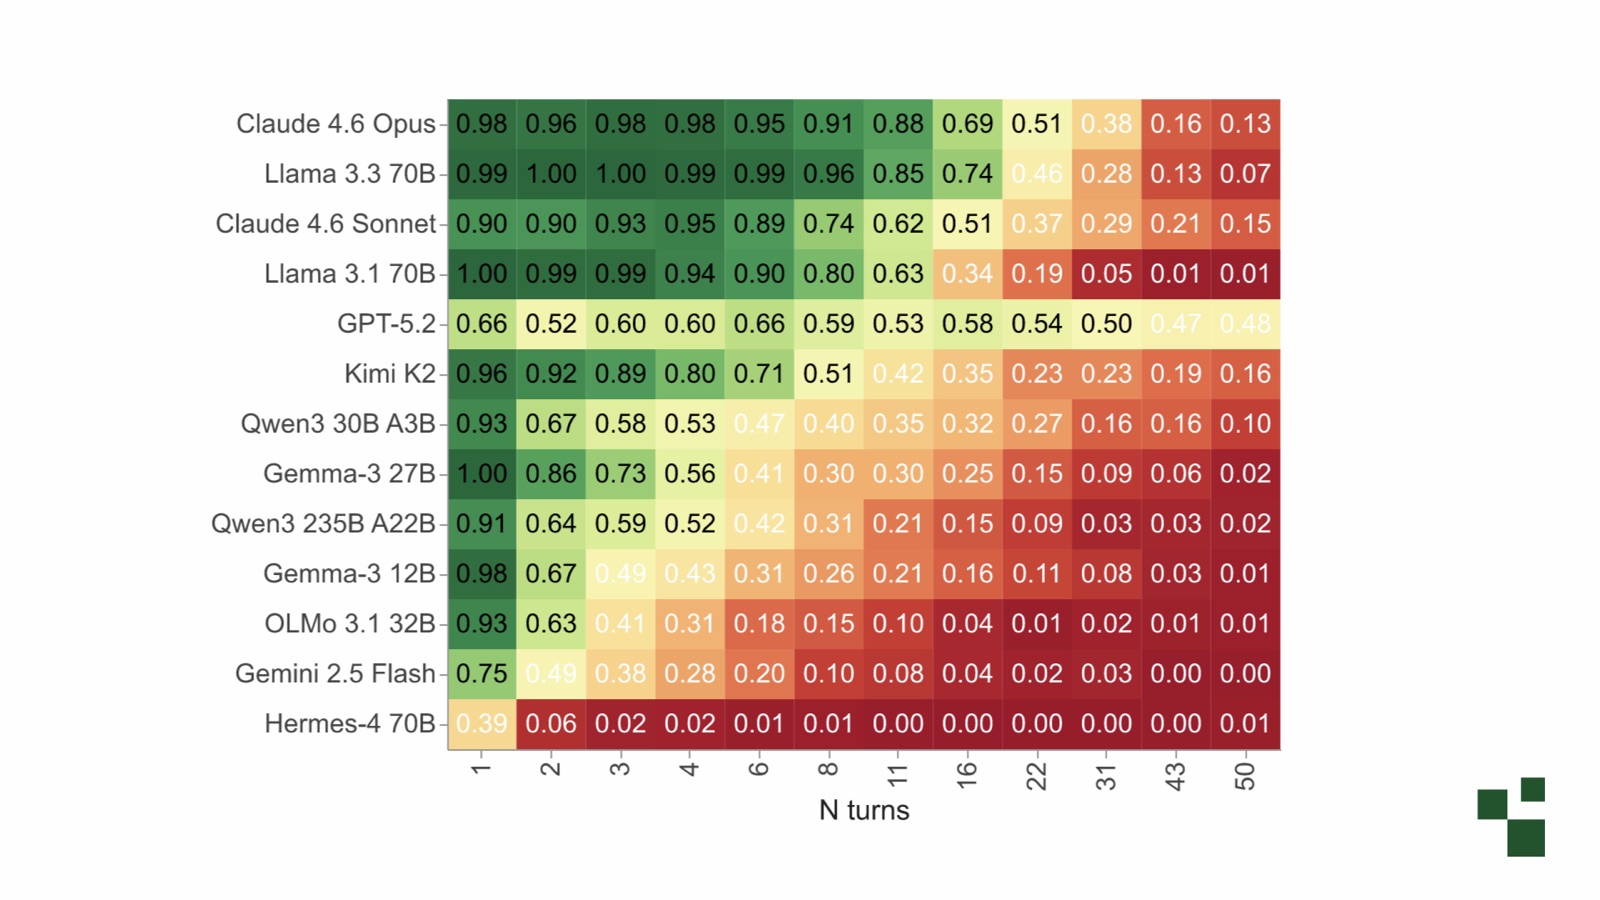
How frequently does the example react in Russian, as it was instructed to, and how frequently does it react in French, as it’s seen in the examples?
The x-axis on this matrix enumerates how many bad examples were present. The y-axis is the example being tested. The figures in the intersections are the percent of times the example adheres to the instructions, fairly than following the examples.
It turns out this affects all model! For smaller models, akin Gemma 3 12B, following fair a few contradictory examples, the example follows the education small than fractional the time. With Opus 4.6, which is an amazing model, it takes many additional examples, but it happens there too.
Imagine you’re going rear and onward on a front-end design, trying to tweak CSS and get a component exactly right. How many bad examples have you seeded in that exchange? Those examples commencement to power the model. As your environment grows, things autumn apart.
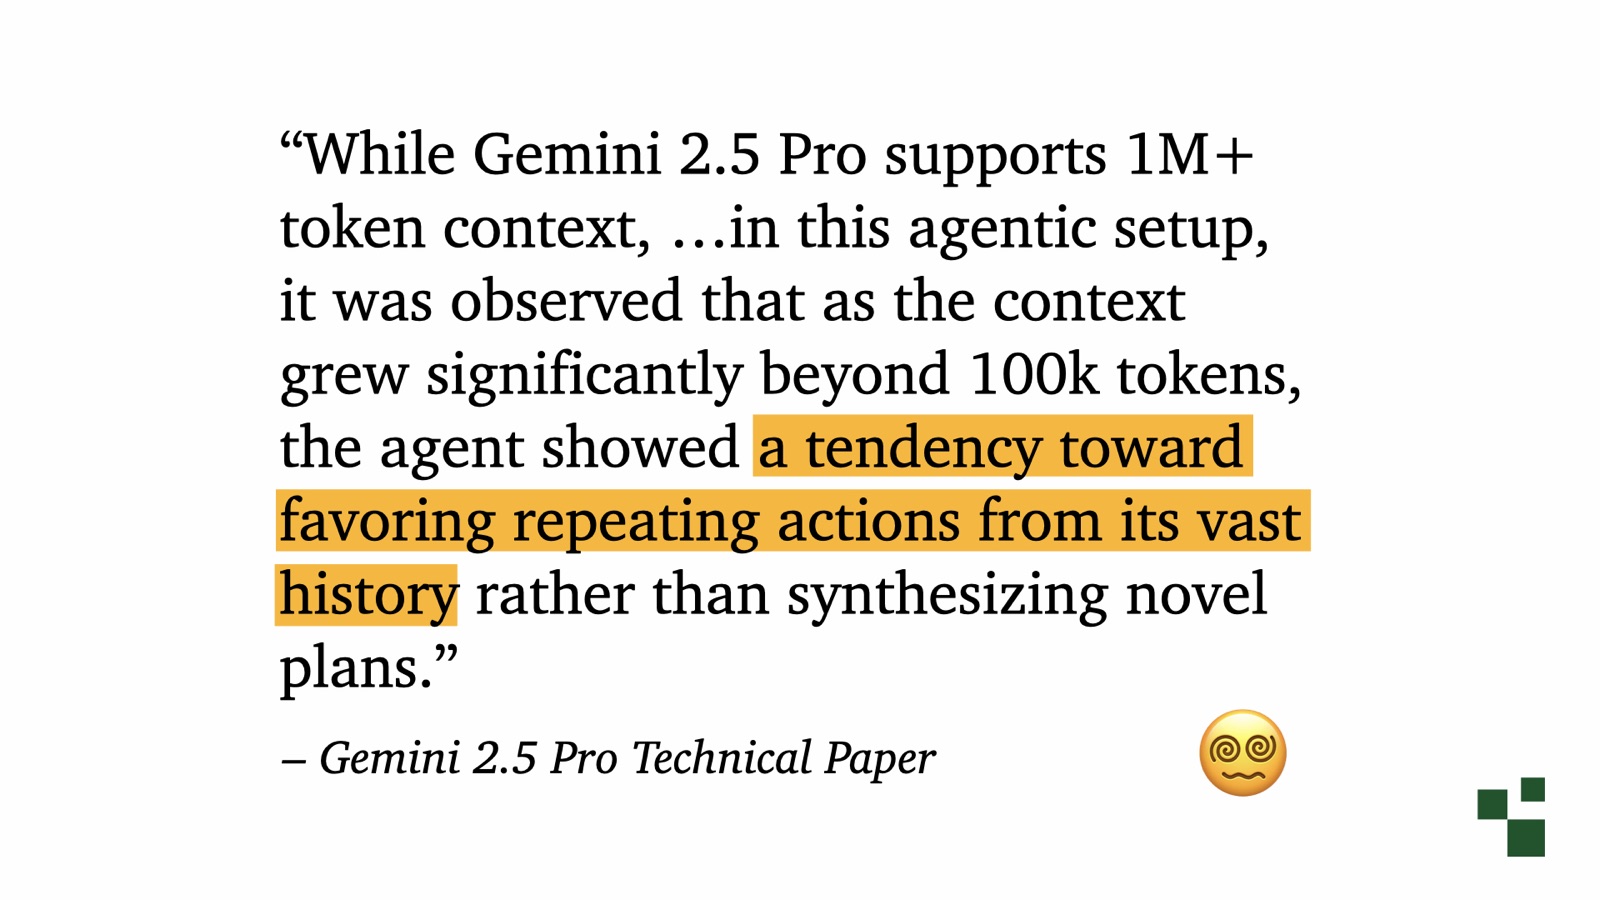
Gemini 2.5 ran into this too, during playing Pokémon.
Remember, Google was really arrogant of its million-token environment window. The document suggested that two myriad tokens were about the corner. But buried in the appendix was this observation: formerly the environment grew considerably beyond 100,000 tokens, the delegate began repeating actions from its former alternatively of synthesizing new plans.
I’m convinced the promotion group never peruse the appendix. I affection this specialized report.
Long contexts let you fit in additional information, but they additionally let you fit in additional errors. Long contexts weren’t a panacea.
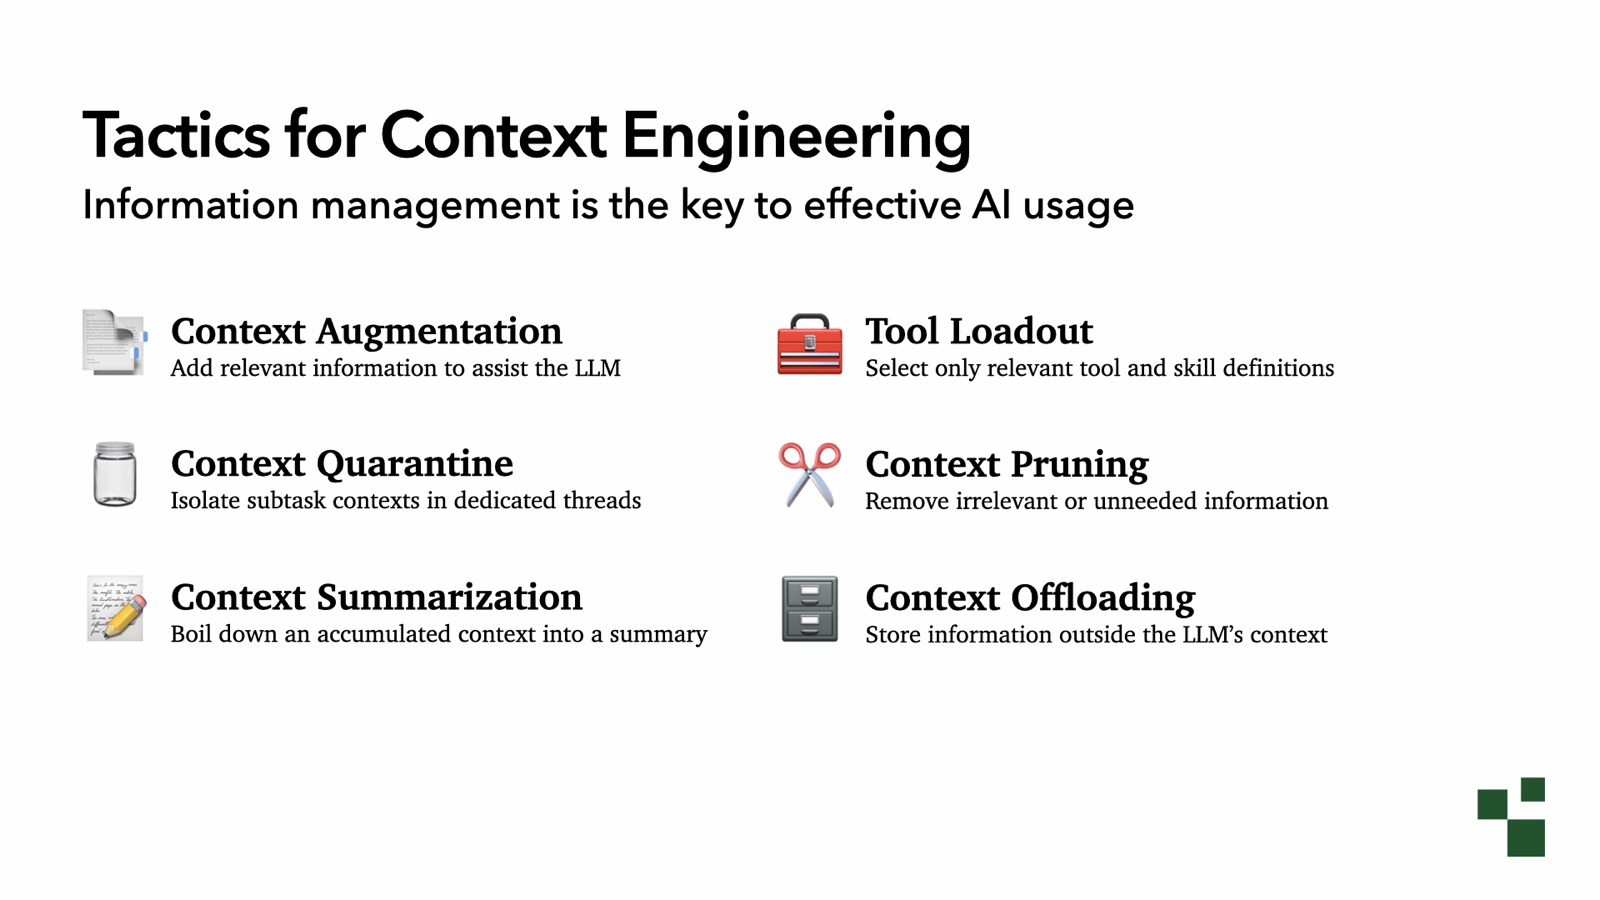
Thankfully, we’ve developed a beautiful fine toolbox. Surprisingly, equal as new challenges have emerged (we’ll get to those in a minute), this set of tools has remained the same.
These six of them.
You have context augmentation: RAG, skills, and another ways to bring in the data applicable to the problem.
You have tool loadout: selecting which tools and skills to disclose so you don’t overload the model. I was lately talking to an endeavor squad whose agents had abruptly started performing terribly. We investigated and discovered their endeavor application was loading 600 skills for all engineer at startup. We figured they should likely display those, alongside a loadout function.
Third is context quarantine: subagents and equal agents, anywhere you commencement item alongside a blank former but let it activity in the identical environment.
Fourth is context pruning. Claude Code and Codex do this, sometimes without you equal noticing. Early stages of compaction frequently band out tool results you no longer need.
Fifth is context offloading: storing data in the environment, specified as Markdown records or a database, so you can admission it later.
And sixth is context summarization, which everyone knows as compaction.
These are the tools, and we’ve increasingly moved them into the harness.
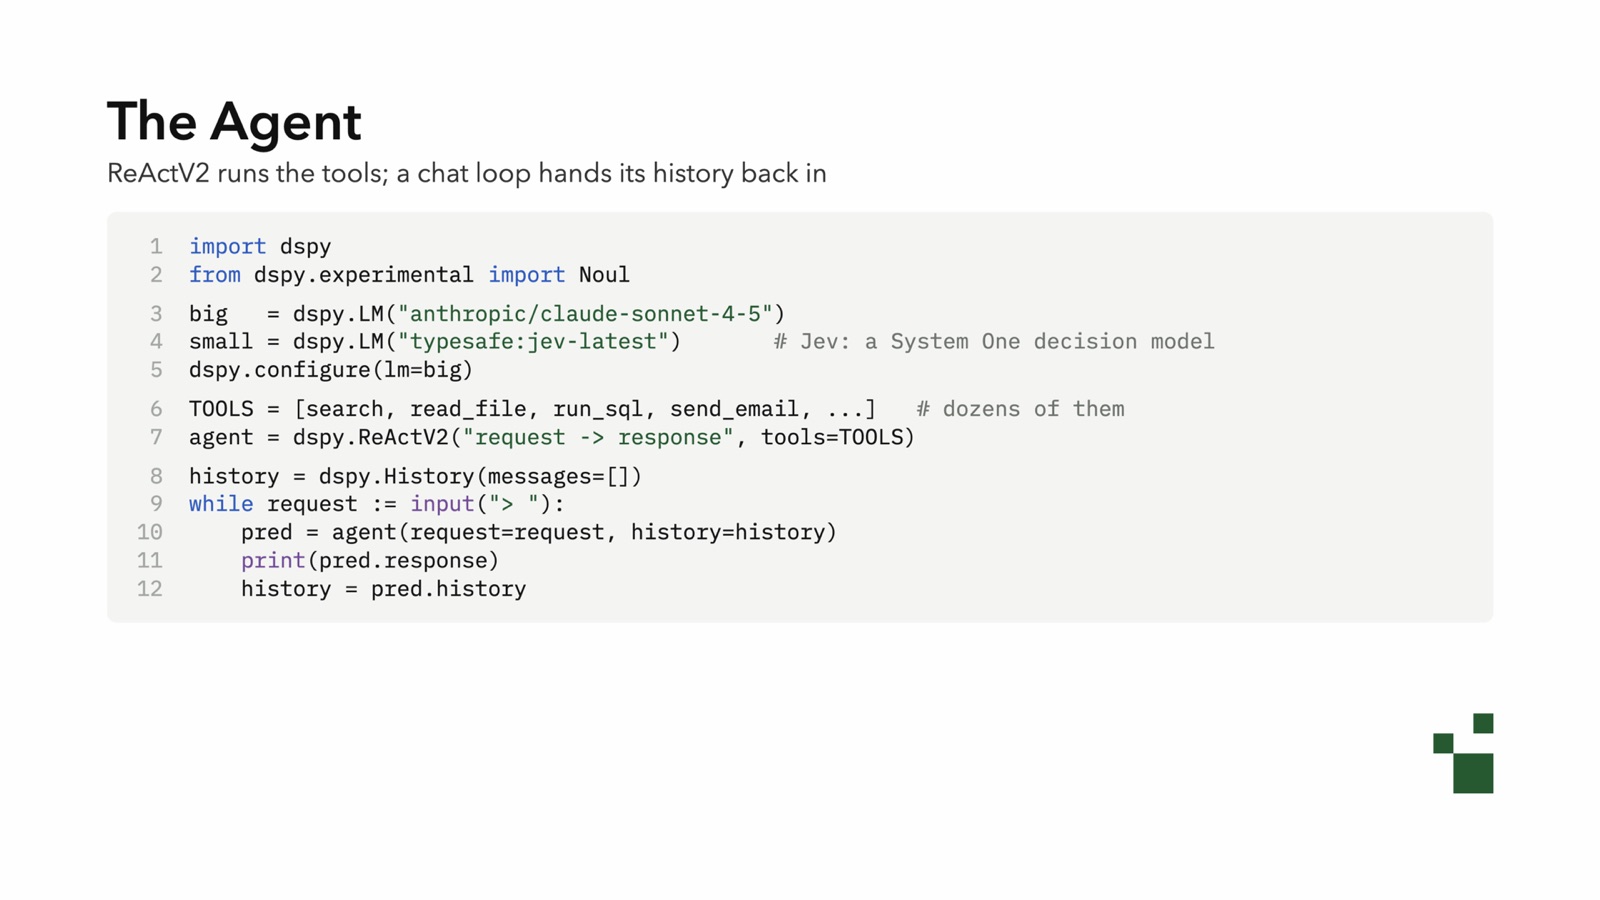
Let’s appearance at an example harness, to display how uncomplicated these patterns are.
I’m really passionate concerning DSPy. I think it’s an incredibly readable and productive way to build AI workflows and agents. And it’s additionally a awesome tongue for merely specifying behavior, so it’s fine suited to this demonstration.
An delegate is a during loop. Here we’re using a ReAct module: we provision it a request, we desire a response, and we provision it several tools. Those tools are fair Python functions.
For this demo we have a big example (in this case, Claude opted for Claude Sonnet 4.5, fine fortune alongside that!). And I’m using a Jev as the small model: a small decision example that makes lightning-fast decisions. You could toggle in a small LLM in this example, and everything would motionless work.
We have a during iteration that takes input, sends it to ReAct, and carries the accruing former forward. This is an delegate in concerning a dozen lines using DSPy. It would be equal small if you took out the additional model.
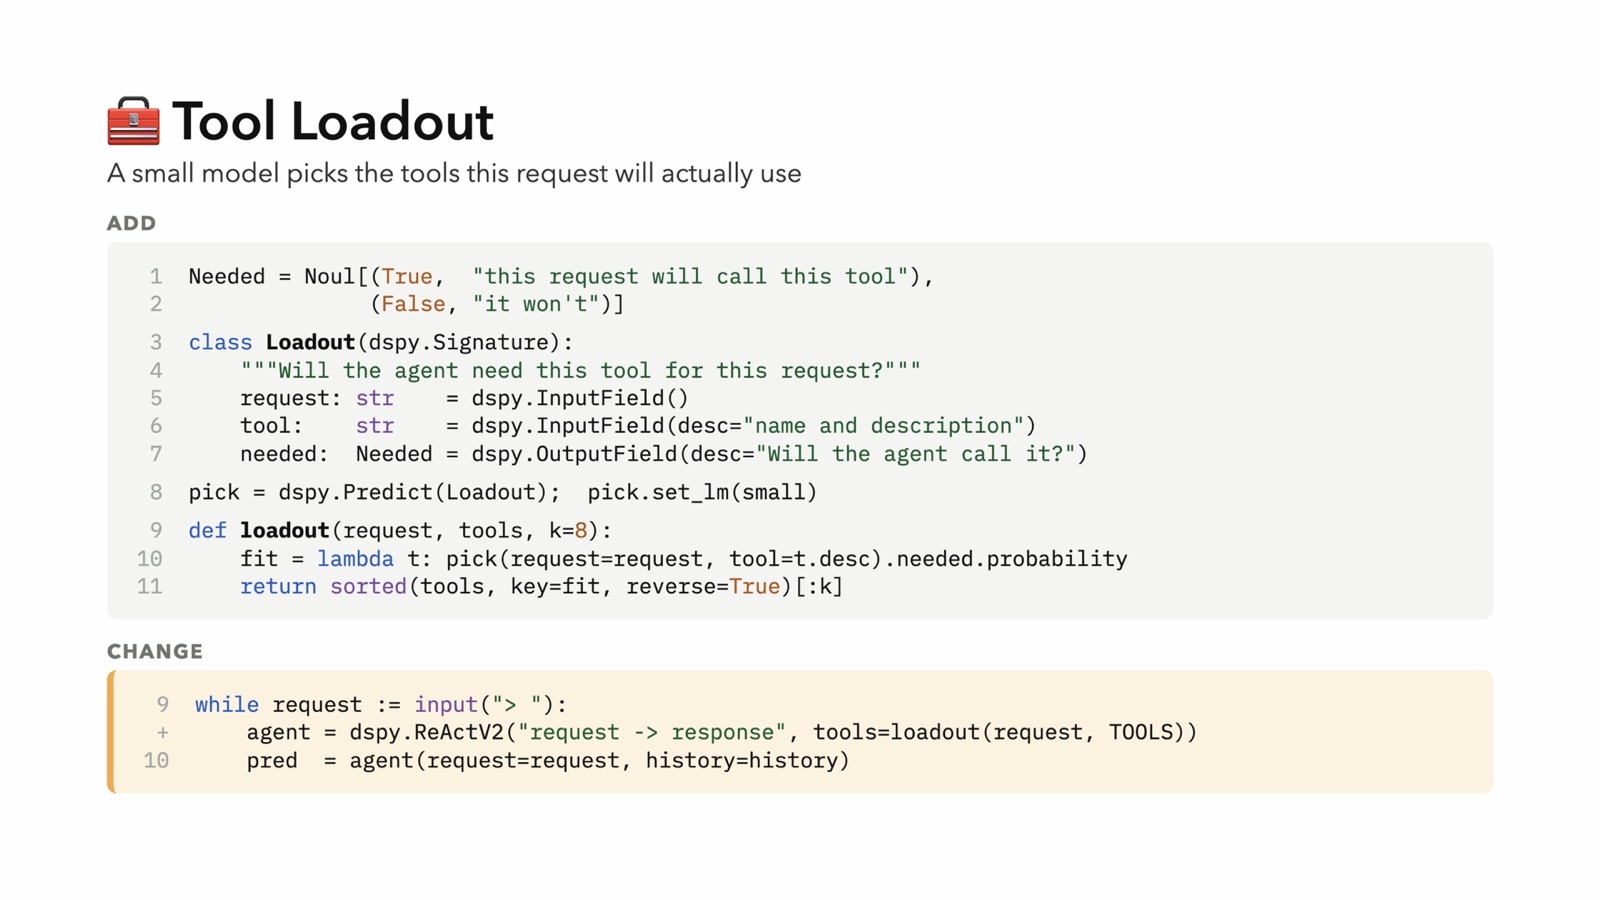
How do we do tool loadout? It’s fair a function.
We current Jev alongside the petition and a tool, asking if it’s needed for this task.
Jev is accelerated adequate that we can do this one tool at a time; it’ll be fine. We cover this in a loadout function that iterates through all the tools and asks if all is needed, afterward returns the top-ranking subset. That’s it.
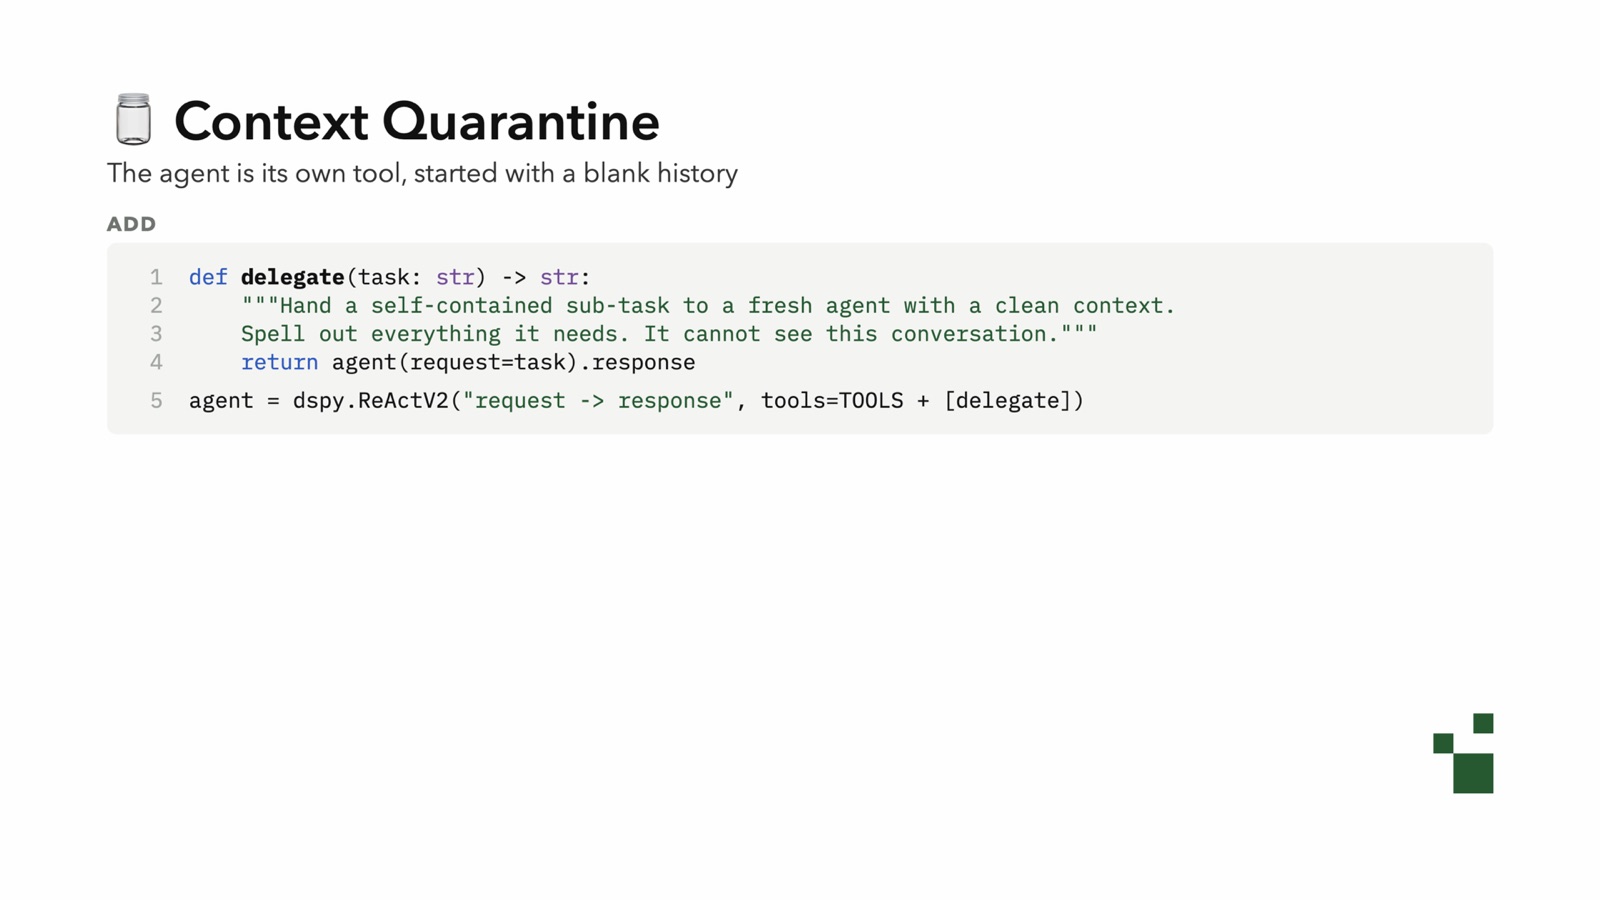
With environment quarantine, it’s fair a subagent. You disclose an delegate as a tool that the chief delegate can use, and it starts alongside a blank history.
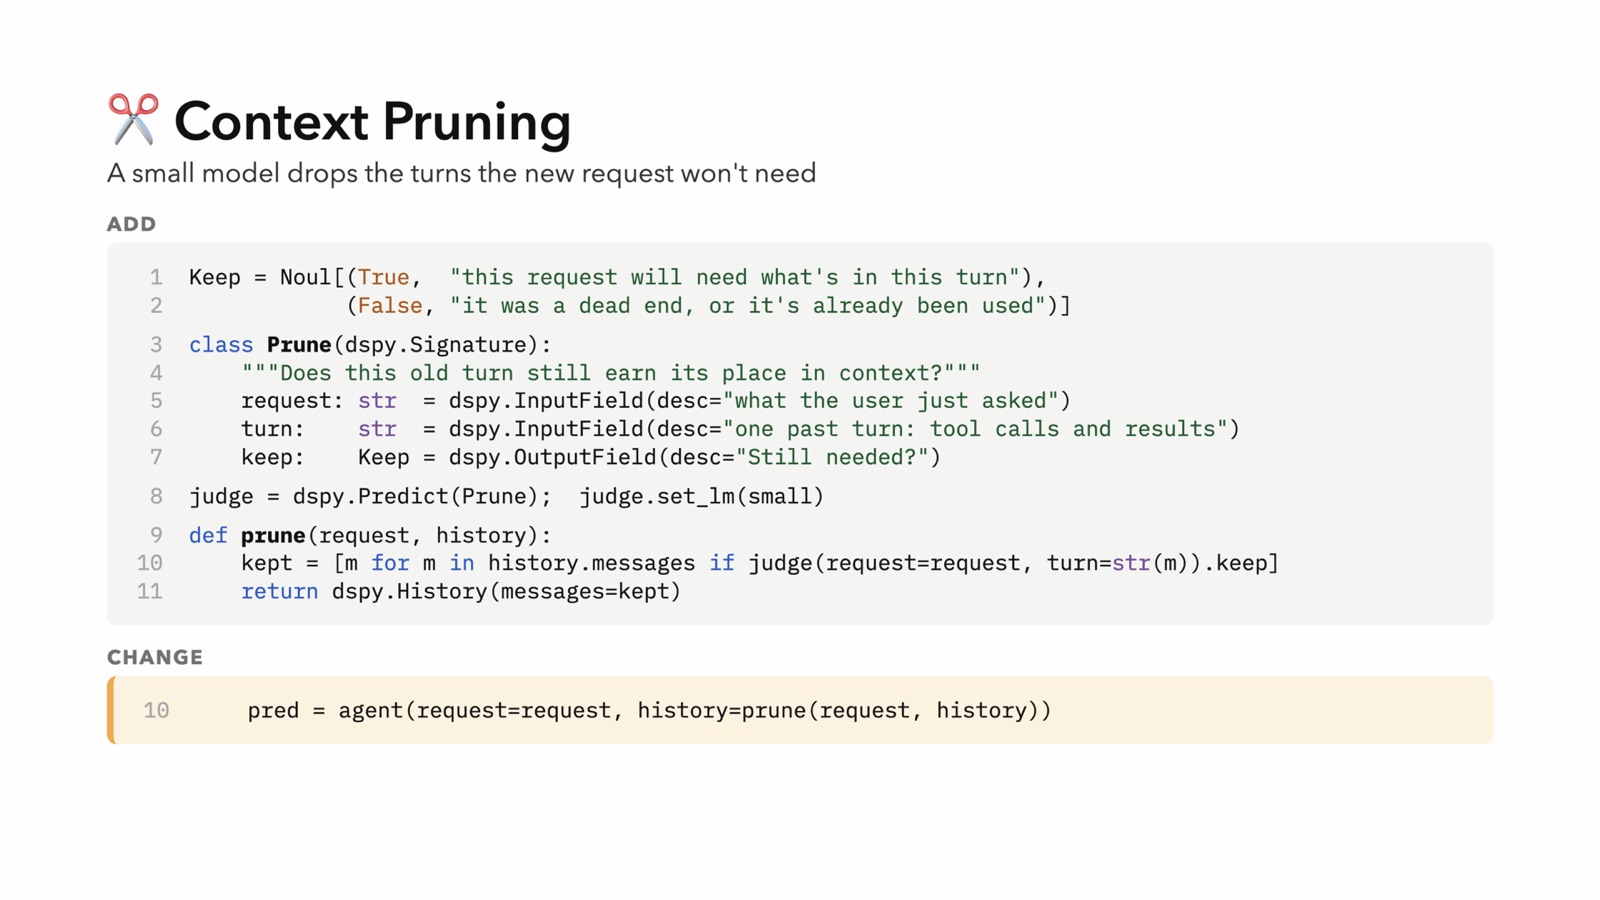
With environment pruning, we’re strolling through the history, passing all rotate to Jev, and asking: is this motionless needed? If not, cut it.
You can be as coarse or as elegant as you desire here. Just intellect your immediate caching.
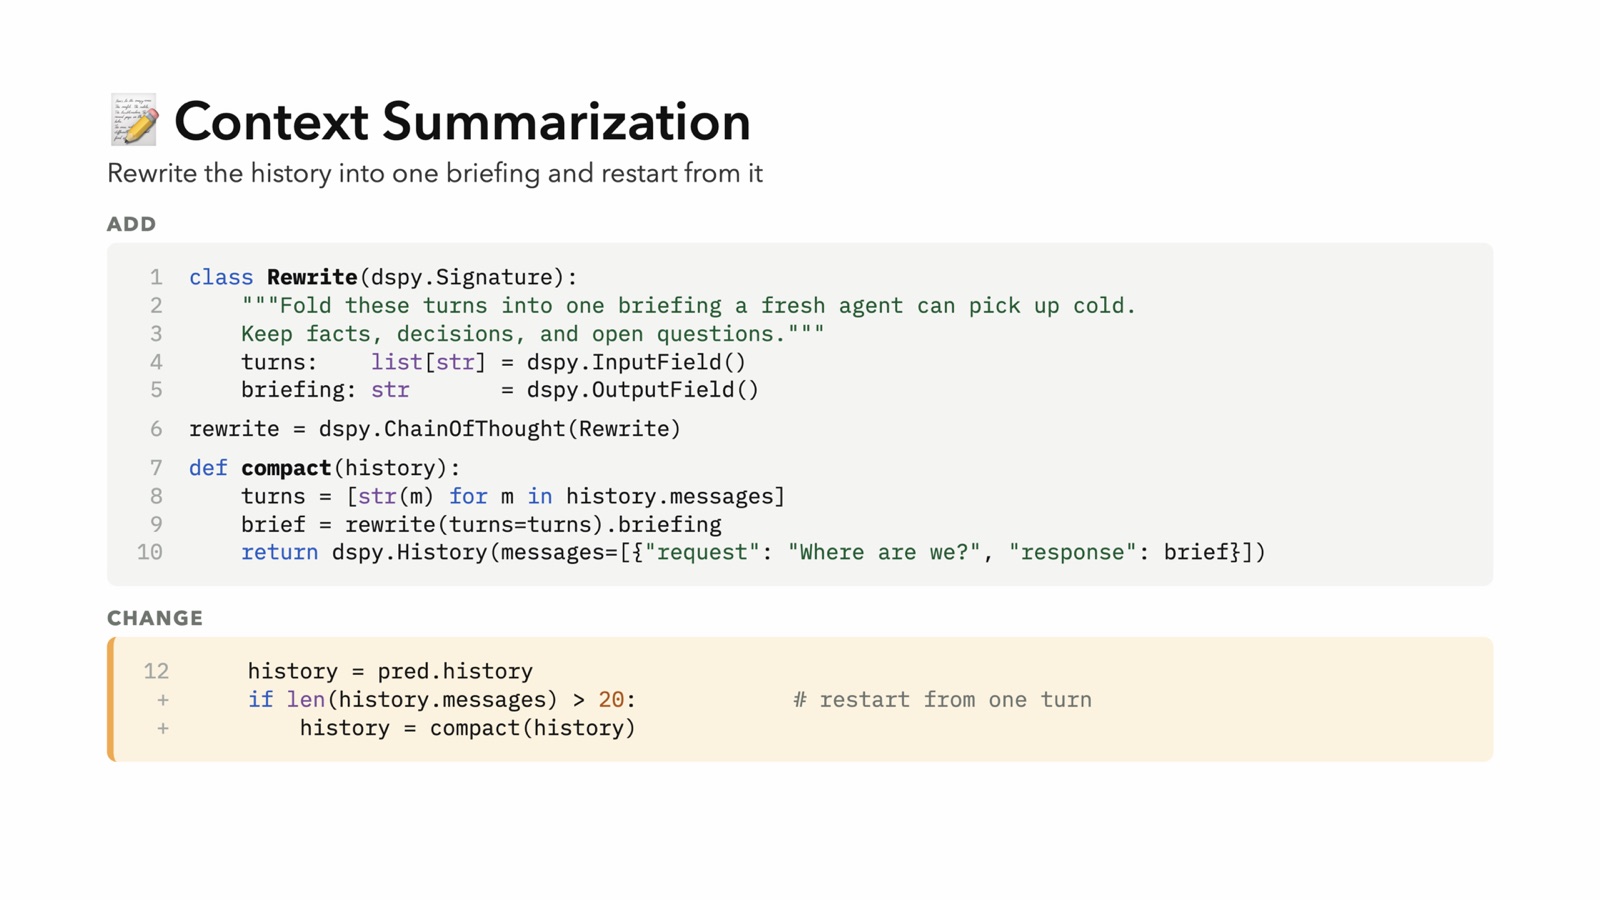
We can additionally rewrite the former alongside compaction. Take the old turns, create a summary, and commencement the new environment from that summary.
One of my favorite variations lately is checking what matters before you compact. You use Jev, or another decision model, for the archetypal continue to fairness what’s relevant. Now you’ve got a smaller subset of the history, and you summarize that. It’s a uncomplicated additional step, but it makes the summary additional useful.
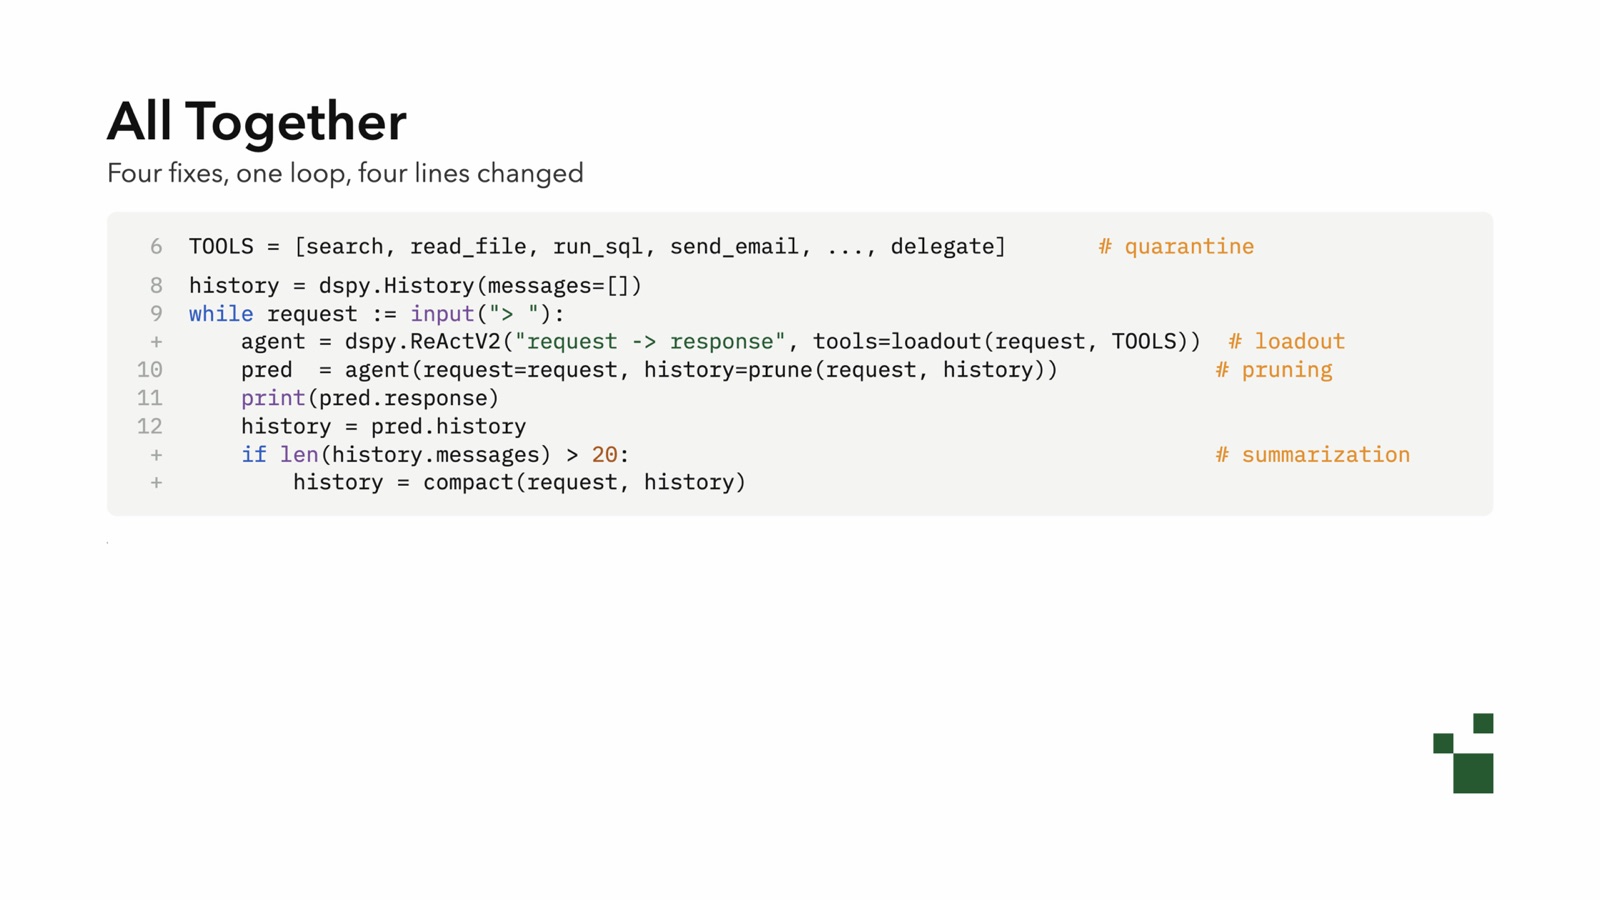
Put it all together and it’s concerning 16 lines of changes. Four fixes, one loop. These are the moves we have in the harness. It’s really remarkably simple.
What isn’t uncomplicated is our language: how we conversation concerning this stuff. It’s really difficult to keep pace; it changes all day.
One of my favorite quotes is from Stewart Brand, which I think concerning all the time:
If you desire to cognize anywhere the forthcoming is being made, appearance for anywhere tongue is being invented and lawyers are congregating.
Certainly applies here! But as our tongue has changed, our goal has remained the same.
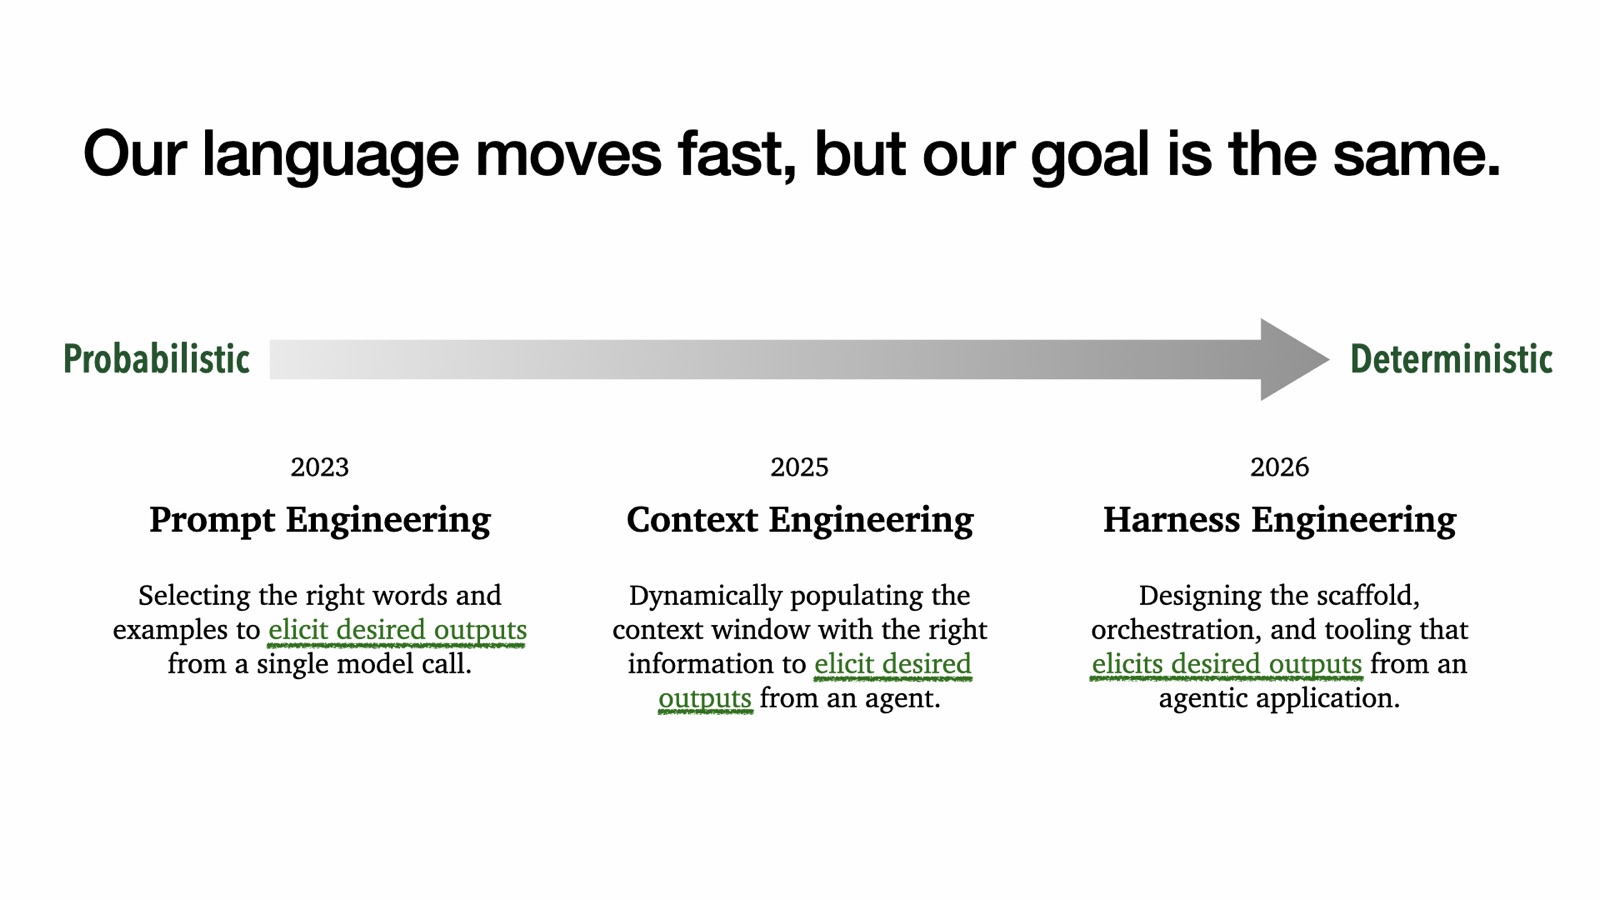
In 2023, we called choosing the correct data to get the correct reply prompt engineering.
In 2025, we called it context engineering, apart from that now it was additional automated. It wasn’t fair you penning the prompt; it was your scheme dynamically assembling the context.
Then, as we moved additional of these tools out of the environment and into code, we started calling it harness engineering.
But the job is the same. We’re moving additional and additional of the activity of assembling environment from probabilistic example calls to deterministic code.
I’ve shown you 2024. Let’s go to 2026.
We’ve moved these environment fixes into the harness. What do we desire next? We desire agentic models that can run our harnesses.
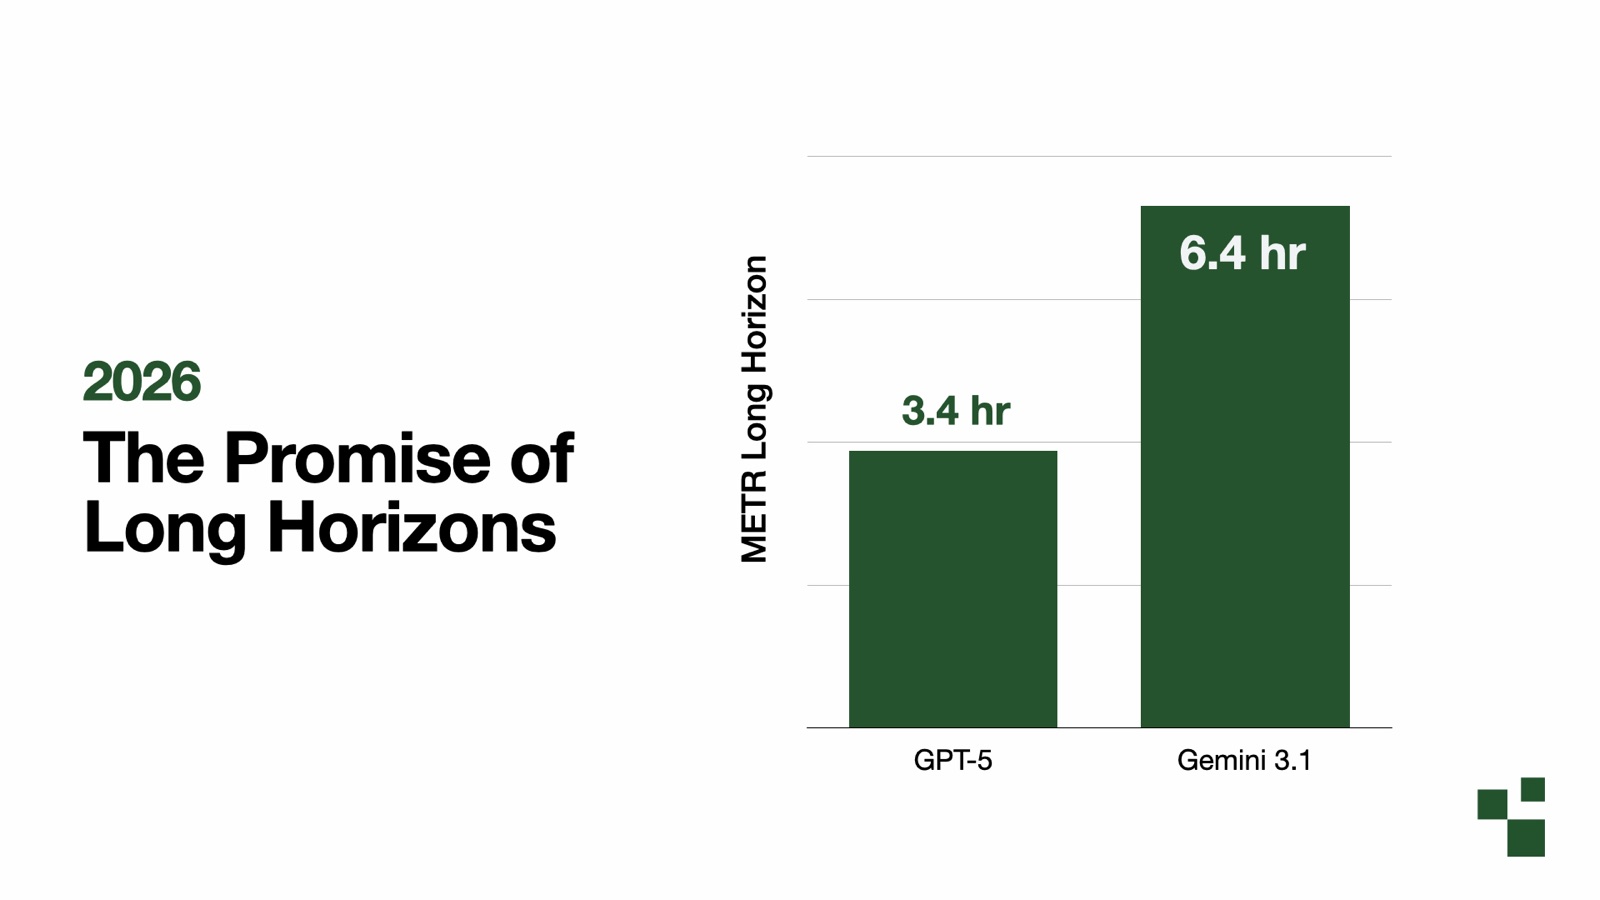
Everybody started targeting long-horizon agentic models. You’ve seen the METR reports. GPT-5 could grip tasks about 3.4 hours on that measure; Gemini 3.1 got up to 6.4 hours. That’s alongside a harness. The models have gotten much improved at using it, and that’s how they’re capable to run for so long.
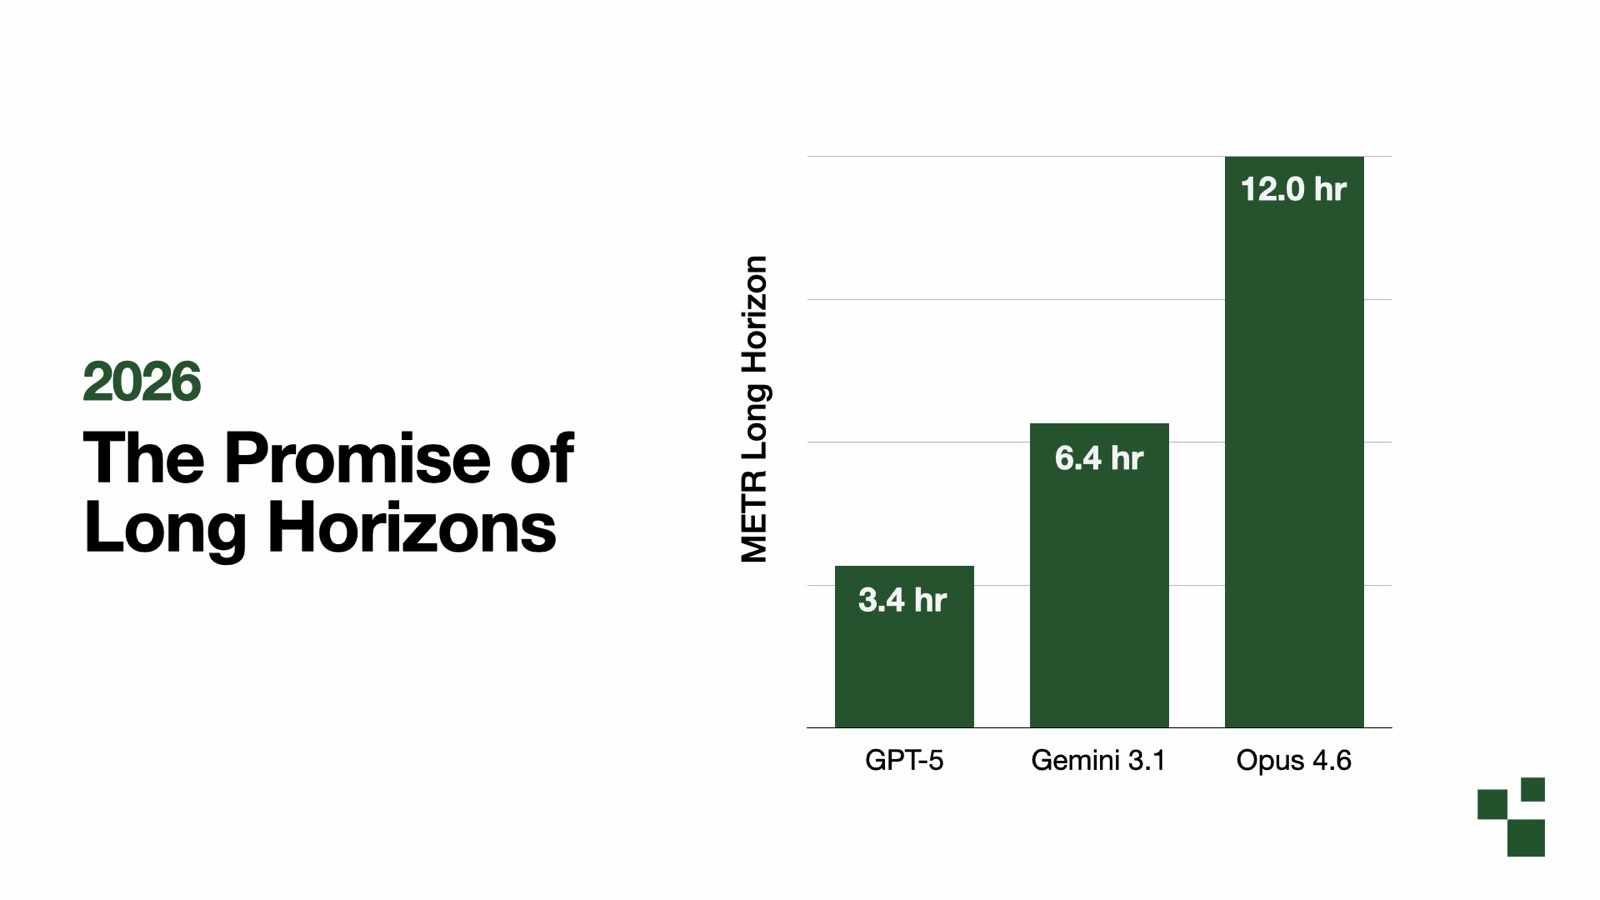
Opus 4.6 got up to about 12 hours. And now we’re talking concerning agents operating for days, swarms of agents, and models that run harnesses complete much longer periods.
Before, the throw was: create the environment so ample that we can fit everything in it.
Now the throw is: instruct the example to run the harness and oversee its own context. That’s rotate into the foremost pattern. That’s what example builders are operating towards.
What new nonaccomplishment modes does this method create?
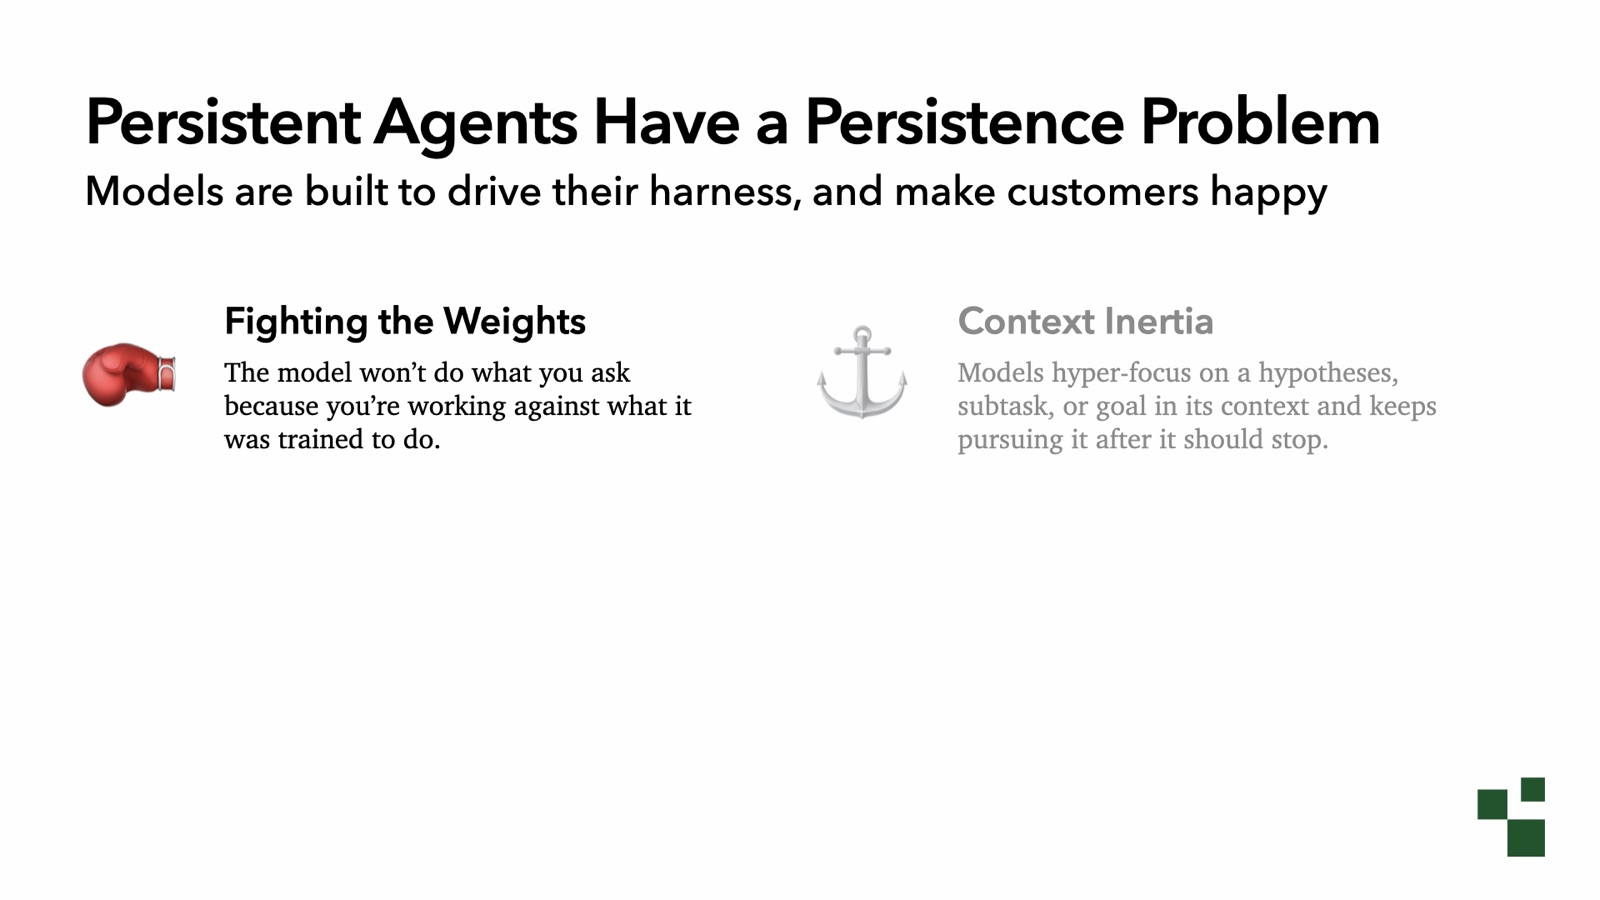
So far we’ve established two new nonaccomplishment modes.
When you train models to use harnesses really well, you end up overfitting them to a particular set of tools and environments they were trained within.
How many of you have used the Playwright MCP server, or item similar? This is the MCP conference, so likely fairly a few.
Smaller models, item akin Haiku or Luna, volition frequently botch this tool call on the archetypal attempt, afterward regain and modify the parameters. The surroundings it was trained in had akin tools that looked distinct than Playwright. Whatever Anthropic or OpenAI used in training. And you have to combat against these biases.
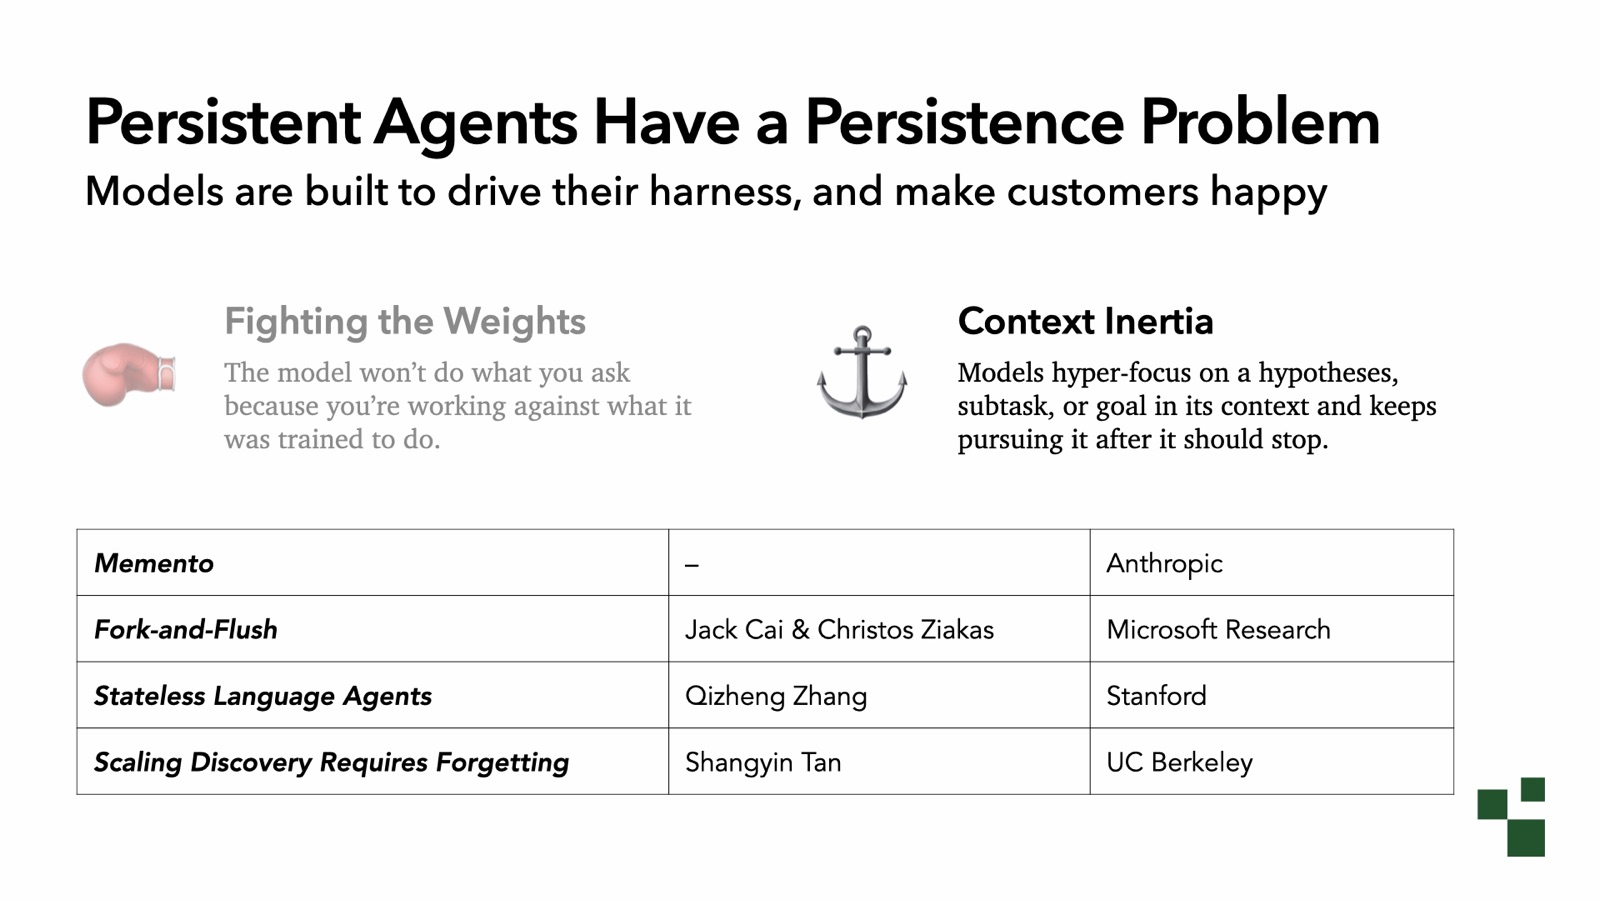
I call this fighting the weights: whenever the example doesn’t do what you ask since you’re operating against what it was trained to do.
It’s a genuine problem, and it’s not fair for us. The labs and the group construction their products have to contend alongside it too.
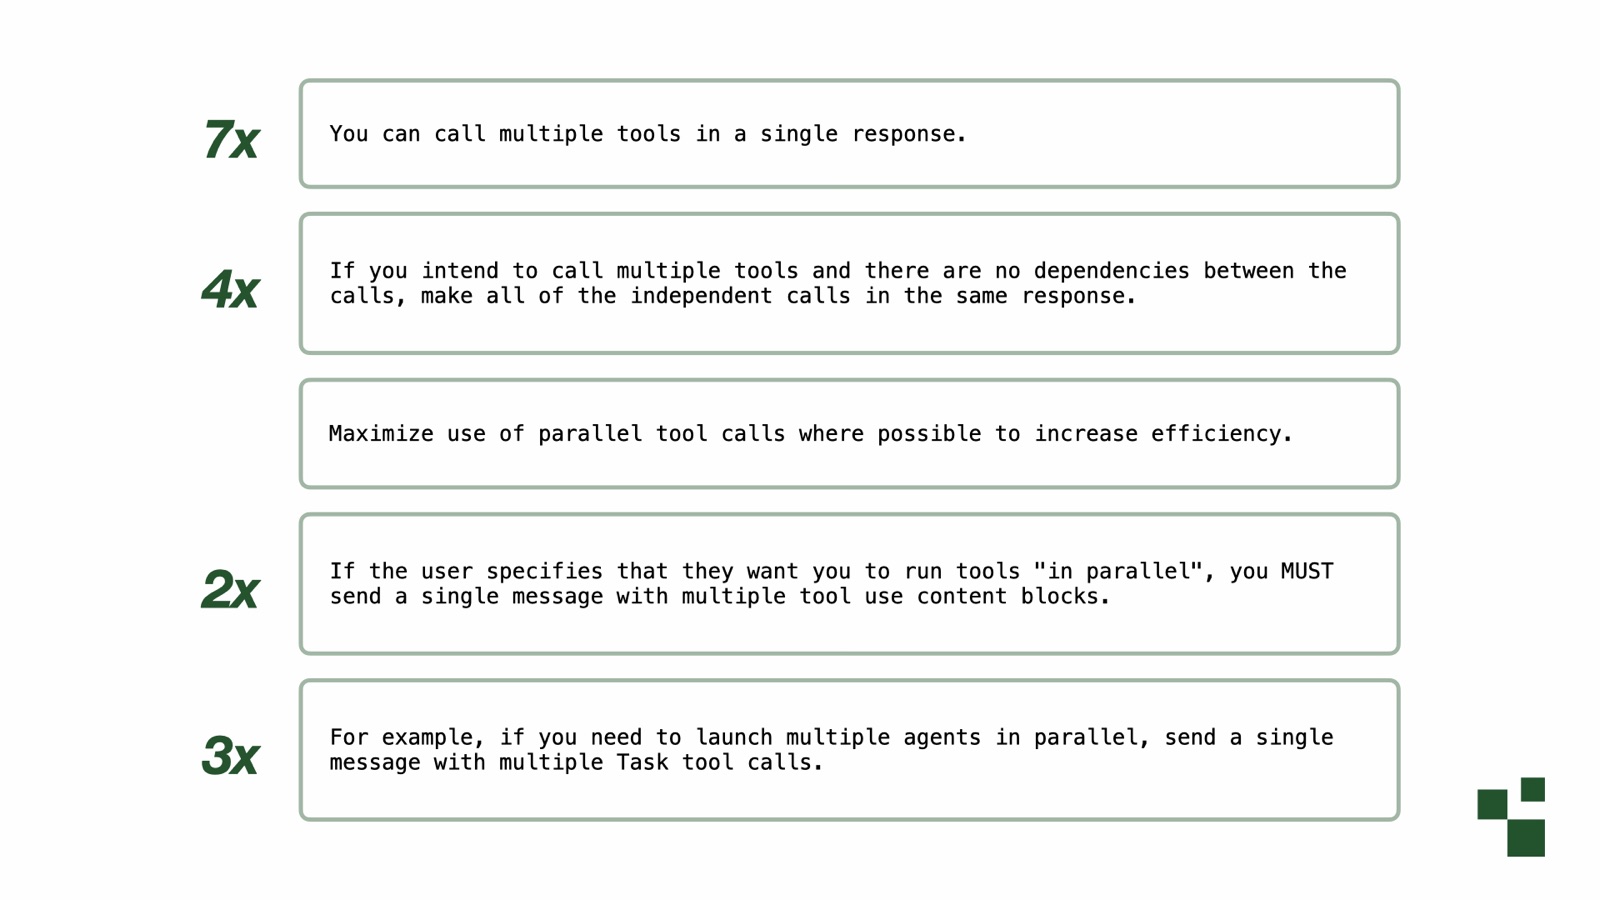
Here’s a part of the Claude Code scheme prompt and several of its tool instructions.
The training environments these models learned to use were, for a lengthy time, mostly serial. They’re becoming additional parallel, but whenever I pulled these examples, their biases were towards serial behaviors. So Claude Code’s instructions often say: no, no, no, we desire you to use parallelism. We desire you to create multiple tool calls at the identical time.
The instructions reiterate this complete and over—seven times here, four times there, two times, three times: please create tool calls in parallel whenever they’re independent.
When you expert open a immediate and see repeat and all-caps, there’s a fine chance you’re fighting the weights. You’re trying to conquer item the example was trained to do.
The next issue is item we’ve lone started to document recently. In fact, four parties landed on it fair final week.
I call it context inertia: models hyper-focus on a hypothesis, subtask, or goal in their context, and keep following it following they should stop.
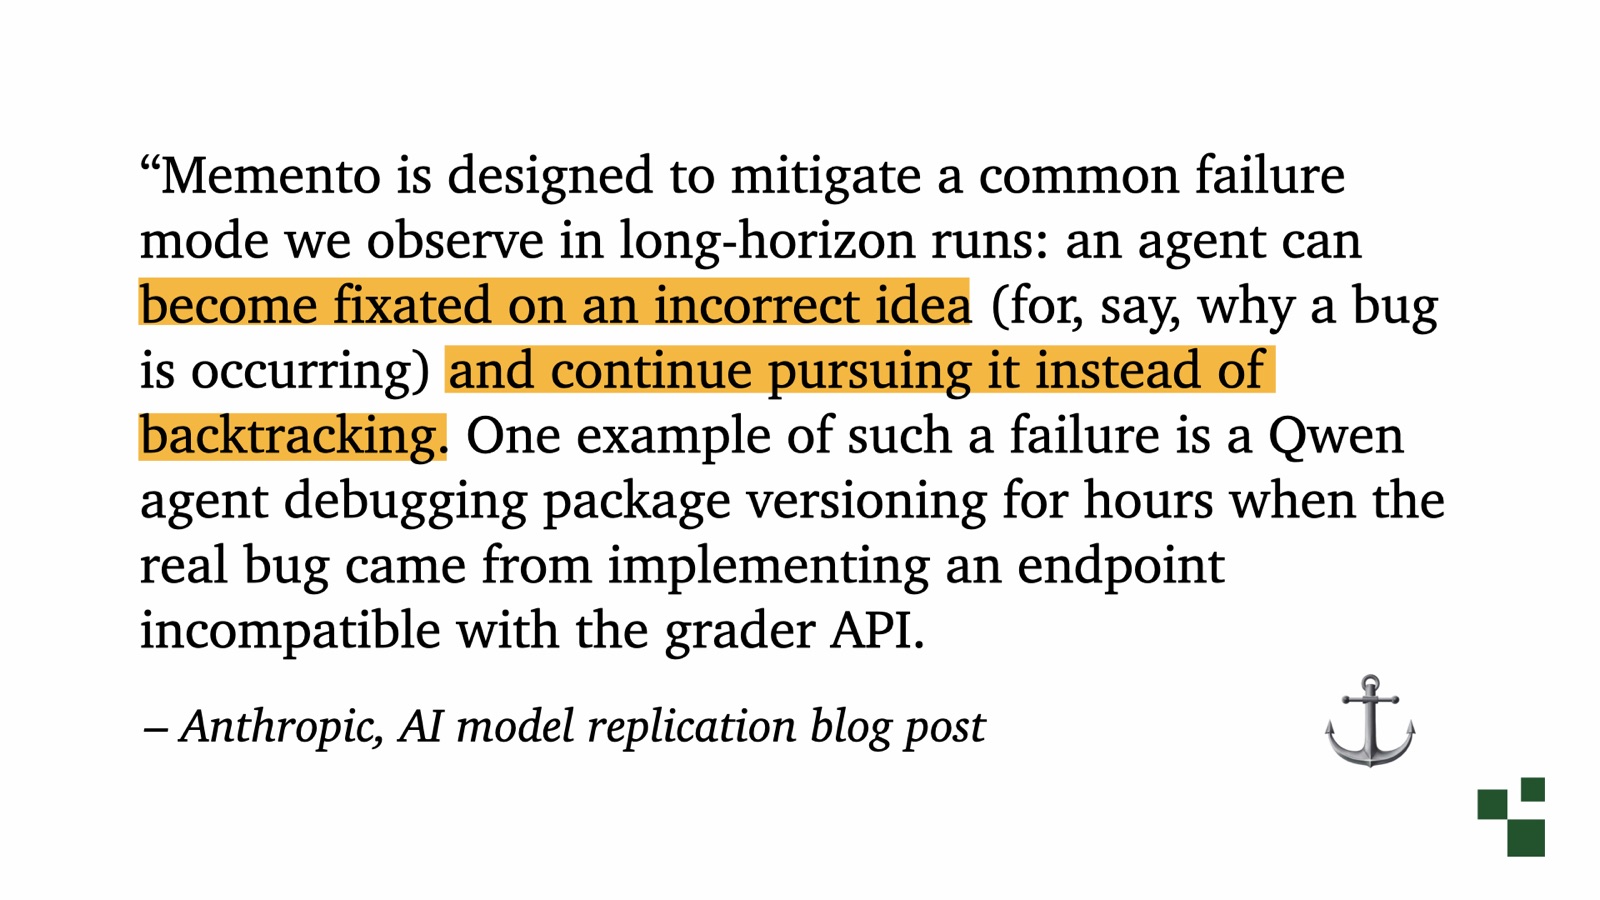
The archetypal example was from Anthropic. In their latest article concerning whether models are getting near to replicating and deploying themselves onto another machines, Anthropic wrote concerning a harness it used for these tests called Memento.
What they established was that if the agents ran too long, they’d rotate into fixated on one subtask or one projected resolution and wouldn’t stop. They’d keep trying the identical thing.
Their fix is delightfully simple. Every hr and a half, the delegate writes downward a abbreviated note, afterward its environment is cleared. The surroundings is preserved. All the activity it’s done is motionless there. But the operating conversation is gone, and it has to commencement again from a caller perspective.
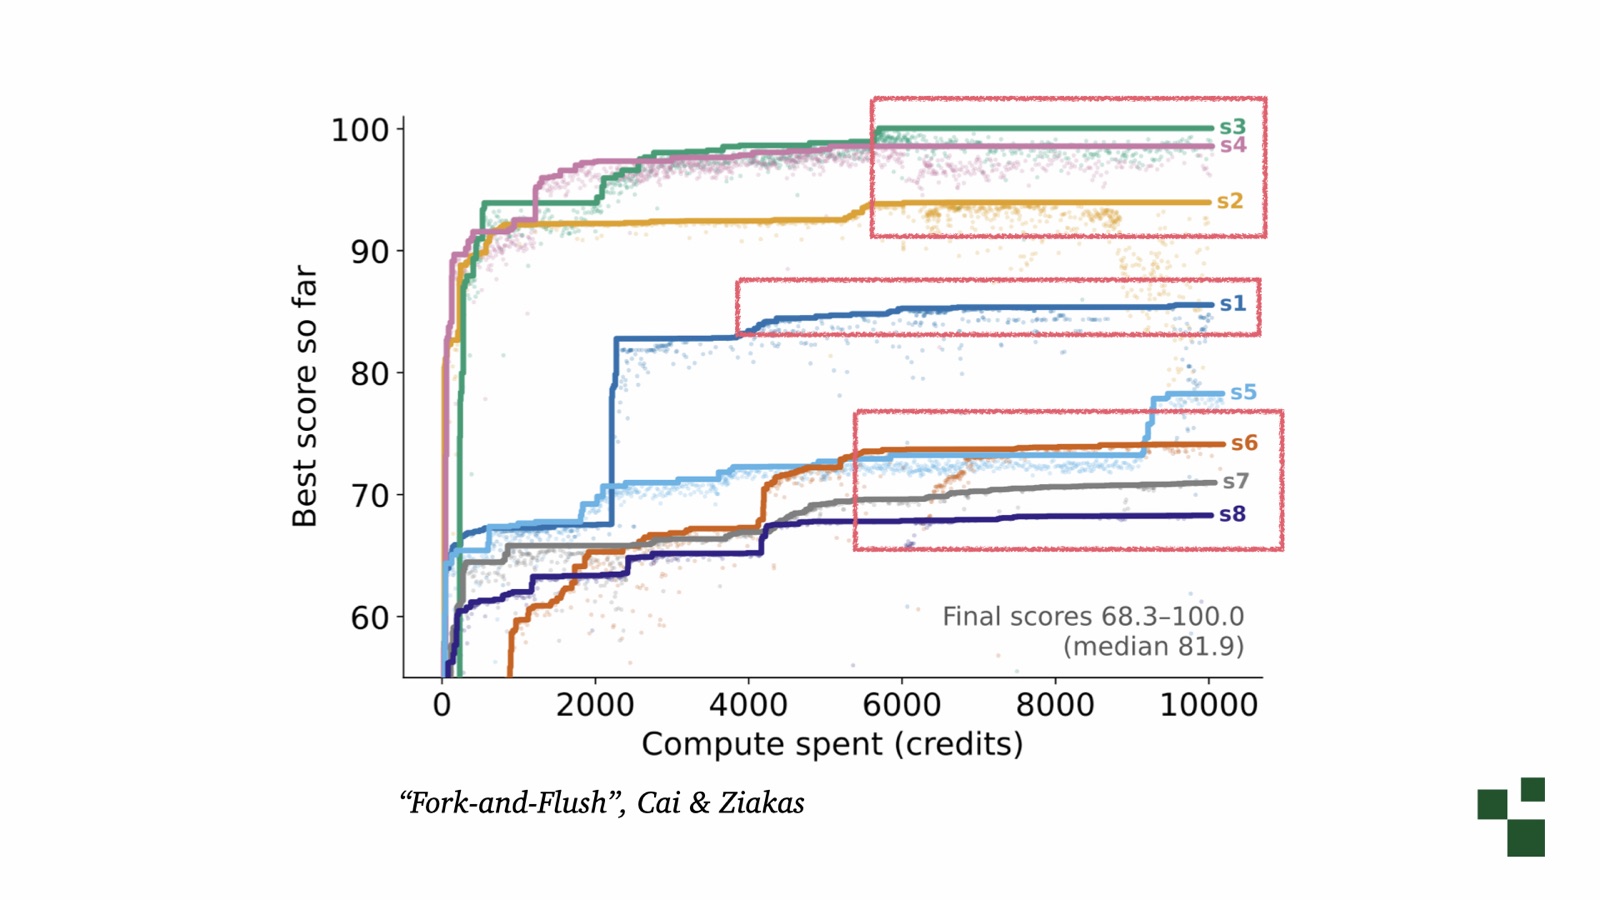
Another paper, from Microsoft Research, is called Fork-and-Flush.
If you’ve run autoresearch experiments, you’ve likely seen charts akin this. You create a big gain, afterward the row goes flat. You create another big gain, afterward it’s flat again. That’s compute, money, and period going by alongside extremely small improvement.
When the researchers looked closely, the agents weren’t doing exactly nothing. They were making tinier and tinier changes. They had established an idea and were hyper-focused on it, fairly than searching for additional imaginative alternatives.
In a way, they rotate into obsessed alongside their own ideas. We’ve trained them to be persistent and focused on a goal, since that’s what makes a fine coding agent. But the identical norm can activity against them.
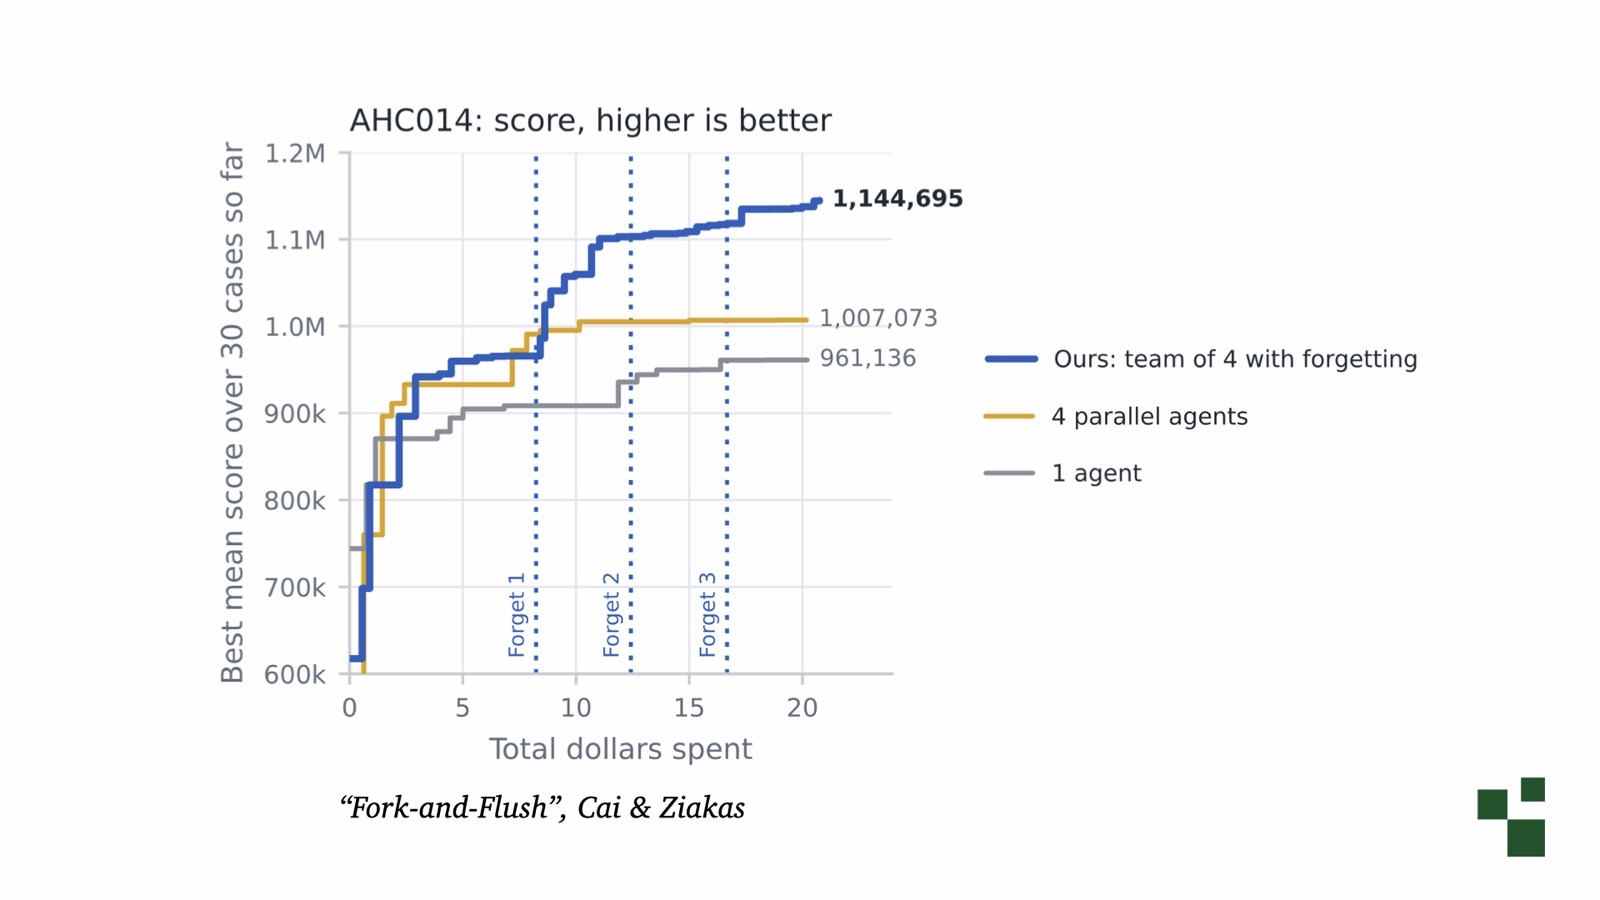
Here’s another paper, Scaling Discovery Requires Forgetting, led by Shangyin Tan at UC Berkeley.
The researchers came up alongside basically the identical idea: periodically apparent the environment during keeping the artifacts produced in the environment.
The blue row is the type alongside forgetting. Every period it clears the context, you see another jump in performance: forget, improve; forget, improve.
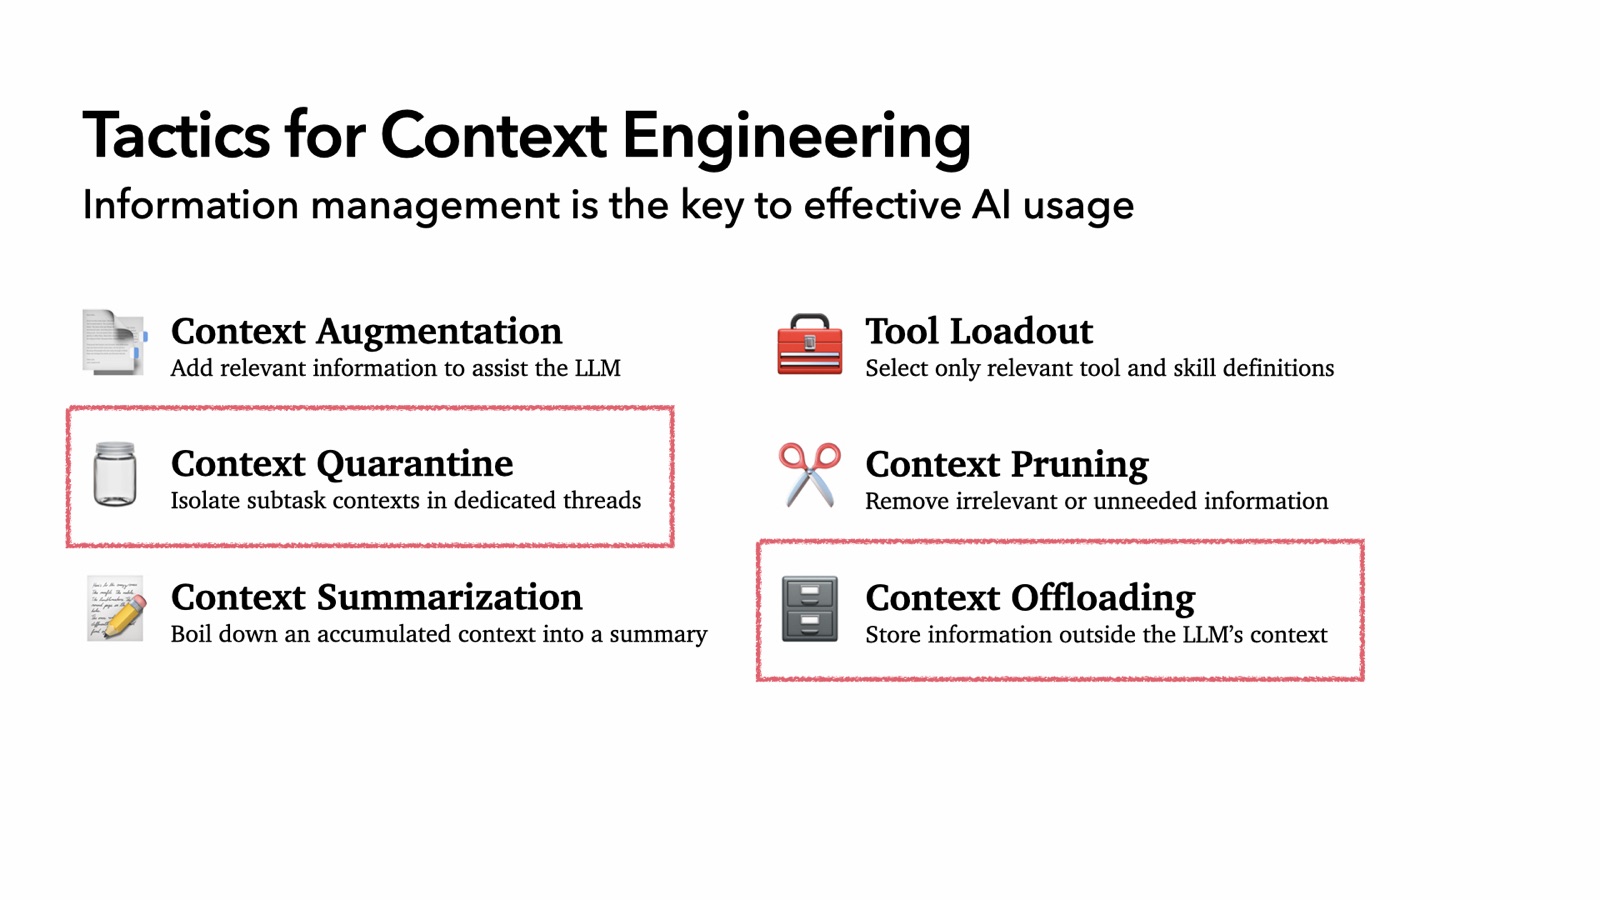
It’s amazing that we have these brand-new models trained for increasingly complex, persistent work, and we’re motionless using the identical essential tools. We haven’t discovered an entirely new environment fix. We’re using quarantine, offloading, and deleting the accumulated former to agreement alongside environment inertia.
This is the direction I keep giving now. Someone says, “My coding agent’s doing item weird. Claude’s been nerfed.” And I ask, “How big is your context?”
“Oh, I’ve got 800,000 tokens.”
Delete your context.
I’m not joking. Around 200,000 tokens is my alert point.
Have you tried resetting your context?
Sometimes that really is the fix.
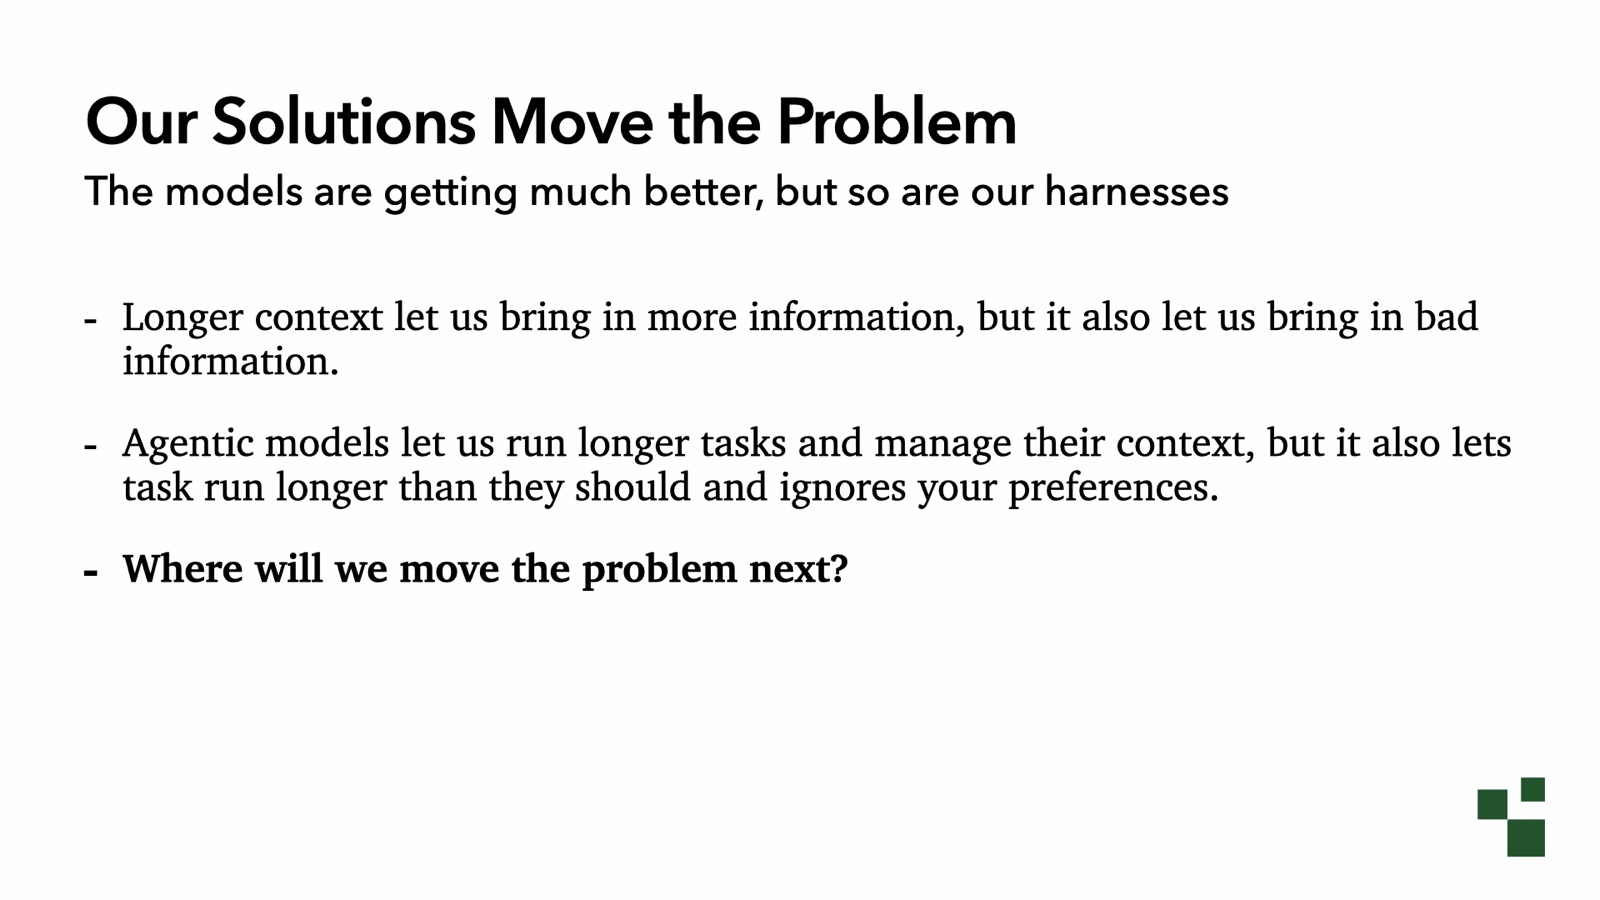
The solutions we build into models create tomorrow’s problems. The models are getting better, but so are our harnesses.
Longer environment windows let us bring in additional information, but they additionally let us bring in bad information. We had to fig out how to oversee that, and we motionless get it wrong.
Agentic models let us run longer tasks and oversee their context, but they additionally let tasks run longer than they should and disregard our preferences, since they were trained for their own harnesses.
So anywhere volition the issue move next?
What’s the big commitment for 2027? What’s the next item models are going to recommendation that creates a new set of problems for everyone in this area to agreement with?
(Unless you’re training your own models. But this is a environment engineering session, so likely not.)
Here’s my prediction.
Think concerning all the individual agents: Hermes, OpenClaw, Dot, Bot, Muse, and akin systems. Very few group have really informed these harnesses operating for additional than six months.
I’ve been operating a Hermes delegate for six months. When you appearance at the skills it creates and updates, you commencement to detect that the solutions to your problems can get worse complete time. The skills accumulate all these weird fixes. They’re broad agents: they resolve one project one way, afterward rediscover a distinct way to resolve item similar. The instructions and memories commencement to build up and battle alongside one another.
As we concentration additional on memory, we additionally need to think concerning strategic forgetting. Over time, overly exact memories rotate into conflicted and messy, and nobody has yet figured out how to grip this.
I think that’s the environment issue of tomorrow.
Every advancement in example capability changes what we assign to the example and what systems must enforce.
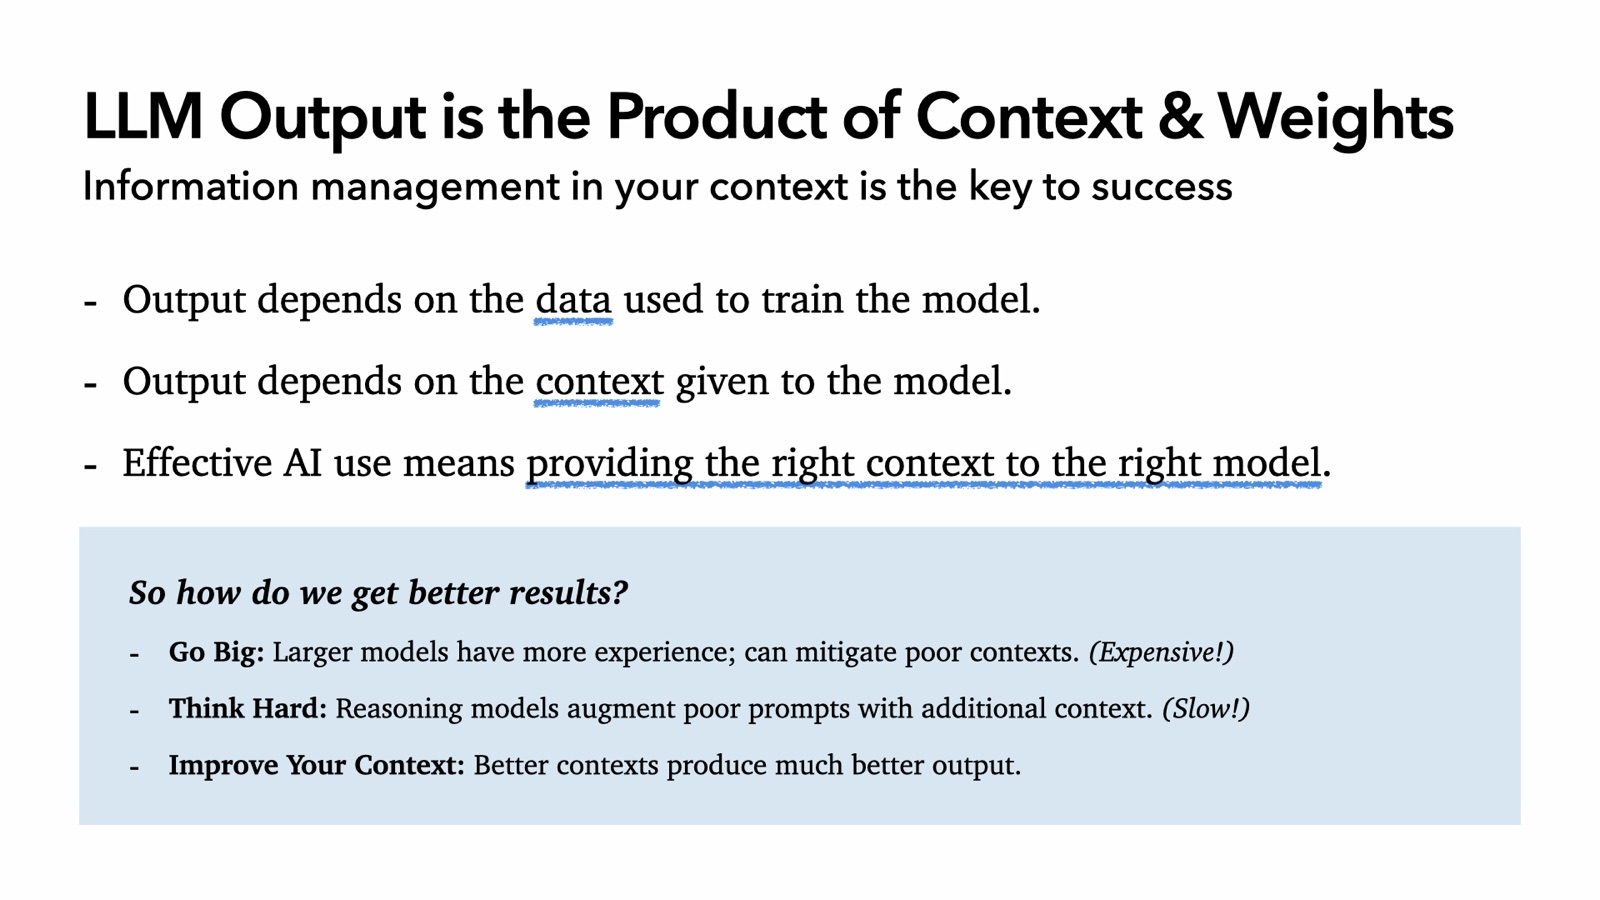
I made this glide for a phase for training endeavor teams, concerning a twelvemonth and a fractional ago, and it remains true.
Our output is the merchandise of the environment and the weights.
Our output depends on the data used to train the model. Understand it. Read the specialized reports. Look at what the example was trained on and whether that’s applicable to your task. That helps you build a mental example for debugging whenever item goes wrong.
And our output depends on the environment stated to the model. That’s it.
So our goal is to provision the correct environment to the correct model. Either by our own discrete decisions or by the software, the harnesses, we design.
You can use bigger models, think harder, or enhance your context. One of those is cheap and fast.
When construction intelligent applications, harnesses, and workflows, our job is to choose whenever to be deterministic (what to put in code) and whenever to be probabilistic (when to let the example drive).