
Qwen 3.8- 27B on iPhone 18 Apple Neural Engine. Added outline example , dflash-2 at ~ 2.8 bpw ( blended 2-4 vector quantization alongside small autumn in acceptance rate) Base is @PrismML Bonsai-2, 1.585 bpw requantized to 1.5 bpw ( VQ 6 bits per 4 weights) Decoding speed is 15-60 tps.
Qwen3.8-27B on the iPhone 18 Neural Engine at 15–70 tok/s (1.5 bpw)
 by Riki Setiawan 1 min read
46x views

Other Article Hacker News
Related Article

TikTok bans Musk documentary account
Terrence 17 October 2026
Microsoft and CMU Team Up to Train Early Career Software Engineers
Adi 17 October 2026
Owner of Former UWS Barbecue Restaurant Indicted for Wage Theft: Manhattan DA
Adi 17 October 2026
Pattern Matching Beats Narrative Reasoning
Adi 17 October 2026
AI Can Write the Code. Who Verifies It?
Adi 17 October 2026

OpenCode Hacked: User credentials leaked
Riki 17 October 2026
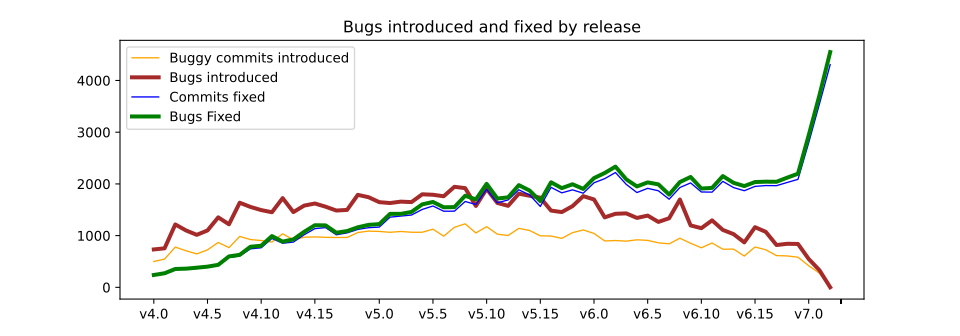
Linux bugs fixed per release over time: >2× rise since 2026-04
Adi 17 October 2026
Artie (YC S23) Is Hiring Enterprise AES and Senior Engineers
Adi 17 October 2026

Elon Musk settles lawsuits over $1 million voter giveaway
Terrence 17 October 2026
OpenAI discloses four more rogue incidents
Adi 17 October 2026


Popular Article

Buying Apple’s wall-mounted HomeView? The mount costs extra
Jess 521x views

Neural Networks Are Already Clean
Mira 518x views


