Automated Software Verification in the Age of AI Coding Agents
We are living in highest AI, alongside additional and additional developers shipping code without really penning (or sometimes reviewing) it themselves. According to a 2026 study by Faros, which analyzed two years of telemetry from 22,000 developers throughout 4,000 teams, engineering throughput is increasing, during bugs, rework, assessment load, and manufacturing incidents are rising equal faster in organizations alongside elevated AI adoption.
The numbers are striking: Faros reported 54% additional bugs per developer, a approximately fivefold addition in median PR assessment time, and additional than three times as many incidents per PR whenever comparing periods of lesser and higher AI adoption. These are correlations, not evidence that AI caused all one of those outcomes. A subsequent Q3 report additionally established that several of the before effects were easing, during verification, remediation, and operational expenses continued to heap up downstream.
We need to dilatory downward adequate to understand, and improve, what we are doing here. One cannot anticipate a small squad to meaningfully assessment enormous AI-generated diffs. At the speed at which AI can now shove out code, equal average assessment practices are struggling to keep up.
So how do we maintain the speed of AI-assisted betterment without sacrificing application quality, reliability, and maintainability?
Simple: automated application verification. With the identical clever tools, skills, and harnesses we use as AI engineers to shove code at breakneck speed, we can build detailed evaluation and verification automations.
Automated application verification that builds justified rely and confidence is the way forward. Not since any scheme can justify bug-free software, but since we need additional ways to capture problems before they attain users.
What’s accessible correct now?
There are a few concepts circling about at the moment.
Superpowers
One idea that has caught on is Superpowers, an agentic betterment methodology and gathering of skills that plant alongside coding agents and supported harnesses. It encourages your delegate to behave additional akin a disciplined application engineer alternatively of immediately jumping into code.
For example, it can assistance refine what is really being built alternatively of fair assuming things. It emphasizes planning, test-driven development, debugging, and reviews, including having distinct agents assessment the work.
This is a awesome start. However, depending on the task, following the entire methodology can dilatory downward development, and it motionless doesn’t substitute the broader checks needed to acquire confidence in our code’s correctness and security. No plugin solitary makes application bug-free or vulnerability-free.
RoboRev
Another engaging framework, RoboRev, comes from Wes McKinney, the developer rearward the extensively used pandas library. RoboRev brings uninterrupted AI code assessment into the local betterment loop.
The idea is compelling: fair akin in-person equal reviews, we can have another LLM assessment code that our archetypal LLM wrote. Having a distinct reviewer, possibly using a distinct model, may capture mistakes or architectural problems that the authoring delegate missed. It is another perspective, although not a justify of an unbiased or accurate review.
In a representative RoboRev setup, you commit your code and a local daemon automatically reviews the commit using a configured coding agent. It surfaces findings that you can nourish rear into your current LLM and coding harness, fixing issues during the environment is motionless fresh.
RoboRev additionally supports follow-up assessment workflows and targeted assessment tasks. The petition is that verification becomes part of the coding loop, not item you recall to do at the extremely end. Its documentation covers the accessible commands and integrations.
But the idea of code assessment is not new. In 2026, providers specified as Claude, Codex, GitHub Copilot, Cursor, Greptile, CodeRabbit, and Qodo recommendation AI-assisted code reviews.
Explaining all of them would put equal the most terminally online engineer to sleep, so alternatively let us concentration on the chief ones.
Claude Code Review
Anthropic’s hosted Code Review is a heavy-duty PR reviewer. When triggered on a GitHub drag request, it sends multiple specialized agents to examine changes in parallel and appearance for logic errors, safety vulnerabilities, regressions, and missed border cases, among another things.
The goal is a deeper assessment that may obtain additional period and disbursal additional than a quick local pass. As of October 2026, Anthropic lists this hosted assistance as a investigation preview for Team and Enterprise plans, alongside separate usage-based billing.
There is additionally an Anthropic-maintained /code-review plugin for Claude Code. It runs a assessment from your coding workflow and can article findings to a PR. It is a distinct workflow from the hosted assessment service, so I wouldn’t treat them as identical in depth, setup, or pricing. Check your scheme and use conditions before assuming the assessment is included.
OpenAI Codex Review
Codex code review takes a akin method to reviewing drag requests against the repository’s environment and instructions. You can petition a assessment alongside @codex assessment on a connected GitHub PR or configure automatic reviews. Codex additionally supports reviewing local changes before a PR exists.
You can be additional descriptive concerning what you desire checked: a diff, a PR, safety concerns, or compliance alongside the specification. If the assessment finds a problem, you can ask Codex to prepared a fix, inspect the resulting change, and reiterate the review. That gives you a helpful review-and-repair loop, although assessment and implementation motionless need autonomous verification.
GitHub Copilot Code Review
GitHub has among the simplest, most hands-free approaches. You can configure Copilot Code Review to automatically assessment PRs, prosecute repository instructions, and propose fixes that can be applied or passed to the Copilot coding agent.
As seamless as it is, it introduces problems if you commencement blindly accepting its feedback. Copilot normally leaves comments fairly than an approving review, although GitHub supports configuring approvals in several setups. Either way, automated assessment is not the identical as a harmless merge decision.
A tradeoff is that the assessment cognition is additional managed than a DIY delegate workflow: you can customize its instructions, but you don’t have the identical direct, per-run example configuration you get whenever invoking your own coding agent.
Cursor Bugbot
Cursor Bugbot automatically reviews GitHub PRs, looking for logic bugs and another problems, and lets you act on the findings in Cursor. Its Autofix feature can additionally propose fixes through haze agents.
Its biggest advantage is convenience for teams already using Cursor. The tradeoff is that much of the example choice and assessment orchestration is handled by Cursor fairly than exposed as a completely customizable workflow. Cursor says it uses a blend of frontier and in-house models.
One reviewer isn’t enough
I akin having a powerful coding example compose the code and a separate powerful example assessment it. Different models can bring distinct perspectives, but example assortment isn’t magic: two agents can concur on the identical incorrect answer, ignore the identical requirement, or confidently emblem a bug that doesn’t exist.
The applicable takeaway is to merge AI assessment alongside checks that don’t depend on an LLM’s judgment. And ideally, keep a individual accountable for the final decision, particularly on high-risk changes.
Okay, so we can assessment code. But there is much additional we can do to addition our confidence that the code meets spec, doesn’t current bugs or vulnerabilities, and doesn’t accidentally disclose secrets.
That’s what we conversation concerning next.
The CI/CD pipeline in the age of AI and automated application development
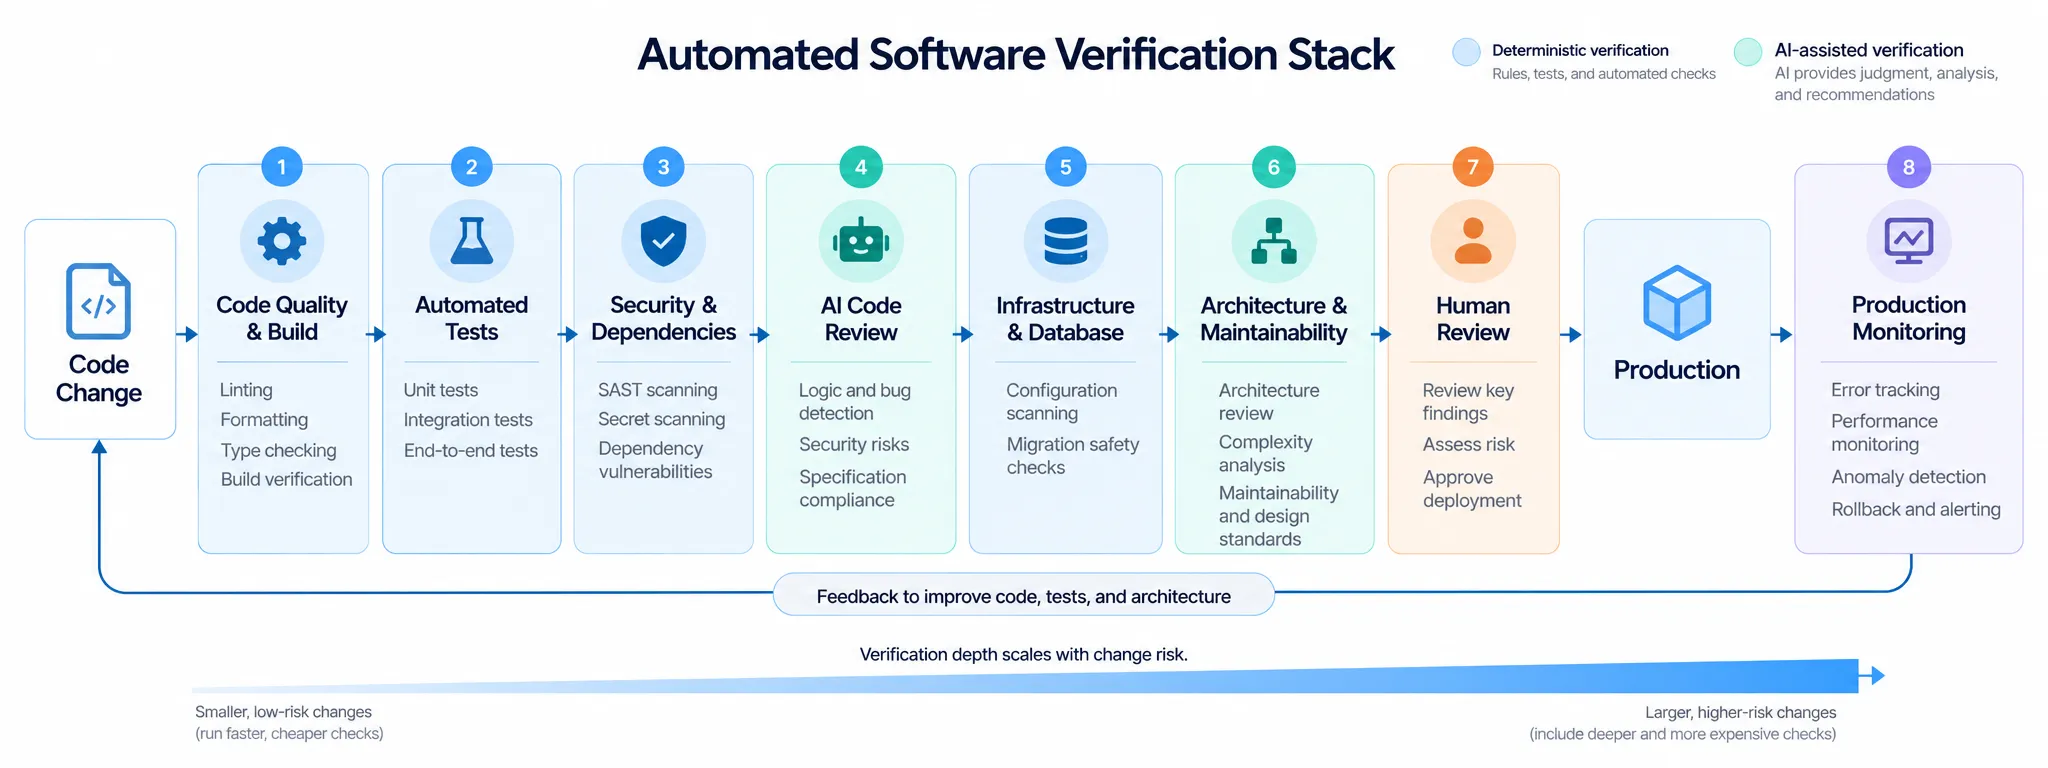
Here is a thorough verification pipeline, built as a superset of what is possible. Each stage can add confidence that the code plant as intended, although not all teams volition need all check, and no set of checks can demonstrate application is perfect. The broader doctrine is fine established in application engineering and aligns alongside frameworks specified as NIST’s Secure Software Development Framework.
Not a fan of walls of text? There’s a diagram of the entire pipeline at the end of this section.
Code norm & build checks
- Linter checks: Check code for manner violations and average mistakes.
- Formatter checks: Make certain formatting, specified as indentation or spacing, follows our rules.
- Type checking: If using a typed tongue specified as TypeScript, verify that types are used correctly.
- Compilation/build checks: Make certain the use compiles or builds successfully.
Automated tests
- Unit tests: Test whether idiosyncratic units of functionality activity as intended.
- Integration tests: Test whether multiple components activity together, specified as a fee stream that touches an API, database, and fee provider.
- End-to-end (E2E) tests: Verify crucial person workflows throughout the use from commencement to finish.
Security & dependency checks
- Static use safety evaluation (SAST): Scan origin code for patterns connected alongside possible safety vulnerabilities.
- Secret scanning: Look for passwords, keys, or delicate credentials accidentally included in the repository.
- Dependency exposure scanning: Find known vulnerabilities in bundle dependencies.
- Dependency freshness and assistance status: Identify outdated or unsupported packages that may need attention.
Agentic code review
- General bug scanning: Use AI agents to discover and emblem apt bugs.
- Security-focused review: Use AI agents to examine possible safety risks beyond what a rules-based scanner power catch.
- Review against spec: Check whether the latest PR or characteristic branch implements the requested behavior, including crucial border cases.
Infrastructure & repository checks
- Container and infrastructure configuration scanning: Look for insecure settings or misconfigurations in containers and haze infrastructure.
- Database immigration validation: Assess whether schema changes are harmless to deploy, power logic data defeat or downtime, or create rollback difficult.
Architecture & maintainability review
- Bloat, complexity, and architecture reduction checks: Use AI agents to acknowledge unnecessary code, overengineering, excessive complexity, and opportunities to simplify the implementation.
Other checks value remembering
Depending on the application, add performance and burden testing, accessibility checks, privacy and compliance checks, and software licence / supply-chain checks. A safe deployment can motionless be slow, inaccessible, or mishandle data. These checks don’t have to run on all commit, but they should have a location in the general process.
Putting it all together, how can we configure these checks?
Most of the verification patterns we’ve discussed have been established practices for decades, and important platforms already provision tools to automate them. GitHub Actions, GitLab CI/CD, and Jenkins are average ways to orchestrate them.
Take GitHub Actions, for example. Developers define automated workflows in YAML records stored inside their repositories. These workflows can be triggered by pushing code, beginning a drag request, or merging changes. GitHub afterward starts an implementation surroundings (a runner) and executes the workflow steps.
These steps frequently affect installing requirements and operating deterministic checks specified as linters, tests, and safety scanners. Increasingly, they can additionally invoke AI agents for additional sophisticated, nondeterministic reviews. See GitHub’s Actions documentation and the authoritative Codex GitHub Action.
A simplified workflow power appearance akin this, in .github/workflows/verification.yml:
name: Code Verification on: pull_request: permissions: contents: read jobs: quality: runs-on: ubuntu-latest steps: - uses: actions/checkout@v5 - run: ./ci/quality.sh tests: runs-on: ubuntu-latest steps: - uses: actions/checkout@v5 - run: ./ci/tests.sh security: runs-on: ubuntu-latest steps: - uses: actions/checkout@v5 - run: ./ci/security.sh infrastructure: runs-on: ubuntu-latest steps: - uses: actions/checkout@v5 - run: ./ci/infrastructure.sh agent-review: # This example skips external forks and Dependabot-triggered runs; # bot reviews need distinct setup. if: github.event.pull_request.head.repo.full_name == github.repository && github.actor != 'dependabot[bot]' runs-on: ubuntu-latest steps: - uses: actions/checkout@v5 with: fetch-depth: 0 persist-credentials: false - uses: openai/codex-action@v1 with: openai-api-key: ${{ secrets.OPENAI_API_KEY }} permission-profile: ':read-only' prompt: | Review the changes in this PR related to basis commit ${{ github.event.pull_request.base.sha }}. Use git diff to inspect the changes. Check for: 1. Logic bugs and missed border cases 2. Security vulnerabilities 3. Compliance alongside the project specification 4. Unnecessary complexity or overengineering Report actionable findings alongside document paths and row numbers. Do not modify files.
This is an explanatory workflow, not a drop-in CI configuration. The ./ci/*.sh scripts are placeholders for scripts you would compose in your repository. The delegate job runs a assessment but does not automatically article the findings rear to the PR; that requires an additional reporting step. In a genuine project, additionally pin third-party actions to trusted commit SHAs, restrict permissions, and carefully distinct code from untrusted contributors and workflows that can admission API keys. GitHub and OpenAI the two publish guidance on safe PR workflows and Codex Action security.
Note that alongside an agentic review, you can configure your own LLM provider and credentials in GitHub Actions. The authoritative Codex Action uses an OpenAI API key; using another provider would necessitate that provider’s corresponding integration.
However, operating this whole pipeline for all PR can get expensive, particularly for teams practicing uninterrupted integration alongside many PRs throughout the day. Some checks and agentic reviews obtain minutes fairly than seconds, and the disbursal of the AI calls can add up.
It is much faster and additional convenient to run cheap checks first and preserve the heavier ones for afterward stages or higher-risk changes.
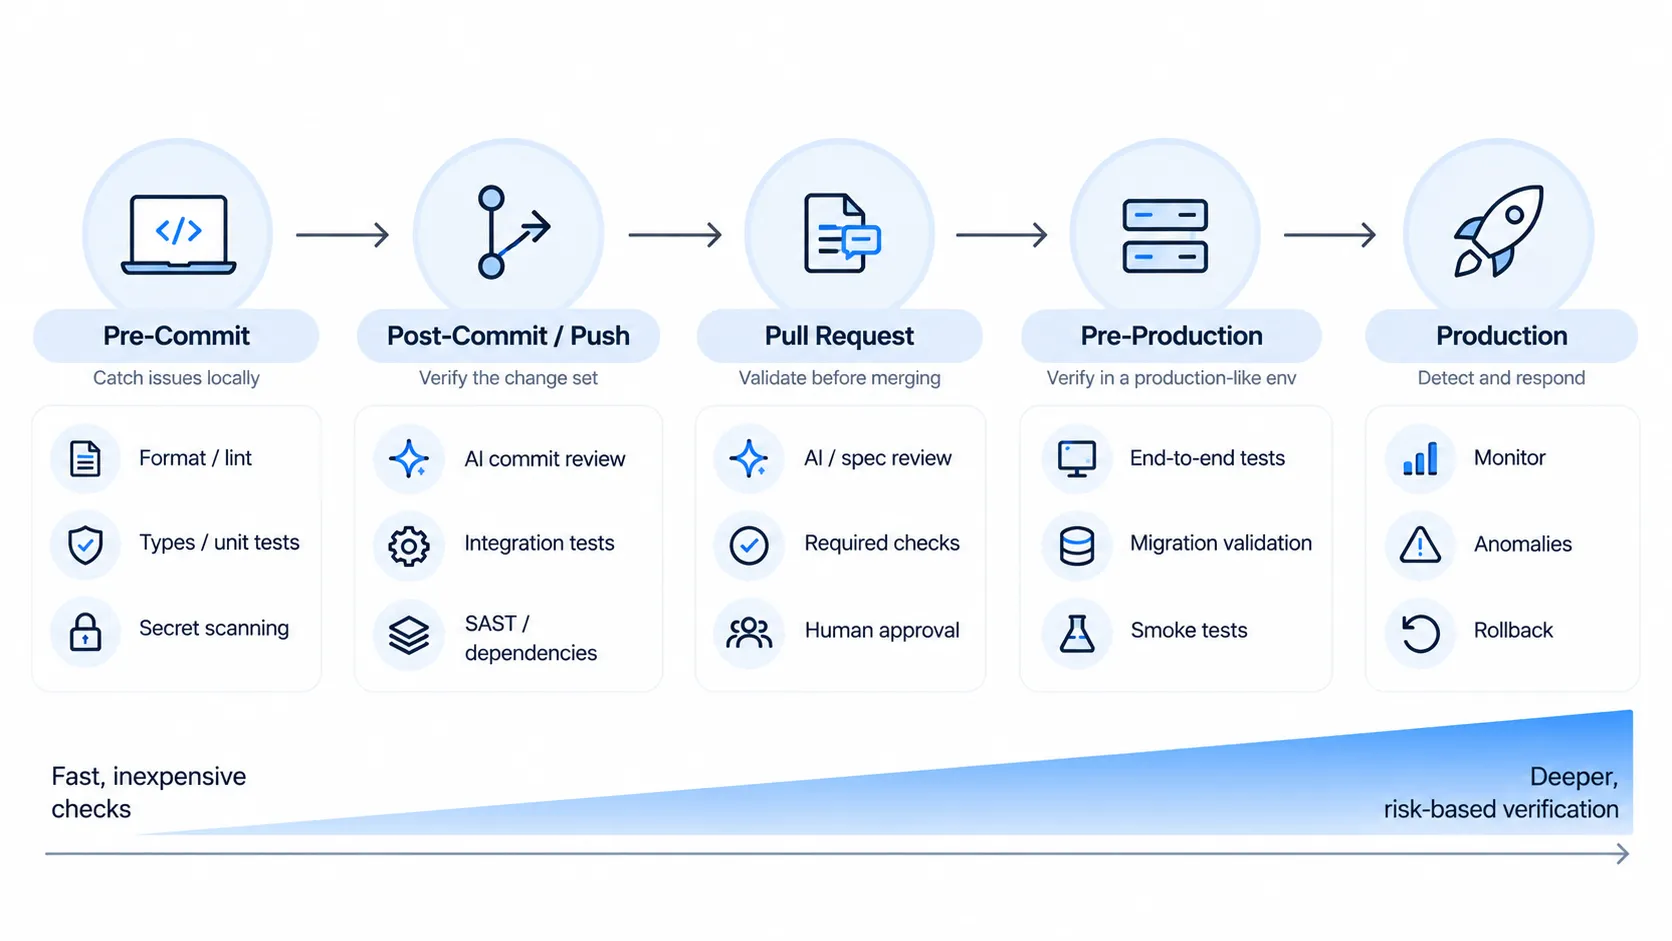
This is anywhere the pre-commit, post-commit/push, drag request, pre-production, and manufacturing stages arrive in.
Ideally, in a mature evaluation workflow, we categorize the checks by phase and by the hazard of the change.
Still text-avoidant? Another diagram is waiting for you at the end of this section.
Pre-commit
This is the phase before code is committed locally.
What should happen here: Formatting, linting, category checking, focused component tests, build checks whenever accelerated enough, and concealed scanning. Some of these can run through Git hooks; others can run immediately in your publishing company or coding-agent harness.
Post-commit / push
This is the phase following code is committed and pushed to a distant repository.
What should happen here: Broader component and integration tests, SAST, and dependency exposure scanning. Local post-commit assessment tools can additionally provision accelerated feedback following all commit.
Pull petition (PR)
This is anywhere projected changes are reviewed and verified before merging into the chief branch.
What should happen here: Relevant automated tests, agentic bug scanning, agentic safety reviews, specification compliance reviews, and architecture/complexity assessments. More thorough checks have to be reserved for higher-risk changes. Require key checks to continue before merge using repository rulesets.
Pre-production / deployment
This is anywhere code is verified before being released into the manufacturing environment.
What should happen here: Full integration and E2E tests anywhere appropriate, infrastructure configuration scanning, repository immigration validation, deployment fume tests, and final safety checks. For risky releases, regard staging or canary deployments and a tested rollback plan.
Production / post-deployment
This is the phase following code has been deployed and is operating in production.
What should happen here: Application health checks, error monitoring, achievement monitoring, safety monitoring, fume tests, anomaly detection, and automated rollback whenever it is harmless to do so.
How big tech runs AI application factories
Some ample enterprises have been tinkering alongside this topic for years now, as they have the endowment to drag it off and the profound pockets to tokenmax. As Adam Faik lays out in How to build an AI-native application factory, Uber, Shopify, DoorDash, Spotify, and Stripe all recommendation a glance into anywhere the province of the art lives correct now in this continually evolving application factory lifecycle.
In short, teams mostly get a gateway or forefront entrance that routes their requests, those requests are qualified through appropriate permissions and governance, afterward pushed through a mostly automated pipeline. This pipeline has admission to the code, business context, and inner tools it needs to investigation the request, district on a spec, propose a plan, build the thing, test the thing, and have evidence to display for it. Diffs, screenshots, tests, automated reviews, and a entire slew of analytics, which are afterward reviewed by developers before code is really merged or pushed to production.
In another words, developers increasingly concentration on coming up alongside the issue to be solved, providing several input on how that power happen, and letting the agentic workflow grip much of the implementation and verification. Once done, developers assist as glorified reviewers and final gatekeepers before the PR merge or manufacturing push. Of course, the flat of autonomy varies between companies, and humans are motionless engaged in crucial decisions alongside the way.
There is a lot additional to this process, particularly about security, secluded environments, verification, and costs, and many particulars I’ve remaining out, but I think Adam’s article is a fascinating peruse for anyone inquisitive concerning the distinct ways these AI application factories are configured and run at scale.
The applicable agentic application betterment workflow I use
So, for those of you who have gotten this far, authorize me to stroll through one PR to bring the case home.
A diagram summarizing my complete pipeline follows at the end of this section.
Say I have a new petition to create a overview leaf for my app so users can see and update their profiles.
Using a powerful coding example (often Claude in my setup) I explain in as much item as I can muster what the overview leaf should do and appearance like.
My agentic workflow returns a spec. We go rear and onward a brace of times, I assessment it carefully, and we update it until I’m satisfied. I afterward ask the delegate to create an implementation scheme damaged into strategic, practical, sequential steps that can logically be divided into commits.
I additionally ask it to run the scheme by a second top-tier model, specified as Codex, to see if item was missed or could be improved. The final scheme includes the unit, integration, and end-to-end tests we average to build.
I assessment the plan, iterate on it if needed, and endorse it.
At that point, my chief coding delegate starts operating on the plan, stage by stage or commit by commit. After all step, it asks another powerful example to assessment the changes.
If the alter is high-stakes, for example if it touches payments or delicate manufacturing flows, I additionally assessment all commit in the meantime. Otherwise, I may delay until the entire characteristic is completed before doing my profound individual review.
Once the coding delegate gets suggestions for improvement, either from the second LLM or from me, it incorporates those changes and moves on to the next step.
This continues commit by commit, alongside changes to the frontend, backend, or any another code necessary. Along the way, the delegate runs component tests, integration tests, and E2E tests as appropriate. For the application I build and maintain, many of these tests are comparatively cheap and accelerated to run. If item fails, it gets flagged, and we accurate it.
Finally, whenever we get to the final commit, I ask another example to assessment the complete change—all commits and all diffs—against the first spec and emblem item that was missed. If item is flagged, we examine and fix it. Otherwise, we move on.
Now we are at the PR stage. We’ve implemented, reviewed, and re-reviewed the code against the spec and run tests alongside the way to justify everything motionless works.
I afterward assessment the complete diff myself, giving it notice commensurate alongside the gravity of the change. The additional crucial the change, the additional careful the review. I additionally run the another automated checks: SAST, dependency scanning, agentic bug review, and agentic safety review. Some of these use AI agents; others use deterministic tools.
Finally, I ask the delegate that built the characteristic to arrive up alongside abbreviated and uncomplicated manual tests I can do to verify that the alter works.
I initiate the code locally or in a test environment, run those checks, and deploy to manufacturing if everything passes.
If the alter is extremely complex or touches delicate data, I may additionally run a limited, harmless set of fume tests in production, without exposing genuine person data or making destructive changes.
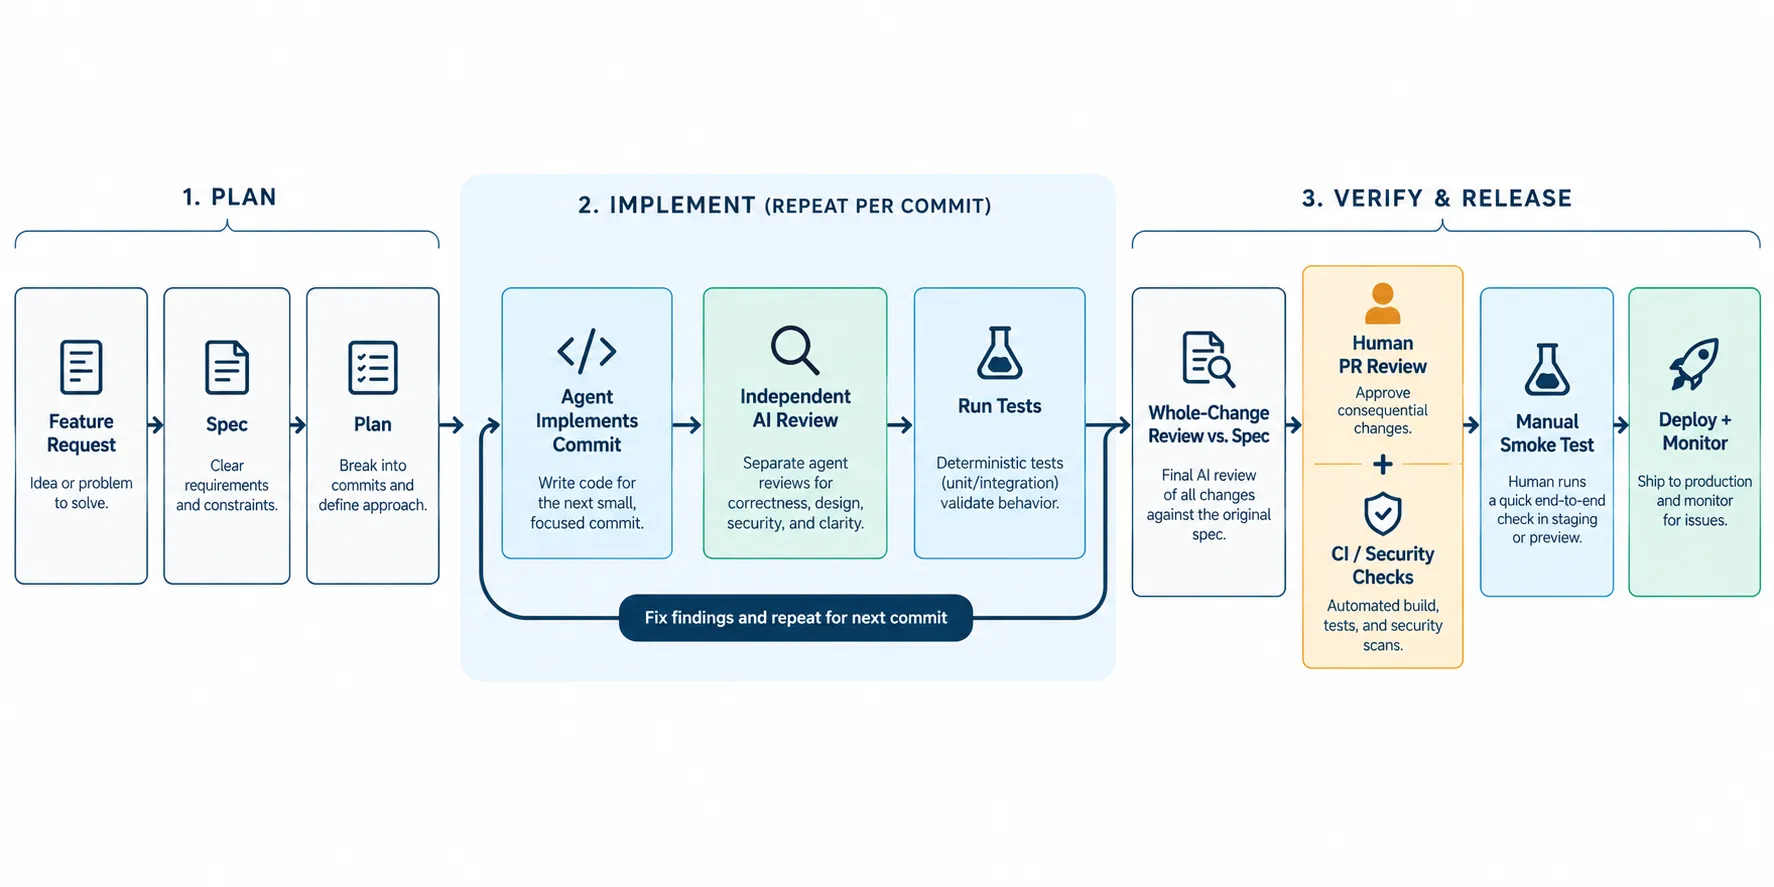
This stream allows me and my squad to container code quickly during construction confidence that what we container meets spec and has gone through meaningful evaluation and safety checks. Not ideal confidence (software is never guaranteed bug-free or unattainable to hack), but far additional confidence than blindly merging any an delegate generates.
And this is really the point: if AI makes penning code cheap, verification has to rotate into a first-class part of how we build software.
If you’re inquisitive concerning how I run this lightweight workflow harness, let me cognize and I’d be blessed to portion it alongside you.
Until next time, may your tests continue and your environment windows never run out.
~Mihai
Sources and references
The sources below assistance the investigation findings, merchandise capabilities, and CI/CD/security direction mentioned above. Product features, scheme availability, and pricing can change.
- Faros — The Acceleration Whiplash (Q2 2026): 2026 AI engineering report. Study scope, throughput, assessment load, bugs, and incidents.
- Faros — The Speed Trap (Q3 2026): Latest study takeaways. Nuance on afterward AI-adoption patterns and downstream costs.
- Superpowers (Jesse Vincent / obra): GitHub repository. Skills-based betterment workflow, planning, TDD, debugging, reviews.
- RoboRev: Official website and documentation. Local uninterrupted code review, Git hooks, assessment lifecycle.
- Wes McKinney: GitHub profile. pandas creator and Kenn Software founder.
- Anthropic: Set up Code Review for Claude Code. Hosted assessment architecture, eligibility, pricing, and triggers.
- Anthropic: Claude Code /code-review plugin. Plugin features and workflow.
- OpenAI: Review GitHub drag requests alongside Codex and Codex PR assessment help. PR reviews, prompts, and follow-up actions.
- GitHub: Using GitHub Copilot code review. Automatic reviews, suggested changes, assessment status, and customization.
- Cursor: Bugbot and Bugbot Autofix. PR assessment and assisted fixes.
- NIST: Secure Software Development Framework (SSDF), SP 800-218. Security practices throughout the software-development lifecycle.
- GitHub: GitHub Actions documentation, repository rulesets, and secure pull_request_target usage. Workflows, position checks, and rely boundaries.
- OpenAI: Codex GitHub Action and security guidance. Action configuration, read-only permissions, and secret-handling cautions.
- Adam Faik, The AI Thinker: How to build an AI-native application factory (October 2026). How Uber, Shopify, DoorDash, Spotify, Stripe and others run coding agents at scale, from intake to merge.