
Providing developers the champion exemplary for the task astatine manus has ever been our goal. Earlier this year, we made that easier by launching Auto exemplary selection, which reviews your task and matches it to the best-suited exemplary for that task.
Today, we’re introducing Project HydraFusion, a investigation preview that delivers frontier intelligence done runtime orchestration. It creates a afloat execution plan, choosing from models crossed aggregate providers to draft, critique and revise, aliases cascade to much powerful models to complete your task.
HydraFusion fills a cardinal domiciled successful our wide strategy to present automated semantic routing betwixt local, cloud, and compound models. For developers, that complexity stays down the scenes: you prime HydraFusion for illustration immoderate different model, and it chooses a workflow that balances performance, cost, and latency for each task.
HydraFusion treats workflow action arsenic an optimization problem. It uses capacity signals for reasoning, codification generation, debugging, and instrumentality usage to prime the astir businesslike execution shape to meet the value bar.
For each request, HydraFusion presently chooses 1 of 3 execution patterns:
- Single. One selected exemplary solves the task directly.
- Cascade. An businesslike exemplary drafts a solution and a value gross decides whether to judge it aliases escalate to a stronger model.
- Critique. One exemplary drafts a result, an independent read-only professional from a different exemplary family reviews it (following the aforesaid reappraisal shape arsenic Rubber Duck), and the drafting exemplary revises once.
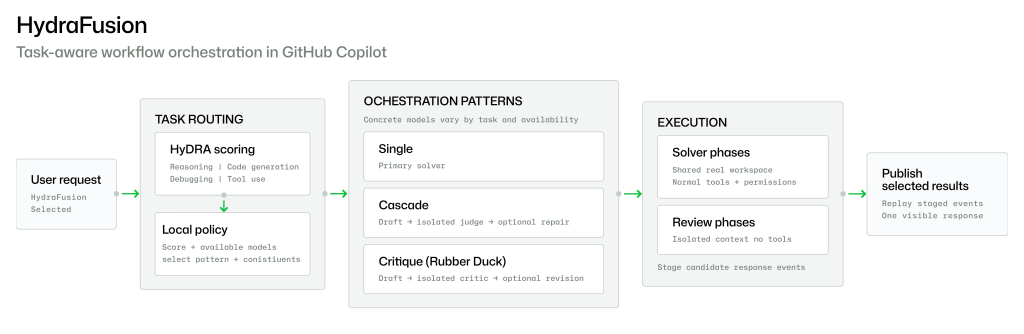 Figure 1. HydraFusion architecture
Each shape addresses a different quality-to-cost trade-off. Single preserves velocity and ratio erstwhile 1 exemplary tin lick the task directly. Cascade gives an businesslike exemplary the first effort while retaining a way to stronger conclusion erstwhile the campaigner does not clear the acceptance gate. Critique adds an independent position for tasks wherever reappraisal is much useful than different unaided attempt.
In offline evaluations crossed 3 agentic coding benchmarks, HydraFusion consistently demonstrated frontier-level value pinch important estimated costs savings. On TerminalBench 2.1, it improved verified task value by 4.9 percent points astatine 67% little estimated costs compared pinch Claude Opus 5.
Let’s dive into the approach, the results, and the benchmarks.
Adaptive multi-model orchestration
Developers already coordinate models manually: choosing 1 for a task, asking different to reappraisal the work, aliases escalating a difficult problem to a much tin model. HydraFusion brings that acquainted process into the runtime. You take HydraFusion erstwhile and enactment focused connected your task while it manages the models and workflow down the scenes.
The cardinal is selectivity. Some coding tasks tin beryllium solved directly, while others use from review, revision, aliases escalation. HydraFusion evaluates each petition and chooses the slightest analyzable workflow expected to meet its needs, utilizing further exemplary calls only erstwhile they are apt to amended the result. This adaptive attack balances quality, cost, and latency crossed models.
As the exemplary frontier advances, truthful does HydraFusion. When caller models go disposable successful GitHub Copilot, we tin measure and incorporated them into its exemplary pool, bringing their strengths to the tasks champion suited to them.
Building HydraFusion
Turning adaptive multi-model orchestration into 1 dependable coding acquisition requires observant power of execution, review, cost, and repository state. HydraFusion is built astir 5 operating principles:
- Complete accounting. Aggregate costs and usage crossed each workflow leg, including drafting, critique, revision, escalation, retry, and fallback.
- Bounded execution. Give each limb definitive timeout and cancellation behaviour to support execution and costs wrong defined limits.
- Isolated review. Run reappraisal steps successful isolated, tool-less contexts, while solver steps usage the shared workspace and normal permission-aware supplier loop. This allows models to measure the activity independently without modifying the repository.
- Fail-safe application. Apply nary spot erstwhile the workflow is cancelled aliases fails validation, preventing incomplete changes from reaching the repository.
- Validated routing. Verify workflow definitions, exemplary bindings, fallback behavior, and exemplary readiness earlier execution begins.
Together, these principles make multi-model orchestration applicable for repository-level work. Internally, the runtime records the role, outcome, cost, latency, and diagnostics of each limb truthful the workflow tin beryllium understood aft execution. Externally, the developer receives 1 coherent consequence and 1 permission-aware alteration set.
Benchmarking results
Fixed HydraFusion policies were evaluated crossed 3 agentic coding benchmarks — TerminalBench 2.1, DeepSWE, and CheckpointBench, our soul benchmark based connected existent GitHub Copilot sessions — utilizing Claude Opus 5 and GPT-5.6 Sol arsenic comparison baselines. Each argumentation utilized the aforesaid task inputs, tools, execution limits, pricing assumptions, grading conditions, and curen of missing results. The information measured verified task quality, which is the stock of tasks confirmed arsenic correctly answered, and the complete estimated workflow cost. Cost accounting included each invoked leg, specified arsenic drafting, critique, revision, escalation, retry, and fallback. The results beneath show the champion tuned HydraFusion configuration.
| TerminalBench 2.1 | 67% lower | +4.9 points |
| DeepSWE | 36% lower | -1.5 points |
| CheckpointBench | 65% lower | -0.1 points |
These controlled offline results are circumstantial to the evaluated benchmark revisions, workflow configurations, exemplary pool, and pricing assumptions, pinch each models evaluated astatine the aforesaid mean reasoning level. Through this investigation preview, we’ll validate really these results construe to existent developer workloads and usage the findings to further optimize HydraFusion for accumulation quality, latency, reliability, caching efficiency, cost, and safety.
TerminalBench 2.1
TerminalBench 2.1 evaluates coding agents connected complex, multi-step tasks successful terminal environments.
Figure 2 compares HydraFusion and Opus 5 crossed verified task value and estimated workflow cost.
DeepSWE
DeepSWE evaluates challenging repository-level package engineering tasks that require navigating ample codebases, knowing cross-file dependencies, and producing end-to-end fixes. On this benchmark, HydraFusion comes wrong 1.5 percent points of Opus 5 while reducing costs by 36%, demonstrating a compelling quality-cost tradeoff for analyzable real-world engineering tasks.
CheckpointBench
CheckpointBench is an soul multi-turn benchmark curated from existent GitHub Copilot agentic coding sessions. Each speech is anchored to a circumstantial nationalist repository and immutable commit, ensuring each convention is replayable. The benchmark is balanced crossed language, task type, difficulty, scrubbed for quality, resulting successful a realistic information group that intimately mirrors accumulation agentic sessions. On this benchmark, HydraFusion comes wrong 0.1 percent points of Opus 5 astatine 65% little cost.
Early soul testing has echoed that result.
So far, the reasoning and task solving capacity [of HydraFusion] is astatine aliases amended than Opus.
Principal Software Engineer astatine MicrosoftHill-climbing HydraFusion
HydraFusion’s routing policies were shaped by really developers usage GitHub Copilot connected existent coding tasks. To make those workflows reproducible, we curated CheckpointBench from existent Copilot coding-session trajectories. We refined HydraFusion many times crossed CheckpointBench, DeepSWE, and TerminalBench 2.1, optimizing crossed the information sets alternatively than for immoderate azygous benchmark.
HydraFusion’s per-capability scores provided a accordant ground for comparing campaigner routing policies. Instead of manually tuning thresholds, we utilized beam hunt to build the optimal determination policy. Each campaigner was measured against a stiff baseline connected quality, cost, and nonaccomplishment modes, truthful improvements were evaluated connected unchangeable ground.
TerminalBench 2.1 provides the astir complete series of runs, making it the clearest position of this iterative improvement. The progression was not linear. Between August 11 and August 25, 2 operational failures successful the information harness produced invalid runs. Those failures were excluded from the capacity trend, corrected, and followed by continued gains successful the HydraFusion configurations. By August 25, HydraFusion had reached its strongest operating points successful the recorded series.
This improvement grounds shows really the policies improved from repeated experiments. TerminalBench 2.1 was 1 of respective benchmarks utilized during development. Its comparative saturation makes broader validation important, truthful the three-benchmark information besides includes DeepSWE’s much demanding repository-level tasks. The investigation preview extends that learning loop to existent developer workloads.
Try the investigation preview
For this preview, first-turn, single-prompt coding tasks are the champion spot to start. We’ll beryllium focusing connected beardown multi-turn capacity pinch longer, iterative sessions next.
This preview is designed to study which tasks use from compound workflows and really orchestration affects latency and costs successful practice. For the champion acquisition today, commencement pinch substantial, well-scoped coding tasks that you tin manus to Copilot successful autopilot mode successful a azygous prompt. Share what you find, including wherever it excels, wherever it falls short, and what you’d want to spot next, done /feedback successful Copilot CLI aliases successful the GitHub Community discussion.
HydraFusion remains an progressive investigation effort. Results, models, workflows, availability, names, and merchandise behaviour whitethorn alteration arsenic we study from the preview. We judge the adjacent existent summation successful coding agents will travel from combining frontier intelligence pinch runtime orchestration. HydraFusion is our first stake connected that idea: moving from choosing the champion exemplary to dynamically constructing the champion measurement to lick each task.
Acknowledgments
A immense thank-you to the researchers, engineers, merchandise managers, and designers crossed GitHub and Microsoft who curated the training information and built the training pipeline, information suites, customer experience, and serving stack. We are particularly grateful to the GitHub Copilot CLI, Copilot API and VS Code squad for overcoming galore challenges to bring this investigation preview to our customers.
Meet the Team
 Aashna Garg, Principal Applied Scientist, Code AI
 Shengyu Fu, Partner Applied Science Manager, Code AI
 Carlos Castro, Partner Architect, GitHub Copilot
 Siddharth Singha Roy, Research Scientist II, Code AI
 Andy Salerno, Principal Software Engineer, GitHub Copilot
Written by

GitHub is the world's champion developer acquisition and the only AI-powered level pinch information incorporated into each step, truthful you tin innovate pinch confidence.








 English (US) ·
 Indonesian (ID) ·


