
This is astir apt the mobility I get asked astir about Spacetime. It’s a elemental capable question, and it surely seems for illustration it should person a elemental answer.
Scaling is simply a analyzable topic, and the devil is successful the details, arsenic it truthful often is. On the different hand, it’s besides not truthful analyzable that we can’t understand scalability from first principles successful a blog post.
Let’s commencement by exploring scalability successful general, and past let’s reply the question, “How does Spacetime scale?”
If you want the TL;DR: There are 3 dimensions of scale: compute, storage, and networking. Horizontally scaling retention is comparatively straightforward and shipping October 31st, 2026. However, not each networking and computation tin beryllium scaled horizontally. OLTP databases that declare wide horizontal scalability often salary tremendous overhead per transaction and execute highly poorly erstwhile faced pinch contending transactions. Spacetime provides precocious capacity nether contention and provides devices to make it easy for you to standard your parallelizable OLTP workloads.
NOTE: I talk astir CockroachDB a batch successful this article. CockroachDB is simply a unsmooth stand-in for fundamentally each wide purpose, horizontally scaling RDBMSs including Spanner and Aurora DSQL. Although I talk astir immoderate issues pinch these technologies, each of them are incredibly awesome feats of engineering.
Scale
Intuitively, everyone has an thought of what it intends to “scale”. It intends to beryllium capable to do more. It intends to support up pinch demand. It intends to grip a cardinal requests, aliases “infinite” requests, aliases an infinite magnitude of data, aliases an infinite number of customers, aliases the expertise to turn your app astatine 10x aliases 100x twelvemonth complete twelvemonth without needing to rewrite your software.
In particular, I deliberation that erstwhile astir group opportunity a strategy is scalable, they’re talking astir whether aliases not it’s specifically horizontally scalable. Whereas vertical scalability intends to do much pinch a azygous computer, horizontal scalability is the expertise to do much pinch much computers. If doubling the number of computers lets america do astir doubly arsenic overmuch work, the computation scales horizontally. After all, a azygous machine tin only beryllium truthful large and fast, but successful mentation there’s nary limit to the number of computers you tin buy. There’s thing very satisfying astir that idea, truthful that’s the spot that everyone looks for.
NOTE: The “doing much pinch much computers” meaning implies that each horizontally scalable systems must beryllium distributed systems. However, it does NOT connote that the only intent of distributed systems is horizontal scalability. For example, distributed authorities instrumentality replication is designed to redundantly do the aforesaid computation connected galore computers for the intent of reliability, not scale. More connected this beneath successful the Spacetime section.
The mobility “Does it standard horizontally?” is underspecified. A amended mobility is, “In what ways does it standard horizontally?” This is because location are really 3 beautiful independent dimensions of scalability:
- Compute: really galore transactions you tin process
- Storage: really overmuch information you tin store
- Networking: really galore connections and really overmuch bandwidth you tin support
To spot what I’m talking about, let’s look astatine a fewer database systems that each expose broadly PostgreSQL-compatible interfaces, but person radically different architectures.
For example:
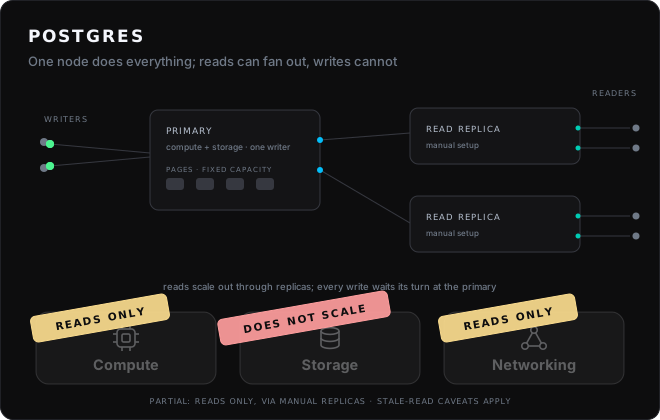
- Postgres is for the astir portion a single-node database. Postgres does not standard compute, storage, aliases networking horizontally for you. You tin of people standard Postgres horizontally by deploying galore Postgres instances, but arsenic acold arsenic the Postgres codification is concerned, it’s mostly unaware of those different instances. The 1 objection to this is publication replicas which let you to manually nonstop readers to a replica. This helps to standard some networking and compute, but it comes pinch caveats astir read-after-write consistency and performance. Postgres itself has nary conception of a cluster of primaries, cannot tally transactions aliases queries crossed them, aliases way you to the due one. You tin of people constitute package to do this, and this is really group tin and do standard Postgres horizontally, but really to do it is near arsenic an workout to the reader.
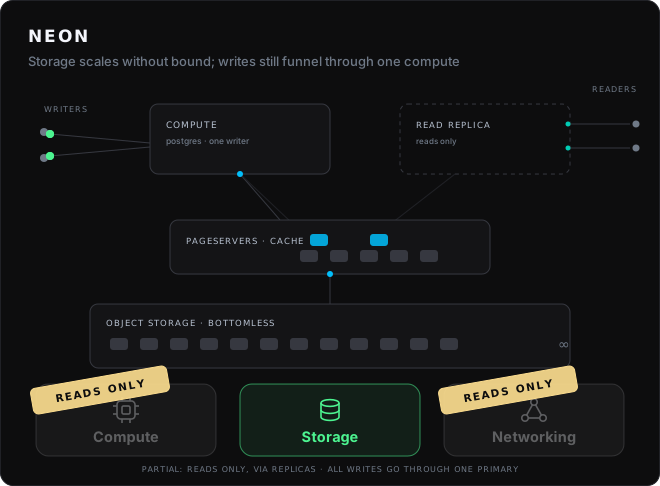
Neon, which is simply a modified version of Postgres, scales retention horizontally. Neon tables are backed by entity retention pinch a section page caching building to make information entree accelerated and efficient. Page entree latency tin beryllium higher for cache misses, but this architecture gives your Neon databases efficaciously infinite storage. Neon does not automatically standard compute and networking horizontally, however. Like Postgres, each constitute transactions must spell done a azygous primary. However, being a Postgres variant, Neon besides supports publication replicas to horizontally standard compute and networking for publication workloads, though this comes pinch similar consistency caveats.
Horizontally scaling retention is simply a large win, moreover without automatic compute scaling. Even mini web apps pinch not truthful galore users tin successful rule usage a batch of storage.
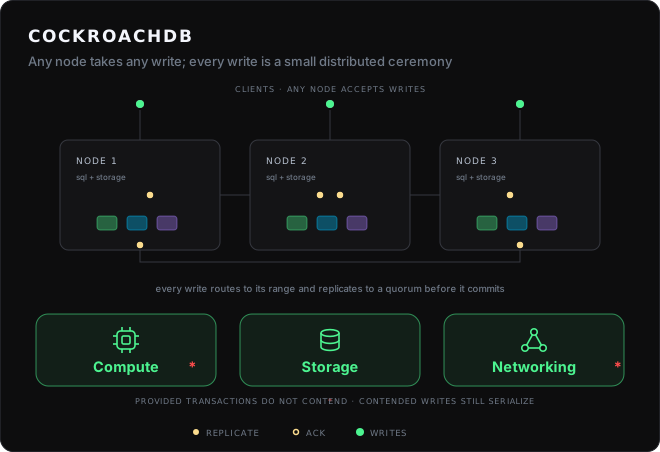
- CockroachDB (and Spanner), successful principle, scales retention horizontally by spreading each table’s information astir the cluster truthful that a information of each table, called a “range”, is stored connected each instrumentality and typically replicated to 2 different machines. Provided that writers don’t each effort to modify the aforesaid range, it tin besides standard networking horizontally. It has a symmetric architecture, meaning immoderate node successful the cluster tin service immoderate SQL request, some sounds and writes. Finally, for computation that parallelizes cleanly (e.g. analytics aliases writes to unrelated keys), it besides scales horizontally. The node you link to will compute the query scheme and return the results, but some publication and constitute operations will execute arsenic portion of a distributed transaction crossed the cluster based connected the ranges.
Can we find the Holy Grail?
So if CockroachDB is capable to standard successful each 3 dimensions, it must beryllium amended than Postgres and Neon successful each respects, right? Maybe it does thing typical pinch the CAP theorem[1] aliases atomic clocks?
Unfortunately, location is nary magic here. While CockroachDB is simply a modern marvel and does standard definite computations horizontally, not each computation can beryllium scaled horizontally. Horizontal scalability is really a mobility of parallel computing: tin we divided the computation into pieces that different computers tin do astatine the aforesaid time? The reply is often no, and the rumor is pinch CockroachDB, you salary the tremendous coordination costs of horizontal scalability moreover erstwhile information contention forces you to do updates 1 astatine a time. What CockroachDB gains successful horizontal scalability, it loses successful vertical scalability and past some.
The disfigured truth is that alternatively than doing much pinch much computers, horizontal scalability tin often mean doing less pinch much computers: conceptually what 1 machine tin do successful 1 millisecond, 10 computers tin do successful 100 milliseconds.
There are 2 main issues pinch CockroachDB’s attack to horizontal scalability:
- The information progressive successful each transaction is seldom co-located connected a azygous machine.
- No transaction has exclusive entree to a range, truthful each transaction pays distributed concurrency-control overhead, and conflicting transactions must wait, abort, aliases retry.
The first problem is caused by spreading ownership of the information evenly astir the cluster. If your information is dispersed astir the cluster, you request to do web requests for fundamentally each transaction. Although sharding often sounds inconvenient, it tin supply overmuch amended capacity if astir of your transactions run wrong a azygous shard. Also statement that Neon’s creation does not suffer from this aforesaid rumor for galore workloads because it caches basking pages connected the aforesaid machine.
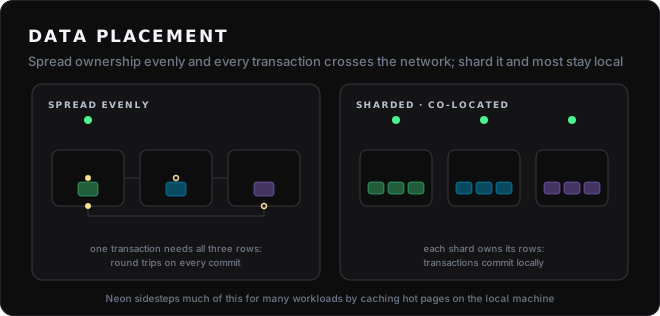
Spanner partially addresses this rumor pinch “table-interleaving” which allows you to fundamentally show Spanner to colocate related tables. This tin dramatically amended capacity successful elemental cases. CockroachDB supported array interleaving for respective years but removed it successful v21.2, judging the benefits excessively mini to warrant the complexity.
The 2nd problem is simply a wide problem of parallelizing arbitrary computation: coordination nether contention. Even vanilla Postgres runs into the aforesaid problem, conscionable connected a smaller timescale. Rather than coordinating transactions crossed a distributed system, it has to coordinate transactions crossed aggregate cores. Postgres tin tally transactions connected galore CPU cores, but arsenic soon arsenic those transactions touch the aforesaid data, they request to walk clip coordinating. The CPU itself has to coordinate earthy representation entree crossed L1, L2, and L3 cache. Another writer modifying the aforesaid cache statement tin invalidate your section transcript and unit the cores to synchronize. Postgres has to coordinate the transactions themselves: who owns a lock, which versions of rows are visible, what bid transactions perpetrate in, and whether conflicting activity needs to wait, abort, aliases retry.
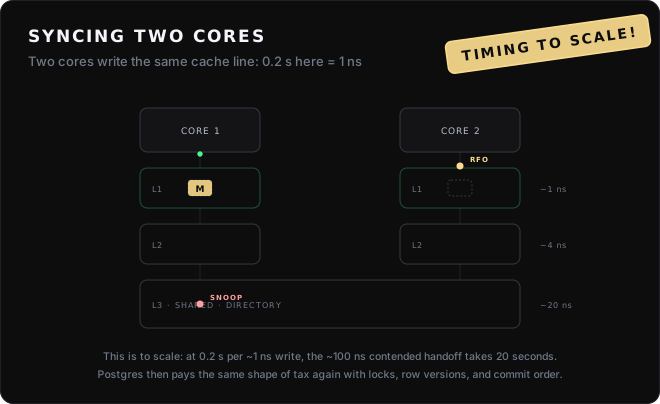
For example, ideate a mini OLTP transaction that involves a personification statement and a related metadata row. Firstly, whereas successful single-node Postgres some rows will beryllium connected the aforesaid machine, successful a CockroachDB cluster pinch N nodes and random superior keys there’s an astir 1/N probability of them being connected the aforesaid leaseholder/leader. What could person been a ~3 microsecond captious section connected a azygous halfway is now a 1 millisecond distributed captious conception pinch aggregate web requests. Even successful the 1/N lawsuit wherever the rows are colocated, the transaction still can't merchandise its locks until the constitute has been replicated to a quorum, truthful it holds them for astir the aforesaid information trip. Secondly, and moreover much importantly, a different transaction that wants to publication aliases modify the aforesaid rows must now hold 1 millisecond for our transaction to perpetrate aliases abort. These 2 problems compound multiplicatively. A basking cardinal pinch a ~3 µs captious conception admits ~300,000 contending transactions per second; astatine 1 sclerosis it admits ~1,000 tps. Counterintuitively, the single-threaded solution is 300x much “scalable” successful this scenario!
Note that pinch 1 sclerosis distributed commits, moreover conscionable 1% of transactions contending connected a azygous statement makes every horizontally scalable cluster slower than a azygous core. This is conscionable Amdahl's law applied to horizontal scalability. Contending transactions must beryllium executed serially and full throughput tin ne'er transcend the serial complaint divided by the fraction of serial transactions: (1 / 1 ms) / 1% = 100,000 TPS. No matter really galore cores you add! There's fundamentally only 1 script wherever a cluster thumps a azygous halfway connected throughput: you person nary contention AND you're paying much than $3,600 per period (based connected the model's overhead assumptions). That is simply a script immoderate companies find themselves in, but it's a niche scenario.
Under contention, aggregate writers make transactions substantially slower than conscionable moving them 1 astatine a time, because the cores walk much clip agreeing connected who gets to modify shared authorities than doing useful work.
But, even for computations that can beryllium executed successful parallel, group often dramatically underestimate really overmuch further hardware tin beryllium needed conscionable to flooded coordination overhead. As a unsmooth illustration, L1 cache latency tin beryllium astir 20x little than L3 latency. If parallelizing a workload turns cheap, section cache accesses into predominant synchronization and cross-core communication, it’s wholly plausible that you could request 10+ cores conscionable to lucifer the capacity of 1 cautiously cache-optimized core. And that doesn’t moreover relationship for the overmuch higher costs of going retired to main representation erstwhile larger moving sets and metadata, specified arsenic MVCC bookkeeping, push useful information retired of cache. And we still haven’t considered web requests and serialization required for thing for illustration distributed MVCC bookkeeping and each the cache misses those will cause. Are you judge you want to salary for 10 cores erstwhile 1 halfway will do? Maybe for a subset of problems we extremity up achieving scalability, but astatine what cost?
For inherently serial computation, you tin move it to a faster machine, optimize the code, aliases replicate the results for responsibility tolerance, but you can’t make 10 machines do it faster, nary matter really overmuch you’d for illustration to. Every programmer who has publication The Mythical Man-Month knows this intuitively. Adding programmers to a task doesn’t mean penning your package faster; it intends penning it slower but pinch much meetings. 10 authors can’t constitute a caller faster than 1, particularly if they’re coordinating by snail mail.
The civilized of the communicative is horizontal scalability isn't simply a spot that a strategy has aliases doesn't have. It's chiefly a spot of the workload.
Spacetime
So let’s talk astir Spacetime.
First, it’s worthy separating the API you usage from the architecture that implements it. Nothing astir the Spacetime programming exemplary inherently requires a single-node aliases distributed implementation.
There are galore ways to implement:
ctx.db.myTable.insert({ name: 'Tyler' });or:
SELECT * FROM my_tableThe API says thing astir wherever that information lives, which instrumentality executes the transaction, aliases really galore machines are progressive down the scenes. Convex, for example, built a transaction furniture connected apical of existing retention engines for illustration MySQL aliases Postgres. In principle, we could person implemented Spacetime pinch a fleet of Spacetime module servers and a elephantine CockroachDB cluster arsenic the retention engine. It mightiness astonishment you to study that this is beautiful adjacent to really we started. The first prototype of Spacetime was built connected Postgres + Kafka!
However, successful situations pinch little than afloat parallelism aliases less than dozens aliases moreover hundreds of machines, this results successful worse capacity contempt a overmuch higher cost. This blog post explains successful item why that is.
Spacetime began arsenic the backend for our real-time MMORPG, truthful we simply had utmost transaction latency and throughput requirements from the very beginning. We could not spend to make the communal lawsuit prohibitively costly simply truthful that the uncommon lawsuit could span arbitrary numbers of machines. These requirements forced america to build our ain civilization retention and execution motor from scratch.
Perhaps surprisingly, coming the execution exemplary for Spacetime databases is single-threaded by design. Intuitively, particularly to engineers pinch constricted acquisition optimizing cache performance, this could sound for illustration “bad news”. Initially, we started pinch that presumption too: early versions of our civilization database motor utilized parallel execution enabled by MVCC transactions. The rumor is that erstwhile we really measured, we recovered that single-threaded execution level retired outperformed parallel execution. In a sense, it astir apt costs america much than $1m conscionable figuring retired that we should conscionable usage a large ol’ lock. It’s not impossible that we could instrumentality parallel execution wrong a azygous database successful the early which achieves amended capacity successful constricted situations, but not without highly observant engineering and capacity measurement to guarantee that it doesn’t present much complexity and overhead than it’s worth.
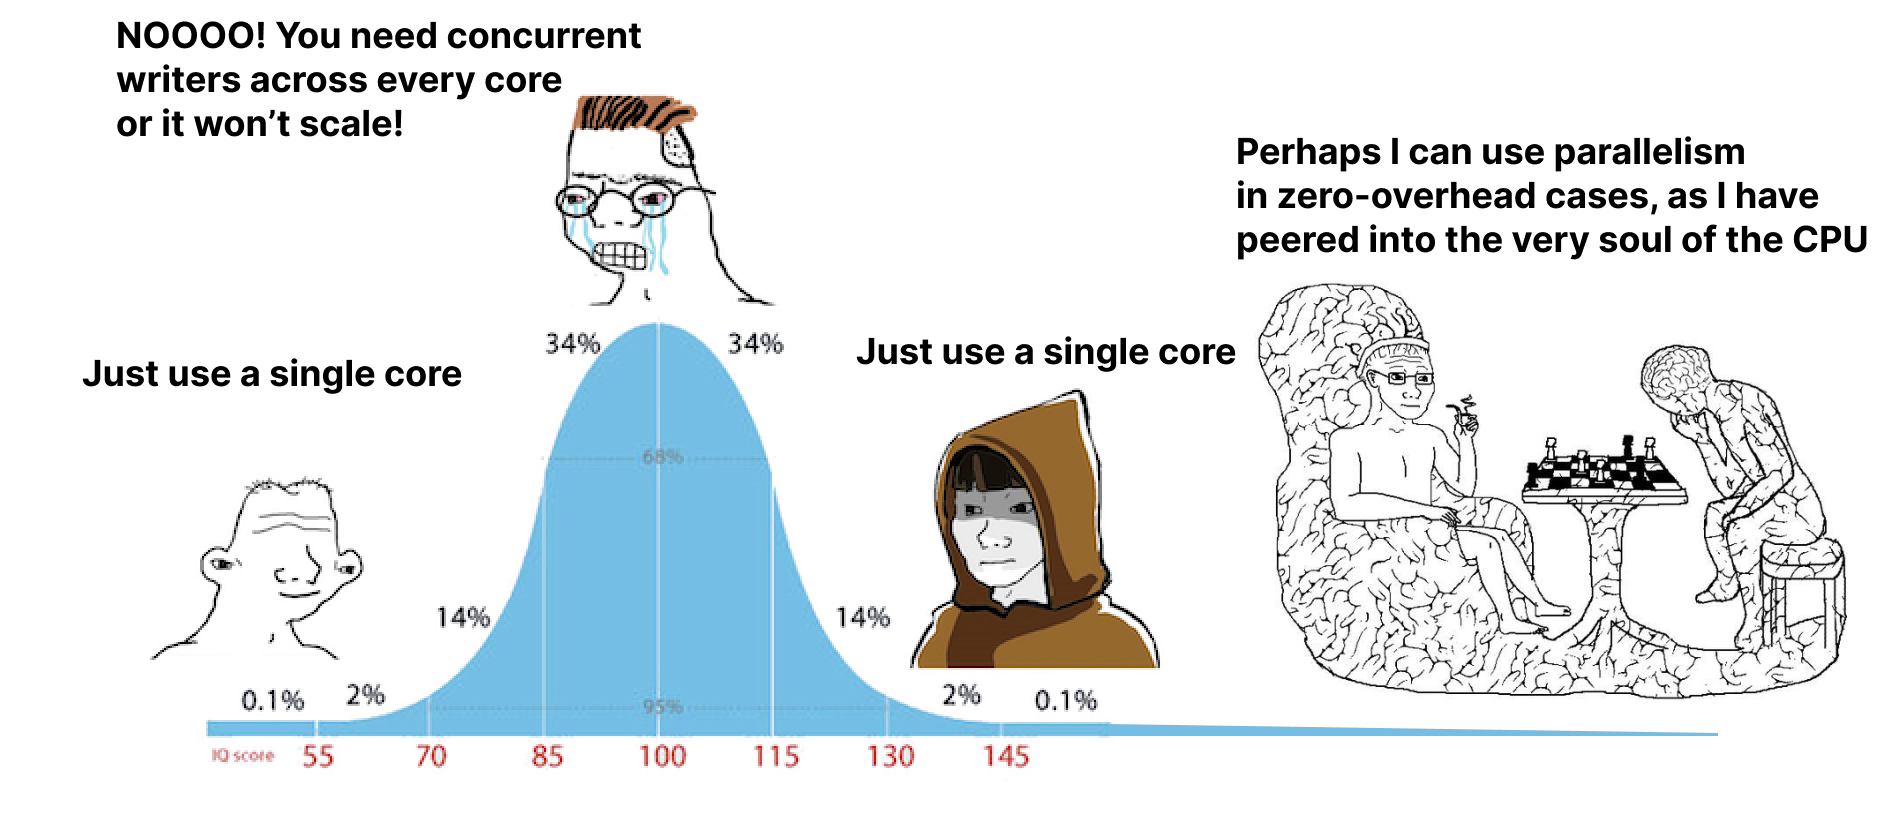
So does this mean that Spacetime cannot standard horizontally? Not remotely.
Scaling Spacetime Horizontally
The instauration for Spacetime’s horizontal scaling solution is inspired by the actor model. The character exemplary is simply a wide exemplary of parallel computing, “motivated by the imaginable of highly parallel computing machines consisting of dozens, hundreds, aliases moreover thousands of independent monoprocessors, each pinch its ain section representation and communications processor, communicating via a precocious capacity communications network.”
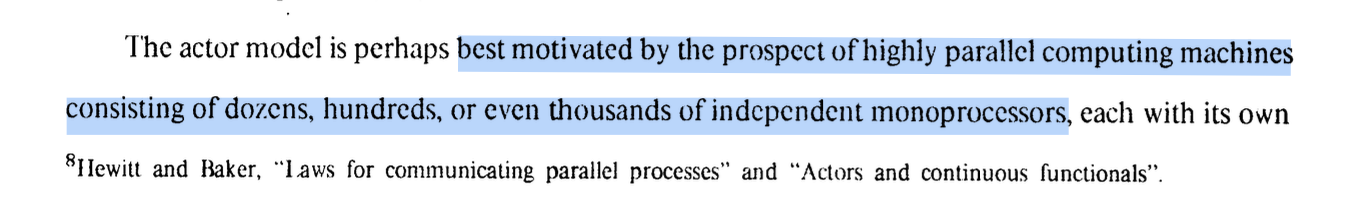
Today successful Spacetime, each database is simply a single-threaded character and we person a six-step strategy to make horizontal scalability an progressively friendlier dev experience.
The adjacent shape already has a date: asynchronous inter-database connection and gradual retention vessel connected October 31st, 2026 arsenic portion of our scalability launch: Spacetime Continuum.
| 1 | Deliver replicated databases pinch world-class performance | Today |
| 2 | Deliver a world-class sharding experience (async IDC) | Oct 31, 2026 |
| 3 | Scale each database’s storage horizontally (tiered storage) | Oct 31, 2026 |
| 4 | Scale each database’s networking horizontally (read replicas) | Planned |
| 5 | Implement inter-database transactions (sync IDC) | Planned |
| 6 | Implement intra-database partitioning | Planned |
Before going into the details, location are 2 versions of Spacetime worthy distinguishing:
- SpacetimeDB Standalone, the single-node type disposable connected GitHub.
- SpacetimeDB Cloud, the proprietary, clusterized version.
Replicated databases pinch world-class performance
We’ve already talked astatine magnitude astir really each Spacetime database achieves world-class, single-threaded capacity but it’s important to statement that SpacetimeDB Cloud besides supports distributed authorities instrumentality replication for databases.
This intends that moreover though each database is single-threaded, it isn't needfully moving connected only 1 machine. This sounds counterintuitive, but the wide thought is that we tin replicate what a azygous thread is doing onto aggregate machines truthful that if machines fail, the database remains available. This intends that each database successful SpacetimeDB Cloud operates arsenic a distributed system.
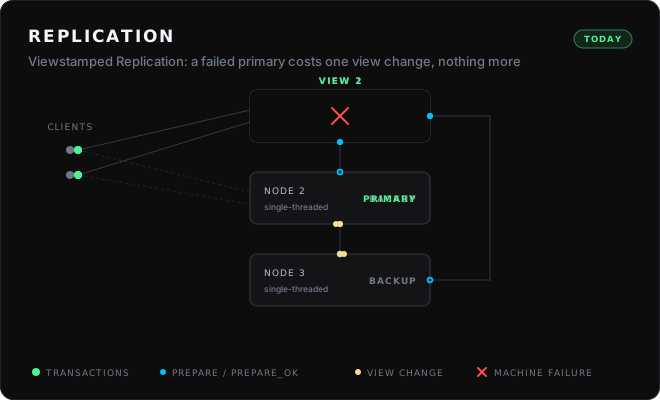
It’s important to statement that pinch our pipelined implementation, we've demonstrated successful our benchmarking that replicated databases execute the aforesaid throughput arsenic unreplicated databases (roughly 300k TPS for the benchmark transactions), provided location is capable web bandwidth betwixt nodes and representation for pipeline depth.
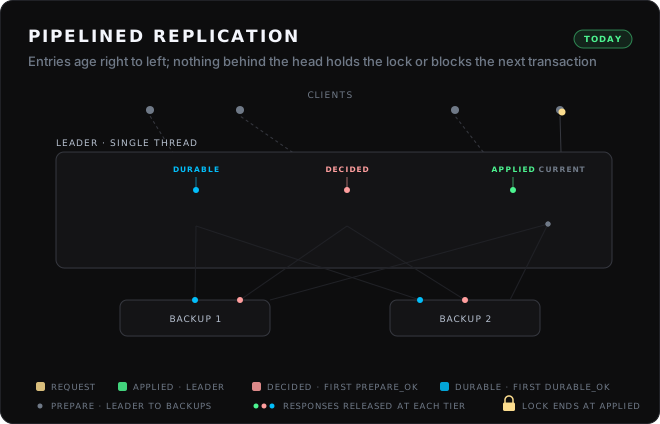
Note that confirmedReads(true), the default mounting for Spacetime, configures clients to publication only aft transactions scope durable position connected the cluster.
World-class sharding experience
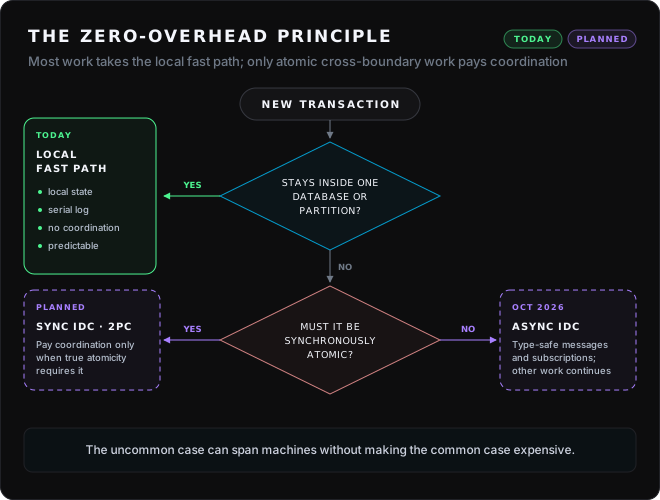
Sharding your database gives you the champion capacity for transactions that run solely wrong a azygous shard. Distributed transactions springiness you the expertise to tally transactions which span shards. Why can’t we person the champion of some worlds? What if astir transactions operated wrong a azygous instrumentality and we gave the programmer devices to shape their information truthful that astir transactions hap wrong that machine? Only successful uncommon instances should we request to do a distributed transaction.
The cardinal is to make the shard bound definitive and ergonomic. In the character model, each shard tin behave for illustration its ain independently scheduled actor: transactions wrong a shard stay fast, local, and single-threaded, while only transactions that genuinely request to touch aggregate shards salary the costs of coordination. This lets the architecture sphere the capacity characteristics that make Spacetime accelerated coming without pretending that distributed coordination is free.
Each database is an independent character pinch its ain authorities and transaction log, truthful transactions against different databases tin execute concurrently without coordination.
Spacetime already provides devices for managing this architecture. Databases tin beryllium created arsenic children of different databases. Procedures tin people databases and telephone functions connected them. A guidelines database tin support way of the identities and authorities of the databases beneath it.
Several of our customers run hundreds aliases thousands of databases successful this measurement and BitCraft besides scales this way. A azygous guidelines database maintains world data, while region databases grip different parts of the world and different groups of players. Transactions wrong 1 region stay accelerated and local, while the regions themselves execute successful parallel.
We scheme to make this exemplary considerably easier done first-class inter-database connection (IDC). Asynchronous IDC will let 1 database to telephone functions connected different database successful a type-safe way.
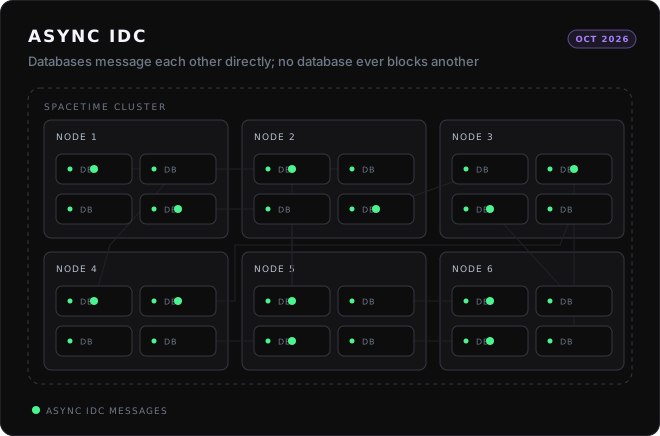
At a precocious level, the TypeScript APIs will look thing for illustration this:
// Async IDC: nonstop a type-safe connection to different database. // This will consequence successful precisely 1 reducer telephone connected the target DB. ctx.db.receivePlayer.insert({ msgId: 0n, target: regionDb, player, });Scale each database’s retention horizontally
As of today, Spacetime stores each array information in memory connected the leader node. This intends that successful a azygous database, the magnitude of information you tin put successful your tables is constrained by the beingness representation of the machine.
However, this regularisation is not basal to Spacetime aliases the cardinal to its unthinkable performance. We position memory, disk, and entity retention arsenic a earthy hold to the CPU cache model. Spiritually we dainty representation arsenic L4 cache, disk arsenic L5 cache, and entity retention arsenic L6 cache. This caching exemplary is simply a time-honored measurement to get maximum capacity from a azygous writer. This is often referred to arsenic “tiered storage”.
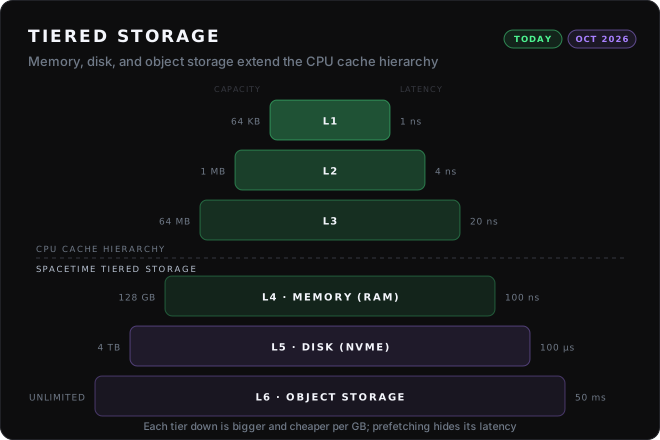
Cache lines and prefetching let you to preemptively propulsion successful batches of information from cheaper, slower retention into much expensive, faster storage. Providing gradual retention to databases allows you to amortize the costs of cache misses, and execute capacity which is wide adjacent to the faster, much costly storage, while still retaining the scalability of bigger, cheaper storage.
Won't paging stall the azygous thread?
If each transaction executes connected 1 thread, it mightiness look for illustration a azygous cache miss to entity retention would stall the full database for 50 milliseconds. That would beryllium for illustration operating a room and immoderate clip a customer puts a book connected order, you make the full statement of customers guidelines location and hold for 2 weeks for the book to travel successful earlier processing the adjacent customer. Obviously silly. The norm that makes gradual retention compatible pinch single-threaded execution is simple: don't hold for a cache miss while holding the lock. Order books asynchronously and process the adjacent customer while you're waiting!
Fortunately, this is simply a good studied problem. H-Store called the method anti-caching: execute the transaction normally, and the infinitesimal it touches information that isn't resident, abort it, fetch the information asynchronously, and tally different transactions while you wait. When the information arrives, tally the transaction again. Aborting is astir free because thing has committed, and each re-execution costs microseconds of CPU against the milliseconds of I/O it avoids serializing. Calvin utilized a akin instrumentality it called reconnaissance queries: dry-run the transaction against a caller snapshot to observe what it reads, prefetch that, past execute for real. TigerBeetle runs an definitive prefetch shape earlier synchronously applying each batch of transactions.
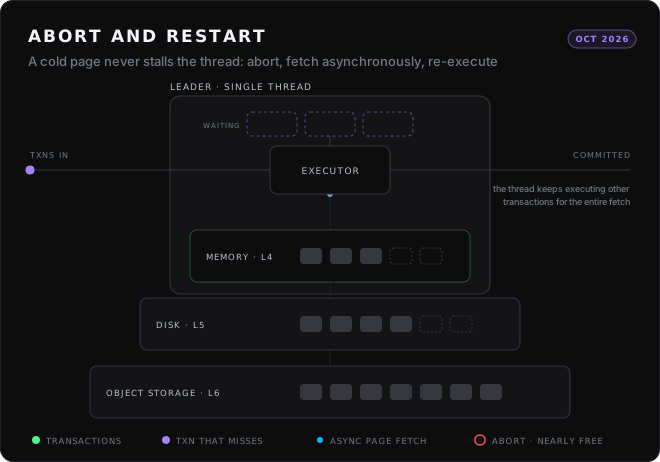
Spacetime is unusually good suited to these techniques because reducers are deterministic. A reducer cannot execute I/O, publication clocks, aliases make randomness, and each information entree goes done the reducer context, truthful the motor observes each publication a transaction makes. That intends aborts person nary visible effects, a re-execution against the aforesaid authorities touches precisely the aforesaid rows, and a barren tally discovers the information the existent tally will need.
This is simply a strategy that the highly tin squad astatine TigerBeetle mention to arsenic “diagonal scaling”.
Disk and entity retention tables will beryllium releasing connected October 31st, 2026. We position this arsenic a captious betterment to the scalability of Spacetime. With disk tables, we tin greatly summation the retention limits and alteration the prices of information storage. With entity retention tables, we tin efficaciously region retention limits and let you to shop a theoretically unlimited magnitude of information successful a azygous database.
Scale each database’s networking horizontally
As alluded to previously, overmuch for illustration compute, scaling networking horizontally is not ever imaginable because successful immoderate cases writers want to mutate the aforesaid state, and truthful request to link to and nonstop information to the aforesaid computer. This is 1 of the reasons CockroachDB recommends utilizing random keys to debar hotspots connected the cluster. However, moreover successful specified instances we should strive to support maximum imaginable scholar and writer throughput.
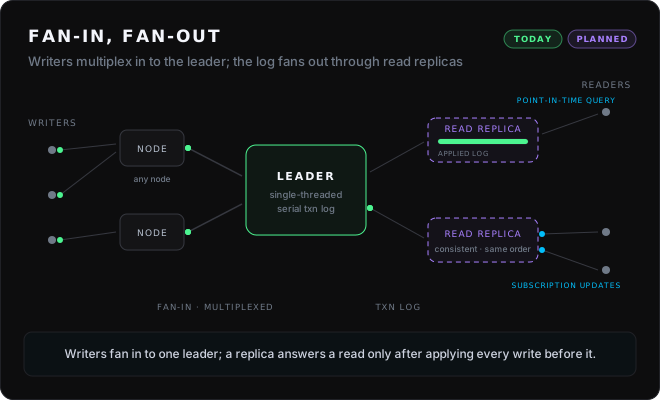
Like CockroachDB, SpacetimeDB Cloud besides has a symmetric architecture, meaning that you tin link to immoderate node and SpacetimeDB Cloud will guarantee your constitute petition gets processed aliases proxied to the correct place. From the extracurricular it benignant of looks for illustration 1 elephantine computer. For writers, this allows america to “fan-in” the connections. Clients link to immoderate node, and that node will multiplex those connections complete a azygous relationship to the node that hosts the database.
In principle, we tin besides move the processing of SQL subscriptions and publication queries disconnected the leader by introducing accordant publication replicas. Consistent publication replicas let america to “fan-out” from the leader. Instead of connecting straight to the leader, subscription information tin beryllium routed to a accordant publication replica. In truthful doing, we tin standard scholar connections and bandwidth horizontally.
“Consistent" present intends the replica applies the leader's transaction log successful the aforesaid full order, truthful a subscription sees precisely the aforesaid series of updates, conscionable delayed. For point-in-time SQL queries, the leader will delegate each query a position successful the transaction log without executing it, and a replica won't reply the query until it has applied done that offset. Reads are truthful linearizable pinch respect to each write, and the leader's only costs is handing retired series numbers.
Inter-database Transactions
Synchronous IDC provides the built-in two-phase perpetrate machinery required to do existent distributed transactions of the benignant that CockroachDB provides. This will let a transaction to span aggregate databases wrong a cluster erstwhile existent atomicity is required.
The TypeScript API for this looks conscionable for illustration calling a regular reducer, isolated from connected a overseas database.
// Sync IDC: telephone different database wrong the existent transaction. ctx.at(regionDb).reducers.receivePlayer(player);There is an evident hostility here. If each database is simply a azygous thread down 1 large lock, past a synchronous telephone from database A into database B holds B's fastener until A's transaction commits aliases aborts, which takes a web information trip. Our scheme is to support execution single-threaded but reintroduce MVCC for these distributed transactions to let concurrent transactions to proceed while the round-trip is in-flight.
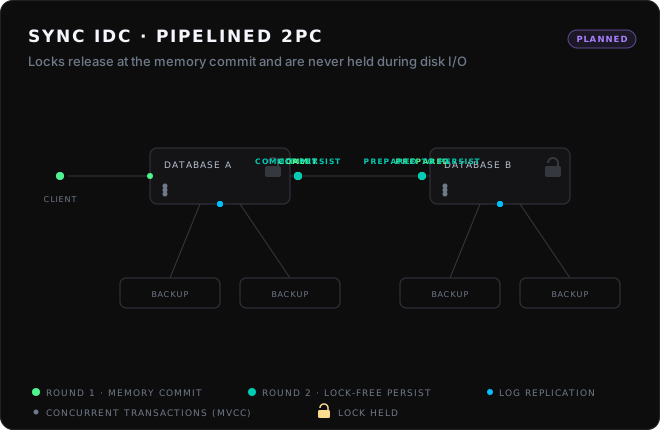
We've designed a pipelined two-phase perpetrate protocol which commits transactions successful representation first and ne'er holds the database fastener during disk I/O, and we've model-checked its information properties successful TLA+. The specifications are worthy a abstracted post.
Together, these features will move aggregate databases into a cohesive distributed exertion without putting distributed coordination successful the way of each transaction. Most activity will stay section and asynchronous. Only operations that genuinely require atomicity crossed databases will salary the costs of a distributed transaction.
Intra-database partitioning
Multiple databases are a earthy scaling boundary, but they besides require you to negociate aggregate modules, update their schemas independently, and fig retired really to rebalance load arsenic it changes. The adjacent measurement to reside these UX issues is to present partitions wrong a azygous logical database.
Partitions will let 1 database module to incorporate aggregate independently executing shards. This preserves a azygous deployment artifact and allows schema changes to beryllium applied atomically crossed the full database, while transactions against different partitions execute concurrently.
A partition successful Spacetime is simply a different point from a scope successful CockroachDB. A scope is simply a placement decision: it says which instrumentality stores immoderate portion of a table, but immoderate transaction tin still touch immoderate range, and each constitute is replicated and coordinated the aforesaid measurement nary matter wherever it lands. A Spacetime partition is an execution unit. It owns its data, it has its ain serial transaction log, and the reducer codification that operates connected that information runs wrong it. Developers take partition boundaries to lucifer the building of their workload truthful that the communal transaction ne'er leaves its partition, and Spacetime tin move full partitions betwixt machines to rebalance load without weakening that guarantee.
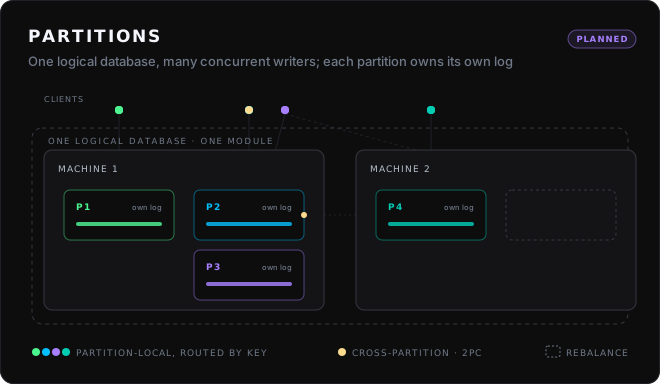
A transaction that ne'er leaves its partition pays thing for the beingness of the others. This is the zero-overhead principle: you should not person to salary for horizontal scalability until you usage it.[2]
So, does it scale?
Yes, it does. Today, you tin standard parallel workloads by sharding them crossed databases while keeping each shard accelerated and local. As we’ve seen, this architecture is arsenic bully arsenic it gets if your workload has almost immoderate contention, aliases if you'd alternatively not salary for a ample cluster to get the capacity of 1 core.
Over time, gradual storage, inter-database communication, distributed transactions, and partitions will make that architecture progressively transparent. The extremity is not to make coordination free. It is to guarantee you only salary for it erstwhile your workload really requires it.
Tyler Cloutier
Cofounder, Clockwork Labs
[1] A little speech astir the CAP theorem for the distributed systems nerds. The CAP theorem, besides known arsenic Brewer’s Theorem, simply states that nary strategy tin successful wide beryllium each 3 of: consistent, available, and partition tolerant. A strategy tin beryllium 0, 1, aliases 2 of those things, but ne'er 3.
“Consistent” successful this lawsuit intends that each publication receives the astir caller constitute aliases an error. In practice, this spot is achieved by correctly implementing distributed authorities instrumentality replication (aka immoderate version of Paxos/Viewstamped Replication).
“Available” intends each petition to a non-failing node receives a non-error response.
“Partition tolerant” intends that the strategy exists successful a world wherever messages betwixt nodes tin beryllium delayed aliases dropped entirely.
If I perceive different personification vaguely motion astatine the CAP theorem arsenic “proof” that a database tin aliases cannot beryllium horizontally scalable, I whitethorn conscionable person a intelligence breakdown. There is for immoderate logic a communal misconception that the CAP theorem, besides known arsenic Brewer’s theorem, someway limits the scalability of OLTP database systems. For example, I person been asked by investors and engineers possibly half a twelve times really we “got astir the CAP theorem” successful bid to get the Spacetime benchmark numbers. In reality, the CAP theorem makes nary remark connected it.
My mentation is that this misconception arose from this publication and this paper by Google’s Eric Brewer, the original formulator of the conjecture (now theorem: it was later proven successful this paper by Seth Gilbert and Nancy Lynch), specifically because Spanner is known to beryllium the famous horizontally scalable SQL database. Perhaps it sewage into the aerial that because this insubstantial references some the CAP theorem and Spanner, CAP theorem must someway beryllium important for scalability. However, you will statement that the original Spanner insubstantial makes nary mention of the CAP theorem astatine all.
At immoderate rate, the CAP theorem is only applicable to databases insofar arsenic the best you tin do is make a prime betwixt designing a CP strategy aliases an AP system. In a CP strategy you’re ever consistent, but sometimes unavailable owed to web failure, and successful an AP strategy you’re ever available, but sometimes inconsistent owed to web failure.
So because we can’t make networks infallible, successful a consciousness the CAP theorem is conscionable asking the question: do you want to beryllium correct aliases available? The CAP theorem says thing astatine each astir throughput, latency, aliases scalability.
Regardless, successful believe for OLTP databases, location isn’t moreover a existent prime to make. OLTP databases pinch beardown consistency guarantees, including Spanner, must beryllium CP systems, because inconsistency intends that your users spot the incorrect results (stale reads, non-monotonic reads, conflicting writes, which could successful uncommon instances descend your full e-commerce business).
Through this lens, you tin now intelligibly spot that the CAP theorem is not absorbing aliases applicable to scalability. The really absorbing mobility is: really tin we build a horizontally scalable, accordant (i.e. correct) OLTP database system?
The Consistency successful CAP is intimately related to Isolation successful ACID (Confusingly, Consistency successful ACID describes something other entirely). CAP's consistency is linearizability: operations look to hap successful a azygous bid that respects existent time. ACID's isolation, astatine its strongest, is serializability: transactions look to hap successful immoderate serial order. A database that gives you some is “strictly serializable”, which is what Spanner offers.
Linearizability requires that each transaction beryllium assigned a position successful 1 world bid that respects existent time. For transactions that touch the aforesaid data, that bid is inherently serial, which is the contention problem discussed above. For transactions that don't, the bid still has to beryllium agreed on, and statement would ordinarily mean coordination by measurement of connection passing.
Now we tin besides understand why Spanner uses atomic clocks. The atomic clocks let Spanner to delegate a linearizable bid to transactions that person nary communal information limitations (i.e. they are trivially parallelizable) and mightiness beryllium executing connected different sides of the earth. The clocks let Spanner to opportunity which transaction happened first without needing to nonstop messages astir the world to determine the comparative ordering of transactions which would NOT different request to coordinate.
[2] What astir queries and transactions that span partitions? We surely could yet support them. Distributed SQL queries crossed partitions would retrieve the wide horizontal scalability offered by systems specified arsenic CockroachDB while preserving Spacetime's accelerated section way for transactions that stay wrong 1 partition.
However, we apt wouldn't let reducers that could publication and constitute crossed partitions because that's the aforesaid capacity footgun we've discussed astatine length. Instead, partitions would still colocate related information and your module codification would still explicitly respect those boundaries, but clients would beryllium capable to do SQL queries and subscriptions globally crossed each partitions.
This could beryllium operationally convenient aliases useful for specialized workloads, but it's unclear arsenic of coming whether this last shape is worthy the complexity, aliases whether astir of these queries should really conscionable target a read-only analytics database cluster instead. Either way, for performance's sake, cross-partition queries astir apt shouldn't beryllium the champion of your application.
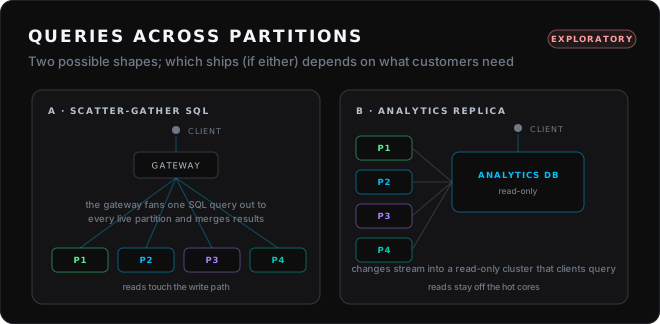
For this one, I deliberation it's champion to return a listen-to-our-customers attack and spot what they really need.








 English (US) ·
 Indonesian (ID) ·


