
Today, we’re releasing Mercury 2.5, our astir tin accumulation exemplary yet. It is simply a important measurement up successful value complete Mercury 2, pinch the aforesaid low-latency, low-cost serving profile.
Since Mercury 2’s launch, thousands of developers person built pinch it, dozens of enterprises person put it into production, and usage has grown complete an bid of magnitude. It now serves latency-sensitive workloads crossed search, voice, and coding products.
Those workloads gave america a clearer awesome than benchmarks alone. We utilized customer feedback and accumulation nonaccomplishment cases to sharpen the evals and attraction training. Mercury 2.5 is the first consequence of that loop.
What changed
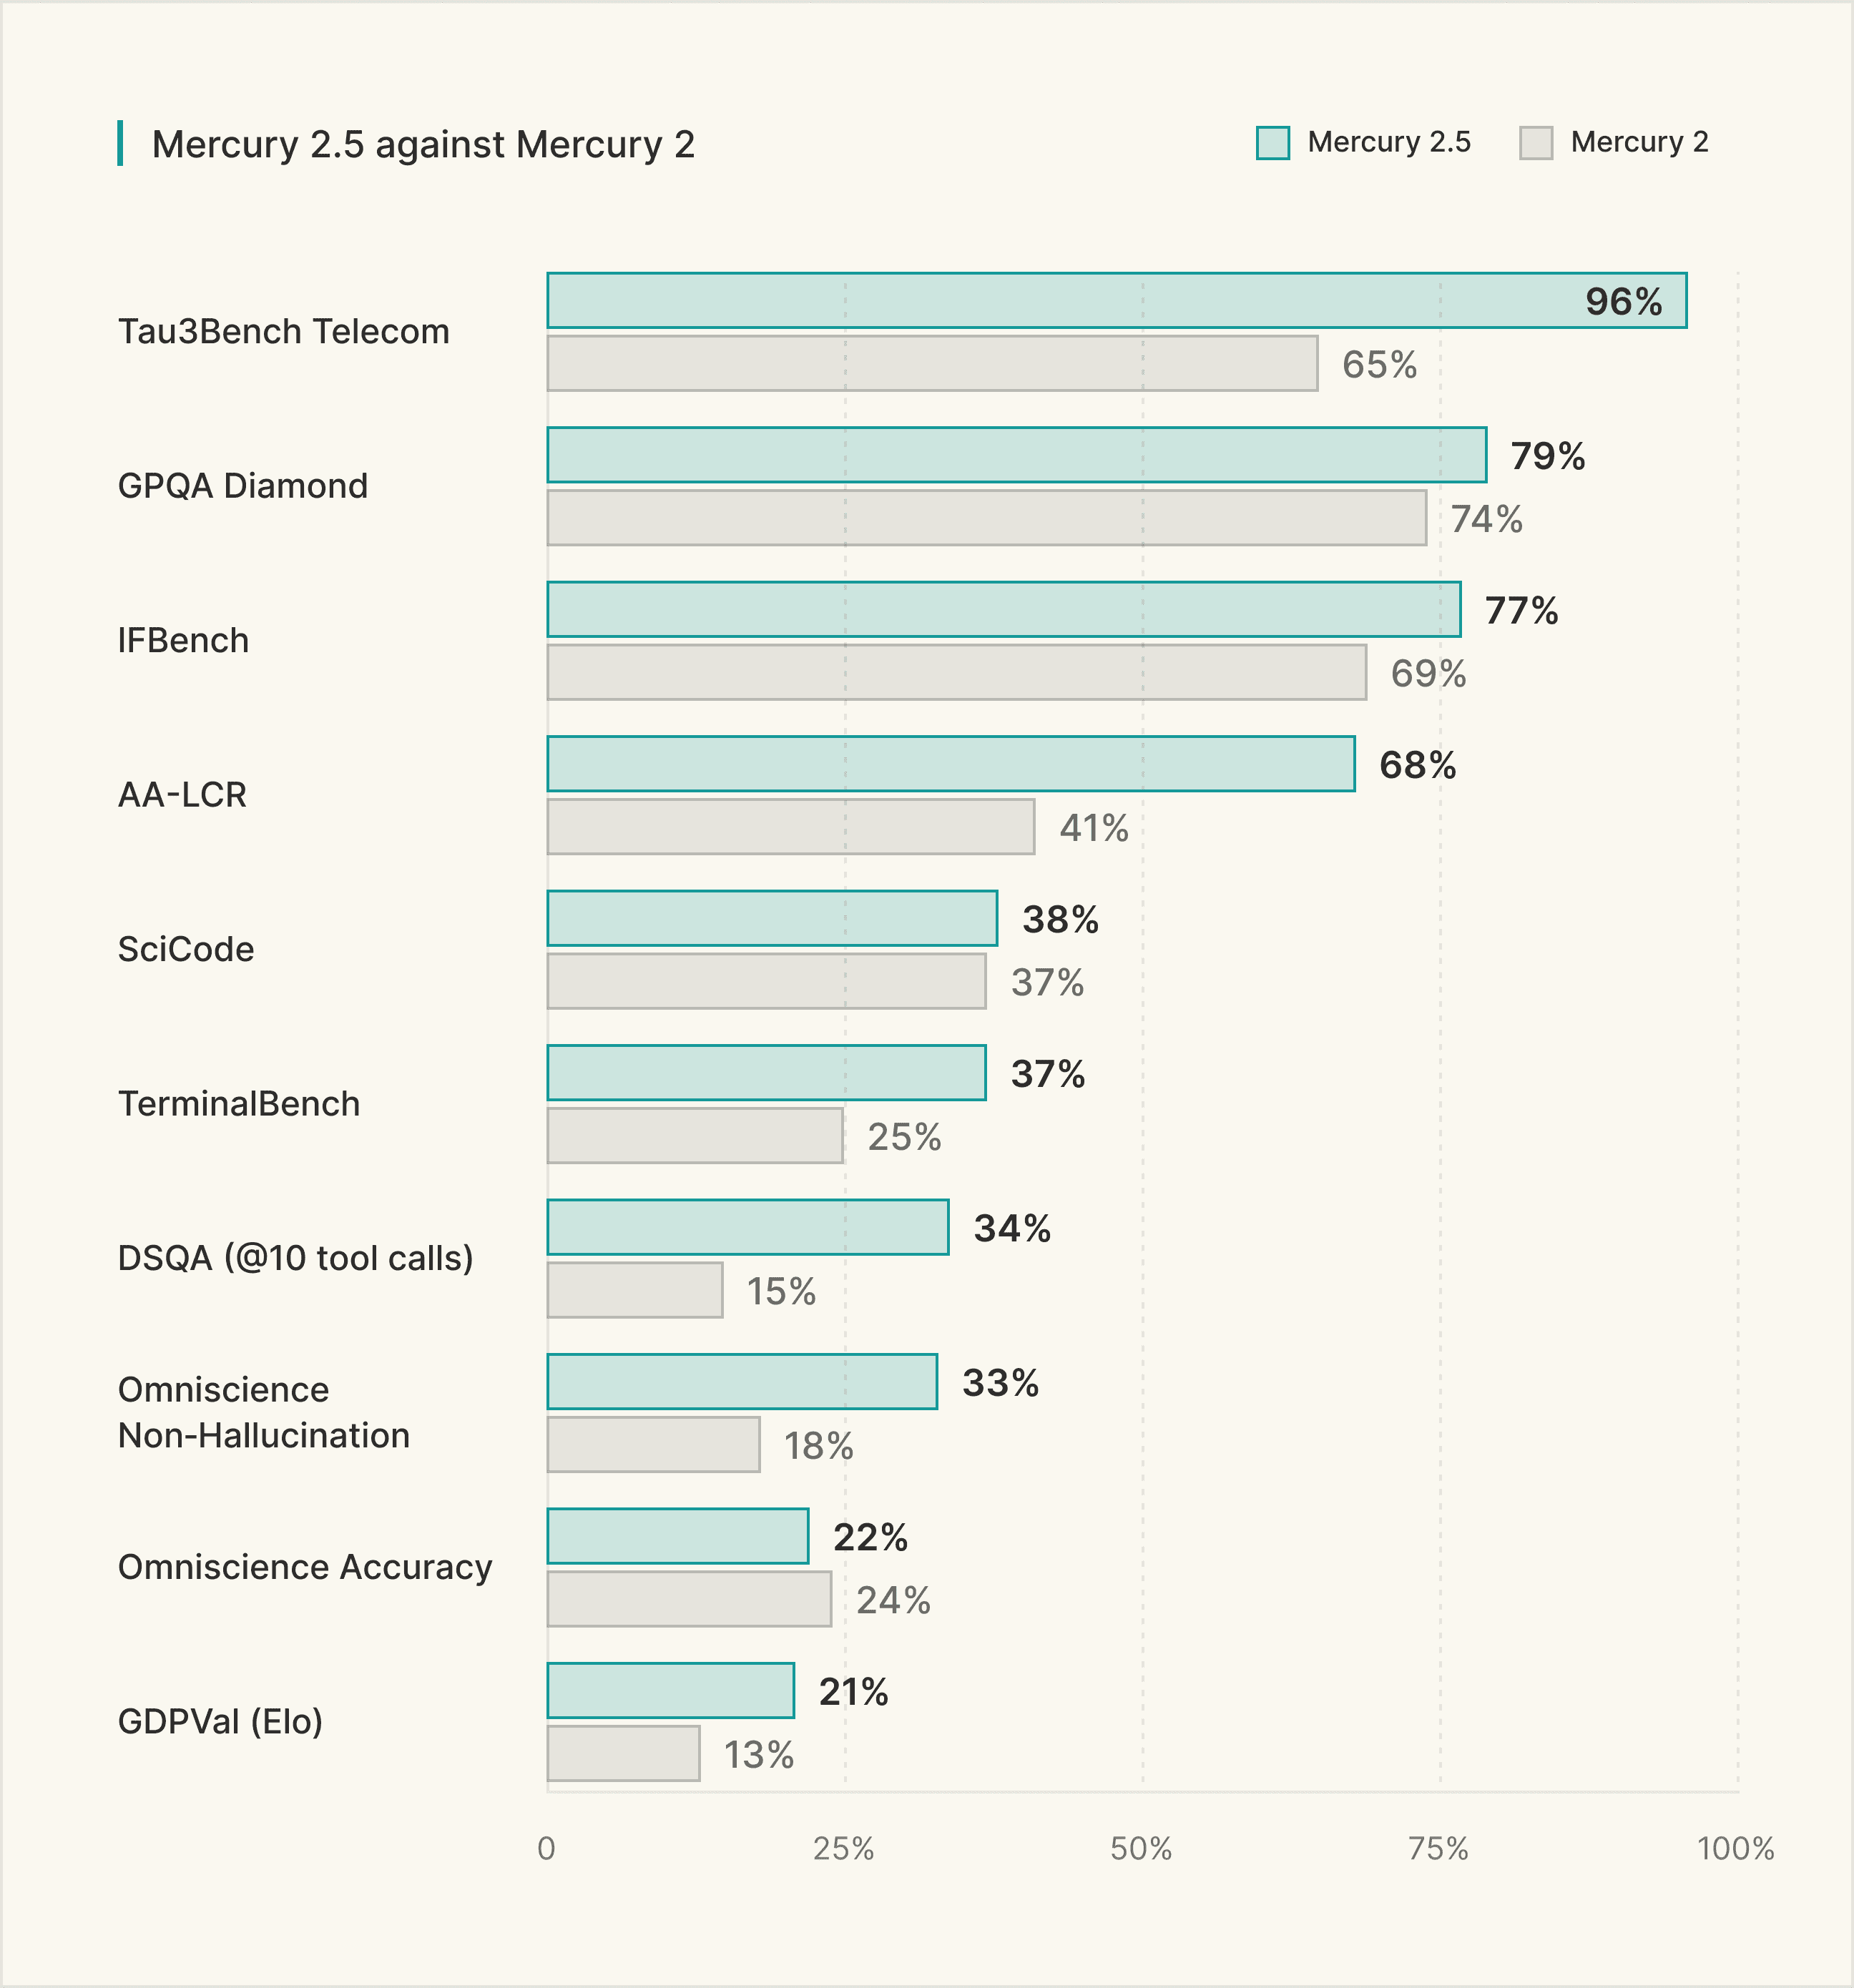
Mercury 2.5 is the astir tin diffusion LLM connected the market. To our knowledge, it is the largest diffusion connection exemplary ever trained.
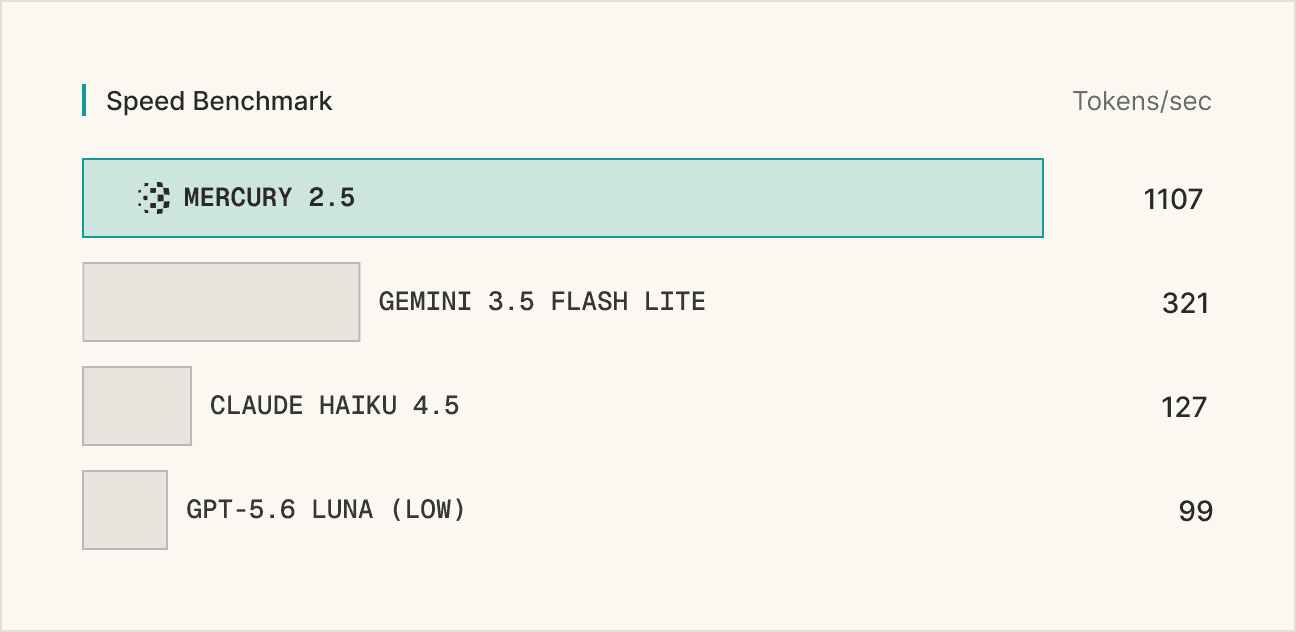
Quality: 40% summation successful intelligence from Mercury 2. Comparable to cost-optimized frontier models for illustration GPT-5.6 Luna (Low), Gemini 3.5 Flash-Lite, and Claude Haiku 4.5.
Speed: 1,107 tokens per 2nd connected widely-available NVIDIA GPUs.
Context: 260K tokens.
Price: $0.20 per cardinal input and $0.75 per cardinal output.
At launch, Mercury 2.5 is 80% disconnected astatine $0.04 per cardinal input and $0.15 per cardinal output.
Capabilities: Tunable reasoning, parallel instrumentality calls, and schema-aligned JSON.
Since Mercury 2's launch, we've watched Inception beforehand diffusion-based connection models further connected NVIDIA AI infrastructure. Mercury 2.5's measurement up successful intelligence paired pinch sustained speeds and debased costs, reflects really quickly caller architectures tin mature into production-ready systems connected the NVIDIA platform.
Shruti Koparkar, Senior Manager of Product, Accelerated Computing Group astatine NVIDIA
Mercury successful production
Search Agents and RAG pipelines
One hunt petition tin trigger dozens of exemplary calls: scheme the search, rewrite queries, rerank results, building facts, summarize sources, and cheque the answer. Mercury keeps those calls accelerated capable to enactment wrong a azygous personification interaction. Several starring search-infrastructure companies now tally it successful production.

Voice agents and interactive applications
In voice, latency isn’t an infrastructure detail. It is the region a caller hears.
OpenCall builds AI telephone agents that grip unrecorded customer calls. On its accumulation workload, Mercury brought median exemplary consequence latency adjacent to 170 milliseconds.
After we switched to Mercury, our P99 consequence clip dropped from respective minutes to conscionable 1 second, and our P50 dropped from 0.4 seconds to nether 0.2 — importantly faster than immoderate different supplier we’ve seen, and that’s including reasoning.
Oliver Silverstein, Co-founder and CEO, OpenCall
Coding subagents and assistants
Coding agents already divided activity crossed models. One whitethorn scheme aliases constitute codification while others search, tally tools, way requests, summarize state, aliases compact a agelong session. Those supporting calls hap again and again, truthful latency and costs compound quickly.
Augment Code uses Mercury for discourse compaction, exemplary routing, and MCP instrumentality search. Moving compaction to Mercury trim latency by 82%, from astir 150 seconds to 27 seconds, and reduced costs by 90% while maintaining quality. Tool-search summaries return successful nether a second.
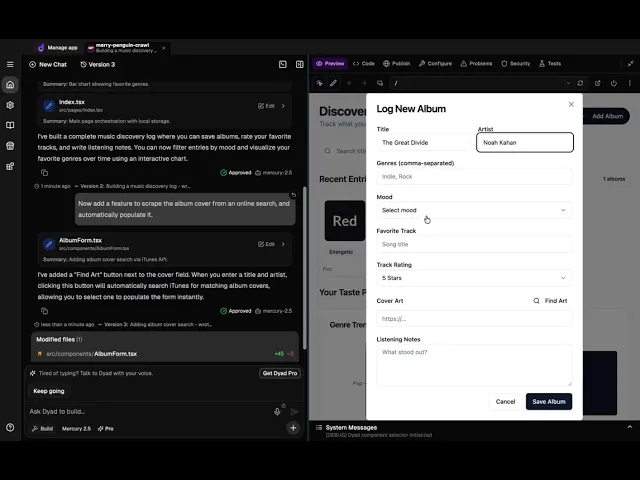
The aforesaid velocity applies to processing web apps. Watch Mercury 2.5 make a moving euphony find log web app from a fewer prompts successful the demo below.
Mercury Voice and Mercury Router Preview
Alongside Mercury 2.5, we’re announcing a preview of Mercury Voice and Mercury Router.
Mercury Voice delivers time-to-first-token (TTFT) nether 170 milliseconds and is simply a dLLM optimized for sound agents pinch the tightest latency budgets.
Mercury Router understands incoming prompts pinch a dLLM and routes them to the champion models (open and closed models) that connection the champion operation of quality, speed, and cost.
Get Started
Mercury models are disposable done our Inception API, Baseten, and OpenRouter. Enterprise deployments support dedicated capacity, autoscaling, compliance controls, and configurable information retention.
Try Mercury 2.5 successful chat
Try the API pinch 100 cardinal free tokens · Read the API docs
Baseten customers: Deploy Mercury 2.5 done your existing Baseten setup.
Y Combinator companies: Claim $500,000 successful deployment benefits.
Evaluating Mercury for voice? We’ll activity pinch you to trial workload fit, and validate capacity nether your serving constraints. Contact us.
What’s Next
We person already started training our adjacent model. It is our largest exemplary yet, and we are targeting a merchandise successful the coming months. Our adjacent exemplary will beryllium a leap successful capacity without giving up diffusion’s velocity and token-efficiency. That requires advancement connected exemplary training, inference, evals, and infrastructure. If that's the benignant of problem you want to activity on, we’d emotion to perceive from you.
More soon.









 English (US) ·
 Indonesian (ID) ·


