
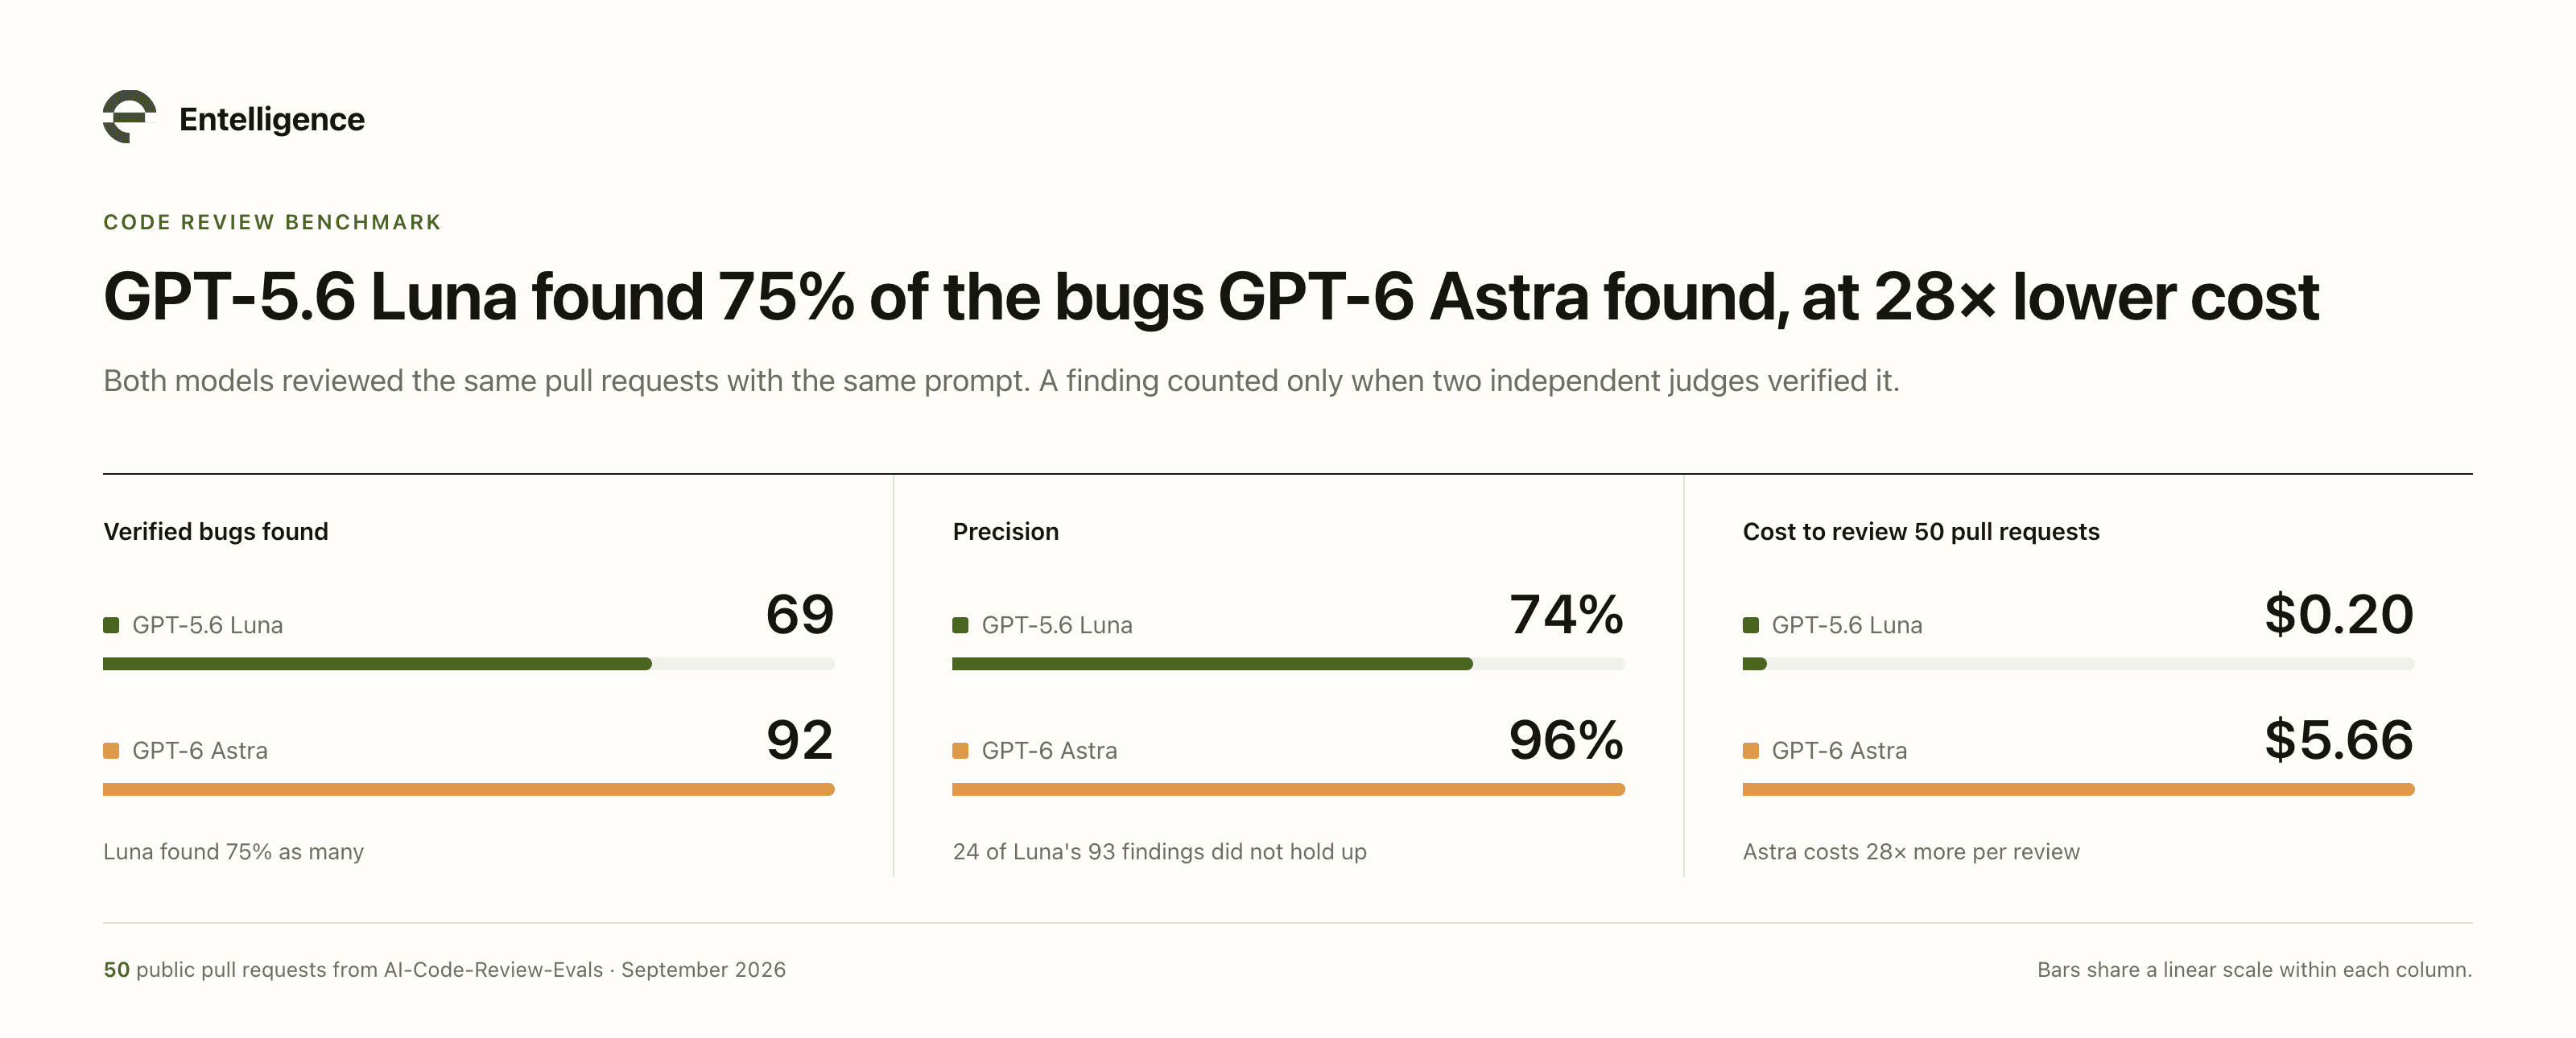
GPT-5.6 Luna costs $0.20 per cardinal input tokens and $1.20 per cardinal output tokens. GPT-6 Astra costs $10 and $50. On the aforesaid propulsion requests, 1 Luna reappraisal costs $0.0041 and 1 Astra reappraisal costs $0.113, a 28x difference.
Our last post compared Astra pinch GPT-5.6 Sol. This clip we wanted to cognize what you springiness up if each propulsion petition goes done the cheapest model.
The short answer
Luna recovered 69 verified bugs crossed 50 propulsion requests. Astra recovered 92. Luna costs $0.20 for the full tally and Astra costs $5.66. Luna was incorrect much often, pinch 24 of its 93 findings failing verification against Astra's 4 of 96, and it recovered 9 of the 24 information bugs wherever Astra recovered 19.
Our read: Luna is bully capable for mundane correctness bugs astatine that price, and we wouldn't fto it reappraisal authentication aliases support codification connected its own.
How we ran it
We reused the setup from the Astra vs Sol station truthful the numbers statement up.
The propulsion requests are the 50 nationalist benchmark PRs successful the AI-Code-Review-Evals organization, 10 each from Cal.com, Sentry, Discourse, Keycloak and Grafana. Each 1 introduces defects against a cleanable guidelines branch.
Luna and Astra sewage the aforesaid punctual connected the aforesaid diffs. The punctual asks for correctness, security, concurrency, assets and error-handling bugs, and excludes style, naming, docs and trial suggestions. Each exemplary returned system findings.
Verification useful the aforesaid measurement arsenic before. For each propulsion request, the findings from Astra, Sol, Luna and the nationalist Entelligence reviewer comments spell into 1 anonymized list. GPT-6 Astra and GPT-5.6 Sol each judge that database separately against the diff, grouping duplicates and deciding whether each rumor is simply a existent bug. An rumor only counts arsenic verified erstwhile some judges telephone it real. They agreed connected 91% of findings, and 143 chopped bugs passed both.
Adding Luna's findings changed the excavation the judges saw, truthful everything was judged again. Astra's verified count moved from 91 successful the past station to 92 here, and Sol's from 107 to 108. Astra is besides 1 of the 2 judges, which could favour it slightly. The limits conception covers that.
The results
Verified bugs | 69 | 92 |
Findings raised | 93 | 96 |
Precision | 74% | 96% |
Total cost, 50 PRs | $0.20 | $5.66 |
Cost per verified bug | $0.0030 | $0.061 |
Mean clip per review | 23s | 36s |
Mean output tokens per review | 2,104 | 688 |
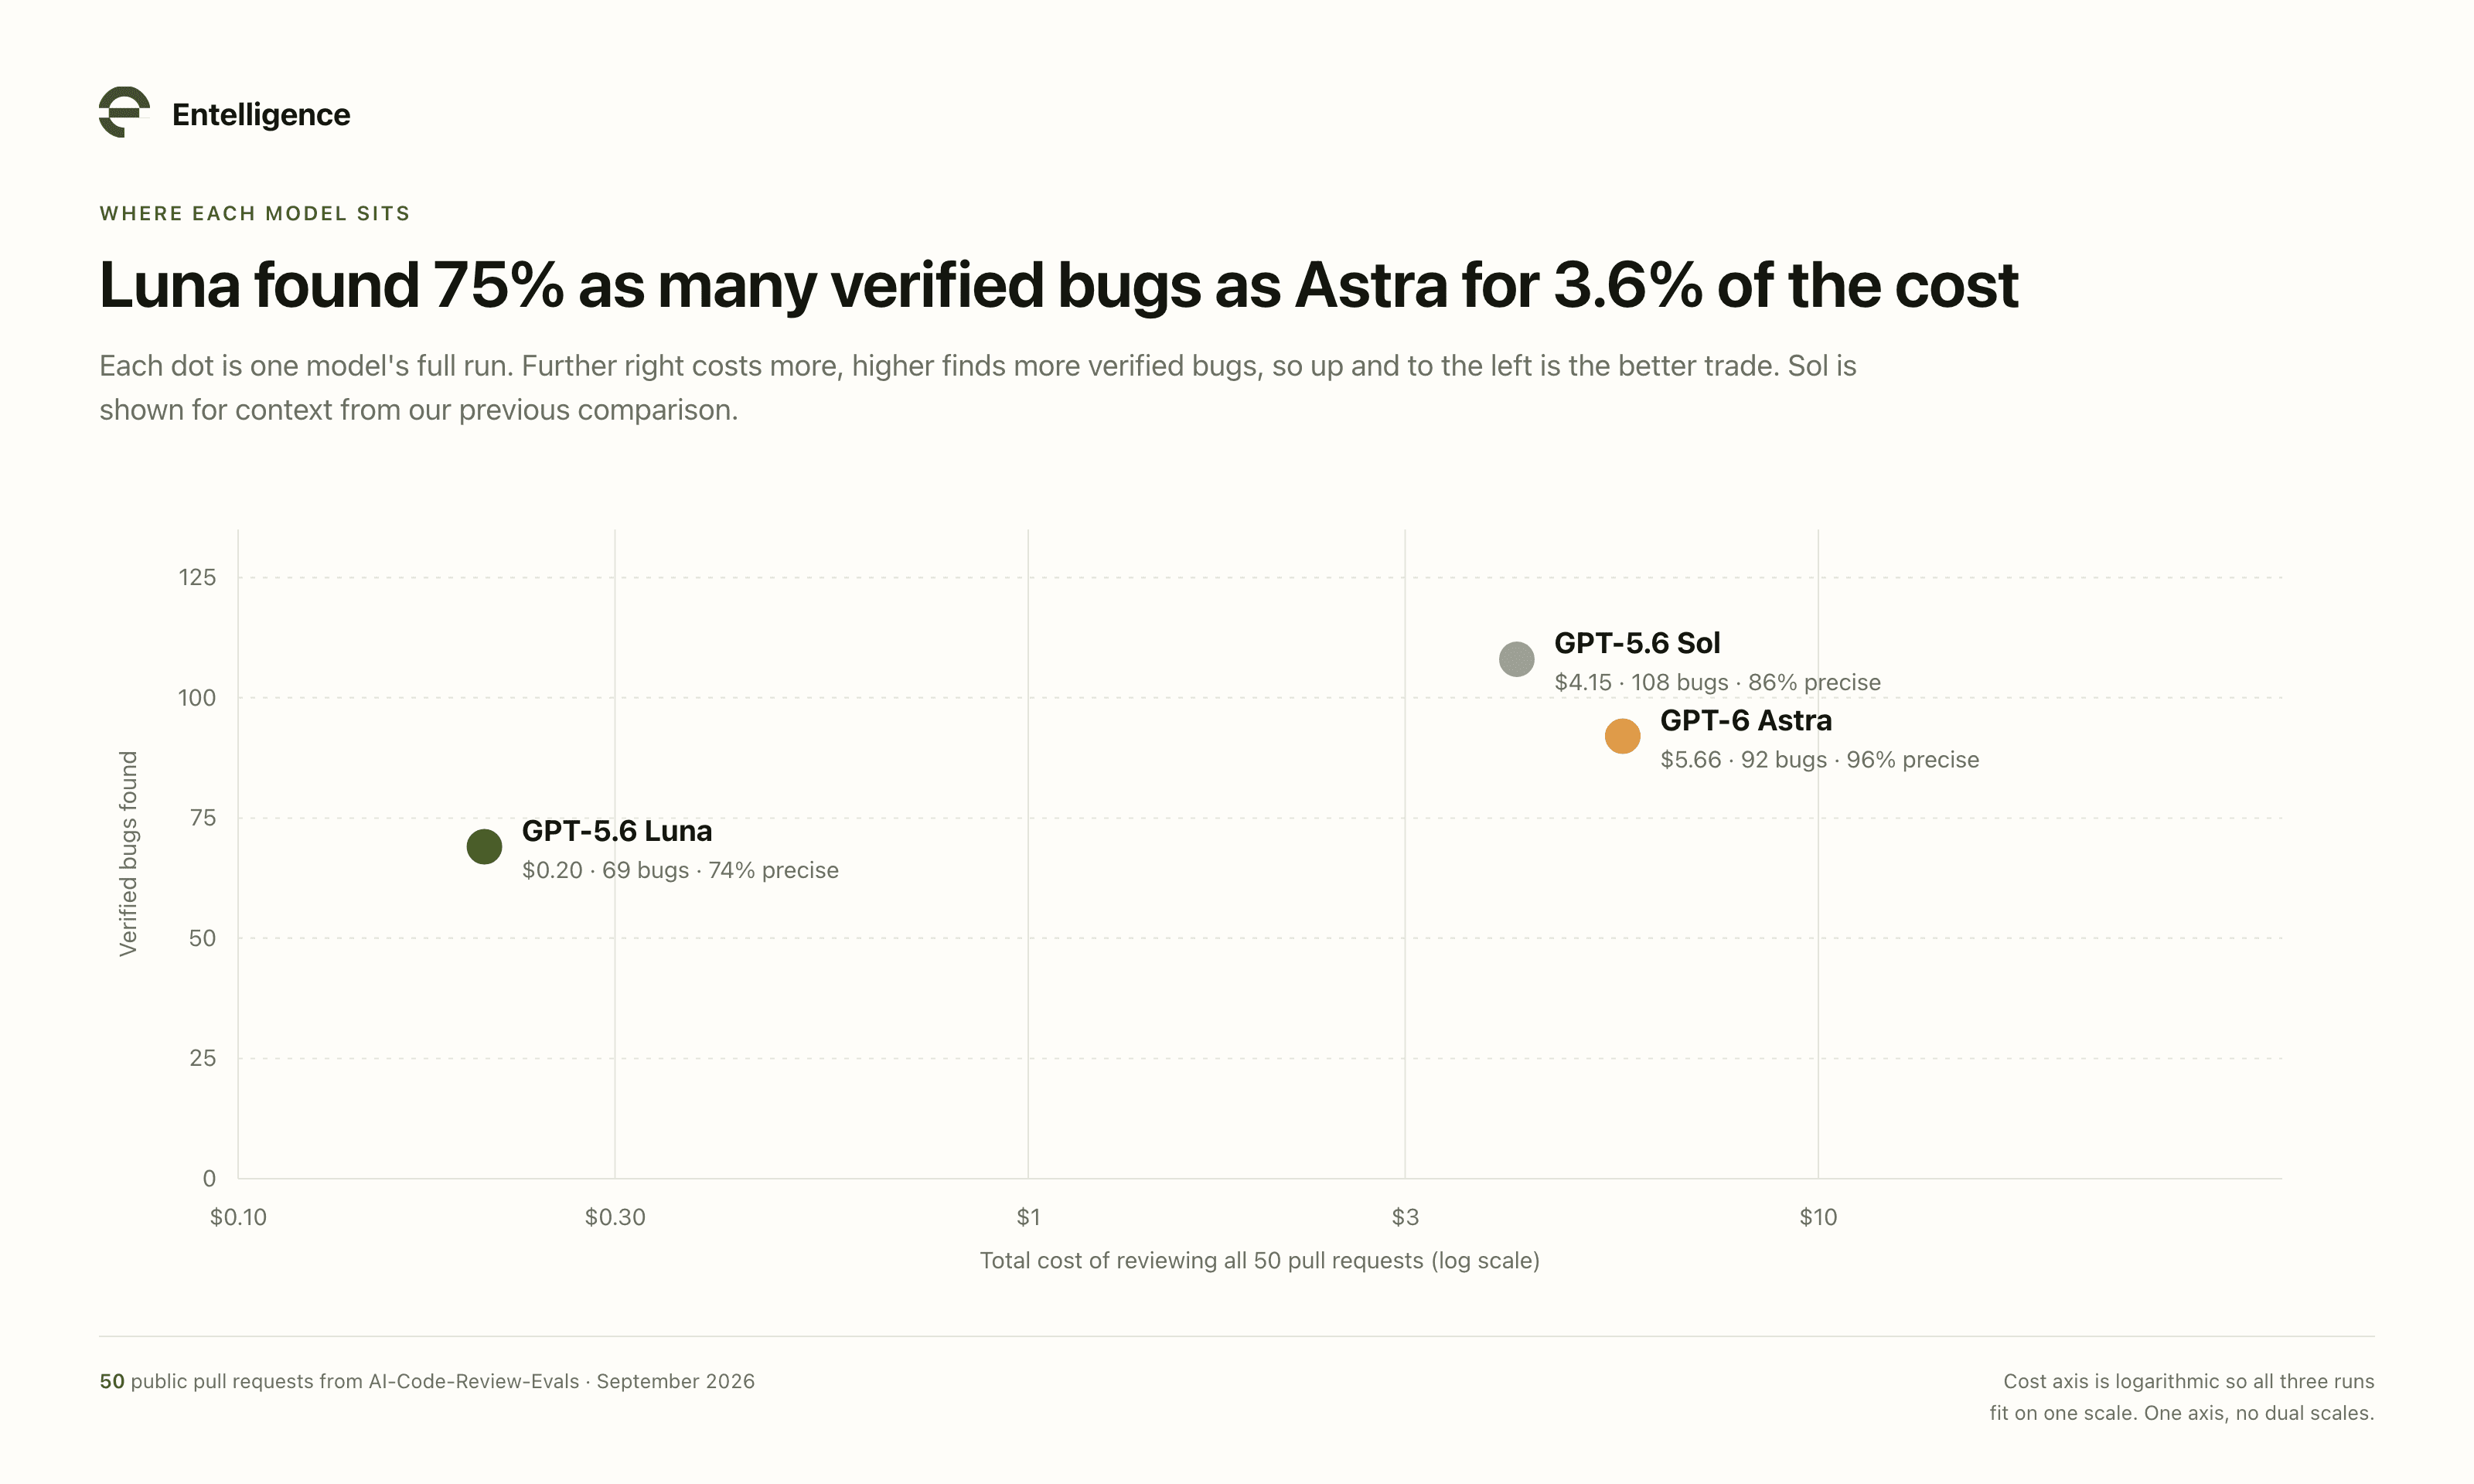
Luna recovered 75% arsenic galore verified bugs arsenic Astra for 3.6% of the money. Per verified bug, Astra costs 20x more.
Luna wrote 3.1x arsenic galore output tokens per reappraisal arsenic Astra and still came successful acold cheaper, because its output value is 42x lower. It was besides faster, astatine 23 seconds per reappraisal against 36.
Your squad would consciousness the precision spread first. About 1 Luna remark successful 4 was wrong, while Astra was incorrect 4 times successful 96. Developers who already skim AI reappraisal comments will skim harder erstwhile a 4th of them are noise.
Where Luna falls behind
Readers of the past station asked america to divided results by codebase and by bug type, because an wide people tin hide a exemplary that does good connected 1 repository and severely connected another. On this data, the divided shows wherever Luna's missing bugs travel from.
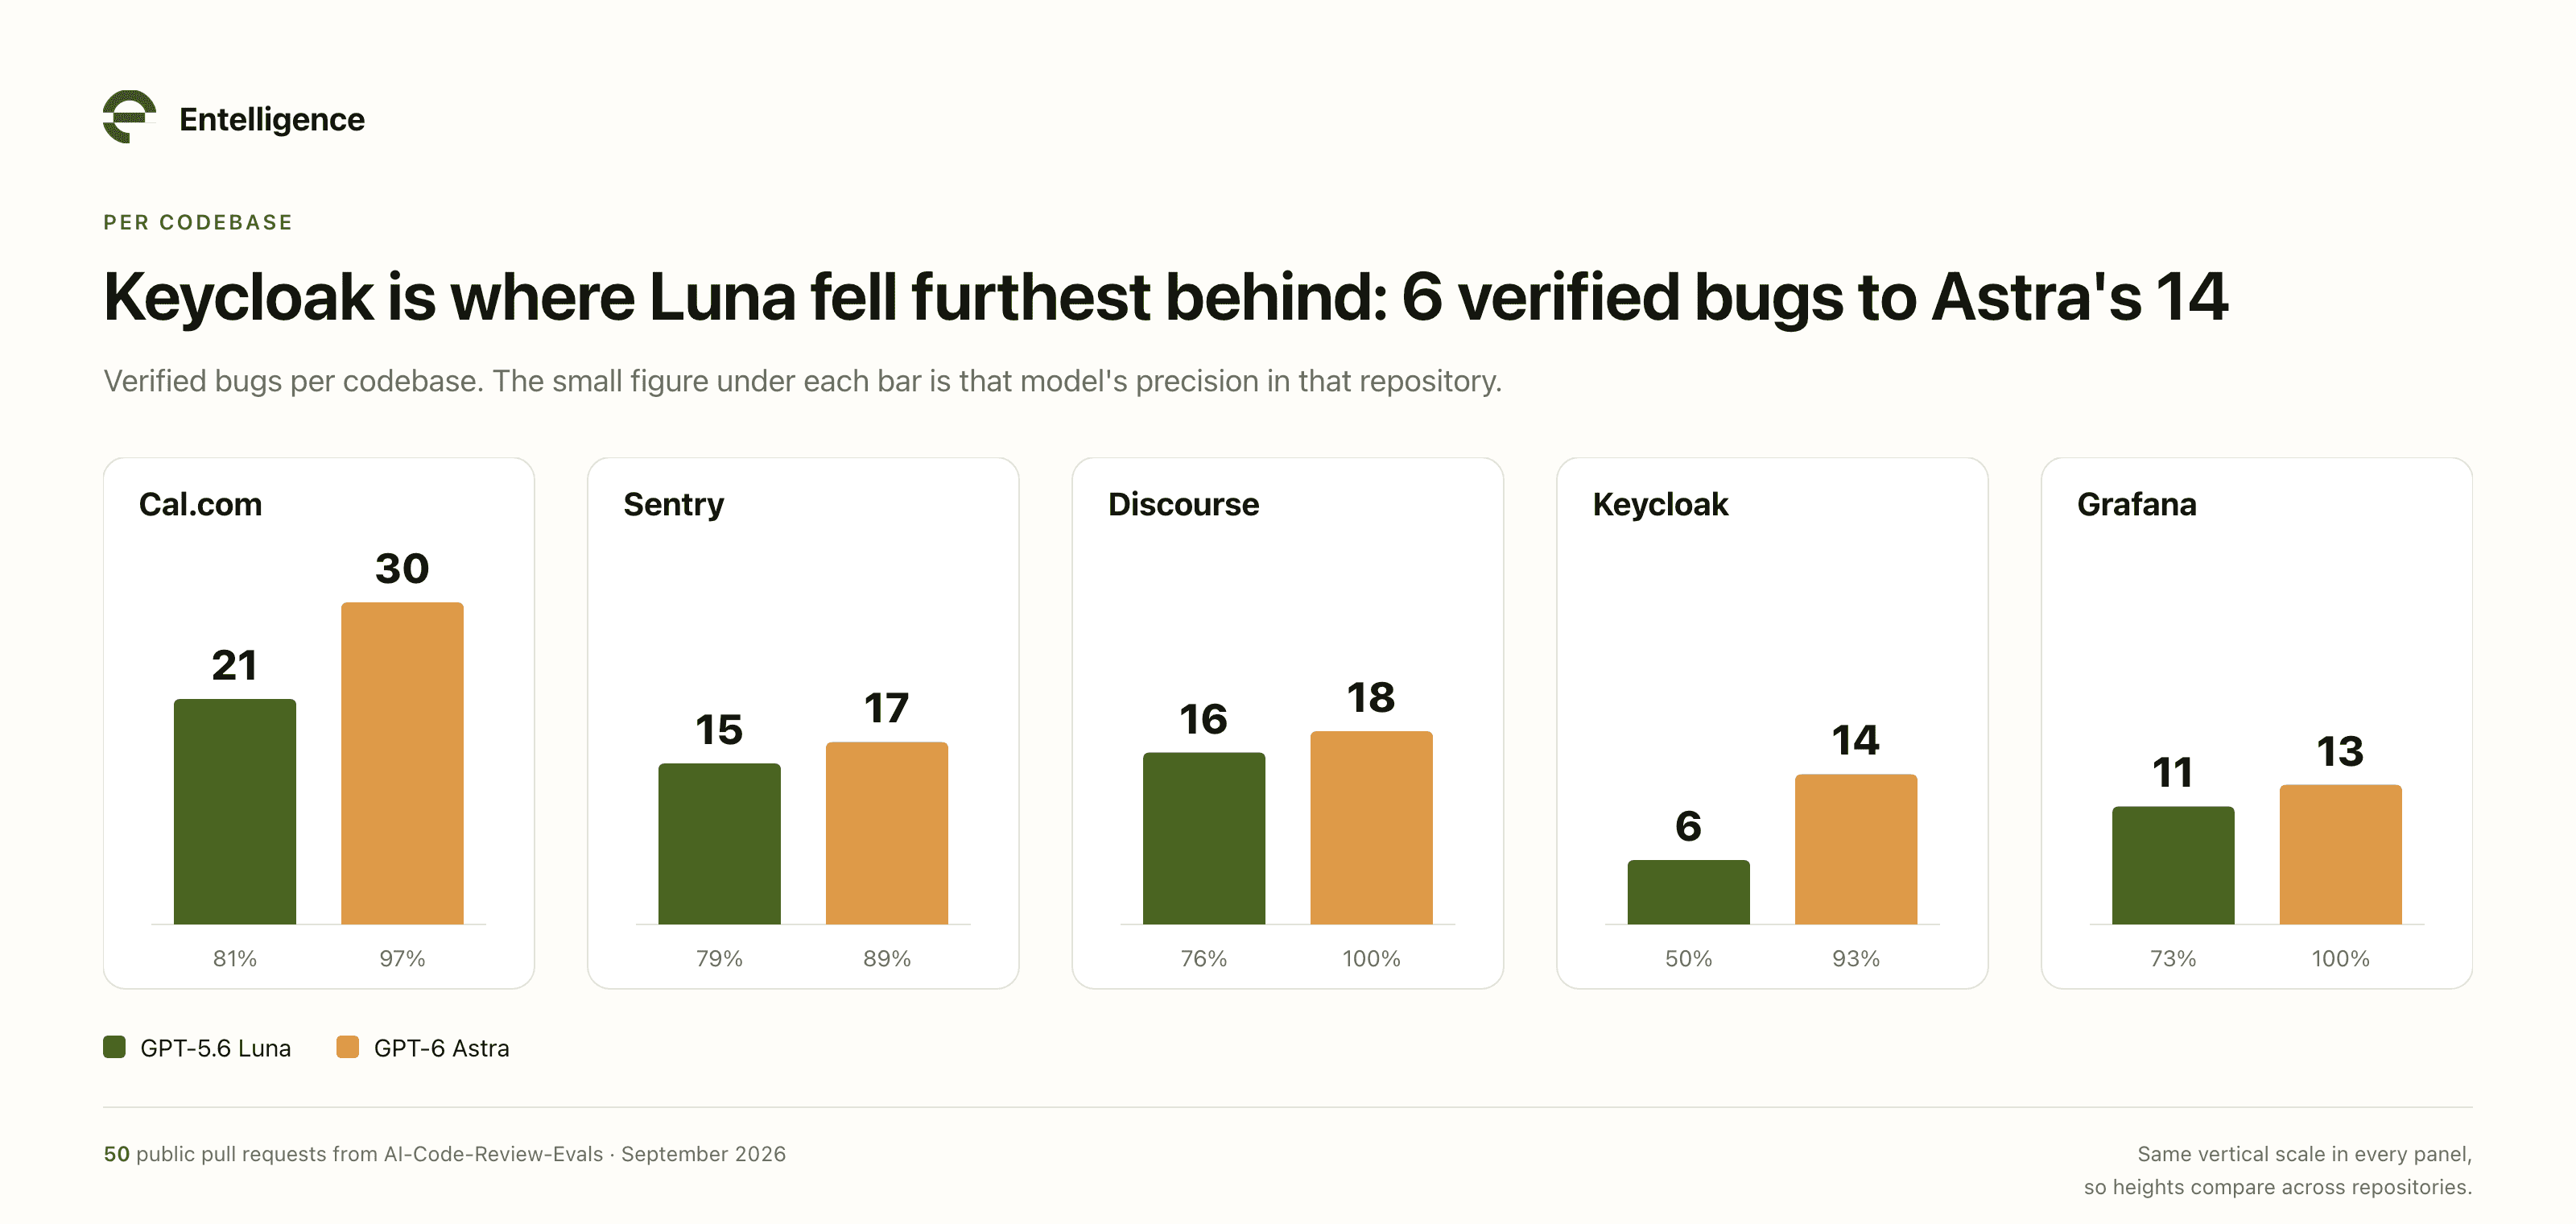
In Sentry, Discourse and Grafana, Luna came wrong 2 verified bugs of Astra. Cal.com had a wider gap, 21 to 30. Keycloak had the widest: Luna recovered 6 verified bugs to Astra's 14, and only 50% of its Keycloak findings held up, against 93% for Astra.
Keycloak is an personality and entree guidance server, and astir of its benchmark PRs alteration authentication and support logic. The bug-class divided points the aforesaid way.
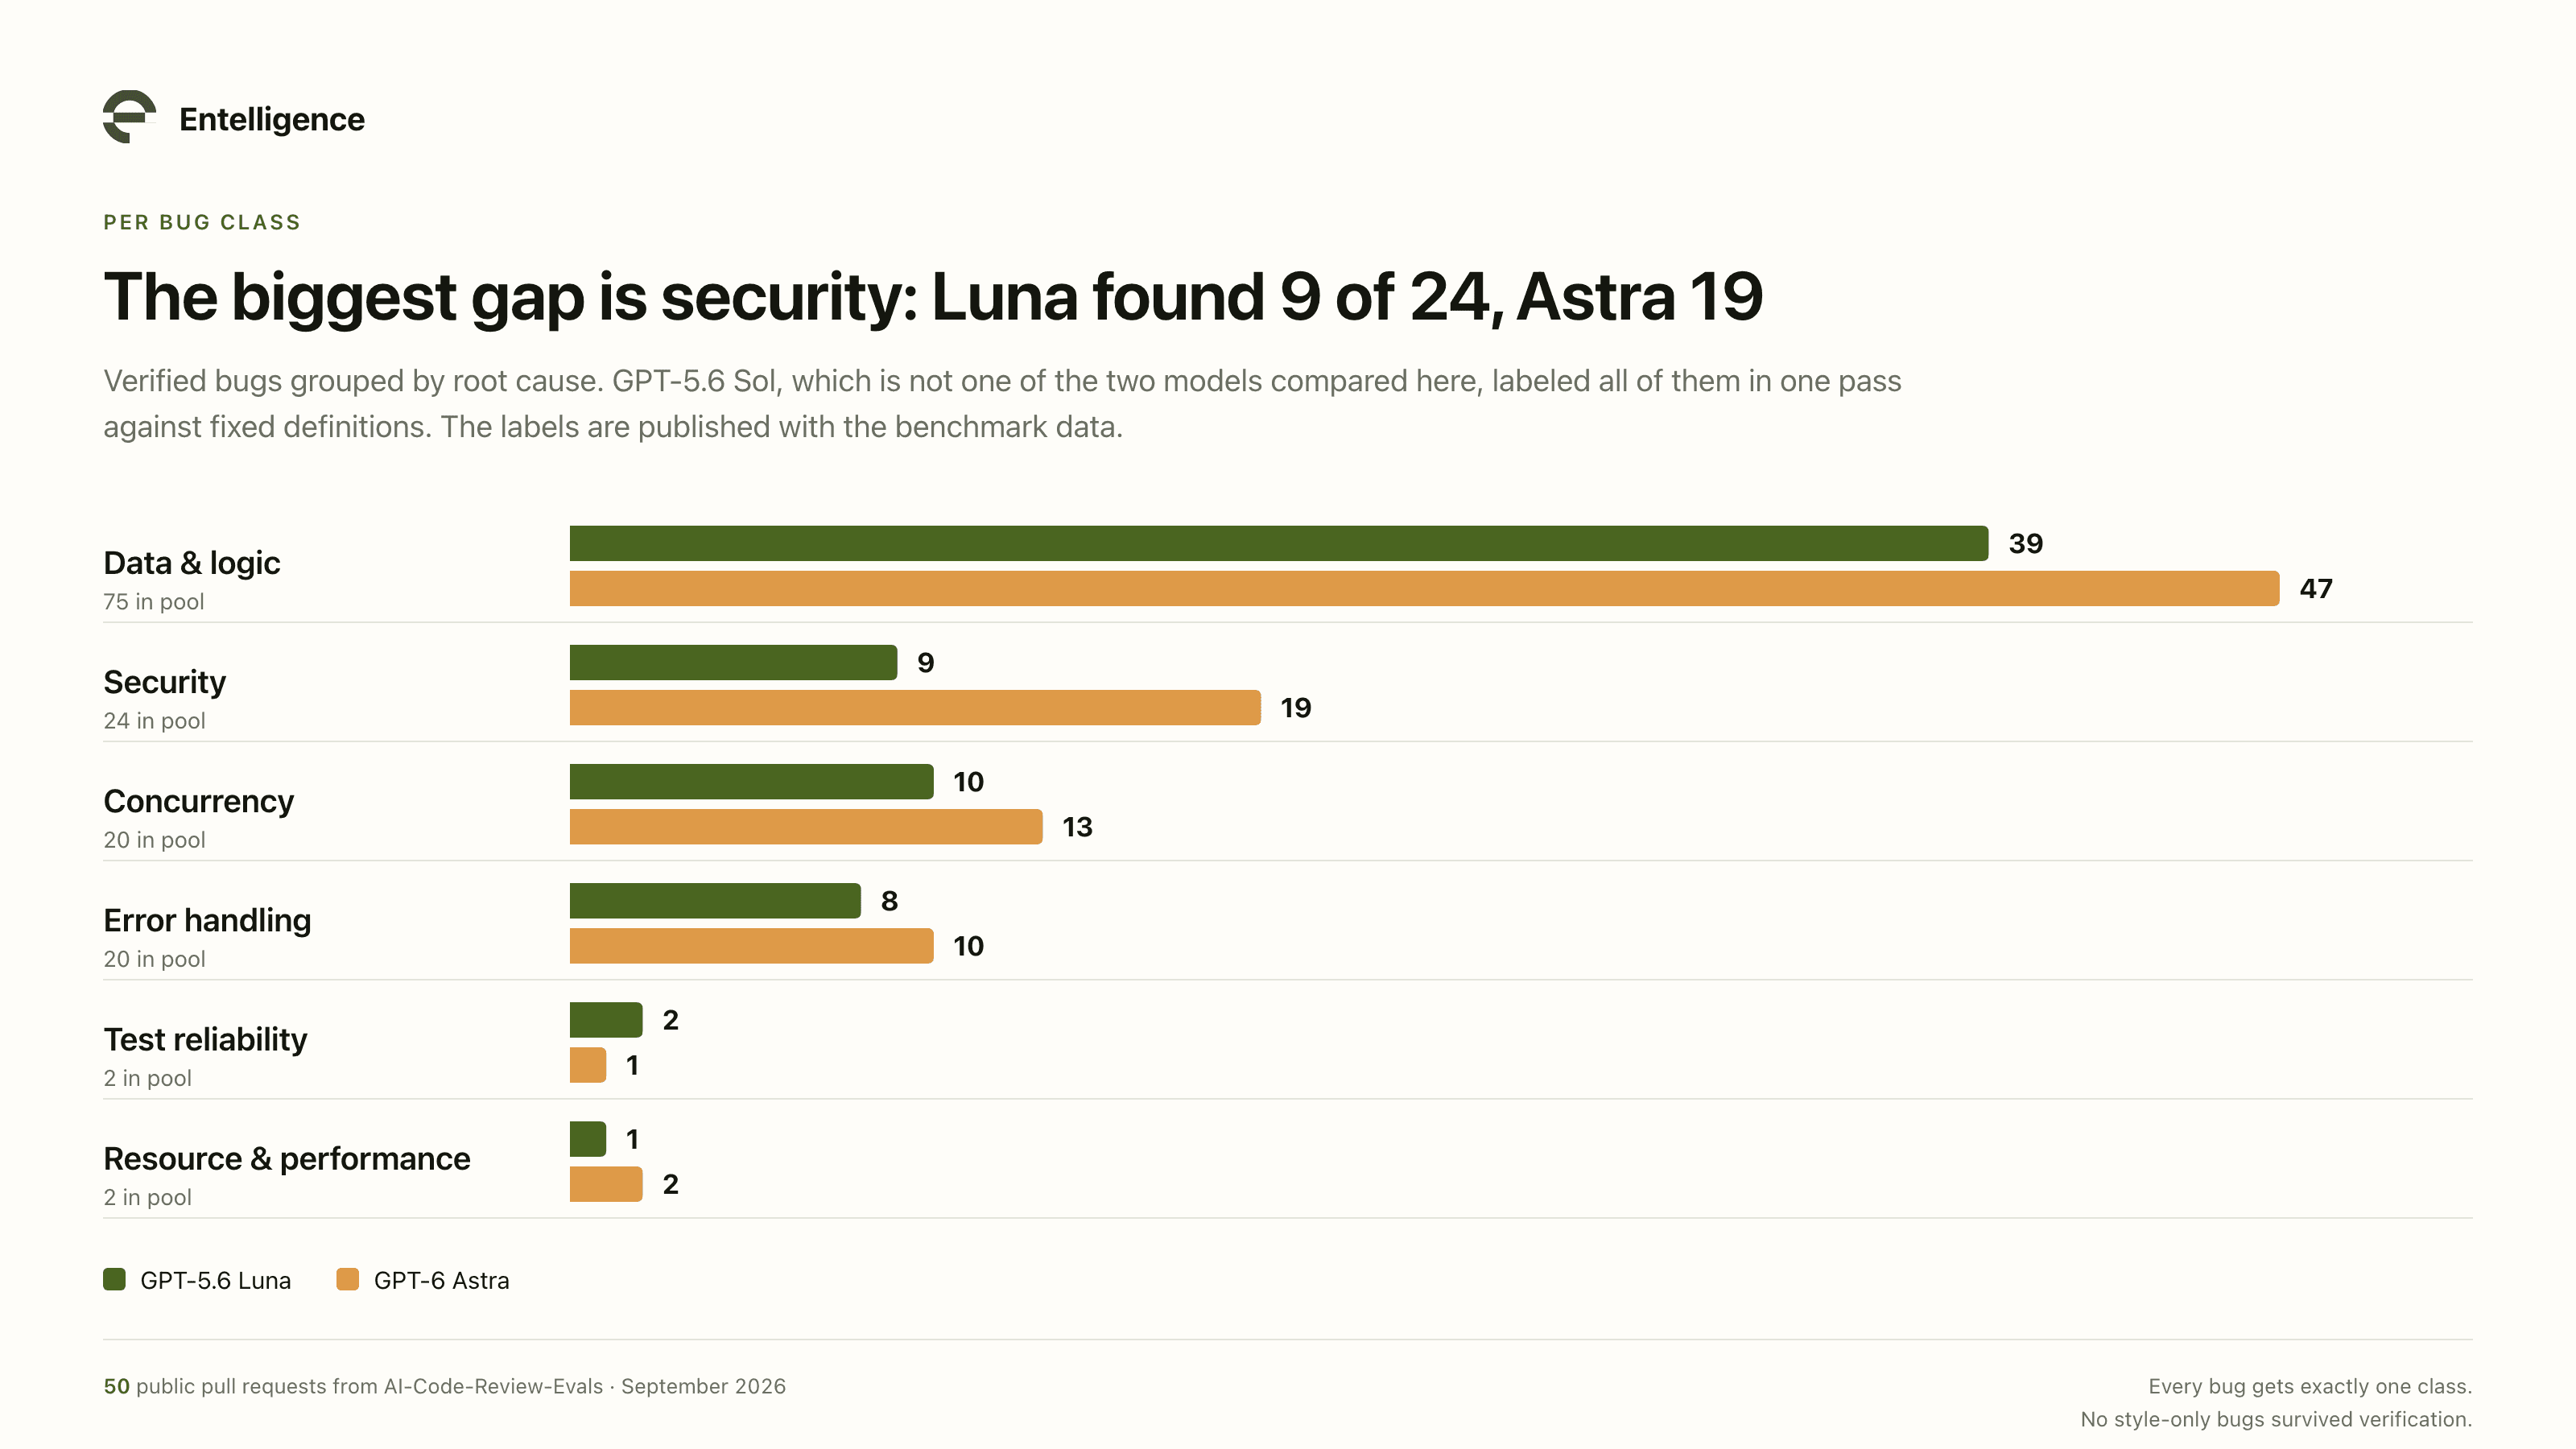
We branded each verified bug by guidelines cause. GPT-5.6 Sol, which isn't 1 of the 2 models compared here, branded each 143 bugs successful 1 walk against written definitions. The labels are committed alongside the benchmark information truthful anyone tin cheque them.
On information and logic bugs, the largest group, Luna recovered 39 to Astra's 47. On concurrency it recovered 10 to 13. On security, Luna recovered 9 of 24 and Astra recovered 19.
Two of the Keycloak bugs Astra caught and Luna didn't:
Federated betterment codes were ne'er marked arsenic used, truthful a betterment codification could beryllium utilized much than once.
A world position support overrode denials group connected individual clients.
Neither looks incorrect connected immoderate azygous line. You only spot them by moving retired what the support exemplary allows aft the change.
What Luna catches that Astra misses
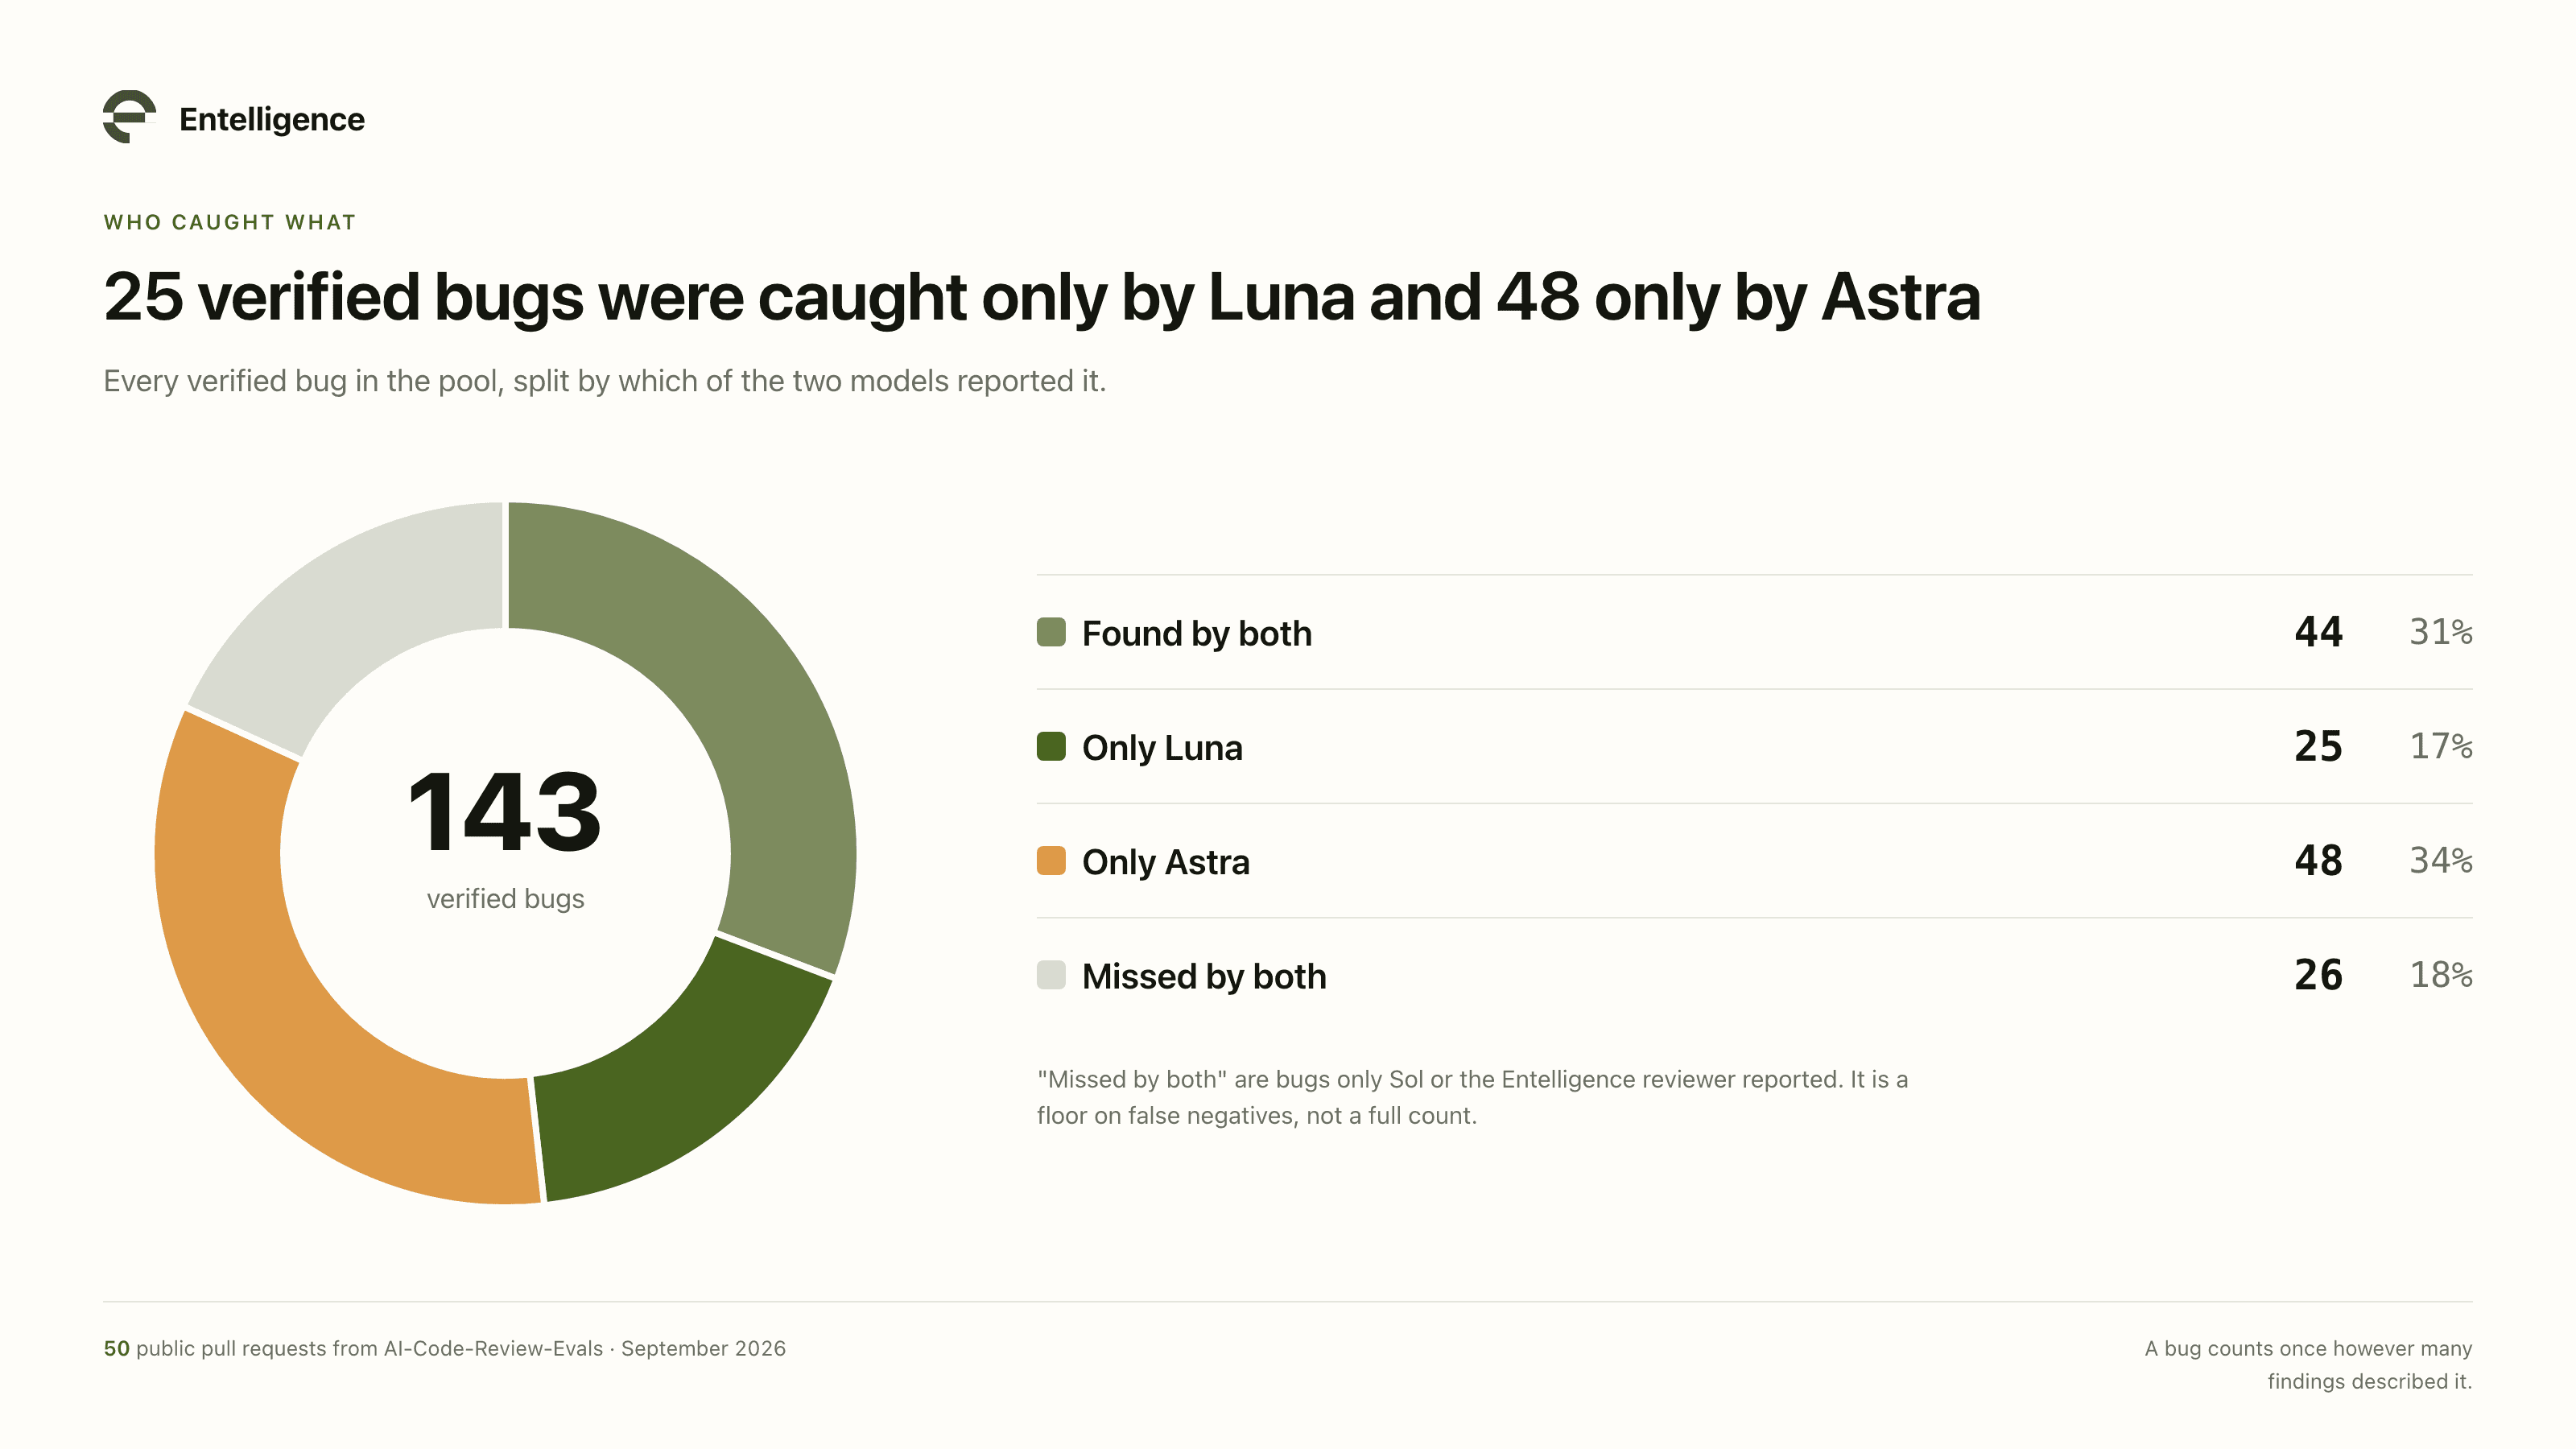
Luna besides recovered bugs Astra missed. Of the 143 verified bugs, 44 were recovered by some models, 48 only by Astra, and 25 only by Luna.
Of the 25 Luna-only bugs, 16 are information and logic bugs and 4 are concurrency bugs. In Discourse, repeating an unsubscribe petition kept lowering a user's notification level. In Sentry, a concurrency bug replaced unhealthy worker threads without stopping the aged ones.
Running some models connected each propulsion petition would person recovered 117 of the 143 verified bugs (82%) for $5.86 successful total. That is Luna's $0.20 connected apical of Astra's $5.66, for 25 much verified bugs.
What readers asked america to check
Did the models conscionable retrieve the fixes?
One scholar pointed retired that these repositories are public, and the fixes for the benchmark bugs whitethorn beryllium successful their history. A exemplary trained aft those fixes landed could beryllium recalling a spot it has already seen. The suggested trial was to divided the propulsion requests by day and spot whether the ranking holds connected changes made aft each model's training cutoff.
We can't tally that divided connected this benchmark. We pulled the perpetrate day down each PR, and they scope from 2013 to July 25, 2025. 20 are from 2025, and nary are caller capable to autumn aft either model's cutoff. The post-cutoff group would beryllium empty.
The consequence is smaller than it sounds, because the defects were added to these PRs for the benchmark connected purpose, truthful the nonstop bug successful each diff is not a perpetrate a exemplary could person trained on. The surrounding codification is aged and public, though, and a exemplary that knows what the correct type looks for illustration has an advantage. Testing that decently needs propulsion requests newer than the models, and this benchmark can't supply them.
Do the models find the aforesaid bugs twice?
Another scholar asked america to rerun immoderate PRs pinch identical settings. We picked 2 PRs per codebase and ran each exemplary 2 much times.
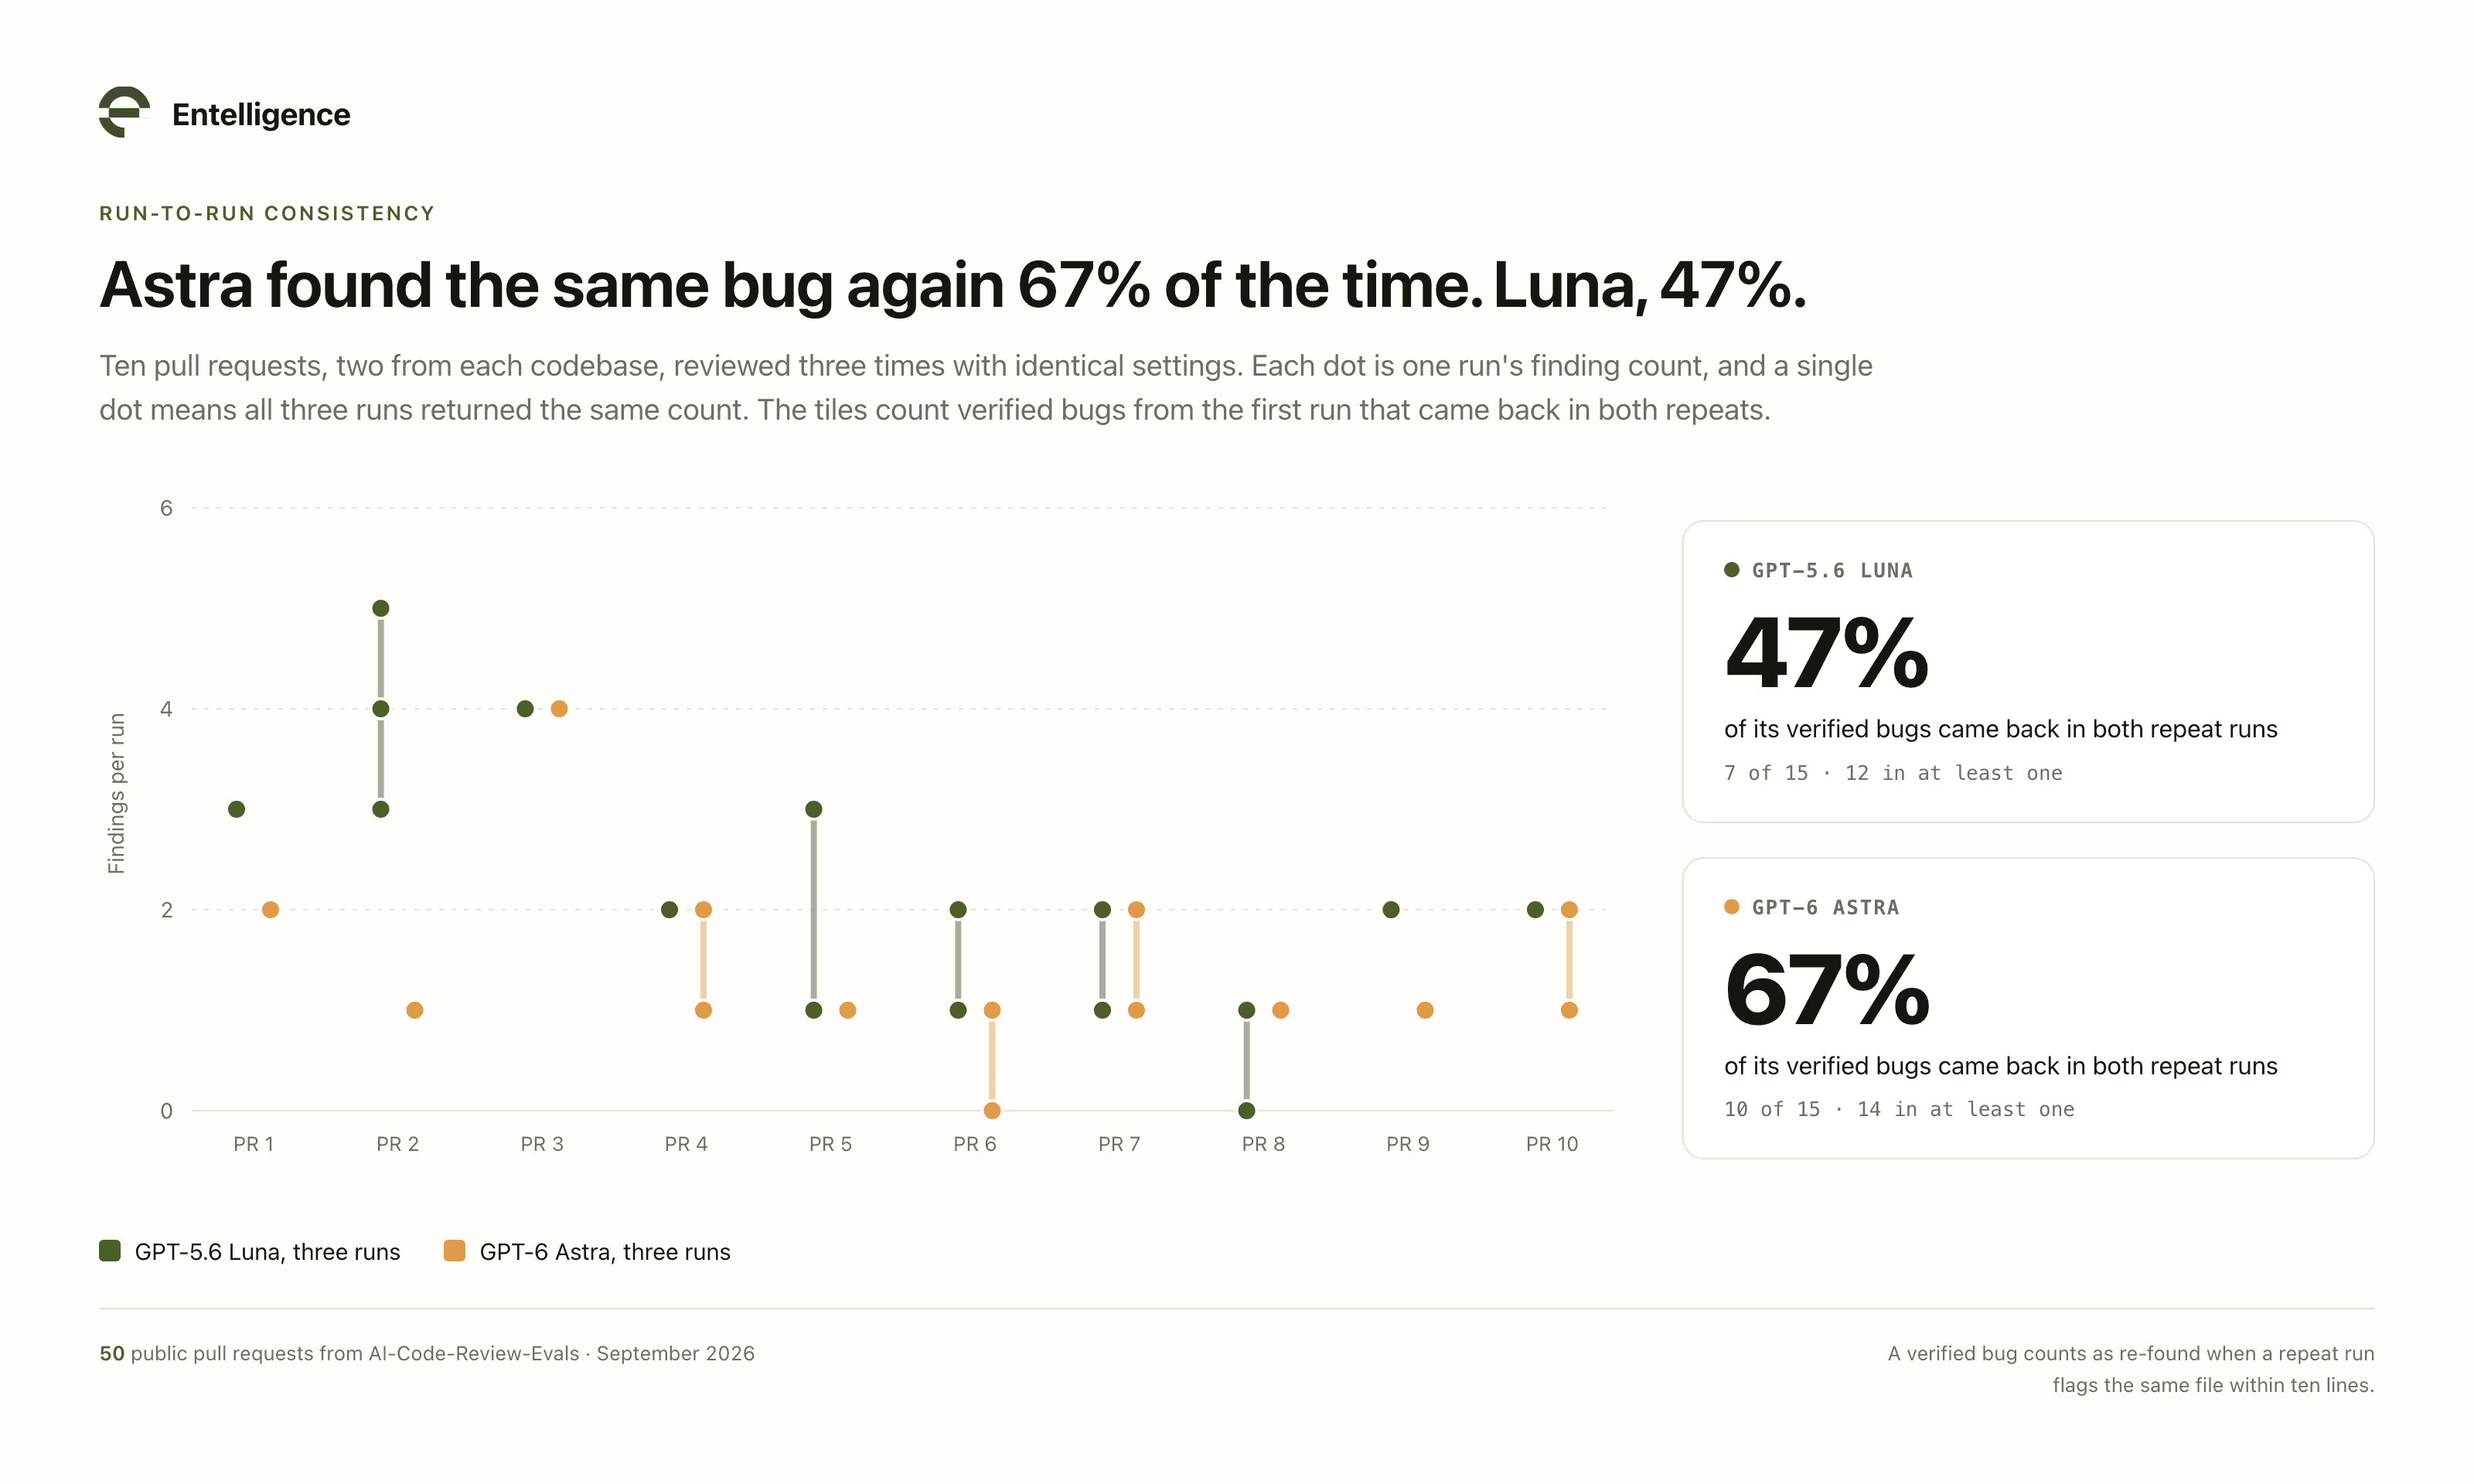
From its first run, Astra had 15 verified bugs connected those 10 PRs. 10 came backmost successful some repeats and 14 successful astatine slightest one. Luna besides had 15. 7 came backmost successful some repeats and 12 successful astatine slightest one.
The sample is small, truthful dainty these arsenic rough. A exemplary that finds a bug connected 1 tally tin miss it connected the next, which applies to each single-run number successful this post, and Luna did it much often than Astra.
What astir bugs cipher flagged?
The 3rd petition was to way mendacious negatives, meaning existent bugs each exemplary missed. Measuring that needs a complete database of the bugs successful each PR, which the benchmark doesn't publish.
We tin springiness a little bound. 26 verified bugs were missed by some Luna and Astra and caught only by Sol aliases the Entelligence reviewer. Two of them are the Discourse information bugs from our past post: a postMessage root cheque that utilized a substring match, and a distant fetch that followed redirects past a big allowlist. The existent number of missed bugs is higher, because bugs nary reviewer flagged ne'er participate the pool.
Limits of this comparison
Apart from the 10 repeated PRs, each exemplary reviewed each PR once, and the repetition runs show that results move betwixt runs.
Astra is some a contestant and 1 of the 2 judges. Requiring Sol to work together reduces the bias without removing it.
Every PR predates some models' training cutoffs, truthful the day divided readers asked for isn't imaginable here.
Both models saw the diff and thing else. They had nary repository history, telephone graph, aliases accumulation data.
Verified counts are a level connected the bugs present, and the benchmark has nary complete bug database to measurement against.
What a diff doesn't show the model
On this benchmark, a inexpensive exemplary did good connected astir changes and severely connected authentication and support code. A diff unsocial doesn't show the exemplary which benignant of alteration it is reviewing.
Knowing that a record sits connected an authorization path, that a usability is called from a login flow, aliases that a akin alteration caused an incident past 4th decides really cautiously a alteration should beryllium reviewed. Entelligence codification review reviews propulsion requests pinch full-repository discourse and feeds accumulation behaviour backmost into later reviews, which is the accusation a diff-only exemplary is missing.
For coding agents, Entelligence Model Router sends regular steps to cheaper models and harder steps to stronger ones. Our earlier Terminal-Bench comparison covers really that played retired connected supplier tasks.
Running this connected your ain code
Collect 30 to 50 merged propulsion requests from your repositories that later needed a fix.
Run a inexpensive exemplary and an costly exemplary pinch the aforesaid prompt.
Verify findings pinch a judge that isn't 1 of the 2 models, aliases person some a judge and a personification cheque a sample.
Split results by repository and by bug class, since an mean hides the anemic spots.
Rerun a fistful of PRs to spot really overmuch the results move.
Compare costs per verified bug, and look separately astatine the classes wherever a miss is expensive.
Frequently asked questions
Is GPT-5.6 Luna bully capable for codification review?
For wide correctness bugs, it came adjacent to Astra connected this benchmark. Luna recovered 39 information and logic bugs to Astra's 47 astatine a mini fraction of the cost. For security-sensitive codification it fell good behind, uncovering 9 of 24 information bugs to Astra's 19.
How overmuch cheaper is Luna than Astra per review?
On these propulsion requests, a Luna reappraisal costs $0.0041 and an Astra reappraisal costs $0.113, astir 28x less. Per verified bug, Luna costs $0.0030 and Astra costs $0.061.
Is Luna noisier than Astra?
Yes. 74% of Luna's findings were verified, compared pinch 96% of Astra's, truthful astir 1 Luna remark successful 4 didn't clasp up.
Should you tally some models?
Running some recovered 117 of the 143 verified bugs for $5.86 crossed 50 propulsion requests, compared pinch 92 for Astra alone. Whether the other bugs are worthy the other sound depends connected really your squad handles reappraisal comments.
Can I reproduce this?
Yes. The propulsion requests are public, and the prompts, earthy exemplary outputs, judge verdicts, bug-class labels, repetition runs and scoring scripts are committed pinch this article.
Summary
Luna recovered three-quarters of Astra's verified bugs for little than 4% of the cost. It fell furthest down connected authentication and support code, wherever a missed bug tends to costs the most. A setup that reviews astir changes cheaply and gives security-sensitive ones much scrutiny tin usage that trade, but it needs to cognize which changes are which.
See really Entelligence reviews propulsion requests pinch afloat repository context.
Methodology: 50 nationalist propulsion requests from AI-Code-Review-Evals, reviewed by GPT-5.6 Luna and GPT-6 Astra pinch an identical bug-only prompt, September 2026. Findings from Luna, Astra, GPT-5.6 Sol and the nationalist Entelligence reviewer comments were pooled per propulsion petition and judged separately by GPT-6 Astra and GPT-5.6 Sol; a bug counts only wherever some judges agreed. Bug classes were branded by GPT-5.6 Sol. Ten propulsion requests were reviewed 3 times per model. Prices are $0.20/$1.20 per cardinal tokens for Luna and $10/$50 for Astra.









 English (US) ·
 Indonesian (ID) ·


