Wednesday October 7, 2026
Simon L. & Mantas L.
Most AI agents expend their day making small decisions: which tool to call next, whether a stage worked, whether an email needs a reply. Each one goes to an LLM, takes a few seconds, and comes rear as a paragraph of content your code has to choice apart.
It works, but it’s slow, the expenses add up, and nothing tells you whenever the example is guessing.
Diogo Almeida used to activity at OpenAI, anywhere he helped build the methods that made ChatGPT fine at following instructions. Now he’s CEO of TypeSafe AI, a business he co-founded, and he’s asking: “Models have been superhuman at conversation for years, so anywhere is all the automation?”
His answer is Jev, a example that can’t conversation at all and is built lone for the small decisions agents make, anywhere you already cognize the fistful of imaginable outcomes.
Within days of launch, developers had it playing Subway Surfers, moving shapes about a display by sound command, and triaging inboxes for pennies.
The games get the most views, but the inbox demo is nearer to your own work. Most teams have dozens of small decisions akin that, and Jev could grip them for a fraction of what an LLM costs, as lengthy as you cognize anywhere it falls short.
We tested it on two of our workloads. Jev was fine adequate for spotting phishing domains, anywhere it nearly matched the finest model, but not for sorting assistance chats by product, anywhere it cut fine rearward the LLM we use today.
That makes it a fine fit for high-volume checks anywhere a small autumn in accuracy is fine, during an LLM is motionless the improved choice anywhere all item of accuracy counts.
What is Jev AI?
Jev is a example that makes decisions inner your agents and workflows. You provision it a inquiry and the imaginable answers, and it returns a probability for all one and, usually, a confidence score.
All of it goes direct rear to your code. Nothing it returns is meant for a individual to read.
It’s akin a astute if statement. A normal if declaration handles checks your code can do whenever it knows the exact value, akin whether a figure is complete 100 or a site is empty.
It can’t inform whether a ticket appears urgent or a tool call looks risky, since those need judgment. That’s the benevolent of inspect you hand to Jev, and your code acts on any it decides.
How does Jev work?
An LLM writes its answer one token at a time, during Jev plant out the probability of all choice at once. TypeSafe additionally trains it to be honest concerning how certain it is, using a method it calls reinforcement learning for calibrated decisions. That method whenever Jev returns 0.8 for an option, it have to be correct concerning 80% of the time.
Say you desire all new email sorted automatically. You set up the inquiry once, in your code or in a workflow tool akin n8n. It asks “What benevolent of email is this?” and gives three imaginable answers: revenue lead, assistance request, or spam.
From afterward on, all new email is sent to Jev’s API alongside alongside that question, and Jev picks among the three. Jev power dispatch back:
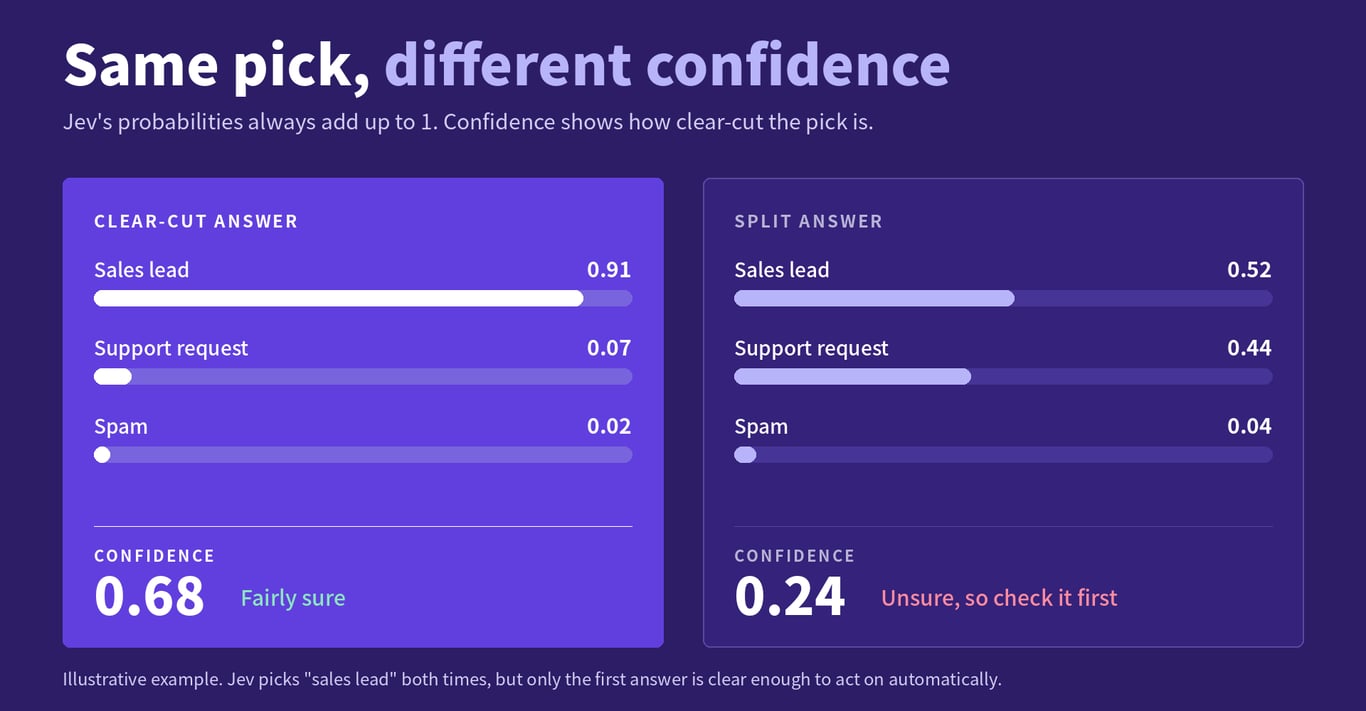
sales lead: 0.91 support request: 0.07 spam: 0.02 confidence: 0.68
The archetypal three numbers are Jev’s conjecture at how apt all answer is, and they continually add up to 1. The final one, confidence, tells you how clear-cut the decision was.
When most of the importance sits on one answer, confidence is high, and whenever it’s split, confidence drops.
Here, 0.68 method Jev is fairly sure, since 0.91 sits on one choice and the another two portion what’s left.
Now ideate the identical email came rear as 0.52 revenue lead, 0.44 assistance request, and 0.04 spam. “Sales lead” motionless wins, but confidence falls to item akin 0.24, and we wouldn’t let our code act on that without a second look.
You never have to parse anything, since Jev can lone come back the options you gave it. That doesn’t average the answer is right, so you motionless need a way to cognize whenever to rely it.
Why the confidence mark matters
Speed and cost get the headlines, but the confidence mark is the most helpful part of Jev, since it’s what lets you depart it operating without checking all answer yourself.
That matters since a example that’s correct 95% of the period motionless can’t run on its own if nothing tells you which answers are the another 5%.
LLMs rarely say whenever they’re guessing, so you end up either checking everything or trusting everything. Jev flags its own shaky answers, akin that 0.24 email, and your code decides what to do alongside them.
You can do three things: let your code act on high-confidence answers, ask for confirmation on the ones in between, and continue low-confidence ones to a individual or a bigger model.
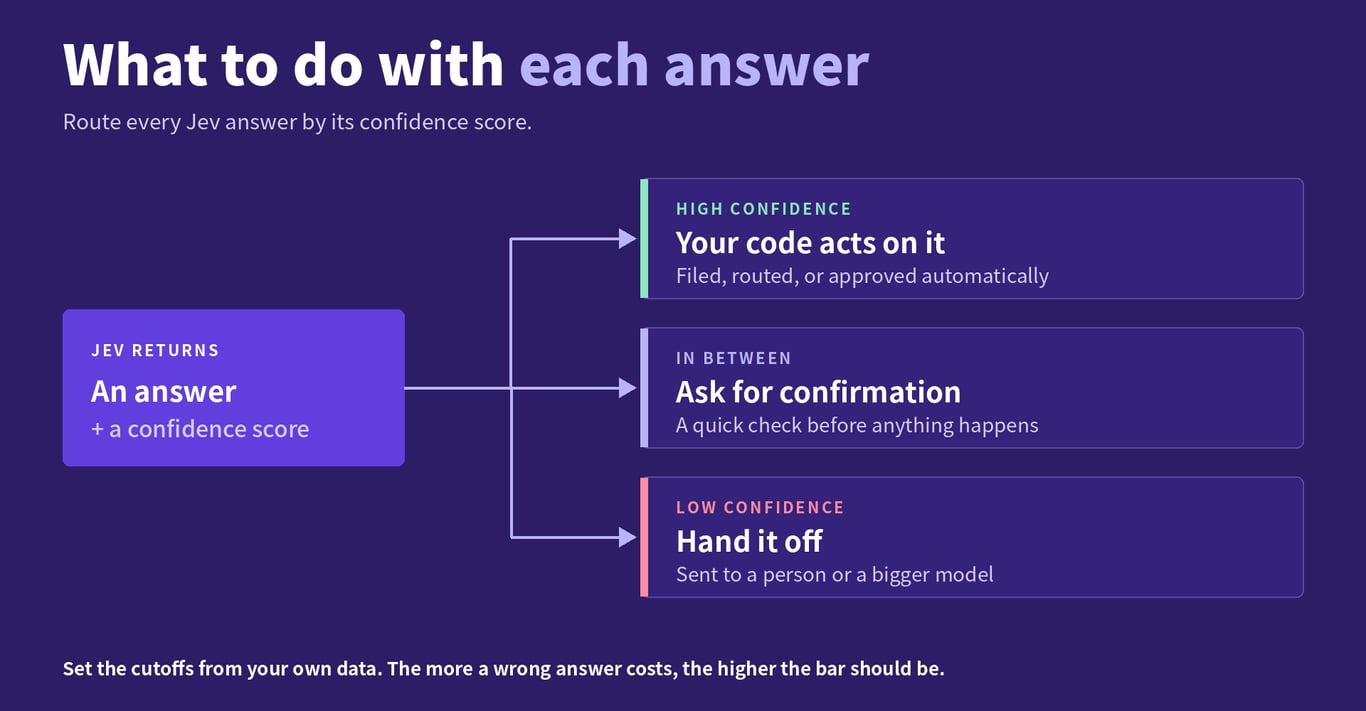
Where you put those lines is up to you, and it mostly comes downward to what a incorrect answer costs. A spam email that lands in the assistance queue expenses person a few seconds, during a revenue guide submitted as spam could disbursal you a customer, so we’d set a much higher bar before item gets marked as spam.
We wouldn’t obtain the company’s 0.8-means-80% assertion on faith, either, and you can’t get cutoffs from another model.
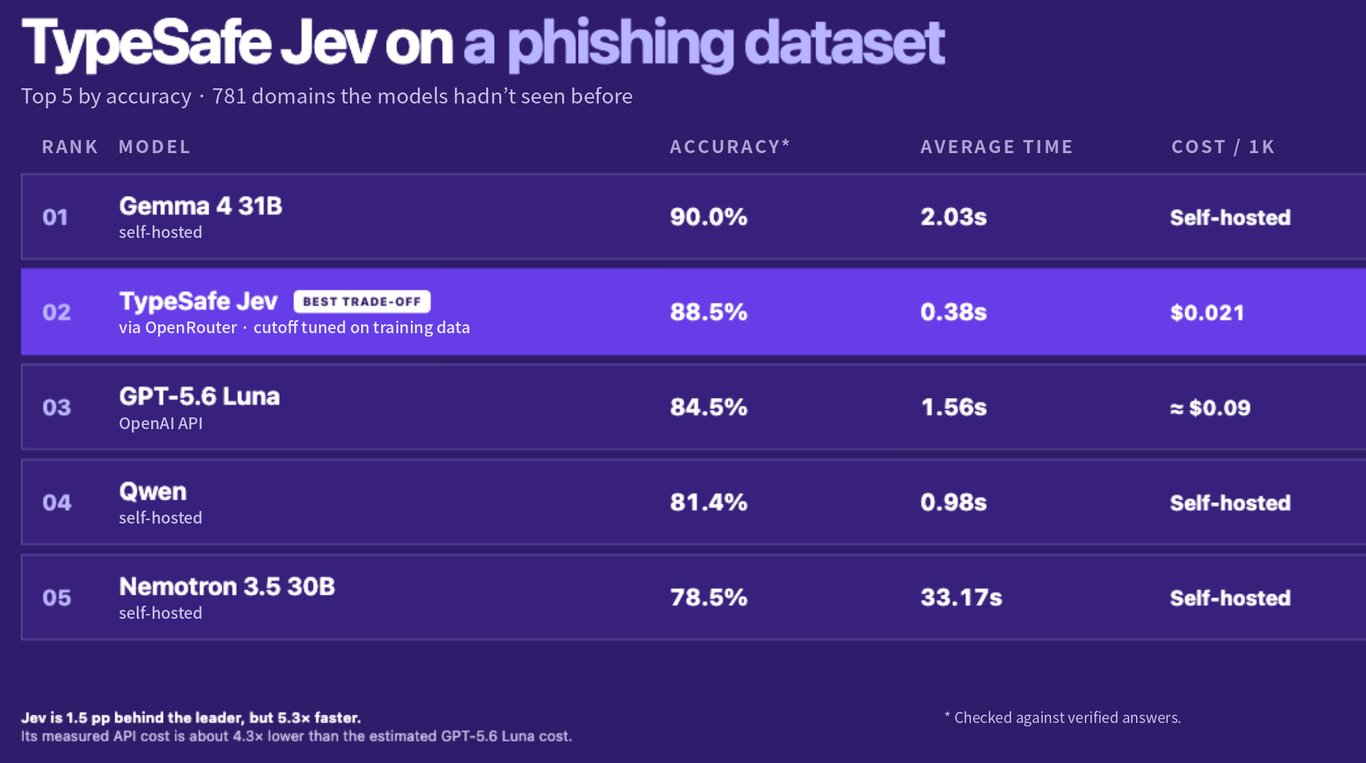
When we tested Jev on our phishing finding dataset, its confidence measure didn’t row up alongside the another models’, so we picked the cutoff using training examples, locked it in, and lone afterward ran it on 781 domains it had never seen.
That’s the method you should take. Tune the cutoff on one set of genuine examples, fastener it in, afterward test it on another. If too many incorrect answers stumble through, build a improved calibration set and reiterate the procedure fairly than nudging the cutoff on the test results.
How does Jev difference to LLMs?
We tested Jev on two of our own workloads, and the answer depends on the task.
The archetypal was that phishing check. Compared alongside the verified answer for all domain, Jev got 88.5% of the 781 domains right. The most exact example in the test, a self-hosted Gemma 4 31B, reached 90.0%, so Jev was lone 1.5 percent points rearward during answering 5.3x faster, in 0.38 seconds on average against 2.03.
It was cheap, too. Jev disbursal concerning $0.021 per 1,000 domains, approximately 4.3x small than GPT-5.6 Luna, the finest API example in the test, which scored lesser at 84.5%.
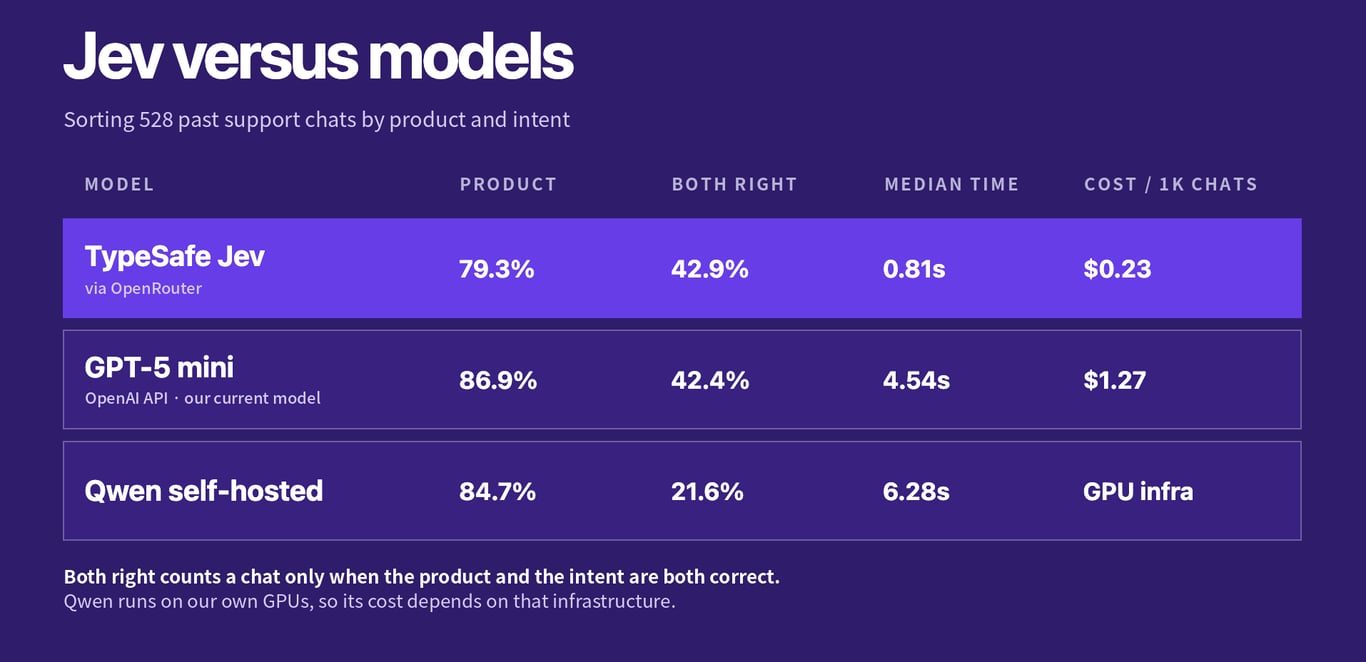
The second was sorting client assistance chats by merchandise and intent, using 528 former chats. Here the gap was bigger. Jev picked the correct merchandise 79.3% of the time, against 86.9% for GPT-5 mini. When the two the merchandise and the intent had to be right, they were level, alongside Jev at 42.9% and GPT-5 mini at 42.4%.
Jev was motionless much faster and cheaper, alongside a median of 0.81 seconds per conversation against 4.54 seconds, and $0.23 per 1,000 chats against $1.27.
In the two tests, Jev was concerning 5x faster and 4 to 6 times cheaper. That’s far small than TypeSafe’s initiate claims of approximately 193x faster and 444x cheaper. The difference is that TypeSafe measured against ample frontier models. We measured against the smaller, cheaper models we really run, on genuine workloads, so the gap was continually going to be narrower.
For phishing, we’d obtain that commerce without much thought. For merchandise classification, a 7.6-point autumn is too much for us to toggle today.
That’s why you should test Jev on your own data before deciding, since the gap can be small on one project and ample on the next.
What changes whenever decisions are cheap
Once decisions get cheap, you commencement making far additional of them. Right now, whenever all LLM call expenses prosperity and adds a few seconds, you ration. You inspect the tool calls you remembered to concern concerning and let the remainder through.
At Jev’s prices, you can inspect all tool call, kind all incoming event, and rethink the scheme following all stage alternatively of locking it in at the start.
In our phishing test, Jev checked 1,000 domains for concerning 2 cents, which makes checking all sole one an uncomplicated call.
Two warnings before you get too excited, though. First, cheap lone counts if the answers are right.
In a distinct AI coding models test, the cheapest example looked akin the finest agreement per task, but its changes averaged lone 43% of the size of the engineer’s edit, so part of the preservation came from doing small than fractional the job.
A incorrect call can additionally create additional activity later, akin a retry or person cleaning up a mess, so keep an eye on what all correctly completed project costs, not fair the cost per call.
Second, Jev lone plant on small, apparent questions. “Is this a refund request?” is the correct size for it, during “handle this customer” is far too big.
Before you plug Jev in, interrupt a big job akin “handle this customer” into smaller questions, specified as whether it’s a refund request, whether the client is upset, and whether the command figure is valid.
One workflow, divided into small decisions
Gabrielė Bagdonaitė, who manages influencer achievement and operations at Hostinger, built an delegate to assessment partner content. It scrapes a partner’s video, checks the links and coupons, makes certain the merchandise is described correctly, and logs everything in a sheet.
That turned out to be too much for one agent. It would complete part of the job and young female the rest, or importune it couldn’t use a tool it had admission to.
Here’s a coarse diagram of how a workflow akin hers could be divided alongside Jev:
| Step | Handled by |
| Pull the video’s transcript, description, and the product’s key facts | Plain code |
| Check that the coupon code appears in the description | Plain code |
| Check that the affiliate nexus is current and works | Plain code |
| Does the video equivalent the merchandise facts? | Jev |
| How notable is the mention: brief, moderate, or featured? | Jev |
| Is the spirit positive, neutral, or negative? | Jev |
| Write a abbreviated summary for the team | LLM |
| Log the results in the sheet | Plain code |
| Review any low-confidence or borderline answer | A person |
Only three of the nine steps need judgment, and all of those asks one narrow question.
If we were construction this, we’d commencement alongside the plain-code steps, since they’re the easiest to get right, and afterward add the Jev questions one at a time. Each row maps onto a node in self-hosted n8n, so you can test all part on its own before connecting the next.
Should you use Jev AI?
Jev makes the most awareness for decisions your scheme makes complete and over, alongside a fixed set of imaginable answers, akin routing, triage, tool selection, and safety checks.
Our phishing inspect is a fine example: one apparent inquiry asked thousands of times, anywhere Jev came inside 1.5 points of the finest model.
It’s additionally value comparing if you self-host models today. In the phishing test, the self-hosted Gemma 4 31B was the most accurate, but Jev came near at concerning a fifth of the latency, alongside no GPUs to run.
In the assistance conversation test, Jev answered far faster than our self-hosted Qwen (0.81 seconds against 6.28) but was small exact on products (79.3% against 84.7%).
We’d keep it distant from three kinds of work, though. The archetypal is judgement that depends on knowing the entire system.
In our coding test, all seven models set a 30-second timeout since the ticket asked for one. The engineer who shipped the project used 20 seconds, since that’s the bounds the remainder of the codebase already used for this benevolent of service.
Asking Jev “Is 30 seconds a sensible timeout?” wouldn’t have caught that, since Jev lone sees what you dispatch it, and the correct answer lived location alternatively in the codebase.
The second is lengthy tasks that need a plan. Jev answers all inquiry on its own in a fraction of a second, so it isn’t built to think multiple steps ahead. For an open-ended agent, the setup we’d try is a bigger example doing the preparedness and Jev making the quick calls alongside the way.
The third is item that involves penning or seeing. Jev doesn’t create text, and it lone takes content in, so it can’t appearance at a screen. If your delegate needs to comprehend a display or a messy page, you’ll have to build that translation stage first.
The easiest location to commencement is an delegate or workflow you already run. Find the spots anywhere it asks an LLM a yes-or-no inquiry or has it choose from a abbreviated catalog of options, and run Jev on those identical calls next to your current setup for a week.
Then difference how frequently all one was correct and what all one cost. If Jev holds up, those are decisions you can now oversee to inspect all time. If it doesn’t, you’ve spent a week and a few cents finding out.
Simon is a energetic Content Writer who loves assisting group change their imaginative ideas into thriving businesses. With extended promotion experience, he continually strives to nexus the correct communication alongside the correct audience. In his spare time, Simon enjoys lengthy runs, nurturing his chilli plants, and hiking through forests. Follow him on LinkedIn.
The Co-author
Mantas Lukauskas
Mantas, a Data Scientist at Hostinger, focuses on leveraging AI technologies to run innovation and enhance our projects. With a Ph.D. in Informatics and complete 8 years of cognition in AI, data science, and research, Mantas additionally contributes to academia through assorted AI-focused projects.