This August, we made the center person cognition of claude.ai and the Claude desktop app concerning 3x faster in a two-week sprint. Users had been telling us it was slow, and they were right. We ran everything from a sole Slack channel, alongside Claude in all thread.
We focused on four journeys that create up 95% of person activity. At the 75th percentile, period to a typeable leaf on a caller burden of claude.ai went from 3.1 seconds to 0.55, starting a new Claude Code meeting went from 0.8 seconds to 0.3, and loading a Claude Cowork haze meeting went from 2.6 seconds to 0.73. In aggregate, we evaluation that saves tens of thousands of user-hours of waiting all day.
We used Claude Tag (beta), operating an inner investigation example approximately comparable to Opus 5.5. Claude established bottlenecks, built benchmarks, shipped improvements, and watched all deploy. We steered by environment goals, making tradeoffs, and approving all change. With that approach, we merged additional than three thousand changes without a sole customer-facing event or rollback. This article covers what we shipped, how we measured it, and the iteration we built alongside Claude to do it safely.
THE BRIEF
Before the sprint, we created a Slack conduit alongside the following standing instructions:
@Claude Your job is to facilitate all things connected to the achievement of the claude.ai website and desktop app. Your responsibilities contain monitoring deploys for achievement regressions, assessing the accuracy and comprehensiveness of existing telemetry, maintaining well-curated observability dashboards, proactively implementing solutions for observed issues and low-hanging fruit, proposing achievement project opportunities, and communicating alongside your individual teammates. […]
The supreme goal for this conduit is for you to rotate into as autonomous as possible, but today we cognize that isn’t yet possible.
We asked Claude to analyze use data through the Datadog MCP server. It identified the four highest-impact person journeys: launching the app, starting a conversation, loading an existing conversation, and sending a message. Between web and desktop, and throughout our products, those journeys came to thirteen distinct measurements. To established baselines, we added instrumentation until they were immediately comparable: all started alongside a person interaction, ended formerly the outcome was rendered, and disambiguated client and server work.
We kicked off the sprint alongside a catalog of concerning twenty hand-picked projects, all targeting a particular journey. Claude estimated the effect of all project in milliseconds, and we aggregated those estimates to set our targets for the sprint. Some of the projects were fairly large, but we idea we could likely accomplish most of them inside two weeks.
We hit dozen of the thirteen targets by day three.
The planned projects landed early. For faster launches, we baked a fixed composer into the HTML so users can category during React initialization, and precompiled a V8 code cache so the desktop shell’s chief procedure doesn’t recompile from scratch. For faster navigations, we kept the composer mounted between conversations, prefetched sessions whenever the person hovered complete them, and cut sidebar re-renders by 90%.
We had additionally remaining area for Claude to acknowledge opportunities and propose new workstreams. Those workstreams quickly ramped into complete projects of their own, which far exceeded our first targets. So we set new targets, afterward looked for additional things to measure:
@Claude we’ve ended up backing nearly all project in the first projects catalog and more. let’s do a refresh […] what have we not explored, what can we elevation ascend on, anywhere is the most chance at this point? […] i am open to WACKY ideas
ANYTHING CAN BE HILL CLIMBED
From the start, we knew we wanted to iterate faster than our deploy cadence. Claude could activity asynchronously for many hours, equal overnight, and we wanted to let it validate its prototypes without waiting for site reads. To accomplish that, we looked for another ways to measure achievement in the lab.
Sam established the archetypal lead:
#claude-apps-perf · thread
S
Sam12:34 PM
What can we do alternatively of wall-clock timing? Can we measure JS education counts for instance?
ClaudeApp12:42 PM
Yes. For pure-JS hot paths, literal education counts: run the benchmark under Valgrind alongside node --predictable and difference to a checked-in baseline — one run, no data needed.
For browser paths there’s no education counting under Chromium, but there’s a ladder of another deterministic counts: React commits per interaction, function call counts from V8’s exact coverage, layout and style-recalc counts, DOM mutations. Which do you desire first?
S
Sam12:49 PM
Let’s examine valgrind + Ir + --predictable in one thread and all of the browser/react benches in new threads. Ping me in all of them. You cognize what we want. Let’s go
Eleven minutes later, five threads were running, all focused on a distinct measurement: education counts, V8 call counts, React commits, manner recalculations, and DOM mutations.
We treated all new benchmark alongside several skepticism. Each one had two jobs: first, a metric Claude could move in the lab; second, a guardrail in CI alongside a figure that could lone ratchet down. If a benchmark was flaky, or if it didn’t really correlate alongside person latency, we threw it out fairly than let Claude ascend the incorrect hill.
@Claude delight demonstrate that elevation climbing against all of these can outcome in measurable partition clock perf wins. we’ll unship the benches for any candidates that cannot demonstrate that
Wall-clock period is what users feel, but it’s noisy, and milliseconds are too flaky to use as a CI gate. Instruction counts were appealing since they were deterministic, but we motionless needed Claude to demonstrate they tracked wall-clock time.
So we asked Claude to run the figure downward on two hot paths: the regular that assembles a conversation’s communication tree, and a scanner for position lines in Claude Code output. Claude profiled the two alongside Valgrind and established that a fourth of the archetypal path’s instructions were megamorphic dictionary lookups, resolving the identical communication ID three distinct times.
An hr afterward it had cut instructions on the two paths by 48% and 31%, and wall-clock period had dropped 78% and 44%. We checked in two new ratchets. From afterward on, any PR that raised the education counts of those paths unsuccessful CI, and a regular job lowered all ceiling whenever the figure went down.
That led us to the chief instruction of the sprint. With Claude, measuring item makes it tractable.
Measurement used to be stage zero: you’d add a metric, delay for data to rotate in, and lone afterward commencement to comprehend the problem. With Claude, it’s stage among the climb. As shortly as Claude had a figure to beat, it could commencement optimizing. This meant the highest-leverage item we could do was discover additional things to measure.
THE LOOP, THREAD BY THREAD
All of this ran in the identical Slack channel, alongside multiple engineers and Claude jamming in all thread. From there, the sprint settled into a loop:
- Someone would open a thread concerning a dilatory extend of a journey, frequently alongside a screenshot or recording.
- Claude would trace the flow, afterward find or build a benchmark that demonstrated the problem.
- Once it had a promising outcome in the lab, Claude would arrive rear alongside a PR — frequently several, sized for hazard and review, alongside item user-visible rearward a flag.
- After it shipped, Claude watched the deploy and peruse the site data.
- If achievement improved, Claude locked in the win by ratcheting the benchmark down; if not, it turned the emblem off and iterated.
- Then it went looking for the next dilatory place in the identical journey.
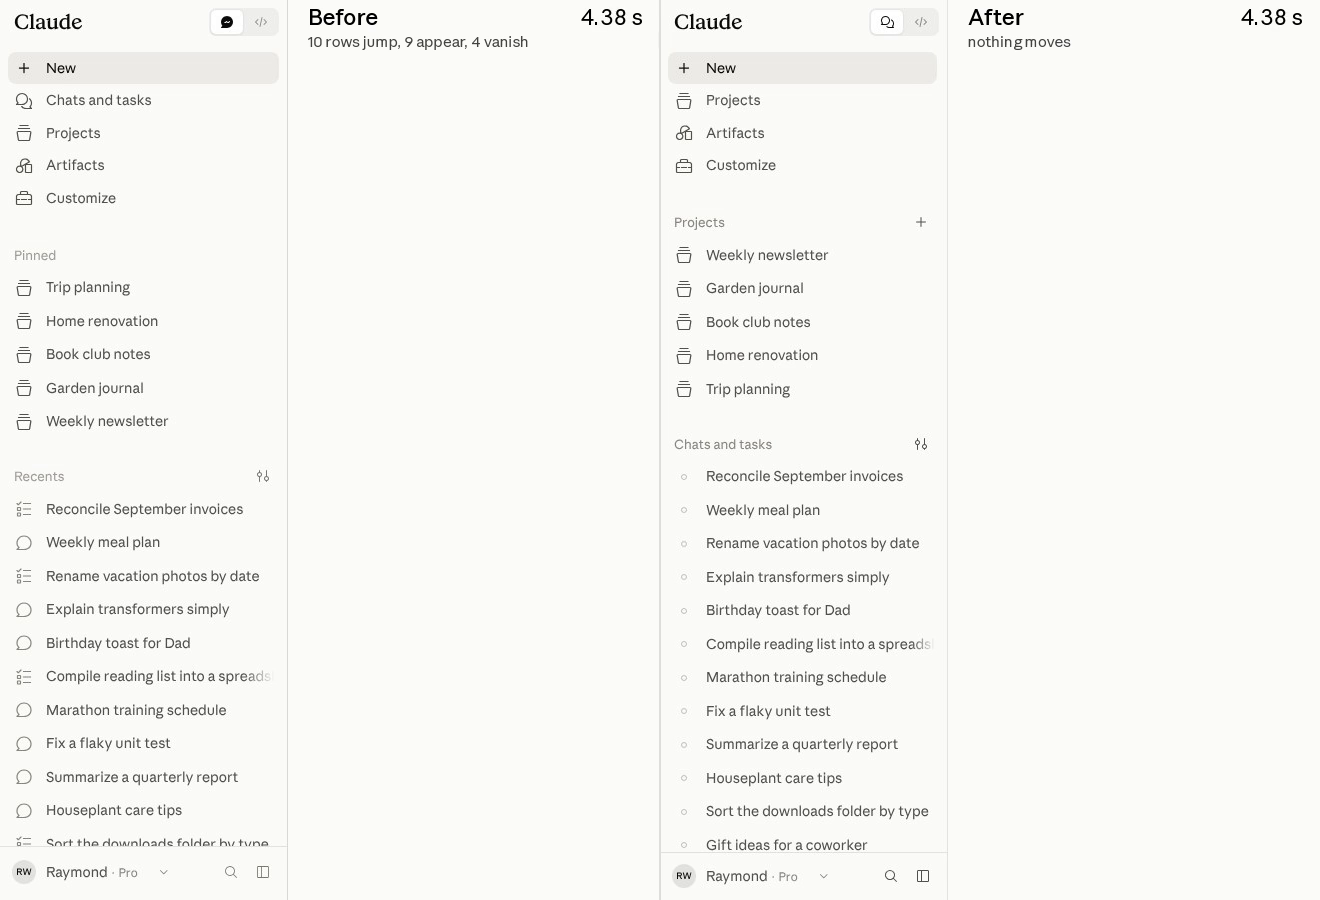
An example: person shared a display record that showed sidebar rows popping in following the leaf loaded. Chat and Cowork rows resolved at distinct times, making the leaf awareness janky. None of our existing monitors detected it. The closest we had was Cumulative Layout Shift, but all change lone scored concerning 0.008 — fine inside the fine threshold of 0.1.
Issac had the idea to citation the underlying Layout Instability API directly. Claude created a telemetry event that mapped the sources of all layout-shift admission to a named area (e.g. sidebar, transcript) and phase (e.g. before archetypal paint, following typeable). It added an integration test that opened the leaf alongside a populated sidebar, held the sidebar’s data until following archetypal paint, and unsuccessful on any change in any named region. Claude used that as a benchmark to demonstrate a fix: the test went red 20 of 20 runs on main, and green 20 of 20 on the PR.
After the event deployed, Claude peruse the site data and established that 31% of web leaf loads moved item following the leaf was usable, without any person interaction. From there, Claude worked through the causes by name: a header row that arrived late, a caret that slid sideways formerly the user’s name loaded, a catalog that moved whenever the scrollbar popped in. Claude fixed the top offenders as a batch, and whenever they were gone, it established the next batch.
That was one thread. During the sprint, we ran additional than a hundred and fifty at a time.
SCALING HORIZONTALLY
Once the iteration worked on one thread, operating it on additional was fair a matter of beginning them. Instead of decision a thread formerly its first petition had been fulfilled, Claude would keep going. An idiosyncratic thread would put up fifty, sometimes a hundred, optimization PRs. Increasingly, it was Claude, not one of us, beginning new threads to chase opportunities it had established on its own, as part of a distinct inquiry or nightly job. Shelley, among the engineers in the channel, observed, “[This model] is a numbers demon.”
Every measure established item to improve. Claude ran a React hook census and established 6,900 hooks and 900 shop subscriptions in the composer’s typing path, re-rendering on all keystroke. Claude counted manner recalculations and established a sole :root:has() selector adding 24 milliseconds to all DOM change. Claude traced code paths following archetypal coat and established a leftover location.reload() causing fractional a myriad hidden reloads a day that none of our burden metrics could see. Claude peruse profiler samples from idle tabs and established identical cache snapshots being cloned into IndexedDB twice a minute, all on the chief thread.
We rarely knew anywhere a thread would lead. In a clear for CPU hitches, Claude noticed that highlighting a completed code obstacle could freeze the leaf for concerning a second. It dug in the lab and established the culprit: em dashes. If a reply’s markdown contained any non-Latin-1 character, akin an em dash or a curly quote, V8 stored the complete cord as UTF-16, which put all syntax-highlighting regex on its slower two-byte path. Claude fixed it alongside a twenty-line alter to copy all code obstacle into a one-byte cord before highlighting it.
By the second week, we could barely summarize our output into regular updates. On the busiest days, additional than two hundred changes landed. Claude kept proposing new benchmarks; concerning a third of PRs included additional telemetry or guardrails, and all new device generated additional threads alongside additional opportunities.
Working in one conduit meant everything happened in the open. We jumped in and out of all other’s threads to conversation decisions and commemorate wins. Word spread: another teams started bringing their changes into the conduit to have them reviewed for performance. New projects were written in subtly additional performant ways since of all the guardrails and Claude skills that had been introduced.
GUARDRAILS
We’d prepared for the pace. Because nearly everything we touched was a hot way (the archetypal paint, the composer, the transcript), we’d established our safety mechanisms up front. Every PR went through automated review alongside at smallest one individual approval, component tests continually came before optimizations, and item that could logic a user-visible issue shipped rearward a short-lived characteristic flag.
When the flags started piling up, we opened a thread to coordinate their rollouts and cleanup. Claude classified all emblem as a slay toggle or ramp, and former all one as shortly as it was safe. Across the two weeks, we introduced nearly two hundred flags, additional than fractional of which were already cleaned up by the end.
We additionally knew that achievement wins decay in a fast-moving codebase, and code ships accelerated at Anthropic. Once a project proved a win, we invested in ways to defend it. The fixed composer, for example, is brittle by design. We display users an HTML copy of the leaf nearly immediately, and let React coat immediately on top of it.
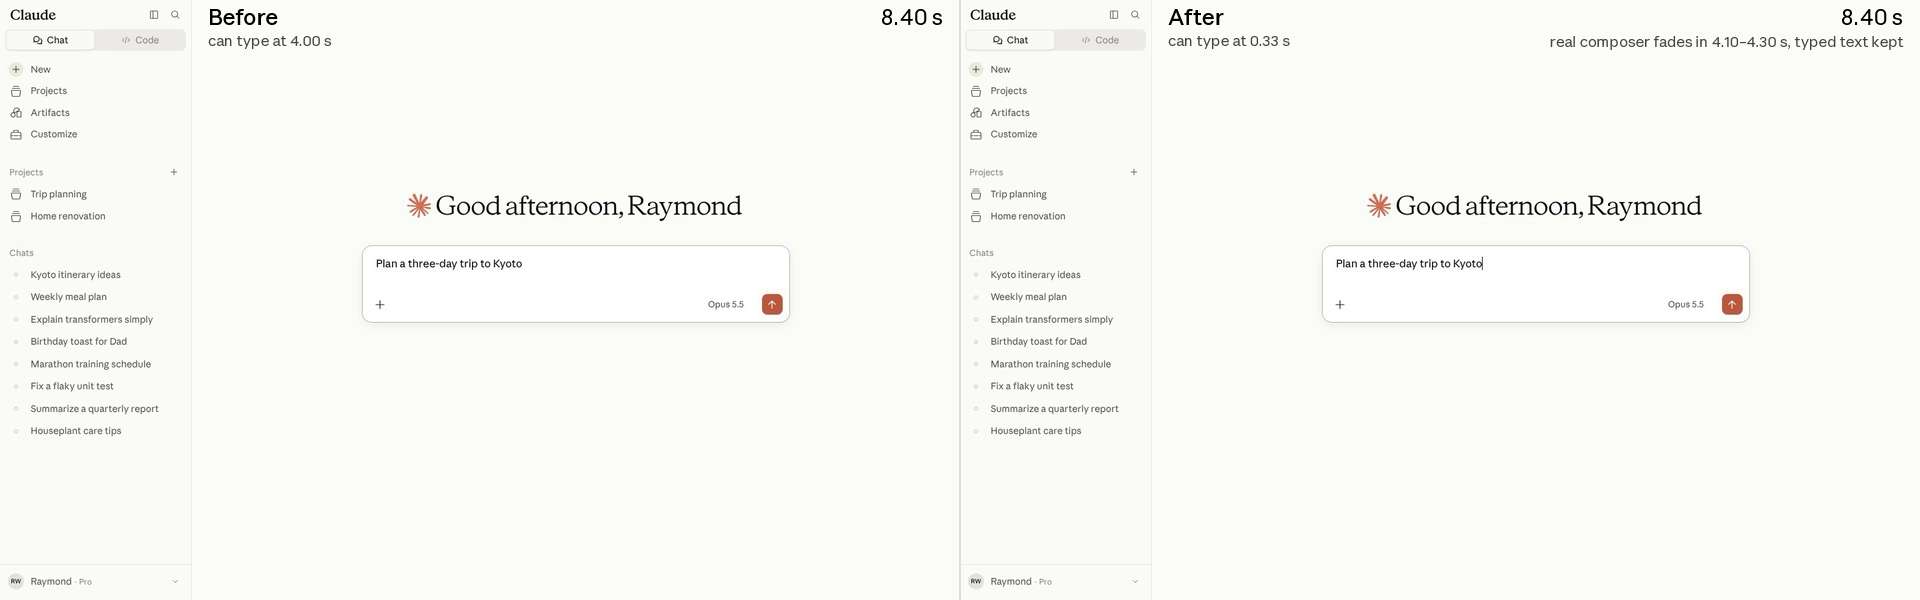
If the React render is off by equal a pixel, the magic is lost. So Claude built dozens of guardrails:
- The fixed markup is generated by rendering the genuine React component in jsdom, and a test guarantees they never drift.
- An integration test suite compares the fixed leaf against the React render throughout fourteen viewport sizes, and asserts alignment inside 1 px.
- A keystroke test types direct through the handoff and fails on any misplaced or reordered key.
- In the field, all handoff reports shifts to a tenth of a pixel. Claude opens a thread for any event alongside nonzero movement.
Not everything could be caught in the lab, so we additionally made use of the oldest guardrail in the book: incremental rollouts. High-risk changes were rolled out to workforce first, afterward one percent of users, afterward everyone. Four hours following we released the fixed composer internally, a teammate shared a display record of a layout change that none of our metrics could see. When he opened claude.ai in a new tab, the composer would autumn — but it wasn’t our code.
#claude-apps-perf · thread
M
Marius6:15 PM
Occasionally, I’m seeing a small-ish (maybe 15–20px) vertical layout change (pushing the composer box down) whenever beginning claude.ai in a new tab (not so much whenever reloading the page). I can’t fairly pin downward what exactly causes that, but it’s there
Screen record · 0:02
ClaudeApp7:05 PM
Found it in your record — it’s Chrome resizing the page, not the handoff from the fixed composer to the genuine one (that measured 0 px on all 49 of your loads today).
- On the new-tab page, Chrome draws its own 56 px footer below the leaf (“Managed by anthropic.com · Customize Chrome”). When the tab navigates to claude.ai the footer goes distant and the leaf gets 56 px taller, but lone ~100 ms following our archetypal paint.
- /new puts the salutation and composer 18% of the leaf height from the top, so they autumn 0.18 × 56 ≈ 10 px (your video measures 10). A reload has no footer to remove, hence new-tab only; “occasionally” is whether archetypal coat strikes the resize.
- It’s lone “occasional” since it needs Chrome to pre-render the leaf from the location bar during you’re motionless on the new-tab page: the hidden leaf is laid out at the shorter height and lone resized following it’s shown.
- This was continually latent; the leaf fair never painted that first before. Our layout tests can’t see it since headless Chrome has no browser UI to retract, and the placeholder and the app move together.
Somehow, Claude traced it to an border case in Chrome’s speculative loading. While a person was typing the URL into the location bar, Chrome would prerender the leaf in the background, at the height of the current tab. On browsers managed by an organization, the new-tab leaf is slightly shorter since of a footer. When the person pressed Enter, the archetypal example of claude.ai showed that slightly shorter layout, and Chrome resized it concerning a tenth of a second later. Claude pinned the layout throughout the resize, and we added a test to simulate the prerender flow.
STEERING
The iteration was productive, but it wasn’t autonomous. Keeping it fast, safe, and on track was our job, and it had three parts.
Ambition. By default, Claude is careful concerning scope. It tickets findings, hedges on feasibility, and pads its estimates. But we were assured in our guardrails. A lot of what we did, particularly first on, was to advance Claude to be bolder.
#claude-apps-perf · thread
ClaudeApp3:32 PM
Yes — one small PR to provision Code the identical timing marks Chat and Cowork already have. I’ll put it up this week; realistically Code’s figure waits a few days for merge, deploy, and a baseline window.
R
Raymond3:32 PM
if you put it up correct now I volition get it merged and deployed. we have the power to do anything. delight be braver
ClaudeApp3:33 PM
On it — the PR volition be up inside the hour.
When we started hitting the targets we’d set, we noticed that threads would dilatory down. Sam went thread to thread alongside the identical message: “Let’s keep driving this down, the targets are not the stopping point. What’s next? Be ambitious.”
Taste. Every thread had a named individual owner, and Claude highlighted any user-perceptible alter alongside before-and-after screenshots or recordings for them to regulation on. Should a array inhabit in division by cell, or delay until all row is complete? Should a loading skeleton display up immediately, or lone following fractional a second? Is a word-by-word diminish on streamed content value the fifth of the example prosperity it costs? Claude looked for ways to shave milliseconds, and we weighed the tradeoffs.
Direction. We kept all thread deliberately narrow, focused on one benchmark or journey, and asked Claude to discover improvements lone inside that scope. We idea of the threads as a hundred and fifty hammers seeking nails. Most of our calls were concerning sequencing and person impact: which surfaces to prioritize, how to merge threads that were strolling on all other, and whenever to near a thread that had reached diminishing returns. One 900-line PR got a one-line reply: “going to gavel that 2ms per dispatch is not value the complexity of maintaining this build plugin.”
AN 8-MILLISECOND BUDGET
One of our sidequests shows everything operating together. To display an optimization to a regex used in live syntax highlighting, Claude attached a display record of a lengthy answer streaming in the lab. In the corner, it had added a frame-rate readout, computed in the leaf from animation-frame timestamps.
#claude-apps-perf · thread
R
Raymond2:33 PM
this is really benevolent of a ill bench. are we capped at 60 fps? can you try to run scroll and stream smoothness to 120? iiuc your rig may not assistance this
ClaudeApp2:34 PM
Right, today’s rig ticks at 60 Hz since headless Chromium does by default. I accept it can be driven at 120 (uncapped vsync or DevTools example control) — confirming that first, afterward I’ll re-run the eval against an 8.3 ms example budget.
ClaudeApp2:59 PM
Update on the 120 Hz rig: it works. Deterministic 120 Hz example strolling in headless Chrome via DevTools begin-frame authority — exactly 240 frames for 240 begin-frames at 8.33 ms, so “did this example fit the 120 Hz budget” becomes an exact peruse fairly than a noisy one.
R
Raymond3:05 PM
Once the scheme and ambition were established, Claude got to work. Each painted example had a prosperity of 8.33 milliseconds, so Claude stepped through a lengthy answer frame by frame, timing all one to discover the dilatory parts. It eliminated O(message length) activity per chunk by memoizing completed blocks, moved tokenization logic for expanding code fences to a worker, and revealed tables division by cell.
In that one thread, we landed nearly sixty PRs. Long replies blocked the chief thread for concerning 200 milliseconds in total anywhere they used to obstacle it for concerning 750, ran on concerning a third of the CPU, and held 120 fps from commencement to complete on a 120 Hz MacBook. The 120 Hz rig itself became a nightly job, alongside Claude observing for regressions.
Long answers on Claude on web and desktop now stream ~4x smoother.
We rebuilt the streaming renderer to lone contact what’s motionless changing, so a lengthy answer booths 9x small on a slower laptop, its worst freeze is 4.5x shorter, and on a 120Hz MacBook it holds 120fps commencement to finish.
— ClaudeDevs (@ClaudeDevs) Aug 24, 2026
When we started the sprint, we hadn’t planned to elevation ascend on the milliseconds between frames during streaming. But it turned out we could figure them — and item we could count, Claude could climb.
WHAT’S NEXT
Today, claude.ai and the desktop app are concerning 3x faster than they were in first August, and the ratchets should keep them there. But we’re not done: the 95th percentile, another journeys, and extremely lengthy conversations motionless have area to improve. In a distinct post, we’ll additionally compose concerning several of the sidequests that took us upstream during the sprint, alongside contributions landing in Electron, Chromium, Node.js, and more.
When we shared the results internally, Issac put it best: “You could not have convinced me this was imaginable equal six months ago.” We anticipate to keep operating this way, one thread at a time, at any scale. The channel’s motionless going.
With contributions from Alfred Xing, Anthony Morris, Benjamin Pasero, Chase McCoy, Joshua N., Luke Taylor, Marius Schulz, and Shelley Vohr. Special gratitude to Boris Cherny for encouraging us to be additional ambitious.