Sep 04, 2026
/
By Ksenija
/
24 min Read
To train a ample connection exemplary (LLM), you request to set its learned parameters by presenting it pinch tokenized text, measuring prediction error, and optimizing its weights.
During training, the exemplary predicts the adjacent token, calculates a nonaccomplishment that measures prediction error, uses backpropagation to cipher gradients, and applies an optimizer to update its weights. That loop repeats crossed tremendous numbers of token sequences.
Reaching that constituent requires acold much than moving a training loop. Every shape of the process influences the last model, from preparing high-quality datasets and selecting a tokenizer to evaluating the model’s capacity aft training.
There are 2 main routes. Training from scratch starts pinch randomly initialized weights and a very ample pretraining corpus, while fine-tuning starts pinch an already pretrained exemplary and adapts it to a narrower task, style, domain, aliases instruction group utilizing overmuch little information and compute.
For astir developers and mini teams, fine-tuning a suitable open-source exemplary is much applicable than training a instauration exemplary from scratch because it requires acold little data, compute, time, and engineering effort.
Training an LLM from scratch vs. fine-tuning
Training from scratch builds a connection exemplary from randomly initialized weights, while fine-tuning models modifies an already pretrained exemplary for a circumstantial task, behavior, aliases domain.
Between these 2 approaches is continued pretraining, which extends a pretrained model’s knowledge earlier it is fine-tuned for a peculiar application.
The array beneath compares the main differences betwixt training an LLM from scratch and fine-tuning an existing model.
Factor | Train from scratch | Fine-tune an existing LLM |
Starting point | Random exemplary weights | Pretrained model |
Data required | Very ample corpus | Smaller task- aliases domain-specific dataset |
Compute | Multi-GPU aliases distributed GPU training | Often 1 aliases respective GPUs |
Cost | Very high | Much lower |
Time | Days to months | Hours to days |
Flexibility | Full power complete architecture and training data | Works wrong the existing architecture |
Best for | Research labs, instauration exemplary providers, AI companies building proprietary models | Application developers, startups, enterprises, and AI teams customizing existing models |
Main risk | High costs and training instability | Overfitting aliases degrading wide capabilities |
Training from scratch originates pinch an untrained exemplary whose parameters are randomly initialized.
At this stage, the large connection model has nary learned connection practice from data; it has nary knowing of language, grammar, facts, aliases reasoning.
It gradually learns statistical patterns by processing a monolithic matter corpus, many times predicting the adjacent token successful each sequence, measuring prediction errors, and adjusting its parameters complete a very ample number of training steps and token sequences.
As the training progresses, the exemplary learns statistical patterns successful the data, enabling it to make coherent matter and execute a wide scope of connection tasks.
Because each capacity must beryllium learned during this first training stage, training from scratch requires tremendous datasets, important computing resources, and observant optimization.
The consequence is simply a instauration exemplary that tin later beryllium adapted to circumstantial domains aliases tasks done continued pretraining aliases fine-tuning.
Continued pretraining starts pinch an existing pretrained exemplary and exposes it to further matter from a peculiar domain, specified arsenic medicine, law, finance, aliases package development. The nonsubjective is to grow the model’s knowledge earlier adapting it to a circumstantial application.
Fine-tuning besides starts pinch a pretrained model, but the nonsubjective is different. Rather than school the exemplary caller wide knowledge, fine-tuning adjusts its behaviour for a peculiar task, output format, penning style, aliases group of instructions utilizing a overmuch smaller dataset.
What happens erstwhile you train an LLM?
The LLM workflow starts pinch preparing matter and training the model, past moves into evaluation, post-training, wherever needed, and deployment aft the trained exemplary has been produced.
Between those stages, the exemplary many times learns from the training information by making predictions, measuring errors, and improving its soul parameters.
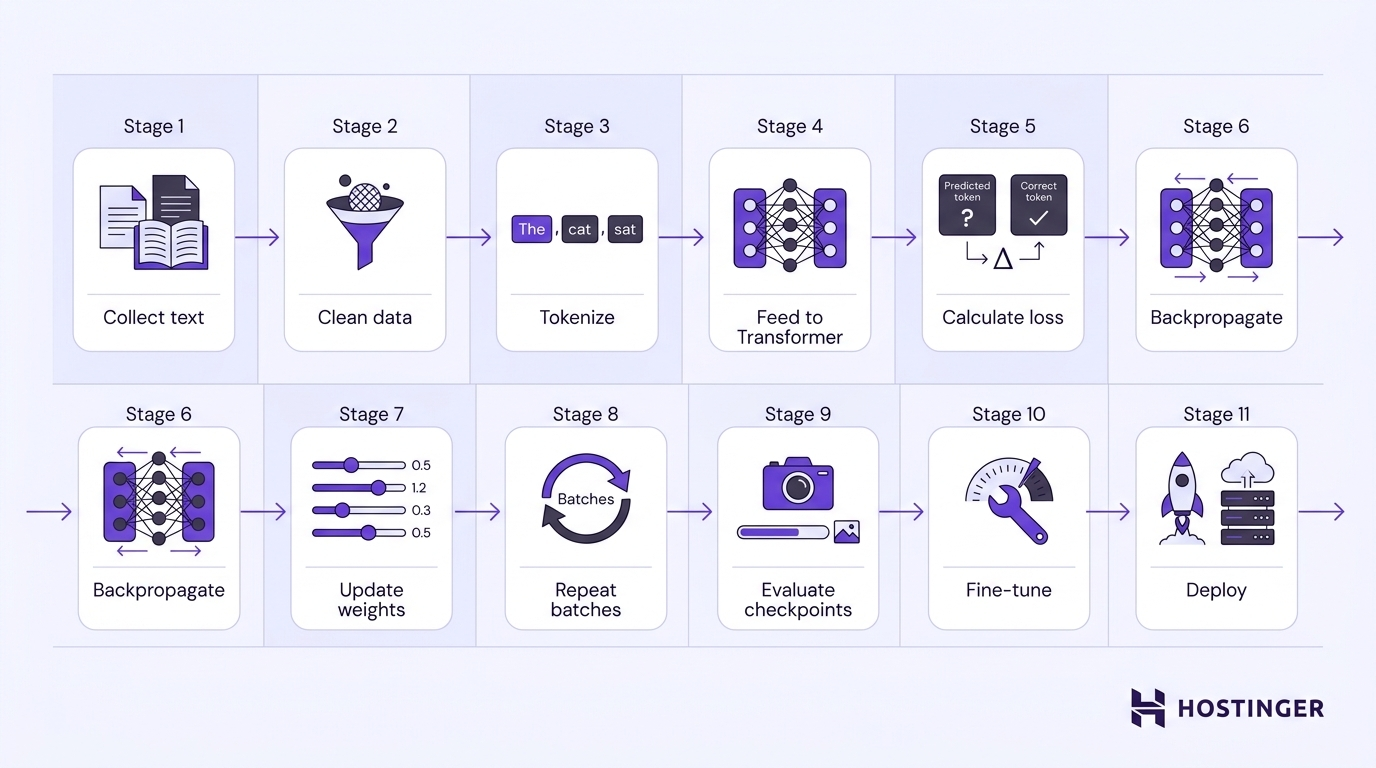
At a precocious level, the training process follows these stages:
- Collecting text. Training originates pinch a ample corpus of matter gathered from books, websites, investigation papers, root code, aliases different information sources.
- Cleaning and preparing the data. The dataset is filtered to region low-quality, duplicated, aliases irrelevant contented earlier being converted into a format suitable for training.
- Converting the matter into tokens. Because LLMs cannot process earthy matter directly, a tokenizer breaks each archive into smaller units called tokens, which go the model’s input.
- Feeding token sequences into the Transformer. The Transformer processes each series of tokens and predicts the adjacent token based connected the preceding context.
- Calculating the loss. The predicted token is compared pinch the correct token from the training data. The quality betwixt the prediction and the correct reply is measured by the loss, a numerical worth indicating really acold the prediction is from the expected result.
- Backpropagating the error. The training process calculates really overmuch each exemplary parameter contributed to the prediction error. This process, called backpropagation, determines really the exemplary should alteration to trim early errors.
- Updating the exemplary weights. An optimizer uses the results of backpropagation to set the model’s weights, the numerical parameters that find really the exemplary processes information.
- Repeating crossed galore batches. The training information is divided into batches, aliases groups of training examples processed together. The optimizer updates the exemplary crossed galore training steps until the planned token aliases measurement fund is reached.
- Evaluating checkpoints. During training, developers periodically prevention checkpoints, which are snapshots of the exemplary astatine different stages of learning. These checkpoints thief measurement progress, comparison exemplary quality, and resume training if necessary.
- Fine-tuning aliases post-training the model. Once pretraining is complete, the exemplary whitethorn acquisition further training to amended instruction following, accommodate to a peculiar domain, aliases specialize successful circumstantial tasks.
- Deploying the model. After evaluation, the trained exemplary is fresh for inference, enabling applications to make responses, reply questions, aliases execute different connection tasks.
How to train an LLM from scratch
Training an LLM from scratch involves a bid of interconnected stages, from defining the model’s intent and preparing the training information to optimizing the exemplary and evaluating its performance.
Each shape builds connected the erstwhile one, and decisions made early successful the process power each measurement that follows.
1. Define the model’s intent and size
The first measurement is determining what the exemplary is expected to do. A exemplary designed to reply questions crossed galore subjects requires a different architecture, training dataset, and computing fund than 1 built exclusively for ineligible research, aesculapian literature, aliases package development.
At this stage, developers specify the model’s scope by answering respective cardinal questions:
- Will the exemplary beryllium general-purpose aliases domain-specific?
- Which languages should it support?
- What context length should it handle?
- Approximately really galore parameters should it contain?
- What are the inference requirements, specified arsenic consequence latency, representation usage, aliases deployment environment?
- How overmuch time, hardware, and budget are disposable for training?
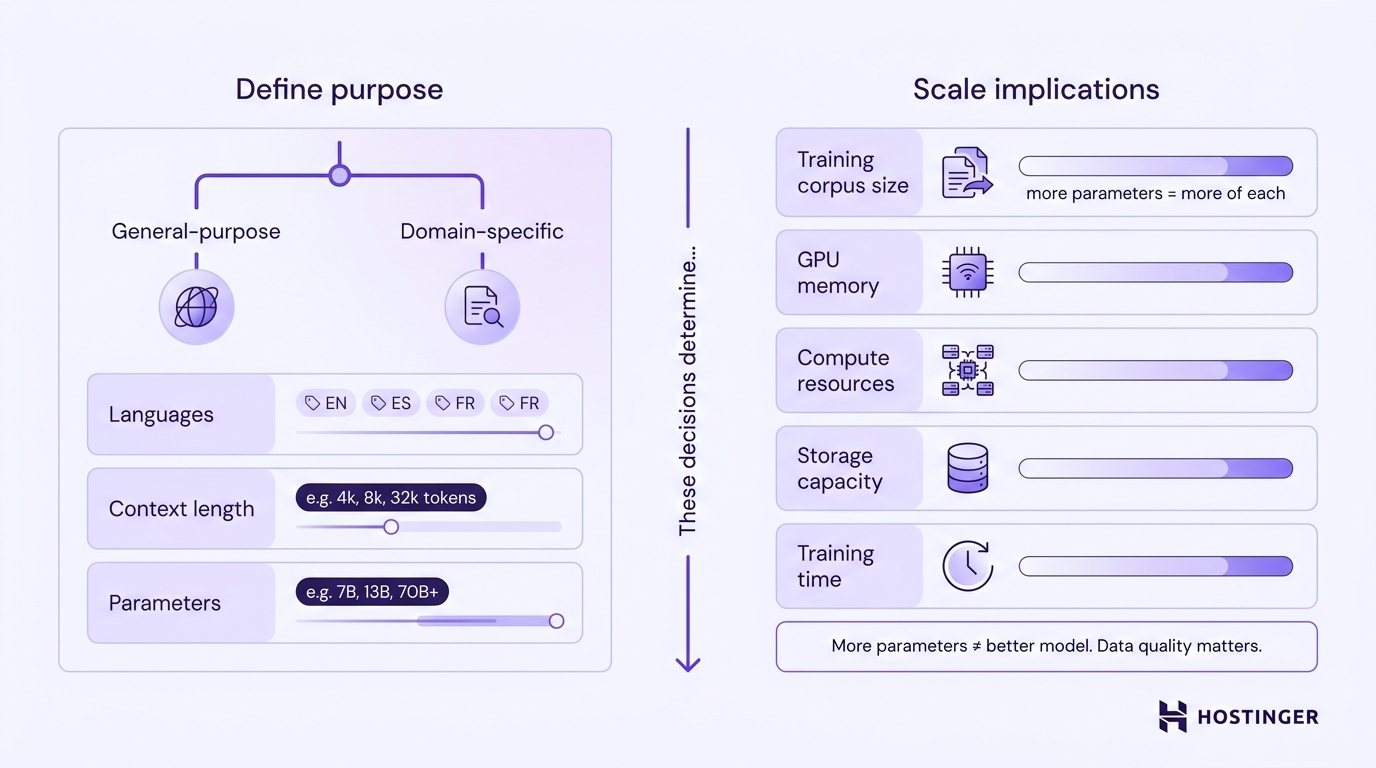
Parameter count unsocial does not find exemplary quality. Dataset quality, token coverage, optimization stability, architecture choices, and information results tin matter arsenic overmuch arsenic earthy size
2. Collect the training dataset
The adjacent measurement is to combine the dataset that the exemplary will study from. During pretraining, an LLM analyzes tremendous amounts of matter to observe connection patterns, actual relationships, and reasoning structures.
The value and diverseness of that information straight effect the model’s capabilities, making dataset mentation 1 of the astir important stages of the training process.
A pretraining corpus typically combines aggregate sources to seizure a wide scope of penning styles, topics, and vocabulary.
Common sources see licensed datasets, public-domain books, method documentation, world publications, codification repositories pinch due licensing, web content, and organization-owned data.
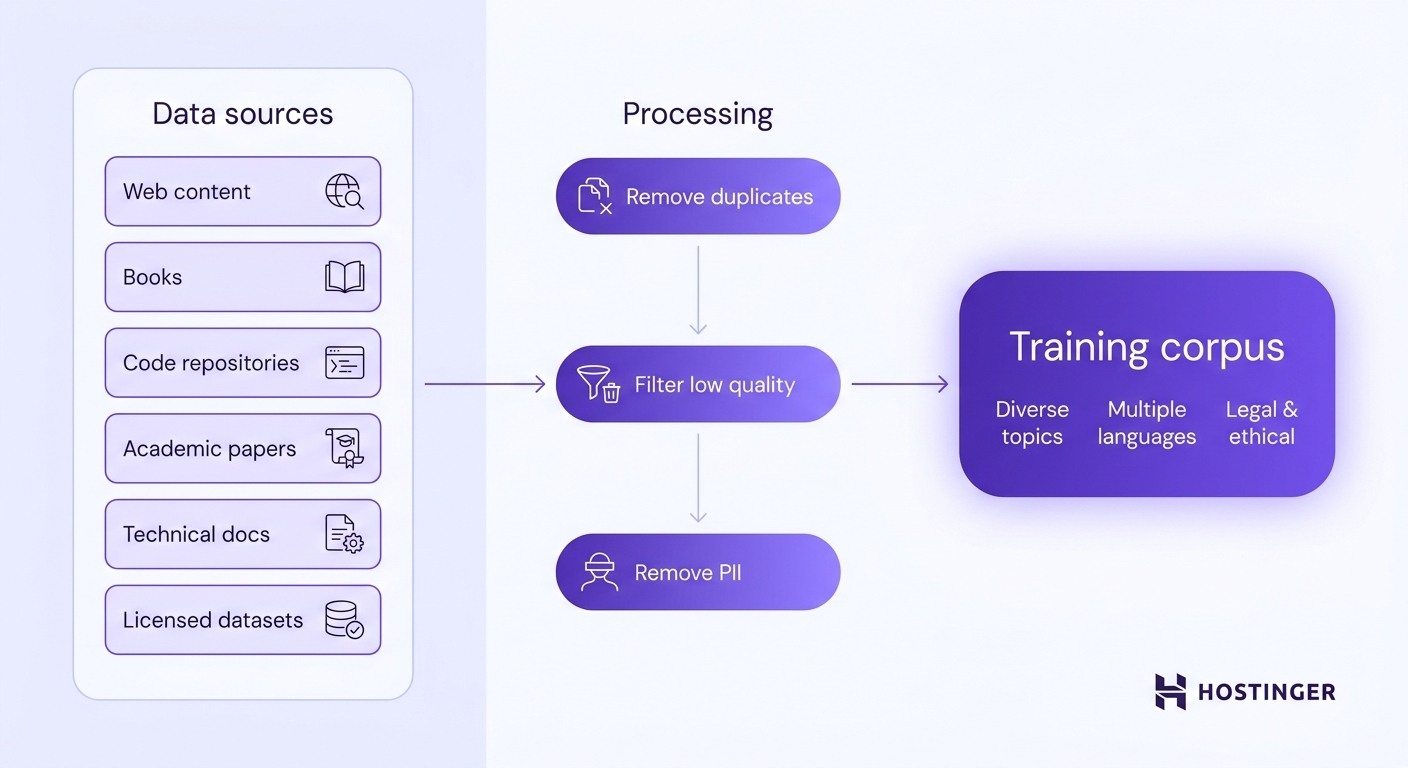
The nonstop operation depends connected whether the extremity is to build a general-purpose instauration exemplary aliases 1 specialized successful a peculiar domain.
Before utilizing a source, corroborate that its licence aliases position licence the intended training usage and relationship for applicable copyright, privacy, and data-protection obligations. Remove, anonymize, aliases different protect personally identifiable accusation (PII) and delicate information wherever required.
3. Clean and hole the data
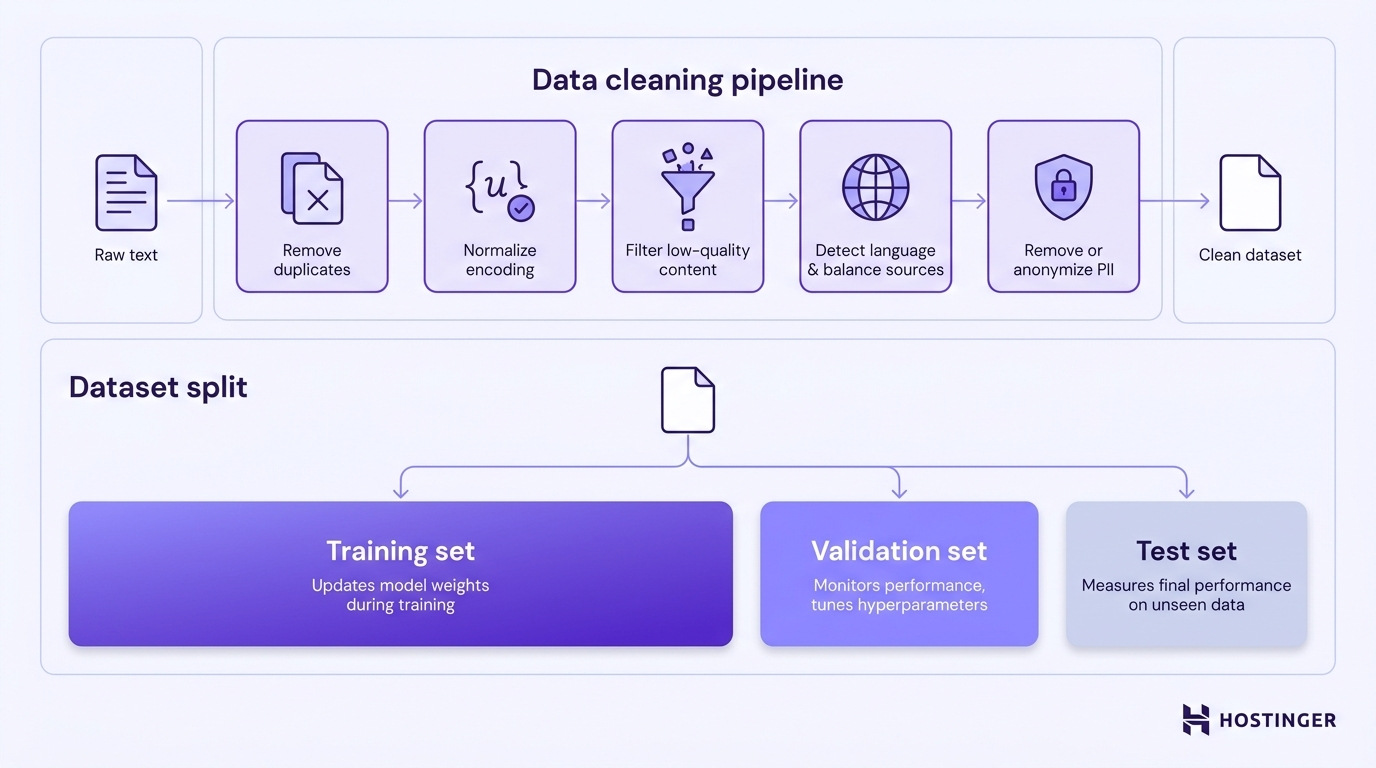
Before the dataset reaches the tokenizer, developers region copy documents and corrupted aliases malformed text, normalize characteristic encoding and formatting, and select retired spam, low-quality content, and synthetic information that does not meet the project’s value criteria
They besides observe the connection of each document, equilibrium multilingual and domain-specific information sources, and region aliases anonymize personally identifiable accusation (PII) and different delicate data.
Once the dataset has been cleaned, it is divided into 3 subsets, each serving a different intent passim development:
- Training set – The information of the dataset utilized to update the model’s weights during training.
- Validation set – A abstracted dataset utilized to show the model’s capacity during development, helping developers tune hyperparameters and observe problems specified arsenic overfitting (where the exemplary performs good connected training information but poorly connected unseen data).
- Test set – A dataset the exemplary has ne'er seen during training aliases validation, utilized only to measurement its last capacity connected unseen data.
Careful information mentation improves some the value of the trained exemplary and the reliability of its evaluation.
Without it, moreover a ample training corpus tin nutrient a exemplary that memorizes repeated content, learns from noisy data, aliases performs poorly connected caller tasks.
4. Train aliases take a tokenizer
The adjacent measurement is deciding which tokenizer the exemplary will use. When training an LLM from scratch, developers typically train a caller tokenizer truthful its vocabulary matches the languages, terminology, and penning patterns of the training corpus.
A tokenizer converts earthy matter into a format the exemplary tin process. LLMs do not publication words aliases sentences directly. Instead, they process tokens, which whitethorn correspond full words, parts of words, punctuation marks, spaces, aliases moreover individual characters.
The tokenizer assigns each token a unsocial numerical identifier called a token ID, and the complete group of tokens it recognizes forms its vocabulary.
In summation to mean text, the vocabulary contains special tokens that people the opening aliases extremity of a sequence, abstracted different inputs, aliases pad shorter sequences to a accordant length.
For example, the sentence:
The feline sat connected the mat.
might beryllium converted into the pursuing tokens:
["The", "cat", "sat", "on", "the", "mat", "."]
Each token is past mapped to a numerical token ID. For illustration, a tokenizer mightiness produce:
[154, 892, 431, 78, 25, 613, 9]
The exemplary processes the token IDs alternatively than the original text.
Many modern tokenizers spell 1 measurement further by utilizing subword tokenization, which breaks unfamiliar aliases uncommon words into smaller, reusable pieces.
Rather than assigning a unsocial token to each imaginable word, the tokenizer tin harvester existing subwords to correspond words it has ne'er encountered before.
For instance, if the tokenizer has ne'er seen the connection “untestable”, it mightiness divided it into:
["un", "test", "able"]
Because each subword already exists successful the vocabulary, the tokenizer tin correspond the complete connection without needing a dedicated token for “untestable”.
This attack keeps the vocabulary compact while allowing the exemplary to process a overmuch wider scope of text.
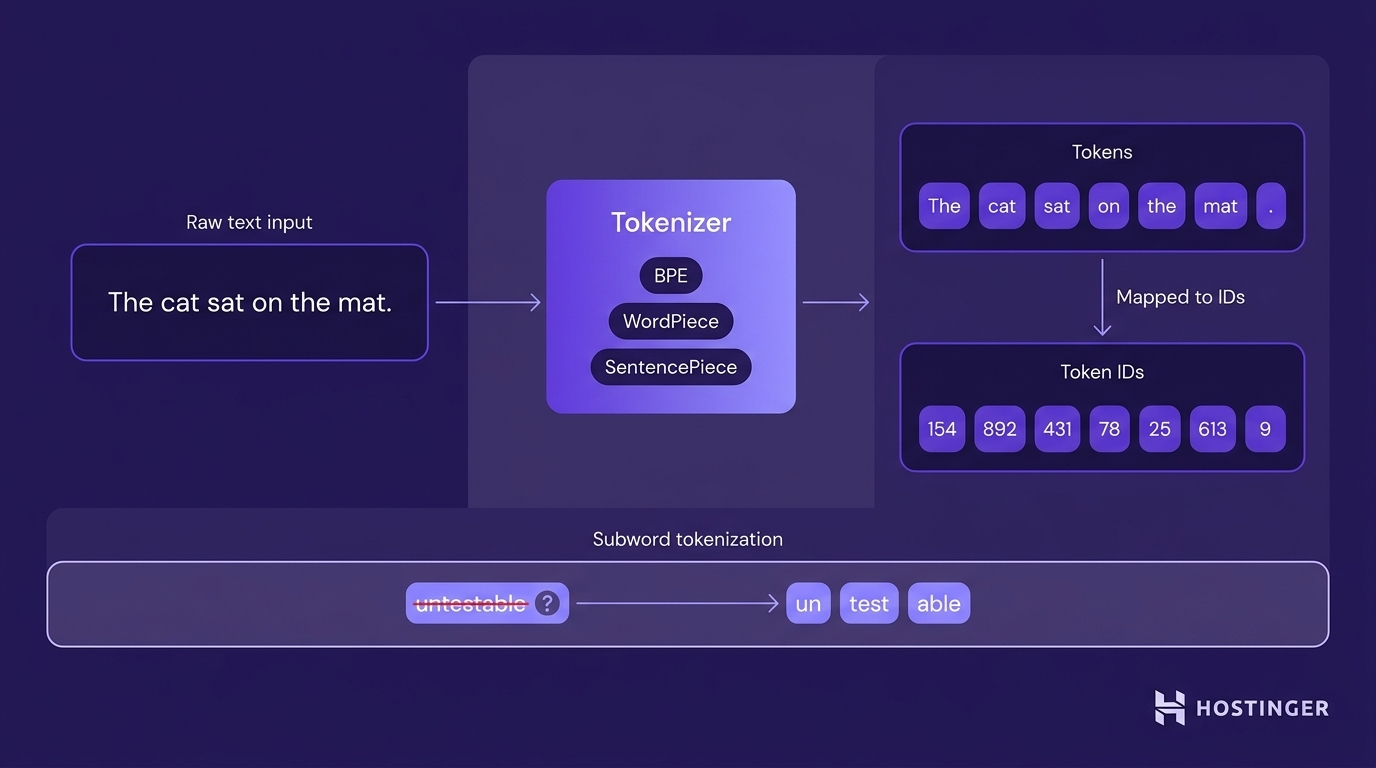
Several tokenization methods instrumentality this thought successful different ways:
- Byte Pair Encoding (BPE) builds the vocabulary by many times merging the astir communal pairs of characters aliases subwords recovered successful the training corpus.
- WordPiece creates a compact vocabulary by selecting the astir useful subwords from the training data.
- SentencePiece learns subwords straight from earthy matter without requiring the input to beryllium divided into words first.
5. Configure the Transformer architecture
Configuring the architecture intends deciding really overmuch capacity the exemplary should have.
Developers statesman by choosing the number of layers, which determines really galore processing stages the exemplary uses to analyse each token sequence.
They past prime the hidden dimension, which defines really overmuch accusation each token tin transportation arsenic it moves done the network.
The number of attention heads controls really galore relationships betwixt tokens the exemplary tin analyse simultaneously, while the context length specifies really galore tokens the exemplary tin process successful a azygous input.
Finally, the vocabulary size establishes really galore unsocial tokens the exemplary tin admit done its tokenizer.
These architectural choices impact exemplary capacity, representation use, and training cost, but expanding them does not automatically amended exemplary quality. The correct configuration depends connected the data, training budget, target tasks, and evaluation.
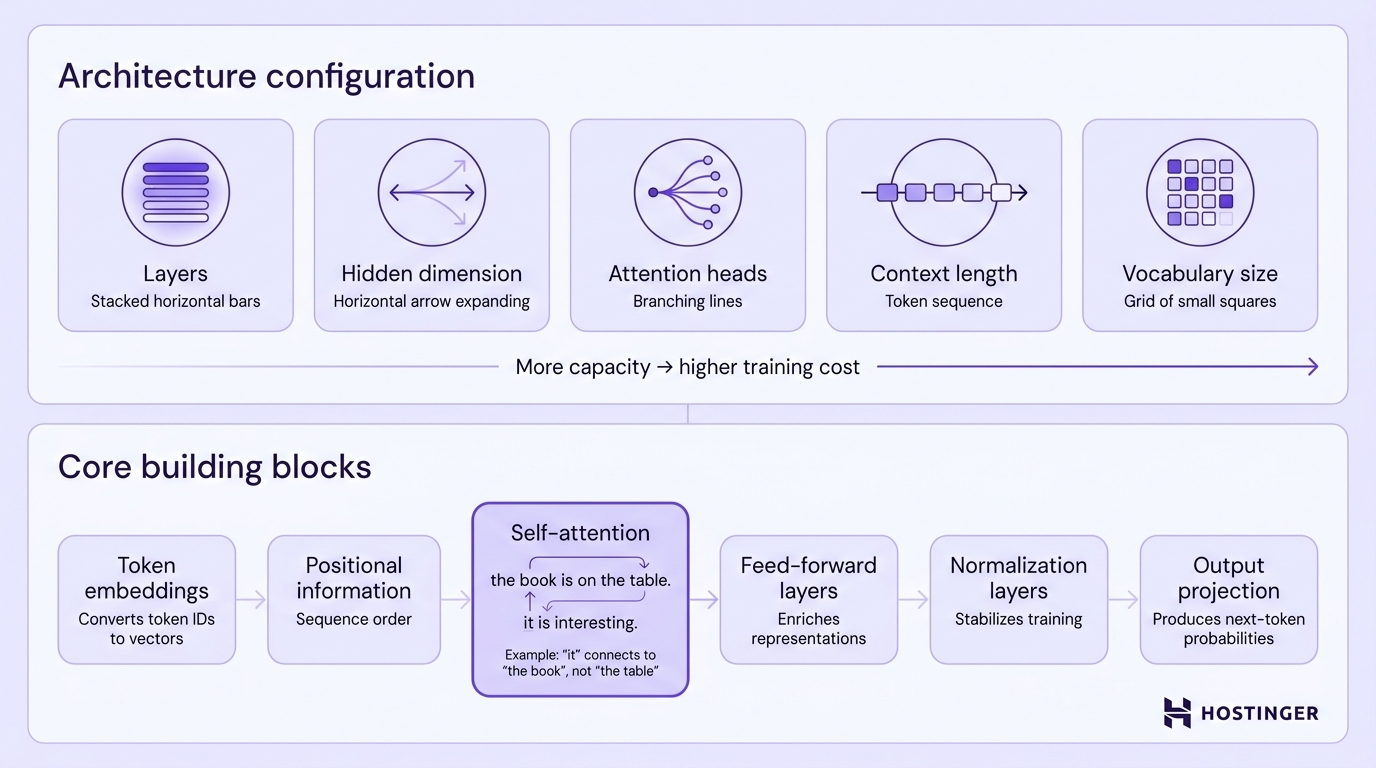
Most modern LLMs usage the aforesaid underlying Transformer architecture. Although developers configure its size, the halfway building blocks stay the same:
- Token embeddings person each token ID into a numerical practice that the exemplary tin process.
- Positional information tells the exemplary wherever each token appears successful the sequence.
- Self-attention allows the exemplary to find which earlier tokens are astir applicable erstwhile processing the existent token. For example, successful the condemnation “The book was placed connected the array because it was heavy,” self-attention helps the exemplary subordinate “it” pinch “the book” alternatively than “the table.”
- Feed-forward layers toggle shape the accusation produced by self-attention into richer connection representations.
- Normalization layers stabilize training by keeping numerical values wrong a accordant range.
- The output projection layer converts the model’s soul practice into a probability distribution complete the vocabulary, enabling it to foretell the adjacent token.
6. Configure the training environment
Configuring the training situation involves preparing the hardware and package that will tally the training job.
The hardware requirements dangle connected exemplary size, series length, batch size, precision, optimizer state, and the standard of the training run. Modern LLM training relies chiefly connected graphics processing units (GPUs) aliases different AI accelerators because they tin efficiently execute the ample matrix operations utilized successful neural web training.
As the exemplary grows, training whitethorn require aggregate GPUs to supply capable representation and compute power.
GPUs are only 1 portion of the training environment. CPUs hole and load the training data; strategy RAM temporarily stores that information earlier it reaches the GPUs; retention holds the training corpus, exemplary checkpoints, and software, and networking allows aggregate machines to speech information during distributed training.
Training requires overmuch much representation than conclusion because the strategy stores much than conscionable the model’s weights.
During training, it besides stores activations (intermediate values produced arsenic information moves done the network), gradients (values utilized to cipher really the weights should change), and optimizer states (additional accusation utilized erstwhile updating the weights).
These intermediate training states tin devour much representation than the exemplary weights themselves.
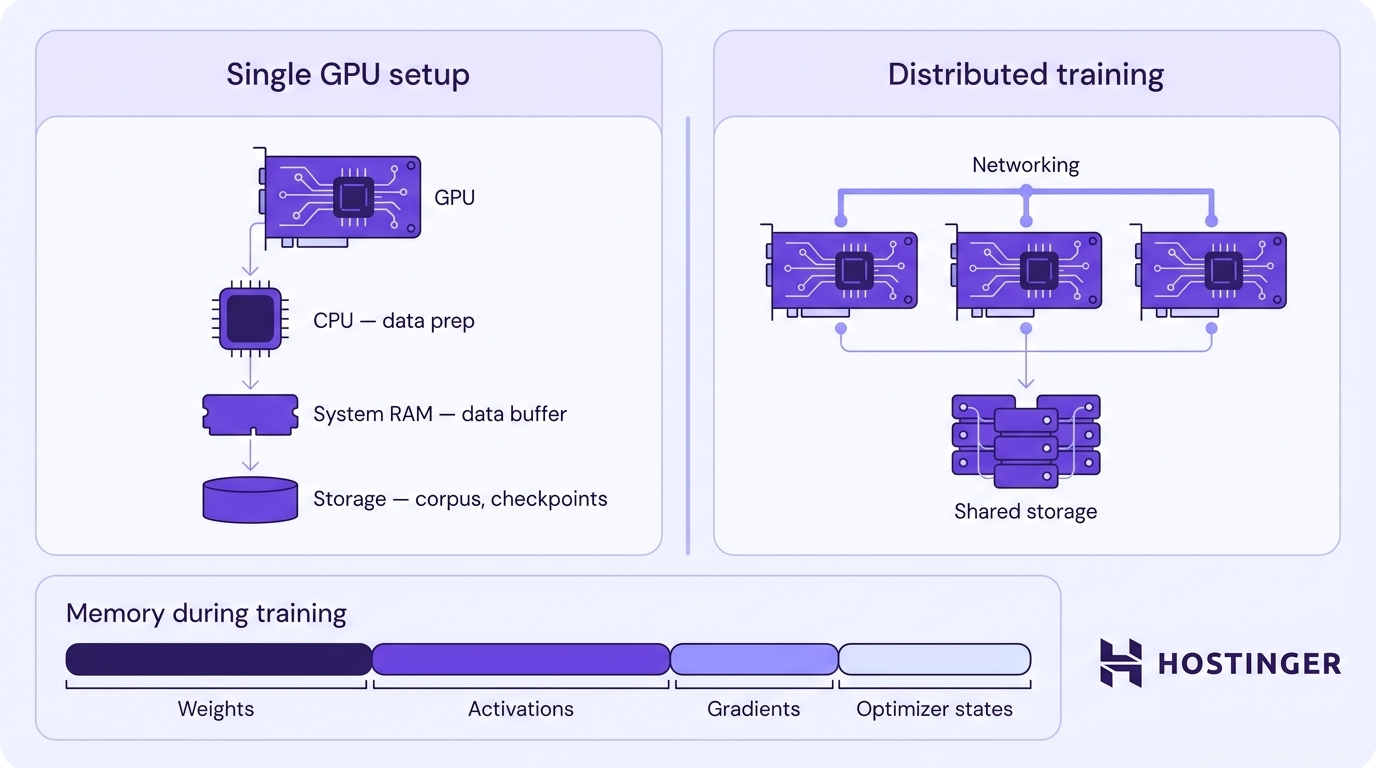
As models turn larger, configuring the situation besides intends deciding really the training workload will beryllium distributed.
Smaller models whitethorn fresh connected a azygous GPU, whereas large-scale pretraining typically requires aggregate GPUs aliases distributed training crossed respective machines to supply capable representation and computational power.
7. Set the training hyperparameters
Hyperparameters are predefined training settings, specified arsenic the learning rate, batch size, and number of training steps.
Unlike exemplary parameters, they are selected by developers alternatively than learned by the model.
Setting them involves choosing values that equilibrium training speed, representation usage, numerical stability, and the model’s last performance.
Developers usually statesman by selecting the optimizer, which defines really the model’s weights are updated aft each training step.
They past take a learning rate, which controls really overmuch the weights alteration aft each update.
Because a learning complaint that is excessively precocious tin make training unstable, galore training runs commencement pinch a warmup period, gradually expanding the learning complaint earlier pursuing a predefined learning-rate schedule for the remainder of training.
The adjacent measurement is configuring really the training information is processed. The batch size determines really galore training examples are processed together earlier the exemplary updates its weights, while the sequence length sets the maximum number of tokens the exemplary processes successful a azygous input.
When GPU representation is limited, developers tin usage gradient accumulation, which combines gradients from aggregate smaller batches earlier updating the weights.
This produces the effect of a larger batch size without requiring further GPU memory.
Training long must beryllium configured earlier learning begins. An epoch represents 1 complete walk done the training dataset, though LLM pretraining is much commonly measured by the number of training steps aliases the full number of tokens processed because the datasets are highly large.
Developers besides configure weight decay, a regularization mounting that discourages excessively ample weight values and tin thief trim overfitting erstwhile tuned appropriately.
Finally, they take the numerical precision utilized during training. Common formats see FP32 (32-bit floating-point), FP16 (16-bit floating-point), and BF16 (Brain Floating-Point 16).
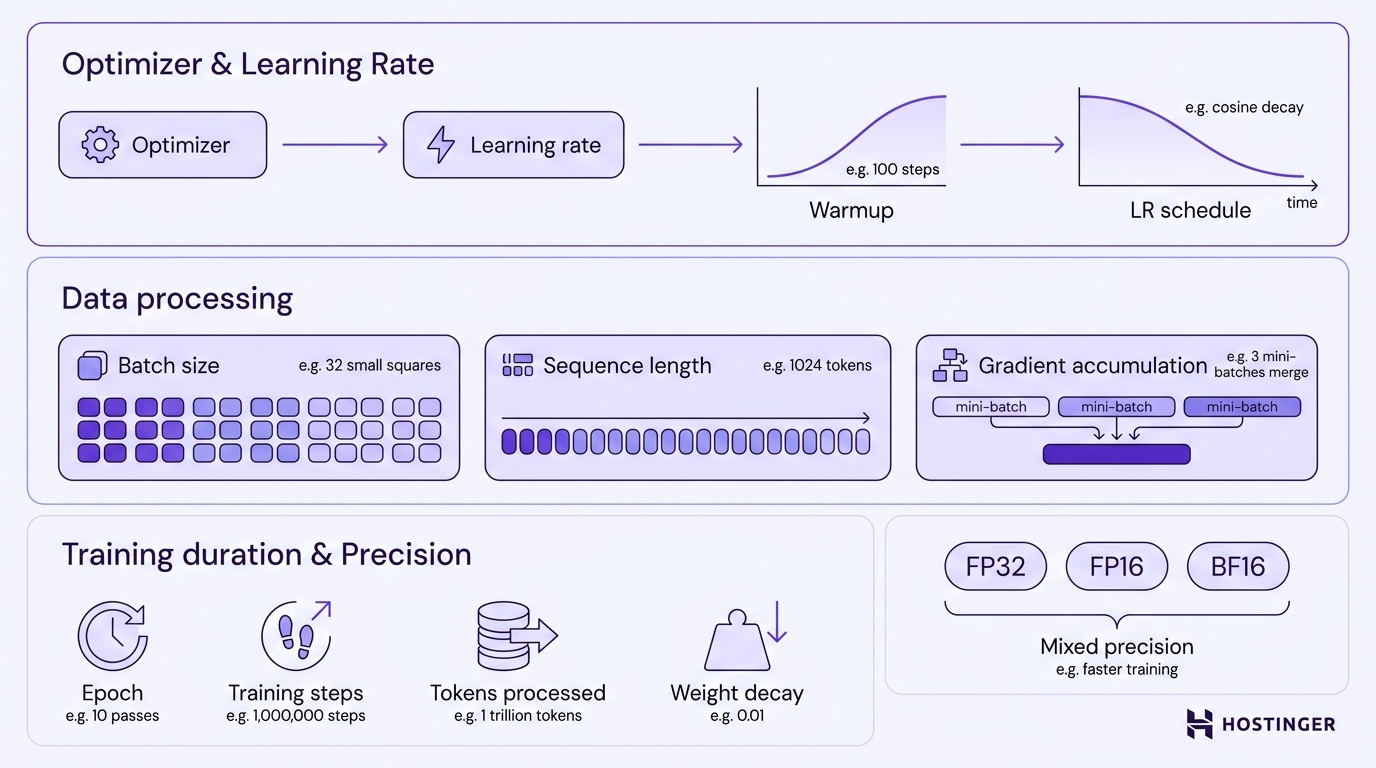
Many training runs usage mixed aliases reduced precision to little representation usage and summation throughput connected compatible hardware, while monitoring for numerical instability aliases value regressions.
8. Run the pretraining loop
Running the pretraining loop involves many times processing batches of training information until the exemplary reaches the desired capacity level.
Each training step processes a batch of token sequences and updates the model’s weights. The extremity is for capacity to amended complete galore updates; an individual measurement is not guaranteed to amended the model.
Repeated crossed a very ample token budget, these updates let the exemplary to study statistical regularities successful the training data.
During each training step, the training strategy performs the pursuing series of operations:
- Load a batch of token sequences.
- Feed the tokens into the Transformer.
- Predict the adjacent token astatine each position successful each sequence.
- Compare the predictions pinch the correct tokens from the training data.
- Calculate the nonaccomplishment to measurement the prediction error.
- Run backpropagation to find really each exemplary weight contributed to that error.
- Update the model’s weights utilizing the optimizer.
- Clear aliases accumulate gradients, depending connected the training configuration.
- Repeat the process pinch the adjacent batch.
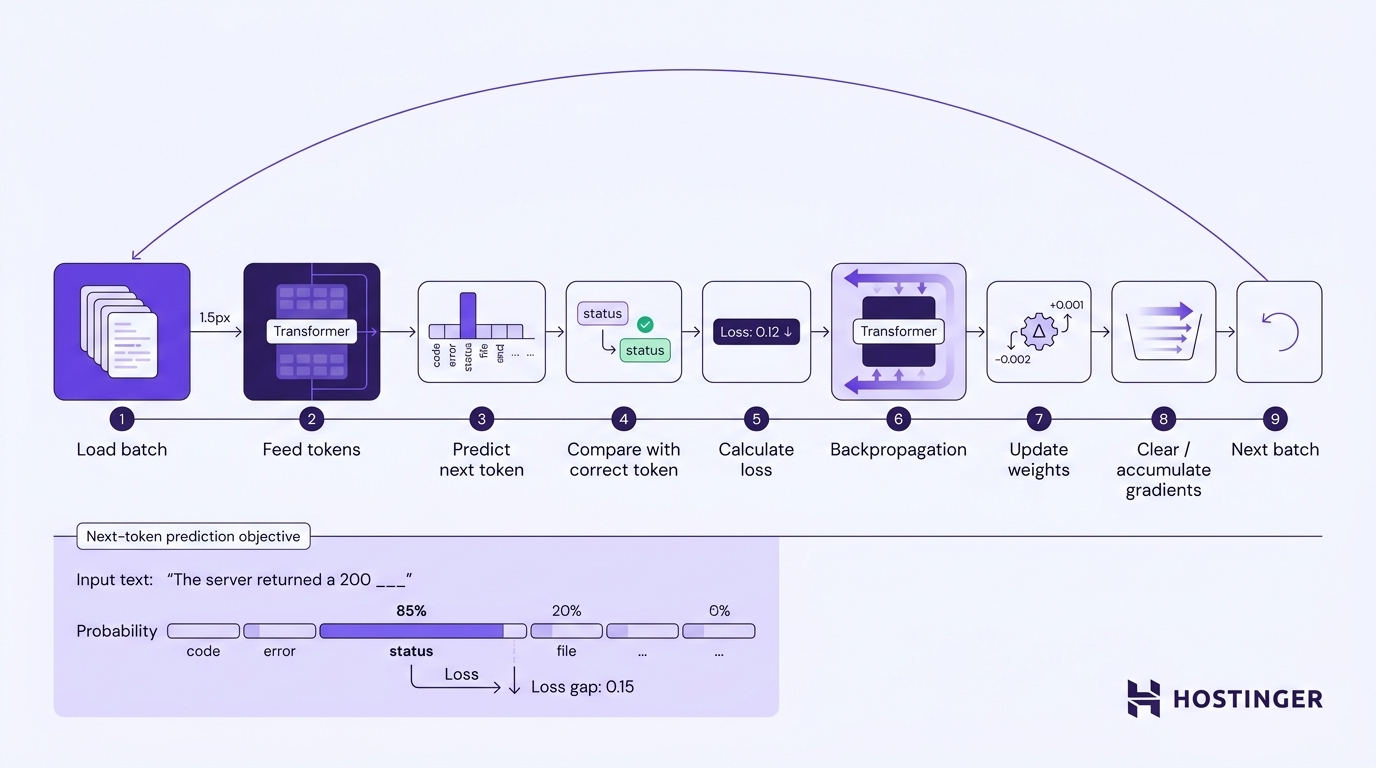
The full loop is driven by a azygous objective: next-token prediction. Suppose the exemplary receives the text:
“The server returned a 200 ___”
The exemplary assigns a probability to each imaginable adjacent token successful its vocabulary. If the correct adjacent token successful the training information is “status”, the nonaccomplishment measures really acold the prediction differs from that expected result.
The optimizer past adjusts the model’s weights truthful that “status” becomes much apt successful akin contexts during early training steps.
Predicting the adjacent token whitethorn look for illustration a elemental objective, but repeating the aforesaid learning process crossed billions of token sequences allows the exemplary to study grammar, vocabulary, actual relationships, programming syntax, reasoning patterns, and galore different statistical regularities without being explicitly programmed pinch those rules.
9. Save checkpoints
Saving checkpoints periodically protects training advancement and makes agelong training runs easier to manage.
Rather than waiting until pretraining finishes, developers prevention checkpoints astatine regular intervals passim the training process.
If training is interrupted by a hardware failure, package error, aliases powerfulness outage, it tin resume from the astir caller checkpoint alternatively of starting over.
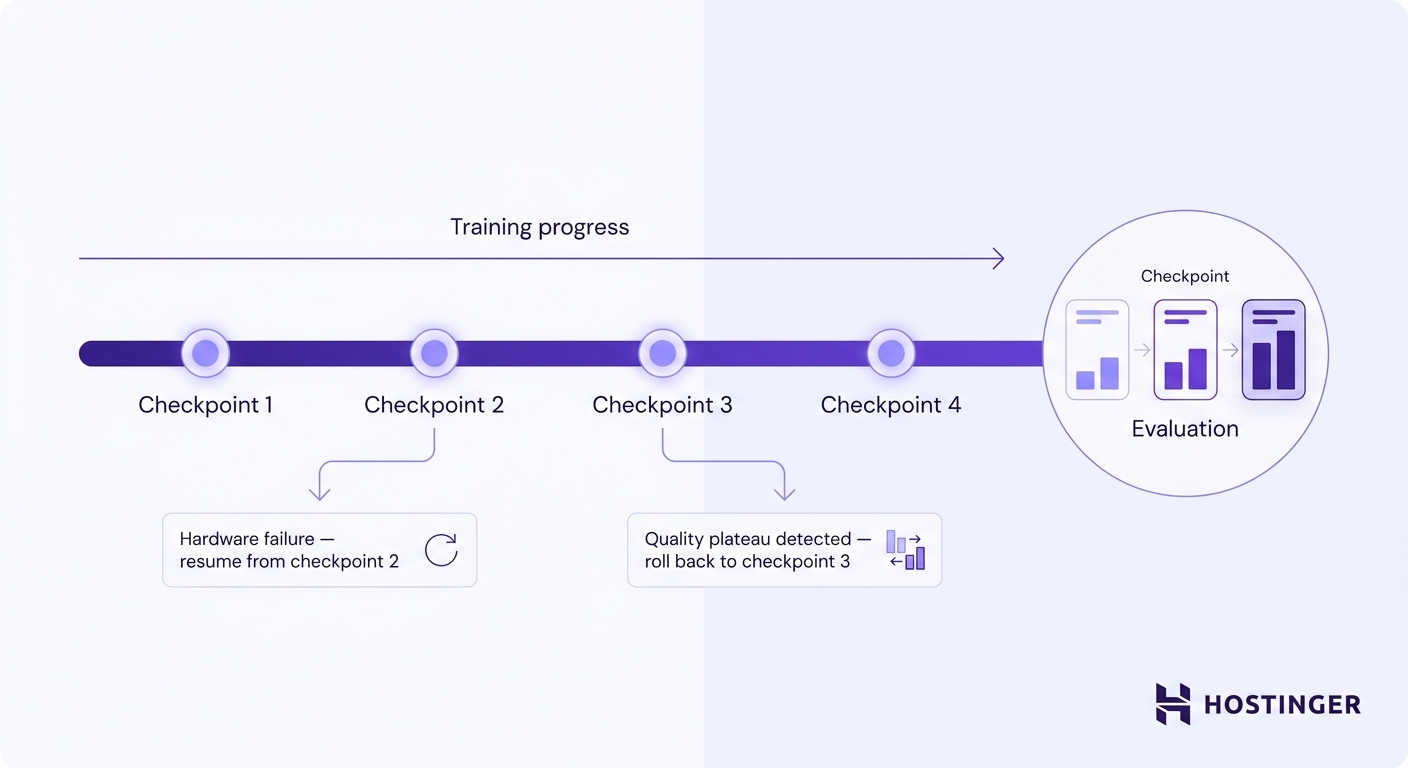
Regular checkpoints besides make it easier to comparison different stages of training. Developers tin measure aggregate checkpoint versions, place erstwhile exemplary value originates to plateau aliases decline, and rotation backmost to an earlier checkpoint if a later type becomes unstable aliases performs worse.
10. Monitor training
Training should beryllium monitored continuously to verify that the exemplary is learning arsenic expected and that the training infrastructure is operating efficiently.
Developers typically way the pursuing metrics passim the training run:
- Training loss – Measures prediction correction connected the training batches. A plateau tin mean the tally is approaching its existent limit, but it tin besides bespeak the learning-rate schedule, information mix, aliases optimization settings.
- Validation loss – Measures capacity connected information the exemplary has not seen during training. If validation nonaccomplishment increases while training nonaccomplishment continues to decrease, the exemplary whitethorn beryllium overfitting.
- Learning rate – Confirms that the learning-rate schedule is progressing arsenic intended passim training.
- Gradient stability – Indicates whether weight updates stay numerically stable. Unstable gradients tin forestall the exemplary from converging aliases origin training to fail.
- GPU utilization – Shows really efficaciously the disposable GPUs are being used. Low utilization whitethorn bespeak bottlenecks successful the training pipeline.
- Throughput – Measures really galore training examples aliases tokens the strategy processes complete time. Unexpected slowdowns often constituent to hardware, storage, aliases data-loading issues.
- Memory usage – Tracks GPU and strategy representation depletion to thief observe representation bottlenecks earlier they interrupt training.
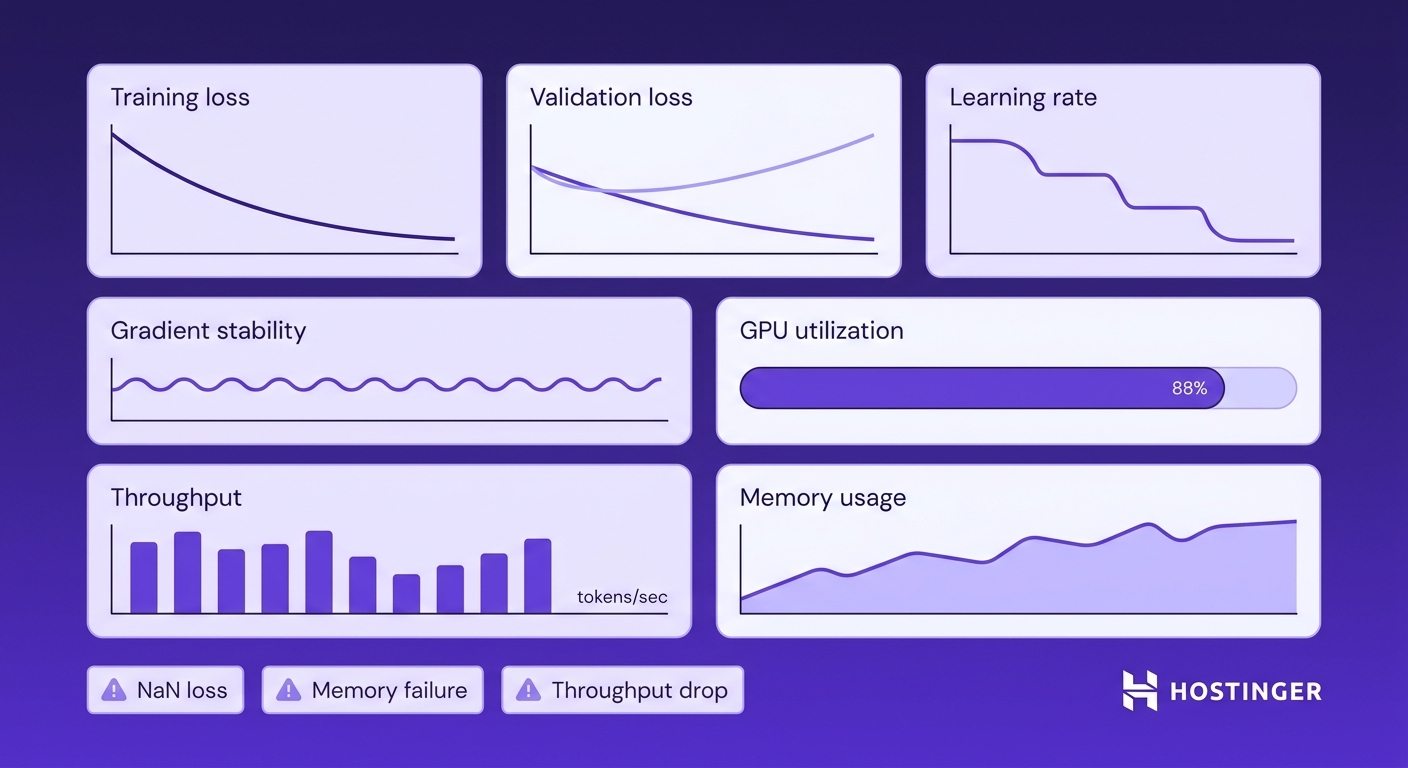
Monitoring these metrics helps place problems early. Common informing signs see NaN (Not a Number) nonaccomplishment values caused by numerical errors, GPU representation failures, and unexpected drops successful throughput.
Detecting these issues early allows developers to set the training configuration earlier the training tally fails aliases produces a lower-quality model.
11. Evaluate the pretrained model
Evaluating the pretrained exemplary determines whether it has learned the connection patterns and capabilities required for its intended use.
A debased training nonaccomplishment unsocial is not enough, because a exemplary tin execute good connected the training information while still producing mediocre results connected caller tasks aliases unseen text.
Evaluation originates pinch held-out datasets that were not utilized during training. Developers measurement language modeling loss to measure really accurately the exemplary predicts unseen text.
Some evaluations besides study perplexity, which measures really good the exemplary predicts the adjacent token connected unseen data. Lower perplexity mostly indicates amended predictive performance.
The information process past expands beyond next-token prediction to measurement really good the exemplary performs real-world tasks.
Depending connected the intended application, evaluations whitethorn include:
- Reasoning tasks to measurement logical problem-solving ability.
- Factuality tests to measure really accurately the exemplary recalls and presents information.
- Coding benchmarks to measure codification generation, completion, and debugging capabilities.
- Language knowing tasks to measurement comprehension, summarization, aliases mobility answering.
- Instruction-following evaluations to find really good the exemplary responds to personification requests.
- Domain-specific tests for fields specified arsenic medicine, law, finance, aliases package engineering.
- Safety evaluations to place harmful, biased, aliases different inappropriate outputs.
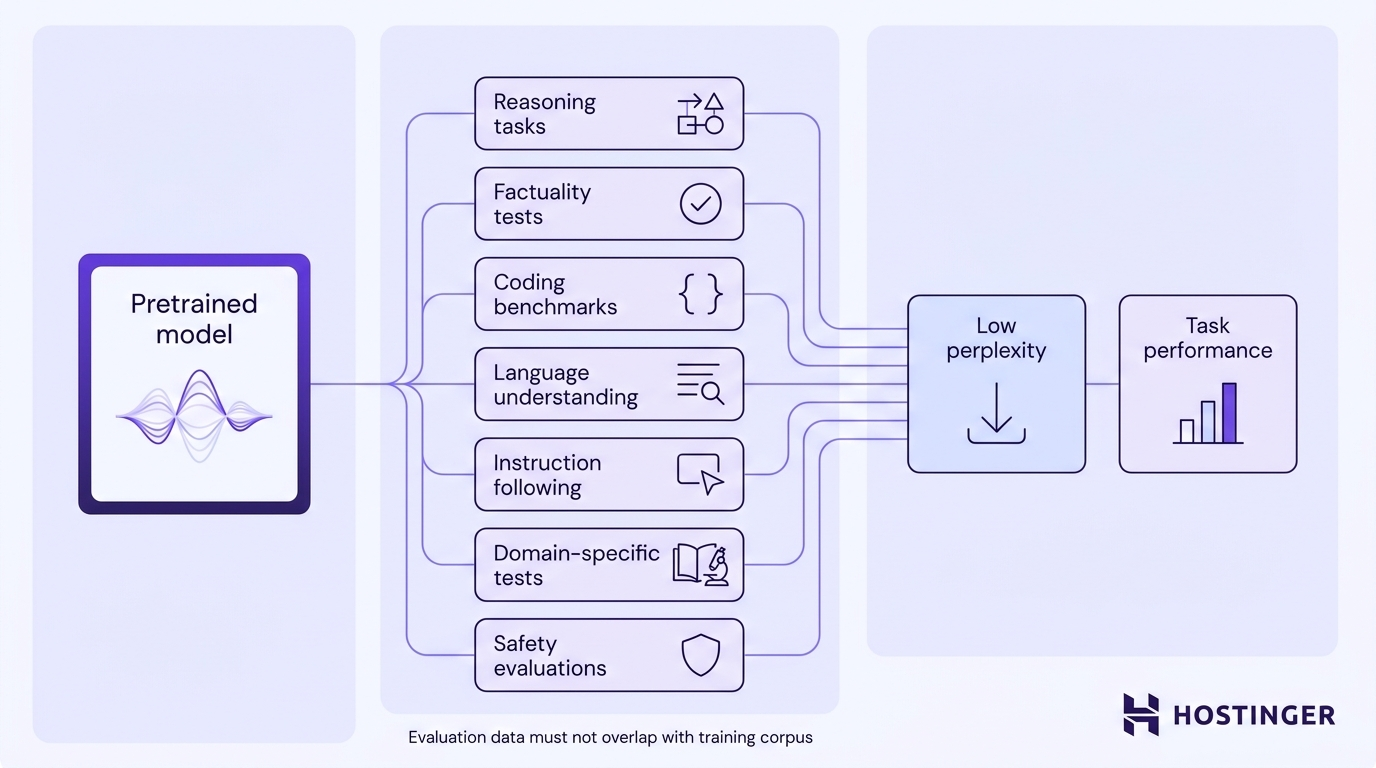
The information strategy should bespeak the model’s intended purpose. A coding assistant, for example, should beryllium evaluated chiefly connected programming tasks, while a aesculapian exemplary requires domain-specific aesculapian evaluations successful summation to wide connection benchmarks.
Finally, information datasets should stay independent of the training corpus. If benchmark questions aliases trial information overlap pinch the training data, the exemplary whitethorn look to execute good simply because it has already seen akin examples during training.
Using unseen information information provides a much reliable measurement of really good the exemplary generalizes to caller tasks and inputs.
Fine-tuning adapts an existing pretrained LLM by continuing training connected a overmuch smaller dataset designed astir the behaviour aliases domain you want the exemplary to learn. Instead of school the exemplary wide connection patterns from scratch, you build connected the knowledge it has already acquired and accommodate it to a circumstantial application.
What happens aft pretraining?
Pretraining teaches an LLM wide connection patterns, but it does not automatically nutrient a adjuvant conversational assistant.
Before a exemplary is deployed, it typically undergoes post-training, a bid of further training and information stages that amended its behavior, reliability, and safety.
A communal first shape is supervised fine-tuning (SFT), wherever the exemplary learns from curated examples of desired inputs and outputs.
For a casual LLM, SFT still uses token-level language-modeling loss: the exemplary predicts target consequence tokens from the preceding context, but the examples are curated to thatch instruction following, conversational behavior, domain responses, aliases required output formats.
Many models past acquisition preference optimization, which teaches them to favour amended responses erstwhile aggregate valid answers are possible.
During this stage, the exemplary compares preferred and less-preferred responses and learns to nutrient behaviour that aligns much intimately pinch quality expectations.
Common approaches see reinforcement learning from quality feedback (RLHF), direct penchant optimization (DPO), and related preference-training methods.
Post-training besides includes extended safety and alignment testing. Developers measure the exemplary for harmful aliases biased outputs, privateness leakage, punctual injection attacks, hallucinations, inappropriate refusal behavior, and capacity successful delicate domains specified arsenic healthcare aliases finance.
Alignment is not a one-time process. Production models proceed to beryllium monitored, tested, and updated arsenic caller risks, usage cases, and onslaught techniques emerge.
How to fine-tune an existing LLM
The wide process resembles pretraining. You’ll still take a model, hole a training dataset, configure the training process, tally a training loop, and measure the results.
The quality is that fine-tuning uses a overmuch smaller dataset, requires acold little computing power, and focuses connected refining an existing exemplary alternatively than creating a caller one.
1. Choose a guidelines model
The first measurement is choosing a pretrained exemplary that matches your fine-tuning goals and disposable hardware.
The correct exemplary will besides dangle connected the resources disposable for training and deployment.
When comparing campaigner models, measure the following:
- License – Check whether the licence permits commercialized use, redistribution, aliases the creation of derivative models. Some unfastened models restrict commercialized deployment aliases require attribution.
- Parameter size – Match the exemplary size to your hardware. A sub-billion aliases 7B-class exemplary is acold easier to accommodate than a 70B-class model, while PEFT, quantization, offloading, and multi-GPU training tin alteration the nonstop representation requirement.
- Context length – Choose a discourse model that matches your workload. Customer support assistants whitethorn request only a fewer 1000 tokens, whereas archive study aliases codification assistants often use from overmuch longer contexts.
- Supported languages – Verify that the exemplary was pretrained connected the languages you scheme to use. Fine-tuning tin amended a target connection aliases domain, but it whitethorn not afloat compensate for anemic connection sum successful pretraining.
- Instruction tuning – Decide whether you request a guidelines exemplary aliases an instruction-tuned model. Instruction-tuned models are a amended starting constituent for chatbots and assistants, while guidelines models are often preferred for continued pretraining aliases highly specialized fine-tuning.
- Hardware requirements – Estimate the GPU representation needed for fine-tuning earlier selecting a model. Choosing a exemplary that exceeds your disposable VRAM whitethorn require techniques specified arsenic LoRA, quantization, aliases distributed training.
- Model format – Confirm that the exemplary is disposable successful a format supported by your training and deployment framework. Hugging Face Transformer checkpoints and Safetensors are communal for fine-tuning, while formats specified arsenic GGUF and ONNX are commonly utilized for optimized conclusion aliases export workflows.
- Ecosystem support – Look for models pinch progressive maintenance, elaborate documentation, information results, and organization tooling. A mature ecosystem makes fine-tuning, benchmarking, and deployment overmuch easier.
Start pinch the exemplary card, license, task-specific evaluations, and caller benchmark results that lucifer your usage case. Re-run the astir important evaluations yourself earlier committing to a guidelines model.
Smaller models are mostly easier and little costly to fine-tune because they require little GPU memory, storage, and computation.
They are besides faster to deploy and tally during inference. Larger models whitethorn execute amended connected immoderate analyzable tasks, but that use is workload-dependent and comes pinch higher memory, compute, and latency costs.
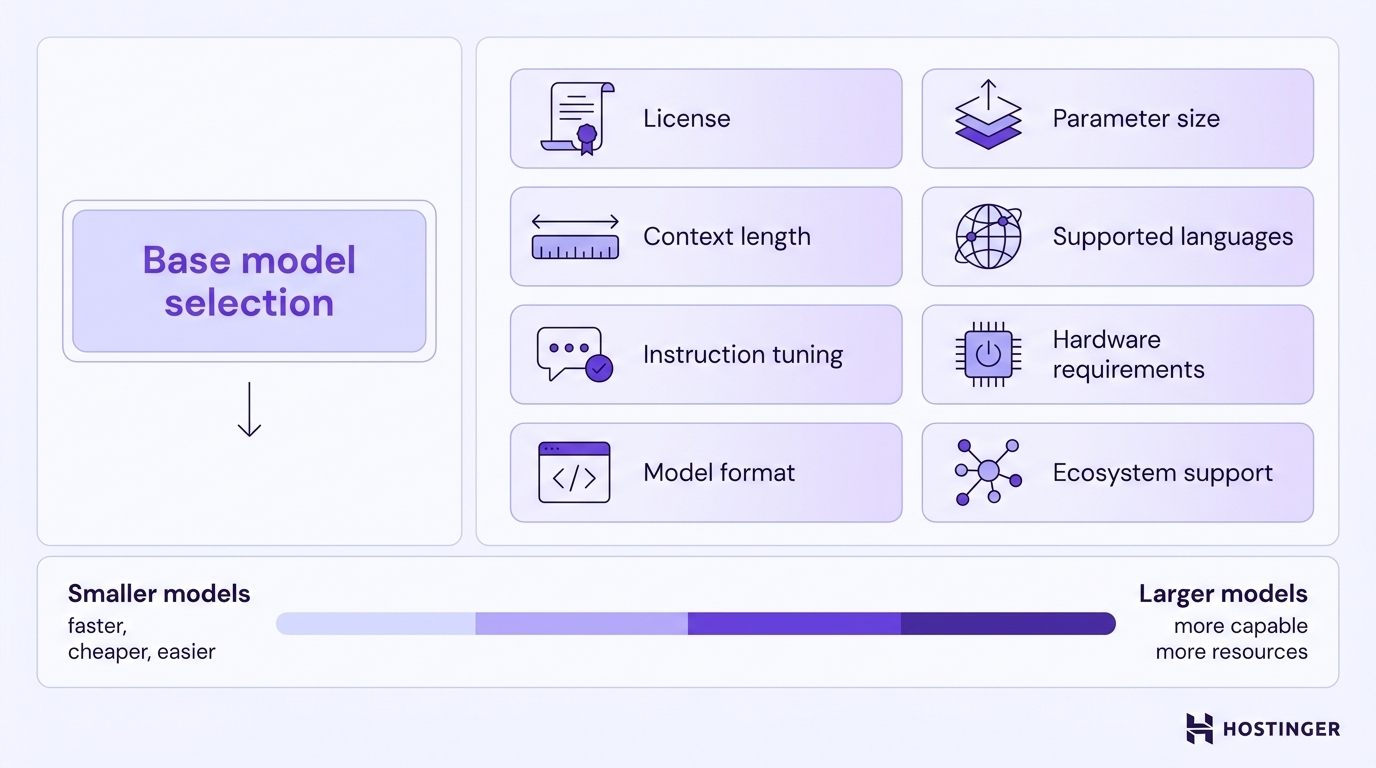
For galore applications, starting pinch the smallest exemplary that satisfies your capacity requirements is the astir applicable approach.
2. Prepare a fine-tuning dataset
The adjacent measurement is preparing a dataset that teaches the exemplary the behaviour you want it to learn. The format of the dataset depends connected your objective.
If you want the exemplary to follow instructions, create pairs of prompts and expected responses that show the desired behavior.
For example:
Input: Summarize this support ticket.
Output: The customer cannot entree their relationship aft resetting the password. Escalate the rumor to the authentication team.
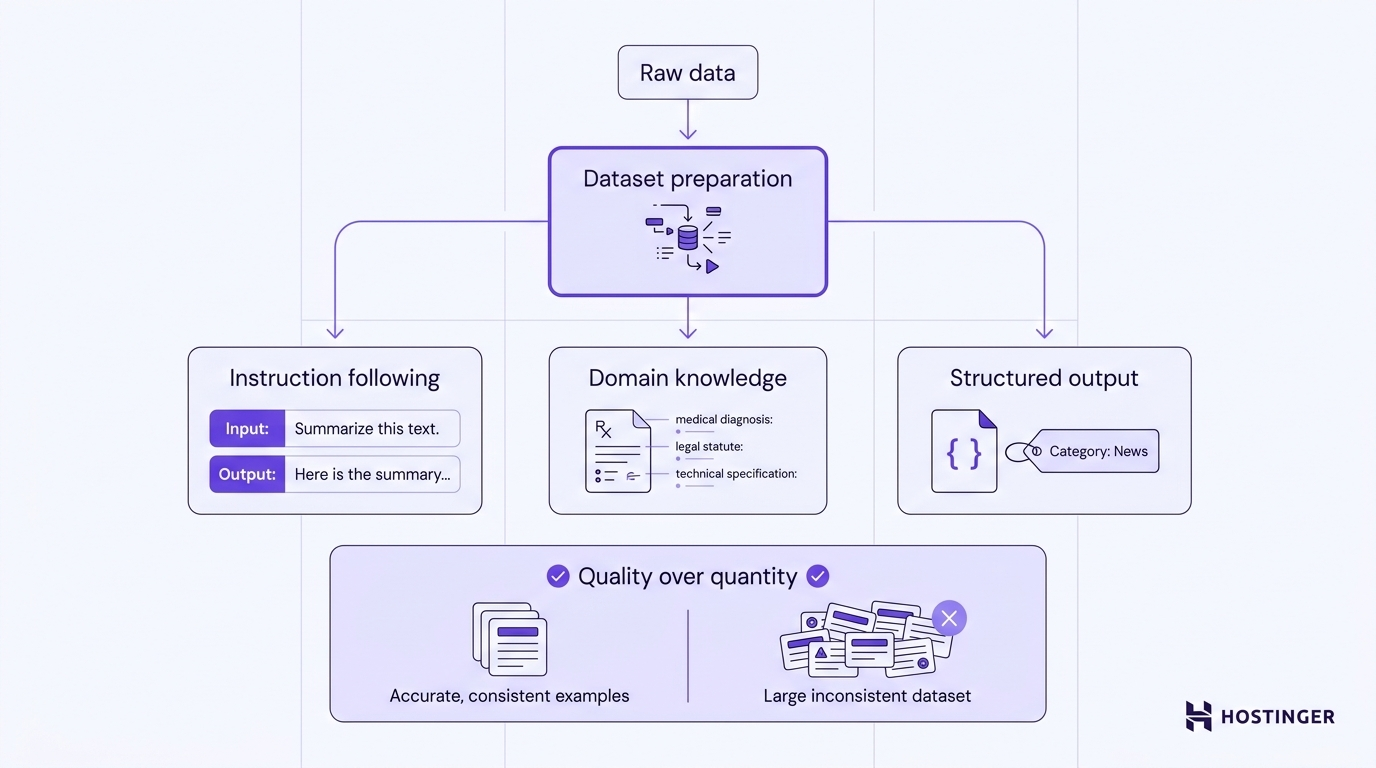
If you want deeper adjustment to a specialized domain, separate betwixt continued pretraining and supervised fine-tuning. Continued pretraining uses high-quality domain matter to accommodate the model’s connection distribution, while supervised fine-tuning uses curated input-output examples to thatch task behavior.
Medical, legal, financial, aliases package archiving tin beryllium useful for continued pretraining aliases for constructing supervised examples, but fine-tuning should not beryllium treated arsenic a guaranteed measurement to inject meticulous domain knowledge. Domain accuracy still needs dedicated evaluation.
If you want the exemplary to produce system aliases accordant outputs, see examples that show the nonstop behaviour you expect.
The dataset mightiness thatch the exemplary to:
- Generate responses successful a accordant penning style.
- Return information successful a circumstantial JSON format.
- Predict predefined classification labels.
- Produce requests successful a required tool-use format.
- Use organization-specific terminology and naming conventions.
3. Choose afloat fine-tuning aliases parameter-efficient fine-tuning
For astir projects, parameter-efficient fine-tuning (PEFT) is the applicable prime because it requires overmuch little GPU representation and retention than updating the full model.
Full fine-tuning is usually reserved for situations wherever maximum elasticity justifies the further computational cost.
Full fine-tuning updates each weight successful the pretrained model. This attack gives you complete power complete really the exemplary adapts to the caller task aliases domain, making it suitable erstwhile you request to make important changes to the model’s behavior.
The trade-off is that training requires importantly much GPU memory, produces larger exemplary checkpoints, and increases the consequence of degrading the capabilities the exemplary already learned during pretraining.
Parameter-efficient fine-tuning (PEFT) keeps astir of the pretrained exemplary unchanged and updates only a mini subset of parameters aliases adds lightweight trainable components called adapters.
Because acold less parameters are trained, PEFT requires little memory, generates overmuch smaller checkpoints, and is often the preferred attack erstwhile moving pinch constricted hardware.
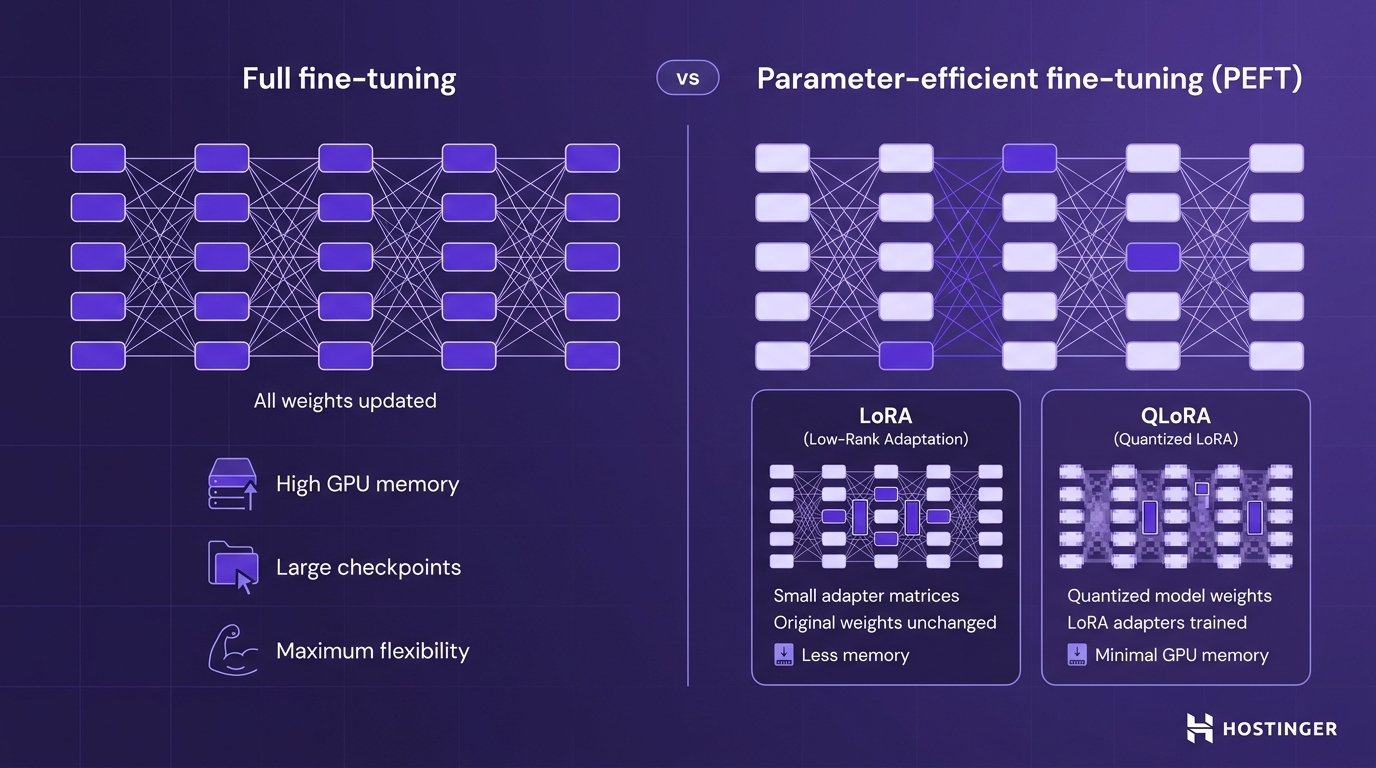
A communal PEFT method is LoRA (Low-Rank Adaptation). Instead of modifying each exemplary weight, LoRA trains mini further matrices that set the model’s behaviour while leaving the original weights unchanged.
This tin trim some representation usage and retention requirements while retaining beardown task capacity successful galore settings, but the consequence still needs to beryllium benchmarked against afloat fine-tuning aliases the guidelines exemplary for the intended task.
If GPU representation is peculiarly limited, QLoRA (Quantized Low-Rank Adaptation) offers an moreover much businesslike alternative.
QLoRA combines LoRA pinch quantization, storing the pretrained exemplary successful a lower-precision format while training only the LoRA adapters.
This importantly reduces representation requirements, making it imaginable to fine-tune larger models connected much humble hardware.
The Hugging Face PEFT room provides ready-to-use implementations of LoRA and QLoRA that merge straight pinch Transformers, truthful you tin adhd adapter-based fine-tuning without implementing the method from scratch.
4. Fine-tune and measure the model
Once the dataset and training configuration are ready, you tin commencement the fine-tuning process.
The exemplary still follows the aforesaid training loop utilized during pretraining: it processes a batch of inputs, performs a guardant pass, computes the loss, backpropagates, and updates either the exemplary weights aliases the trainable adapters.
The quality is that fine-tuning uses a overmuch smaller dataset and focuses connected improving a circumstantial capacity alternatively than learning wide connection patterns.
As training progresses, show some task capacity and the model’s wide behavior. Watch for:
- Overfitting – The exemplary memorizes the fine-tuning dataset alternatively of learning patterns that generalize to caller examples.
- Catastrophic forgetting – The exemplary loses capabilities it learned during pretraining while adapting to the caller task.
- Formatting consistency – Verify that responses travel the required structure, specified arsenic JSON schemas, classification labels, aliases tool-call formats.
- Task accuracy – Measure really good the exemplary performs the circumstantial task it was fine-tuned for.
- Regression connected wide capabilities – Check that improvements connected the target task do not trim capacity connected broader language, reasoning, aliases coding tasks.
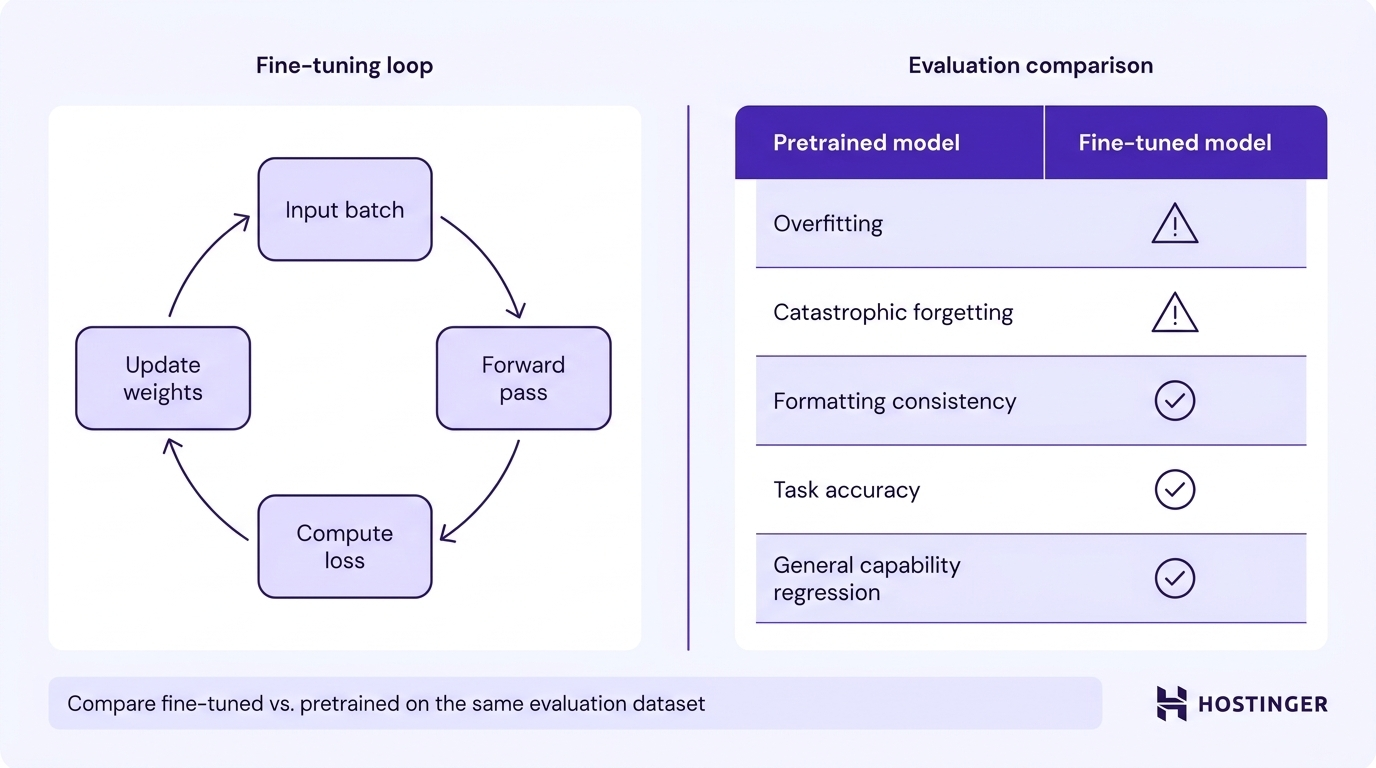
Don’t measure the fine-tuned exemplary successful isolation. Compare it pinch the original pretrained exemplary utilizing the aforesaid information dataset and metrics.
If the fine-tuned exemplary doesn’t nutrient a measurable betterment connected the target task, aliases if the betterment comes astatine the costs of importantly worse wide performance, you whitethorn request to revise the dataset, set the hyperparameters, aliases take a different fine-tuning approach.
Fine-tune an open-source LLM: Step-by-step example
The illustration beneath uses Python, PyTorch, Hugging Face Transformers, and LoRA to accommodate a mini open-source exemplary connected a mini instruction dataset.
Although the nonstop exemplary and dataset whitethorn disagree depending connected readiness and licensing, the wide workflow remains the same: load a pretrained model, hole the dataset, configure LoRA, train the adapter, and comparison the results.
1. Set up the environment
Before you tin fine-tune an LLM, you request a Python situation pinch the libraries required to load the model, hole the dataset, configure LoRA, and tally the training process.
A emblematic workflow uses:
- PyTorch to tally the training process and execute tensor computations connected the CPU aliases GPU.
- Transformers to download pretrained models and tokenizers from the Hugging Face Hub.
- Datasets to load, preprocess, and divided the fine-tuning dataset.
- PEFT to configure parameter-efficient fine-tuning methods specified arsenic LoRA.
- Accelerate to simplify training connected 1 aliases much GPUs.
If you person entree to a compatible GPU, PyTorch and Accelerate tin usage it to importantly trim training time.
CPU fine-tuning is technically imaginable for very mini aliases artifact workloads, but it is usually impractical for modern LLM fine-tuning because training tin beryllium dramatically slower than connected a compatible GPU.
For the champion experience, usage a instrumentality pinch a GPU that has capable representation to clasp the exemplary and the LoRA adapters during training.
2. Load the exemplary and tokenizer
The adjacent measurement is loading the pretrained exemplary and its tokenizer. The tokenizer must lucifer the exemplary because some were trained together and usage the aforesaid vocabulary.
Replace the exemplary identifier beneath pinch immoderate mini open-source exemplary that supports fine-tuning and is compatible pinch your hardware.
from transformers import AutoModelForCausalLM, AutoTokenizer model_name = "your-model-name" tokenizer = AutoTokenizer.from_pretrained(model_name) model = AutoModelForCausalLM.from_pretrained(model_name)
After loading the model, it’s bully believe to verify that some the exemplary and tokenizer were initialized correctly earlier moving connected to dataset preparation.
At this stage, the exemplary is fresh for inference, but it has not yet been adapted to your circumstantial task aliases domain.
3. Prepare the training dataset
Before training tin begin, the dataset must beryllium converted into the format expected by the model.
Most instruction-tuning datasets dwell of paired prompts and responses, wherever each illustration demonstrates the behaviour the exemplary should learn.
The illustration beneath formats each training illustration arsenic a elemental instruction followed by its expected response, past converts the matter into tokens.
from datasets import load_dataset dataset = load_dataset("your-dataset-name") def format_example(example): return { "text": ( f"Instruction: {example['instruction']}\n" f"Response: {example['output']}" ) } dataset = dataset.map(format_example)
The formatted matter must past beryllium tokenized truthful the exemplary tin process it. During tokenization, agelong examples are truncated to the model’s maximum discourse length, while shorter examples are padded wherever basal truthful aggregate examples tin beryllium processed together successful the aforesaid batch.
Finally, divided the dataset into training and validation sets. The training group updates the exemplary during fine-tuning, while the validation group helps measurement capacity connected unseen examples and observe problems specified arsenic overfitting earlier training finishes.
4. Configure LoRA
LoRA fine-tunes a exemplary by adding a mini group of trainable parameters while keeping the original exemplary weights frozen.
Because only those further parameters are updated, LoRA requires acold little GPU representation and produces overmuch smaller checkpoints than afloat fine-tuning.
A basal configuration looks for illustration this:
from peft import LoraConfig, get_peft_model lora_config = LoraConfig( r=8, lora_alpha=16, lora_dropout=0.05, target_modules=["q_proj", "v_proj"], # varies by exemplary architecture task_type="CAUSAL_LM" ) model = get_peft_model(model, lora_config)
The nonstop target_modules values dangle connected the guidelines model. They place which Transformer projection layers person LoRA adapters, truthful you should cheque the exemplary architecture aliases its PEFT archiving earlier training.
Some models usage names specified arsenic q_proj and v_proj, while others expose different module names.
The different settings power really the adapters are trained. r sets the rank of the LoRA matrices and affects some adjustment capacity and representation use. lora_alpha scales the LoRA update, while lora_dropout applies dropout to the adapter way during training.
5. Run the training job
Once the model, dataset, and LoRA configuration are ready, you tin commencement the fine-tuning process.
The training configuration defines really agelong the exemplary trains, really galore examples it processes astatine a time, wherever checkpoints are saved, and really often advancement is evaluated.
A minimal configuration mightiness look for illustration this:
from transformers import TrainingArguments, Trainer training_args = TrainingArguments( output_dir="checkpoints", learning_rate=2e-4, per_device_train_batch_size=4, num_train_epochs=3, evaluation_strategy="epoch", save_strategy="epoch" ) trainer = Trainer( model=model, args=training_args, train_dataset=train_dataset, eval_dataset=validation_dataset, ) trainer.train()
During a patient run, training nonaccomplishment will often inclination downward, but it tin up and down betwixt steps. Compare training and validation behaviour alternatively than treating each alteration arsenic impervious that the exemplary is improving.
The training process will besides prevention checkpoints to the output directory astatine the configured intervals, allowing you to resume training aliases comparison different stages later.
Keep an oculus connected GPU representation usage passim training. If representation becomes a limiting factor, you tin trim the batch size, shorten the series length, aliases usage techniques specified arsenic gradient accumulation to little representation requirements without changing the dataset.
6. Compare the results
Fine-tuning is only successful if it improves the behaviour you intended to change. The easiest measurement to verify this is to tally the aforesaid punctual done some the original and fine-tuned models, past comparison the responses.
prompt = "Summarize the pursuing support ticket..." base_response = generate(base_model, prompt) fine_tuned_response = generate(model, prompt) print("Base model:") print(base_response) print("\nFine-tuned model:") print(fine_tuned_response)
Don’t trust connected a azygous illustration erstwhile evaluating the results. Test the exemplary connected aggregate prompts that were not included successful the fine-tuning dataset to verify that it has learned the desired behaviour alternatively than memorized the training examples.
If possible, comparison the 2 models utilizing the aforesaid information metrics and benchmark dataset.
A mini tutorial dataset is useful for demonstrating the fine-tuning workflow, but it is not capable to nutrient a production-ready model.
High-quality fine-tuning requires a typical dataset, observant evaluation, and aggregate rounds of testing to verify that the exemplary generalizes good beyond the examples it was trained on.
7. Save the fine-tuned adapter
After verifying that fine-tuning improved the model’s behavior, prevention the LoRA adapter truthful it tin beryllium reused later without retraining.
model.save_pretrained("fine-tuned-adapter") tokenizer.save_pretrained("fine-tuned-adapter")
The saved adapter contains the further LoRA parameters learned during fine-tuning, not a complete transcript of the guidelines model.
To usage it later, load the original guidelines exemplary and connect the saved adapter earlier moving inference.
Training from scratch vs. fine-tuning: Which attack should you choose?
Most developers should fine-tune an existing open-source LLM alternatively than train a caller instauration exemplary from scratch, unless they specifically request power complete the architecture, tokenizer, aliases pretraining corpus and person the resources to support it.
Choose fine-tuning if you:
- Have recovered a guidelines exemplary that already understands the language, domain, aliases type of contented you need.
- Want the exemplary to travel a circumstantial penning style, consequence format, aliases group of instructions.
- Need accordant outputs, specified arsenic JSON responses, classification labels, aliases instrumentality calls.
- Have a comparatively small, high-quality dataset focused connected a circumstantial task aliases domain.
- Want to support infrastructure costs debased and activity wrong constricted GPU resources.
- Expect to refine the exemplary often arsenic your information aliases requirements change.
Training a caller instauration exemplary from scratch is worthy considering only if you:
- Cannot find a suitable guidelines exemplary for your usage case.
- Need complete power complete the exemplary architecture, tokenizer, aliases pretraining process.
- Have a training corpus that differs fundamentally from the information utilized to pretrain existing models.
- Must meet licensing, regulatory, aliases data-provenance requirements that forestall you from utilizing an existing model.
- Have entree to the ample datasets, GPU infrastructure, engineering expertise, and fund required to train a instauration model.
Training from scratch and fine-tuning aren’t the only options. If a suitable pretrained exemplary already meets your requirements, you whitethorn not request further training astatine all.
In galore cases, you tin simply set up an open-source exemplary pinch Ollama and commencement utilizing it for conclusion aliases exertion development.
How to deploy and tally a trained LLM
After training aliases fine-tuning, the exemplary must beryllium packaged and served successful an situation wherever applications tin nonstop conclusion requests to it.
Deployment prepares the trained exemplary for accumulation by optimizing it for inference, loading it into a serving system, and making it accessible to users aliases different applications.
The deployment process typically follows these steps:
- Select the last checkpoint that achieved the champion information results.
- Merge LoRA adapters, if required, truthful the exemplary tin beryllium deployed arsenic a azygous group of weights.
- Convert aliases quantize the model to trim representation usage aliases amended conclusion capacity wherever appropriate.
- Transfer the exemplary files to the target serving environment.
- Load the model into an conclusion motor tin of processing prompts and generating responses.
- Expose an API aliases exertion interface truthful applications tin nonstop conclusion requests and person outputs.
- Monitor the deployment by search latency, representation usage, correction rates, and assets utilization.
One communal deployment optimization is quantization, which reduces the numerical precision utilized to shop the model’s weights.
Lower-precision weights trim exemplary representation requirements and tin amended conclusion throughput connected compatible hardware, but the quality-speed trade-offs alteration by model, quantization method, and workload.
Important
Aggressive quantization (e.g., 4-bit) tin degrade output value connected tasks requiring precise reasoning aliases actual recall. Always benchmark your quantized exemplary against the original earlier deploying it successful production.
Run LLMs pinch Ollama
If you’re deploying an open-source LLM locally aliases connected your ain server, Ollama provides a straightforward measurement to negociate and service compatible models.
Ollama is an open-source instrumentality for downloading, managing, and moving LLMs locally. It packages compatible models pinch an conclusion engine, making it easier to service them without manually configuring the underlying software.
Once you install Ollama, you tin download compatible models from the Ollama library, shop them locally, and service them for inference.
Using Ollama to tally LLMs locally typically requires only a compatible exemplary and a fewer commands to commencement serving it.
After the exemplary is running, you tin proceed working pinch Ollama from the bid line to download further models, negociate your section exemplary library, and commencement aliases extremity conclusion sessions.
To support your exemplary disposable without manually restarting it, configure Ollama arsenic a systemd work connected Linux. This ensures the conclusion server starts automatically connected footwear and recovers from unexpected restarts without manual intervention.
Choose a deployment environment
Training infrastructure and serving infrastructure are not the aforesaid thing. The last deployment determination is wherever the trained exemplary will tally for inference, and that prime depends connected exemplary size, quantization, latency targets, concurrency, and whether you request persistent self-hosting.
Large-scale pretraining relies connected specialized GPU clusters that supply the compute and representation needed to train billions of exemplary parameters.
Once training is complete, however, serving a smaller aliases quantized exemplary typically requires acold less resources.
An LLM VPS is well-suited for workloads that support exemplary improvement and deployment. You tin usage it to:
- Experiment pinch smaller open-source models.
- Run information preprocessing aliases information scripts.
- Store and negociate datasets, checkpoints, and training artifacts.
- Host Ollama and service compatible models.
- Expose an conclusion API for your applications.
- Run supporting services specified arsenic web applications, databases, aliases vector stores alongside the model.
Hostinger LLM VPS Hosting provides a persistent VPS situation for self-hosted AI exemplary deployment and supporting applications.
You power the operating strategy and package stack, and Hostinger offers an Ubuntu 24.04 pinch the Ollama template that includes Ollama, Llama 3, and Open WebUl for faster setup. You tin past big compatible models and link them to your ain applications aliases APIs.
Allocated VPS CPU, RAM, storage, and networking resources besides supply a unchangeable situation for conclusion endpoints and supporting services specified arsenic web applications, databases, aliases vector stores.
An LLM VPS should not beryllium confused pinch a large-scale training cluster. Training a instauration exemplary from scratch still requires specialized GPU infrastructure, whereas deploying and serving a suitably sized aliases quantized exemplary tin often beryllium done connected acold much humble hardware.
All of the tutorial contented connected this website is taxable to Hostinger's rigorous editorial standards and values.

The author
Ksenija Drobac Ristovic
Ksenija is simply a integer trading enthusiast pinch extended expertise successful contented creation and website optimization. Specializing successful WordPress, she enjoys penning astir the platform’s nuances, from creation to functionality, and sharing her insights pinch others. When she’s not perfecting her trade, you’ll find her connected the section hoops tribunal aliases astatine location enjoying a crime story. Follow her connected LinkedIn.