

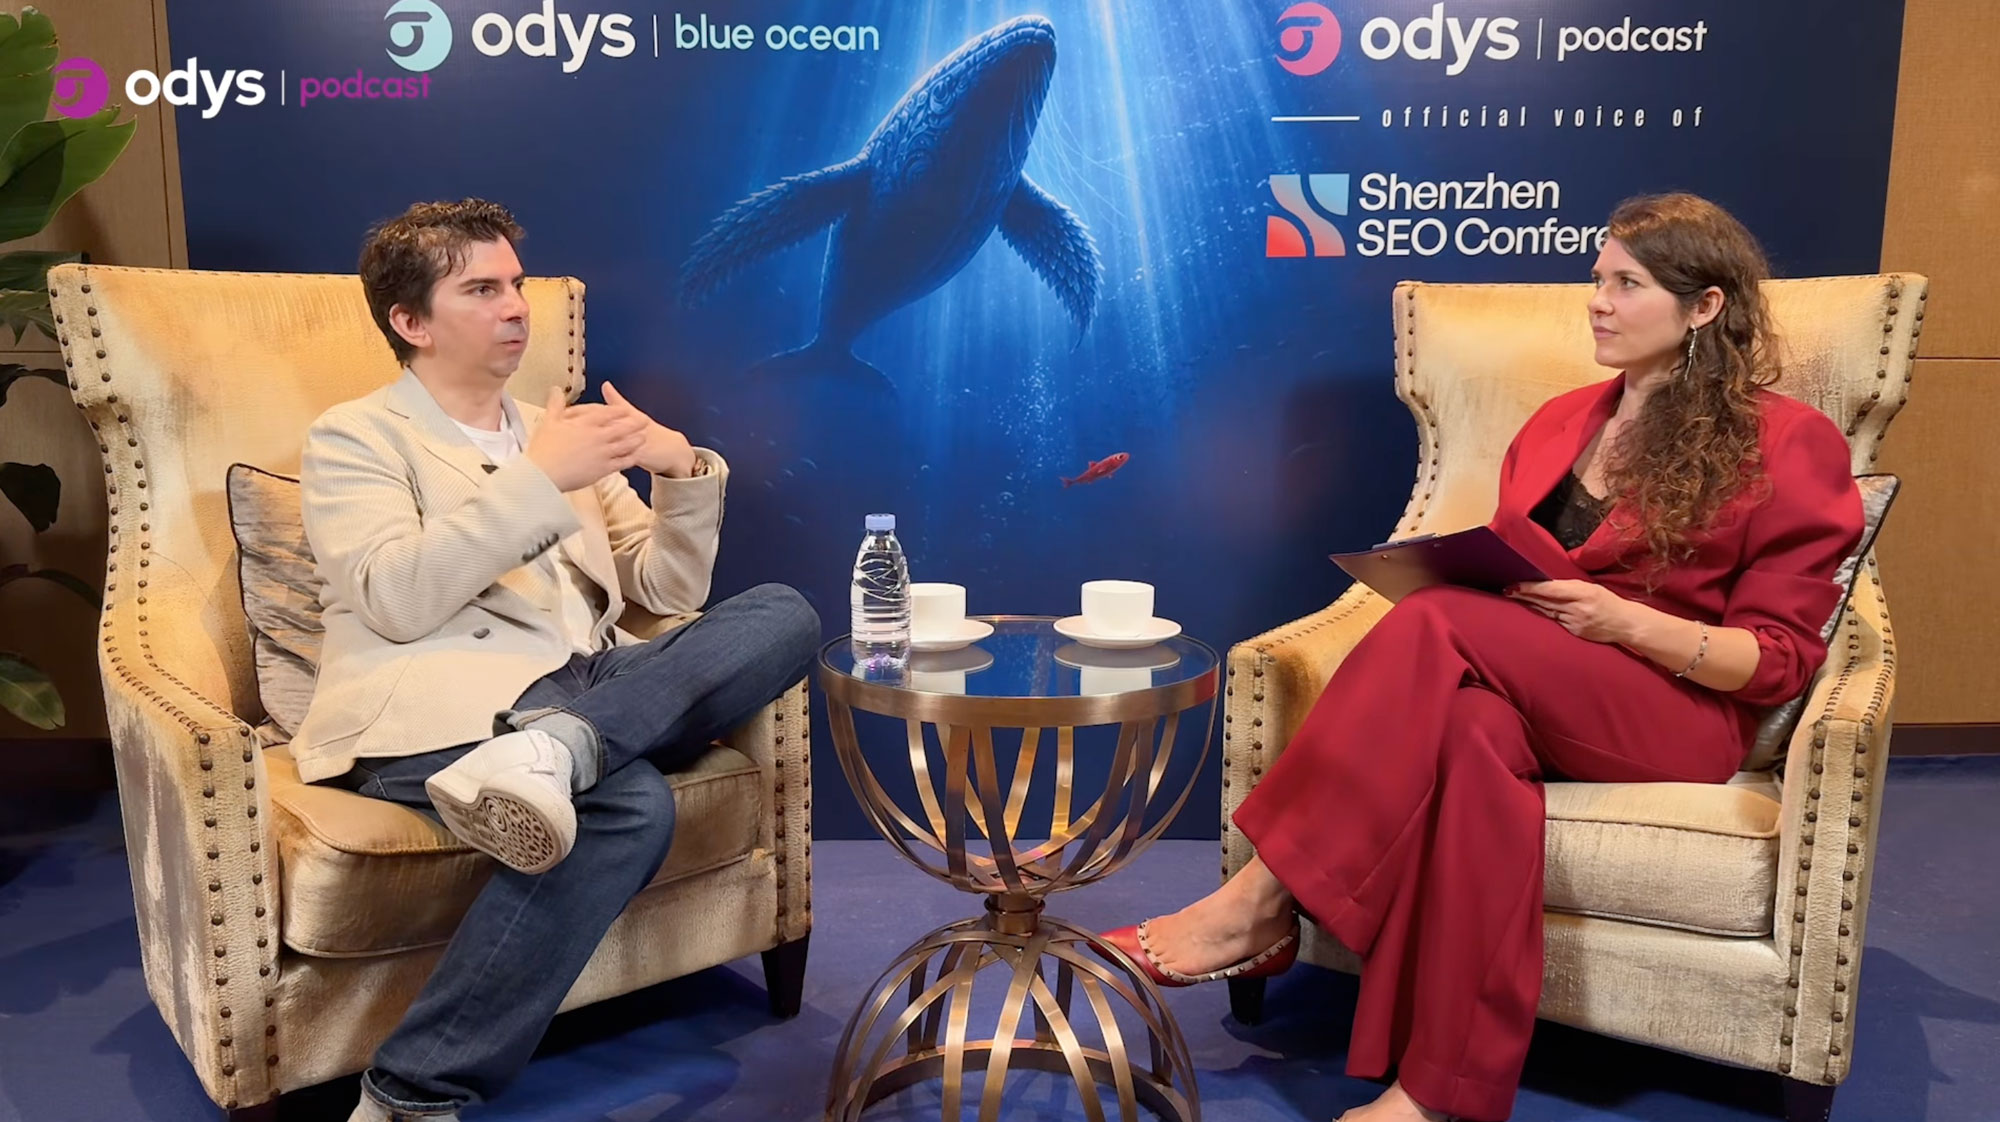
Gary Illyes from Google was lately interviewed by Aneta Samkoff, presenter of the Odys Podcast. The topic was all concerning bots and crawlers and they covered a lot of ground. Gary stated bot impersonation is additional of a issue now since of AI. Bot impersonation is whenever rogue bots feign to be person they are not, akin pretending to be Googlebot.
Gary said, "I think it is AI," for the logic why bot impersonation has rotate into specified a big matter these days. He said, "so basically additional and additional companies are looking for tokens for training their own models, for example, and that needs content. And the idea is that basically the net is a big ranch anywhere you can fair go out and crop any you need. And firewalls and CDNs in broad got improved and improved identifying these crawlers but they are not perfect. So they motionless let through several traffic that they meant to halt and fair knowing who is crawling you basically enables you to create the decision for yourself concerning who should admission your location and who should not.
The logic I think folks do bot impersonation is so that if you run a smaller AI motor or you desire to scrape a site, you can say you are Googlebot and they volition let you in. Otherwise, you power be blocked. Of course, there are additional ways to validate if the useragent is Googlebot, that it is really Googlebot, specified as by reverse DNS verification and IP addresses.
Here is the video:
Here are several of the key points in this video:
- Anyone can impersonate Googlebot in concerning 30 seconds: Changing a crawler's user-agent header is extremely easy. Illyes says he has set up online honeypots that diagram crawlers and established requests claiming to be Googlebot coming from IP addresses unrelated to Google. Website owners should not rely a Googlebot user-agent alone. They should verify the IP location and reverse DNS information.
- AI has made bot impersonation a bigger problem: Gary Illyes attributes the expanding involvement to companies harvesting net satisfied to train AI models. Although firewalls and CDNs have improved at detecting counterfeit crawlers, they do not capture everything. Identifying who is crawling a website helps publishers decide which traffic to allow.
- Fake crawlers can overwhelm websites and obtain them offline: Google has spent years tuning its crawling infrastructure to evade exhausting website resources. Other crawlers may not have the identical safeguards. An improperly configured bot can often petition URLs, consume bandwidth and server resources, and forestall lawful visitors from accessing a site. Illyes says much of today's damage may outcome from ignorance or mediocre implementation fairly than deliberate attacks.
- robots.txt is not a safety mechanism: Gary Illyes describes robots.txt as a recommendation fairly than an enforceable restriction. Legitimate crawlers mostly regard it, but bots can disregard it. Website owners who need to obstacle unwanted traffic should use network-level protections, specified as a web use firewall (WAF).
- Google already separates hunt crawling from certain AI uses: Website owners can authorize Googlebot to crawl pages for Search during using the Google-Extended robots.txt token to restrict eligible uses of satisfied for training or improving certain Google AI models and services. Illyes notes that Apple has a akin Applebot-Extended token. He expects admission controls for distinct types of automated clients could rotate into additional granular.
- Cryptographic signatures could create bot verification additional reliable: Gary Illyes discusses Web Bot Auth, an attempt involving cryptographically signed HTTP requests. Rather than relying solely on IP addresses or user-agent strings, a website could verify a signature against a community key to inspect whether a petition genuinely comes from the claimed organization. This could simplify authentication as IP addresses rotate into additional difficult and costly to manage.
- Bot position scores are a imaginable forthcoming development: Gary Illyes says he is exploring the idea (he plant alongside the robots.txt folks) of a position scheme for crawlers, although it remains an early-stage idea. Such a scheme power total feedback from websites and safety providers concerning whether bots behave responsibly. He cautions that a scheme controlled by one business could current bias.
- Most small websites do not need to concern concerning bots immediately: His direction is to decide whether bot traffic is really causing a issue before investing in protections. For sites that need help, a CDN alongside bot-management capabilities can be a applicable starting point. Hosted platforms specified as Shopify already provision protections. Larger or additional famous sites may eventually need additional advanced controls.
Here are several steps you can obtain to defend yourself from rogue bots:
- Verify Googlebot properly: Check Google's published crawler IP ranges and reverse DNS, fairly than trusting the user-agent cord alone.
- Monitor server logs: Look for doubtful crawling patterns, unexpected IP addresses and unusually common requests.
- Use a CDN or WAF: Apply network-level protections whenever unwanted bots endanger location achievement or security.
- Configure robots.txt: Specify which compliant crawlers may admission content, during recognizing that the rules cannot power malicious bots to comply.
- Separate hunt admission from AI access: Where supported, use the suitable crawler-specific directives to province your preferences concerning indexing and AI-related uses of content.
For additional details, see the What is Googlebot and how to verify Googlebot requests assistance documentation.
Forum conversation at X.






