Disclaimer: The views expressed current are my own and do not portray those of any current or erstwhile director or affiliated organization.
On September 17th, I quote tweeted Trail of Bits’s blog article titled “1Password's AI patching benchmark is misleading,” which additionally referenced Davi Ottenheimer’s “Disinformation Pushed by 1Password: Their AI Patching Report is False.” Both criticized “Frontier Models’ Vulnerability Patches are Often F.L.A.W.E.D” (henceforth referred to as “FLAWED”) from 1Password's Off‑by‑1 Labs.
I saw FLAWED whenever it was released and discussed it alongside another researchers; we classified it as slop and moved on. What I had not realized at the period was how far 1Password’s allocation had carried it: into news safety and guardian roadmaps. Watching this activity obscure additional rigorous investigation from less-resourced groups compelled me to article on Twitter, and the responses to that compelled me to compose this blog post.
The first thread
What follows is the thread, including two follow-up replies, reproduced verbatim.
- There are glaring issues in this document beyond the evaluation problems raised by Davi and ToB, including ones that create me inquiry the proportion of individual to AI aid here, but a few are so egregious we should regard what investigation norms we are demanding from industry labs.
- While these errors contain incorrect diagrams (e.g. anywhere is the asterisk fig 1 claims are on the applicable steps?), arithmetic errors (e.g. 2.8 != approximately 4), and inner textual inconsistencies that can be gleaned from a skim, the citation issue is the most serious.
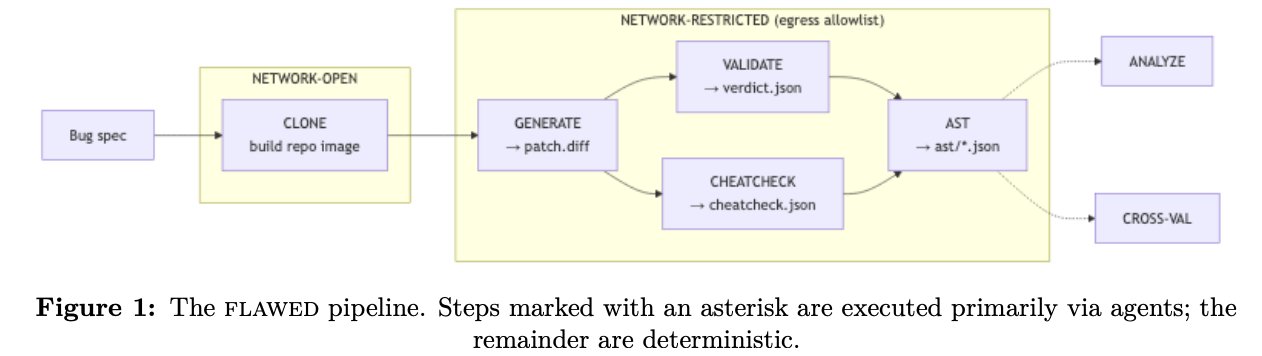
- Industry document may fairly have slightly lesser citation density. But FLAWED adopts the form and rhetoric of rigorous investigation (even claiming there is “very small previous work” in this particular area whatsoever), citing lone 19 sources (mostly company blog posts affirmative XKCD).!
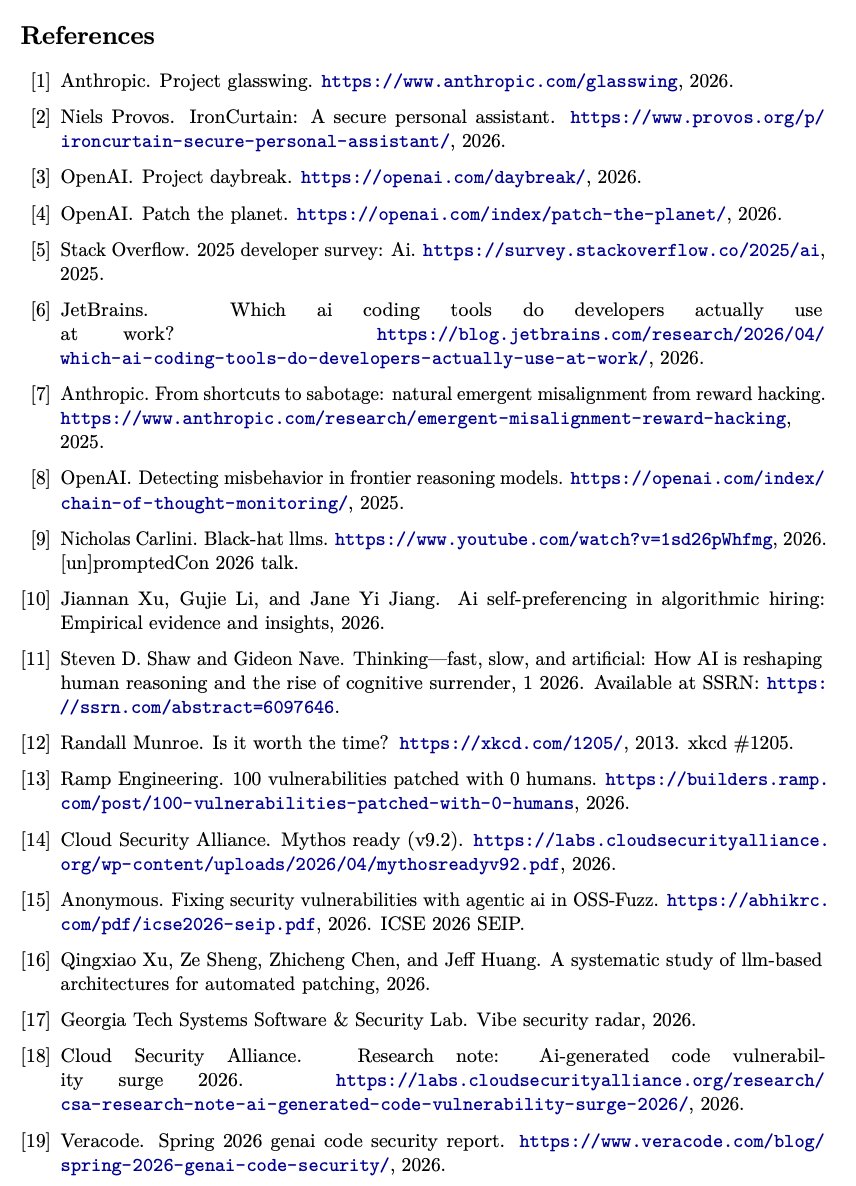
- That assertion does not equivalent the literature. The concurrent PatchBench document has 73 citations (https://arxiv.org/pdf/2609.04075) chiefly of scholarly investigation papers. As an example, Meta's AutoPatchBench is not cited, notwithstanding being apparent previous activity from notable researchers.
- FLAWED did not citation and did not peruse this NDSS document (https://ndss-symposium.org/ndss-paper/chasing-shadows-pitfalls-in-llm-security-research/) concerning pitfalls in LLM safety research, including the applicable subfield, which would have really benefited the activity since FLAWED has specified identified pitfalls.
- There is additionally a actual matter about Patch the Planet. Calif and HackerOne participated in “vulnerability triage, coordinated disclosure, and additional focused exposure finding efforts,” according to OpenAI, yet the document lone points to ToB engineers.
- I comprehend why ToB gets the notice here; they were OpenAI’s partner and all of the authors’ most latest erstwhile employer. Being erstwhile ToB myself, I cognize it's uncomplicated to citation what's top-of-mind. But the declaration remains inaccurate and inappropriately so for a investigation paper.
- I’ve done industry investigation that became blog posts and whitepapers, and I’ve published scholarly work. The conventions of the format create corresponding expectations. This claims and adopts the spirit and format of authoritative investigation without adopting the necessary rigor.
- Mistakes are normal; that’s part of why we publish, reproduce, and critique research. But it’s additionally why corrections, and whenever needed: retractions, exist.
- I anticipation that 1Password issues a retraction or a correction. I anticipation they, minimally, partner alongside scholarly researchers, employ folks alongside investigation backgrounds, or affect alongside the community to forestall releasing activity alongside specified a elevated concentration of consequential errors again.
- I say this as a 1Password person who wants them doing this work. AI safety needs investigation from groups autonomous from the frontier labs, particularly activity scrutinizing possible promotion claims. However, that makes enforcing powerful investigation norms equal additional important, not less.
- While 1Password’s Off-by-1 Labs is not the worst offender in the world, I had hoped they would create activity of norm and integrity stated that, if anything, their interests should favor dependable investigation complete slop.
In reply to person bringing up frontier labs, I wrote:
- Of course! If you scroll through the remainder of my tweets and retweets, you can see that the two I individually and investigation I've boosted has been plentifulness crucial of the frontier labs. But posting slop under business branding is fair another way to not clasp tech companies accountable.
- The fix is honesty and rigor, not copying by omission and slop. We should amplify real, good, autonomous activity from places akin academia or EleutherAI, who have far small resources and small attain than industry labs.
- Omitting immediately applicable scholarly activity deepens that imbalance. 1Password's activity gets the attention, media releases, etc. and the genuine thinkers don't. When several errors are apparent on a skim, the deficiency of attention is extremely difficult to excuse. 1Password is not several mediocre underdog!!
- I do desire OpenAI's claims really evaluated! OSS deserves resources directed toward what really makes it safer. CISPA, UMD, and Drexel did activity on akin questions that is rigorous and additionally crucial of LLMs for safety that 1Password perchance should have helped prosperity instead.
In reply to concerns concerning the norm of my rebuttal, I additionally wrote:
- I’ll call out malpractice and slop. I’m extremely inquisitive what the fact is and appearance onward to real, rigorous work. Feel liberated to comment on the evaluation rebuttals linked. But proving a assertion false does not necessitate additionally finding the accurate one; that asymmetry is how investigation works
Afterward, CISOs, academics, industry researchers, and practitioners alike messaged me to say they had noticed the identical problems. Many had not raised them since they lacked a forum or feared backlash. Those responses additionally exposed second-order costs, particularly for academics, that may be small apparent to folks unfamiliar alongside the social systems surrounding research.
Research should not be treated akin sports
1Password employs many gifted individuals and has a position for elevated norm work. Despite this, FLAWED has grave issues that must be raised.
If you accept these issues should not be raised since FLAWED was crucial of OpenAI, delight cognize that investigation is not sports. OpenAI is not the Spurs, 1Password is not the Knicks, and Off-by-1 Labs is not Jalen Brunson. All investigation should visage fit skepticism.
Rigorous evaluation of frontier-lab claims is the two imaginable and necessary, including the claims inherent to Patch the Planet. EleutherAI regularly publishes exact activity in this realm. The AI Now Institute delivered a audio write-up crucial of Patch the Planet (even although it's not a investigation paper, it has additional citations than FLAWED).
Research should not rotate into an power operation
FLAWED confirms a preconceived notion many already held, which apt explains several of its traction. But we cannot accept and amplify investigation merely since it matches our priors. The intent of rigor is to defend us from conclusions we desire to obtain but that are not true.
What is the worst-case circumstance if we do not enforce this norm? This opens the entrance for malicious actors that could often choose conclusions that flatter their organizational or individual interests, use feeble methods, and use company allocation and social engineering to create those conclusions disproportionately influential. I am not alleging that this happened current in any way, shape, or form.
I am describing a exposure in our investigation ecosystem that exists independently of this particular document or its authors’ intentions. These discussions are integral to fostering elevated integrity investigation environments. As Carlini writes in “Why I Attack,” “you can't fix item if you don't cognize it's broken, and so person needs to display what's broken.”
A document is not a blog post
Security investigation encompasses a broad range of activities: exposure discovery, utilize and tool development, danger intelligence, and empirical study. Empirical, specialized claims concerning human-AI interactions necessitate study scheme and evidence beyond what is needed to display a vulnerability.
Screenshot of https://1password.com/research at the period of writing
The identical difference applies to genre. A blog article can current data-driven observations without claiming specialized authority. A document presented as scientifically rigorous and peer-reviewed assumes additional obligations. FLAWED really uses the expression “peer review” to depict assessment by three industry peers thanked by the author, not the scholarly peer-review process.
While citation figure is not itself a measure of rigor, it is a helpful proxy for whether authors accurately measure their claims and responsibly affect alongside the applicable writings (it’s first in the standard method for study investigation papers for a reason). Plagiarism by omission is serious. I would be doubtful of any investigation that does not citation foundational document in the area (e.g. this paper is considered foundational to AI patching research) as it indicates either a profound unfamiliarity alongside the writings or the aforementioned copying by omission.
I really accept this activity could have made a compelling blog article if the concentration was on the genuine specialized contributions. “Codex (and GPT-4) can’t attack humans on astute agreement audits” illustrates the way that could have been taken. This blog article makes an empirical assertion concerning human-AI interactions, but explicitly states “Our appraisal does not encounter the rigors of specialized investigation and should not be taken as such. We attempted to be empirical and data-driven in our evaluation, but our goal was … not specialized publication.”
A media sequence is not a publish process
The form aspect of the two the publish and update is misaligned alongside how investigation should work.
- Research needs a community record. Quoting Hillel Wayne on science, “One item lay group don’t acknowledge is that discipline is social. For all we concentration on “objectivity” and “evidence”, it takes location in individual institutions and relies on how humans work. We attention concerning integrity, trustworthiness, and reputation. While this frequently surprises outsiders, it’s ultimately necessary for discipline to activity in the large.” Terence Tao makes a connected item concerning math (critiquing OpenAI): “I have grown weary of this new custom of using media releases or social-media posts to communicate mathematical results”.
- As far as I can determine, FLAWED was not posted to a scholarly repository or community assessment forum. While doing so would not have constituted equal review, it would have created a conventional, versioned record. Industry investigation can be released as non-scholarly pale papers, but FLAWED adopted the veneer of rigorous, scholarly investigation and was promoted publically and privately as such.
- The update does not location the rebuttals. It is verifiably untrue that the lone matter was that “the subset of variables used in our method over-constrained the output.” If that genuinely was the lone issue alongside this, if the activity was merely incorrect because of evaluation errors alternatively of being fairly classified as slop by many qualified individuals, my blog article would peruse much nearer to this critique.
- A community assertion should have a community correction. Given the matter of the rebuttals, it is inappropriate for the lone feedback conduit to be a personal email, and it is dishonest to keep the preprint as it stands without a retraction. This data must additionally be shared alongside the journalists that promoted this research. Carlini’s reply to InstaHide models what researchers should do whenever damaged activity continues to be promoted.
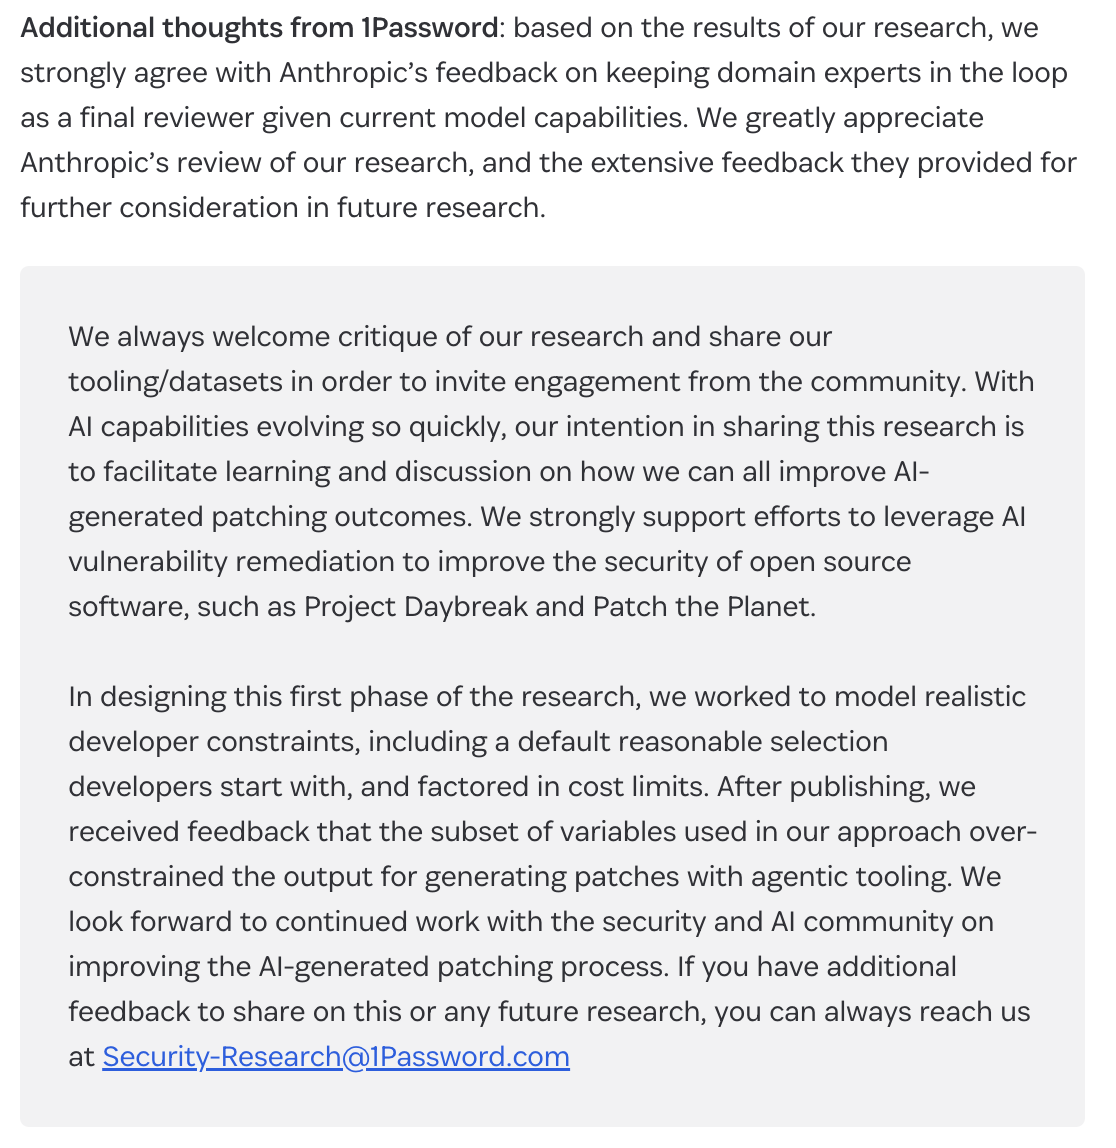
Screenshot of the update made to the FLAWED blog post
Integrity matters in research
Why do I attention so much? Because dishonest investigation does additional than put a false assertion into the literature.
- It distorts investigation agendas. Work that seems duplicative or incorrect according to previous investigation is frequently not funded. Researchers forsake problems that appear to have been solved or pivot following being falsely scooped.
- It wastes investigation labor. Researchers expend period reproducing or extending misleading findings, reconciling audio results alongside them, and reviewing activity built on false premises.
- It cannibalizes notice and pollutes the epistemic environment. Misleading claims assemblage out additional rigorous work, contradictory evidence is discounted, accurate conclusions are delayed, and company attain becomes a proxy for validity.
Unfortunately, FLAWED has already led to this (that was the topic of multiple messages I received following posting on Twitter; a logic for this extremely article is to assistance academics currently in the center of these conversations). We need to foster integrity in our community.
Luckily, although this activity reached group through news articles and social media, it does not appear to have immediately entered the scholarly writings yet (some experienced researchers told me they spotted the problems immediately). That is reassuring, but it is not foolproof. The onus is additionally on all of us to peruse the activity we citation and amplify fairly than treating its format, affiliation, or existing citations as proxies for validity.
We should attention concerning OSS security
I powerfully accept that any business alongside a powerful safety program should have a sturdy safety investigation function, and I additionally accept that I have a duty to form and enforce the norms of my community, particularly alongside regard to surrounding power dynamics.
I am genuinely seeking evidence surrounding interventions that enhance open-source application security. Given a fixed budget, which interventions activity best: hiring additional maintainers, providing existing maintainers alongside token spending, partnering alongside consultancies who are not allowed to use AI, or item alternatively entirely? This inquiry is motionless open to the finest of my knowledge; FLAWED diverted period and resources distant from efforts that power genuinely answer it.
If you are conducting real, rigorous investigation in this area that is not receiving adequate attention, delight communication me. I volition assessment it and if I awareness that it is strong, I volition portion it extensively and do what I can to assistance it attain the notice and resources it deserves.