Search Engine
Category
Home
Business
Marketing
Technology
Programming
Digital Products
Indonesian
Videos
DigitalOcean Tutorials Article Page 9
Home
Business
Marketing
Technology
Programming
Digital Products
Indonesian
Videos
DigitalOcean Tutorials
Prefill/Decode Disaggregation: Why Production LLM Inference Is Splitting Onto Separate Hardware
Continuous Batching Mechanics: The Scheduler Behind vLLM, TGI, and SGLang
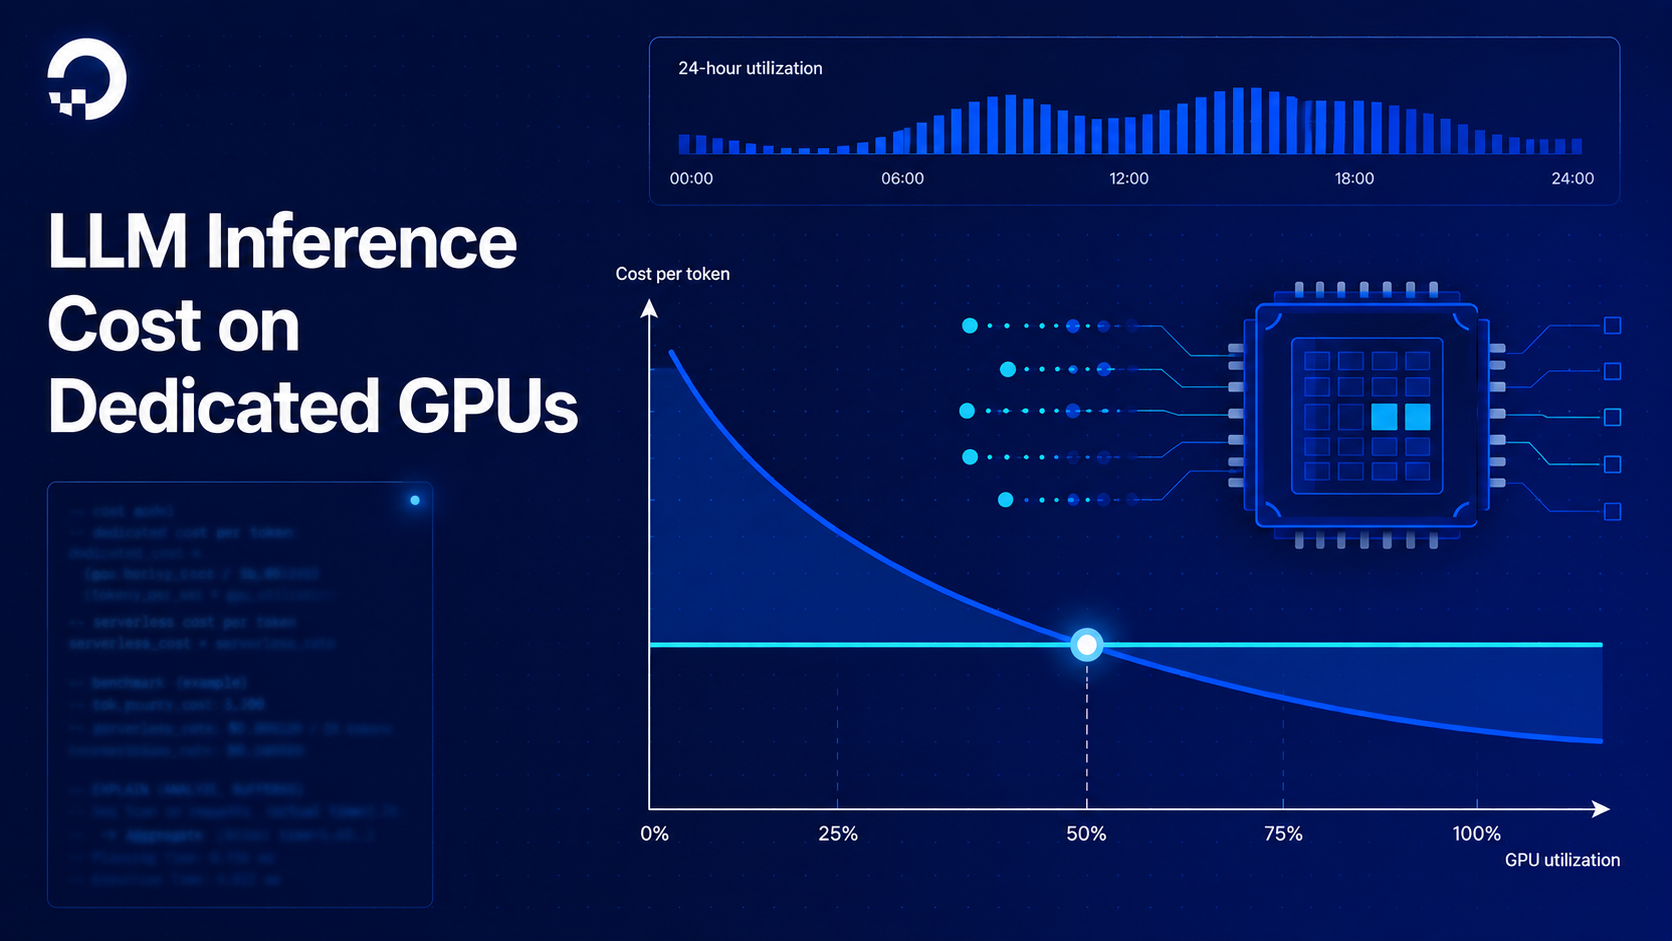
Serverless vs. Dedicated vs. Self-Hosted LLM Inference: When Self-Hosting Actually Gets Cheaper
Real-Time Customer Support Agent with Fallback Routing

Choosing the Right Model for Your Inference Use Case
The Inference Cost Model Nobody Has Published: Token Economics Across Traffic Profiles on Dedicated GPUs
The Four Hidden Surcharges in Your GPU Bill
Beyond GPUs: How Inferentia2, TPUs, Groq LPUs, and Tenstorrent Actually Differ for LLM Serving
State of the Union's Open Source AI: How American Open-Weights Models Compare Globally
Speculative Decoding on vLLM: A Configuration and Decision Framework
First
Prev
8
9
10
Next
Last
AI Assist
•
Ask ChatGPT
•
Ask Claude
•
Ask Perplexity
•
Ask Gemini
•
Ask Copilot
•
Ask Yandex
•
Ask Github
•
Ask You.com
•
Ask Manus AI
•
Ask Minimax
Trending
1.
Crowley
2.
The Guardian
3.
Nathaniel Moran
4.
California Prop 40
5.
Travis County Election Results
6.
Impeachment
7.
Pete Hegseth
8.
Scott Jennings
9.
Lame Duck
10.
Elon Musk
Popular Article
Google Signals A Wider Crackdown On UGC SEO Spam
Roger
524x views

Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5
Doris
522x views
Ten days later, Git on macOS still trusts the compromised eMudhra certificates
Putri
522x views
TCP Use-After-Free: CVE-2026-98432 / CVSS 9.8
Riki
521x views

How to Run Untrusted LLM-Generated Code in an Isolated Environment With MicroVMs
Andrew
521x views
↑