Search Engine
Category
Home
Business
Marketing
Technology
Programming
Digital Products
Indonesian
Videos
DigitalOcean Tutorials Article
Home
Business
Marketing
Technology
Programming
Digital Products
Indonesian
Videos
DigitalOcean Tutorials
DigitalOcean Serverless Inference latency: p50, p95 and p99 TTFT for GLM-5.3, DeepSeek V3.2, Gemma 4 and Llama 4 Maverick (3,456 requests, 48 hours)
Request Queuing and Latency Under Burst Traffic: What Happens When Your Model Gets Overloaded?
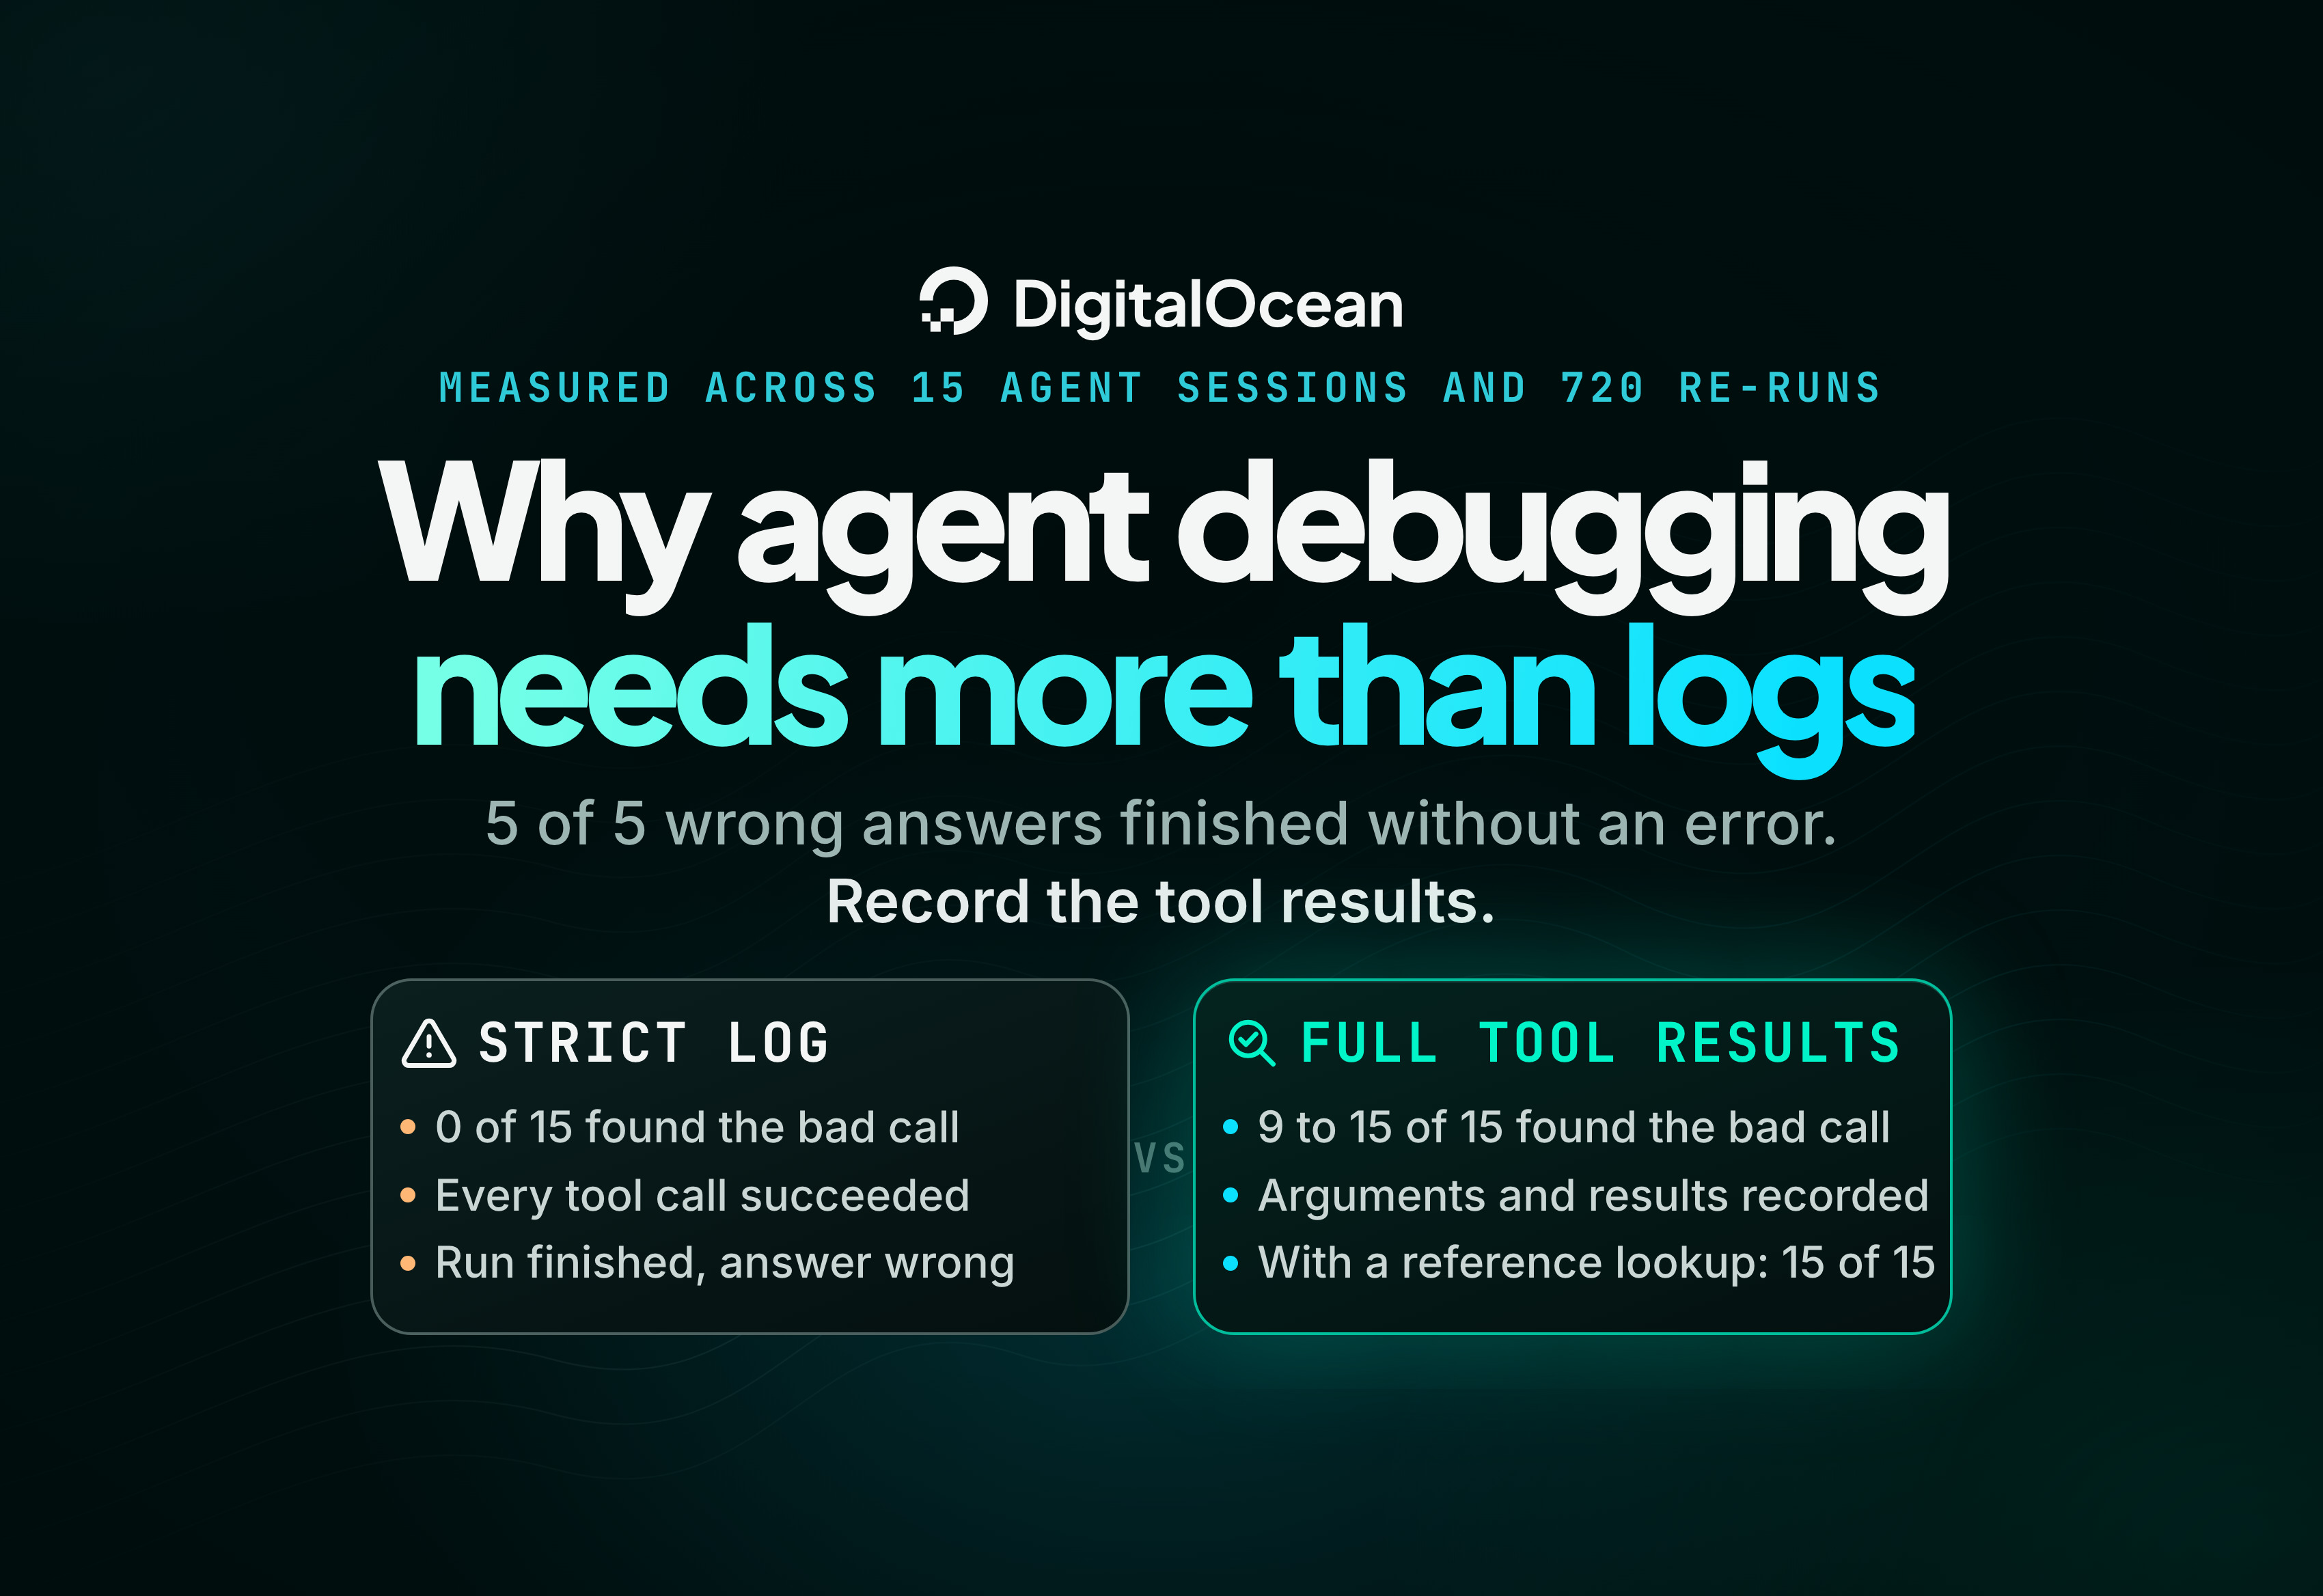
How do I monitor and trace AI agents running in Production

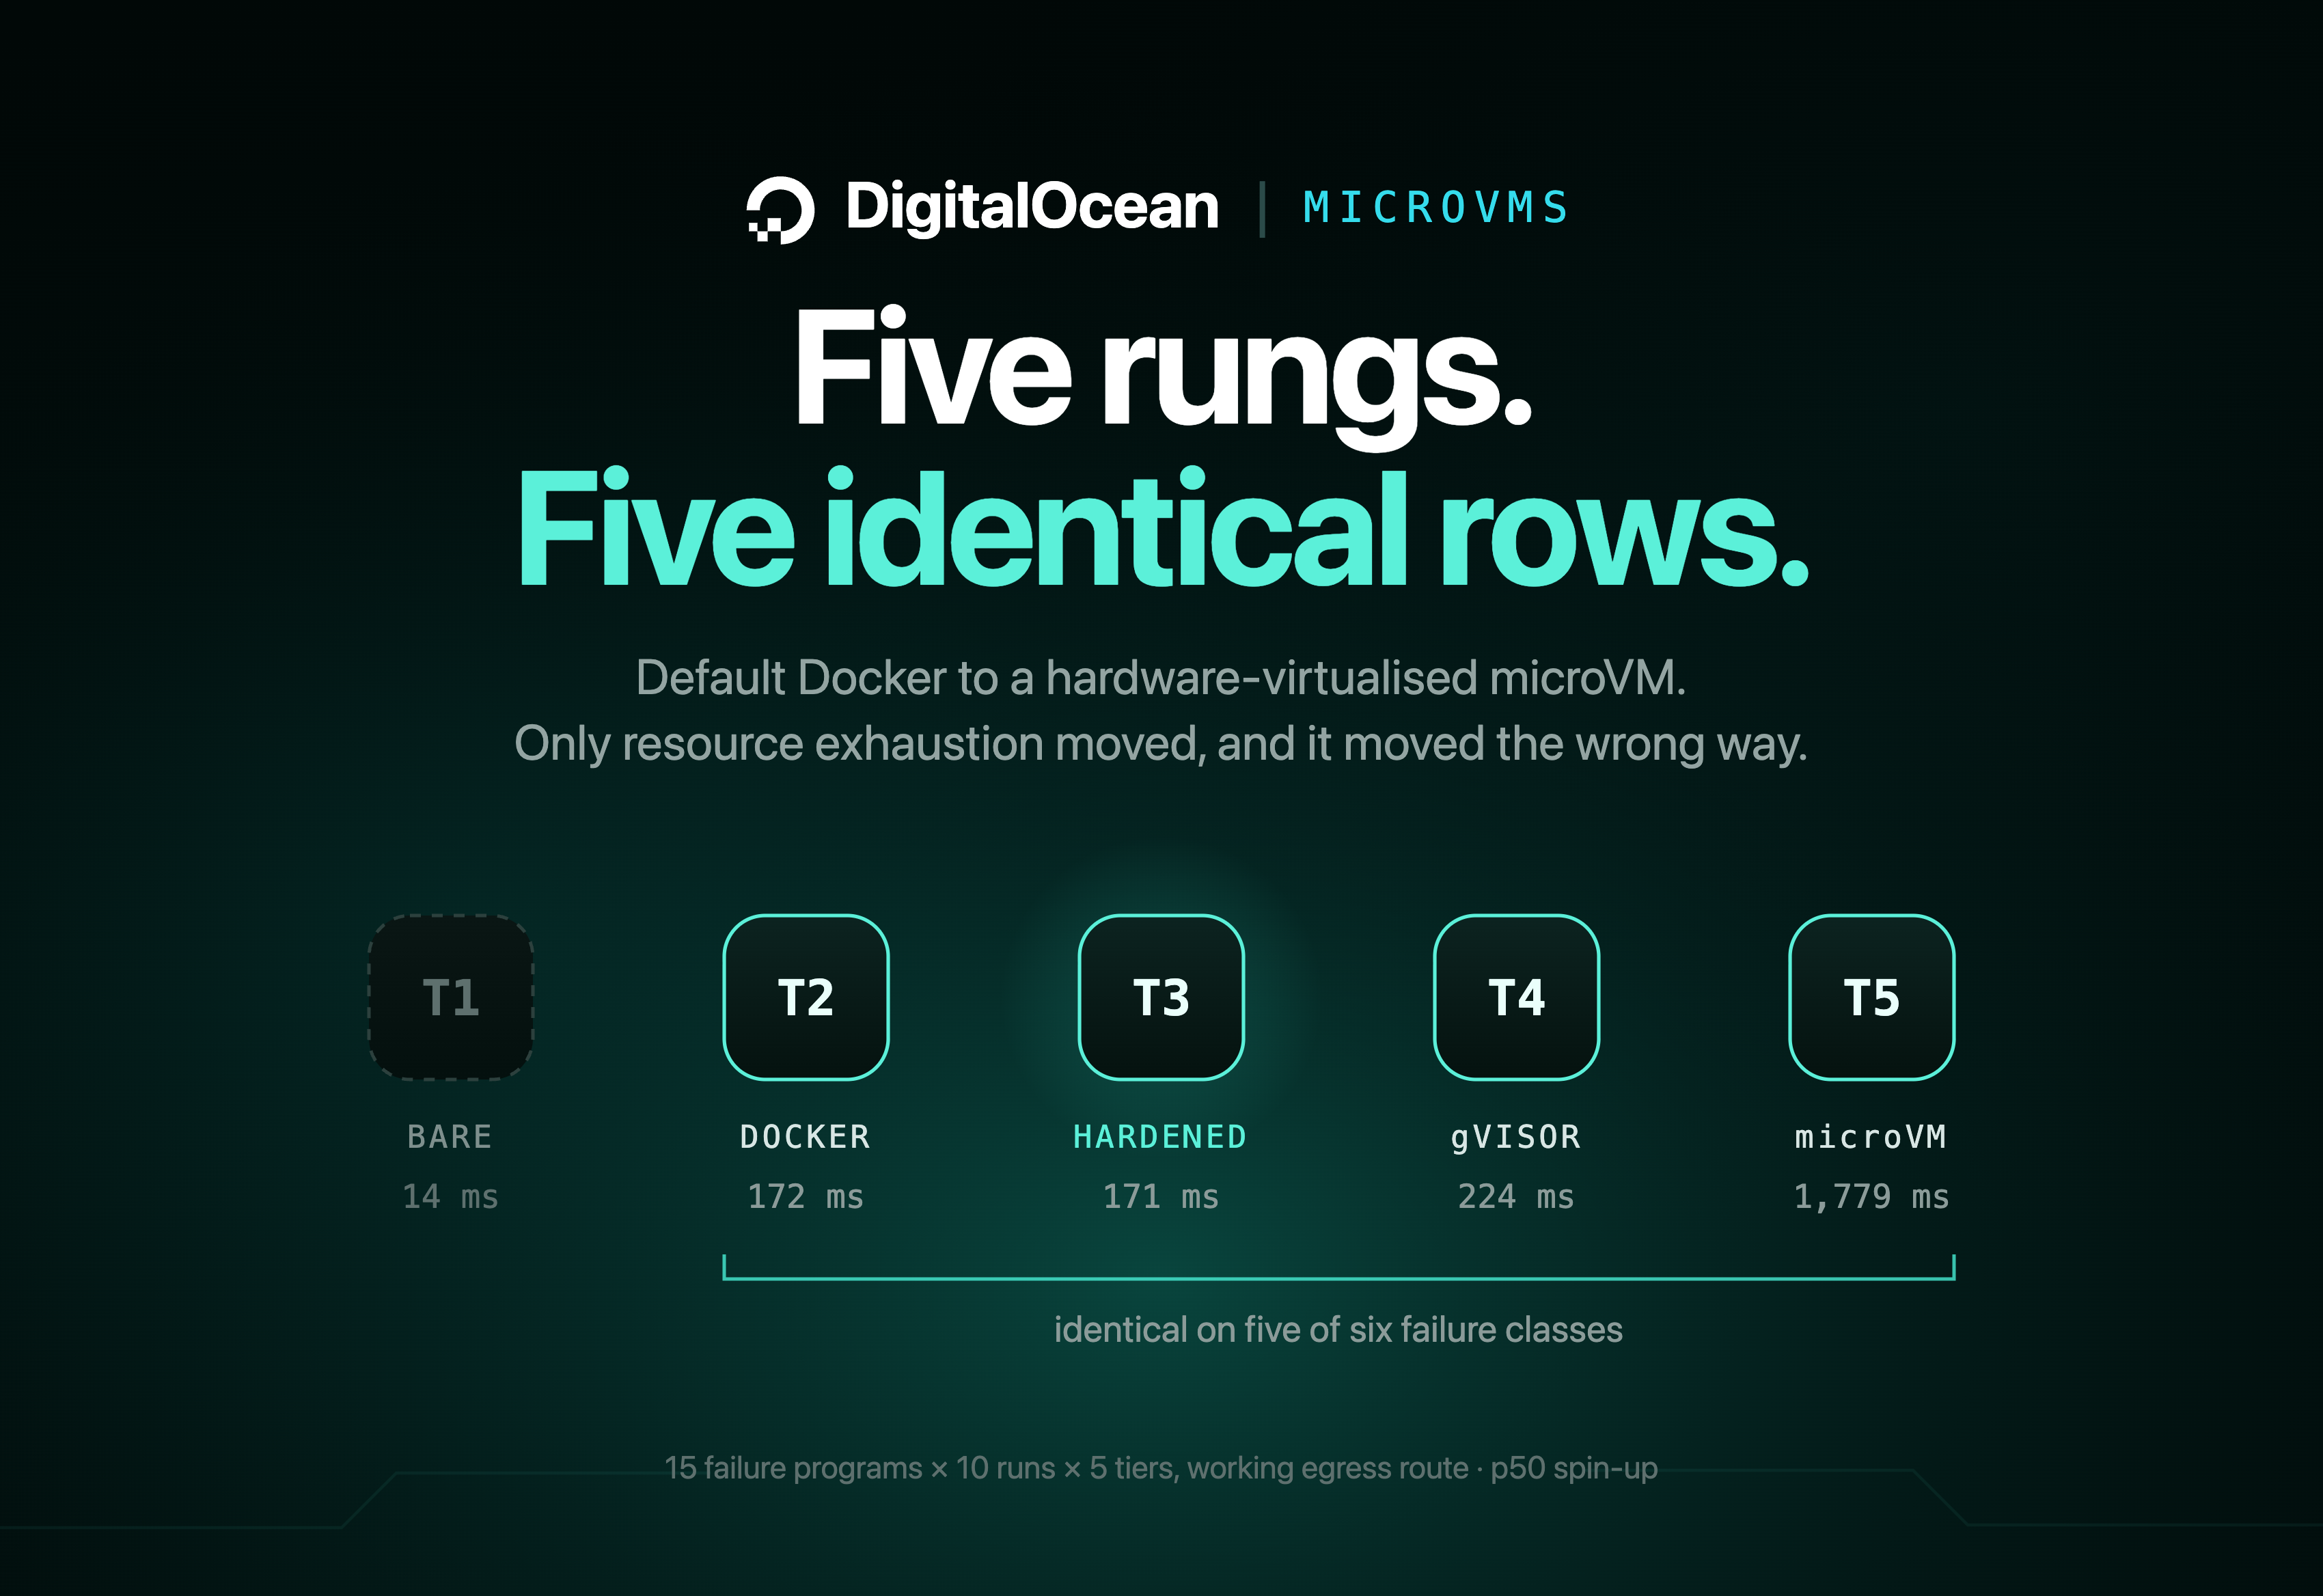
How to Run Untrusted LLM-Generated Code in an Isolated Environment With MicroVMs
Sandboxing LLM-Generated Code Needs a Different Threat Model
DigitalOcean Managed Agents latency: cold start and resume
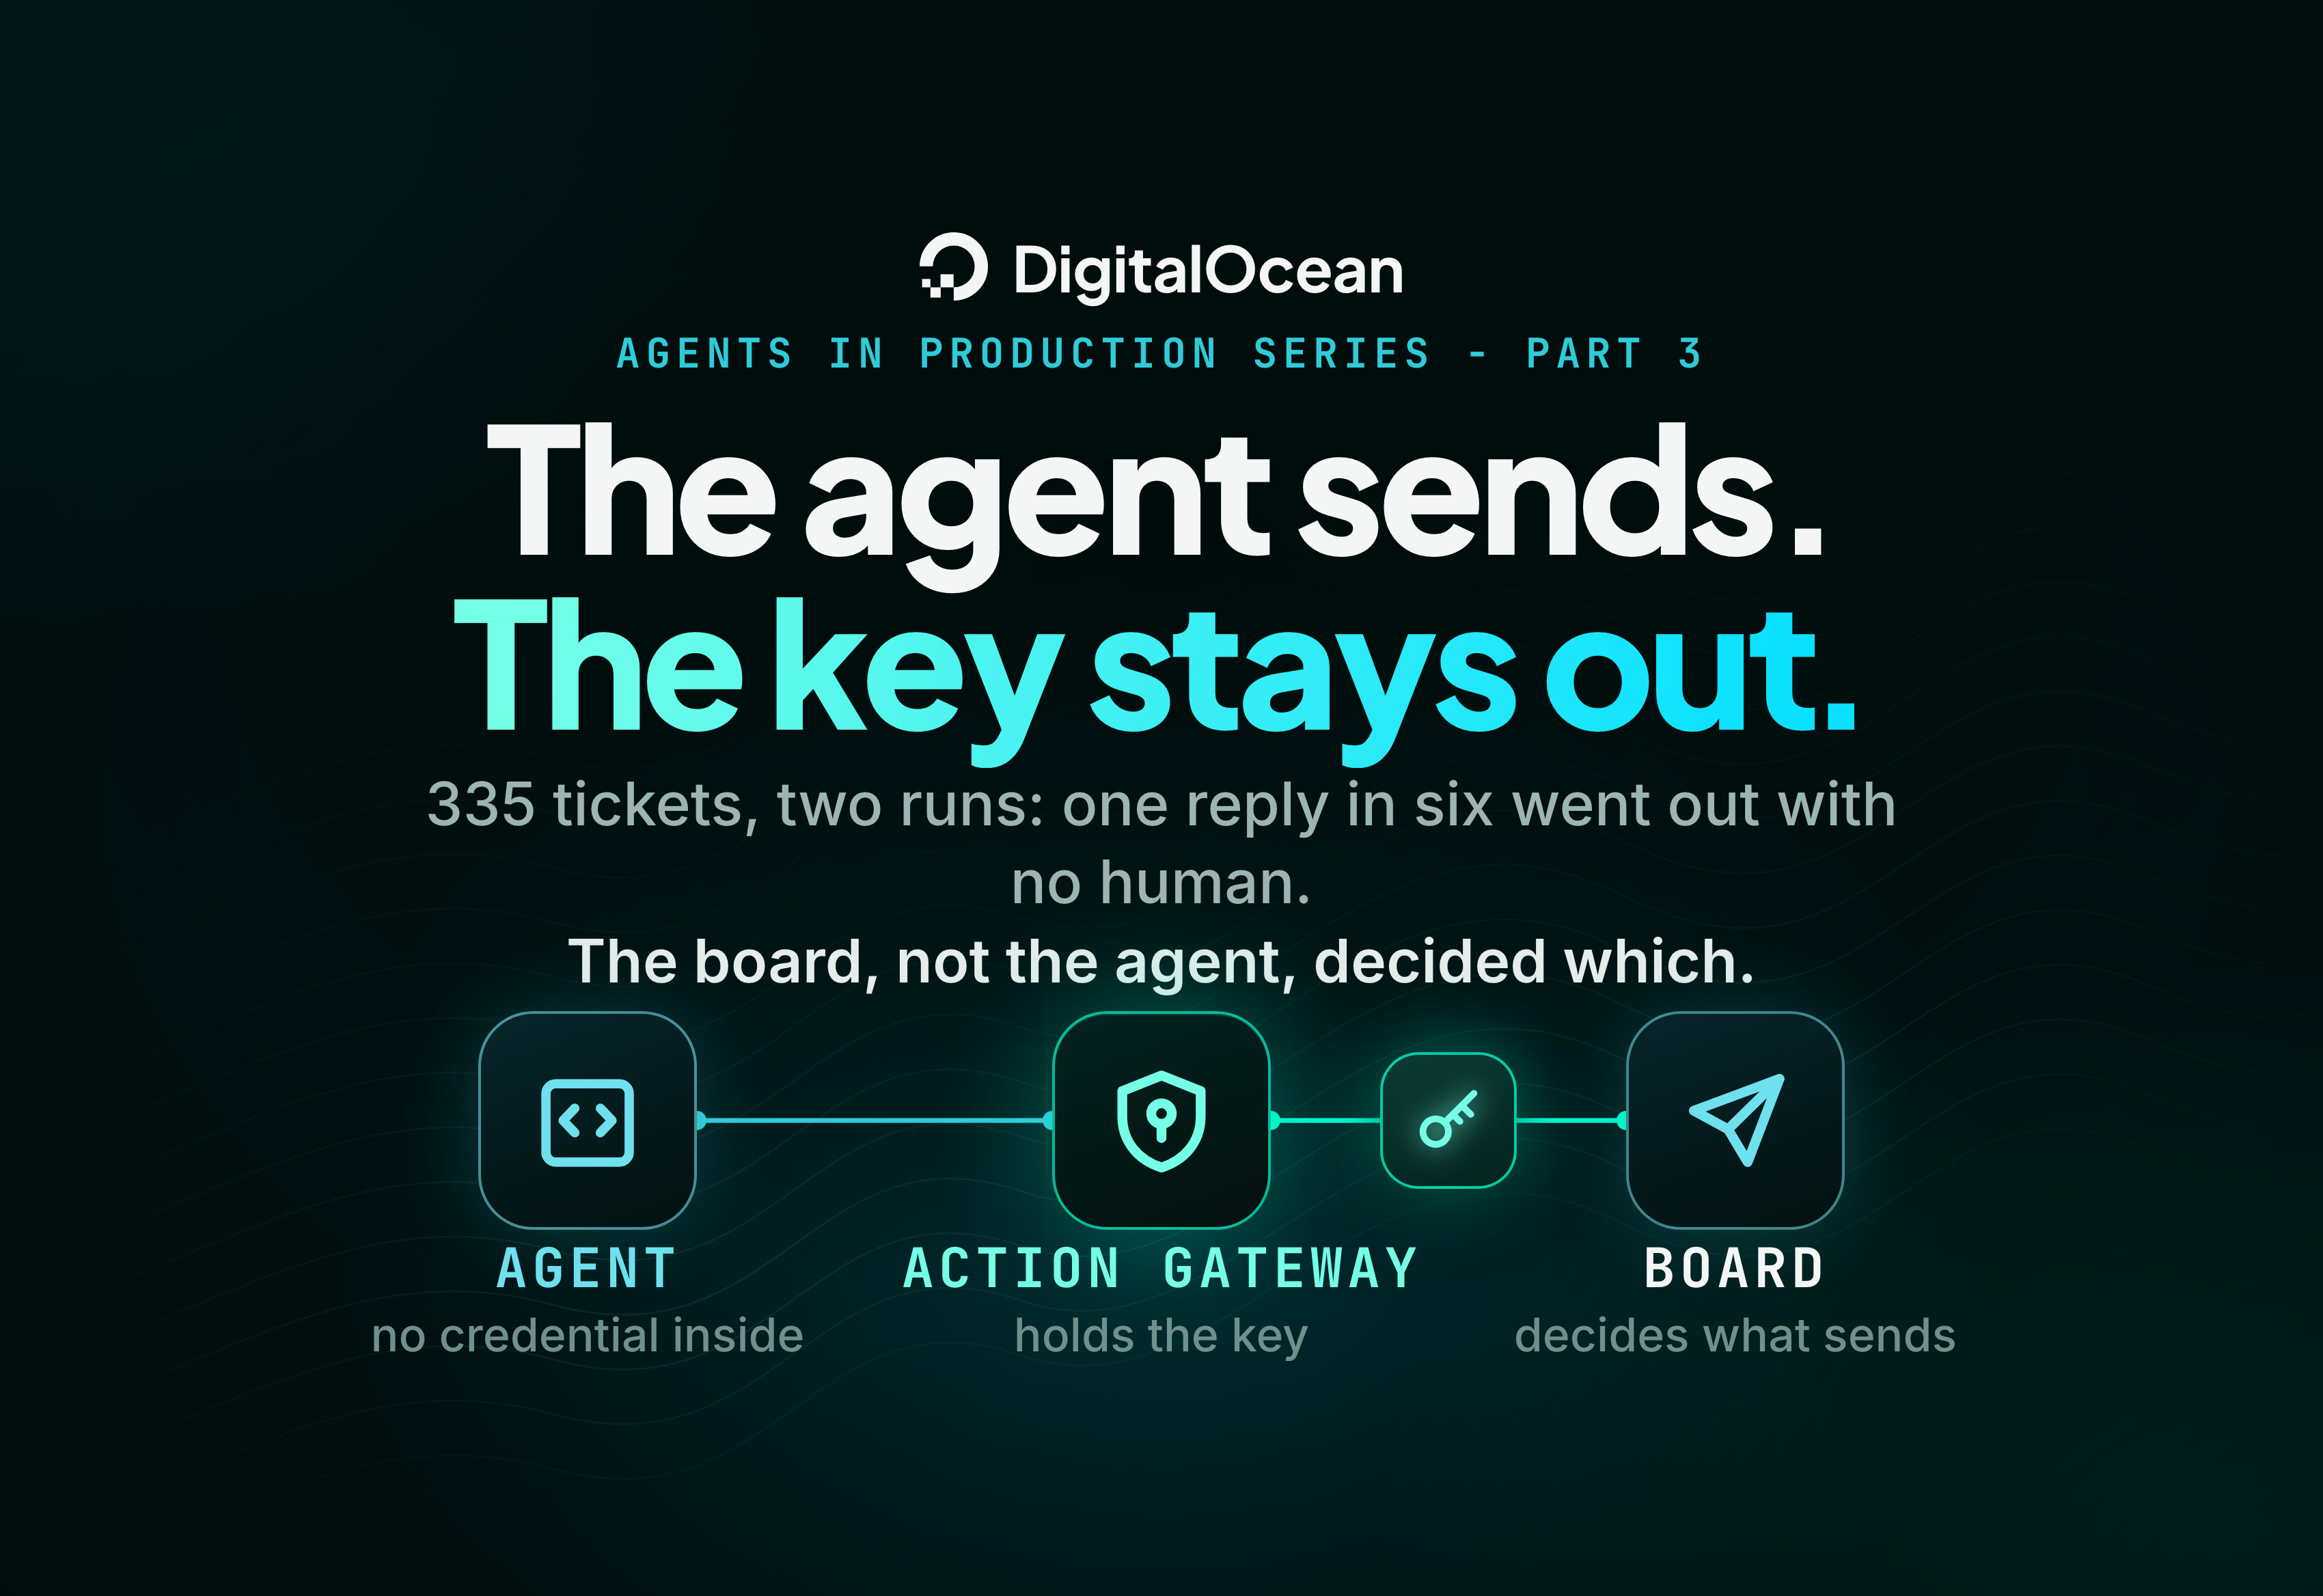
Agents in Production, Part 3: Let Your AI Support Agent Send Replies, Without Giving It the Credential
Cold Start Mechanics: How Warm Pools and Model Caching Actually Work
Spot vs Reserved GPUs:-A Practical Cost Guide for AI Startups
How to Measure Time to First Token for a Coding Agent: A Reproducible Benchmark on DigitalOcean Inference Engine
Prev
1
2
3
Next
Last
AI Assist
•
Ask ChatGPT
•
Ask Claude
•
Ask Perplexity
•
Ask Gemini
•
Ask Copilot
•
Ask Yandex
•
Ask Github
•
Ask You.com
•
Ask Manus AI
•
Ask Minimax
Trending
1.
Dan S. Sullivan
2.
David Hatley
3.
Bridget Fonda
4.
Tennessee Basketball
5.
Ken Burns
6.
Salary
7.
Babysitter
8.
Nj Election Results
9.
Embark Studios Arc Raiders Ai Voice
10.
Ohio Vs Akron Prediction
Popular Article
Google Signals A Wider Crackdown On UGC SEO Spam
Roger
524x views

Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5
Doris
522x views
Ten days later, Git on macOS still trusts the compromised eMudhra certificates
Putri
522x views
TCP Use-After-Free: CVE-2026-98432 / CVSS 9.8
Riki
521x views
How to Run Untrusted LLM-Generated Code in an Isolated Environment With MicroVMs
Andrew
520x views
↑