
- ReplacingMergeTree Is No Fun
- The Weird Partition Key
- Order By Slightly Changed
- Removing an Expensive Join
- Reading Fewer Columns
- Templating
- Aggressive Merges
- Reading Fewer Rows
- Ok But Why
Imagine you subordinate a caller task pinch a clear goal, amended ClickHouse performance, truthful our biggest customers tin tally their queries successful a reasonable magnitude of time. This is thing you’ve done tons of times before. You inquire for the astir costly query since it’s usually the 1 that will person the astir effect and a fewer low-hanging consequence improvements. You tally it and it takes much than a infinitesimal to complete.
1 row in set. Elapsed: 85.715 sec. Processed 1.96 billion rows, 198.69 GB Peak memory usage: 23.05 GiB.The query is 1 of the 12 being tally successful parallel, each computing its ain metric aliases sparkline. And they are successful the first surface a customer lands connected erstwhile accessing the application. Imagine a customer looking astatine a spinner for astatine slightest a mates of minutes correct aft logging in.
This is simply a statement connected each the changes, learnings, and optimizations we’ve made during the past 4 months to bring that query to sub-second latency. Changes were elemental and incremental. None of them was a clever trick, conscionable basal improvements compounding connected each other.
ReplacingMergeTree Is No Fun
The setup is simple, events get written to a ClickHouse array straight from Kafka. Events are mutable, immoderate arena astatine immoderate fixed constituent successful clip tin beryllium updated aliases deleted1. So, events changing past history are being received astatine akin aliases moreover faster rates than caller events. Exactly what a database based connected immutable retention is not for. We are forced to usage ReplacingMergeTree motor and make dense usage of FINAL, that’s wherever astir of the clip goes.
On apical of that, location are a fewer metrics that require going done the full history of a client’s events to beryllium computed. History that is ever expanding since they support their activity and make events each day. For this reason, immoderate numbers successful this station whitethorn vary. An optimization that took a query from 200GB to 150GB could later beryllium seen reference 210GB owed to the magnitude of information received betwixt 1 optimization and the next2.
The Weird Partition Key
The array was primitively walled by month:
PARTITION BY toYYYYMM(event_created_at)This is the evident choice, but the incorrect 1 successful galore ways for this case.
Events travel successful batches, and those batches effect immoderate constituent successful time. A azygous batch will incorporate events from aggregate months, penning a batch of files per insert and causing the accustomed snowball effect: expanding the number of files real-time queries person to read, adding unit to merges, etc.
Also, FINAL merges rows together, and its parallelism depends a batch connected really keys are distributed crossed partitions and really they overlap, the worst lawsuit script is simply a azygous thread doing the last merge and taking a batch of time. Partitioning by clip intends that a client’s events are dispersed crossed each partition successful the table, truthful ClickHouse has to walk a sizeable magnitude of clip building the pipeline and splitting ranges to trim intersections.
An illustration of the capacity effect of this partitioning causing FINAL to beryllium performed by a azygous thread:
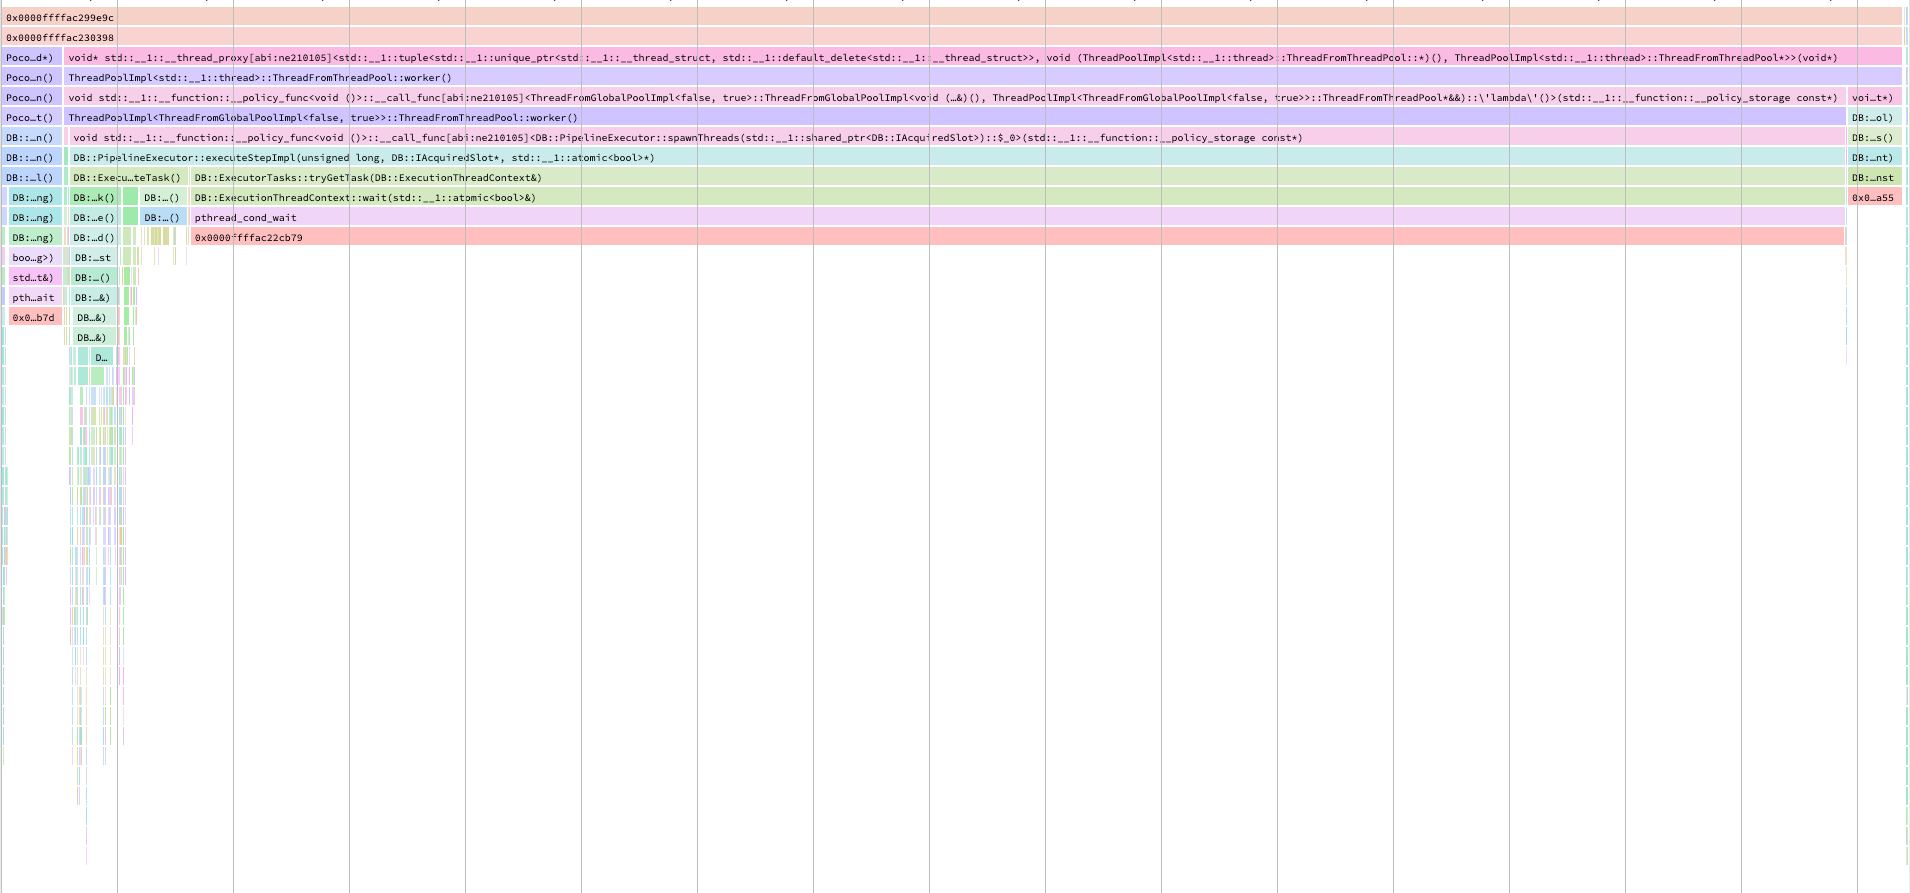 FINAL capacity utilizing a azygous thread
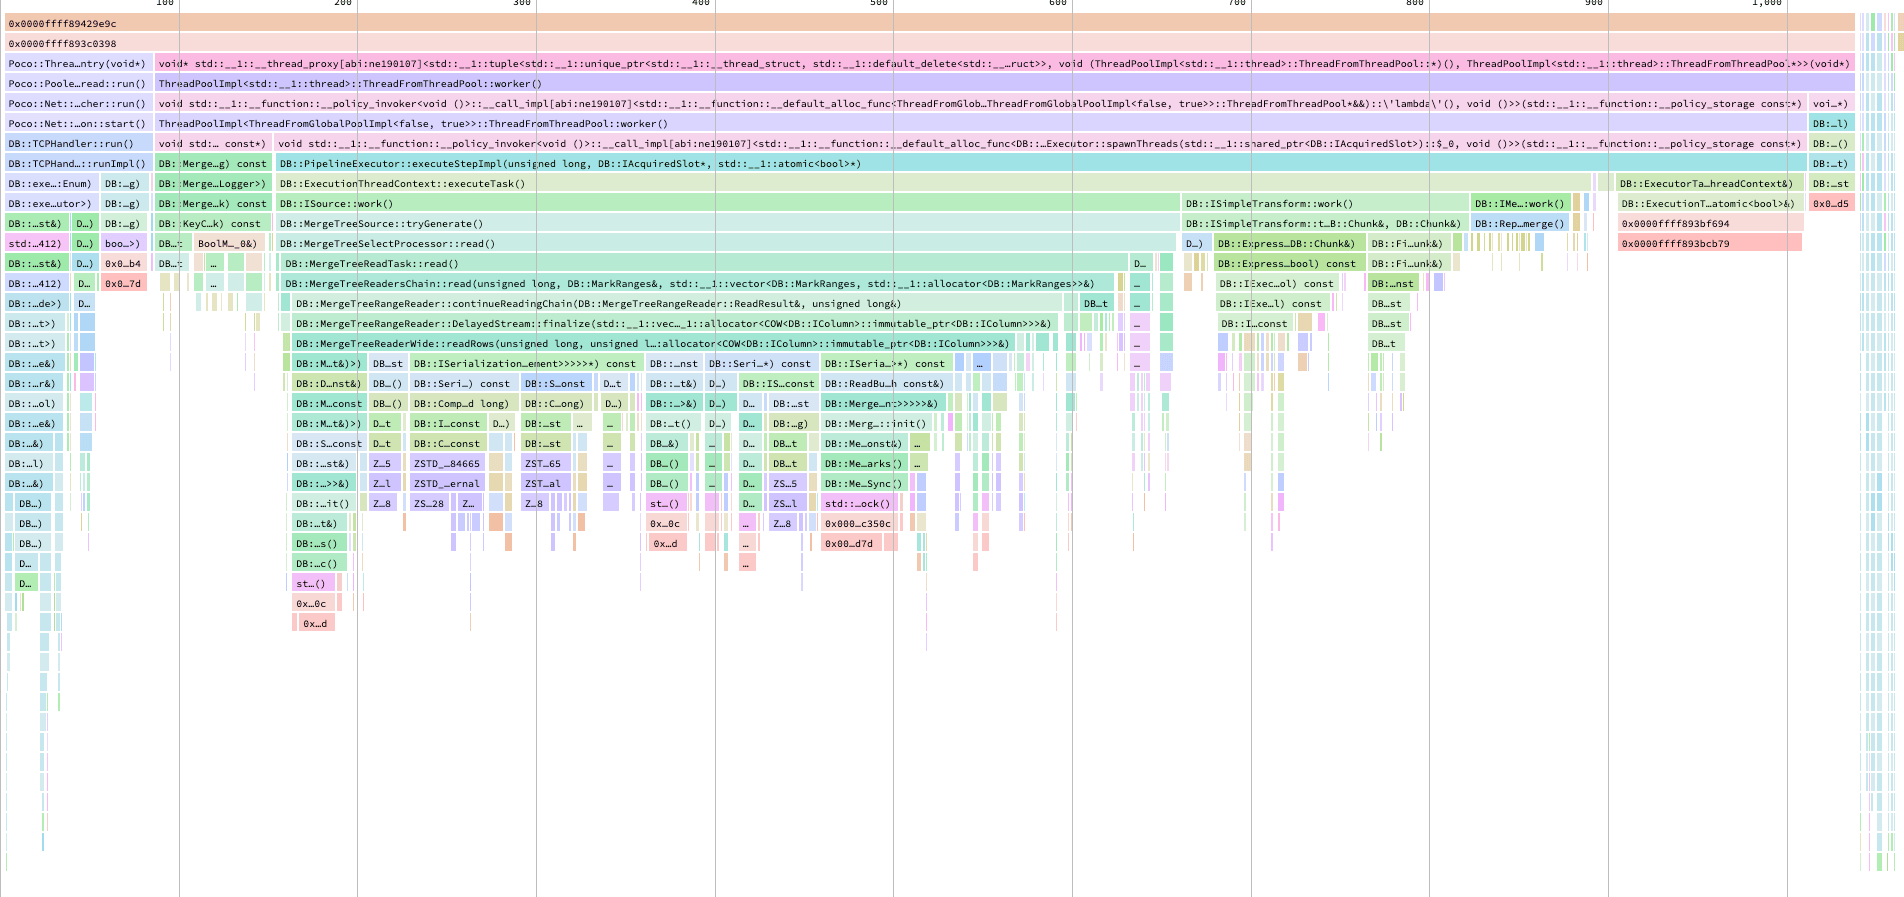 FINAL capacity utilizing the correct parallelism
To lick some issues while gaining a spot of performance, we applied the pursuing partitioning strategy:
PARTITION BY (client_customer_id % 36)Note that client_customer_id is not our client’s id but our client’s customer id, we don’t usage this file successful our queries. The strategy is counterintuitive3 but it useful good for our usage case:
- Keeps insert capacity nether power by “only” creating 36 parts per insert
- Partitions are arsenic distributed. There are nary immense partitions containing whale clients and slowing down queries for each customer landing successful the aforesaid partition
- Ensures FINAL parallelism without requiring ClickHouse to compute ranges intersections. Which intends that we tin disable split_parts_ranges_into_intersecting_and_non_intersecting_final and split_intersecting_parts_ranges_into_layers_final redeeming a fewer other seconds connected the information pipeline building step
- We springiness up partition pruning entirely, since we ne'er select by client_customer_id. There is simply a cost, but not for metrics that person to publication a client’s afloat history anyway. Partitioning by period was not pruning thing either. And arsenic mentioned above, we summation a batch successful parallelism
Order By Slightly Changed
While checking really each event_type contributes to each metric, we discovered that a fewer of them didn’t lend but we were still reference and processing them. They were ~16% of the rows connected the table. Not a immense quality but an evident alteration that could amended query performance.
Promoting event_type to an earlier position is not an ALTER. The sorting cardinal is fixed erstwhile the array is created, truthful this meant a caller array and a afloat rewrite. Behaviour stayed the same, since event_type was already successful the cardinal and only its position moved, truthful ReplacingMergeTree still collapses precisely the rows it collapsed before. After the change, we saw a important betterment successful query performance:
Before4
1 row in set. Elapsed: 13.43 sec. Processed 256.67 million rows, 18.82 GiB Peak memory usage: 18.78 GiB.After
1 row in set. Elapsed: 11.44 sec. Processed 237.86 million rows, 15.67 GiB Peak memory usage: 14.04 GiB.The query latency improved by ~15% while reference ~7% less rows. That explains why we don’t spot the afloat ~16%: the sorting cardinal filters retired granules, and if a granule contains moreover 1 statement of an event_type we are willing in, we person to publication the remaining rows from that granule.
Removing an Expensive Join
The query had a fewer costly joins, almost each of them down a instrumentality that fto america skip the existent array without removing the join. The correct broadside is simply a subquery gated by a parameter, truthful erstwhile the branch isn’t needed the select is mendacious and it returns nothing:
ANY LEFT JOIN ( SELECT ... FROM table_2 WHERE {has_currency:Boolean} = 1 AND ... ) USING ...Executing that costs a fewer milliseconds, parsing and readying it a fewer more. That’s what the templating conception is about.
There was a subordinate though that was being performed against a existent array connected each azygous call. The subordinate was simply retrieving a mates of fields utilized to compute immoderate intermediate values utilized for the metrics.
ANY LEFT JOIN ( SELECT client_id, internal_id, latest_a_field, latest_another_field FROM table_derived_from_original_table FINAL PREWHERE client_id IN {client_ids:Array(UInt64)} ) USING client_id, internal_idA 2nd FINAL connected a array derived from the original 1 to compute the latest values of the 2 fields we were willing in. ClickHouse builds the hash array for the correct broadside and puts it successful memory, the subordinate is comparatively accelerated but the costs is not only reference but besides successful representation footprint.
The hole was easier than it seems. The intermediate file computed pinch these 2 values could beryllium precomputed astatine exertion level and sent arsenic portion of the event. The queries are now simpler and the subordinate tin beryllium removed entirely.
1 row in set. Elapsed: 2.46 sec. Processed 49.86 million rows, 5.60 GiB Peak memory usage: 1.09 GiBMemory went down almost 13x, and query clip improved by almost 5x.
Reading Fewer Columns
We person seen really precomputing a file astatine exertion level tin prevention america a batch of representation and CPU. Why should we extremity there?
Turns retired that immoderate of the metrics, particularly the ones that require to publication afloat client’s history, were utilizing 9 columns. This is not a large woody pinch row-based databases but ClickHouse is columnar and reference a ample number of columns intends accessing other information that could beryllium avoided otherwise.
After precomputing the metrics publication for each statement astatine exertion level5, the effect was clear.
1 row in set. Elapsed: 1.38 s. Processed 49.69 million rows, 3.46 GiB Peak memory usage: 582.40 MiBThe 9 columns came to astir 38 bytes per row. Replacing them pinch an 8-byte file saves 1.5GB of sounds connected its own. Add the other files you debar reading, indices and marks, positive the seeks you save. And you get different ~2x improvement.
Templating
At this point, we person managed to spell from 13.43s to 1.38s, that’s almost a 10x betterment by conscionable compounding optimizations that we managed to use successful a fewer weeks. During the process, we person observed a fewer things that request to beryllium addressed pinch a much fierce approach.
One of the biggest bottlenecks we identified was related to really queries are being executed. We were utilizing nested ClickHouse parameterized views, 3 levels heavy generating immense queries that were re-parsed and re-planned connected each azygous request. Those views were passing parameters and rendering immoderate optional branches for illustration the joins mentioned above. No matter what we tried, the branches were still location consuming CPU moreover if it was not being used.
Measuring the effect was easy. Building a minimal type of the query and moving it against a customer without data. Execution is almost zero, truthful everything near is parse, AST, and pipeline building6:
| metric_1 | 0.448s | 0.029s | 420ms |
| metric_2 | 1.345s | 0.051s | 1.3s |
420ms of fixed overhead connected a query whose mean execution clip was 740ms. More than half of the clip was spent connected preparing the query.
So we replaced the views pinch level query templates. dbt compiles each metric into a azygous self-contained connection (from the aforesaid macros that build the parameterized views, truthful there’s 1 root of truth) leaving second-stage markers pinch bracket delimiters, which walk done dbt’s ain curly-brace Jinja untouched:
SELECT [% if has_currency %] {currency:String} as display_currency, coalesce(nullIf(exchange_rate, 0), 1) [% other %] 'USD' as display_currency, 1 [% endif %] AS exchange_rate, money_field_in_usd * exchange_rate as money_field_in_display_currency FROM original_table FINAL PREWHERE client_id IN {client_ids:Array(UInt64)} [% if has_currency %] ANY LEFT JOIN ( SELECT date, exchange_rate FROM exchange_rates PREWHERE rate = {currency:String} ) USING date [% endif %]The exertion renders the Jinja template (with the bracket delimiters) per request. Rendered queries are a fewer KB alternatively of 20+ KB. As you tin spot successful the example, pinch nary currency, the exchange-rate subordinate doesn’t beryllium successful the query astatine all.
The A/B consequence tagged done log_comment successful system.query_log:
| metric_1 | template | 233 | 626 | 44,897 |
| metric_1 | view | 735 | 1,355 | 67,199 |
| metric_2 | template | 448 | 1,290 | 58,403 |
| metric_2 | view | 1,835 | 2,940 | 100,885 |
Results from different query, measurement much awesome successful Grafana:
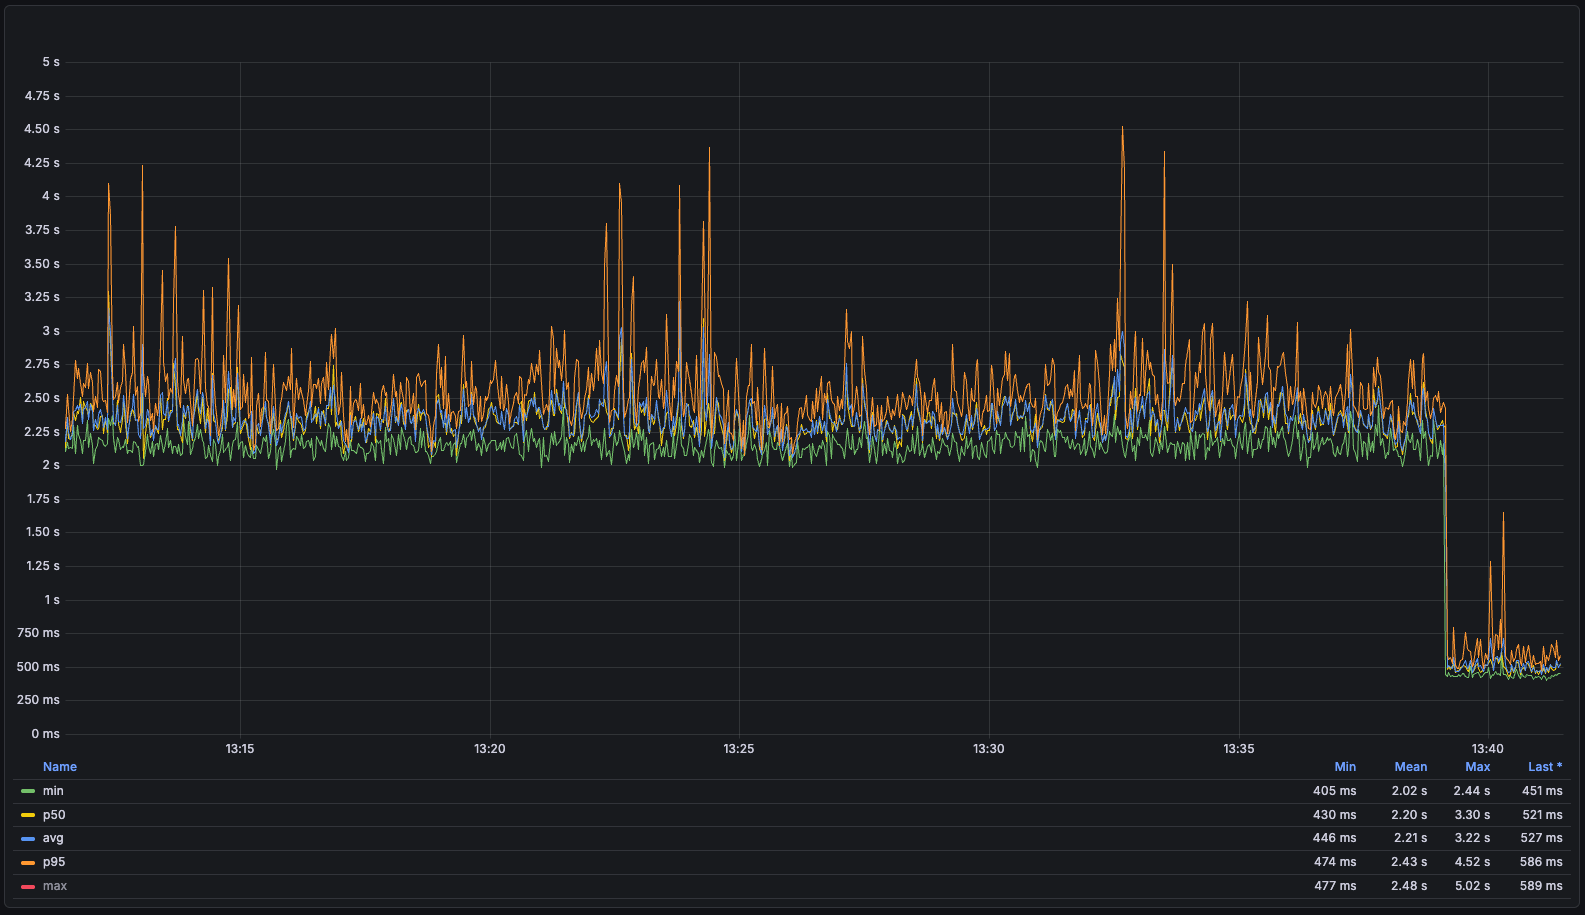 Average 2.21s to 527ms, p95 2.43s to 586ms.
Of course, this comes astatine a price. The templates person to beryllium compiled and rendered connected the exertion server. The first attack was caching the compiled templates successful memory, but this was not capable owed to the thousands of servers we tally and really often they get restarted owed to deployments. The dense templates were taking complete 300ms. We added an other cache layer, moving the compiled bytecode to memcached. If the template is not recovered successful memory, we effort to fetch it from memcached, and if it’s not recovered there, we compile it connected the fly.
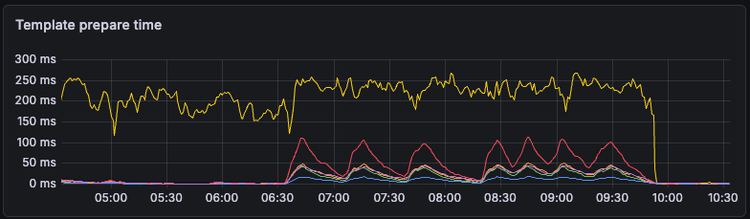 Template hole (compile + render) time, earlier and aft the shared cache.
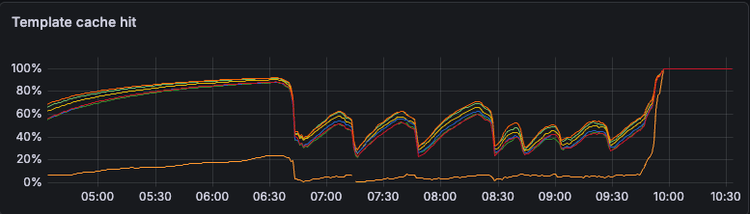 Hit ratio going to ~100%. The 2nd furniture is moving arsenic expected.
Compilation clip tin beryllium considered astir zero.
Those queries tally astir 2.4 cardinal times a week, truthful mini per-query savings support compounding into thing the cluster tin feel.
Aggressive Merges
The templating managed to trim down a changeless overhead we had successful each our queries. The effect was constricted though, and the betterment is comparatively mini for queries that are still reference a batch of data.
Now it’s clip to commencement reference little data. The easiest measurement I person recovered is to analyse the accusation successful system.processors_profile_log. We moreover person a instrumentality to crippled the results. See really the query we are trying to optimize looks like:
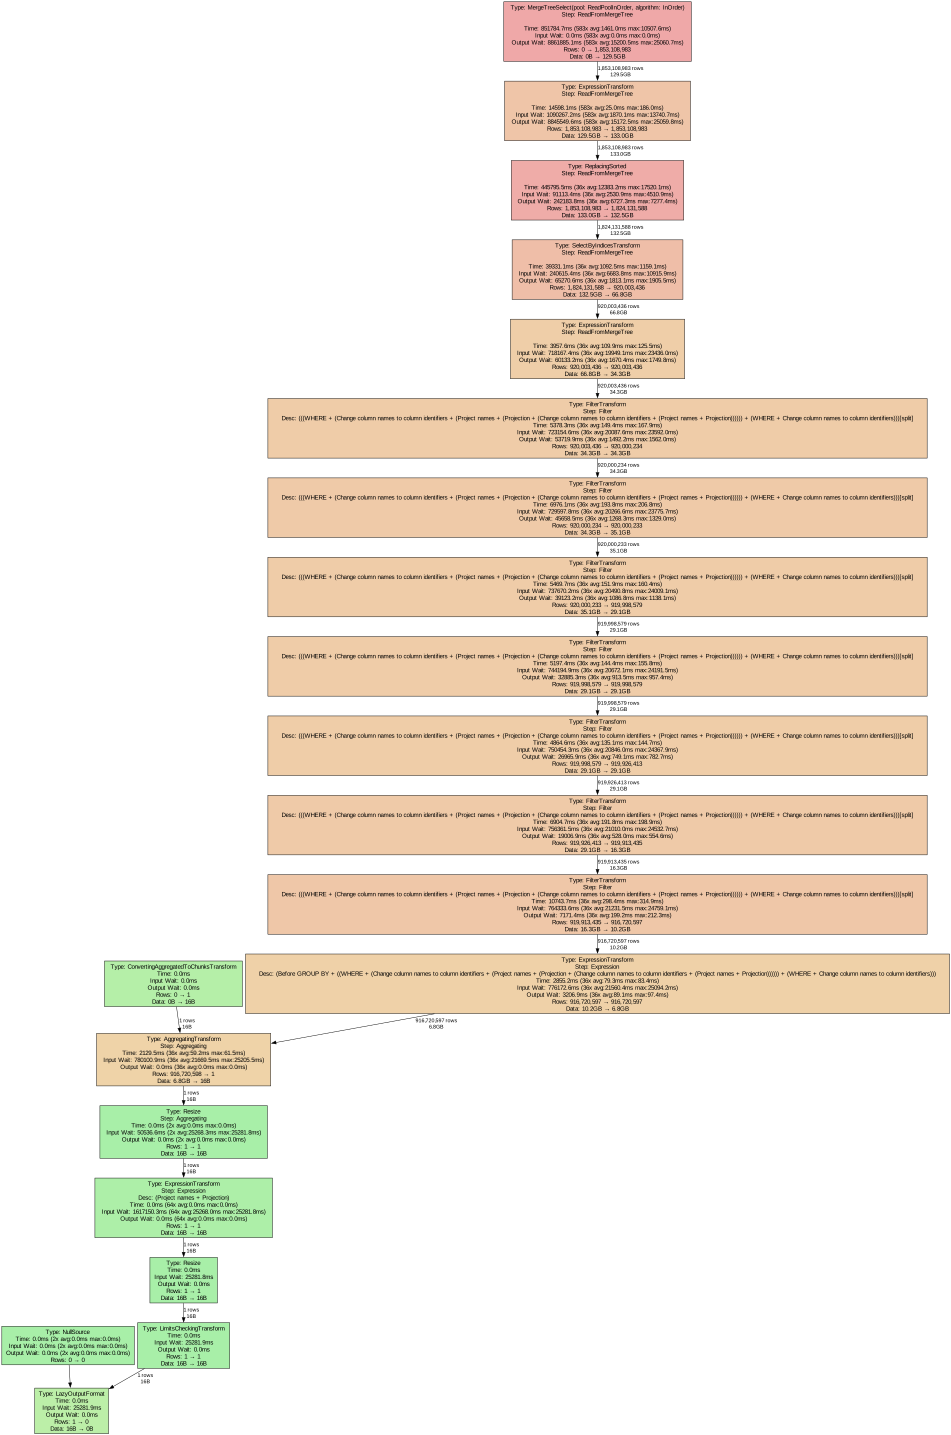 The ClickHouse pipeline for the metric needing the afloat humanities data.
Since we are trying to make this query to publication little data, we tin attraction connected the first 4 aliases 5 stages of the pipeline. These are the stages responsible for reference information and use the FINAL deduplication. Everything that happens aft that is different filters, aggregations, etc. and we are not willing successful that now.
A fewer important things to note:
- We publication 130GB of information but only 35GB are applicable for the computation
- There is already a 2x plagiarism successful our tables (1.8B rows → 920M rows)
- Columns from the sorting cardinal being publication only to use the FINAL correspond 30GB of the 60GB. If we return into relationship the 2x duplication, these columns correspond 60GB of the 130GB publication from disk.
A ReplacingMergeTree is only arsenic cleanable arsenic its merges, and someway merges were stuck:
Totals: ┌─partition─┬─parts─┬──parts_+30_gb──┬──perc─┬─bytes────┐ 1. │ │ 534 │ 32 │ 50.73 │ 2.12 TiB │ └───────────┴───────┴────────────────┴───────┴──────────┘32 of 36 partitions contained a azygous portion larger than 30GB holding astir 50% of the partition rows. And looks for illustration our merges limit (max_bytes_to_merge_at_max_space_in_pool) was group astatine 50GB. Those parts were ne'er going to get merged pinch thing again, truthful each copy that landed adjacent to them is kept forever.
Two settings changed here:
- max_bytes_to_merge_at_max_space_in_pool was raised from 50GB to 100GB, truthful parts larger than 30GB that had ne'er been merged would person a chance again
- min_age_to_force_merge_seconds was group to 86400 (24 hours), truthful parts older than 24 hours were merged
The first 1 did nothing, astir apt because the merge selector filters merge input size by really overmuch room is near successful the merge pool. Also, max_bytes_to_merge_* applies to the input, not the result. Because this is simply a ReplacingMergeTree, deduplication makes the output smaller than the sum of its parts (i.e., a 55.9 GiB input produces a 40.69 GiB part)
The 2nd 1 did the trick, parts older than 24 hours were merged regularly. Back connected accumulation data, the array sewage optimized:
| Parts | 534 | 378 |
| Table Size | 2.12 TiB | 1.55 TiB |
| Biggest Client Query Time | 14s | 5.5s |
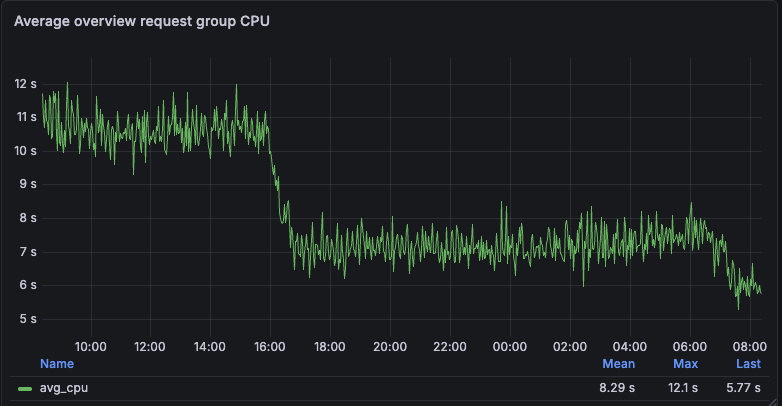 Cluster wide CPU usage per page load. FINAL gets cheaper dropping CPU consumption.
The value to salary is almost a regular rewrite of the array crossed each replicas. But this is the alteration that fto america get to a constituent wherever we considered that query clip is acceptable for each client, including the 1 that started this post.
Reading Fewer Rows
Everything we person done truthful acold has a awesome drawback, the information publication by our astir costly queries grows pinch the client. We person managed to amended query capacity by ~20x connected our biggest client. Let them turn by the aforesaid ratio and we are backmost astatine quadrate one.
We request to find a measurement to publication less rows and support it changeless sloppy of the size of the client. The evident solution is to pre-aggregate utilizing a materialized view. But retrieve what we are dealing with, thing tin beryllium changed aliases removed astatine immoderate constituent successful time. In general, materialized views don’t play good pinch ReplacingMergeTree and mutable events7.
Looking for alternatives, we recovered that astir of the metrics are computed complete events that hap complete periods of clip (e.g., subscriptions pinch commencement and end).
┌─expired─┬────count()─┐ 1. │ 1 │ 6208430114 │ -- 6.21 billion 2. │ 0 │ 179498782 │ -- 179.50 million └─────────┴────────────┘About 97% of the rows we publication beryllium to periods that already ended. A play that ended successful 2021 doesn’t lend to today’s metrics. Theoretically, we are reference six cardinal rows to adhd up 180 million.
Three things were preventing america from utilizing this accusation arsenic thing valuable:
- period_ends_at was not portion of the ORDER BY
- The file was not being updated because cipher utilized it
- Fixing it required editing 6 cardinal rows
We person already seen really comparatively easy it was to beforehand a file from its position to the apical of the ORDER BY clause. But this is different story. It affects a fewer places successful the exertion since you request to cognize the values successful the ORDER BY to nonstop the tombstones to delete immoderate rows erstwhile needed.
Also, earlier continuing pinch this optimization, we request to cheque if adding the file to the ORDER BY would really amended the performance. The existent clause looks for illustration this
ORDER BY client_id, event_type, toDate(event_created_at), ...while the caller 1 will look for illustration this
ORDER BY client_id, event_type, toDate(event_created_at), toDate(period_ends_at), ...The caller file has to beryllium added to the 4th position fundamentally because, while the query we are trying to optimize can’t use from filtering by event_created_at, location are galore different queries that use from it. So the mobility is: are we going to beryllium capable to select granules by placing the toDate(period_ends_at) file successful the 4th position?
The mentation down it is easy, granules are the minimum magnitude of information that tin beryllium publication from disk, indexes and marks are utilized to select granules earlier they are read. By default, those granules are 8192 rows-long. To beryllium capable to select by a column, the erstwhile ones should person capable information to stay constant. Or successful different words, each time we should person astatine slightest 8192 events from the aforesaid customer and arena type.
Turns retired that our apical 10 clients, the ones we are moving this optimization for, surpass that period by a ample margin.
As you tin see, location is simply a 100x simplification successful the number of rows and bytes processed. Filtering granules was the triumph we expected, but location was different we didn’t anticipate. Even erstwhile granules are not filtered and unnecessary rows are publication from disk, we now select them earlier applying the FINAL clause, which has an effect moreover connected mini clients.
We yet managed to bring the query clip down to ~400ms, from the original 85s. That’s much than a 200x improvement.
Ok But Why
If you’ve publication up to this constituent I tin only convey you. Also, you mightiness beryllium wondering why I’m penning this blog.
I’ve spent a fewer years penning down everything I learned astir ClickHouse internals and the process I person followed to analyse and optimize everything I person recovered successful my way. I’m proud of that work, and being unrealistically optimistic, it was useful for others and hopefully will still be. On a much realistic note, I’ve mislaid (or will lose) entree to each that content. Just a fewer coworkers publication it erstwhile I primitively posted it, and I can’t ideate who is going to publication it today.
This is conscionable a mini portion of what I’ve learned, and sharing it present is simply a measurement to effort to support that activity live and accessible for others. Hope it helps.









 English (US) ·
 Indonesian (ID) ·


