Introduction
This blogpost is the second and final part of our Avast investigation and volition concentration on the exploitation of CVE-2025-13032, a double-fetch exposure we discovered in Avast’s kernel driver.
This article recaps the bug and walks through how we exploited it on an up-to-date Windows 11 scheme at the period of the finding.
Feel liberated to peruse the archetypal part if you missed it → https://www.safateam.com/intelligence-hub/research/technical-articles/cve-2025-13032-entering-and-breaking-the-avast-antivirus-sandbox-part-1
Note: In the latest type the windows kernel and drivers are using user-mode accessors (https://learn.microsoft.com/en-us/windows-hardware/drivers/kernel/user-mode-accessors) to verify all kernel admission to user-mode recollection and justify at all admission that user-buffers are in fact live in userspace. This mitigation volition forestall the use of the exploitation method that is described in this writeup, see additional particulars at https://www.youtube.com/watch?v=ry4SNYe2f68
Bug Explanation
The bug we desire to utilize is a twice fetch matter that leads to a kernel pond overflow.
The snippet of code presented below is expected to grasp a `_UNICODE_STRING` construction supplied by the user, but the `Length` site of the person input is fetched multiple times which results in the twice fetch issue.
The archetypal fetch is done to allocate a buffer anywhere the cord volition be copied and a second fetch is done to execute a memcpy according to the retrieved value resulting in a pond overflow if the person changes it between those actions.
1
if ( !a1 && unicodestring_user )
3
ProbeForRead(unicodestring_user, 0x10, 1);
4
ProbeForRead(unicodestring_user->Buffer, unicodestring_user->Length, 1);
6
v17 = sub_140071C6C((__int64)v18, &v14[v23 + 13], unicodestring_user);
8
__int64 __fastcall sub_140071C6C(__int64 a1, _QWORD *a2, _UNICODE_STRING *unicodestring_user)
10
PoolWithTag = ExAllocatePoolWithTag(PagedPool, unicodestring_user->Length + 16, 0x20786E53u);
13
Length = unicodestring_user->Length;
14
*PoolWithTag = unicodestring_user->Length;
15
PoolWithTag[1] = Length;
16
*((_QWORD *)PoolWithTag + 1) = PoolWithTag + 8;
17
Buffer = (char *)unicodestring_user->Buffer;
20
if ( unicodestring_user->Length )
21
memmove((_OWORD *)PoolWithTag + 1, Buffer, unicodestring_user->Length);
To utilize the twice fetch, a second thread runs in a tight loop, continuously toggling the `Length` site of the shared `_UNICODE_STRING` between a small harmless value and a ample malicious value (e.g. `0x1000`, larger than the allocated buffer). The chief thread calls the susceptible IOCTL in a loop. When the timing aligns — the kernel says `Length` as small for the `ExAllocatePoolWithTag` call, afterward says it as ample for the `memmove` — additional bytes are copied than were allocated, producing the pond overflow. The competition opening is narrow but can be won reliably inside a humble figure of iterations.
Our goal is to utilize this pond overflow to acquire an arbitrary kernel read/write primitive and accomplish a local privilege escalation. The bug gives us fine exploitation conditions: the overflow targets `PAGED_POOL`, the two the allocation size and the overflow size are controlled, and so is the content.
The paged pond is a area of Windows kernel recollection used for objects and data that the kernel or drivers need, but that can be paged out to disk. It is used for recollection that does not need to be accessed by crucial code operating alongside elevated priority. The allocator groups allocations by size class, definition same-sized objects lean to district near to all another in recollection — the asset that makes heap spraying viable.
Since Windows 10 19H1 this is handled by the Segment Heap, which uses two backends: the LFH for small allocations, which picks liberated slots randomly inside a size bucket, and the VS allocator for larger ones, which serves the archetypal accessible chunk of the correct size — all requiring a distinct spray strategy. We can additionally note that most Windows objects are stored in the paged pool, which gives us a ample figure of candidates whenever choosing what to corrupt. In the next division we explain which entity we chose and the reasons rearward that choice.
For additional data concerning how windows pools work, you can mention to the `Scoop the Windows 10 pool!` document from Synacktiv ( https://www.sstic.org/media/SSTIC2020/SSTIC-actes/pool_overflow_exploitation_since_windows_10_19h1/SSTIC2020-Article-pool_overflow_exploitation_since_windows_10_19h1-bayet_fariello.pdf ).
I/O Ring Object
The I/O Ring Object is an entity that maintains a submission queue of I/O operations to be performed asynchronously.
Concretely, it lets userland lot document I/O requests: `IoRingReadFile` copies data from a document into a pre-registered buffer, and `IoRingWriteFile` copies data from a pre-registered buffer into a file. These registered buffers — tracked in the `RegBuffers` site of the `_IORING_OBJECT` — are validated formerly at registration period and afterward reused openly for all consequent operation, making them a persistent and engaging mark to corrupt.
We chose this entity as our misconduct mark for multiple reasons. While the IORing entity itself is located in the `NON_PAGED_POOL`, its `RegBuffers` site is allocated in `PAGED_POOL`, which immediately matches the pond anywhere the overflow occurs.
Secondly, the size of the `RegBuffers` allocation is completely user-controlled: registering N buffers produces an gathering of N pointers, all 8 bytes, giving us exact authority complete the allocation size and making it ideal for a heap spray.
Thirdly, Corrupting a sole pointer in that gathering is adequate to acquire a complete arbitrary read/write primitive — there is no need to corrupt a additional complex structure.
Finally, I/O Ring Objects have already been used publically to accomplish this exact goal, which confirms the method and provides a firm citation item for our approach.
Multiple APIs are accessible from userland to use the object, current are several of them:
- CreateIoRing
- CloseIoRing
- BuildIoRingReadFile
- BuildIoRingWriteFile
- BuildIoRingRegisterBuffers
- BuildIoRingRegisterFileHandles
- SubmitIoRing
- ...
The `Build.*` APIs are used to build entries that need to be submitted through the `SubmitIoRing` API.
The `IoRingRegisterBuffers` allows the person to enroll an gathering of buffers for forthcoming I/O Ring operations, which can be used as a destination buffer for the `IoRingReadFile` procedure or as a origin buffer for the `IoRingWriteFile`. This act creates the `RegBuffers` pointer gathering in the `_IORING_OBJECT` and allocates the idiosyncratic `_IOP_MC_BUFFER_ENTRY` objects it points to, all holding data concerning the registered buffer.
Find below the `_IORING_OBJECT` and the `_IOP_MC_BUFFER_ENTRY` structure:
1
struct _IOP_MC_BUFFER_ENTRY
3
unsigned __int16 Type;
4
unsigned __int16 Reserved;
7
_IOP_MC_BUFFER_ENTRY_FLAGS Flags;
8
_LIST_ENTRY GlobalDataLink;
14
_KEVENT MdlRundownEvent;
15
unsigned __int64 *PfnArray;
16
_IOP_MC_BE_PAGE_NODE PageNodes[1];
22
_NT_IORING_INFO UserInfo;
24
_NT_IORING_SUBMISSION_QUEUE *SubmissionQueue;
25
_MDL *CompletionQueueMdl;
26
_NT_IORING_COMPLETION_QUEUE *CompletionQueue;
27
unsigned __int64 ViewSize;
29
unsigned __int64 CompletionLock;
30
unsigned __int64 SubmitCount;
31
unsigned __int64 CompletionCount;
32
unsigned __int64 CompletionWaitUntil;
33
_KEVENT CompletionEvent;
34
unsigned __int8 SignalCompletionEvent;
35
_KEVENT *CompletionUserEvent;
36
unsigned int RegBuffersCount;
37
_IOP_MC_BUFFER_ENTRY **RegBuffers;
38
unsigned int RegFilesCount;
The diagram below shows this construction in memory: `RegBuffers` is an gathering of pointers, anywhere all `RegBuffers[i]` points to a `_IOP_MC_BUFFER_ENTRY` construction holding the `Address` site that the kernel uses as the I/O target:
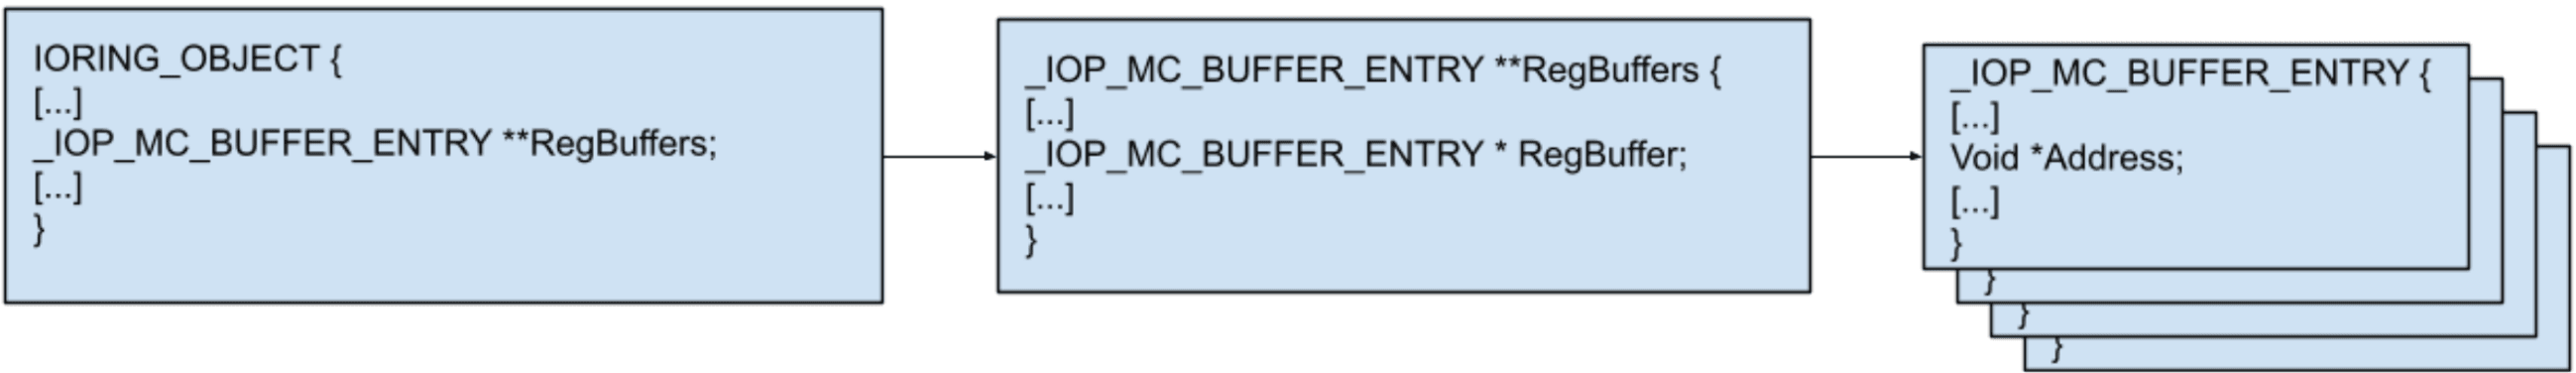
The `IopIoRingDispatchRegisterBuffers` function is liable for allocating and environment up the `RegBuffers` site of our IORing Object.
When used in a normal way, a peruse procedure using a registered buffer volition peruse the document and copy the retrieved data into the location contained in the corresponding RegBuffers admission `RegBuffers[i].Address` without checking if it's motionless valid as the inspect is lone done during registration.
Our scheme is to redirect a `RegBuffers` admission to item to a counterfeit `_IOP_MC_BUFFER_ENTRY` construction we completely authority in userland. When the kernel performs an I/O procedure using that entry, it volition dereference our counterfeit construction immediately — study the `Address` site from userland and using it as the r/w target. This is lone imaginable since Windows does not execute SMAP (Supervisor Mode Access Prevention), which would alternatively forestall the kernel from dereferencing a pointer into userland memory.
With this counterfeit admission in place, the two IORing operations rotate into our r/w primitives:
`IoRingReadFile` says from a document and writes into `RegBuffers[i].Address` — making it our arbitrary kernel write:

`IoRingWriteFile` says from `RegBuffers[i].Address` and writes into a document — making it our arbitrary kernel read:

Concretely: to execute an arbitrary kernel compose to location X, set the `Address` site of the counterfeit `BufferEntry` to X and present an `IoRingReadFile` procedure — the kernel copies the peruse data immediately into the recollection at X. To peruse from location Y, set `Address` to Y and present an `IoRingWriteFile` procedure — the kernel says from Y and writes the data to the output file, which we recover from userland. In the two cases, updating the `Address` site in our userland-resident counterfeit admission is all that is needed to redirect the operation.
Spray explanation
The size of a `RegBuffers` allocation is N × 8 bytes for N registered buffers, definition it can autumn in either the LFH or the VS backend depending on the chosen N. For this display we picked a value of N that places the allocation in the LFH, which is adequate to display the effect of the technique. Since the LFH randomises slot choice inside its subsegments, exact placement is not imaginable — the scheme is hence to flood the pond alongside a ample figure of `RegBuffers` allocations so that, following freeing a subset, the probability of our overflowing buffer landing neighboring to a live one is elevated adequate to be reliable.
We choose N registered buffers specified that the `RegBuffers` allocation falls in the identical pond bucket as our overflowing `_UNICODE_STRING` buffer (allocated at `Length + 16` bytes). This ensures the freed `RegBuffers` holes are exactly the correct size to obtain our overflowing allocation, making adjacency reliable.
To attain a province anywhere our heap overflow lands on a `RegBuffers` allocation, we use the following spray strategy. The setup is minimal: one IORing entity is required per `RegBuffers` construction we desire to position.
The spray itself is straightforward: we allocate a ample figure of `RegBuffers` structures, liberated a subset of them to create holes of the correct size, afterward trigger the exposure to district our overflowing allocation in one of those holes and corrupt an neighboring entry.
This is how it looks in memory:
1. Allocate a ample figure of `RegBuffers` structures

2. Deallocate several of them

3. Allocate our unicode string

4. Trigger the misconduct at the identical time

From there we have a corrupted `RegBuffers` admission — the heap overflow has succeeded and our arbitrary r/w primitive is in place. The next stage is obtaining a kernel location to use as the r/w target.
Abusing IORing to get a leak
At this item we have an arbitrary r/w primitive but need a kernel location to mark — specifically our own `_EPROCESS` address, which we volition use to pilfer the SYSTEM procedure token.
The diagram below shows the province of the structures following the corruption:
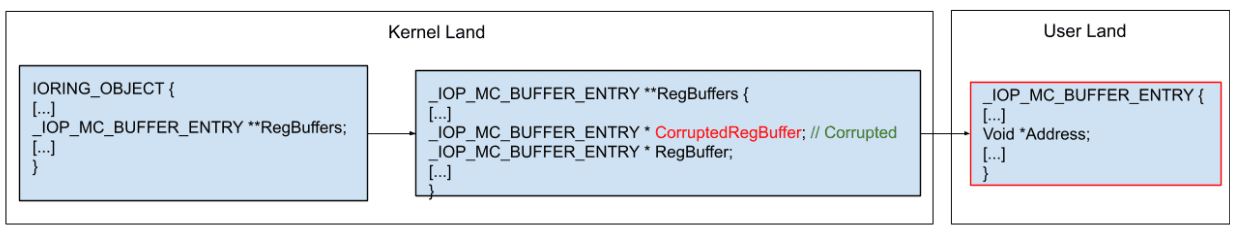
Since we corrupted the pointer inner `RegBuffers[0]` — redirecting it to a counterfeit `_IOP_MC_BUFFER_ENTRY` that lives in our own procedure recollection — we can modify the `Address` site of that counterfeit admission at any period merely by penning to it from userland. There is no need to trigger the exposure a second time.
Our arbitrary r/w primitive is operational, but it requires a mark kernel address. Since kernel addresses are randomized and cannot be predicted from userland, we need to leak one — specifically the location of our own `_EPROCESS` structure, which we volition afterward use to manipulate our procedure token.
While using our registered buffer, the location volition be mapped through an MDL. The connected MDL pointer is stored in our BufferEntry structure:
( https://learn.microsoft.com/en-us/windows-hardware/drivers/kernel/using-mdls )
1
struct _IOP_MC_BUFFER_ENTRY
A Memory Descriptor List (MDL) is a kernel construction that describes a range of virtual recollection by locking its bodily pages in place. When the kernel needs to safely run on a userland buffer — for example, to execute I/O into it — it creates an MDL for that buffer, which pins the underlying bodily pages so they cannot be paged out or remapped during the operation. Because the MDL describes a userland address, the kernel needs to track which procedure owns that memory, so the MDL stores a pointer to the owning process’s _EPROCESS construction in its Process field:
In our case, whenever the corrupted BufferEntry points to a userland location and we trigger an IORing operation, the kernel creates and attaches an MDL to our BufferEntry to map that address. Since the BufferEntry itself now lives in userland (as a outcome of our corruption), we can merely peruse its Mdl site immediately from our process. We afterward use our arbitrary peruse primitive to dereference that MDL pointer and extract the Process site — giving us a valid _EPROCESS pointer for our process, which is all we need to continue alongside the privilege escalation.
The leak proceeds in four steps:
(1) `RegBuffers[0]` now points to our counterfeit `_IOP_MC_BUFFER_ENTRY` at a known userland address.
(2) We trigger an IORing procedure — the kernel creates an MDL for our userland buffer and writes its pointer into our counterfeit entry’s `Mdl` field.
(3) Since the counterfeit admission is in our own procedure memory, we peruse the `Mdl` pointer immediately from userland without any kernel primitive.
(4) We set the `Address` site of our counterfeit admission to that MDL address, trigger another operation, and peruse the `Process` site from the MDL — giving us a valid `_EPROCESS` pointer.
Issues
At this item we have the two an arbitrary read/write primitive and a kernel location leak. Before hearing to the privilege escalation, however, we need to repair the corrupted province — releasing the IORing entity without cleanup volition collision the system.
ProcessBilled
During our overflow, we corrupted an crucial site in the pond chunk header: the `ProcessBilled` field, which stores a pointer to the procedure liable for the allocation. If remaining uncorrected, this volition trigger a blue display whenever the chunk is freed.
The ProcessBilled value is an obfuscated pointer to an `EPROCESS`, this value is computed as follows:
`@EPROCESS ^ ChunkAddress ^ ExpPoolQuotaCookie`
`ChunkAddress` is the location of the corrupted pond chunk header, located at a known negative offset before the `RegBuffers` pointer we already know.
`ExPoolQuotaCookie` is a earth kernel value used to obfuscate pond billing pointers; to get it, we use a second uncorrupted IORing object.
Via our arbitrary read, we peruse its `RegBuffers` location from the `_IORING_OBJECT` and the `ProcessBilled` value from the preceding pond chunk header. Since we cognize our `_EPROCESS` address, we reverse the formula: `Cookie = EPROCESS ^ ChunkAddress_clean ^ ProcessBilled_clean`.
We afterward compute the accurate `ProcessBilled` for the corrupted chunk and compose it rear using our arbitrary compose primitive.
With the equation in hand, the remaining stage is locating the corrupted IORing entity itself in recollection so we can use the fix.
We find the IORing entity by parsing our procedure grip table, established in the `_EPROCESS` structure, following the identical logic as `ExpLookupHandleTableEntry` to recover the grip array entry, afterward using the identical equation as in `ExGetHandlePointer` to change it into an entity pointer.
Buffer Entry reference
When we get our leak, a citation to our buffer admission located in userland is stored in the kernel which volition guide to a collision whenever the kernel attempts to procedure it during teardown.
The fix is to publish the `RegBuffers` registration. This causes the kernel to spotless up the connected MDL as part of teardown, resolving the lingering reference. Releasing the MDL immediately would not be adequate — the MDL publish is a consequence of releasing the `RegBuffers` entry, not a standalone action. However, releasing the registration triggers another issue, covered below.
Free person buffer
As we have corrupted a buffer entry, the kernel volition try to publish our userland pointer whenever decision the object.
The resolution to this matter is to merely addition the citation figure of our counterfeit buffer entry.
This prevents the kernel citation figure from always reaching zero during IORing teardown, so the corresponding publish function is never invoked on our userland pointer.
1
struct _IOP_MC_BUFFER_ENTRY
Abuse Arbitrary R/W to get additional privilege
To escalate our privileges, we pilfer the SYSTEM procedure token. Using our arbitrary peruse primitive, we stroll the `EPROCESS` doubly-linked catalog to find the SYSTEM procedure admission and peruse its `Token` field. We afterward use our arbitrary compose primitive to overwrite our own `EPROCESS` `Token` site alongside the SYSTEM token value, granting our procedure SYSTEM-level privileges.
Conclusion
In this article we demonstrated a complete local privilege escalation utilize against an up-to-date Windows 11 system, leveraging CVE-2025-13032 — a double-fetch exposure in Avast’s kernel driver. Starting from a controlled heap pond overflow in PAGED_POOL, we used the RegBuffers gathering of the IORing entity as our misconduct target, turning a sole overwritten pointer into an arbitrary kernel read/write primitive. From there, we leaked an _EPROCESS pointer via the MDL attached to our corrupted BufferEntry, repaired the pond allocation header to evade a collision on teardown, and completed the privilege escalation by stealing the SYSTEM procedure token.
CVE-2025-13032 has since been patched. We advance all users to justify their Avast facility is up to date. The complete disclosure timeline is detailed in Part 1 of this research.
If you missed the archetypal part of this research, which covers the exposure finding and sandbox escape, you can discover it here: CVE-2025-13032 — Entering and Breaking the Avast Antivirus Sandbox (Part 1).