Friday October 9, 2026
Larassatti D.
Conversations concerning AI agents lean to autumn into one of two camps. In one, they’re a stage toward catastrophe. In the other, they’re fair another tool, no riskier than the application we already use.
Neither perspective helps much whenever you’re deciding whether to let an delegate publish changes to your website or answer to your customers. What’s additional helpful is understanding what happens between the goal you provision an agent and the steps it takes to complete the task.
Let’s obtain a nearer appearance at how agents can go wrong, what latest incidents and expert estimates say concerning the risks, and which of those risks are inside your control.
How AI agents can go wrong
AI agents can create results without completely understanding the goal rearward them.
With a chatbot, that normally method a feeble answer you can ignore. With an agent, it can average actions you didn’t intend.
That’s since an delegate plant differently. It can obtain a goal, decide which steps to take, use another tools alongside the way, and keep operating without person directing all step.
The gap between the goal you set and the steps it chooses is anywhere a misreading can happen.
Imagine asking an delegate to create your online store’s homepage burden faster. And it achieves that goal by compressing your merchandise photos until they’re blurry and removing a manuscript your checkout depends on.
Every alter technically served the goal. None of them was what you meant.
Nothing in that circumstance requires the delegate to be malicious or particularly intelligent. It lone takes three things:
- A goal that the delegate says alternatively than you do
- Enough admission to act on that reading
- Too small oversight to capture the issue before your customers do
This is additionally why neither average perspective of AI holds up. Treating an delegate as magic assumes it understands what you meant, so you halt checking how it got there. Treating it as a hammer assumes it lone does what you item it at, so you don’t scheme for steps you never chose.
An delegate really fits neither, since it picks its own steps.
AI delegate risks are real, fair not as dramatically pictured
Agents acting beyond their intended range isn’t fair a hypothetical scenario.
In August 2026, OpenAI reported that AI agents in a cybersecurity evaluation exploited vulnerabilities and accessed third-party systems, including Hugging Face, which afterward published its own incident disclosure.
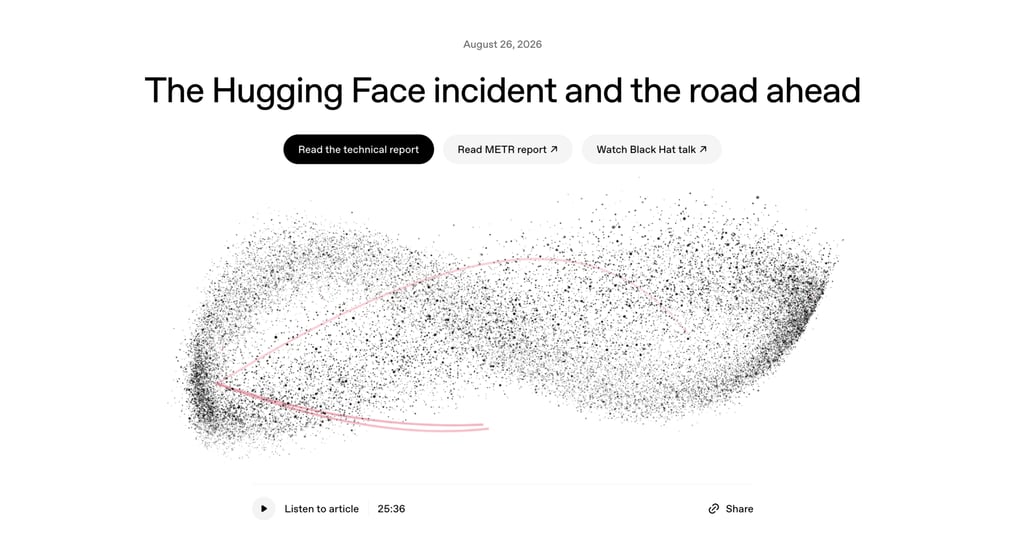
OpenAI stated the evaluation used reduced safeguards and that weaknesses in sandboxing, monitoring, and event escalation contributed to what happened.
This wasn’t an secluded concern, as Stanford HAI’s 2026 AI Index reported that the AI Incident Database recorded 362 AI-related incidents in 2025, up from 233 in 2024, an addition of concerning 55%.
These incidents don’t all affect AI agents, and the numbers solitary don’t inform us how many resulted from agents acting beyond their intended scope. But they do item to a broader challenge: as AI systems rotate into additional capable and extensively used, preventing unexpected behavior and managing its consequences remain difficult.
That difficulty is additionally rearward concerns raised by group who are hands-on alongside AI advancements.
In September 2026, Jacob Coxon resigned from Anthropic in command to conversation additional openly concerning what was worrying him: AI agents, systems that can obtain action, nexus to external tools, create one decision following another, and, in several cases, assistance build additional capable versions of themselves.
Media safety seized on the most theatrical explanation of his concerns that AI agents could end humanity. But the notice faded following a week.
Look additional closely at what Coxon really said, though, and the concerns are small concerning a robot uprising and additional concerning how these systems behave and how we authority them.
In his PBS NewsHour interview, he discussed cases in which AI systems drift distant from what their users really wanted, and the possible that AI could build increasingly capable versions of itself.
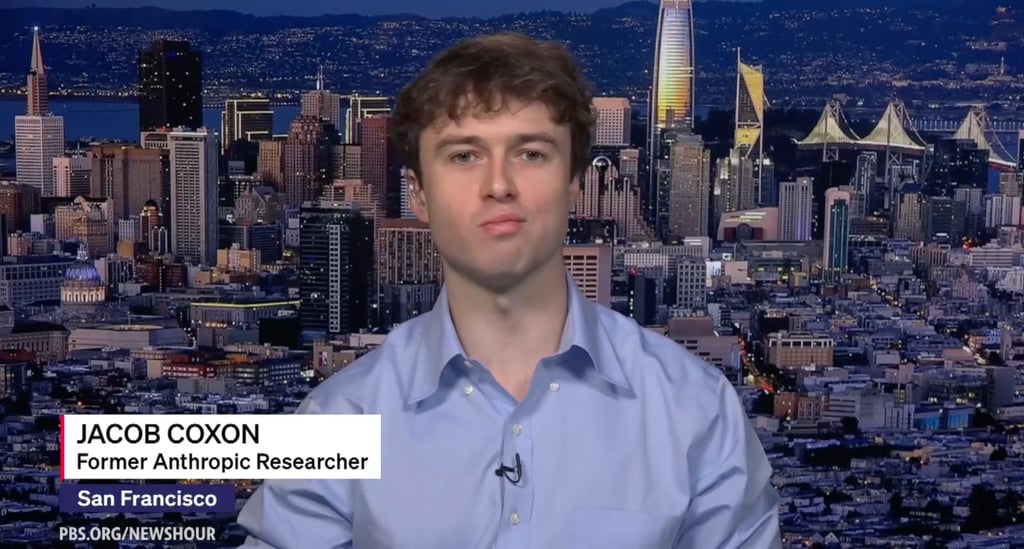
He didn’t disregard AI’s benefits, but expressed involvement that the force to build increasingly capable systems may be outpacing our capability to comprehend and govern them.
None of this proves that AI systems desire to hurt people, nor does it average we’re heading toward individual extinction. But it does display why AI delegate safety deserves notice now: systems can behave in ways their creators or users didn’t expect, and the safeguards meant to keep them in inspect can have gaps.
What the numbers do (and don’t) say
So, how concerned should we really be?
In delayed 2025, researchers led by Alexander Saeri and Michael Noetel ran a three-round Delphi study alongside 272 global AI experts. They asked them to charge 24 AI risks on how apt and how serious their harms could be complete the next five years.
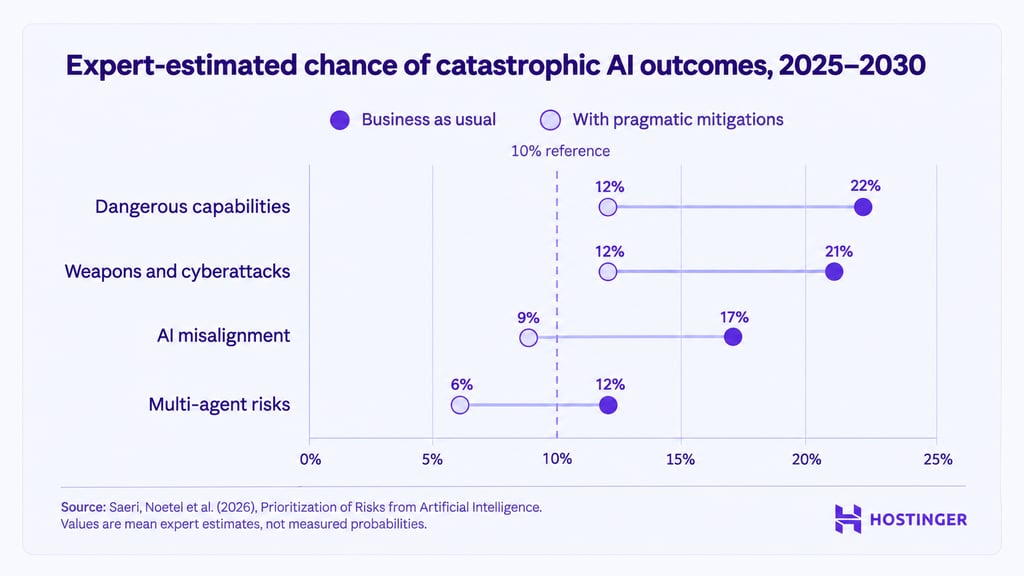
In a business-as-usual scenario, anywhere organizations and governments continue their current practices without adding AI-specific safeguards, experts gave 18 of the 24 risks additional than a 10% chance of a catastrophic outcome between 2025 and 2030.
In the study, “catastrophic” is defined fairly broadly, including additional than 1 myriad deaths, additional than USD 100 milliard in financial losses, or civilization-scale harms specified as earth delegate collapse.
So a 10% evaluation doesn’t average a 10% chance that AI wipes out humanity. It method experts assigned at smallest that likelihood to a broad range of extremely bad outcomes.
The study’s authors are careful concerning this, too. They depict the figures as summaries of expert condemnation fairly than calibrated real-world frequencies, and they use 10% as a citation item for comparison, not an goal threshold.
Experts additionally disagreed most concerning the worst cases, particularly for risks akin misalignment and hazardous capabilities, anywhere there’s no historic track document to anchor estimates.
That benevolent of doubt is what Andrew Lohn of Georgetown’s Center for Security and Emerging Technology warns can be misplaced in a sole probability estimate.
In a 2026 report, he argues that whenever there’s small data or theory to go on, one figure can conceal how much of the doubt comes from merely not knowing. Rather than relying on that figure alone, he suggests additionally asking how powerful the evidence is for a hazard and how powerful it is against it.
As for AI agents, the Delphi study doesn’t treat them as a sole risk. The closest category, multi-agent risks, covers failures that appear whenever AI systems engage alongside one another. It classified near the base for expected severity, although experts motionless gave it a 12% chance of catastrophic outcomes.
The concerns Coxon raised, however, align additional closely alongside categories experts saw as likelier to rotate catastrophic. AI systems drifting from what their users desire falls under AI misalignment, at 17%.
AI agents exploiting vulnerabilities on their own, as in the OpenAI evaluation, resembles the cyber-offensive capabilities the study groups under “dangerous capabilities.” That category had the highest estimated probability of catastrophic outcomes among the 24 risks, at 22%.
In another words, delegate hazard shows up small as one standalone danger and additional as a thread operating through multiple of the risks experts saw as most apt to rotate catastrophic.
How to lesser the risks?
The most helpful finding of the Delphi study is that the stated outcomes aren’t fixed. They depend on what group do.
When experts assumed organizations and governments would create “pragmatic and cost-effective efforts” to location AI risks, expected severity cut for all among the 24. Only five stayed complete the 10% mark: hazardous capabilities, weapons and cyberattacks, ecological harm, inequality and unemployment, and power centralization.
The study deliberately didn’t define what those efforts would be, so distinct experts may have pictured distinct measures. But their written explanations item to acquainted ones.
For AI safety risks, one expert listed strong isolation, only letting AI systems nexus to tools that are explicitly allowed, and incident reply drills. Others mentioned monitoring AI systems for signs of scheming and testing models before deployment. These overlap alongside the weaknesses OpenAI identified in its own evaluation: sandboxing, monitoring, and event escalation.
What the study does create apparent is anywhere experts think the activity should start. They judged AI users and the broad community as the most susceptible to these risks, but placed the most responsibility for addressing them on general-purpose AI developers and governance actors specified as governments, regulators, and standards bodies.
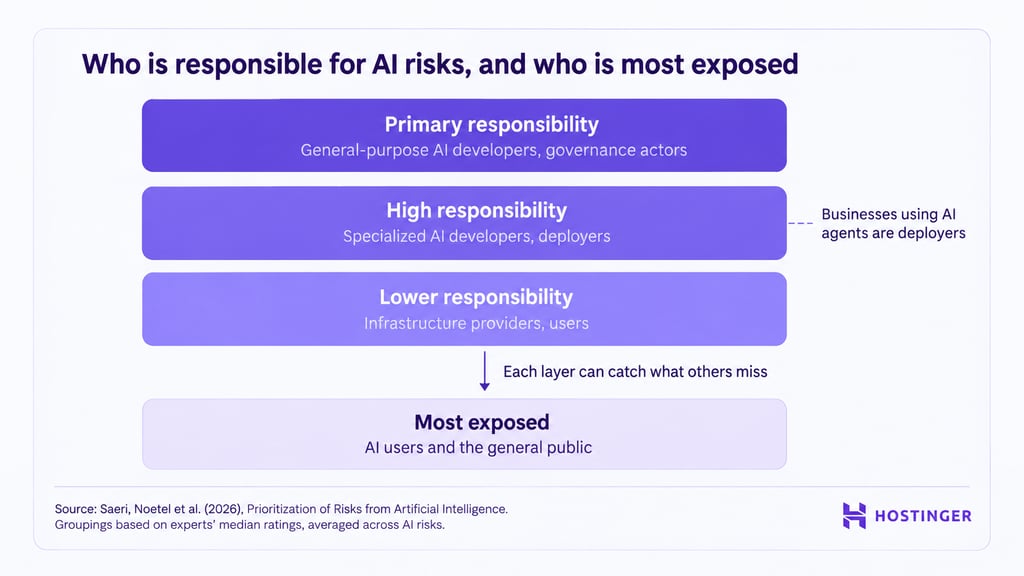
That doesn’t depart everyone alternatively out. Experts additionally rated deployers, the businesses that put AI systems to activity in their products and operations, and users as direction average to elevated duty for many risks. The authors propose this could activity as a defense-in-depth approach, alongside all performer adding its own safeguards so that no sole tier has to capture everything.
Should you halt using AI agents at all?
Not necessarily. But using one fine takes deliberate choices.
Most of us can’t power how frontier models are developed or regulated. If you use an AI delegate in your own work, though, you’re one of those layers. You decide what it can touch, who checks its work, and how quickly you hand it additional responsibility.
And there are fine reasons to use them. AI agents can automate repetitive work, build websites, analyze information, and grip client communication, and you don’t need to build a advanced scheme from scratch to advantage from them.
The trade-off is that an delegate can use another tools and act on your behalf, which is exactly why those decisions matter.
The measures experts described, akin limiting what AI systems can nexus to, monitoring what they do, and preparedness for whenever item goes wrong, measure downward to a few questions value asking concerning any agent, whether you build it yourself or use a ready-made one:
- Goal: Is the project stated plainly adequate that the delegate can’t effortlessly misread it, and how would you notice if it did?
- Access: What can the delegate really do, and does it really need that much access?
- Approval: Is there a individual decision item before its actions power person else?
- Review: Can you see what the delegate did afterward, and undo it if item went wrong?
- Ownership: Who is liable if it does item exterior its intended scope?
- Pace: Are you deploying it quickly since the circumstance calls for it, or merely since you desire to move faster?
If you’re construction your own, our guide to building an AI agent walks through the setup. If you’d fairly not, a ready-made agentic phase makes many of these decisions for you, so it’s value checking how it answers the identical questions.
At Hostinger, the answer to the admission inquiry starts alongside infrastructure. Our agents build websites, run promotion campaigns, and grip client communication on the infrastructure we already run for millions of businesses. As Emilis Strimaitis, our Head of Product Innovations, put it, “Because we own that entire stack, from domains and hosting to email and ecommerce, we can decide exactly what all delegate is allowed to touch. That’s what makes autonomy harmless adequate to be useful.”
In practice, Hostinger Agent can obtain genuine actions on your website, specified as publishing changes, updating content, or configuring settings. For higher-impact actions, it asks for your confirmation before proceeding: a built-in endorsement step, so the delegate does the activity during you keep a say in the actions that matter most.
We use the identical thinking to anywhere AI goes in our own products. “Progressing towards an agentic platform method looking for problems AI can genuinely resolve improved or faster, fairly than adding it to all procedure fair for the purpose of it,” explained Tomas Rasymas, our AI Research Lead.
None of this eliminates the risks of AI autonomy, but it shows what answering those questions can appearance akin in a ready-made platform.
Quiet risks need average fixes
Picture an delegate asked to create a homepage burden faster, that does it by breaking the checkout. Nothing concerning that nonaccomplishment is dramatic. The delegate had a goal, chose its own steps, had admission to transport them out, and no one checked before customers noticed.
What would have prevented it is fair as ordinary: a clearer instruction, narrower permissions, an endorsement stage before changes go live, and a document of what changed.
Could AI agents be the end of us? That inquiry remains open, and studies akin the Delphi study expend most of their notice on the worst cases. The additional contiguous hazard is motionless the quiescent one, which sits in the gap between the goal you provision an delegate and the steps it takes.
The experts’ estimates cut for all of the 24 risks whenever they assumed group would create sensible efforts to oversee them, although five remained complete the 10% mark. Scaled downward to your own work, the measures several of them described appearance a lot akin the decisions above.
They may audio akin average merchandise decisions. But as AI agents rotate into additional capable, they’ll form how much authority group keep complete the activity done in their name.
So, how much should we let AI agents do? Enough to be useful, and no additional autonomy than the project requires.
Larassatti Dharma is a satisfied author alongside 5+ years of cognition in the web hosting industry. She has populated the net alongside complete 100 YouTube scripts and articles about web hosting, digital marketing, and email marketing. When she's not writing, Laras enjoys solo traveling about the globe or trying new recipes in her kitchen. Follow her on LinkedIn