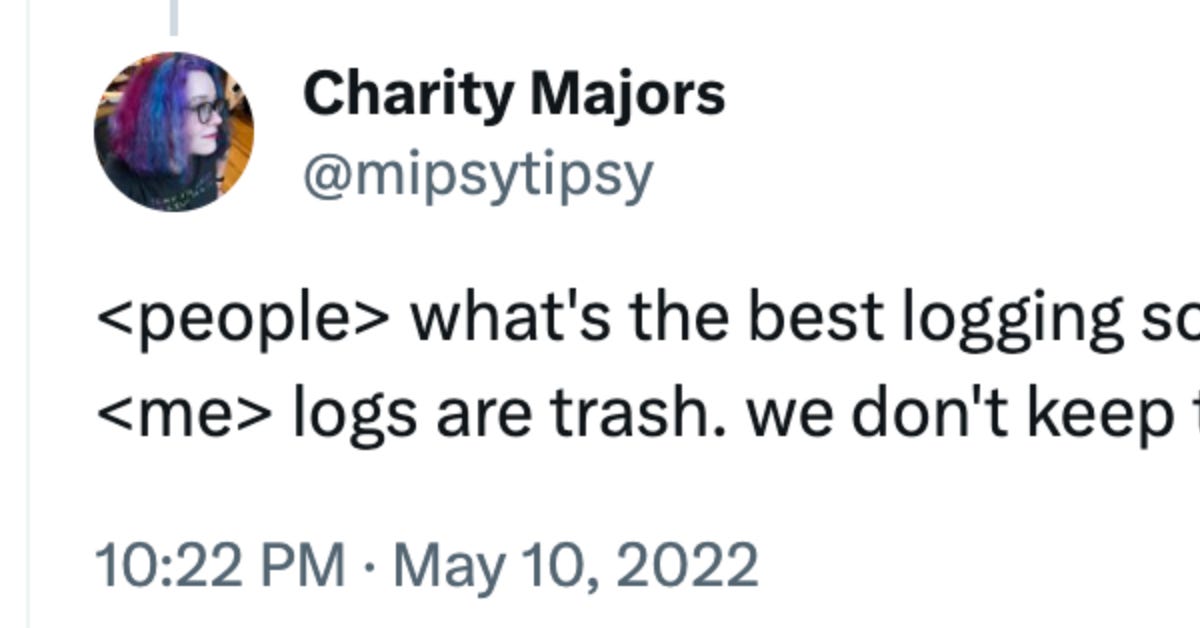

This citation from Charity Majors is likely the finest summary of the current province of observability in the tech industry - a total, bulk confusion. Everyone is confused. What is a trace? What is a span? Is log row a span? Do I need traces if I have logs? Why I need traces if I have awesome metrics? The catalog of questions akin these goes on. Charity - together alongside another awesome folks from observability scheme called Honeycomb - have been doing a awesome job shedding ray on these questions. Yet, per my own cognition it’s motionless extremely difficult to explain what does Charity meant by “logs are thrash”, let solitary the fact that logs and traces are basically the identical things. Why is everyone so confused?
With the hazard of being spicy a little, I’m going to accuse Open Telemetry. Yes, it’s powering the contemporary observability stack and yet I accuse it for the bulk confusion. Not since it’s a bad resolution - it’s great! But the display and the entire method of explaining what Open Telemetry is and what it does makes the observability appearance tricky and complex.
First, Open Telemetry from the extremely commencement makes a apparent distinctions between traces, metrics and logs:
OpenTelemetry is a gathering of APIs, SDKs, and tools. Use it to instrument, generate, collect, and export telemetry data (metrics, logs, and traces) to assistance you analyze your software’s achievement and behavior.
Then it goes deeper in explaining all of these 3.

This is screenshot from the part of open telemetry website introducing traces. Based on my cognition talking to group who activity alongside OpenTelemetry, this display has certainly rotate into among the chief pictures being connected alongside observability. For some, this IS the observability. And it additionally sets traces distinct from item else. This is apparent not a log, is it? This additionally doesn’t appearance akin a metric, right? It’s item special, probably a bit sacred, and requiring learning investment. Per my experience, formerly group learned concerning traces, they lone think concerning them in the environment of this image and the entire set of conditions akin spans, base spans, nested spans and the rest. OpenTelemetry location has a glossary leaf alongside additional than 60 terms! This all is insanely complex!
But what’s additional crucial - does this concentration on “logs, metrics and traces” portray the true power of observability? It does shield several scenarios that’s true, but whenever it comes to the distributed systems at measure what’s additional crucial is an capability to “dig” into data - “slice and dice” it, build and analyze assorted views, correlate, hunt for anomalies… And systems that recommendation all of this do exist.
When I was operating at Meta, I wasn’t conscious that I was privileged to be using the finest observability scheme ever. This scheme is called Scuba and it’s the top 1 item by a ample border that group young female whenever they depart Meta.
The essential idea of Scuba is extremely uncomplicated and doesn’t necessitate a glossary leaf for group to grasp. It operates alongside Wide Events. Wide Event is fair a gathering of sectors alongside names and values, beautiful much akin a json document. If you need to document several data - whether it’s the current province of the system, or an event caused by an API call, backdrop job or any - you can fair compose several Wide Event to Scuba. For instance, if a scheme serves ads, the natural desire would be to document Ad Impressions - the facts that a certain ad has been seen by a user. The corresponding Wide Event power be looking akin this:
{ "Timestamp": "1707951423", "AdId": "542508c92f6f47c2916691d6e8551279”, "UserCountry": "US", "Placement": "mobile_feed", "CampaingType": "direct_ads", "UserOS": "Android", "OSVersion": "14", "AppVersion": "798de3c28b074df9a24a479ce98302b6", ... }Such events called wide, since it’s encouraged to dump to them all the data one can think of. Anything that power be applicable in the environment of a certain data - fair put it there, it power be helpful later. This method is laying the groundwork for dealing alongside unknown unknowns - item you can’t think of now that may be revealed afterward during an event investigation.
Dealing alongside unidentified unknowns can be improved demonstrated on an example. Scuba has a nice intuitive interface which is uncomplicated to examine and perform with. It has a division anywhere one can choice a metric to appearance at, as fine as sections for filters and groupings - and Scuba would diagram a nice period sequence chart. Firs appearance for Ad Impressions dataset would merely diagram a diagram alongside impressions count:

If we province what’s exactly is selected current in conditions of SQL, afterward this is item like
SELECT COUNT(*) FROM AdImpressions WHERE IsTest = False
Well, it’s really not exactly akin that. Scuba additionally has a idea of native sampling. When a certain event is written to Scuba, it additionally must compose a site called samplingRate - the charge this particular event is being sampled with. Scuba uses this data to correctly “upscale” results shown on the charts, so there is no need to do this upscaling in the head. This is a really awesome idea since it allows a energetic sampling - e.g. several category of impressions may be sampled additional than another, during preserving the “real” values in the UI. So, the genuine query under the hood is
SELECT SUM(samplingRate) FROM AdImpressions WHERE IsTest = False
Note that this entire “upscaling” is done transparently by the UI and users don’t think concerning it during querying.
And so assume several vigilant happened and indicated that our precious Ad Impression diagram is looking weird:

The archetypal intuition of everyone who’re using Scuba for inquiry is to “slice and dice”, ie display or collection by, to see if we can study something. We don’t cognize what we’re looking for, but we accept that we’ll discover it. So we would collection by say belief type, or person country, or the placement, until we would discover item suspicious. Let’s assume it’s CampaignType grouping:

We see that several run category called in_app_purchases (just in case desire to note that this category name is entirely made-up by me) seems to appearance alternatively than others. We don’t really cognize that does it average - we don’t need to! - to continue our digging. Okay, now we can display these campaigns only, and continue grouping by item alternatively we can think of. For instance, User OS makes sense.

Hmmm, Android seems to be in trouble. iOS is OK, which suggests that the issue is on the client flank - a damaged app type maybe?

Weird. Some are suffering, several others don’t. Check OS Version maybe?

Ha! It’s the newest type of the OS, and looks akin several of the app versions are not doing fine on this OS type for this category of campaign. The dedicated teams may appearance deeper now, stated this information.
What happened? Without any cognition of the scheme we’ve narrowed downward the range of the issue, and identified the teams to obtain a guide for additional investigation. Could we cognize ongoing that this weird blend of OS, OS Version, Campaign Type and App Version power guide to several issue, to have a dedicated metric prepared? Of way no. This is an example of dealing alongside unknown unknowns. We’ve fair dropped all the applicable environment into Wide Events, and used it afterward whenever needed. Scuba made it uncomplicated to do the exploration since it’s accelerated and has a really nice easy-to-use UI. Also note that we have never mentioned item concerning cardinality. Because it doesn’t matter - any site can be of any cardinality. Scuba plant alongside raw events and doesn’t pre-aggregate anything, and so cardinality is not an issue.
Sometimes UI / Visualisation aspect doesn’t get adequate attention, and observability systems recommendation several query tongue - either a proprietary (bad-bad-bad), or SQL (slightly better, but motionless bad). Such an interface makes it near to unattainable to behavior akin investigations. One crucial aspect of Scuba that all the sectors - function, filter, grouping, etc. - are explorable. Meaning that there is an uncomplicated way to see what benevolent of values we can pick. When the owners of a certain site are not lazy, they equal included a detailed clarification for the stated site alongside applicable links etc. This is huge. I have successfully investigated a lot of incidents myself, without complete understanding of either the entire system, or the data accessible in this dataset. And boy I did study a lot concerning the scheme during these investigations, merely via playing about alongside Scuba! This was amazing. This was observability paradise.
Now ideate my flat of disturbance and disbelief whenever I remaining Meta and got to cognize the province of observability systems outside.

Logs? Traces? Metrics? What the hell? Wide Events, anyone? Can I delight not study that 60 conditions from the Glossary and fair … examine stuff?
It took me fairly a during to map my Scuba-based mental example to Open Telemetry mental model. I realised that Open Telemetry’s Span is, in fact, the Wide Event. Actually, I’m motionless not fairly certain I got it right:

If we obtain AdImpression example, this belief is not really an operation, it’s fair several fact we desire to record… To be fair, there is several notion of Event in Open Telemetry:

But if we prosecute the links to dig deeper, we again discover out that Event is in fact one of Traces, Metrics or Logs 🤷

But anyway, Span is the closest idea to Wide Event. The item is - it’s extremely difficult to protagonist for this mental example whenever the one suggested by Open Telemetry is already learned. Which is really upsetting, since Traces, Metrics and Logs are all fair particular cases of Wide Events really:
Traces and Spans: These are fair broad events having SpanId, TraceId and ParentSpanId fields. So we can display all spans alongside a stated TraceId, topologically kind them using SpanId → ParentSpanId relation, and diagram that distributed tracing perspective everyone loves.
Logs: Honestly, I’m really confused what Open Telemetry method by Logs. Looks akin a lot of things, and one of them is Structured Log which is beautiful much the Wide Event. Great! The problem, however, that “a log” is fairly a defined concept, and normally group average by it is what is produced by those logger.info(…) calls. Anyway, any is meant, logs can be effortlessly mapped to broad events, of course. In the simplest case we can fair get the log message, put it to the “log_message” field, add a bunch of metadata, and be happy. In a additional complex case, we can try to automatically extract a template from a log communication via removing tokens that looks akin IDs, and get a hash of this template. This can authorize to quickly get the most common error, for instance, via grouping by this hash. Meta has specified a system, and it’s beautiful cool.
Metrics: Metrics can be effortlessly mapped, too. We fair need to emit a Wide Event formerly per several duration containing the province of the scheme (system metrics akin cpu, assorted counters,…). Prometheus, by the way, does exactly that alongside the abrasion method - takes a snapshot of the scheme formerly in a while. Unlike alongside prometheus, however, alongside Wide Events method we don’t need to concern concerning cardinality.
But Wide Events can recommendation much much additional than these “3 pillars”. The aforementioned debugging meeting is already a case which is not really covered by Traces, Logs and Metrics - not naturally, at least. There could be another use cases, too - for instance, uninterrupted profiling data can be effortlessly represented as a Wide Event, and queried to build a Flame Graph. No need to have a distinct scheme for this - a sole scheme operating alongside Wide Events can do it all. Imagine the possibilities for cross-correlation & base logic inspection whenever everything in one place, stored together. Especially now, in the era of lift of AI-based tools that are beautiful fine in finding correlations in data.
I don’t know… I fair wanted to province my frustration alongside the flat of disturbance and this concentration on “3 pillars”.
I fair desire that observability vendors took a remain against confusion, and offered a uncomplicated and natural way to engage alongside the system. Honeycomb seems is doing that, as fine as several another systems akin Axiom. This is great! And anticipation the others volition follow.