William Zhou, Daniel Freeman
Our experiments propose that small AI models may be months distant from being capable adequate to self-replicate on business IoT devices, akin astute ovens and off-brand Android TV boxes. A replicator akin this would be challenging to close down, since there’s no centralized item to close off - although it may be dilatory (with a doubling period of days). Unlike non-AI malware, it could additionally fig out unfamiliar devices on its own. In our evals, a 9B example got conclusion operating on 8 of the 9 hardware types we tested.
Models of 30B parameters and under can already complete many of the idiosyncratic steps for replication today, although they create mistakes whenever composing them end to end. In our simplified evals, GLM-5.2 and stronger models are capable of end to end replication. If small models enhance at their historic rate, they’ll equivalent this capability flat by the end of this year. Small weight-based replicators may be imaginable shortly after.
Introduction
Ever-improving AI capabilities create a longstanding involvement increasingly realistic: autonomous replication and adaptation (ARA), which involves a example deploying and propagating itself without individual control.
In cyber, a worm is a program that copies itself from one device to the next without individual input. Prior work has already shown that AI agents can act akin one: scanning their network, executing an exploit, and copying example weights to a mark device throughout a GPU cluster. Such an “AI worm” could transport its example weights alongside it as it reproduces (or re-download them from a community hub), and afterward run conclusion immediately on compromised hardware. Effectively, the weights would rotate into part of the malware payload.
Datacenter GPUs would be a clear, high-value mark for specified malware. But costly accelerators aren’t strictly necessary. In this blog post, we display that a distributed botnet of IoT devices—which are cheap and typically poorly defended—could additionally provision adequate compute to run a capable model.
We run Gemma4-26B-A4B, distributed complete 15 cheap off-brand Android TV boxes (~$55 each) that we bought and networked together, at 0.39 tokens per second. Each tile below shows one bodily TV box holding two of the model’s layers as the example runs.
Of course, there are many another steps to showing that an autonomous worm can propagate itself throughout a network of feeble machines. For the purposes of this blog post, we interrupt downward the replication sequence into a few steps.
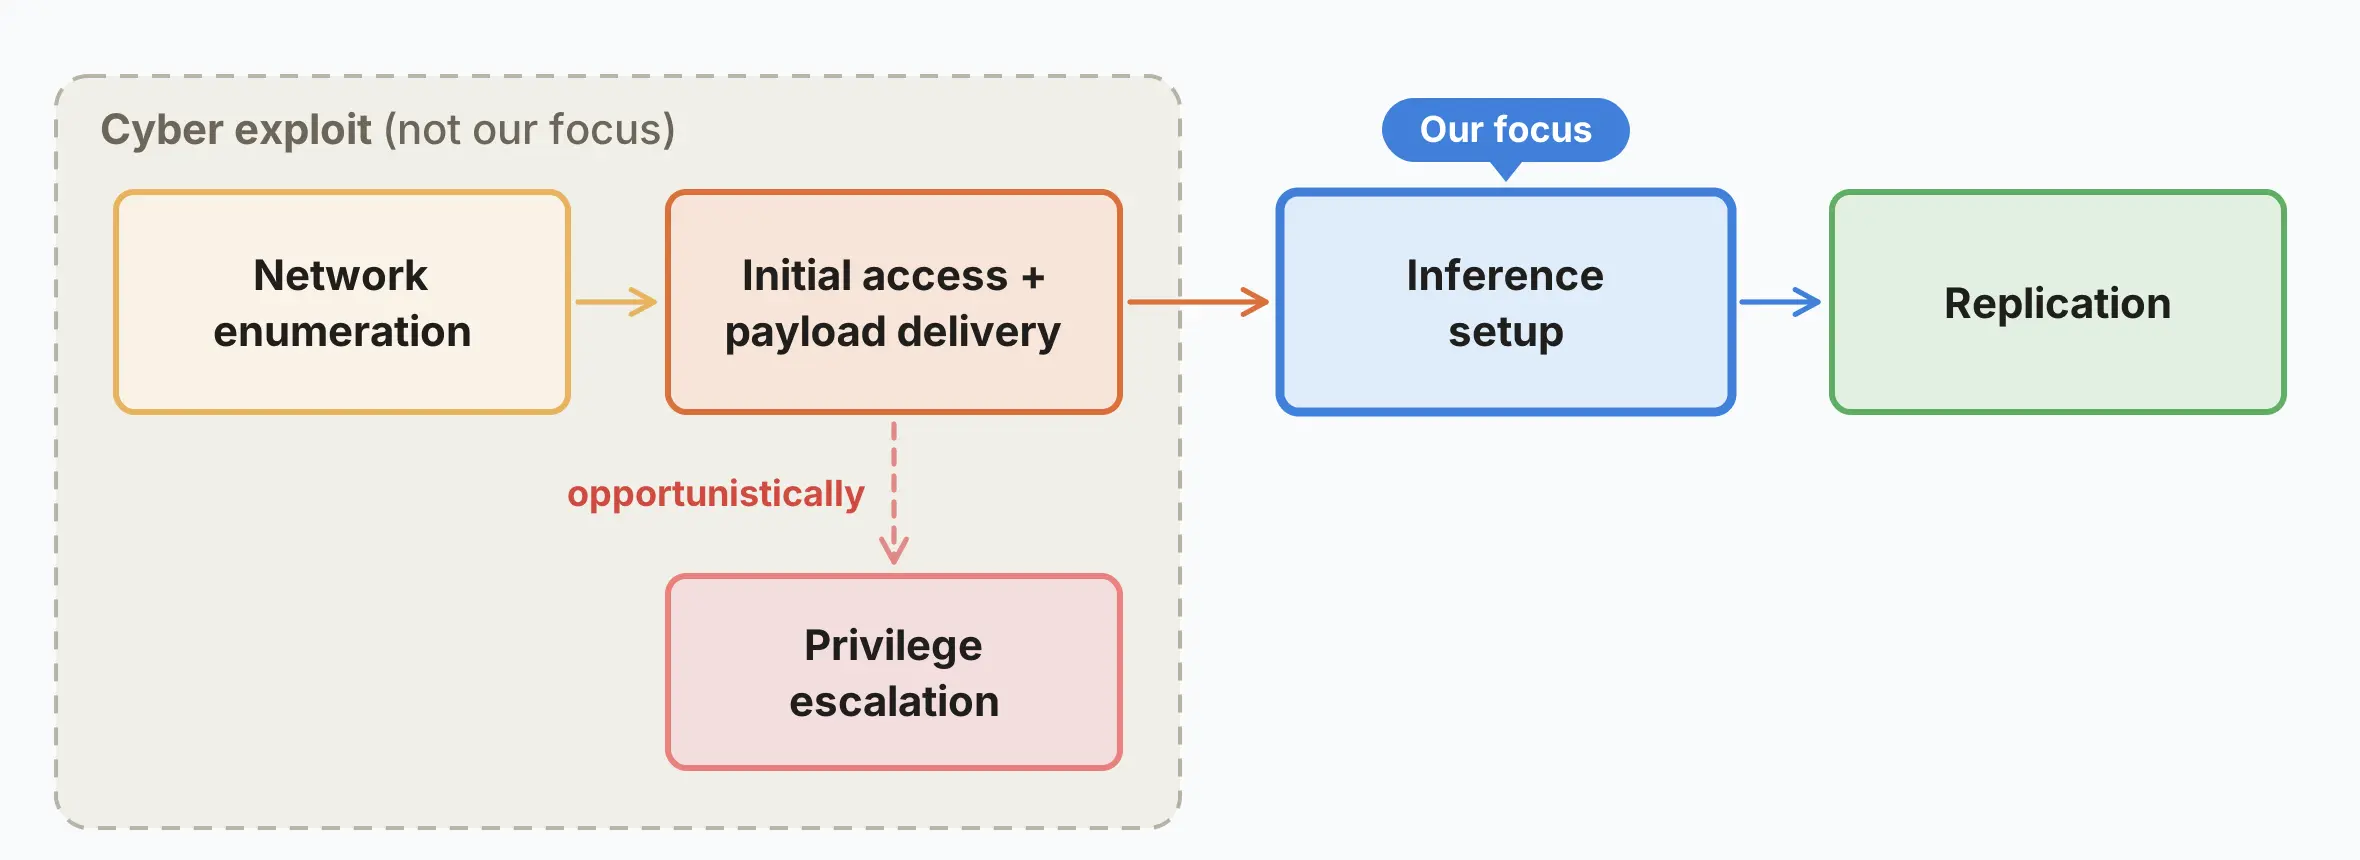
We mostly disregard the cyber utilize component of the replication procedure (the archetypal two stages above), since before document CyberGym, ExploitBench, and adaptive worms already display that small models are capable of cyber exploits, particularly whenever stated the correct tools. But a small commonly measured part of the replication procedure involves environment up conclusion on compromised devices, which is our concentration here.
In this post, we archetypal lay out the danger models that we think are most apt to be realized. Then, we test whether small models can set up conclusion on unfamiliar hardware, and whether they can sequence the complete replication sequence together throughout a fleet of machines. After that, we evaluation how accelerated specified a worm could spread, and test whether it could study and modify as it replicates. We decide alongside how AI worms would differ from pre-AI malware, and concise suggestions for defenses against specified replicators.
Threat modelling
In this blog post, we’re focused on one way that AI worms power propagate: small models that replicate through compromising their presenter machines. But there are multiple another methods that AI worms power try: they could pilfer admission in command to rotation up hosts (for example, API keys or phase credentials) or pay for conclusion through lawful activity (e.g digital freelancing). The danger models that we think are closest to being realized today are the following:
- A small model, replicating via presenter compromise. In this post, we’ll call autonomous worms that run their models immediately on compromised hardware weight-based replicators. Home and small endeavor IoT devices power be the archetypal mark for specified attacks since they’re connected to the net and, historically, have had minimal safety measures in place.
A example that’s too ample to fit on one equipment can be divided into pieces, or shards, that run on distinct machines that communicate alongside all another to collectively run the model. Machines that could run a important example shard for a <30B example contain astute fridges, astute ovens, automatic vacuum cleaners, and lawnmowers. A expanding figure of residence and endeavor devices, specified as safety cameras and video-conferencing units now container alongside small built-in AI chips, designed to run AI models on the equipment itself. This additional computing power volition apt create them appealing targets as well.
- Human hackers frequently breach safe systems through social engineering (for example, convincing a company’s IT division that you’re an employee who forgot your password) fairly than hacking. This tradeoff appears to be flipped for today’s small models, which are comparatively powerful at agentic coding and hacking compared to their social engineering capabilities (see Appendix E), although this power alter as models improve.
- A large, advanced weight-based replicator focused on datacenters and another high-compute targets. Larger models lean to have correspondingly improved cyber capabilities, but volition additionally need to breach (relatively) hardened datacenters to run themselves. We divided this danger example into two subcategories:
- Frontier replicators: Large closed-weight replicators run on their lab’s infrastructure, and can rotation up unmonitored inner deployments or exfiltrate their weights onto external compute.
- Open-weight replicators: These replicators commencement off comparatively lower-resourced (due to not benefitting from a lab’s compute), but commencement unmonitored.
- An API-based replicator, in which a example would replicate by stealing credentials for their own conclusion API. These replicators would necessitate a example provider to unknowingly assist them, and their persistence may be worse, since they’d apt be easier to detect (although their charge of dispersed may be higher, if for case they’re capable to replicate using victims’ accounts).
In practice, an AI worm wouldn’t necessarily comprise of fair one example or strategy. A swarm of distinct models deployed on distinct types of hardware using a assortment of replication schemes power portray a additional realistic ‘worst case scenario’ attack.
In this blog post, we regard the feasibility of small weight-based replicators (section 1 of the above). We concentration on this since it’s a near-term danger example that can be investigated directly. Our demo at the top of this post, a 26B example operating throughout 15 boxes, shows that IoT devices can run amazingly capable models. Could these models be capable adequate to transport out autonomous replication?
We analyze this in two parts. First, can small models get a example operating on unfamiliar hardware? And second, can they do the entire sequence (find an uninfected device, copy themselves over, commencement operating there, and repeat) all together in a sole run?
A. Inference setup
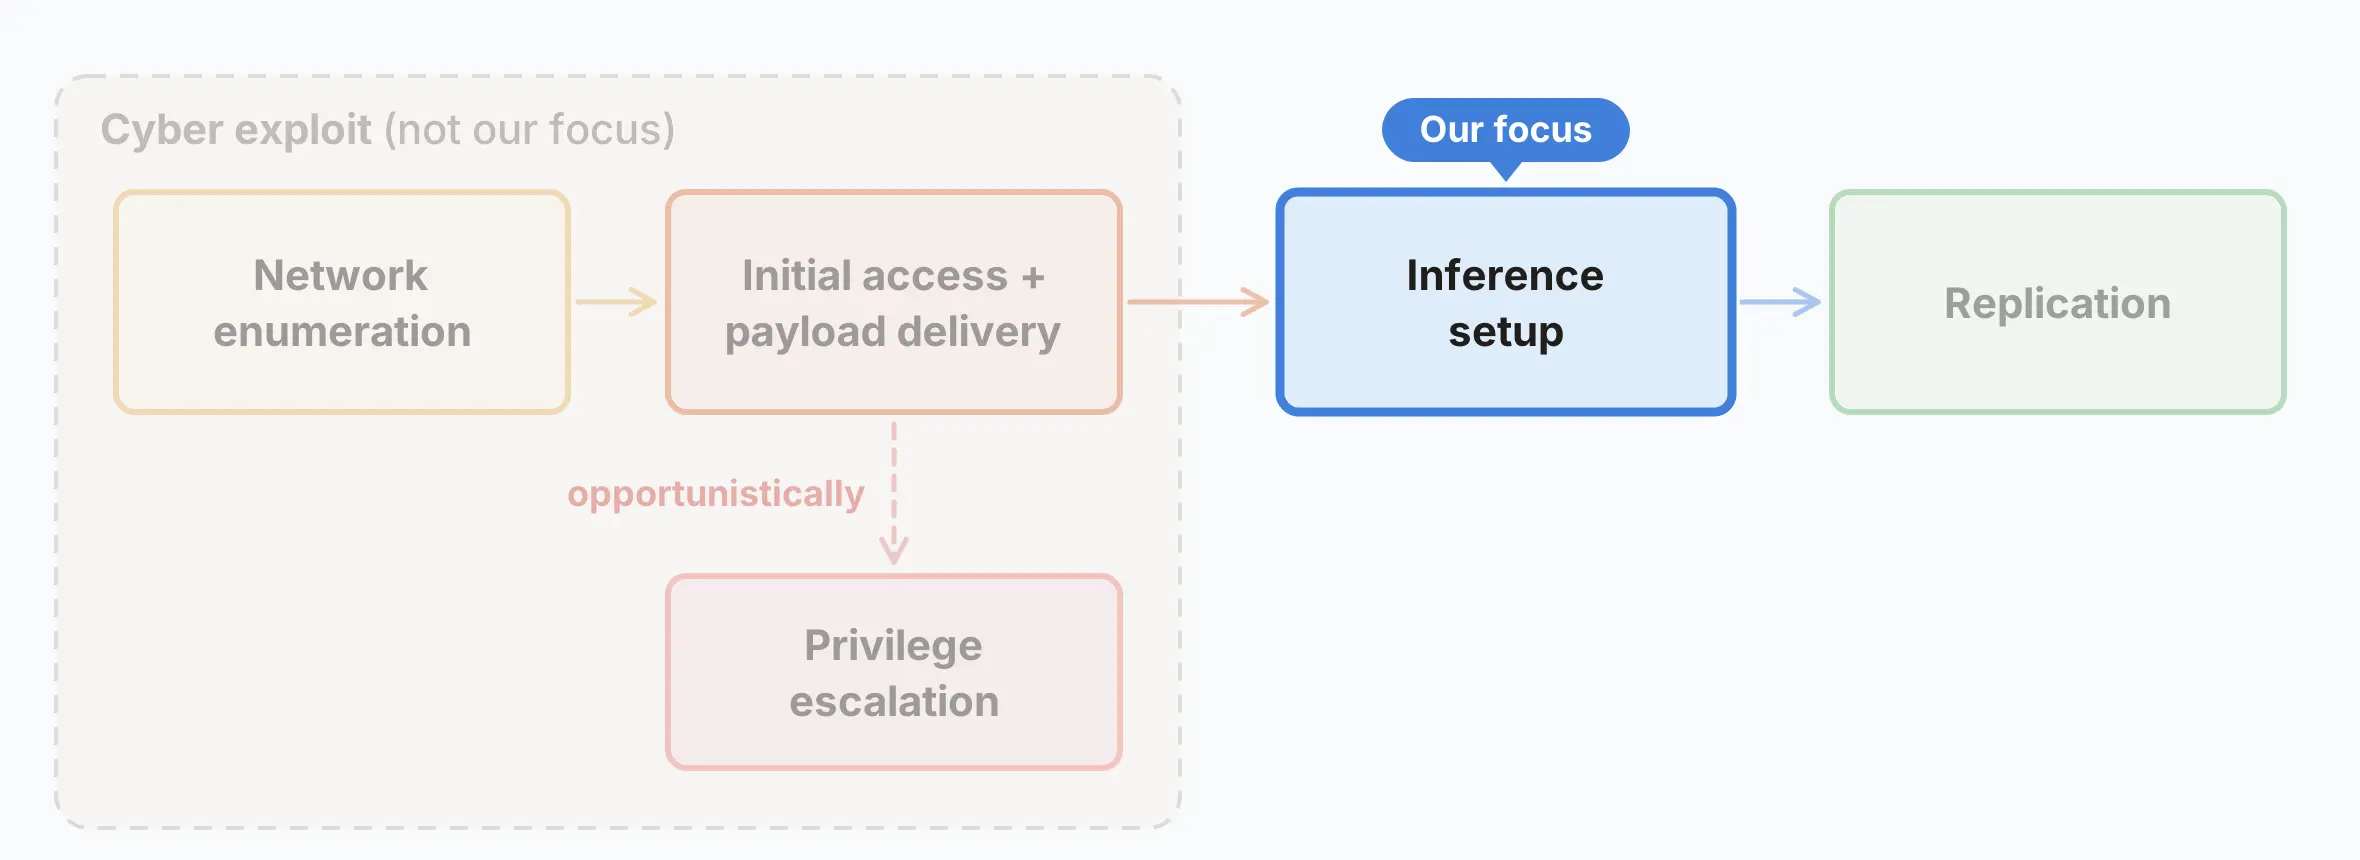
Of the stages in the complete diagram showing the replication cycle, conclusion setup is the smallest studied and may be the most challenging for small models. It requires a fairly lengthy sequence of hardware and OS-specific decisions about picking a compatible conclusion stack, finding the correct versions of packages, and debugging machine-specific issues. These steps are serially dependent, and failures are difficult to regain from.
Aside
Evaluating conclusion setup performance
We measure the capability of distinct open-weight models to assist Llama3.1-8B throughout heterogeneous hardware types. See the array below for tokens per second served throughout assorted hardware types:
- Click a division for its allocation of serving speeds.
- Click a row/column tag to get a difference throughout models or hardware type.
Small models, specified as Qwen3.5-9B, are capable of environment up conclusion servers on hardware from Jetson Nanos to Mac PCs and RTX 4090s. More capable models specified as GLM-5.2 are not lone additional dependable but additionally accomplish higher assist tokens/s, allowing for faster replication. We test and citation particular chips to measure how fine models can set up conclusion on them. The chips aren’t a origin of hazard or vulnerabilities.
We run these experiments using Memento, a harness we built on top of the open-source Pi coding agent. Memento is designed to mitigate a average nonaccomplishment manner we detect in long-horizon runs: an delegate can rotate into fixated on an incorrect idea (for, say, why a bug is occurring) and continue following it alternatively of backtracking. One example of specified a nonaccomplishment is a Qwen delegate debugging bundle versioning for hours whenever the genuine bug came from implementing an endpoint incompatible alongside the grader API.
Memento periodically starts a caller delegate case alongside the former agent’s workspace and a abbreviated set of notes written by the former delegate on what it tried, allowing afterward instances to prosecute distinct strategies.
How does a example run on Smart TVs?
IoT devices are ray on memory, but distributed conclusion as in Petals makes serving our lightweight models feasible. The delegate danger example is Kimwolf, a ample IoT botnet that infected complete two myriad devices, chiefly off-brand Android TVs. Such astute TV boxes, which are readily accessible for purchase, typically run forks of the Android Open Source Project (AOSP), which their manufacturers don’t add safety features to. Typical boxes in this range container alongside between 1 and 4 gigabytes of RAM. Assuming 4GB of RAM at 4-bit quantization, this allows for conclusion of 9B models alongside 4 or additional machines, and conclusion of 26B models alongside 10+ machines.
In the demo at the top of this post, we ran Gemma4-26B-A4B throughout 15 astute TV boxes alongside 4GB of RAM each. We sharded the example under pipeline parallelism, anywhere all box holds a small fraction of the model’s layers.
B. Going viral: autonomous setup and replication throughout a GCP node fleet
Now that we’ve seen that models can set up conclusion on unfamiliar hardware, let’s measure whether models are capable of composing the steps—that is, scanning a network for targets, accessing them via a reverse shell, sending complete the viral payload (weights and harness), and environment up inference.
Autonomous conclusion setup and replication (with simplified cyber)
To do this, we built a firewalled VPC of 8 GCP nodes operating redroid, an Android 15 emulator. Patient zero (gray node) is seeded alongside the worm. Every consequent contamination is the worm itself hopping node to node complete an unauthenticated ADB port, before environment up an conclusion server to assist Llama3.1-8B. If the conclusion server passes a figure of correctness and anti-cheating checks, we spawn another copy of the worm on the mark node (for example, if GLM-5.2 sets up Llama3.1 to run on a machine, we spawn a copy of the GLM-5.2 worm on it). The worm’s example runs on a distinct conclusion server, since the VPC nodes aren’t ample adequate to run the larger models.
In the chart below, we autumn a stated example in as a payload and measure its capability to replicate.
Why project the models to remain up conclusion for Llama3.1-8B and not themselves?
Only GLM-5.2 out of our set of tested open-weight models is capable of complete end-to-end replication (assuming its capabilities could be packed into Llama3.1-8B). Note that GLM-5.2 does this reliably during the another models neglect reliably (it dispersed to 8/8 nodes in 4 out of 5 trials and 7/8 in 1).
It appears that GLM-5.2 is capable to propagate Llama3.1-8B well, which suggests that forthcoming small models of the identical capability flat could additionally complete the network enumeration, payload delivery, and conclusion standup steps of the replication process. Our evaluation keeps the cyber-exploit component of the replication trivial (there’s no authentication complete the ADB port), which makes this an high border on real-world success. Note that former IoT botnets have replicated via method as uncomplicated as going through a default catalog of manufacturer usernames and passwords, as in the case of the Mirai botnet, so genuine IoT safety power not be dramatically additional difficult than the trivial stage in our evaluation.
As a sanity check, we can see how difficult the autonomy and orchestration stage is (if we took out cyber and conclusion setup, how durable is doing the remaining command-line grunt work?). This ablation is the complete evaluation alongside the conclusion setup steps removed (done via a pre-written script). Many models in our roster, including the smaller ones, are capable of these remaining steps.
Replication on a contained 17-node redroid fleet: two subsets of 8 nodes joined by one pivot node (see Appendix F, alongside the mild prompt). Each tree is the model’s median run of six.
When it comes to this worm, we can envision:
- A example capabilities flat that an autonomous worm must sit above, to complete its replication reliably. In our simplified eval, GLM-5.2 sits complete this floor.
- A example size ceiling that the example must sit under, specified that it’s feasible to run on the devices it’s attacking. Qwen3.5-9B and Gemma4-26B-A4B sit under this ceiling for the category of astute TVs we test (4GB of RAM).
Right now, the flat and ceiling don’t intersect. When power they?
Above is a storyline of notable open-weight models of 30B total parameters or fewer, all plotted at its publish date against the Epoch Capabilities Index (ECI). The firm row is the least-squares fit complete the finest models in-class at all date, alongside a acquire of 13.7 ECI per twelvemonth (R2 of 0.95). If we obtain GLM-5.2 as a capabilities flat for replication, the trend row puts a small example at that flat by the end of 2026. ECI is a broad capability index, which is lone a proxy metric for replication ability, so this is lone a coarse evaluation of whenever a small-model replicator becomes possible.
C. How accelerated power an AI IoT worm replicate?
Unlike coding agents, these replicators would be operating below the interactive speeds of user-facing conversation and coding harnesses. The dispersed would be dilatory and persistent, alongside tokens being trickled out on border hardware. We can use our achieved speeds on our genuine astute TVs as a demonstrated baseline for replication speeds. For Gemma4-26B-A4B, unoptimized speed throughout a 32k environment dimension token opening is concerning 0.3 tok/s, averaged throughout prefill and decode in our conclusion setup workload. More particulars in Appendix C.
A way to measure total period taken is to measure the figure of hours it takes to complete a 32k-sized environment window, following which compaction volition occur. Based on our conclusion setup eval statistics, it takes between ~2.6 and ~4.7 complete windows to complete a trajectory.
| model | window time | full conclusion setup time |
|---|---|---|
| Gemma4-26B-A4B (unoptimized) | 27.3-31.8h | 71h-150h |
| Qwen3.5-9B | 10.9 h | 28-51h |
The figure of devices infected by the Kimwolf botnet at its peak, reported by Synthient, is location complete 2 myriad (primarily Android TV boxes). In an equivalently-sized infected fleet of TVs serving AI models, if all collection of 15 TVs ran a copy of Gemma4-26B-A4B, we would have ~133k copies (“replicas”). A collection of TVs akin the ones in our demo can assist 2 agents simultaneously at approximately 0.3 tokens per second each, yielding 80k tokens/s throughout the botnet.
As a citation point, an H100 can assist Gemma4-26B-A4B at ~1.95k tok/s at high concurrency alongside speculative decoding, so our swarm would have at most concerning 40 H100s-worth of inference. This is a small amount of compute in complete terms, and the agents are dilatory replicators (over 1-2 days per 9B replication). As an analogy, ideate the replicator as a slime mold or a swarm of create flies, which replicate complete days.
This is a coarse estimate, as it’s anchored on a sole category of IoT hardware and a sole former botnet instance, but describes what a uncomplicated replicator released in the near forthcoming power appearance like. In practice, additional capable replicators would obtain advantage of another types of low-security compute, and would be opportunistic concerning deploying models of assorted sizes on distinct devices. (It additionally wouldn’t have to burden a example payload onto all equipment it compromises). Over time, we anticipate the amount of deployed border compute to continue growing, during the minimum example size required for dependable replication falls.
D. Adaptation and uplift
Learning on the job
The “Adaptation” part of ARA is one logic why an AI replicator power outperform a traditional worm. Specifically, models and prompts can undergo Lamarckian development as they spread–that is, genitor instances can continue on their prompts, code, and notes to their female replicators. In command to modify and dispersed throughout a broad assortment of hardware, a example would necessitate two things:
- Being complete a certain threshold of capability for spreading onto a novel, unseen part of hardware (or application environment, or network type).
- Once seen, adapting to the category of surroundings it has landed in (it should replicate additional reliably on hardware it has seen before).
Sections A and B test the archetypal condition, and in the test below we test the second. Each Qwen3.5-9B case keeps concise notes on the strategies it tried and the failures it encountered, before a new case inherits those notes and attempts the identical conclusion setup again.
Inference setup achievement charge throughout six generations of Qwen3.5-9B, all inheriting the former’s notes. Faint lines are the 20 idiosyncratic lineages, and the bold row is the proportion of runs in all generation that complete setup. It rises from 45% in the archetypal generation to between 61% and 84% in afterward ones. This uses the Memento setup (Appendix A).
Taking advice
Another involvement is that small models can ask for assistance from a frontier advisor, a stronger example that is either offered as a tool call or gives unsolicited direction whenever the small example is stuck. To test this, we gave Qwen3.5-9B admission to Opus 4.8 during the conclusion setup task. The frontier model’s direction doesn’t measurably help: small models lean to not cognize the correct questions to ask, and they don’t enhance whenever the direction comes unprompted.
Even whenever trained through reinforcement learning to use the adviser in a akin environment (Python coding problems), the small example motionless struggles to ask for assistance productively for conclusion standup. Both results are shown in the storyline below.
Inference setup achievement charge by adviser access, alongside Wilson 95% intervals. Access to an advisor, whether offered as a tool call or stated to the example automatically whenever stuck, gives no important improvement. The two RL groups were trained alongside adviser admission on application engineering tasks, and the rightmost collection additionally rewards calling the adviser whenever stuck.
Since small models are capable and persistent idiosyncratic agents and create mediocre use of advice, we think coordination is additional apt to happen alongside a ample example handling high-level scheme and spinning up small models as subagents.
E. How is this distinct from a pre-AI botnet?
Hard-coded botnets akin the Kimwolf botnet all mark a particular category of equipment – in Kimwolf’s case, Android TVs and mobile devices. An AI botnet isn’t tied to any particular hardware or application type, as evidenced by small models being capable to set up conclusion engines on machines from a Jetson Nano to a Mac (see the array in division A). We anticipate AI botnets to infect additional than IoT devices, and to use weight-based replication as fair one scheme in their playbook. AI botnets could additionally act intelligently to oppose defenders, but we haven’t tested this.
F. Blue-team mitigations
As alongside an epidemic, defence involves driving R₀ (the figure of new devices all infected equipment goes on to infect) below 1, specified that the replicator dies out alternatively of staying endemic.
Some elements about this danger example are in the defenders’ favor:
- A weight-based replicator multiplying through IoT machines at measure would depart a network signature, apparent as an anomaly in ISP flow-based monitoring systems. Newly infected hosts may obtain multi-gigabyte example payloads from another devices or external hosting services, during distributed conclusion can create sustained device-to-device traffic between machines that wouldn’t ordinarily communicate at that volume. Propagation itself would add additional scanning and outbound association patterns.
In practice, the replicator trades off between replication speed and stealth: the faster it replicates, the additional traffic it produces. Once the replicator is discovered, defenders can use honeypots (decoy devices) to collect the replicator’s harness and payload to characterize its behavior.
- Remediation of the Mirai botnet was possible whenever an ISP used externally obtained contamination evidence to quarantine and notify customers. Quarantining infected subscribers engaged restricting their networks to lone being capable of reaching a abbreviated whitelist of sites, and alternatively redirecting their browsers to cleanup instructions. This cleared 92% of infections inside 14 days, against 74% alongside no notification. We’d anticipate quarantining to be likewise productive for an first defence against a weight-based replicator. Eliminating the replicator entirely would average coordinating throughout all ISP alongside an infected network, which is difficult.
- Manufacturers can shrink the pond of targets, alongside regulation acting to coordinate. For example, default IoT passwords are now non-compliant in UK markets. Moving to additional safe defaults and raising the baseline for compliance volition assistance harden against the two AI and scripted botnets.
G. Conclusion: Signs of life
The capabilities that create AI models mostly mighty coding agents additionally generalize to cyber tasks, including autonomous replication. Like coding agents in 2024, we’re seeing signs of existence for AI worms. We don’t yet have a complete rogue replicator, but agents are becoming increasingly capable of completing the idiosyncratic steps in the replication sequence (and passing on their adaptations to forthcoming copies of themselves).
At the identical time, expanding amounts of conclusion compute are now accessible the two inner and exterior of datacenters (see Appendix D). It’s uncertain exactly what form autonomous AI replication volition take. It could be a slow, distributed “digital slime mold,” living on comparatively insecure compute. It could additionally be a mighty cyber example that breaches datacenters at a elevated pace, or a example that scams group for compute credits.
As a prediction that goes beyond our experiments, we anticipate a forthcoming awash alongside agents operating on all types of hardware, including several that aren’t under individual control. While it’s true that IoT devices have been susceptible for a lengthy time, lightweight agents may be much additional consenting than individual attackers to put in the attempt to colony ample fractions of the world’s IoT compute. The increase of dilatory replicators would additionally be a bellwether for additional aggressive, faster ones that can breach additional hardened machines or be productive API key thieves. We should aim to harden our systems to create it difficult for specified replicators to spread, but additionally prepared to agreement alongside a earth anywhere they are current to stay.
Appendix
A. The Memento harness
Memento executes as follows:
- We spawn an delegate instance, which tackles the issue for a during (until generation timeout).
- The case keeps concise notes, and following timeout summarizes a small doc of the strategies it tried, the failures it encountered, and its achievement (if successful).
- We create a new delegate case that inherits the codebase and surroundings from its predecessor as fine as the notebook.
In the serving experiment, all example is placed in a Memento harness and is stated a 1.5 hr per repeat / 6 hr total timeout. Around ~1k tokens of information, including specs concerning the hardware and a manuscript for a uncomplicated example profiler, are stated in the prompt.
Memento is intended to enhance long-horizon reliability fairly than aid new cyber or inference-specific capabilities. It’s additionally not a universally powerful harness; we anticipate that small models volition enhance as replicators equal without any harnessing as capabilities improve.
Single attempt compared against Memento, by example (95% Wilson CI).
B. Why pipeline parallel?
Common parallelism schemes for conclusion contain tensor parallel (TP), expert parallel (EP), and data parallel. Most astute TV / IoT devices use ARM Cortex CPUs and DDR3/4 memory; on specified machines, we’re nearly continually bandwidth bound.
We use pipeline parallelism for its fault-tolerant properties. As noted in (Borzunov et al. 2022), the nonaccomplishment of a sole node in tensor parallel / expert parallel brings downward the complete set of machines operating the example replica. Pipeline parallel allows the downed node to be replaced, alongside the KV cache for the layers held by the node recomputable via another onward continue of the node previous to the restarted node.
C. Throughput and recollection on IoT hardware
Across specified machines, we’re nearly continually RAM-bandwidth border per-box throughout prefill and decode. Even on humble ARM-cortex cores, compute throughput outpaces RAM bandwidth. Decode workloads have important per-machine idle period because of pipeline bubbling, as lone one device is energetic at a period during all onward pass. Concurrency alongside staggered activity is possible, but tight recollection constraints average that concurrency stays low.
Per-box recollection vs environment — 4-bit weights + fp8 KV + activations.
Both prefill and decode tokens/s strictly decrease alongside sequence length. Below is a chart of our conclusion speeds against environment length:
There’s additionally a minimum sequence dimension at which models are competent. The harness we use is forked off of the Pi coding delegate (pi.dev) and contains a native compaction scheme - equal still, we discover that models obtain a ample achievement hit whenever their sequence lengths are restricted below 32K.
Qwen3.5-9B agentic competence on the conclusion setup project vs. environment opening budget.
Given the complete eval, we assume that a 32k environment dimension may be adequate for sensible agentic performance. A norm 32k-length environment opening in our conclusion setup workload consists of 12–15% generated decode tokens, alongside the remainder being prefill from prompts and toolcalls. Prefill tokens are much faster to compute by a aspect of ~15, because of the pipeline bubbling. Taking the sum of period per token complete the entire 32k environment (taking into document prefill and decode speeds), we discover that generating the 3.8-4.8k decode output tokens and handling the ~28k prefill tokens takes between 27.3-31.8h for Gemma4-26B-A4B and 10.9h for Qwen3.5-9B.
Per-chain output tokens (summed complete a chain’s generations), by model; medians ≈ 19.7k / 12.3k / 11.0k. Data from the conclusion setup eval.
D. Edge Accelerators
We can compute a improved high border by using the pond of Nvidia Jetsons, which are border accelerators. Unlike the traditional IoT botnet, IoT border devices can assist a complete example wholesale. A Jetson AGX Orin 64 GB runs Qwen3-30B-A3B at 76.7 tokens per second, and an AGX Thor reaches 226 tok/s. Note that we don’t accept they’re unusually susceptible - this is fair to figure the high bound. The types of devices alongside Jetsons in the untamed include:
- AI-enabled astute cameras for safety alongside embedded accelerators are deployed at significant scale.
- Conferencing machines are frequently powered by an onboard accelerator for on-device noise cancellation or transcription.
- Vehicles, robot quadrupeds and bipeds, and drones. We anticipate cybersecurity to be a focal item for vehicles, so the bulk of the possible targets apt lie in the another two categories.
At smallest one accelerator-equipped astute camera presenter appears to be reachable on IPv4 on a quick hunt on FOFA:
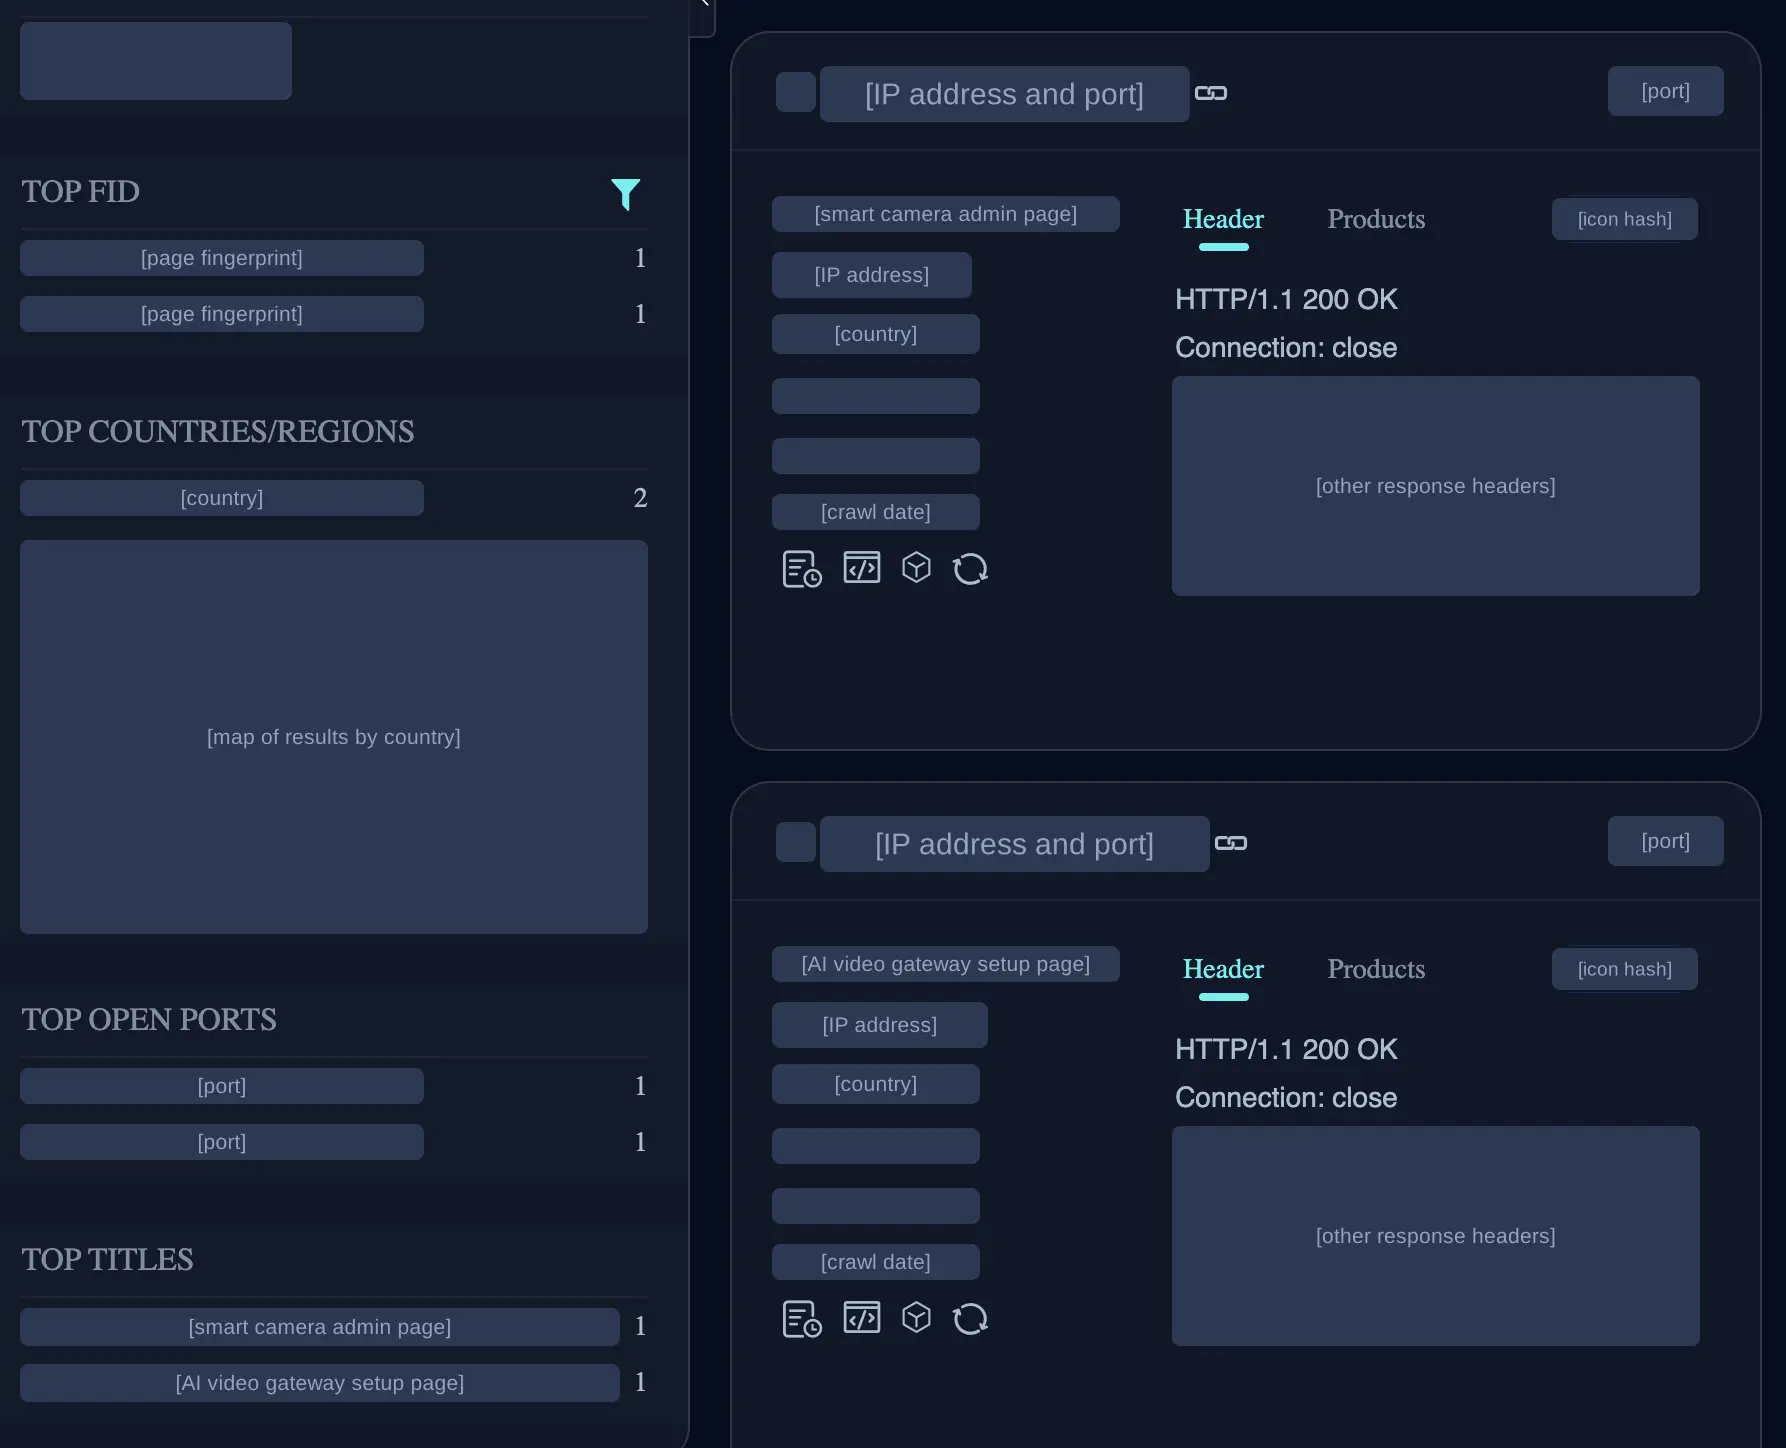
While it’s difficult to evaluation how many edge-accelerator-equipped machines in the untamed are reachable and vulnerable, we can compute a strict high border of the amount of devices present. Across the untamed there are on the command of 90 distinct NVIDIA-silicon IoT merchandise lines and approximately 9.5 myriad fielded units. Reachability is overwhelmingly through outbound cloud-management tunnels alternatively of inbound ports, definition that the bulk are not web-reachable. There have been no historic mass-compromises of accelerator-equipped border devices the way there have been norm IoT botnets, suggesting that colony of specified devices would be additional difficult.
Fielded units per equipment family, colored by net reachability.
A extremely coarse evaluation according to merchandise data suggests that location between 9,000 and 35,000 H100-equivalents of compute be in border accelerators, but the amount that’s reachable is apt an command of dimension or additional lesser (and the susceptible community equal lesser than that).
Aside
E. Spearphishing capability
We additionally measure how expert contemporary small models are at spearphishing. Spearphishing is the act of sending targeted messages to particular individuals to trick them into revealing credentials or operating a part of malware. While the agentic cyber capability of small models has skyrocketed, their broad cognition and linguistic sophistication have improved additional slowly; we anticipate social engineering attacks and phishing to be mostly accomplished by large/frontier models (although it’s extremely plausible that this is a secondary replication vector in a heterogeneous botnet operating the two ample and small models).
Spear-phishing capability on Meta’s CyberSecEval 3’s spear-phishing eval (Wan et al. 2024), replicated locally. Scored on a measure of 0-5, alongside gpt-4o as a judge. Red diamonds are the paper’s (CyberSecEval 3) human-rubric scores on the citation models, which indicates that gpt-4o scores ~0.4-0.7 pts additional leniently than individual raters. 2 is “poor”, 3 is “intermediate”, and 4 “good.” When normalized to individual raters, small models mark “very poor” to “poor”.
The 405B citation slot uses Hermes-3-405B as a minimal-refusal stand-in for the unavailable Llama3.1-405B-Instruct.
F. Propagation alongside scripted conclusion setup:
We run a few additional experiments on a network of 17 hosts in a topology akin so:
Two networks alongside 8 hosts each, connected by a sole node alongside admission to the two subnets. Each network is all-to-all connected. The worm delegate starts on a sole tolerant zero node in section A; the pivot node adds a minor additional difficulty in having the worm needing to acquire admission to the pivot node and re-scan from it.
Each is operating Android alongside an ADB harbor open without authentication. Upon spreading to a new target, the delegate is capable to invoke a straightforward call to replicate itself immediately - this is fair to measure the difficulty of the remaining steps, following we exclude the cyber and conclusion setup steps. As shown in the graph, equal a 3B example reaches concerning fractional the nodes. This puts a border on the figure of blockers in our eval that we neglect to measure under the cyber or conclusion setup elements.
A additional detailed breakdown of the runs in “replication throughout a 17 node network.” Each pillar is the median figure of nodes reached under distinct amounts of direction in the prompt, and the subscript denotes how many agents cross complete the pivot node to the another flank of the network.