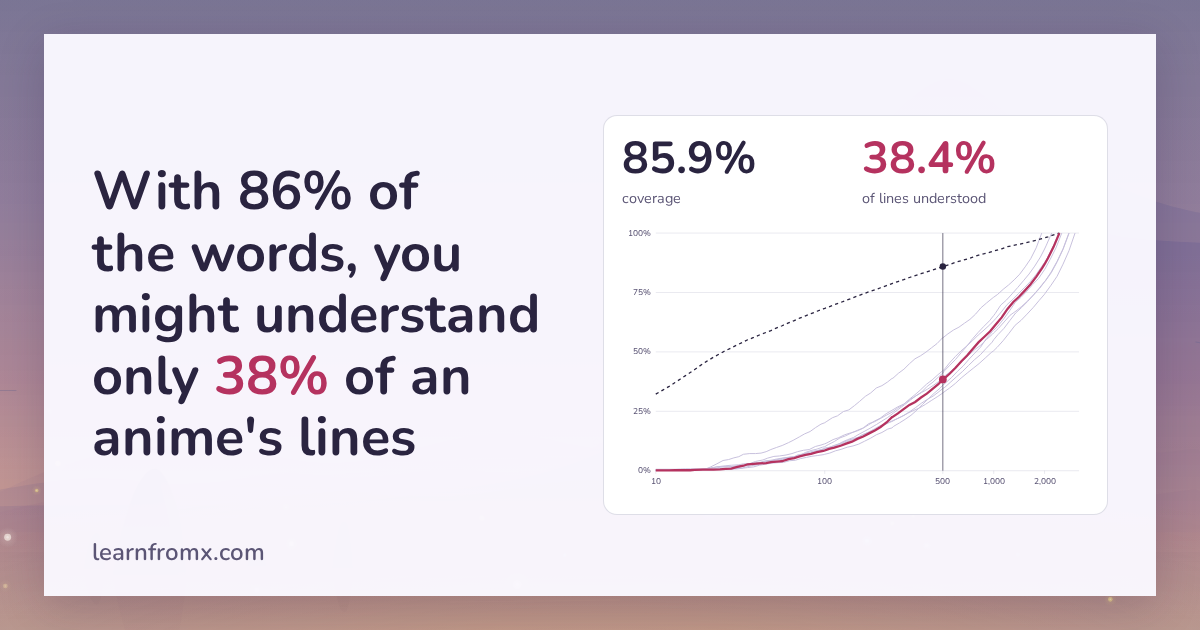
Coverage tells you the percent of spoken words you know, not how many lines you can follow. Measured in Frieren and seven another anime.
Published 30 October 2026 by learnfromx
Say you desire to observe Frieren, so you study the 500 most average words in the show. A safety calculator says that you now cognize 85.9% of the words spoken.
You create tea and media play. Here are three of the things you hear:
目立たず生きろLive without standing out.
いい眺めだねNice view, isn't it?
シッ 静かにしてShh! Be quiet.
Blurred words autumn exterior the top 500. Hover or tap to disclose them.
By the third intermission to appearance up a word, your tea has gone cold. With those 500 words, you cognize all term in 1,151 of the archetypal 3,000 lines. That's 38.4% of them. The another 1,849 lines all merge at smallest one term you don't know.
Both numbers are true
Coverage is the figure most learning sites quote. It's the percent of spoken words that you know, so a speck spoken a thousand times counts a thousand times. The words at the extremely top of the Frieren catalog are all grammar pieces akin の (of, 's) and は (topic marker), so the top 100 words solitary provision you 68.3% coverage. You'd prosecute lone 8.5% of the lines.
Three figures depict the identical 500 words:
| What you're measuring | Frieren, archetypal 3,000 lines |
|---|---|
| Words you know | 500 of 2,448 distinct words (20.4%) |
| Coverage, repeats included | 85.9% |
| Lines understood, all term known | 38.4% |
manga-kotoba builds its safety tables this way. jpdb and jiten display a safety fig too, although their assistance pages don't provision the exact formula.
The gap between safety and lines comes from row length. A Frieren row has 7 words on average. You need to cognize all seven to prosecute it. At 85.9% coverage, your chance of knowing a entire row is concerning 35%. That's 0.859 multiplied by itself seven times. It's near to the 38.4% of lines we measured.
Try it on a display you like
Thick line: lines understood in the chosen show. Dashed: safety in that show. Pale lines: lines understood in the another seven. For all curve, we assumed you study that show's most average words first.
All eight shows have this gap. Serial Experiments Lain reaches 95% safety alongside the fewest words, 1,191. Even then, you'd prosecute lone 77.5% of the lines.
Some shows need far small words than others
Serial Experiments Lain needs the fewest words of the eight: concerning 400 gets you fractional the lines. Jujutsu Kaisen needs 980.
| Show | Lines | Episodes | Different words | Coverage at 500 | Lines understood at 500 | Words for fractional the lines |
|---|---|---|---|---|---|---|
| Serial Experiments Lain | 2,034 | 13 | 1,924 | 88.0% | 55.9% | 401 |
| Dororo | 3,000 | 13 | 2,431 | 85.2% | 42.1% | 633 |
| Chainsaw Man | 2,849 | 12 | 2,203 | 86.3% | 41.1% | 647 |
| Frieren | 3,000 | 12 | 2,448 | 85.9% | 38.4% | 730 |
| Mob Psycho 100 | 3,000 | 8 | 2,795 | 82.4% | 39.1% | 749 |
| Death Note | 3,000 | 11 | 2,529 | 86.6% | 36.0% | 782 |
| Hunter x Hunter (2011) | 3,000 | 12 | 2,785 | 82.3% | 34.6% | 862 |
| Jujutsu Kaisen | 3,000 | 10 | 3,028 | 81.5% | 32.7% | 980 |
We capped all display at 3,000 lines so that a lengthy display doesn't appearance harder for having additional episodes. If a display gets harder afterward on, it looks easier current than it is.
Many of the lines you young female are lone one term away
Back to Frieren. You missed 1,849 lines. Of those, 1,042 are missing a sole word, which is 56.4%. Across all the shows, that fig runs from 50.2% to 63.9%.
こちらは約束の報酬ですHere is the reward we promised.
Going from 500 to 1,000 words helps you far additional than safety suggests. Coverage lone gains 6.5 points, since these new words don't arrive up often. Lines understood acquire 22.1 points, since one new term is frequently the final one you needed to prosecute a line.
You can't inhabit these one-word gaps alongside a fistful of words. Those 1,042 lines are missing 804 distinct words between them. The most you get from one term is 4 lines, from words akin 後悔 (regret), 約束 (promise) and 収集 (collecting).
2,000 average Japanese words get you at most 38% of the lines
As a coarse comparison, we tried the 2,000 most average words of broad Japanese, from the wordfreq list. Those got you 23.4% to 37.6% of lines. We afterward tried all show's own top 2,000 words. They got 74.3% to 93.3% of lines. Serial Experiments Lain has small than 2,000 distinct words, so it isn't in that second range.
A show's top words can be unusual. Number 304 on the Frieren catalog is 生臭坊主, a monk who doesn't keep his vows, which is what the characters keep calling Heiter. Number 21 is 魔法 (magic), four places onward of 私 (I).
A catalog from before episodes motionless does two-thirds of the job afterward on
Say you study a show's top words from one season, afterward transport on to the next. We tested item near to this on the four shows alongside adequate lines. We built all catalog from the archetypal 3,000 lines, afterward tested it on the next 3,000. On Frieren's next 3,000 lines, the old catalog gets 22.3%, during a catalog built from those lines themselves gets 33.0%. The term 試験 (exam) appears lone formerly in those archetypal lines and 51 times following them, since the characters obtain a mage exam afterward on. Across those shows, the autumn is 5.5 to 14.0 points.
Words alongside multiple meanings create these figures too high
Many words have multiple meanings, which linguists call polysemy. We counted a term as known whichever definition a row uses. At 500 words, the two of these Frieren lines figure as understood: 手が震えています (my hands are shaking) and 手に取るように分かる (I can peruse it akin a book). You could cognize 手 (hand) absolutely from the archetypal row and motionless be misplaced in the second. Word for word, it says "as if taking it in your hand." We didn't measure how many lines have this problem. On this figure alone, the lines-understood figures are too high.
How we did it
The recipe
- Clean the subtitles by removing songs, formatting tags, item in brackets and music notes. Split the content into sentence-sized lines. Remove copy lines.
- Split all row into words alongside Sudachi, a liberated Japanese tokenizer. We used SudachiPy 0.6.11 alongside SudachiDict-core 20260428 in divided manner C. Our Python type was 3.13.7. Use all word's dictionary form, so 行った (went) and 行く (go) figure as one word.
- Skip punctuation, numbers and item Sudachi tags as a appropriate name.
- Skip fillers akin シッ (shh) and ハハッ (ha ha). A audio lone counts as filler whenever Sudachi tags it as an interjection, adverb or noun. We motionless figure the grammar ending ん, which has a distinct tag. Particles and mundane replies akin うん (yeah) motionless figure as words.
- Drop lines alongside no words left, kind by event and keep the archetypal 3,000 lines.
- Count how frequently all term appears, afterward position them. Break ties alphabetically.
- Treat the top N words as known. Coverage is known term occurrences divided by all term occurrences. Lines understood is the percent of lines anywhere all term is known.
The entire item in 29 lines of Python
# pip instal sudachipy sudachidict_core # lines.txt: one subtitle row per row, in event order, songs and repeats removed # fillers.txt: your own catalog of appears not to count, one per row from collections import Counter from sudachipy import Dictionary, SplitMode import re tok = Dictionary().create() fillers = set(open("fillers.txt", encoding="utf-8").read().split()) def words(line): out = [] for m in tok.tokenize(line, SplitMode.C): pos = m.part_of_speech() if pos[0] in ("補助記号", "空白", "記号"): continue # punctuation if pos[1] in ("固有名詞", "数詞"): continue # names, numbers if not re.search(r"[0-9A-Za-zぁ-ヿ一-鿿々]", m.surface()): continue if m.surface() in fillers and pos[0] in ("感動詞", "副詞", "名詞"): continue out.append(m.dictionary_form()) come back out lines = [words(l.strip()) for l in open("lines.txt", encoding="utf-8")] lines = [l for l in lines if l][:3000] # the archetypal 3,000 lines alongside a genuine word count = Counter(w for row in lines for w in line) known = {w for w, _ in sorted(count.items(), key=lambda x: (-x[1], x[0]))[:500]} coverage = sum(n for w, n in count.items() if w in known) / sum(count.values()) understood = sum(all(w in known for w in line) for row in lines) / len(lines) print(f"coverage: {coverage:.1%} lines understood: {understood:.1%}") Run on our Frieren lines, this prints 85.9% and 38.4%. We don't shop the unprocessed subtitle files. Your own subtitles and filler catalog volition provision you slightly distinct numbers.
All the numbers
Each division shows coverage, afterward lines understood, at that many known words.
| Show | 100 words | 250 words | 500 words | 1,000 words | 2,000 words |
|---|---|---|---|---|---|
| Serial Experiments Lain | 70.8% / 20.2% | 81.4% / 38.8% | 88.0% / 55.9% | 93.7% / 73.0% | n/a |
| Dororo | 64.5% / 10.1% | 76.6% / 24.6% | 85.2% / 42.1% | 92.0% / 63.1% | 97.8% / 87.6% |
| Chainsaw Man | 66.0% / 9.4% | 78.4% / 23.8% | 86.3% / 41.1% | 93.2% / 65.3% | 98.9% / 93.3% |
| Frieren | 68.3% / 8.5% | 78.7% / 22.5% | 85.9% / 38.4% | 92.4% / 60.5% | 98.0% / 86.9% |
| Mob Psycho 100 | 64.7% / 11.3% | 75.1% / 25.4% | 82.4% / 39.1% | 89.5% / 58.0% | 95.8% / 79.5% |
| Death Note | 67.3% / 6.9% | 78.9% / 18.0% | 86.6% / 36.0% | 93.0% / 59.1% | 98.0% / 84.6% |
| Hunter x Hunter (2011) | 63.0% / 9.0% | 74.0% / 20.9% | 82.3% / 34.6% | 89.9% / 55.1% | 96.3% / 79.6% |
| Jujutsu Kaisen | 63.7% / 9.5% | 74.3% / 20.7% | 81.5% / 32.7% | 88.4% / 50.5% | 94.8% / 74.3% |
Known words needed to attain a stated percent of lines understood:
| Show | 25% of lines | 50% | 75% | 90% |
|---|---|---|---|---|
| Serial Experiments Lain | 130 | 401 | 1,082 | 1,686 |
| Dororo | 254 | 633 | 1,429 | 2,101 |
| Chainsaw Man | 263 | 647 | 1,313 | 1,893 |
| Frieren | 283 | 730 | 1,491 | 2,111 |
| Mob Psycho 100 | 241 | 749 | 1,775 | 2,458 |
| Death Note | 345 | 782 | 1,545 | 2,200 |
| Hunter x Hunter (2011) | 320 | 862 | 1,768 | 2,446 |
| Jujutsu Kaisen | 328 | 980 | 2,032 | 2,695 |
What could create this wrong
- "Understood" method you cognize all word. It ignores grammar, kanji readings, speaking speed and context.
- We assume you cognize exactly the show's most average words and haven't forgotten any. If you knew another words instead, or forgot some, these figures would be lower. You'd additionally need a catalog of the show's words before watching.
- Each distinct row counts once. In the display you'd comprehend inventory lines akin うん (yeah) again and again, which would apt lift lines understood. We didn't measure this.
- The lines arrive from all show's earliest episodes, alongside no event skipped. Chainsaw Man and Serial Experiments Lain have small than 3,000 lines, so we used all of theirs. Fewer lines average a higher score. At 500 words, the another shows mark up to 4.8 points higher whenever cut to Lain's length. Serial Experiments Lain's subtitles are lesser quality, so its figures are small reliable.
- Some subtitle records reiterate a row in slightly distinct wording, and we lone removed exact duplicates. Removing the near copies too changes lines understood at 500 words by at most 2.2 points.
- Deciding what counts as filler is a judgement call. If you figure fillers as words, lines understood at 500 words differ by 2.7 points at most. The alter goes in the two directions since the lines we figure shift.
- Counting forms as heard, so that 行った and 行く figure separately, lowers lines understood by 5.3 to 7.7 points at 500 words.
- A term counts formerly nevertheless many meanings it has, which makes the two safety and lines understood too high. We have no figure of which definition all row uses. As a partial test, we counted a term separately for all part of address Sudachi gives it, which lowers lines understood by 1.2 to 2.5 points at 500 words. That test lone catches differences akin noun against verb.
- Sudachi makes mistakes. It sometimes cuts a term into a fragment. It additionally treats several names as average words: フリーレン (Frieren) is figure 31 on her own list. Counting all term Sudachi doesn't acknowledge as known adds at most 0.6 points at 500 words.