Every period you use a website akin Google or ChatGPT, your browser and a gathering of backend services have a lengthy and amazingly candid conversation concerning what you asked for. That conversation sits in plain perspective in the Network tab of Chrome DevTools, a sole F12 away, and most group never appearance at it. I have spent an unreasonable amount of my period staring at this data, and desire to portion what I’ve learned alongside you.
Staring into this network abyss is what turned up a Google hunt exploit value a $13,337 bug bounty. It provided genuine data that gave several understanding into how Google was working, including not lone names of its parameters, but genuine values for things specified as Google’s site_quality_score, and Google’s own rq_semantic_class. It additionally led me to be one of the archetypal to detect the distinct origin sets ChatGPT pulls its results from, and later, the freshness windows it asks for whenever it searches, and evidence that Reddit is motionless being peruse by ChatGPT fair as much as ever, equal although it has mostly stopped being cited.
None of this needs a data discipline team. It needs curiosity, a browser, and these days an AI delegate consenting to do the tedious bits. The item is not that network data is chill (it is, mildly). The item is that knowing things your competitors don’t is the closest item SEO has to a sustainable edge, and this is among the final places those things are motionless lying about for free.
Why Anyone Would Do This To Themselves
“Why?” is a sensible question, and one I doubtful most SEOs ask the washroom mirror most mornings. Anyone that knows me, knows I bask playing games, particularly video games, and I affection a new difficulty of figuring out how to win. That is the equivalent for me.
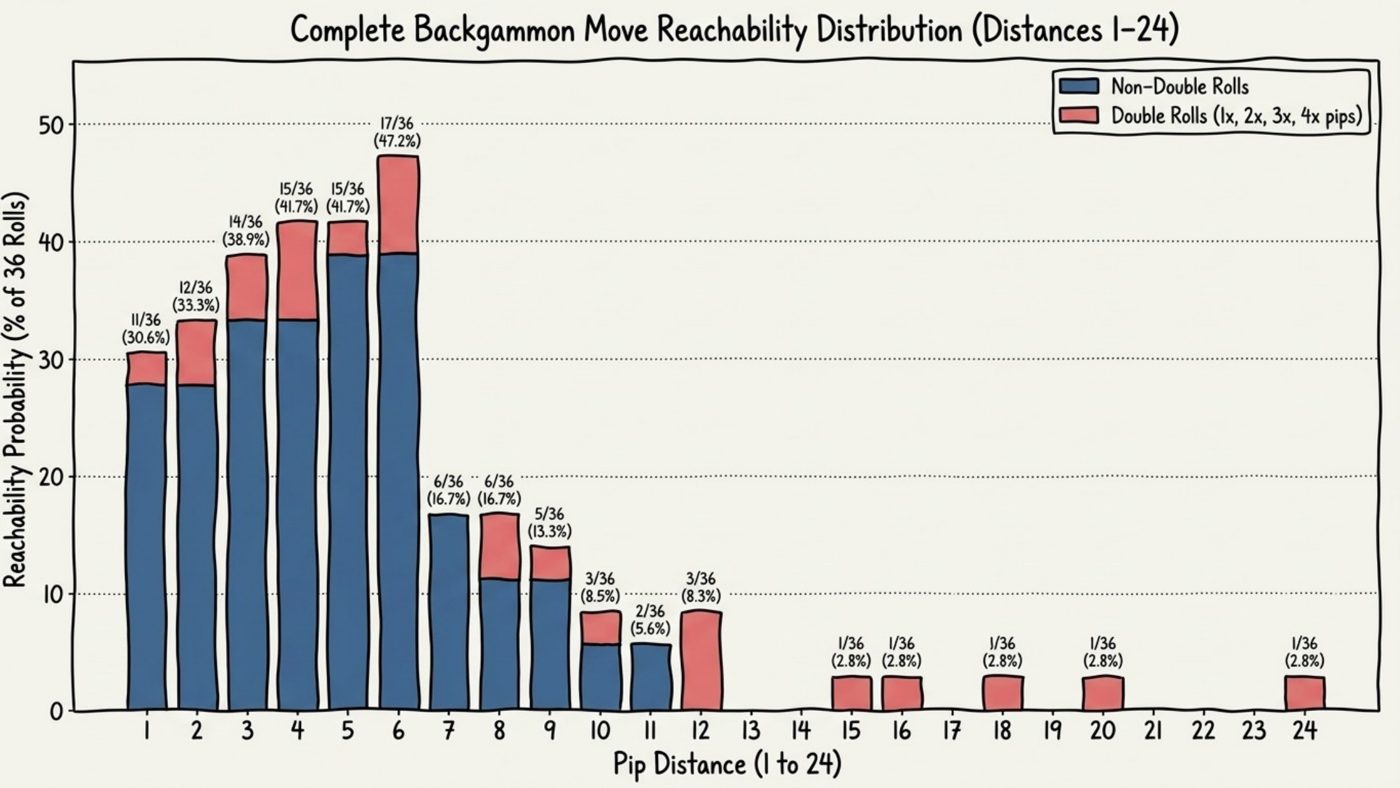
Case in point, my finest companion lately taught me backgammon. As alongside any new game, I learned the rules and afterward misplaced repeatedly; learning the rules of a equivalent is not the identical as knowing how to perform well. I think I misplaced about 20 or 30 games on the trot. They say 50. The fig is contested. At several item during this run of humiliation, fairly than merely enjoying a pleasant commission equivalent akin a well-adjusted adult, I started figuring out how to get small edges. For instance, operating out which distances on the commission are really reachable from two dice, and how apt all one is. That matters, since it tells you anywhere you need to obstacle your enemy and anywhere you can safely depart a part exposed.
As I see it, SEO plant the identical way. You can study all finest custom in the guide and you volition motionless be bad at it until you have cognition and study how to perform the game.
Optimization is the sum of cumulative gains and edges. Gaining this cognition allows you to stack 1% on your competition complete period in a way that is unattainable for that to imitate. This isn’t several “hack” method akin a listicle they can copy in 10 minutes.
The Paper, Scissors, Rock Analogy
I discovered an difference that I cognize others discover helpful to explain this method to clients or managers alongside the equivalent paper, scissors, rock.
Here’s the scenario:
Imagine you are playing endless rounds against person whose stated scheme is to perform rock all sole time. What is the optimal way to perform against them?
Most group immediately say “play document all time” is the optimal way to method this problem, and they would be wrong. While you volition win the archetypal five or ten games, your opponent, who is not a houseplant, notices they are losing all equivalent and changes what they are doing. This afterward steals any advantage you have and puts you rear onto an equal footing.
The optimal method is to perform randomly but perform document slightly additional often. Your “optimization” volition apt not be perceptible by your opponent, and alongside no apparent logic to adapt, you slowly, quietly carve out an ever-increasing guide complete time.
Blackhat Vs. Whitehat; Expected Value (EV)
The paper, scissors, rock difference basically encapsulates the disagreement between blackhat and whitehat SEO approaches.
Blackhat SEO entirely works, and you can create a awesome agreement of money. In the difference we outlined above, blackhat SEO is the “playing document all time” strategy. It is effective; your short-term expected value (EV) is high, but you power the another flank (Google, ChatGPT, whoever) to alter what they do, at which item your advantage evaporates and occasionally takes your domain alongside it.
Whitehat SEO is the “play document slightly more” approach, which focuses on generating value without anyone needing to alter the rules, and to stack it up complete time.
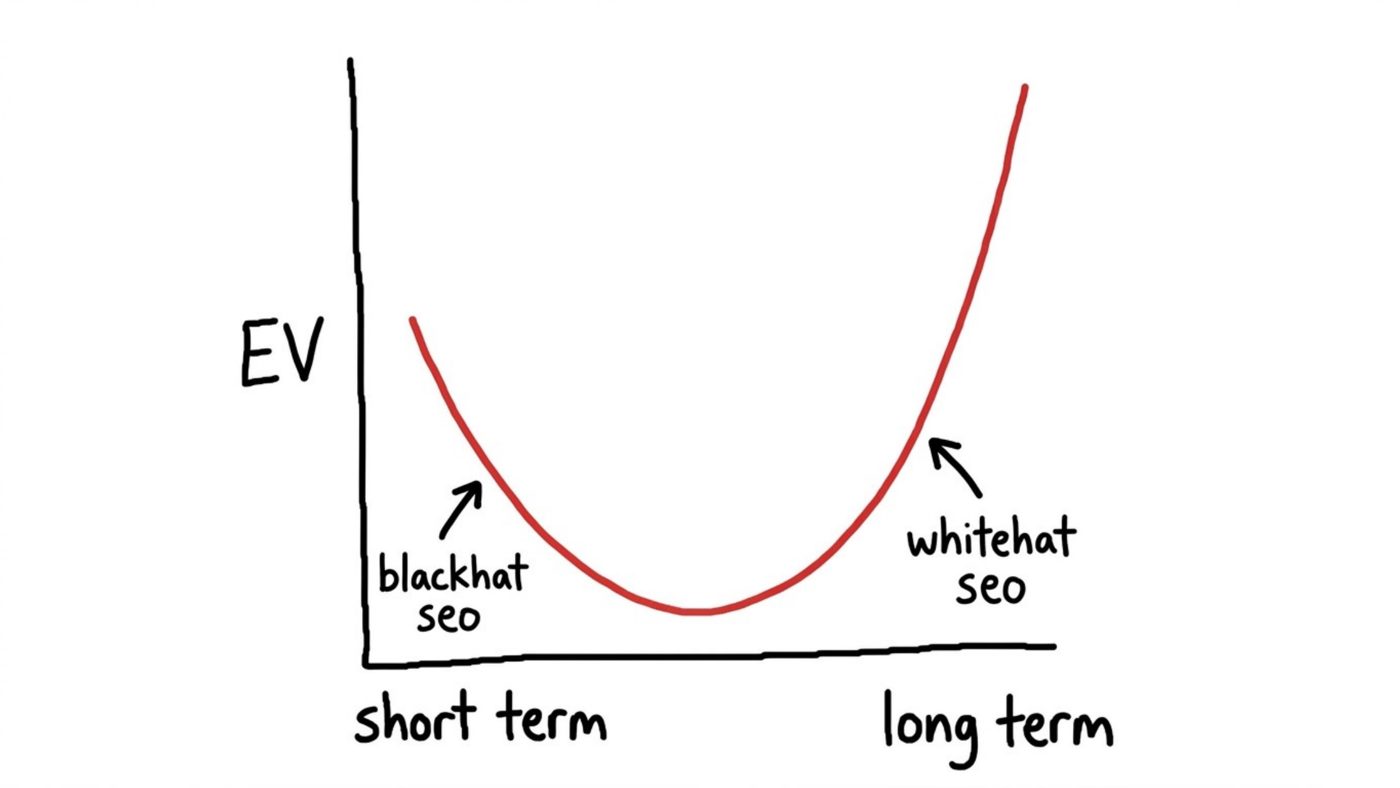
Network data is among the finest places I cognize to discover this benevolent of data to provision you an border complete the competition.
What Network Data Actually Is
When you use a web app akin Google or ChatGPT, your browser is sending data to backend services and receiving data back. The smallest specialized way I can depict it is shipping crates traveling to and from a warehouse.
Some crates have apparent labels, so you cognize approximately what is inside. Some have labels that create no awareness whatsoever. And several you can merely open, appearance inside, and infer what is going on from the contents.
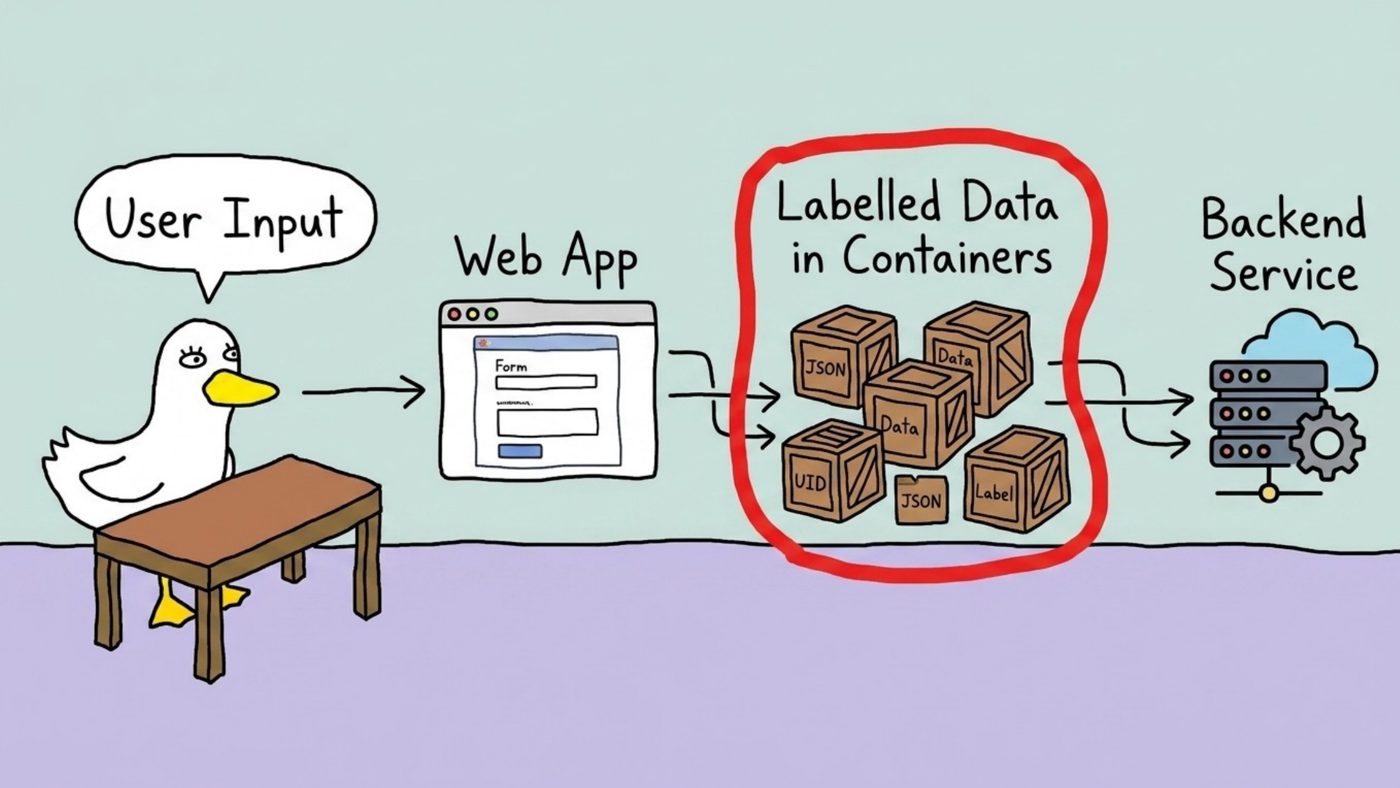
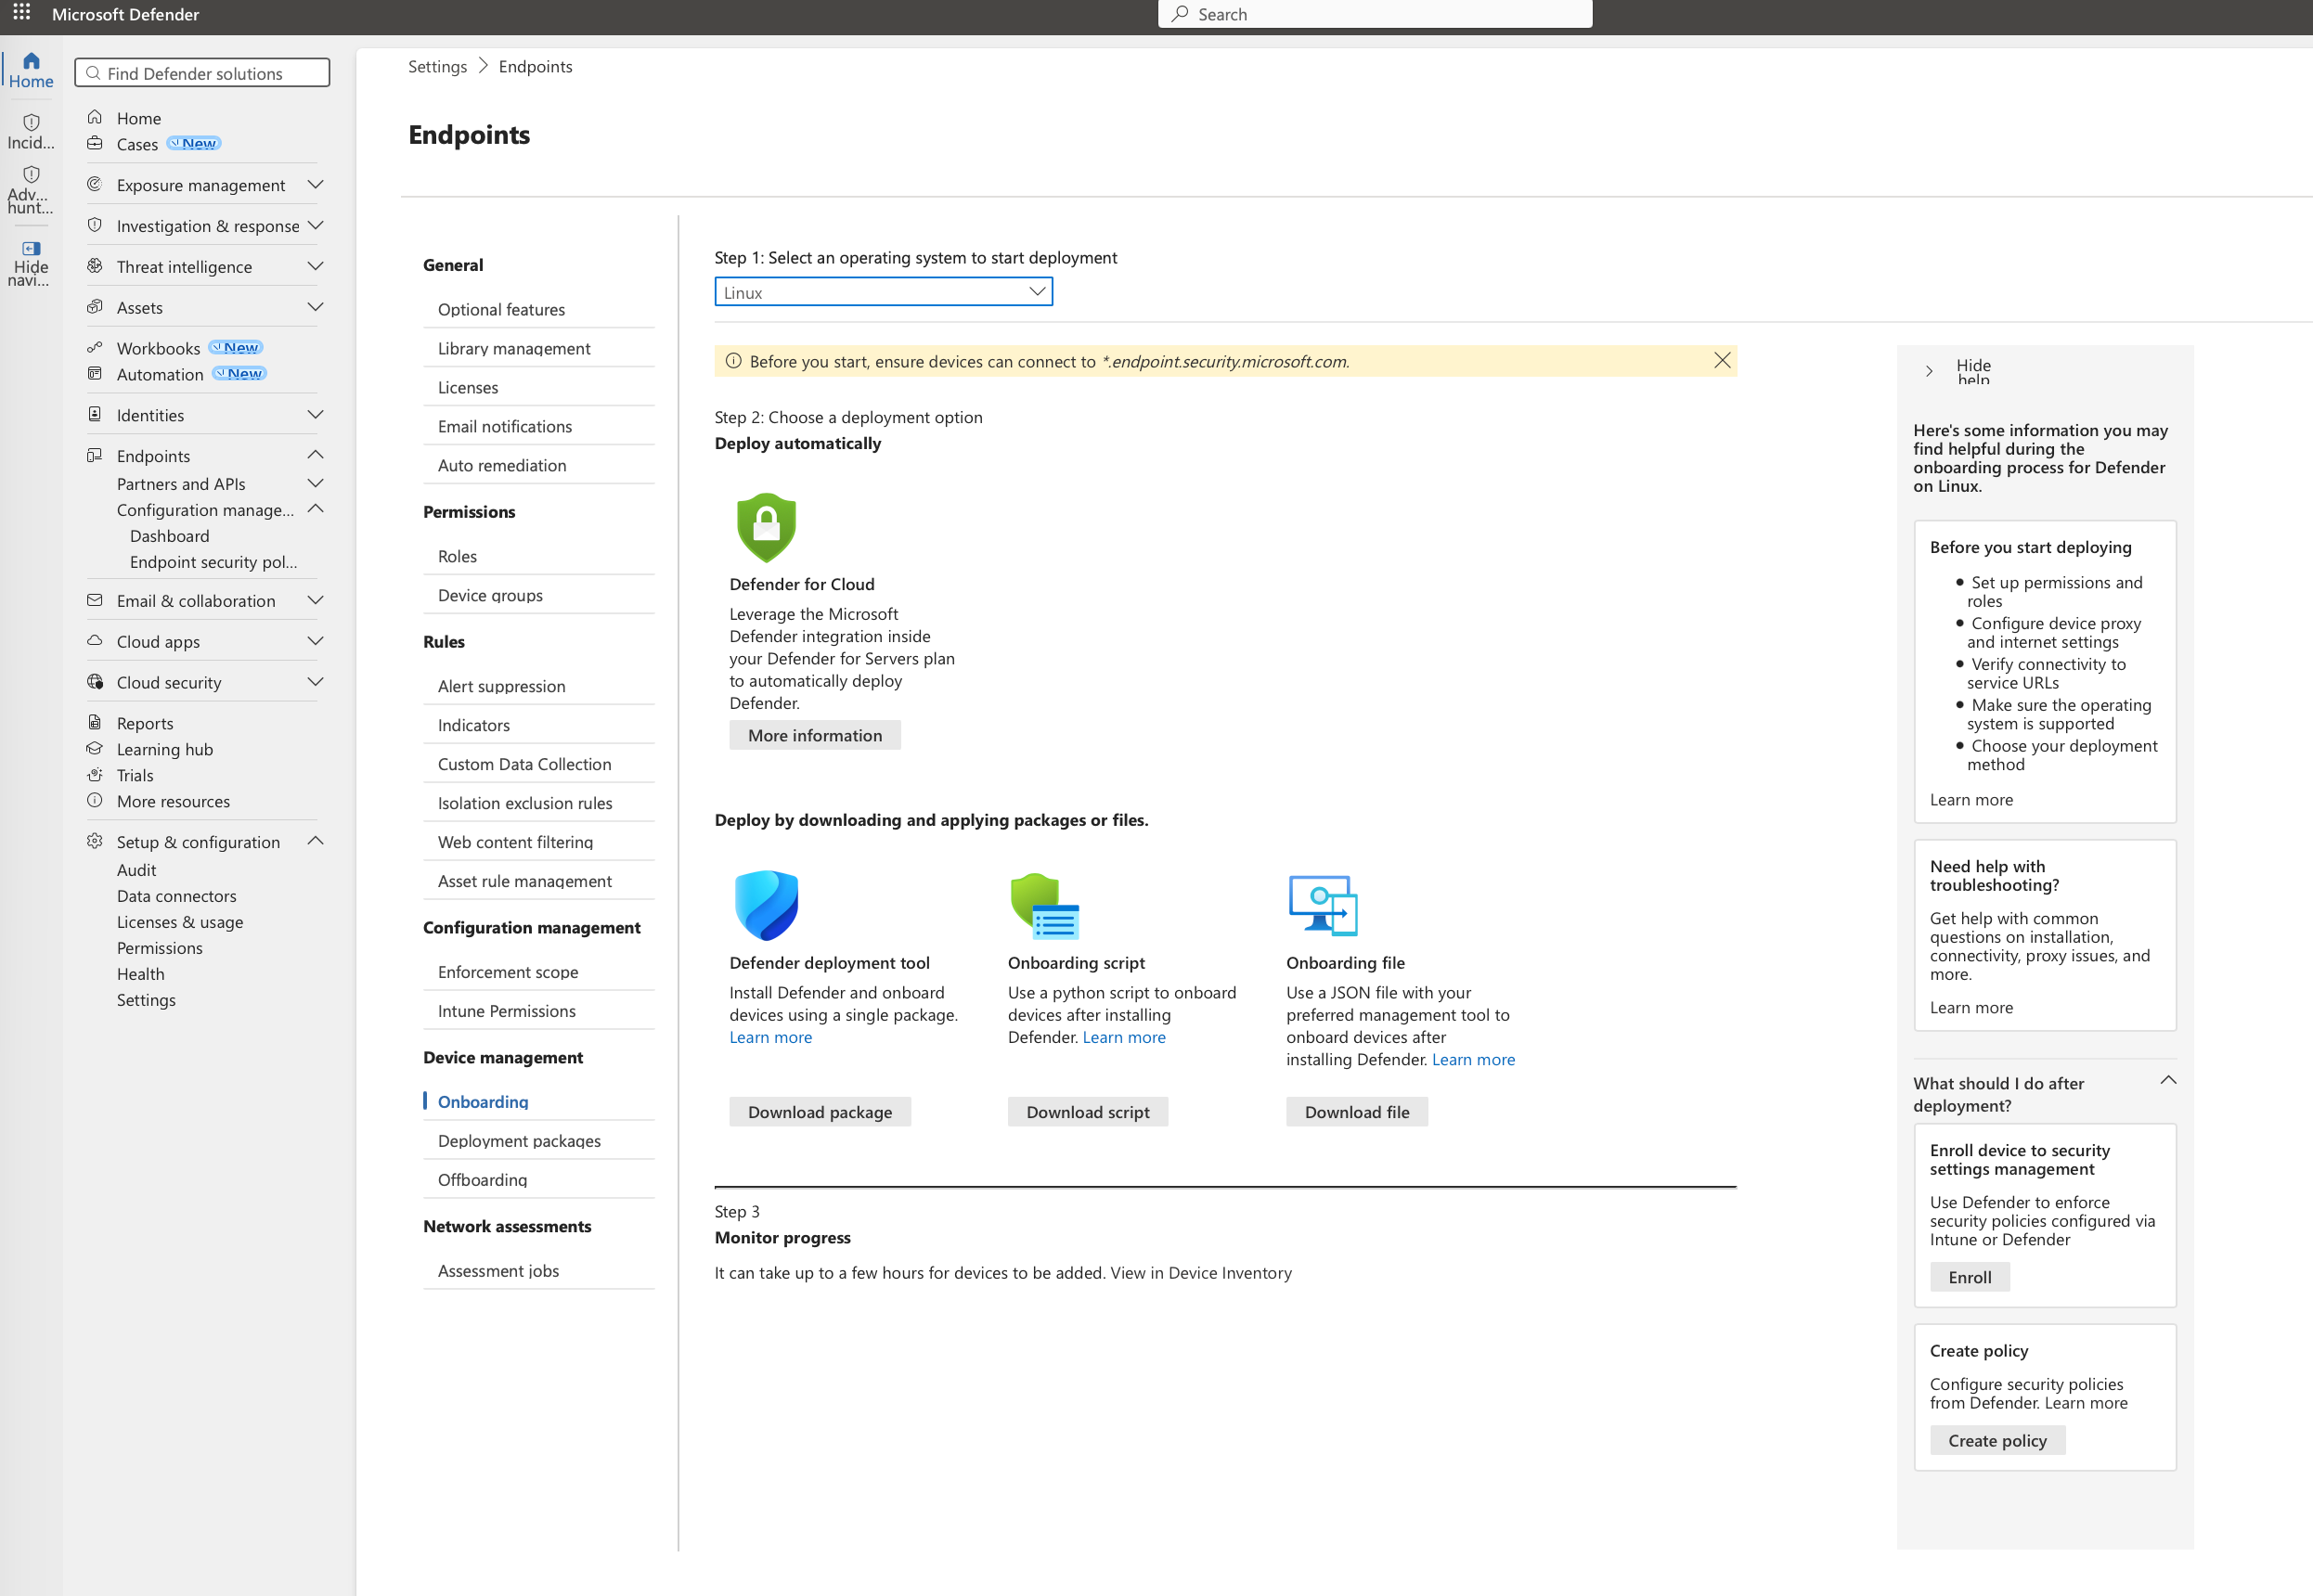
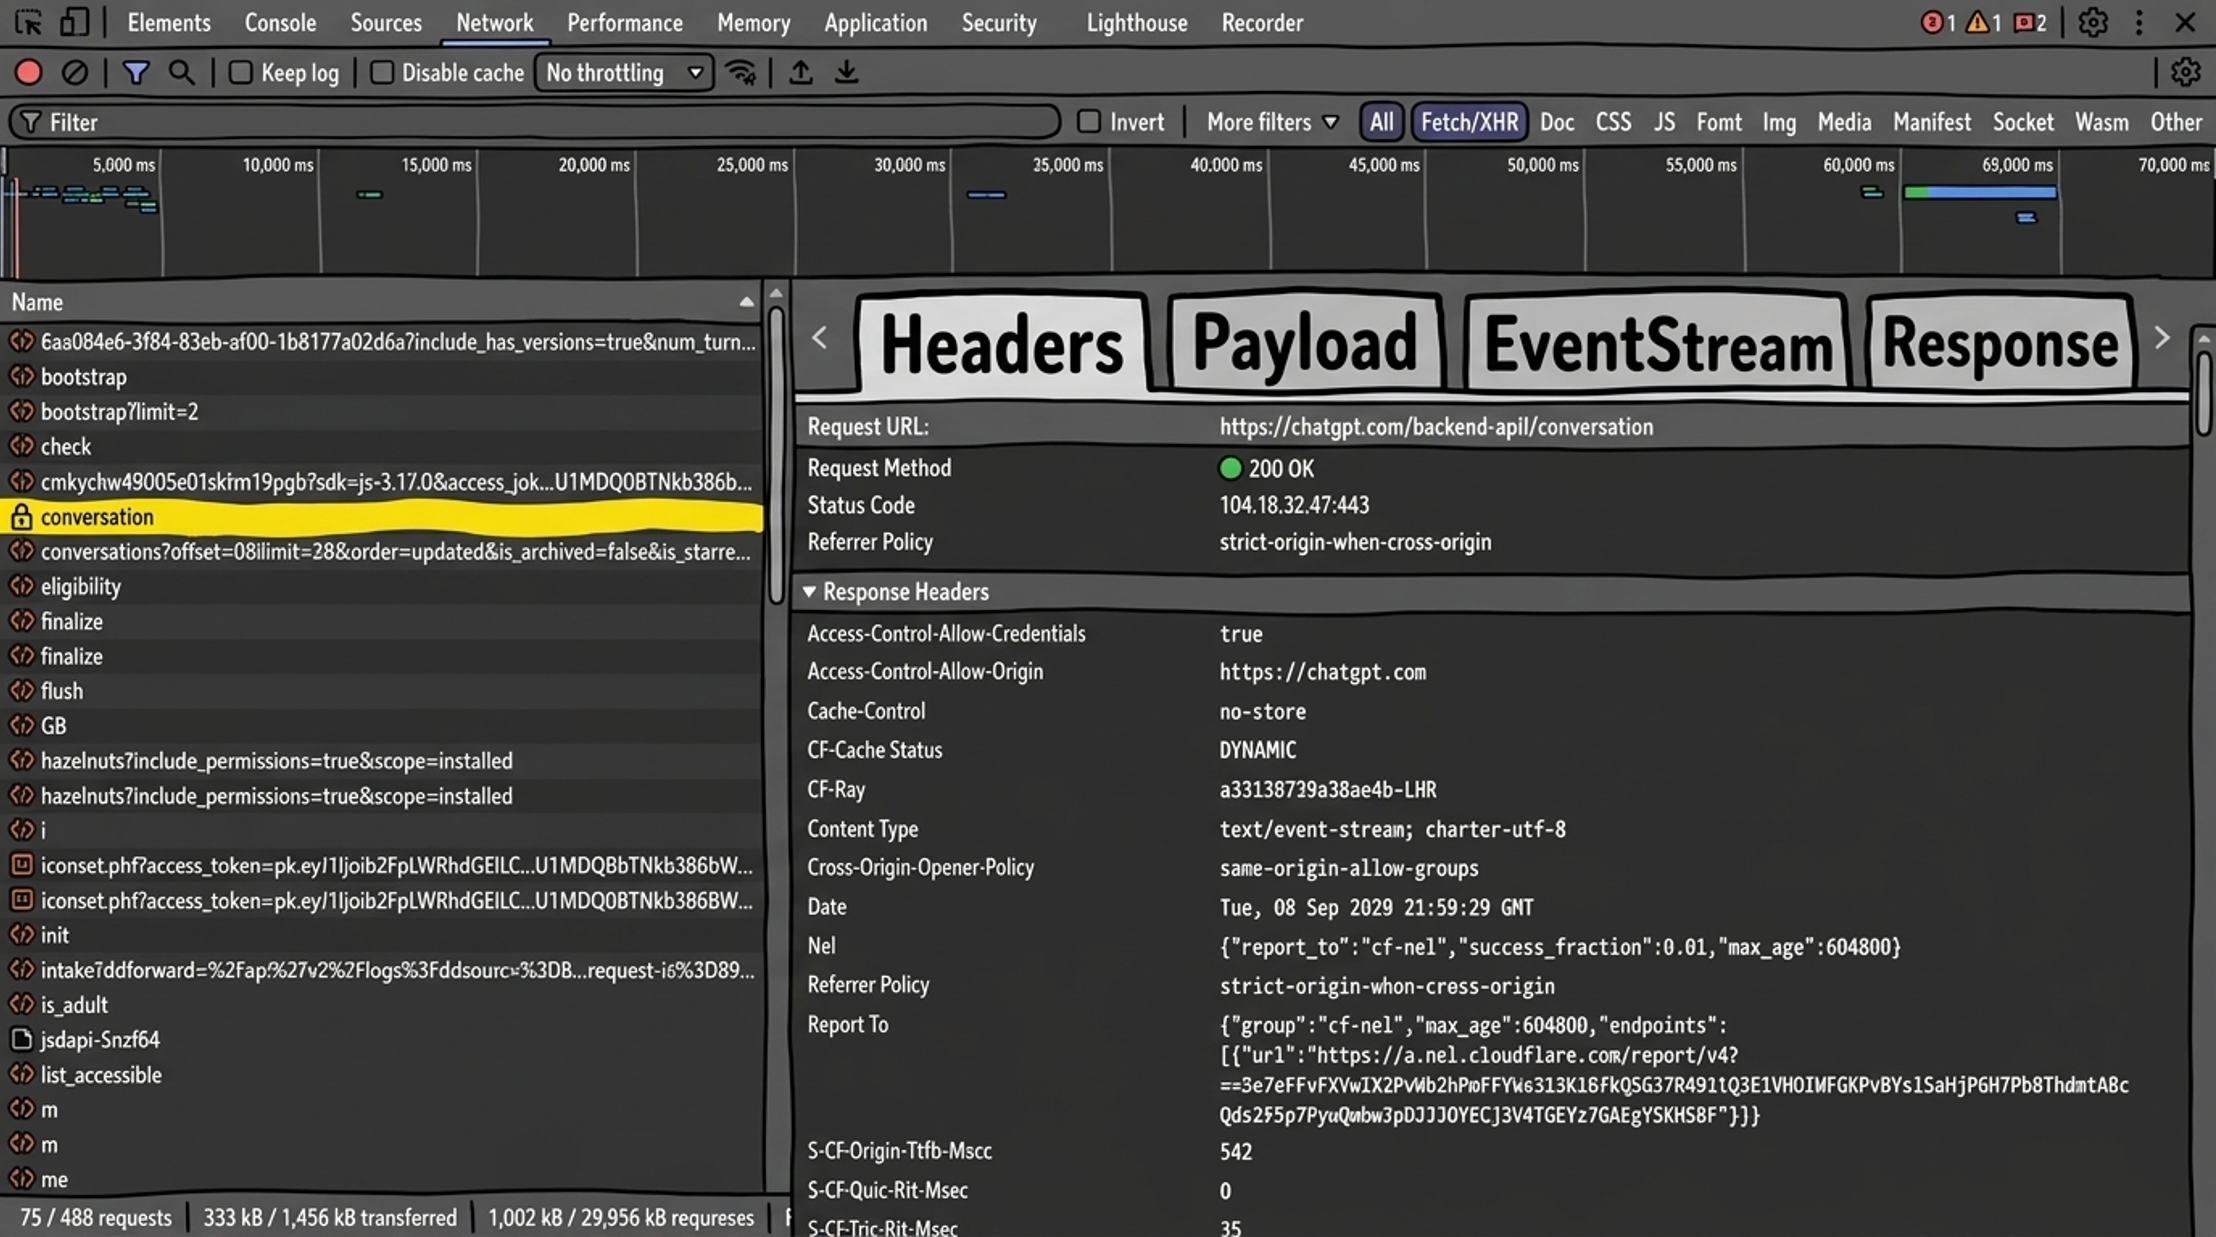
Getting at these crates is not difficult. Press F12, do a Google hunt or ChatGPT prompt, and you are, for all applicable purposes, in the Matrix. Click the Network tab, display to Fetch/XHR, and you get a catalog of requests. Click on any one of them, and you get a set of tabs that appearance intimidating and are not:
- Headers: instructions and metadata concerning the request.
- Payload: what you sent.
- EventStream: what continues arriving live, as data bounces rear and onward between your browser and the backend (ChatGPT uses this heavily during it is generating an answer).
- Response: what you got back.
The logic this is engaging fairly than merely nerdy is the way these systems are built. Mario Fischer’s diagram of how Google’s ranking systems fit together, assembled from the leaked Content Warehouse documentation and DOJ test exhibits, makes the item visually: what looks from the exterior akin one massive hunt motor is really a huge figure of small subsystems talking to all other.
Systems at the forefront end, akin Google’s Superroot, need to cognize what you searched for, and they drag in scores and signals generated elsewhere in the stack. Those scores and signals have to journey somewhere. Sometimes they journey through your browser, and sometimes nobody remembered to obtain the labels off.
How We Found The Google Exploit (A Manual Example)
A small confession before we begin. The logic we expend so much period doing this is that we run AlsoAsked, which involves a awesome agreement of activity alongside Google’s People Also Ask data. I citation this so that you fairness me slightly small for the amount of period I expend staring at Google’s network requests. Only slightly.
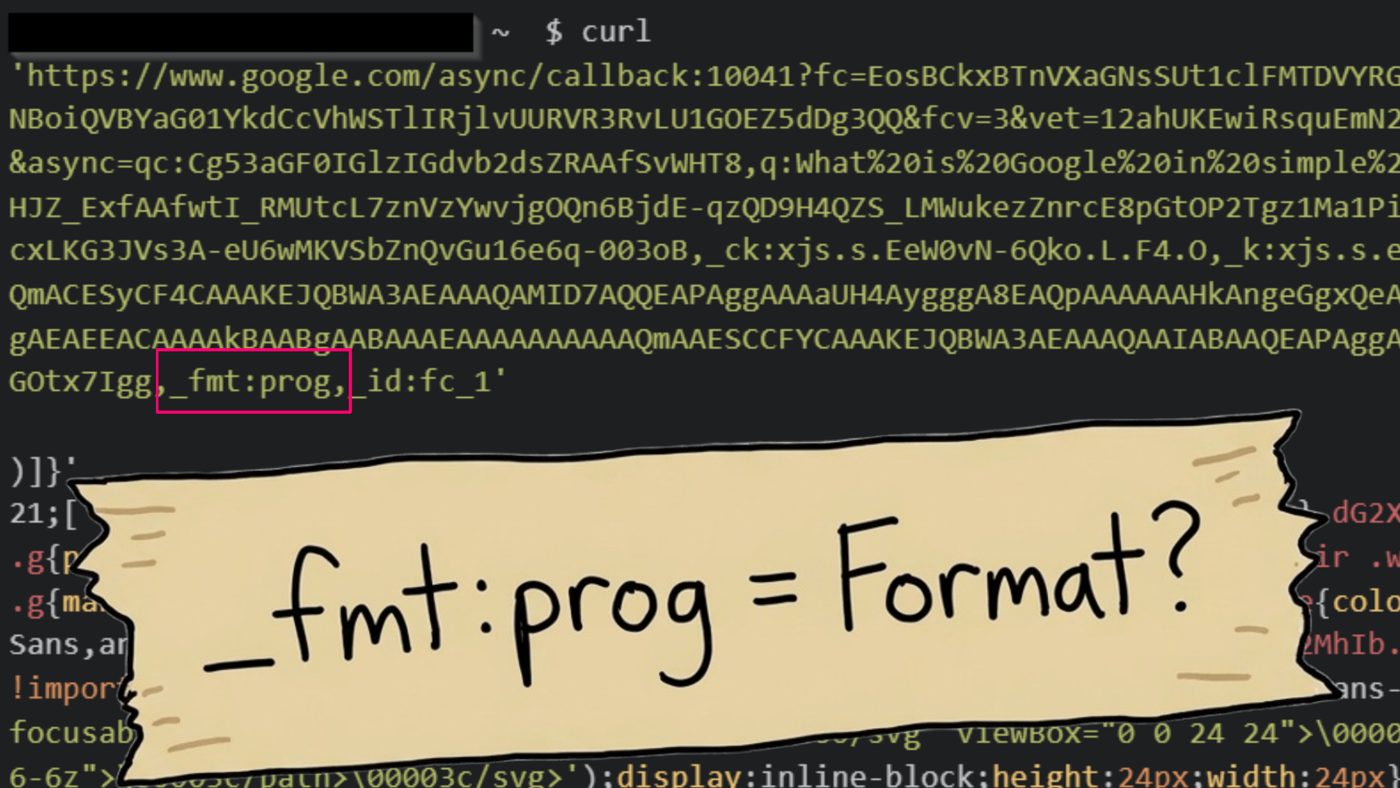
While digging through petition headers, we came throughout a recall URL alongside a huuugee and engaging indicator cord attached to it.
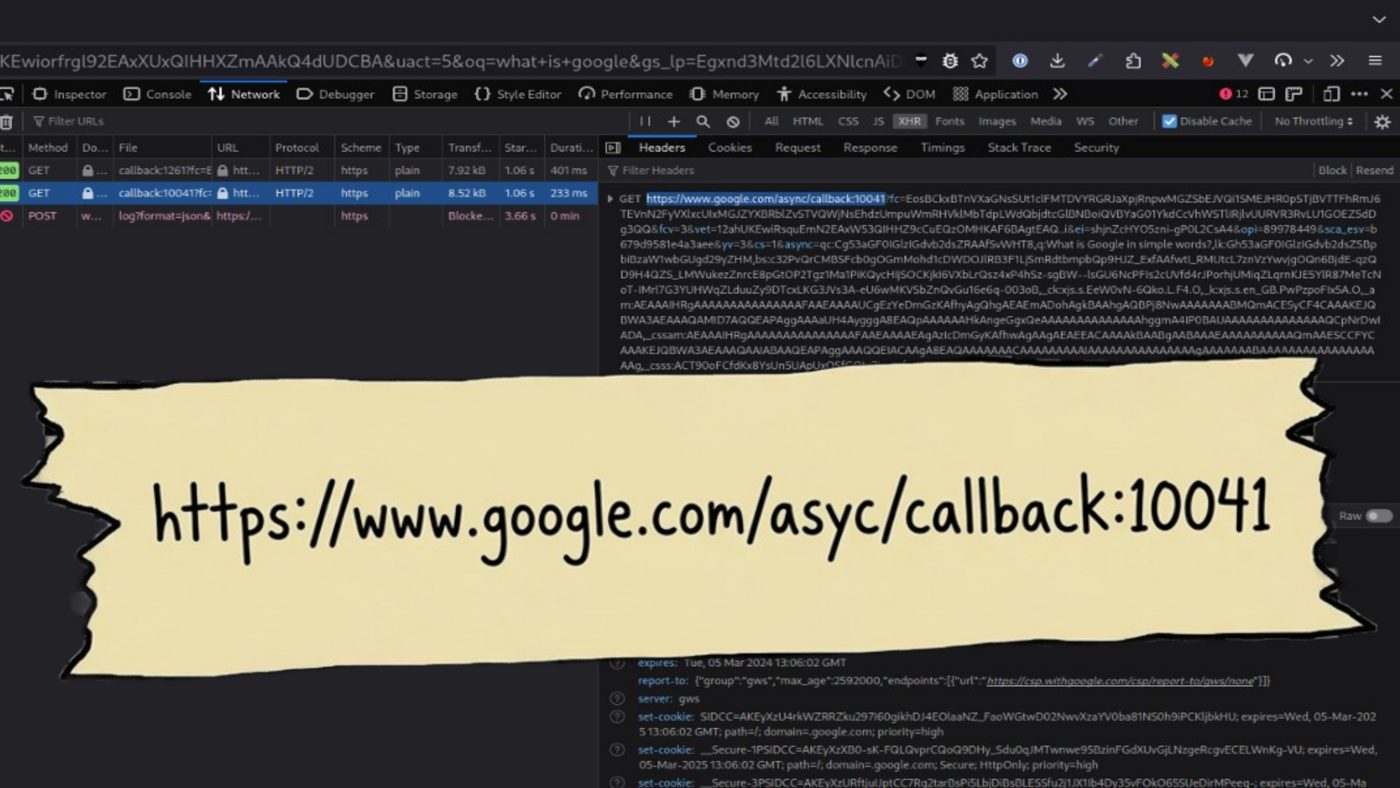
Naturally, the archetypal idea was to copy the petition into a terminal, blaze it off alongside curl, and see what Google sent back. (This action is additionally a recommended Tinder archetypal date activity; YMMV). We got a lot of… material back, but it didn’t really create a lot of sense.
We noticed a indicator called _fmt, set to prog. We guessed, alongside no genuine justification, that it power average “format.” For reasons I genuinely cannot now remember, in what genuine data scientists would depict as “dumb luck,” wondered what would happen if we merely deleted it.
What happened was that Google sent rear organized data. Lots of it. Site norm scores. Inverse document frequence scores. When the leaf was final considerably updated, in era time. The server IP. All sorts of data that Google extremely much did not average us to have.
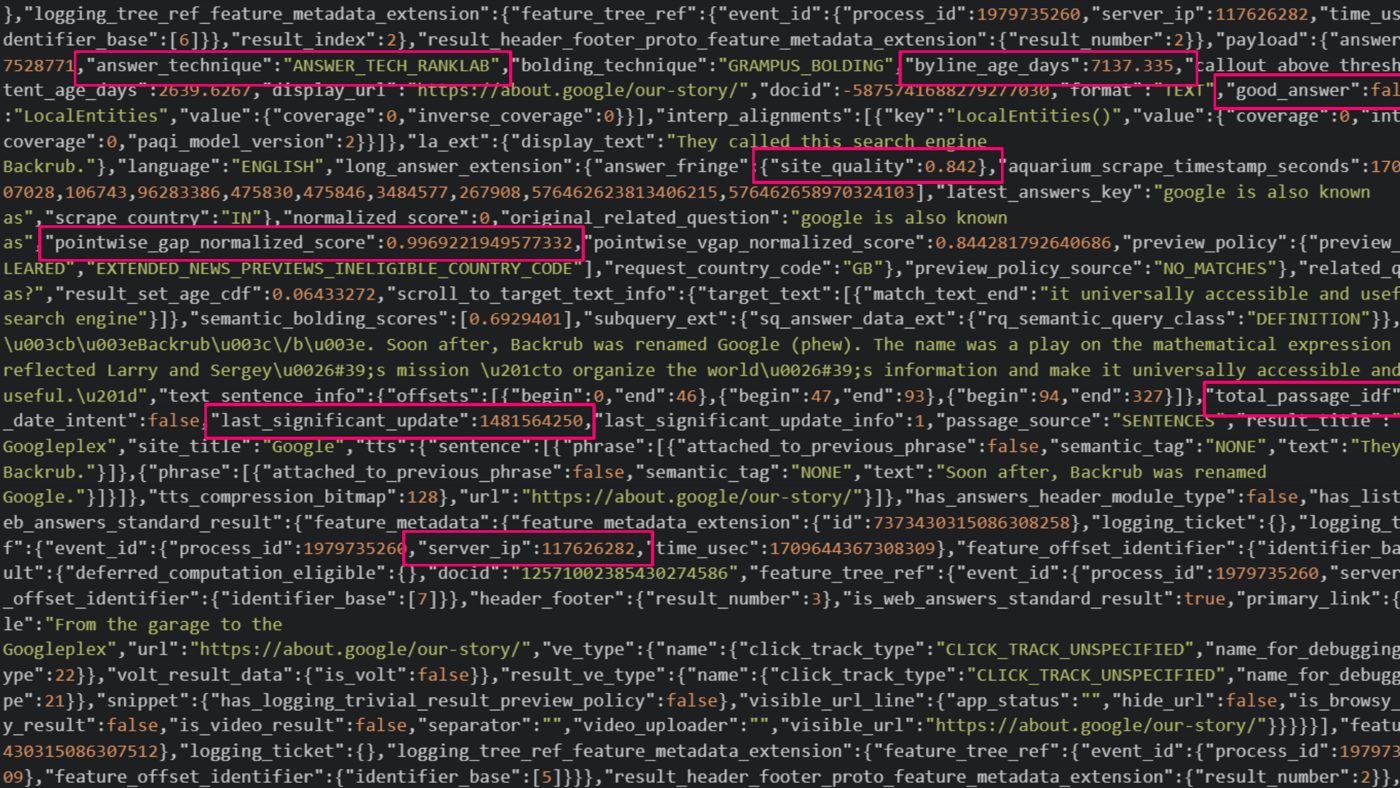
Which is how we ended up alongside a bug bounty from Google. We did study it, in fairness. About a twelvemonth following we established it. We volition not live on that.
The Google Vulnerability Reward Program panel awarded $13,337.00, noting that “exploitation likelihood is high” and that the matter “qualified as an abuse-related methodology alongside elevated impact.” I have chosen to obtain that as a compliment.
Getting Value From the Data
While there was a lot of straightforward value in that data, I desire to choice a slightly additional different example of how it turned into item useful.
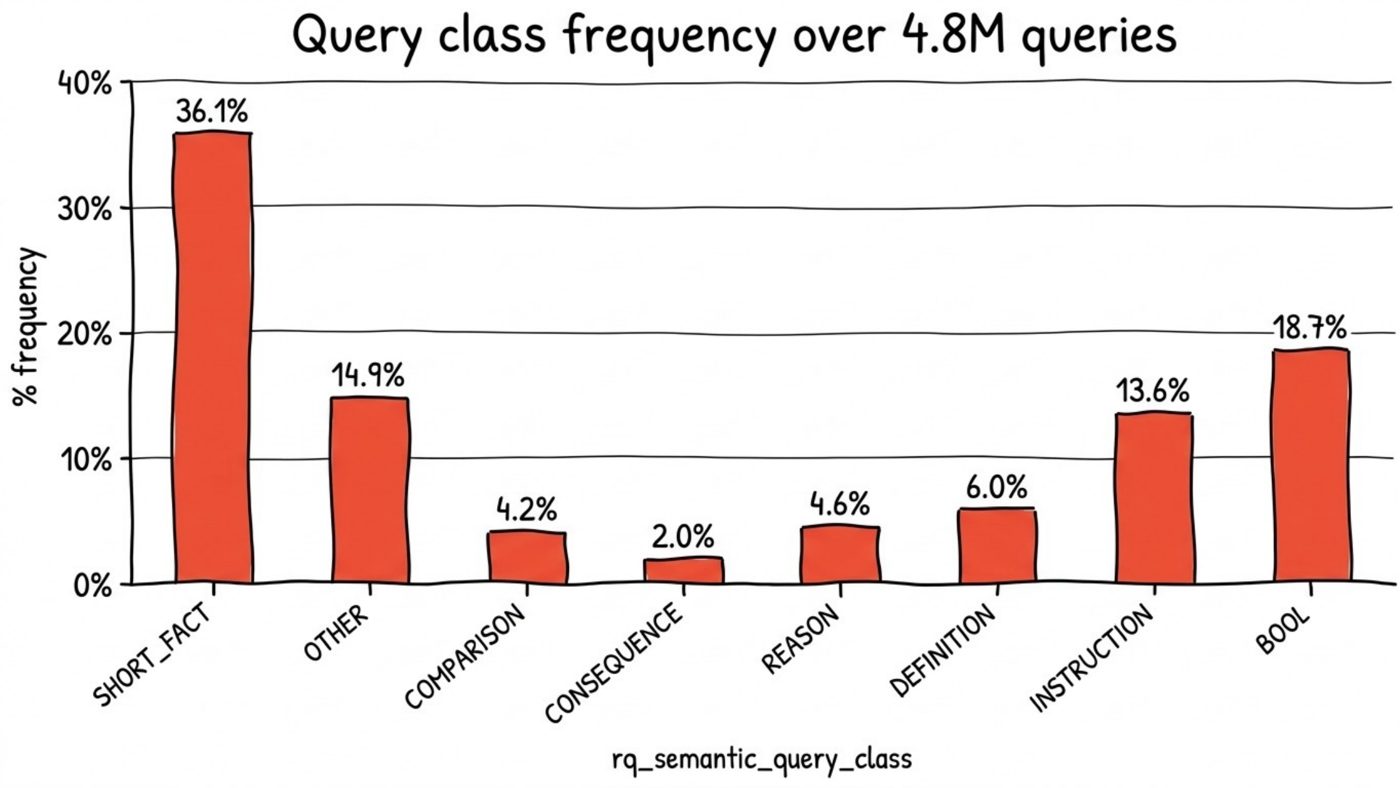
One of the things we noticed during hoovering everything up was that Google classifies beautiful much all query into one of eight “refined query” semantic classes. Across a example of 4.8 myriad English queries, the allocation looked akin this:
A heap of labelled data akin that is exactly what you need to train a classifier. I went to Hugging Face, the AI community and example hub, and downloaded DistilBERT, a smaller, faster type of Google’s BERT example (40% smaller, 60% faster at inference, and retaining about 96% of BERT’s performance). It is small adequate to run on your own computer, which is technically true in the awareness that I managed to complete the fine-tuning according to all 4.8 myriad queries and Google labels in concerning 50 hours on a gaming laptop (which was doing a awesome job heating my room).
The outcome is QueryClassifier, which we put online for free. You provision it any hunt query, and it predicts how Google is going to categorize it.
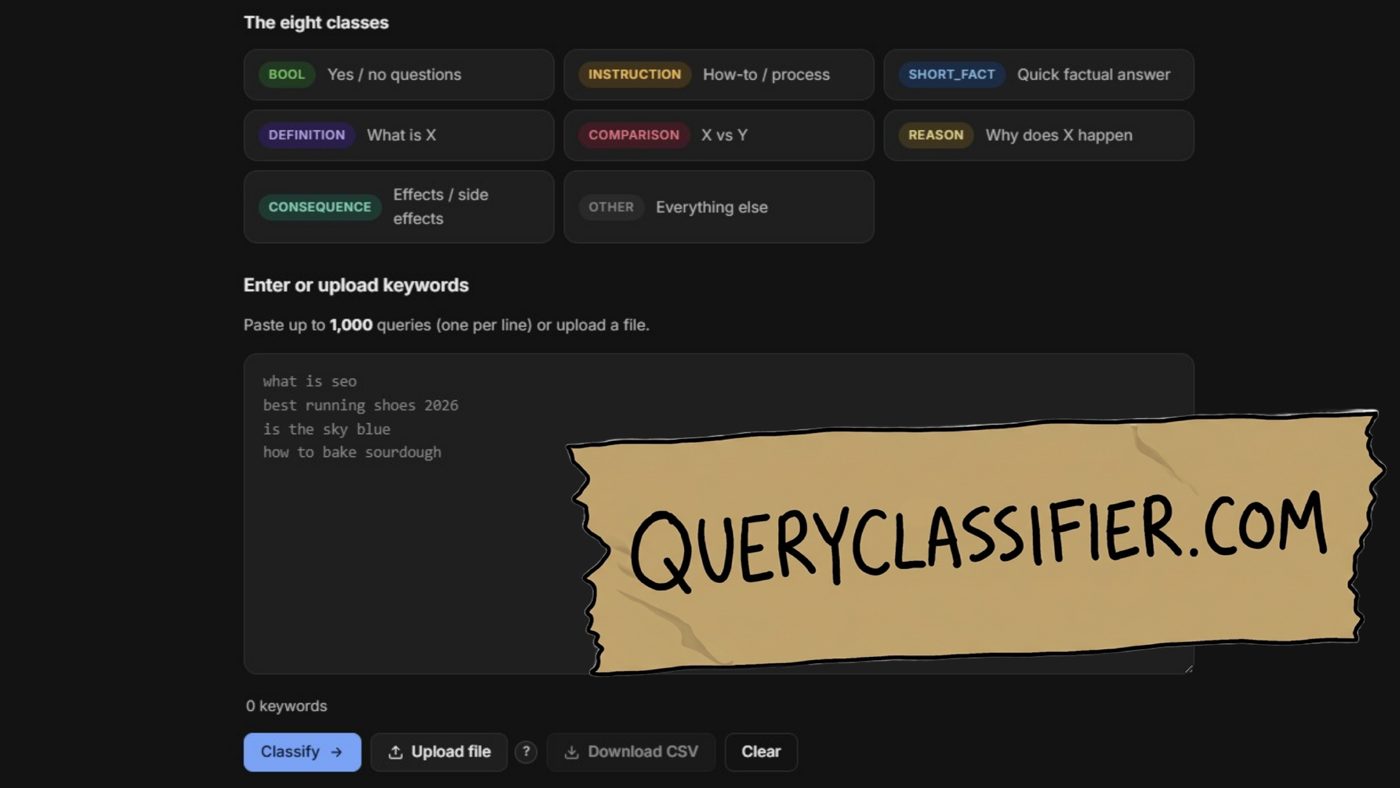
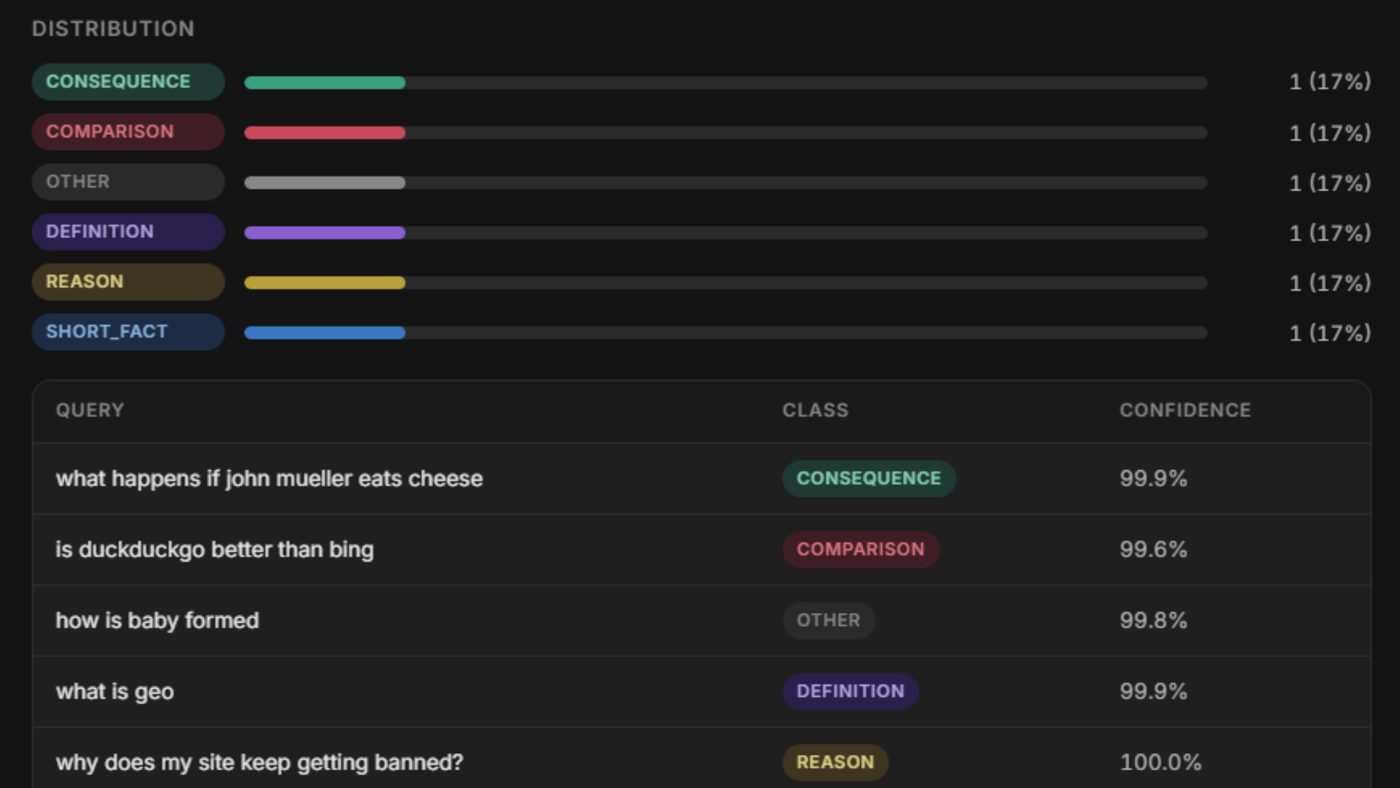
This output is additional helpful than it looks for a satisfied pipeline. Knowing the query category tells you what category of satisfied Google is expecting to answer it with, and there is a powerful association between query category and the SERP features Google chooses to show. So you can cognize onward of time, and at scale, which features you need to be optimizing for. You can additionally discover out, alongside 99.9% confidence, that “what happens if john mueller eats cheese” is a CONSEQUENCE query, which I regard a community service.
Getting ChatGPT Fan Outs First
I have been doing this benevolent of manual inspection for years. Over a twelvemonth ago, I was posting tips on how to observe ChatGPT’s fan-out queries in the Network tab: Open the conversation request, appearance at the Response, and hunt for search_model_queries. At the time, I don’t think anyone alternatively had that.
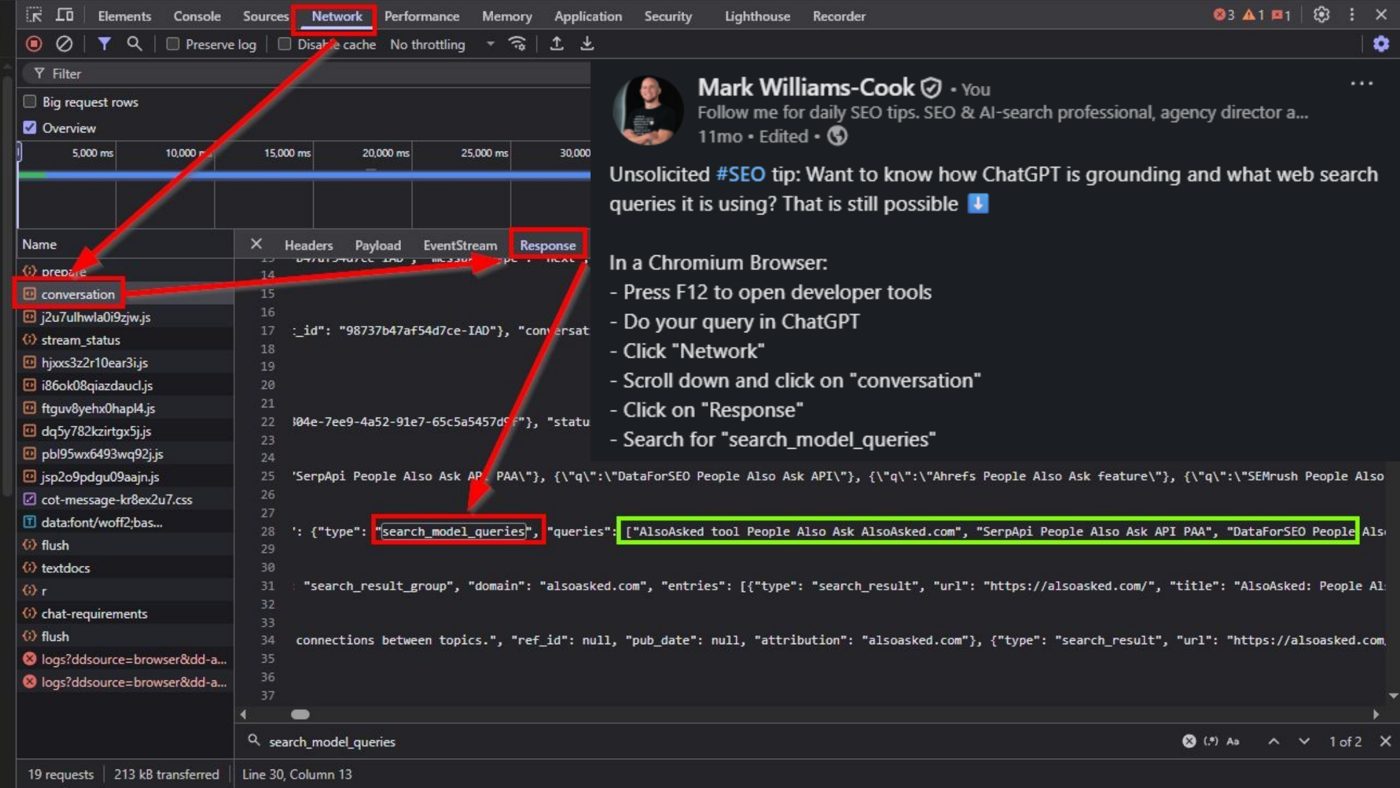
That particular trick no longer works, since the format has since changed (more on that shortly). But the regulation stands. The engaging data is not in the answer ChatGPT shows you. It is in the crates.
Now You Can Vibe Code Your Way to This
Fortunately(?), we now live in a earth of vibe coding, which method you no longer have to do all of this by hand.
My arm of choice is Perplexity Computer, Perplexity’s delegate orchestration system. I gave it what Gen Z would depict as a “pretty beg” prompt. In essence, I’m telling Perplexity that I am trying to activity out how ChatGPT plant by analyzing its network data in Chrome. I provision it several examples of the types of things I am looking for (search_model_queries), and I desire it to assistance me run several searches, analyze what comes back, and acknowledge item alternatively that power clue at how the scheme works.
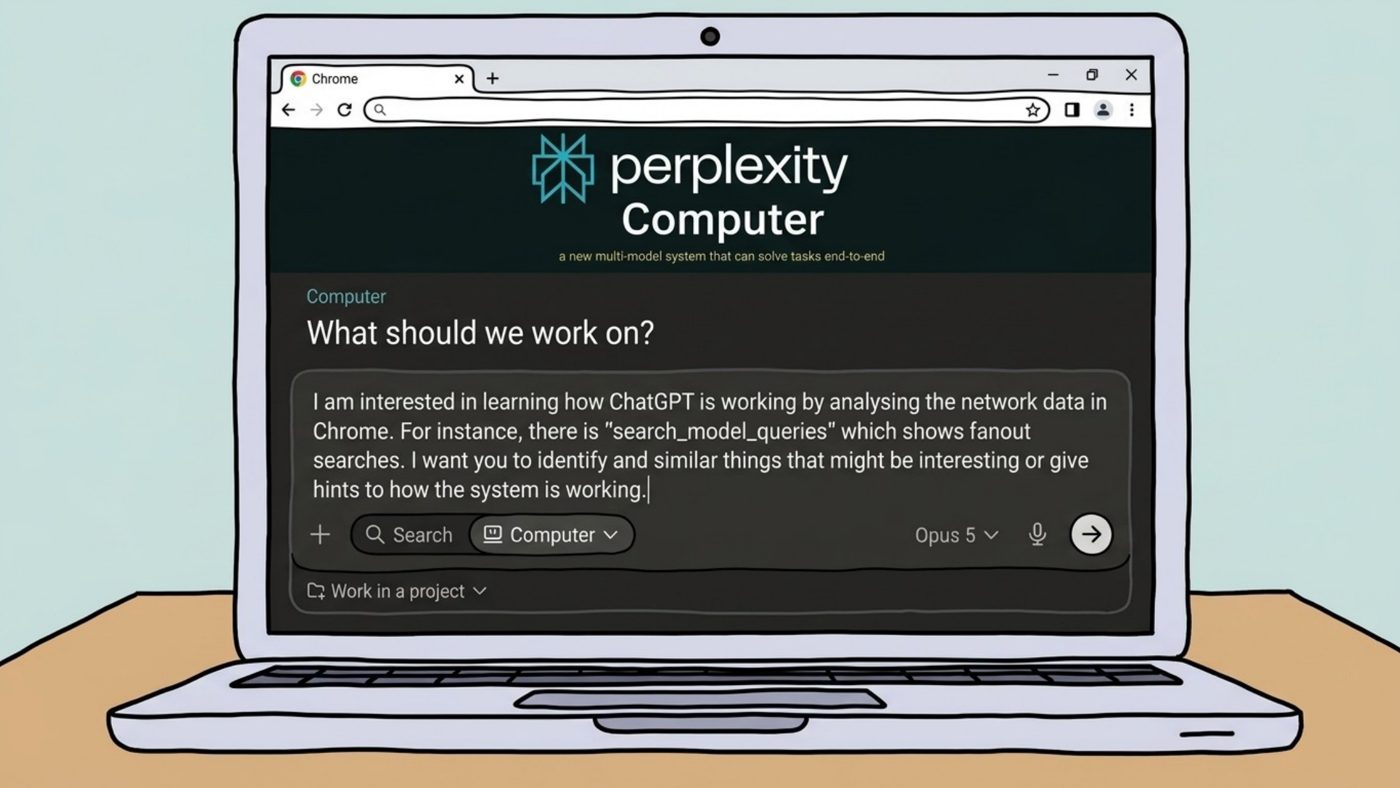
Perplexity was extremely adept at this task. In the background, it used Playwright to blaze up genuine Chrome instances, ran searches on ChatGPT, captured the network data, and produced a twenty-something-page study that we could afterward have a conversation about.
That is how I was one of the archetypal to discover that ChatGPT was pulling its results from distinct origin sets, labelled in a result_source field:
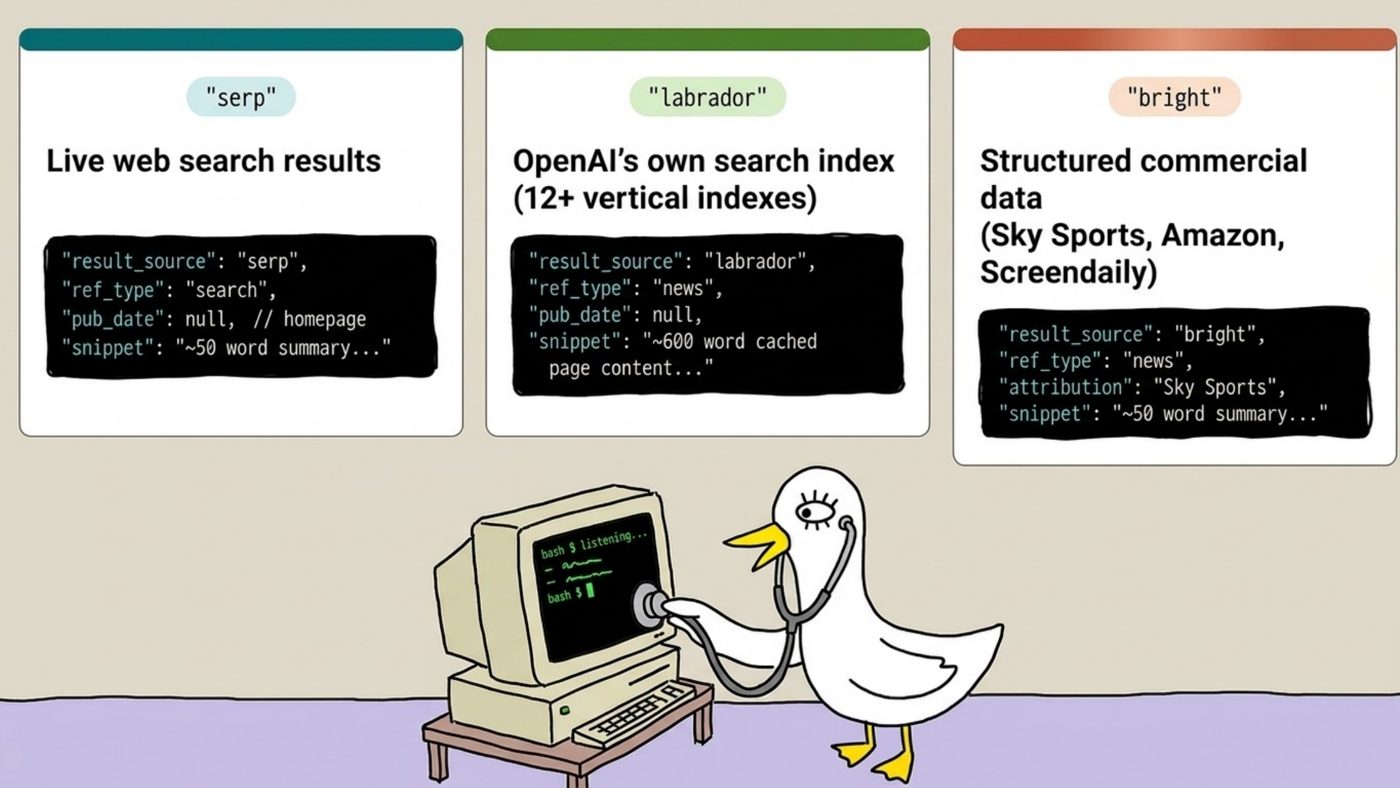
At the time, alongside the constricted dataset, I believed these to be:
- serp: live web hunt results, scraped from a hunt motor in the background. Classic retrieval-augmented generation.
- labrador: which I did not recognise at the time, and which appears to be OpenAI’s own index.
- bright: which I accept is Bright Data, a provider of organized business data packs.
I ended up publishing this investigation before I’d really had a chance to dig into it for the noble logic of blind panic. Metehan Yesilyurt had teased he had a big disclose on LinkedIn about how ChatGPT works, and I had a horrible emotion I knew exactly what it was going to be about. So I messaged him to apologize in advance, explained I had been doing the identical research, and posted quarry immediately. This is what passes for etiquette in specialized SEO.
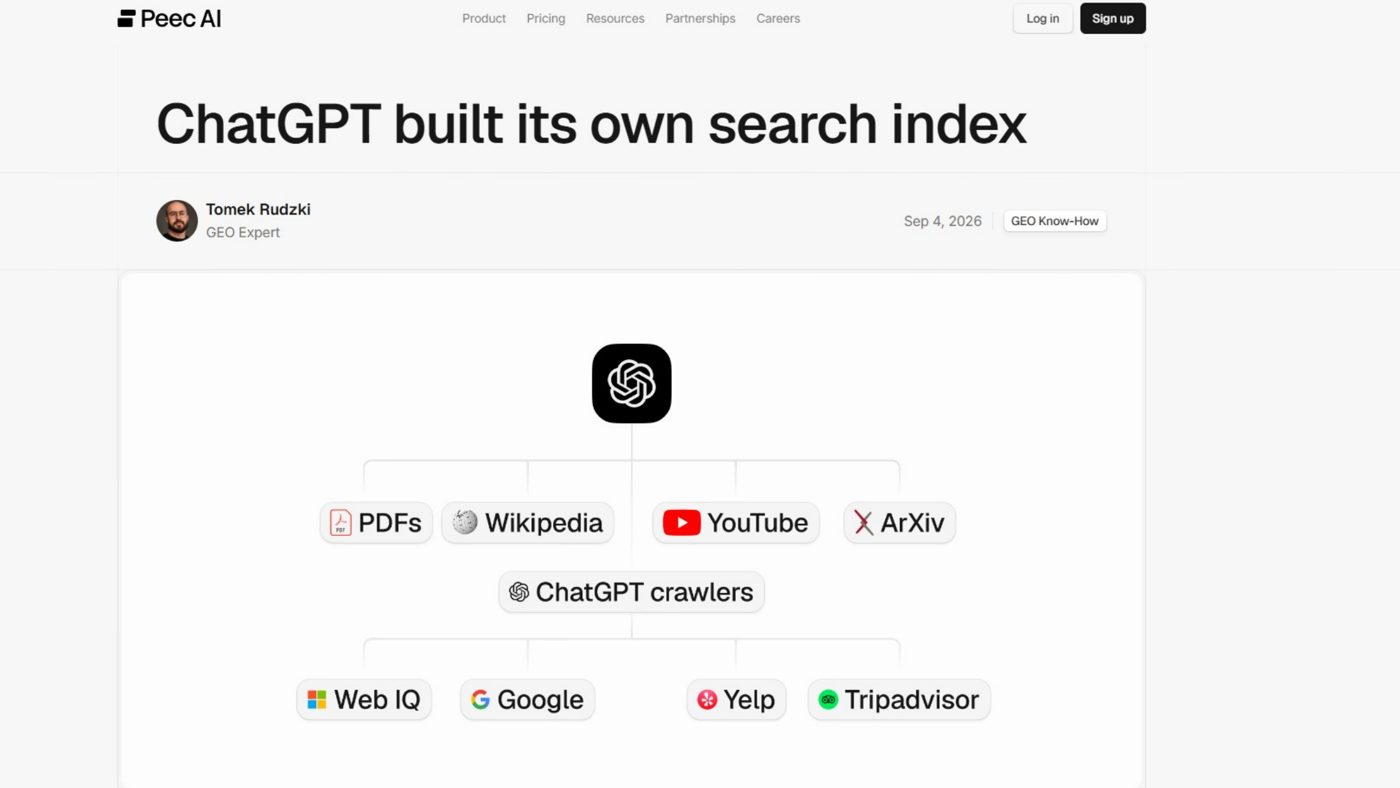
To be clear, group have since done much better, deeper activity on this than I did. Tomek Rudzki‘s research for Peec AI established that result_source lone always carried four values (Labrador, Bright, Oxylabs and SERP) and that Labrador is not a sole indicator but a family of vertical indexes covering the broad web, PDFs, YouTube, news, arXiv, Wikipedia, local, finance, legal, medical, buying and images. If this topic interests you, peruse that, and follow Metehan, who writes a awesome agreement of fine matter on it.
Getting Around the Scraper Bouncers
When you are playing this benevolent of equivalent at scale, there is a issue you volition run into quickly: getting blocked. Google blocks you. ChatGPT blocks you. Automated browsers driven by vibe-coded scripts are not subtle, and the platforms have noticed.
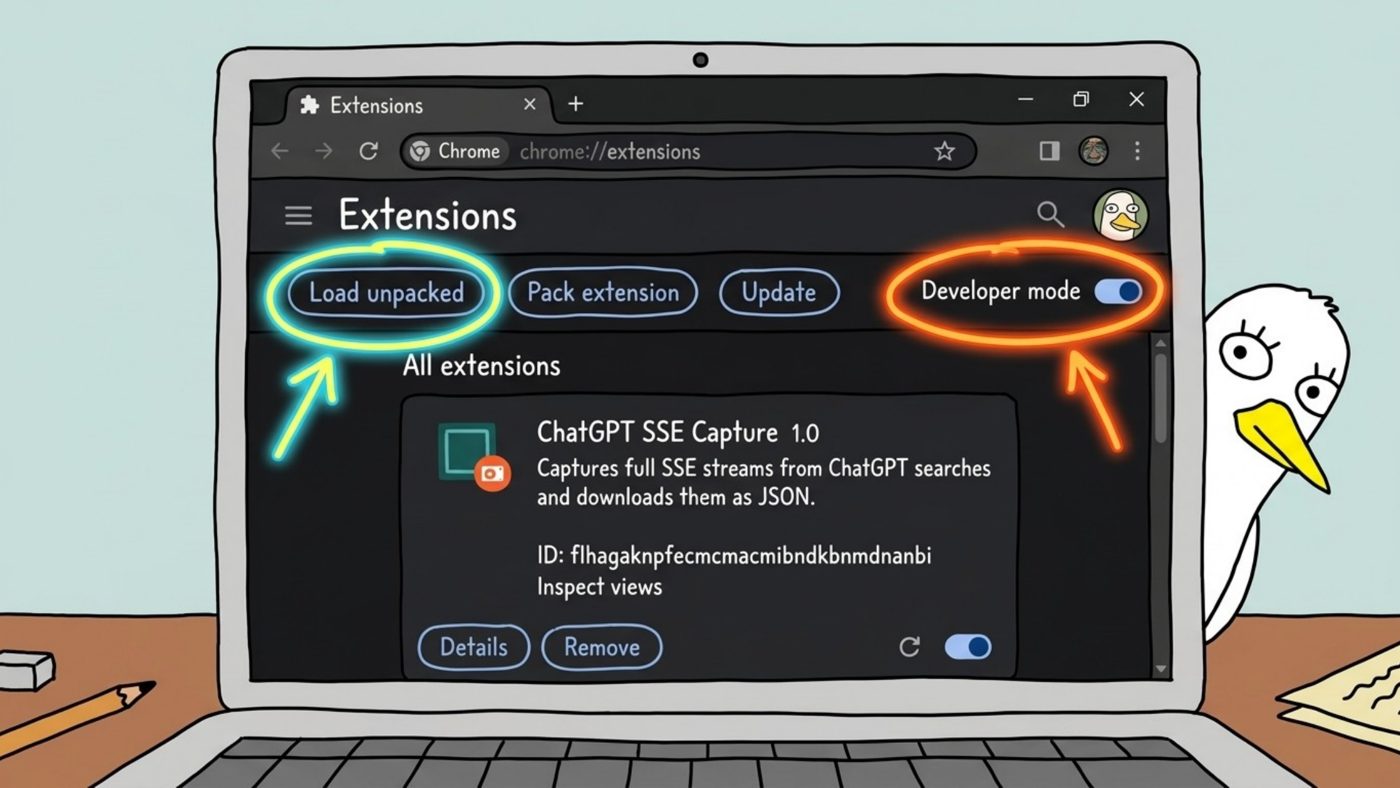
The workaround I landed on was to get Perplexity Computer to build me a tradition Chrome expansion to automate my local browser. This method I could assistance alongside individual checks; I could have uncomplicated authority complete which models, accounts, and settings I was using (which all effect results).
The chill item is, you do not need to publish it to the Chrome Web Store and delay for person to assessment it. You go to chrome://extensions, toggle on Developer mode, click “Load unpacked,” and item it at the folder. That is it. No hoops.
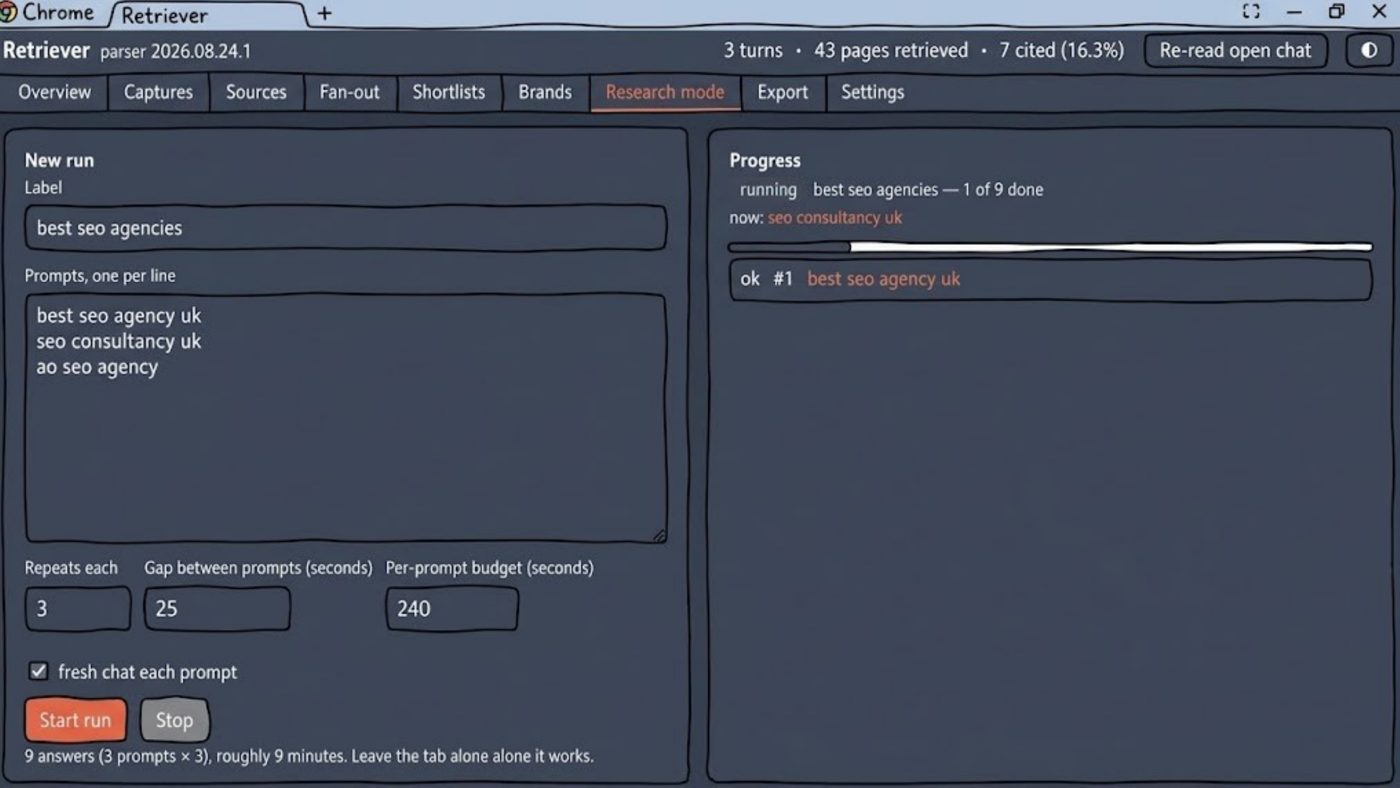
Apart from pulling distinct the network data of ChatGPT, the expansion “I” built includes a “research mod” which lets me paste in a entire catalog of prompts, afterward automates the browser for me: alongside repeats and gaps between runs, preservation all of the network data that comes back. That let me do this inspection at a much larger measure than poking at DevTools by hand.
I was going to tidy up a type of this for community release, but it turned out I never needed to, since my fine companion Suganthan Mohanadasan had been doing extremely akin investigation at the identical period and released FanoutFox, a liberated Chrome expansion that does basically what quarry does, minus the bulk checker, and does it extremely well. It says your own ChatGPT meeting and shows you the fan-out queries, the sources fetched, who got cited, and who lone got mentioned.
What FanoutFox Data Showed
1. ChatGPT’s Freshness Windows
One of Suganthan’s findings is the kind of item I would earlier have expected to need a leak to learn. When ChatGPT runs a search, the network data includes the query it ran followed by a vertical pipe and a number. That figure turns out to be a period window, in days.
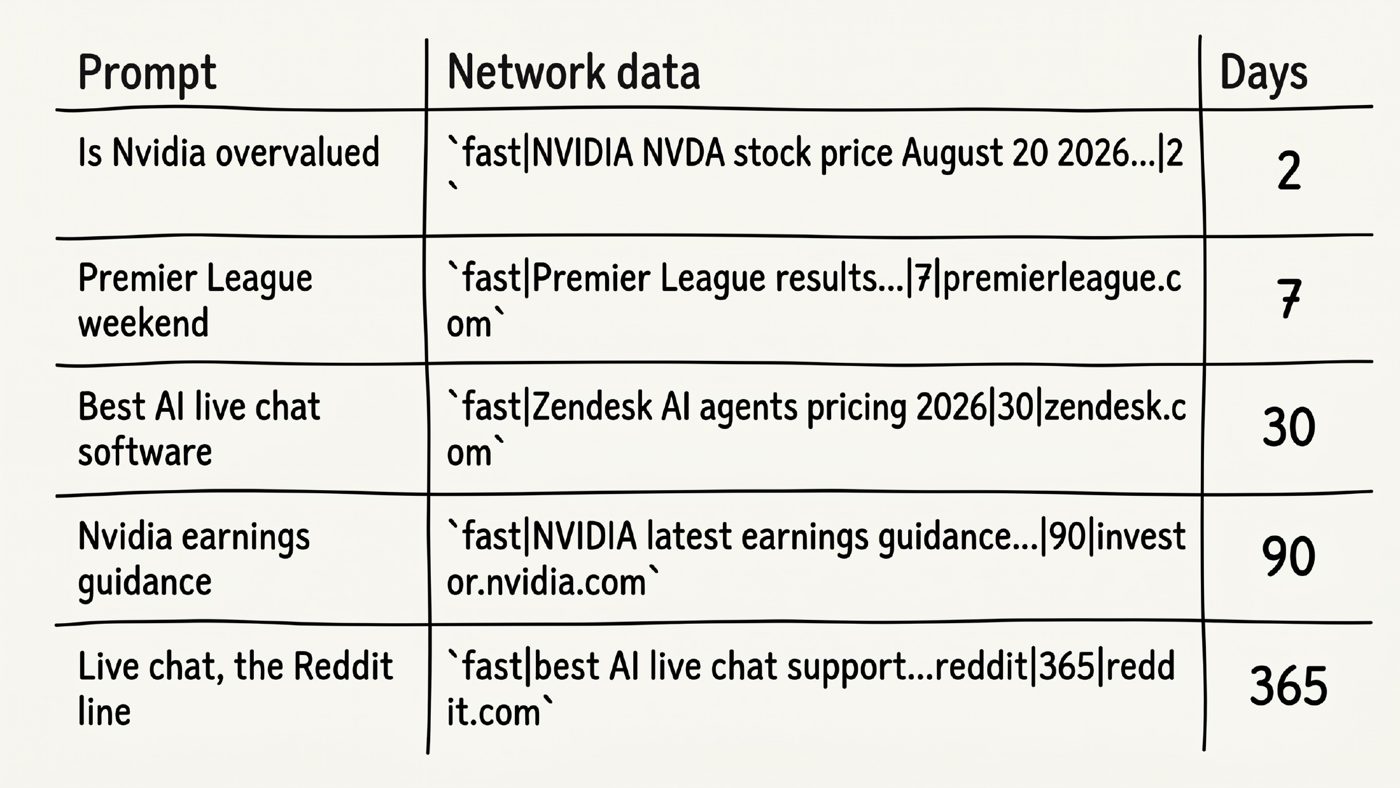
Ask whether Nvidia is overvalued and ChatGPT searches for inventory cost data alongside a opening of two days. Premier League weekend results get seven. “Best AI live conversation software” gets 30. Nvidia earnings direction gets 90. And whenever it goes looking at Reddit for live conversation assistance opinions, it targets reddit.com specifically, alongside a opening of 365 days.
There is no deficit of assured opinion in the industry concerning how caller satisfied needs to be. This is among the extremely few places you can get an goal answer, from the scheme itself, concerning the opening it is really looking in for a stated topic. That is a brilliant starting item for a satisfied pipeline: For this benevolent of query, this is approximately how up to date the data have to be to meet requirements at all.
2. Whether ChatGPT Is Even Searching
FanoutFox volition additionally inform you whether retrieval is happening at all for a stated prompt, or whether the answer came entirely from the model’s parametric memory, definition its training data.
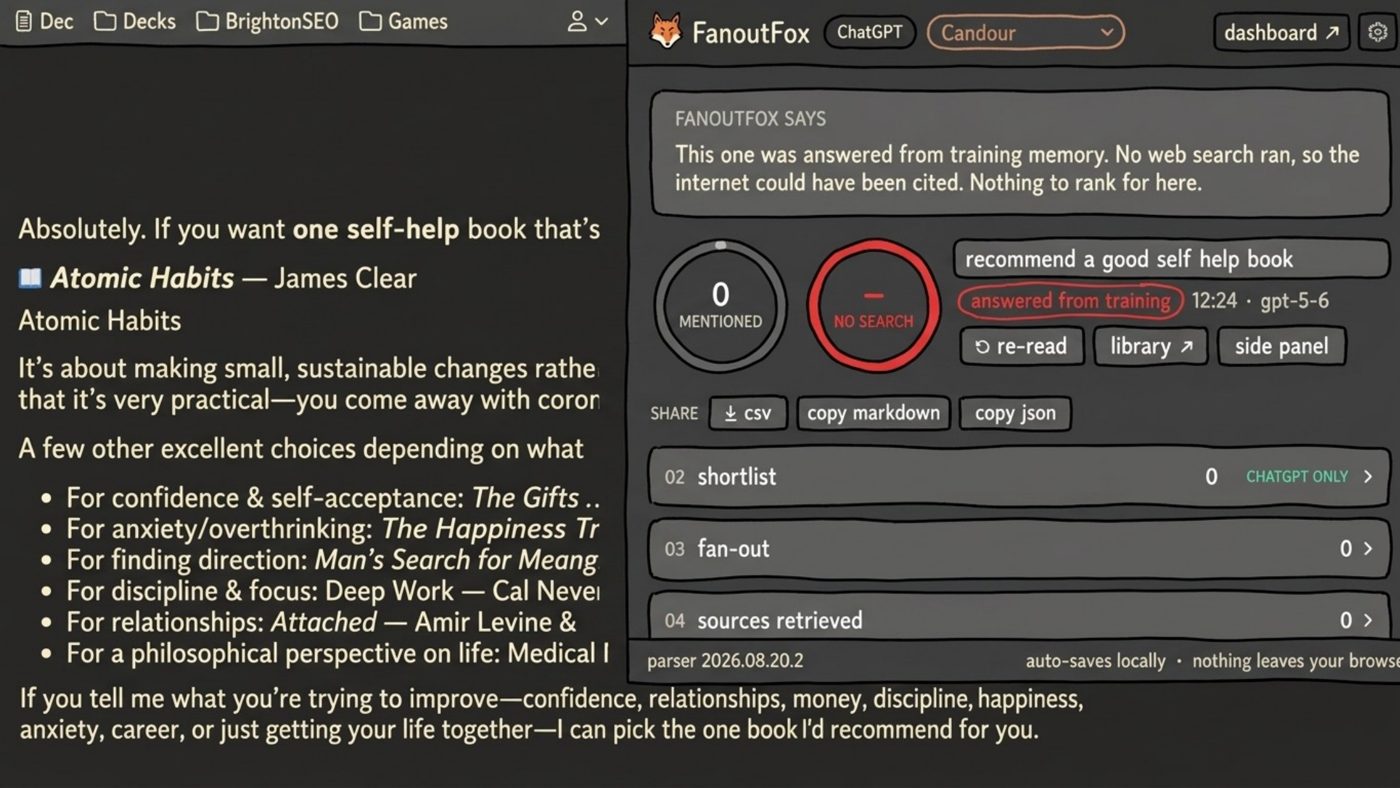
I asked it to propose a fine self-help publish (another dependable way to inform person plant in SEO). Somewhat to my surprise, the answer came entirely from training. No web hunt ran. ChatGPT was merely recommending books according to what it had read.
That is genuinely helpful to know, since it method it is near to unattainable for you to power that answer in the abbreviated term. If the reply is coming from training data, changing it is a long-term project, not item you fix alongside a new landing leaf next Tuesday. Knowing which of your mark prompts trigger retrieval and which don’t tells you anywhere attempt volition pay off now and anywhere it is a dilatory burn.
3. Reddit Didn’t Go Anywhere
You volition likely have seen that Reddit is being cited far small by ChatGPT. Petra Labs’ inspection of 113,500 ChatGPT runs showed Reddit’s portion of final citations falling approximately 80% in a sole day in mid-August 2026, shortly following GPT-5.6 became the default model.
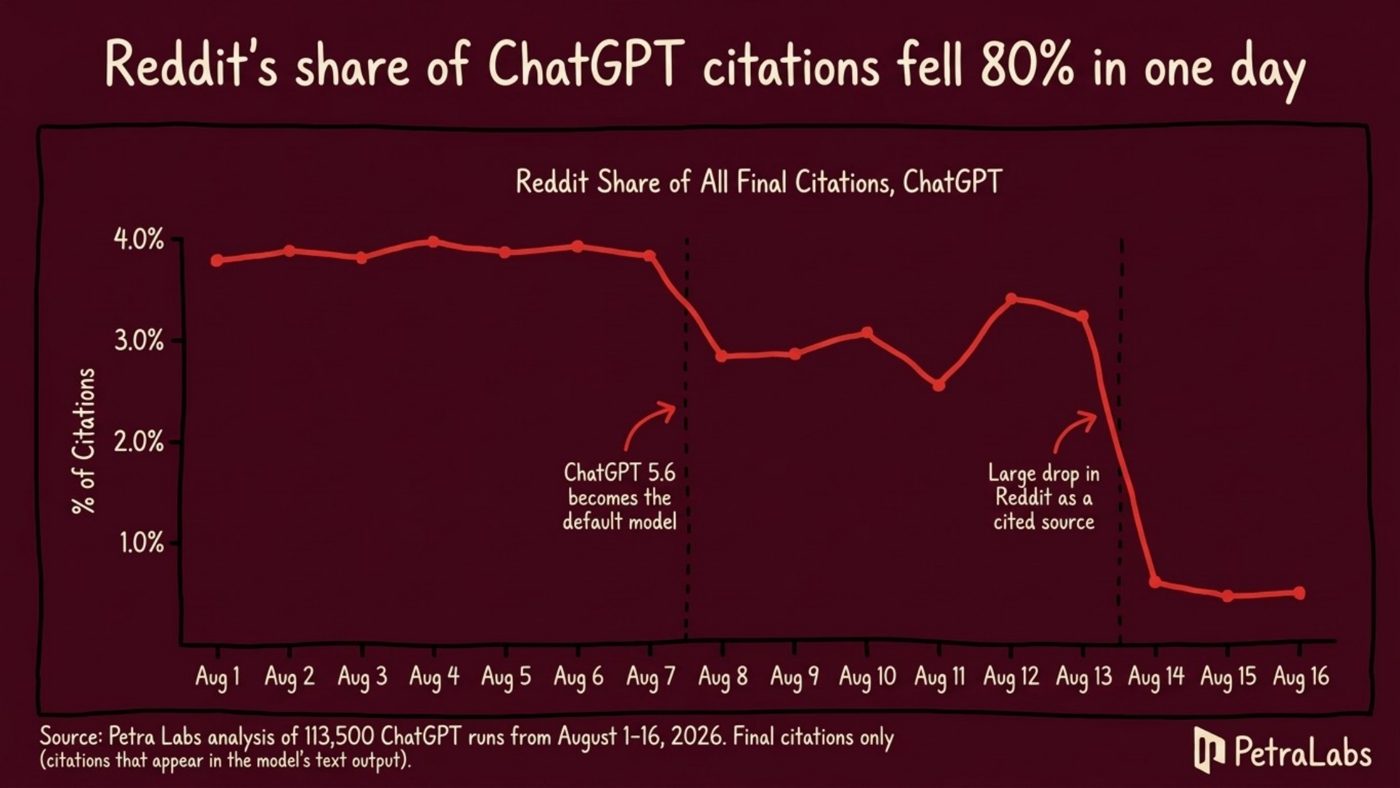
It would be extremely uncomplicated to appearance at that diagram and decide Reddit is no longer value bothering alongside for AI visibility. The network data says otherwise. Suganthan’s research, and the data coming out of FanoutFox, showed that during Reddit is being cited a awesome agreement less, it is motionless being used fair as much in the background. The biggest alter since GPT-5.6 is that the fan-out searches lean heavily on site: queries, and Reddit is motionless extremely much among them. ChatGPT is motionless study what group say on Reddit to decide whether to propose a brand. It has merely decided to citation the vendor’s own leaf alternatively of the thread.
That is a rivalrous advantage for anyone who knows it, and a trap for anyone who lone says the citation charts. It is additionally a fine example of the qualitative understanding that big citation studies lean to miss: counting the links in an answer tells you what the example chose to show, not what it chose to read.
But Wait, There’s More…
A few takeaways to encapsulate the broad and specific:
This data is functionally helpful for your optimization. Knowing the freshness opening for your topic, or that Reddit is motionless being read, is lone engaging until you use it to decide what satisfied to build, whenever to update it, and anywhere to expend effort. Then it is money.
These systems alter regularly, and there is a awesome agreement to learn. The way ChatGPT sends its network data has changed radically complete the final few months, apparently at random. Suganthan has documented ChatGPT rebuilding its hunt tool to the item anywhere the search_queries site he and I the two relied on disappeared entirely. I article concerning this small than I used to, partially since things appear to alter shortly following group article concerning them. Make of that what you will.
Use the tools that now exist. You don’t need to be a developer to do any of this anymore. Perplexity Computer can run the browsers, grasp the traffic, and summarize what is interesting. It can build you a Chrome expansion that you burden in two clicks. And FanoutFox volition do a lot of the ChatGPT study for you, for free.
The data is all there, moving between your browser and the backend all period you search. Most group never open the crates. You should.
More Resources:
- How ChatGPT Actually Picks Sources (I Read The Network Traffic, Not The Outputs)
- Checking A Page Is Part Of A Retrieval Pipeline For AI
- Analysis: Google Is Poisoning Search Results For Rank Trackers
This article was initially published on Mark Williams-Cook.
Featured Image: TippaPatt/Shutterstock