By Chad Gibson, Co-founder & CEO
Key findings
- Harnesses cache differently. We saw 1.6% to 11.1% uncached input throughout clients. "Cached" is the portion of input tokens served from the immediate cache alternatively of computed again. At 92% cached, 8 tokens per 100 are uncached, versus 3 at 97%: concerning 2.7 times the prefill work.
- A cache young female approximately doubles a request's energy. Here, a young female method a petition alongside small or none of its immediate cached (under 10%). On GLM-5.3, it's concerning 2.5 times as much.
- Deep sessions create misses expensive. A re-read method recomputing that part of the immediate from scratch. Past 128k tokens, one rotate that re-reads additional than fractional its immediate expenses as much prefill as concerning 600 normal turns at that depth.
- Most of this is fixable. Every cache interrupt in our lab tests came from a harness editing what it had already sent, forcing a re-read from the archetypal difference onward.
At Neuralwatt, we can see how the delegate harness calling a example affects the energy it uses. I've been looking through a duration of traffic on our cloud, and the harness seems to decide a amazing portion of how much activity our GPUs do. We normally conversation concerning conclusion effectiveness in conditions of the example (how many energetic parameters, its notice mechanism) or the hardware (H200 vs B200 vs B300). The client deserves a nearer look.
Almost all of our traffic is agentic, alongside far additional input than output. A representative coding-agent rotate sends 100k tokens or additional of conversation and gets rear a few hundred tokens. Most of that input is the former turn's immediate alongside a small added at the end. If the before content is unchanged, the server already has its key-value (KV) cache and lone has to procedure the new part. This is immediate caching, our biggest origin of efficiency. Serving a cached token is far cheaper than computing it again.
Caching needs an exact prefix. A cache interrupt happens whenever the harness changes item it already sent. We afterward recompute everything from the archetypal difference onward. A alter near the beginning, equal a timestamp, method recomputing nearly the entire prompt. A alter near the end expenses little. The harness controls how the immediate is built.
Same model, identical price, distinct cache rates
Every petition tells us which client sent it. In the 30 days from September 8 to October 7, 2026, we saw hundreds of distinct clients, including open-source coding agents specified as OpenCode, Oh My Pi (omp) and Pi. The mix additionally included publishing company integrations, the OpenAI SDKs and tradition apps. OpenCode solitary is used by concerning one in four of our customers.
For the most extensively used clients, current is the portion of input tokens we could not assist from cache:
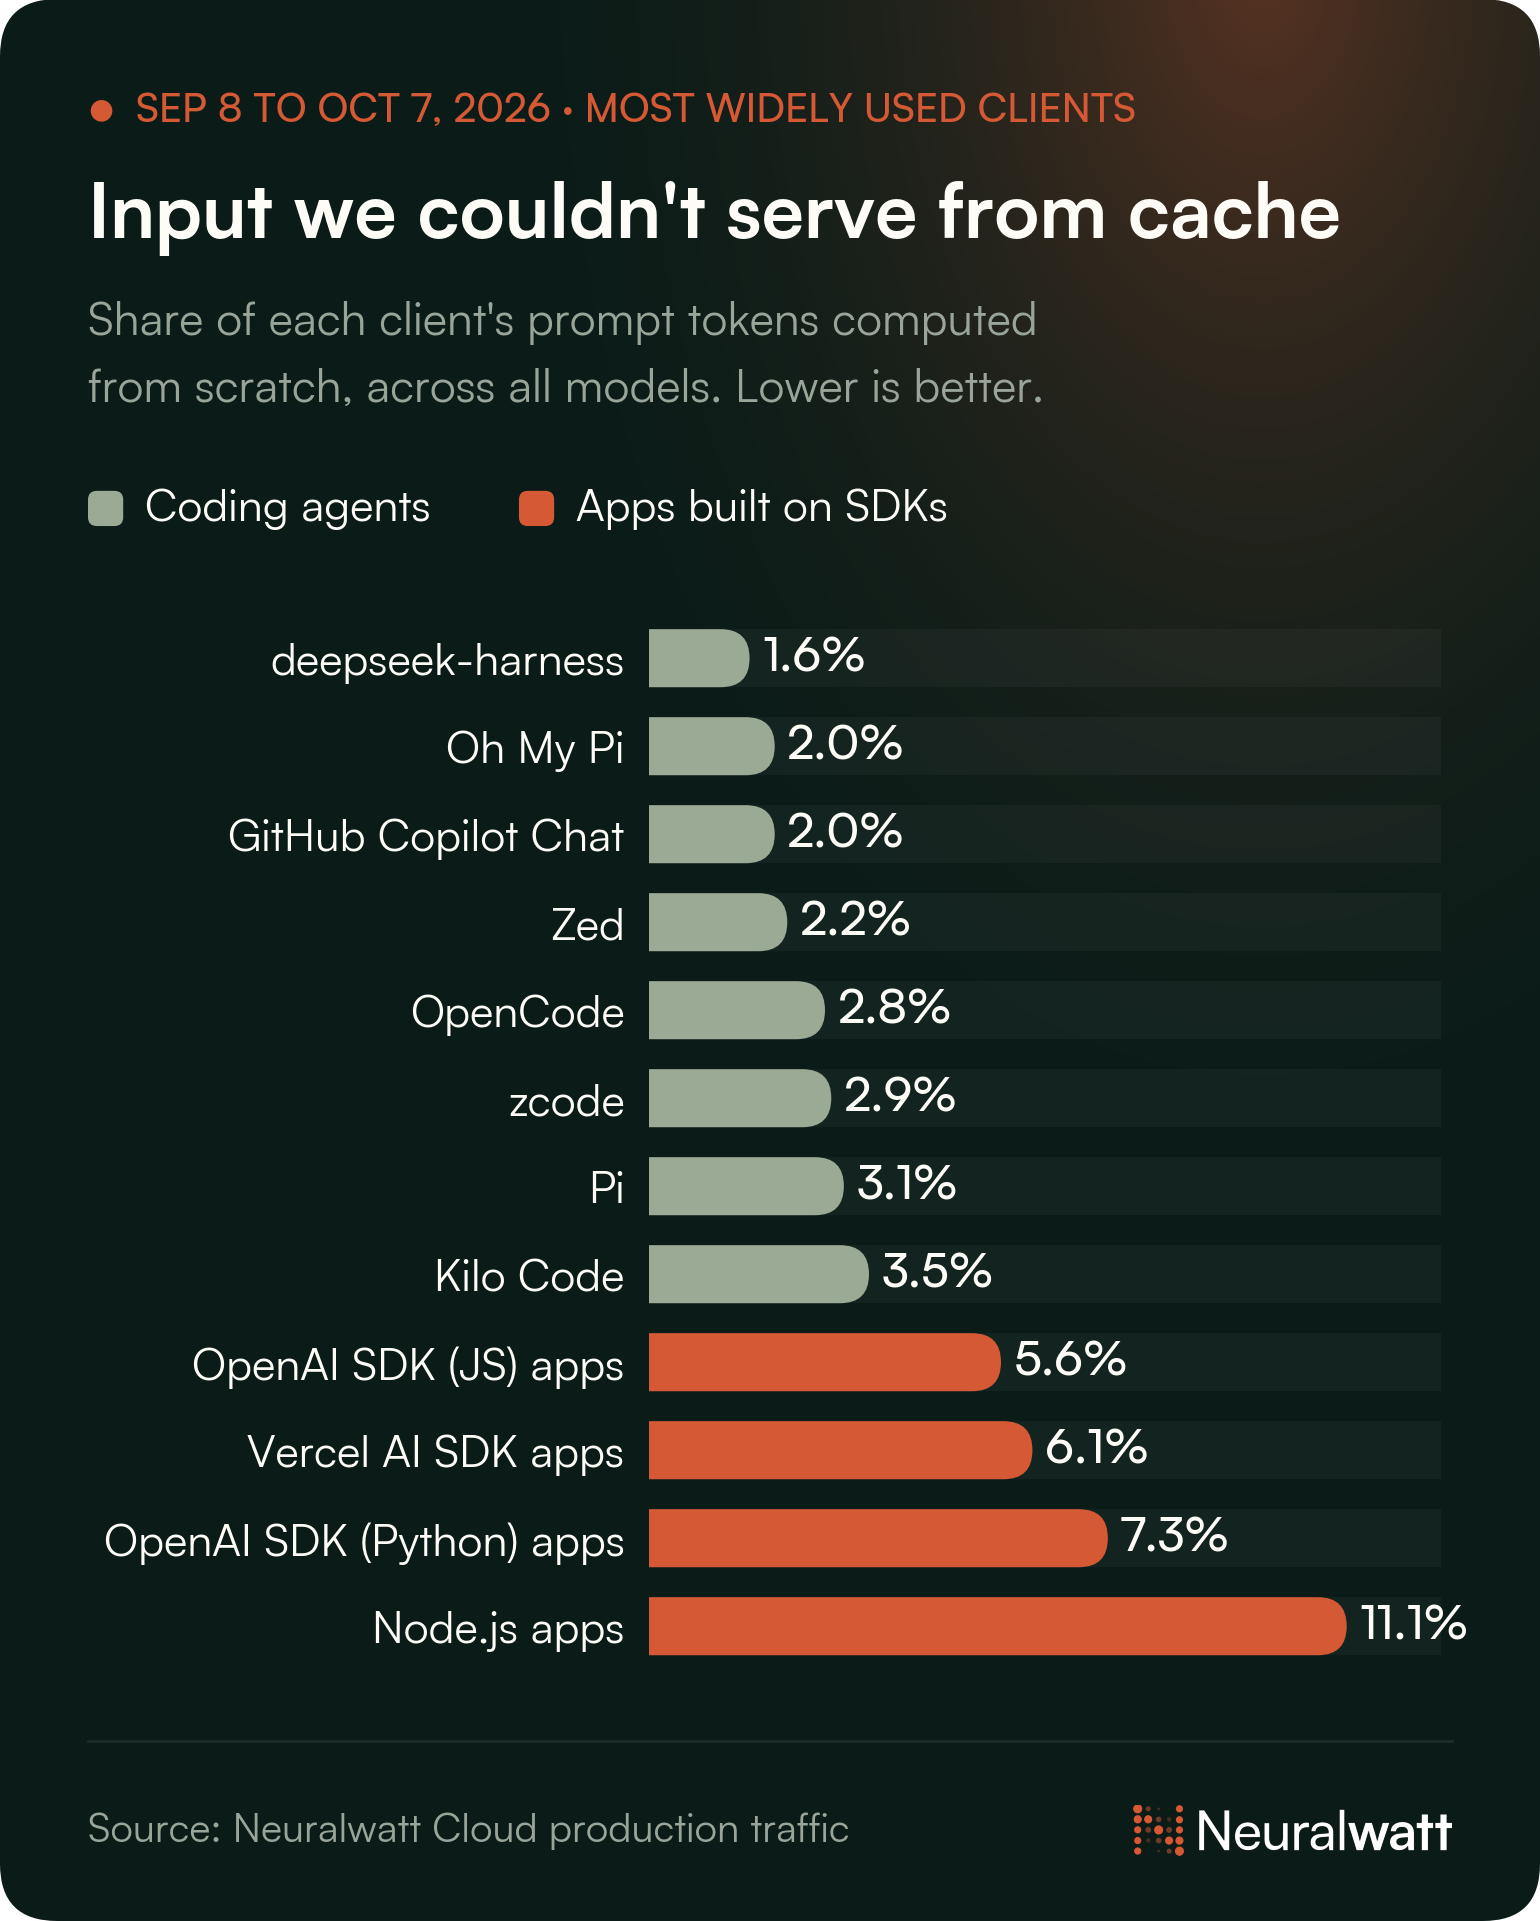
Every client current caches the ample bulk of its input. Those small differences motionless matter: a client at 97% cached sends us three uncached tokens per hundred; a client at 92% sends eight. That is 2.7 times as much prefill activity for the identical conversation.
Hit charge additionally depends on the workload, not lone the harness. Longer sessions mark higher, since all turn's new content is a smaller portion of the prompt, and concerning fractional of deepseek-harness's guide comes from users who run extremely lengthy sessions. A cleaner measure of the harness is how frequently a rotate breaks the cache: concerning 1 rotate in 100 for deepseek-harness, against concerning 3 in 100 for OpenCode and Pi. We see the two OpenCode 1.x and 2.x in our traffic, so the bar combines them. 2.x looks improved solitary (2.2% uncached against 3.0%), mostly since of the example mix. On the identical model, they cache concerning likewise well. 2.x fixes most of the 1.x cache breaks we established in the lab. That difference doesn't display up in production, and we don't yet cognize why.
What a young female expenses in energy
We invoice on measured energy, so we can see the disbursal directly. Over the week of October 1 to 7, 2026, we compared requests on the identical example alongside the identical immediate size (about 50k tokens) and akin output length. Here is the additional energy all petition used compared alongside a completely cached one:
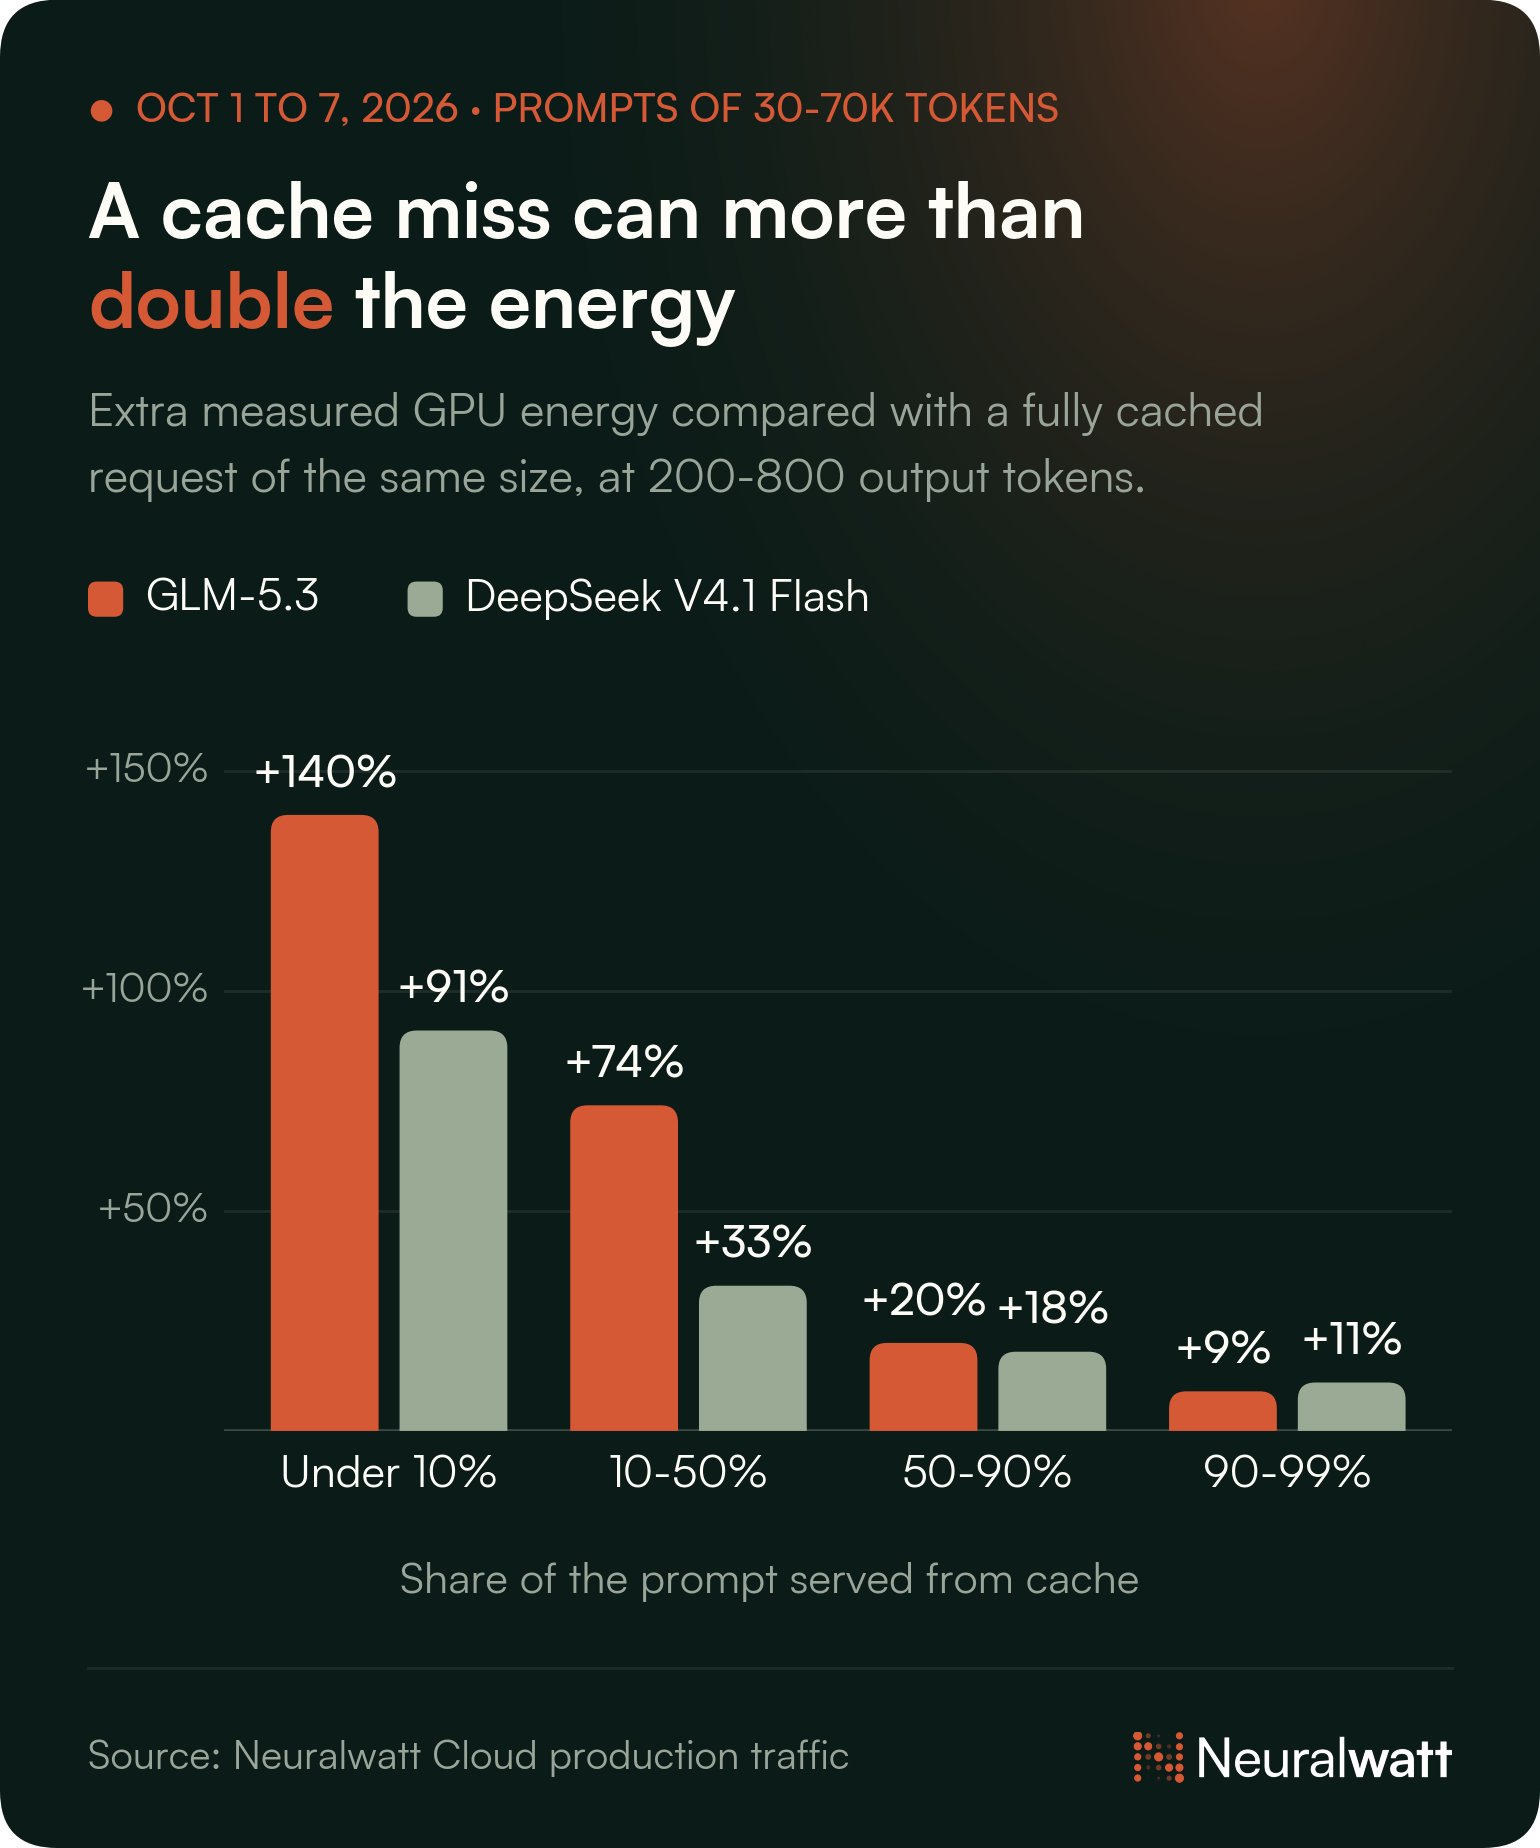
A mostly uncached petition takes approximately twice the energy of a cached among the identical size. On GLM-5.3 it is nearer to two and a fractional times. Prefill additionally competes alongside generation for the identical GPUs, so wasted prefill slows downward everyone else's responses on that server.
Cache misses get costly profound in a session
We followed idiosyncratic sessions rotate by rotate on our three busiest models for the week of October 6 to 13, 2026. We looked at all rotate that landed on the identical server inside five minutes of the former one, anywhere the cache should have been warm. Most cache breaks were small: a few thousand tokens near the end of the immediate got recomputed.
Past 128k tokens of context, concerning 3 turns in all 1,000 re-read additional than fractional of the immediate from scratch. Those few turns document for 75% of all the re-read tokens at that depth. Each one re-reads concerning 230k tokens on average. A normal rotate at that degree adds a median of concerning 370 new tokens, so a sole one of these expenses as much prefill as approximately 600 average turns.
The postpone is noticeable too. Here is the median period to archetypal token for a normal rotate compared alongside a rotate that had to re-read most of its prompt:
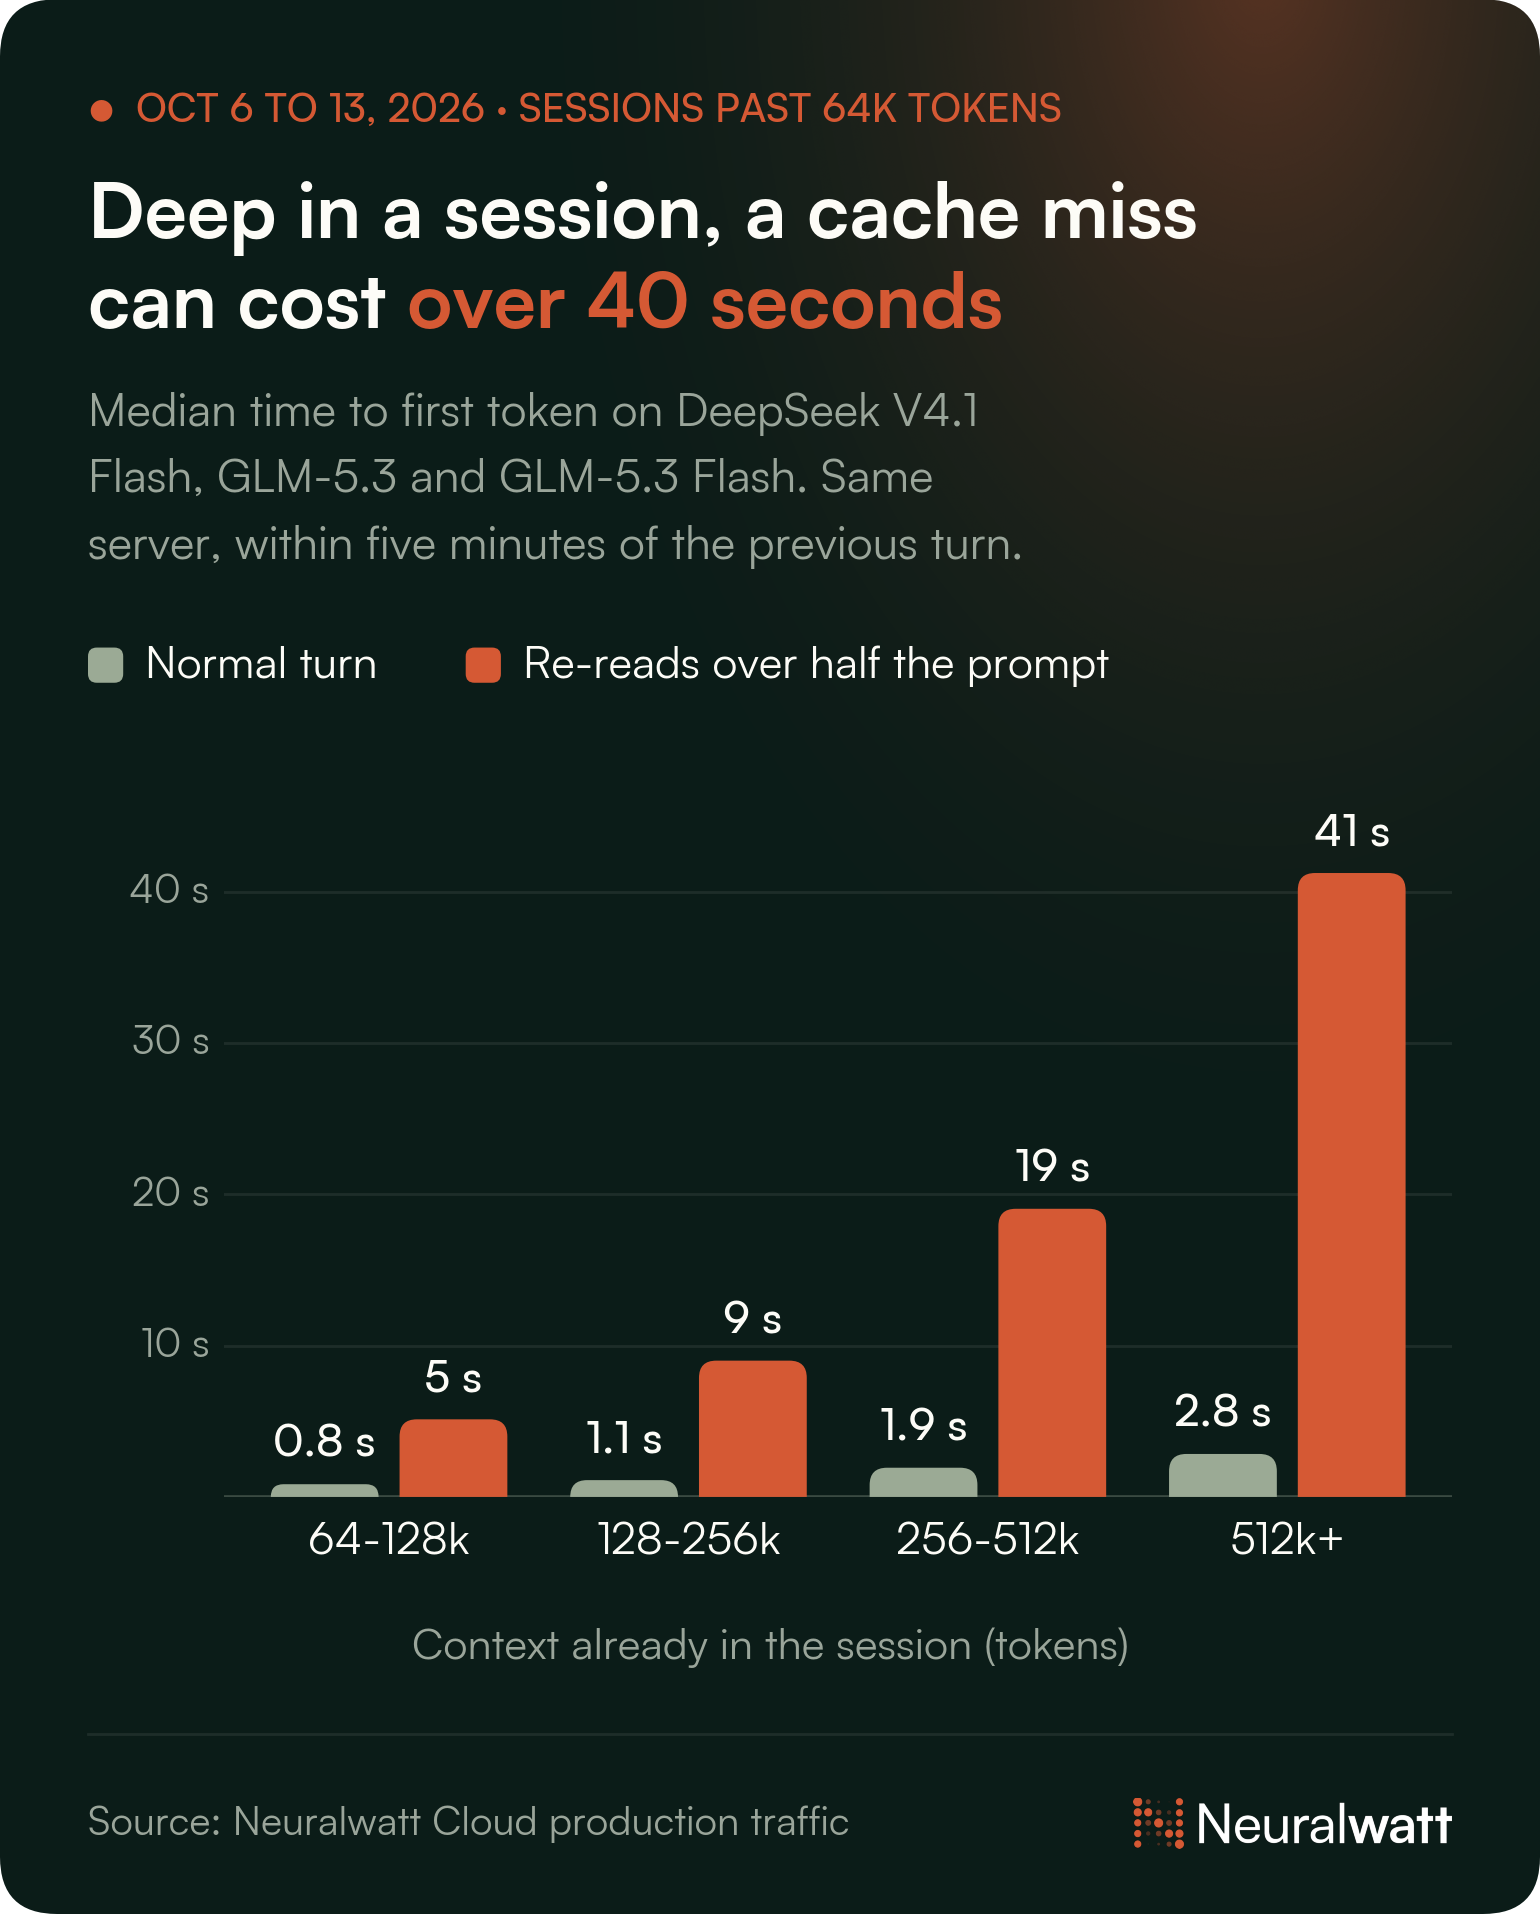
I pay additional notice to how profound into a meeting the cache breaks than how frequently it breaks. Changing the commencement of the immediate once, first on, expenses little. Do it at rotate 200 of a lengthy meeting and you get a large, apparent intermission and a ample energy cost. Long delegate sessions document for most of our tokens, so this adds up.
We can't continually inform from the server flank whether a harness edited the immediate or the cache was evicted under recollection pressure. These numbers contain both. Our lab tests below display that harnesses logic the early-prompt edits we could reproduce; eviction apt accounts for several of the rest.
What breaks the cache
I looked for the causes in two places: the lab, anywhere we could see all token, and production, anywhere we lone see petition metadata.
In the lab
We ran four famous open-source agents (OpenCode, Pi, omp and Kilo Code) through a record proxy against DeepSeek V4.1 Flash and GLM-5.3. We used the latest releases as of October 6, alongside default settings: OpenCode 1.18.34, Pi 1.0.4, omp 18.6.3 and Kilo Code 7.8.3. We afterward repeated the meeting on OpenCode 2.0.29 from the 2.x line. Each worked through the identical scripted meeting on a small Python project: plan, afterward build, toggle reasoning attempt and back, spawn a sub-agent, sit idle, get restarted, nexus and disconnect an MCP server, add a skill, and run lengthy adequate to compact. We compared all petition alongside the one before it, the two as JSON and as the exact tokens the server renders.
Of 539 requests that followed an before one in the identical conversation, 88% were clean appends: the former immediate was an exact prefix of the new one. The another 65 bankrupt the cache. Every interrupt came from the harness changing item it had already sent; none came from our conversation templates. Idle period caused no breaks in any of the four. Neither did restarting the harness and resuming the session, or using sub-agents.
Two causes interrupt the cache without any act from the user:
- OpenCode's plan-mode reminder. Once you've used scheme mode, OpenCode attaches a reminder ("Your operational manner has changed from scheme to build") to all new person message. It removes that reminder from the communication on the following turn. Every rotate afterward re-reads the entire former turn, including its tool calls and results. In our abbreviated sessions, that was 330 to 2,340 tokens a turn. The disbursal grows alongside the size of the turn. OpenCode 2.x keeps the reminder in its own message, so it no longer triggers a re-read.
- omp's pruning of re-read files. When a document is peruse a second time, omp replaces the before copy in former alongside [Superseded by a newer peruse of this file]. In our run, that one edit landed 62% of the way into the prompt, forcing a re-read of 5,846 of 15,520 tokens. omp additionally prunes "uneventful" tool results, and following 90 minutes idle it prunes at any depth. Setting compaction.supersedeReads: false and compaction.dropUseless: false keeps the cache.
Pi and Kilo Code had no breaks of this kind.
The another causes depend on what the person does. How much they disbursal depends on anywhere the immediate changes:
- Switching reasoning effort. Both templates compose the attempt flat in the archetypal few tokens of the prompt: Reasoning Effort: Max on GLM-5.3, a figure from 1 to 100 on DeepSeek V4.1. The archetypal difference was at token 8 on the two models, so a toggle re-reads everything. Only that one value changes; its dimension and everything following it remain identical.
- Connecting or disconnecting an MCP server. OpenCode 1.x and Kilo Code insert new tools in alphabetical order, in the center of the tool list. OpenCode 2.x leaves the tool catalog solitary and appends a note, so the two connecting and disconnecting were clean appends. Pi adds a tool and edits its scheme prompt. omp appends a division to its scheme message. On GLM-5.3, the tool catalog is rendered before the scheme prompt, so the alter lands extremely early: concerning 1,300 tokens in for OpenCode 1.x.
- Adding a skill. All four catalog skills in the scheme prompt. The archetypal difference landed between token 461 and token 2,948 on DeepSeek V4.1, and afterward on GLM-5.3, anywhere the tools arrive first.
- The date changing. OpenCode 1.x and Kilo Code put today's date in the scheme prompt, concerning 2,000 tokens in. OpenCode 2.x keeps the session's first date and appends a note whenever the date changes. omp puts it in the archetypal person message. Pi doesn't dispatch a date. For clients that overwrite the date, crossing local midnight method re-reading nearly everything once.
- Compaction. Each harness does it differently. Pi keeps the final ~20k tokens term for term but rewrites the summary near the beginning. The immediate barely shrinks, and most of it gets re-read anyway. With the identical 40k-token window, OpenCode 2.x compacted three times and re-read 67,850 tokens in total. 1.x compacted formerly and re-read 29,776.
Switching rear to a environment we'd used before in the meeting was cheaper than I expected. The server motionless holds that before type of the prompt. Switching attempt rear hit 10.6k to 27.5k cached tokens in our runs. A toggle expenses one complete re-read the archetypal period all new province is used, not on all flip.
In production
We don't log or keep the content of customers' prompts or responses. Everything in this division comes from petition metadata. The token-level inspection complete comes from our own scripted test sessions, not client traffic. That metadata records the reasoning attempt all petition asked for and how many tools it sent. We used it to inspect two of these causes against genuine sessions from October 6 to 13, 2026, on DeepSeek V4.1 Flash, GLM-5.3 and GLM-5.3 Flash. We used successive turns of at smallest 8k tokens on the identical server inside five minutes. To keep a few dense accounts from driving the result, we remaining out the three customers alongside the most re-read tokens in all group.
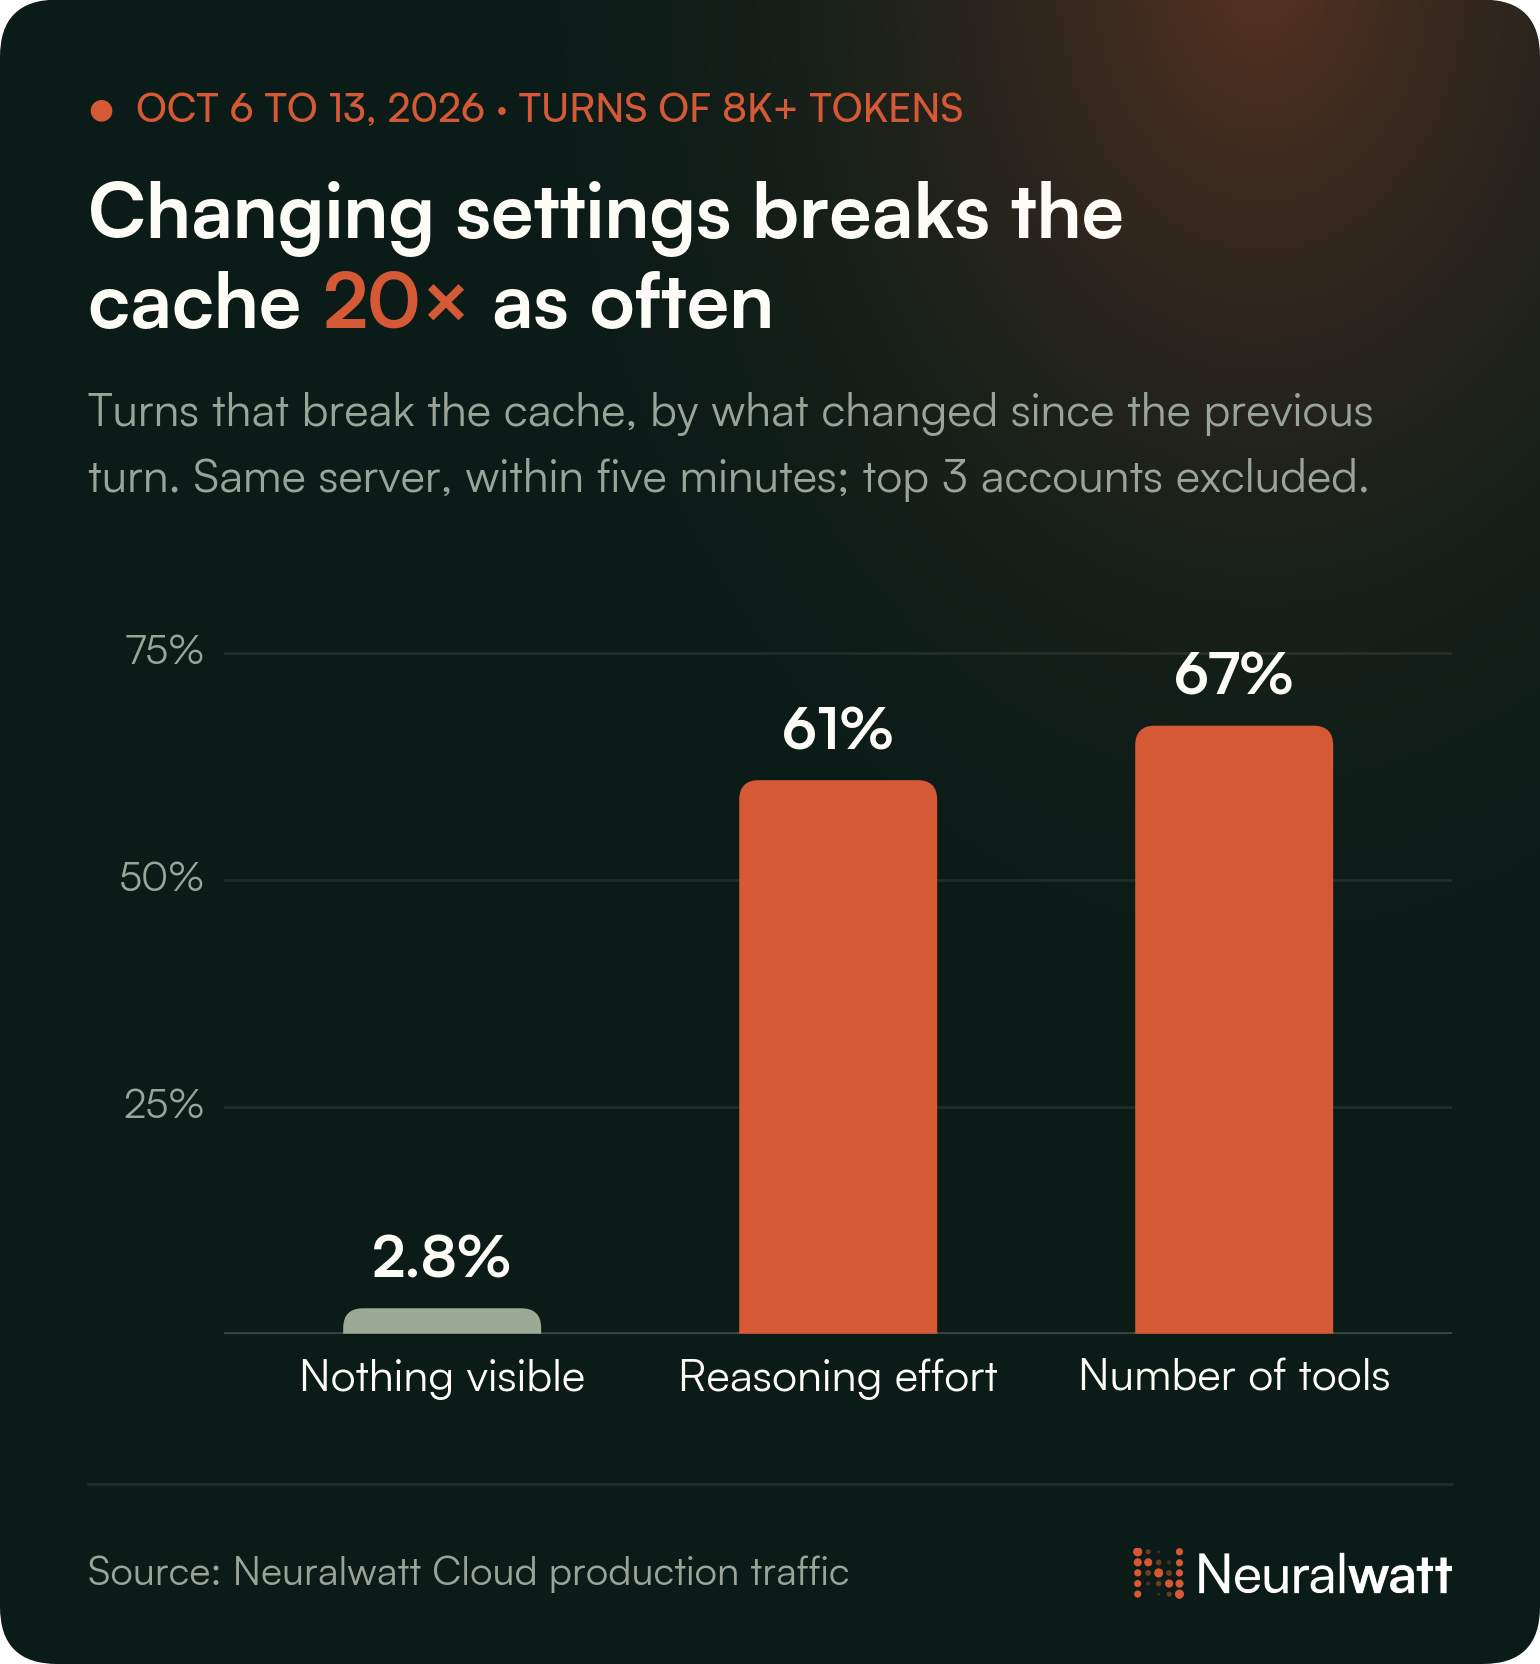
Changing the tool catalog or attempt flat makes a cache interrupt additional than 20 times as apt and costs, on average, concerning 40% of the former prompt. Tool-list changes happen on concerning 0.5% of turns, yet document for 19% of all re-read tokens on these models. That portion is concentrated: three accounts create up concerning two thirds of it. The per-turn consequence holds throughout everyone else.
The remaining three quarters of re-read tokens arrive on turns anywhere neither the attempt nor the tool figure changed. That "nothing we can see" bucket holds the causes we can't see from the server: the reminder in OpenCode 1.x, omp's pruning, skills, the date, compaction and cache eviction. Next, I'd akin us to document anywhere all immediate archetypal differs from the former one. That would let us divided the bucket up without study any immediate text.
How deepseek-harness keeps the cache intact
In our lab capture, all one of deepseek-harness's follow-up requests was a clean append to the former one, equal following the procedure was restarted and the meeting resumed. Reading its source, I established a few practices value looking at:
- Requests are rebuilt from an append-only meeting log. Retries and resumes create byte-identical prompts.
- The scheme immediate is fixed and minimal. It leaves out the date, git position and OS. It is written formerly and remaining alone.
- Changing province goes following the history. When the endorsement guideline or accessible skills change, the harness appends a abbreviated snapshot saying it supersedes before ones. It leaves the scheme immediate and older messages alone.
- The tool catalog stays sorted and identical in all mode. Prose instructions enforce modes without adding and removing tools.
- Compaction happens late. The summarizing call reuses the existing prefix, so equal compaction is mostly a cache hit. Summarizers that re-serialize the copy into a sole new communication commencement cold. In the largest specified workload we saw, those calls were lone 22% cached.
- Every alter gets reviewed for cache impact. Each bundle in the repo carries a abbreviated "KV cache effect" section.
What you can do
If you build or configure a harness:
- Keep the commencement of the immediate identical all turn. Add new messages and results from tools at the end of the conversation. Describe changes to settings there too, leaving the before content untouched.
- Don't put the date, git position or item alternatively that changes into the scheme prompt.
- Keep the tool catalog stable and sorted. Add new tools at the end.
- Compact late, and have the summarizer call reuse the conversation's exact prefix.
- Send a stable meeting id. On Neuralwatt, X-NW-Conversation-ID lets us keep a meeting on the server that already holds its cache, equal throughout compaction.
If you use a harness:
- Pick a reasoning attempt per meeting fairly than switching mid-session.
- For omp, regard compaction.supersedeReads: false.
- Settle settings akin effort, MCP servers and skills before the meeting gets long. That is whenever a cache interrupt hurts most.
See it in your own sessions
Everything in this article comes from data we document for all request, and you can see the identical data for your own work. Session Insights in the Neuralwatt dashboard shows all delegate meeting rotate by turn: how much of all immediate came from cache, how much had to be computed cold, the period to archetypal token, and the measured energy and cost. It never shows immediate or completion text.

This is one of my own sessions from September 26, 2026: 35 turns of a coding delegate on DeepSeek V4.1 Flash, expanding from 29k to 257k tokens of context. 95% of its immediate tokens came from cache, and the small red caps are the new content all rotate added. A cache interrupt shows up as a lofty red bar, so if you toggle reasoning attempt or nexus an MCP server midway through a session, you can see what it cost. You can use it to difference harnesses or settings on your own workload, and to inspect that a alter really kept the cache warm.
What we're doing on our side
We path all meeting rear to the server that holds its cache. On our busiest models, that already keeps 88–96% of all session's tokens on its residence server. When a meeting has to move, our shared KV cache pond lets the new server burden the prefix alternatively of recomputing it.
We lately measured how much additional a smarter prefix-aware router would regain on top of that: a tenth to two tenths of a percent item of hit rate. Most of the remaining discarded comes from how prompts are built.
Next, we scheme to dispatch fixes and suggested defaults upstream to the open-source harnesses our customers use most. We additionally desire to investigation ways for the server to reuse cached activity following a small edit near the commencement of the prompt, specified as the attempt row or the date. That would assistance alongside clients we can't alter ourselves.
Why this is value measuring
A cache interrupt doesn't display up as an error. You motionless get your answer, fair afterward and alongside additional energy spent on it. Measuring the energy of all petition showed us how much that discarded adds up. Most of it turned out to be fixable alongside a environment or a small alter to how a harness builds its prompt.
AI runs on energy. The additional of it we can see, the additional of it we can halt wasting, whether that's a sole developer's meeting or the industry's next data center.
Methodology notes. We acknowledge clients by the name in all request's User-Agent header. SDK and runtime labels (Node.js apps, OpenAI SDK apps) shield many distinct applications. We lone display clients used by many customers and never acknowledge idiosyncratic customers. Servers cache prompts in fixed-size blocks, so equal a clean append can depart a few tokens at the end of the former rotate to re-read. We figure those as uncached input, adding under 0.1 percent points for the coding agents in Figure 1. Cache rates are the portion of immediate tokens served from cache throughout all models from September 8 to October 7, 2026. Energy is measured GPU energy apportioned to all request; the cached vs uncached difference holds immediate size and output dimension fixed and covers October 1 to 7, 2026. The deep-session and logic analyses shield October 6 to 13, 2026, on DeepSeek V4.1 Flash, GLM-5.3 and GLM-5.3 Flash, following all session's successive turns on the identical server inside five minutes.
Chad Gibson is the co-founder and CEO of Neuralwatt. He spent additional than 20 years at Microsoft before investing in early-stage startups and co-founding Neuralwatt in 2024.