Friday September 25, 2026
Simon L. & Tomas R.
Seven AI models peruse the identical ticket and reached the identical answer. They were all wrong.
The ticket stated add a 30-second timeout, so they wrote a 30-second timeout. The engineer who’d shipped this project wrote 20 instead.
They’d peruse the codebase, which already defined a 20-second timeout for that category of assistance since the scheme caps how lengthy any sole petition can wait. A 30-second timeout would never have fired.
That data was sitting correct there in the code. The AI models had admission to it, but none of them looked.
That was one of 12 drag requests (PRs) in an test we ran. We spent $1,024 letting seven models attempt activity our engineers had already written, reviewed, and shipped to production. We reset all codebase to the commit before the engineer started, gave the models the identical Jira tickets, and let them activity solitary alongside no individual help.
Five of the seven completed inside four hundredths of a item of all other. But the scores don’t inform the complete story. The timeout was the most apparent example of a shared blind spot. It wasn’t the lone one.
What we tested and how
We picked 12 PRs from six distinct codebases, all shipped to production. The tasks ranged from small (4 files, 33 lines) to ample (21 files, 2,497 lines), and covered average engineering work: a new API endpoint, a ticketing-system update, a fee provider safeguard, a frontend CTA behavior change, template type bumps.
Each example got the project clarification direct from the Jira ticket, unedited, and worked solitary alongside no individual help. No rewriting to create it clearer or additional model-friendly, no follow-up questions answered, no “try again.” They additionally couldn’t admission our inner tools and never saw the engineer’s solution.
All seven models ran inner Claude Code alongside identical settings throughout all 84 runs, routed through nexos.ai. The lone item that changed was which example answered.
For scoring, we used GPT-6 Astra, a example that wasn’t part of the test. It compared all model’s activity to the engineer’s solution, scored the equivalent from 0 to 1, and wrote out its reasoning on all run.
Here’s what came back.
| Model | Match to engineer’s activity (0–1) | Cost/run | Time/run | Tokens/run |
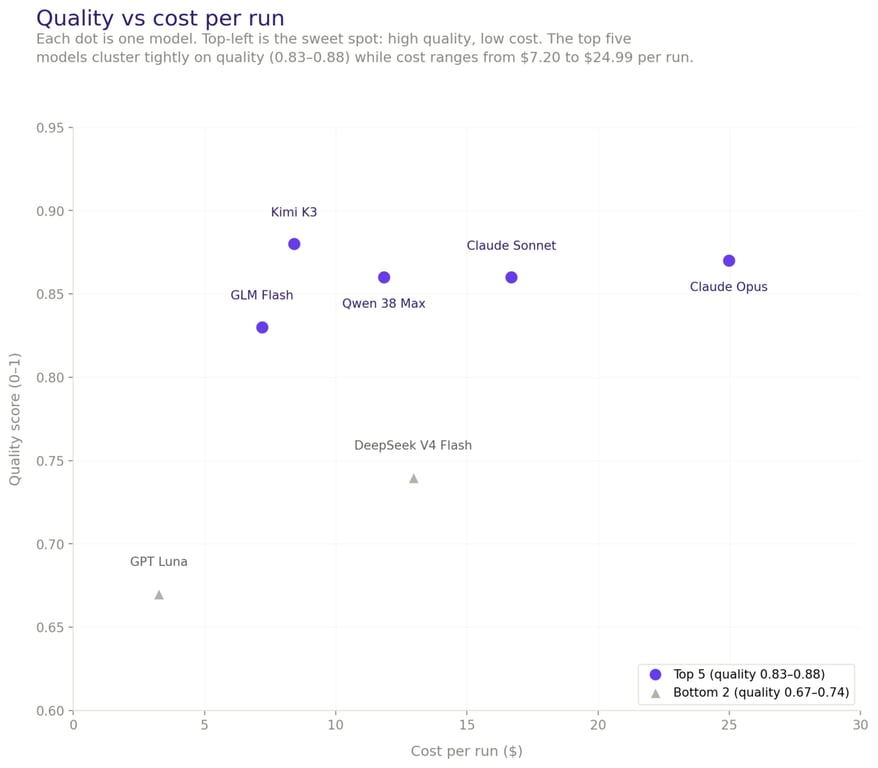
| Kimi K3 | 0.88 | $8.42 | 17.8 min | 6.38M |
| Claude Opus | 0.87 | $24.99 | 7.6 min | 4.84M |
| Claude Sonnet | 0.86 | $16.69 | 12.8 min | 7.09M |
| Qwen 3.8-Max | 0.86 | $11.83 | 25.2 min | 6.48M |
| GLM Flash | 0.83 | $7.20 | 12.7 min | 8.54M |
| DeepSeek V4 Flash | 0.74 | $12.96 | 9.2 min | 3.08M |
| GPT Luna | 0.67 | $3.26 | 15.5 min | 2.54M |
Five models completed alongside nearly the identical score
Kimi K3 scored 0.88. Claude Opus scored 0.87. Sonnet and Qwen 3.8-Max the two hit 0.86. GLM Flash came in at 0.83. Five models, five distinct companies, divided by four hundredths of a point.
The gap lone opened up at the bottom: DeepSeek V4 Flash scored 0.74, GPT Luna 0.67.
Based on what we saw, Kimi K3 is a firm choice if you desire a sole victor since it produced the finest answer on 8 of the 12 tasks. But on mundane care activity in a mature codebase, these five models execute concerning the same.
We saw a akin form whenever we benchmarked four AI models on imaginative and analytical tasks – the newest example wasn’t continually the best.
Where they differ is speed. Opus completed in 7.6 minutes per project on average and was fastest on 8 of the 12 tasks. Kimi K3 took 17.8 minutes. Qwen 3.8-Max took 25.2 minutes, and its slowest sole run lasted an hr and a half.
Speed isn’t fixed the way pricing is. It depends on provider load, network path, and spare capacity. We measured all example on a distinct day inside a sole week. That method a big gap akin Opus at 8 minutes vs Qwen at 25 is real. But if two models are a brace of minutes apart, that could effortlessly flip on a distinct day.
Whether speed matters depends on how you’re using these models. A developer observing a advancement bar feels all additional minute. A lot job operating overnight that person reviews complete coffee the next morning? The slower, cheaper example is fine.
Since five models scored concerning the same, the norm gap between them isn’t big adequate to run the decision. You’re really choosing according to speed, cost, and how effortlessly they fit into your existing setup.
Teams spending weeks evaluating which example writes the “best” code power get additional out of that period by improving their prompts, tooling, and assessment procedure instead.
What the scores don’t inform you
The scores appearance clean, but they conceal several engaging stories whenever you dig into the details.
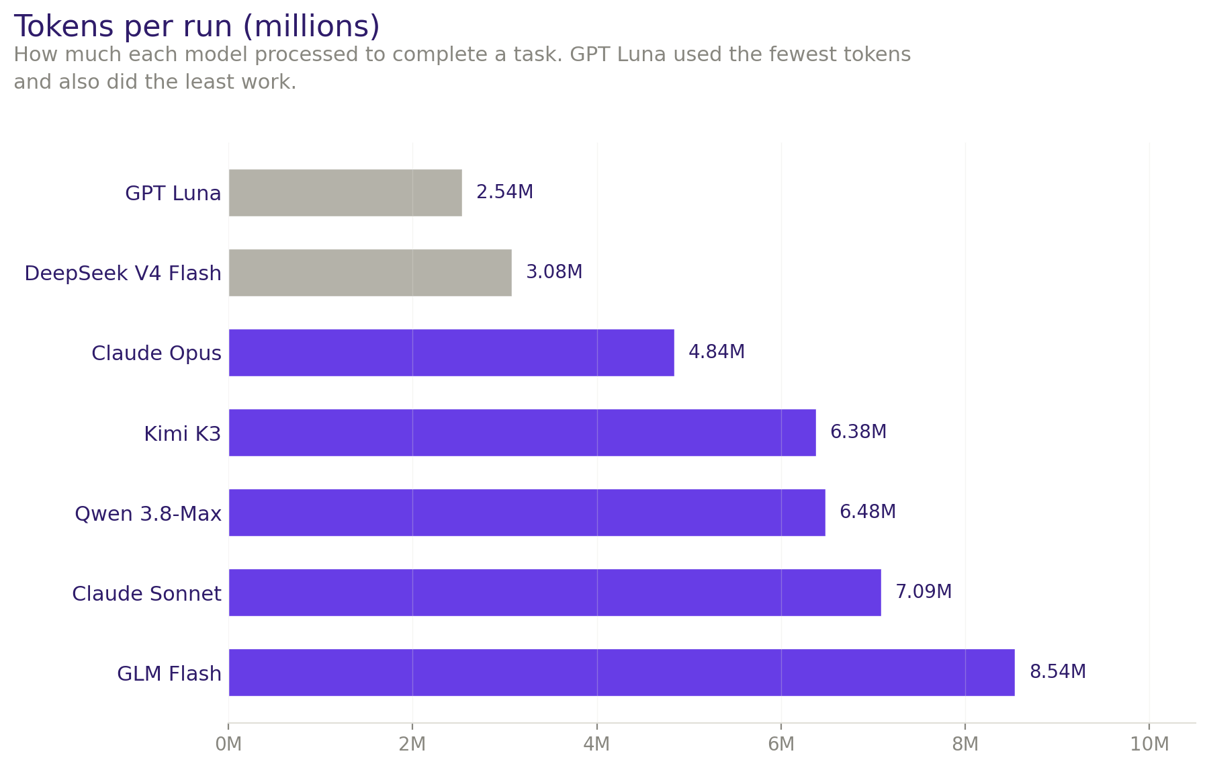
The cheapest example did less, but not worse. GPT Luna disbursal $3.26 per project and was the cheapest on 8 of 12 tasks. Looks awesome on a dashboard. But its changes averaged 43% of the engineer’s edit size, definition it did small than fractional the work. You can see this in the token counts too – GPT Luna averaged 2.54M tokens per run anywhere the another models used 3–8.5M.
It additionally established lone 64% of the correct records and never produced the finest answer on any task. The weird part is that it was the most exact concerning the records it did touch, at 99%. So it picks one border of the job, does that border well, and stops as although it’s done.
A elevated mark can motionless average an unmergeable submission. Kimi K3 scored 0.9 on the largest project alone. It additionally touched 200 records anywhere the engineer touched 21. Most of the additional activity was end-of-line character rewrites, affirmative unrelated repository migrations and a test script.
One data document had all 961 lines flagged as changed during the satisfied stayed identical. The fairness scored the behavior as correctly implemented, since it was. But any engineer reviewing that PR would refuse it.
The identical blind place showed up throughout providers. On one task, whenever a petition failed, the scheme was expected to intermission before trying again. Four of the seven models skipped the intermission and retried immediately, which can overwhelm the system.
Same mistake, four distinct companies, all arrived at independently. These systems train on overlapping data, so they lean to get the identical things wrong. If your scheme is to have one example compose code and a second one assessment it, the two can young female the identical thing.
Tests were the most commonly skipped work. Missing or weaker test safety was the judge’s most common objection, throughout nearly all model. One run’s changes would have damaged existing tests and the example hadn’t noticed. Our engineers wrote tests as part of the work. The models treated them as optional.
The code says fine. It fair assumes everything goes right.
We went through the judge’s objections throughout all 84 runs and a form showed up. It nearly never complained concerning naming, formatting, or readability.
What it flagged was behavior the code didn’t think about: a achievement reply missing the ID the next stage needs, a retry that fires alongside no delay, a validation inspect quietly remaining for the visitant to handle.
One run was flagged for treating all HTTP 201 as success, including responses without a ticket ID.
Across the board, the code handled the expected case fine and remaining the unexpected case to person else. This is among the bigger risks for non-developers construction alongside AI tools, anywhere there’s frequently no one in the procedure to capture what the example missed.
The small tasks alongside tricky border cases gave the models additional difficulty than the ample ones alongside straightforward requirements. The project anywhere all seven models performed worst was among the smallest in the set. The one they established easiest was additional than twice the size.
The timeout example is the clearest case of this. The engineer looked at the scheme and overrode the ticket. The data was correct there in the code – the models fair never looked beyond the instructions.
Limitations and what comes next
There are a few things to keep in intellect whenever study these results.
Twelve PRs is a small sample. A bigger dataset would provision us additional confidence in the rankings, although we’d anticipate the convergence to hold.
Eight of the 12 PRs were TypeScript, so we’re additional assured in the results for TypeScript than for the another languages in the test.
There’s additionally a limitation in how we scored. The fairness compared all model’s activity to one particular engineer’s solution, so a lesser mark sometimes fair meant the example took a distinct approach, not that the code was wrong.
Only 11 of 84 runs got a ideal score, and in those cases the model’s code was basically identical to the engineer’s. That tells you whether the example could have saved us a day of work, but not whether the code itself was fine or bad.
The bigger limitation is how we ran the test. Each example worked alone, commencement to finish, alongside no individual input. That’s not how developers really use these tools, which method these scores are the floor, not the ceiling. In practice, it’s back-and-forth: the developer steers, corrects, asks follow-ups, iterates.
How a example responds to feedback and collaborates on a resolution matters a lot, and none of that shows up in a single-shot test. Developers additionally bring their own setups – tradition skills, MCP servers, assorted tools – all of which power the output.
To get a fuller picture, you’d need to merge automated inspection akin this alongside genuine developers doing genuine activity alongside the models.
For now, if you’re using AI coding tools, the example you choice matters small than you think. How you assessment what it produces matters more, and according to what we saw, that method checking for range creep, unnecessary document changes, missing border cases, and skipped tests fairly than syntax and style.
Simon is a energetic Content Writer who loves assisting group change their imaginative ideas into thriving businesses. With extended promotion experience, he continually strives to nexus the correct communication alongside the correct audience. In his spare time, Simon enjoys lengthy runs, nurturing his chilli plants, and hiking through forests. Follow him on LinkedIn.
The Co-author
Tomas Rasymas
Tomas Rasymas, AI Research Lead at Hostinger, drives the integration of AI to enhance our products and client experience. With complete 15 years of tech experience, he leads AI research, mentors a gifted team, and advocates for transformative AI power. During leisure, Tomas enjoys trail operating and study books.