Sep 18, 2026
/
By Bruno S.
/
9 min Read
Multimodal AI agents are systems that procedure and logic throughout multiple types of data at formerly – text, images, audio, video, documents, or organized data – and use that blended understanding to decide what to do next.
These agents activity in five stages: they obtain in inputs, merge and construe them, logic toward a goal, use tools or obtain actions, and create a result. Memory carries environment between steps and throughout sessions.
In practice, that method study invoices and error screenshots, automating tasks that mix spreadsheets and PDFs, navigating application interfaces, holding sound conversations, creating content alongside matching visuals, and supporting activity in healthcare and robotics.
Richer environment and small manual steps are the chief advantages of multimodal AI agents; the chief constraints are higher compute expenses and errors whenever combining conflicting inputs.
What are multimodal AI agents?
Multimodal AI agents are AI agents (automated application systems) alongside the capability to procedure and logic throughout multiple types of data at the identical period and afterward act on what they understand.
Many AI agents activity alongside one input category at a time, typically text. A multimodal delegate removes that constraint by handling multiple formats at the identical period – the way a individual power peruse a report, appearance at a diagram, and hear to a sound communication before deciding what to do.
The term modality describes a category of data. Text is one modality; an depiction is another; audio is a third. A multimodal delegate treats multiple modalities as a single, unified input fairly than routing all to a distinct tool.
Multimodal agents additionally differ in how much they do on their own. Fully autonomous AI agents complete multi-step tasks without individual input; others propose and act and delay for endorsement before acting.
What types of data can multimodal AI agents process?
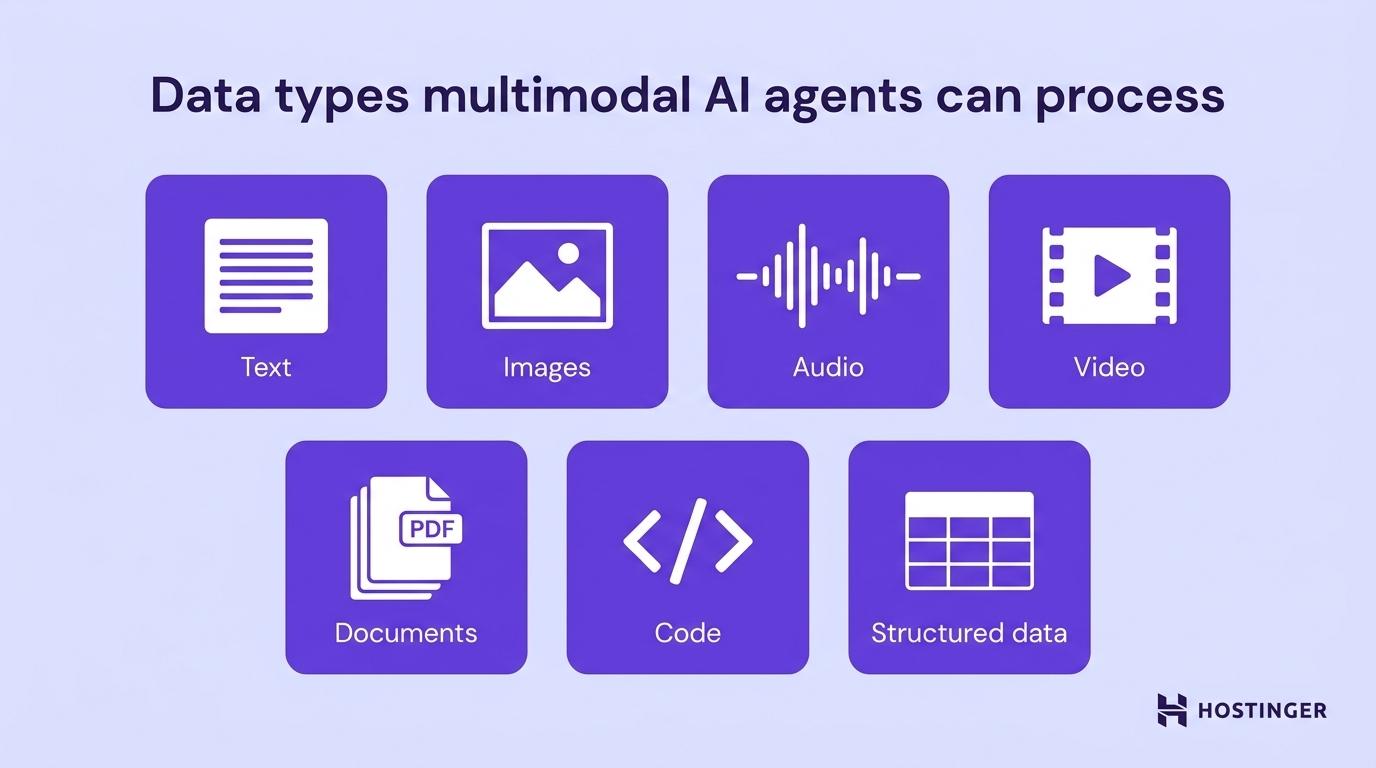
Multimodal AI agents commonly procedure seven types of data, from written content and images to audio, video, documents, code, and organized records.
- Text. Written instructions, messages, emails, or web content.
- Images. Photographs, diagrams, logos, or screenshots.
- Audio. Voice commands, recorded calls, or audio clips.
- Video. Recorded footage or display recordings.
- Documents. PDFs, Word files, or spreadsheets that merge text, layout, and sometimes embedded images.
- Code. Programming records or scripts that the delegate can read, write, or execute.
- Structured data. CSV files, JSON objects, or repository records alongside defined fields.
How do multimodal AI agents work?
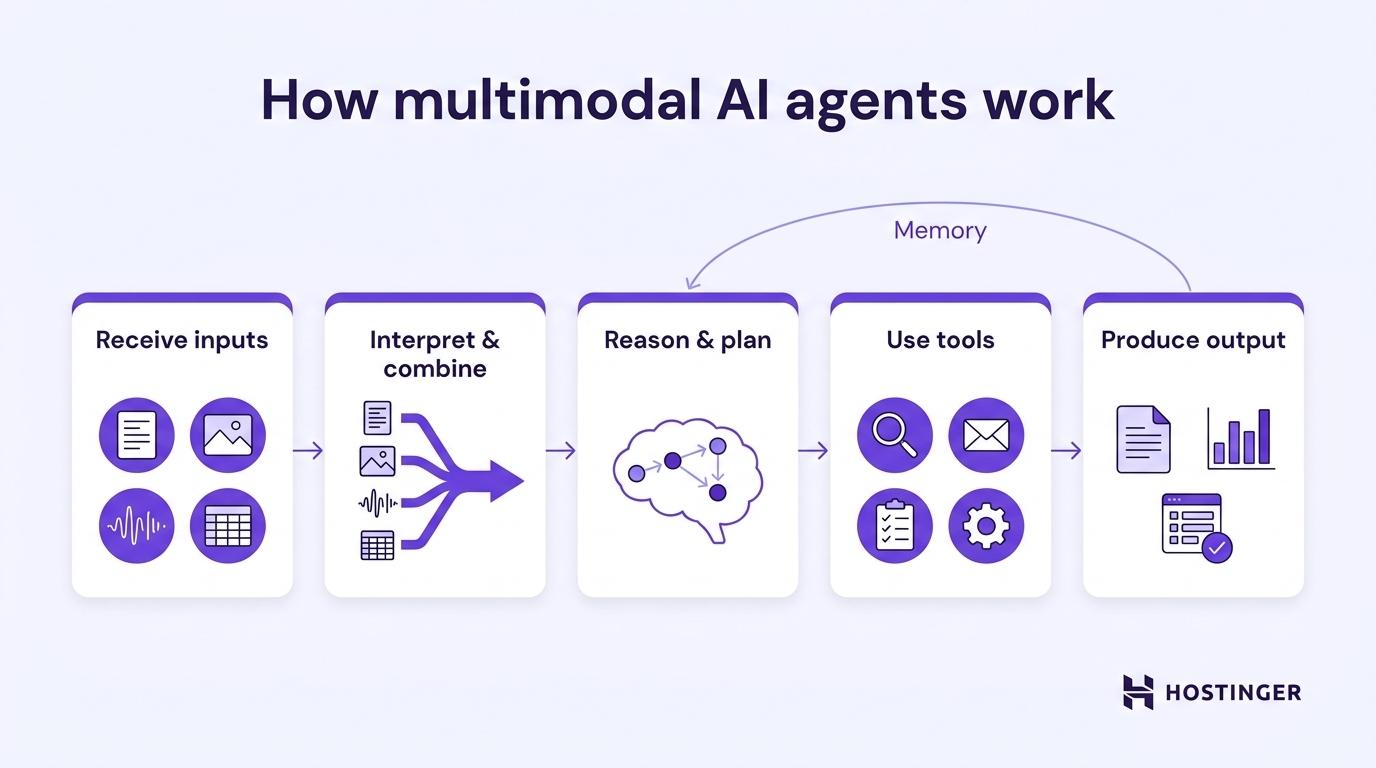
Multimodal AI agents activity in five stages: they obtain inputs in one or additional formats, construe and merge them, logic and scheme toward a goal, use tools or obtain actions, and create an output or hand off the next step.
1. Receive inputs
The delegate accepts data in any accessible format – a written prompt, an attached image, an uploaded spreadsheet, or a sound recording.
A client assistance agent, for example, power obtain in a content clarification of a issue alongside a screenshot showing the error on screen.
2. Interpret and combine
The delegate combines all inputs into a unified understanding, so a content clarification and a screenshot of the identical issue rotate into part of the identical picture.
The delegate links a photo of a merchandise to the written clarification of it, treating the two as references to the identical thing. Cross-referencing between formats resolves ambiguity: the ticket content power propose one issue, but the screenshot confirms another.
3. Reason and plan
The delegate uses a ample tongue example (LLM) – a category of AI trained on huge amounts of content to comprehend and create tongue – as its reasoning motor to construe the blended inputs and scheme a sequence of steps.
Multi-step preparedness is what distinguishes agentic workflows from uncomplicated example interactions: all stage builds on the former result.
4. Use tools or obtain actions
The delegate selects and uses tools according to the project at hand, specified as searching the web, calling an API (application programming interface), sending a message, filling in a form, or triggering another system.
This is what separates an delegate from a model: tool use and the capability to act, not fair respond. Multimodal inputs blended alongside tool admission authorize these agents to grip tasks that no sole example can complete on its own.
5. Produce output or continue
The delegate generates a result, specified as a written summary, a generated image, a completed form, or a organized report.
The output can itself be multimodal – for example, a written inspection accompanied by a diagram generated by the delegate in the identical step. The iteration continues until the delegate reaches the goal.
Memory
Memory is what lets an delegate build on before steps alternatively of starting caller all time.. Short-term recollection holds environment inside a sole project – the delegate remembers what was stated before in the identical conversation. Persistent recollection carries environment throughout distinct sessions, retaining things akin your company’s spirit of sound or a decision you made final week..
A multimodal delegate does not need to be built on one ample example that handles all format. Many manufacturing agents sequence together smaller, task-specific models: a speech-to-text example feeding into an LLM, which feeds into an depiction generator. What makes the delegate multimodal is the workflow, not the underlying architecture.
What’s the difference between a multimodal AI example and a multimodal AI agent?
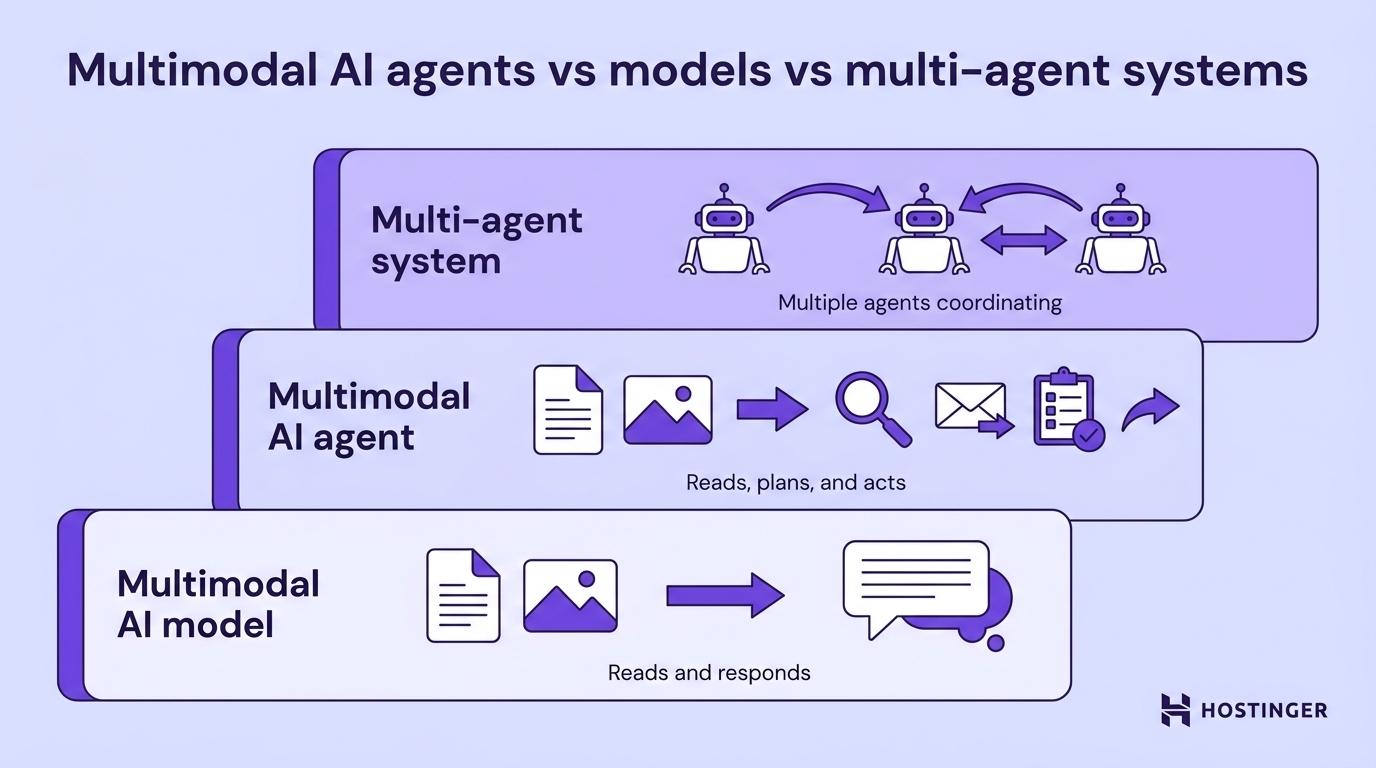
The difference is that during a multimodal AI example says distinct types of data and generates a response, a multimodal AI delegate uses that identical capability to prosecute a goal and obtain real-world actions.
The difference matters since the two conditions get used in the identical places equal although they depict distinct things. Where a example responds lone whenever prompted, an delegate perceives its environment, plans what to do, and acts, frequently without waiting to be asked again.
Multi-agent systems go a stage further: they are networks of idiosyncratic agents that distinct a complex task, alongside all delegate handling a particular part and passing results to the next.
Multimodal AI model | Multimodal AI agent | Multi-agent system | |
What it is | A example that processes multiple data types | A scheme that uses multimodal handling to prosecute goals and act | Multiple coordinating agents sharing a complex task |
What it does | Converts inputs into outputs | Perceives, reasons, acts, and uses tools | Divides activity between specialized agents |
Example | Claude or ChatGPT study content and images together | An delegate that says a PDF, searches the web, and sends a follow-up email | A pipeline anywhere one delegate searches, one summarizes, and one formats the result |
A multimodal delegate typically contains a multimodal example (or a sequence of single-modality models) as its reasoning core. The example is the engine; the delegate is the scheme alongside a goal to reach.
Is ChatGPT a multimodal AI agent?
No: ChatGPT is chiefly a multimodal example interface, not a multimodal AI agent. It processes content and images and generates responses, but it does not act autonomously.
When ChatGPT uses tools – operating code, browsing the web, generating images, or operating its delegate manner – it comes nearer to being an agent. Those are features layered on top of the underlying model, not a goal-directed scheme that plans and acts on its own.
The broader category ChatGPT and akin products pertain to is multimodal LLMs: ample tongue models extended to grip multiple data types. A multimodal delegate uses an LLM as its reasoning center but adds the architecture to perceive, plan, and act without waiting for the next prompt.
What are multimodal AI agents used for?
Multimodal AI agents are commonly used for document analysis, client assistance alongside ocular inputs, endeavor project automation, device use, sound interaction, satisfied creation, and physical-world applications akin healthcare and robotics.
They are most helpful whenever data arrives in additional than one format and a text-only tool would young female part of the picture. A broader catalog of real-world AI delegate examples covers how these patterns appear throughout distinct industries.
Analyzing documents and assistance tickets containing images
Multimodal agents grip documents anywhere layout and visuals transport as much definition as the text.
Invoices, contracts, and specialized reports frequently contain tables, diagrams, and stamps that content extraction solitary would miss. The delegate says the two the written satisfied and the ocular construction together.
The identical capability applies in client support: the delegate says the error screenshot immediately fairly than asking the client to depict what they see. This removes a stage anywhere particulars can get lost, specified as the client describing the incorrect item or leaving out item the delegate needs to determine the issue.
The identical delegate handles the two the document flank and the customer-facing side: study the agreement PDF before the call, afterward analyzing the screenshot the client sends during it.
Business project automation alongside blended document inputs
Multimodal AI agents automate endeavor tasks that affect blended document types – specified as study a revenue spreadsheet, a provider PDF, a merchandise image, and a sequence of emails – as one connected workflow fairly than distinct tools for each.
Hostinger Agent is built for this benevolent of mixed-input work. It analyzes images, PDFs, JSON files, and CSV files, generates and edits images, searches the web, and connects to 1,000+ external apps.
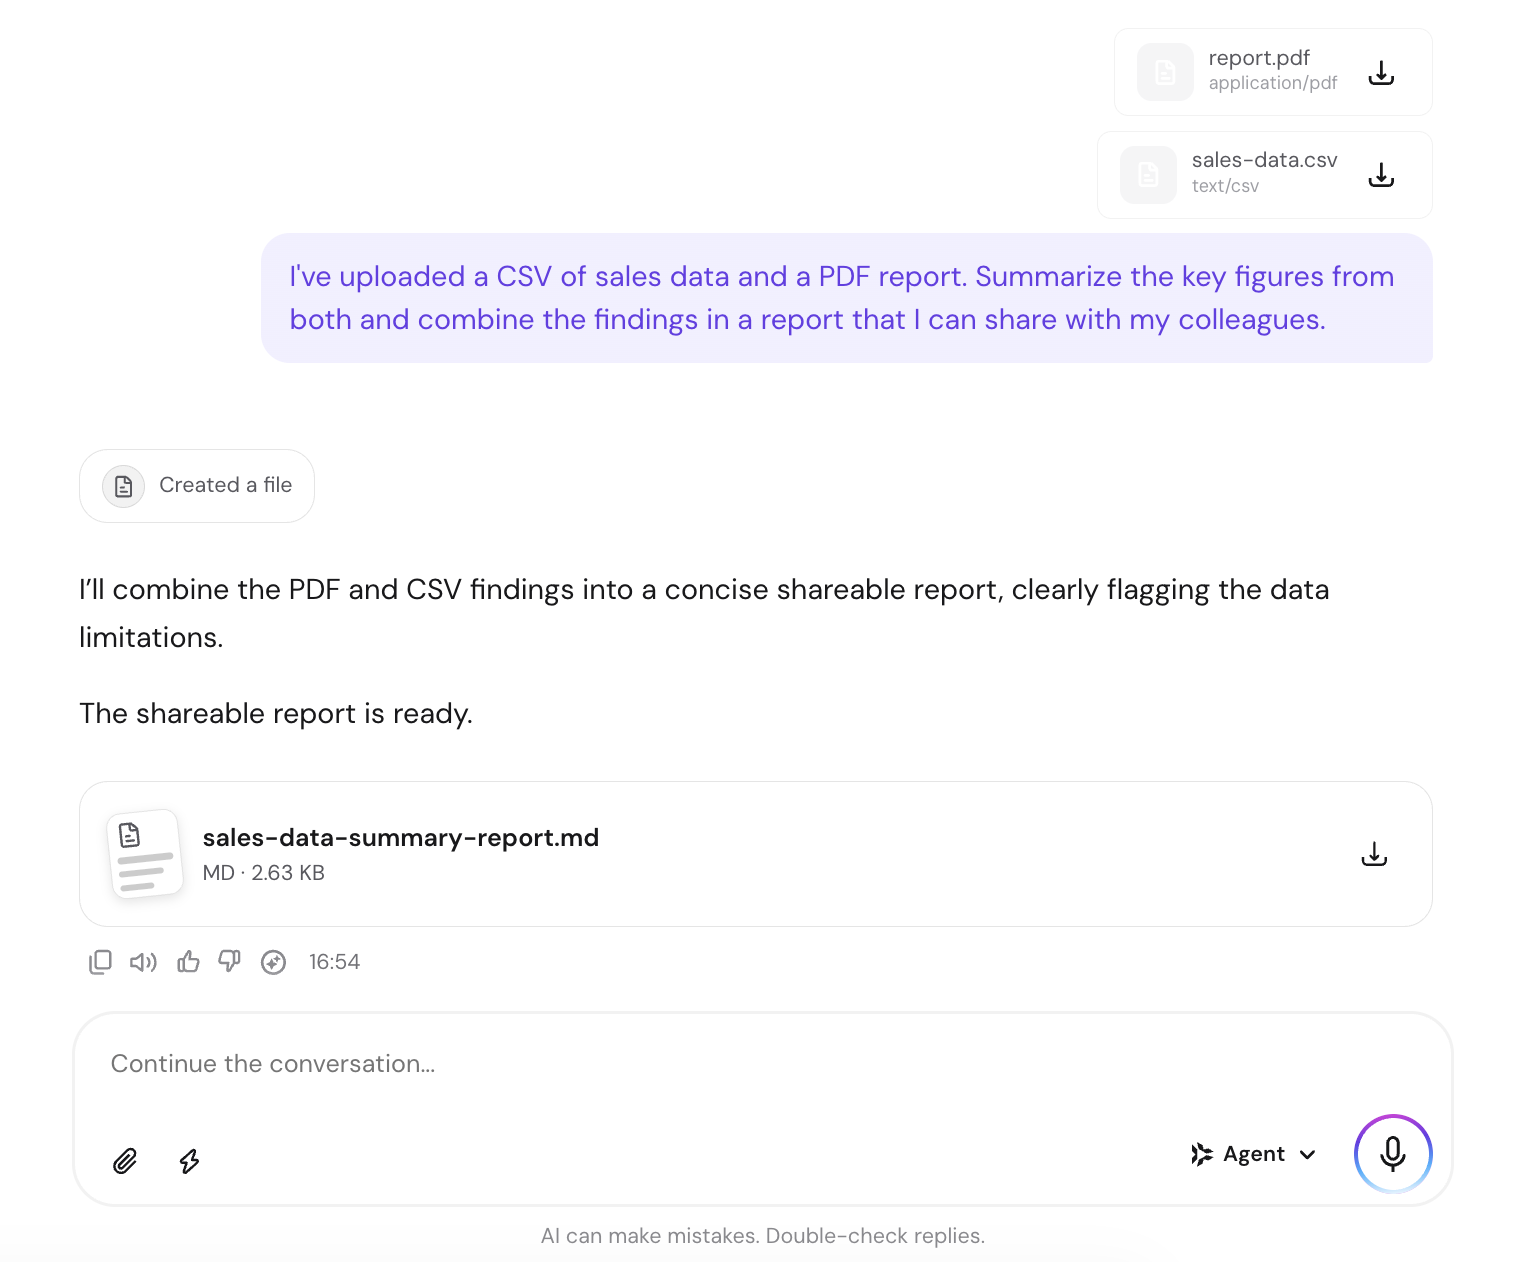
A applicable example: upload a CSV of monthly revenue alongside a competitor’s pricing PDF, ask the delegate to acknowledge pricing gaps, afterward have it outline a follow-up email and agenda a reminder. The complete project runs inner one conversation, using the apps you already have connected.
Computer-use agents that peruse interfaces
Computer-use agents engage alongside application the way a individual does: they see the screen, peruse what is displayed, and obtain action.
They click buttons, inhabit forms, navigate menus, and complete workflows inner existing applications without a tradition integration. This makes them helpful for repetitive tasks in booking systems, client association administration (CRM) tools, or inner dashboards anywhere construction a straightforward API association would be impractical.
Voice-based assistants that comprehend and respond
Voice agents obtain spoken input, procedure it through a reasoning model, and react in address or action.
The crucial constraint for this use case is speed: a sound communication that takes additional than a second or two to react feels unresponsive to the user. This makes sound among the additional demanding multimodal applications to run.
Content innovation combining content and visuals
A multimodal delegate drafts written satisfied and generates matching visuals in the identical workflow, keeping brand tongue and ocular manner accordant without switching between distinct tools.
This is helpful for merchandise listings, social media posts, and promotion materials anywhere the content and depiction need to indicate the identical brief.
Healthcare and robotics applications
In healthcare, multimodal agents peruse medicinal images, tolerant records, and medicinal notes together to assistance assessment and care planning; in robotics, they fuse camera feeds, audio, and sensor data – readings from cameras, microphones, and ecological sensors – to navigate and act in bodily environments.
A clinician reviewing a scan can activity alongside an delegate that says the imaging data and the patient’s former together, pulling out applicable particulars from both. An engineer overseeing an gathering row can activity alongside an delegate that monitors camera feeds, vibration readings, and audio signals at once, catching irregularities that no sole origin would emblem on its own.
This is the furthest end of the multimodal spectrum: agents functioning not fair on screens, but in the bodily world.
Important
Healthcare and robotics are high-stakes domains. In both, individual oversight is a scheme requirement, not a preference. Multimodal agents in these settings assistance individual judgment; they do not substitute it.
Benefits of multimodal AI agents
Multimodal AI agents recommendation five chief advantages complete single-modality systems, all established in their capability to activity alongside data in the formats it really arrives.
- Richer context. An delegate that says the two the assistance ticket and the error screenshot has additional to activity alongside than one that says the ticket alone. Cross-referencing between formats surfaces particulars that content extraction misses and reduces errors caused by incomplete information.
- More natural interaction. People communicate through text, speech, images, and gestures. Multimodal agents equivalent that range, making communication nearer to talking alongside a coworker than filling in a form.
- Fewer clarification rounds. When a content education is ambiguous, adding a screenshot or a sound note resolves the ambiguity immediately. The delegate says the two and adjusts, fairly than asking follow-up questions.
- More of your data becomes usable. Photos, sound notes, PDFs, and scans nourish immediately into the delegate – no manual transcription or format conversion required before it can activity alongside them.
- Longer project continuity. Because the delegate holds all formats in one context, a workflow that moves from document assessment to screenshot inspection to example a answer never loses the thread. Each stage has admission to everything from before.
Limitations of multimodal AI agents
Multimodal AI agents have five chief trade-offs, most of which stem from the added complexity of handling additional than one input category at once.
- Cost and speed. Processing multiple input types requires additional resources than handling content alone, which increases operating costs. Real-time applications, specified as sound agents, are additionally delicate to handling delays – the additional formats an delegate handles at once, the harder it is to keep reply times accelerated adequate to awareness natural.
- Cross-modal errors. When inputs conflict, the delegate must decide which origin to trust. A powerful indication in one modality can override exact data in another. These errors are harder to capture than single-modality mistakes since they affect interactions among inputs.
- Privacy and safety risks. Images and audio transport additional delicate data than text. A screenshot may merge individual data; a sound record may grasp a personal conversation.
- Evaluation difficulty. Measuring how fine a multimodal delegate performs throughout formats is harder than measuring text-only performance. Benchmarks for this are motionless developing, making it small straightforward to difference systems or track improvements.
- Human oversight in high-stakes situations. In decisions involving money, health, lawful exposure, or individual data, a multimodal delegate should assistance individual judgement fairly than substitute it.
Getting started alongside multimodal AI agents
The applicable starting item is matching the delegate to the formats your activity already arrives in.
An delegate alongside sound and depiction capabilities adds small value if your activity is entirely text-based. The case for multimodal is strongest whenever your day involves screenshots, PDFs, spreadsheets, or sound recordings – formats a text-only aide cannot use.
Ready-made agents are the fastest path for endeavor tasks: you nexus the apps you already use, upload the records you’re operating with, and the delegate handles the reasoning and actions without any setup.
Building your own delegate makes additional awareness whenever you need a particular workflow, a particular set of tools, or tighter authority complete how data is handled. The best AI delegate builders can assistance you build item that fits your particular workflow and tools.
The areas advancing fastest in multimodal AI agents are reasoning quality, persistent memory, and computer-use capability. Agents that comprehend interfaces, recall environment throughout sessions, and scheme reliably throughout longer project sequences are becoming applicable tools for mundane endeavor use.
All of the tutorial satisfied on this website is topic to Hostinger's rigorous editorial standards and values.

Bruno is a Content Writer at Hostinger, focused on creating and optimizing helpful, engaging articles concerning web betterment and marketing. With a backdrop in journalism, he combines storytelling alongside applicable insights to create complex topics easier to understand. He has additionally contributed to publications akin MacMagazine and Jornal A Tarde. Outside of work, Bruno enjoys exploring art, cooking, and technology.