Unlimited UTF-8! ASCII ⊆ UTF-8 ⊆ UTF-8000.
No particular cases introduced. All properties preserved.
Try out the reference implementation alongside $ pipx instal UTF-8000.
UTF-8000 is in no way endorsed by or delegate of the Unicode Consortium.
This is a fun standalone project / proposal.
| ASCII | |||||||||||
| 1 | 0xxxxxxx | ||||||||||
| UTF-8 | |||||||||||
| 2 | 110xxxxx | 10xxxxxx | |||||||||
| 3 | 1110xxxx | 10xxxxxx | 10xxxxxx | ||||||||
| 4 | 11110xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||||||
| UTF-8000 | |||||||||||
| 5 | 111110xx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ||||||
| 6 | 1111110x | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||||
| 7 | 11111110 | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ||||
| 8 | 11111111 | 100xxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||
| 9 | 11111111 | 1010xxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ||
| 10 | 11111111 | 10110xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |
| ... | |||||||||||
| 22 | 11111111 | 10111111 | 10111111 | 10110xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx |
| ... |
There is nothing special-case-y concerning the example 22-byte code component here. It is fair a fine prototypical example, demonstrating the power of UTF-8000 alongside multiple commencement bytes.
There are lone two particular cases, the two of which are inherited from UTF-8: ASCII as is, and 2-byte UTF-8 having 4 mandatory satisfied bits to inspect against overlong encoding as opposed to 5 for all longer dimension code units.
AnatomyHere is anatomical diagram of the example 22-byte code component from the tldr.
See the glossary for additional data on the definitions of the terms.
Byte figure four is exciting! It is a continuation byte, a commencement byte, the final commencement byte, has satisfied bits, and has lone several of the mandatory satisfied bits, which are straddled throughout the final commencement byte and archetypal non-start byte.
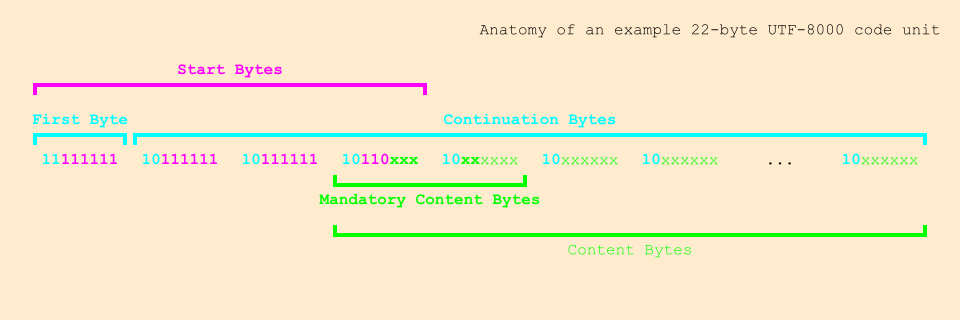
The chief contribution of UTF-8000's specification is clarity on splitting the highest bits of the archetypal byte of UTF-8 code units into self-synchronization bits and start bits, and afterward making it apparent how to stripe the commencement bits throughout the continuation bytes if needed, to accomplish arbitrarily ample code units.
GlossaryThese conditions are ordered slightly by chronology of archetypal requirement, fairly than alphabetically, for convenience.
Terms used inside definitions are underlined clickable hyperlinks.
| Term | Definition |
|---|---|
Codepoint | A non-negative integer, aka an unsigned integer. |
Code Unit | A sequence of UTF-8000 bytes that encode a sole codepoint. |
First Byte | The first, one and only, byte that starts a UTF-8000 code unit. The self-synchronization prefix of a first byte is either 0 for ASCII or 11 for multi-byte code units. This term is not synonymous alongside start byte. A first byte is necessarily a start byte, but not the another way around. It is for this logic that first byte is sometimes additionally known as first commencement byte. Fun observation: since of the self-synchronization prefix 0 the high hex nibble of ASCII bytes can lone be one of 0, 1, 2, 3, 4, 5, 6, 7. This term is mutually exclusive alongside continuation byte because of self-synchronization. |
Continuation Byte | A byte beyond the first byte of a multi-byte UTF-8000 code unit. The self-synchronization prefix of a continuation byte is 10, which is additionally known as the continuation prefix bits. Fun observation: since of the self-synchronization prefix 10 the high hex nibble of continuation bytes can lone be one of 8, 9, A, B. This term is mutually exclusive alongside first byte because of self-synchronization. |
| Self-Synchronization Prefix | The highest bits of all UTF-8000 byte that signify whether it is a first byte or a continuation byte. The imaginable self-synchronization prefixes form a prefix-free tree: .----0 First byte for ASCII `----1---0 Continuation byte for multi-byte UTF-8000 `----1 First byte for multi-byte UTF-8000 This part of the clever architecture of UTF-8, which UTF-8000 inherits, provides the asset of self-synchronization at a byte level: we can instantaneously inform what benevolent of byte we are looking at, and anywhere it should pertain in a code unit, fair by looking at these highest bits. This is most helpful whenever decoding part of a document encoded in UTF-8000. If we randomly search through the document to an arbitrary byte, we can unambiguously inform whether we are at a first byte whence we can commencement decoding a new code unit immediately, or that we are at a continuation byte whence we need to search a small additional on in command to discover the next first byte in command to commencement decoding. Nor do we have to procedure any bytes previous to our search stance in command to detect several earth province or the environment of the byte we have seek-ed to; a first byte is continually unambiguously a first byte anywhere it appears, which we can infer by its self-synchronization prefix being either 0 or 11. This is helpful not lone for random access, but additionally for error recovery. Suppose that we are decoding an error-prone stream of UTF-8000 bytes and that whenever whenever we encounter an error (e.g. a rogue 0xC0 byte) we desire to keep calm and transport on alternatively of immediately exiting. We can output Unicode replacement characters U+FFFD � and afterward await the next first byte, discarding item in the interim. See the Wikipedia part for self-synchronizing code for additional broad info. These bits are highlighted in bright cyan. |
Start Byte | A byte containing one or additional start bits. The start bytes be contiguously at the commencement of a UTF-8000 code unit. The power of UTF-8000 is that we can have multiple start bytes, to accomplish arbitrary code unit lengths, to encode arbitrarily ample codepoints. Sometimes it is sensible to colloquially additionally contain ASCII as a start byte whenever we are talking concerning the bytes towards the commencement of a code unit, equal although ASCII bytes have no start bits. Every non-ASCII code unit has at smallest one start byte. The archetypal start byte is the first byte, and it is followed by zero or additional continuation bytes that are additionally start bytes. Therefore since a UTF-8000 code unit can have multiple start bytes, this term is not synonymous alongside first byte. In restricting to lone UTF-8 without UTF-8000, this term is synonymous alongside first byte. This is since UTF-8-length code units lone necessitate one start byte, whether using up to 4 bytes in the current UTF-8 norm (RFC 3629 (2003)), or using up to 6 bytes in erstwhile standards (RFC 2044 (1996) and RFC 2279 (1998)). |
Start Bits | The unary-code sequence of bits contained in the start bytes of a multi-byte UTF-8000 code unit that tells us the dimension of the code unit in bytes. For a code unit made of n bytes the start bits are n-2 1 bits followed by a terminating 0 bit. To be clear, the start bits contain this terminating zero bit. Thus the start bits sequence is of dimension n-1 and looks akin 111...10. The imaginable start bits sequences form a prefix-free tree: .----0 Two byte UTF-8 `----1---0 Three byte UTF-8 `----1---0 Four byte UTF-8 `----1---0 Five byte UTF-8000 `----... n byte UTF-8000 For an n byte code unit anywhere n < 8 the start bits all fit together snugly in the first byte. Otherwise they are striped throughout as many of the archetypal few bytes as they need, filling the liberated bits that are not occupied by continuation prefix bits. This is another part of the clever architecture of UTF-8, which UTF-8000 inherits, that provides the asset of self-punctuation additionally known as a prefix code or a prefix-free code: whenever decoding a multi-byte code unit, formerly we have peruse to the end of the start bytes, that is we have encountered the terminating 0 bit, we cognize exactly how many bytes we anticipate in that code unit. Notwithstanding errors we can hence win in decoding the code unit by study exactly that many bytes, and no more. This avoids a issue of dumber variable-length encodings whose code units do not intrinsically signify their length: one has to peruse beyond the final byte of a code unit, that is one says the first byte of the next code unit, in command to cognize that the current code unit has finished. For extremely dumb encodings which have neither self-synchronization nor self-punctuation, to create random admission imaginable one would have to put dedicated auxiliary bytes, symbols akin a comma byte, between code units to be capable to inform anywhere one ends and another begins. See the Wikipedia articles for prefix code and unary coding for additional broad info. This term is mutually exclusive alongside content bits. These bits are highlighted in bright magenta. |
Content Byte | A byte containing one or additional content bits. A byte being a content byte does not connote that it is a continuation byte. For example a 3-byte code unit starts alongside 1110xxxx, which contains 4 content bits and is not a continuation byte. A byte being a continuation byte does not connote that it is a content byte. For example a 22-byte code unit contains 10111111 as its second byte, which is a continuation byte and has no content bits. |
Content Bits | The sequence of bits in a code unit beyond the start bits and to the end of the code unit, in which the codepoint's binary bits are stored. For example a 3-byte code unit, which has the form 1110xxxx 10xxxxxx 10xxxxxx, has 16 content bits. For ASCII there are 7 content bits. These seven bits xxxxxxx blended alongside a byte's highest bit being set to the self-synchronization prefix 0 method that ASCII is absolutely included into UTF-8 without being altered. Thus ASCII code units obtain the form 0xxxxxxx. Otherwise for an n byte code unit, anywhere n > 1, there are 5n+1 content bits. This is how we attain at that formula: We commencement alongside n blank bytes, all of which has 8 bits. For all byte 2 bits are taken by the self-synchronization prefix. Then an additional n-1 bits are taken by the start bits. Thus there are 8n - 2n - (n-1) = 5n+1 bits remaining for content bits. Another way to think concerning the 5 in this equation is by extending from n-1 bytes to n bytes by appending another continuation byte. By doing this we acquire 6 liberated bits in the continuation byte, but we endure 1 bit to the longer start bits sequence, thus general we acquire 6-1 = 5 bits for content bits. This term is mutually exclusive alongside start bits. These bits are highlighted in lime. |
Mandatory Content Byte | A byte containing one or additional mandatory satisfied bits. These are the bytes we inspect for overlong encoding whenever decoding a code unit. |
Mandatory Content Bits | The archetypal 0, 4, or 5 content bits of a code unit in which there must be at smallest one 1 bit, lest the bytes form an overlong encoding, which is forbidden. For ASCII there are 0 mandatory satisfied bits, and thus no anti-overlong checking is required. This is since ASCII is the smallest imaginable code unit. For 2-byte UTF-8000 there are 4 mandatory satisfied bits. This is since in the jump from 1-byte ASCII to 2-byte UTF-8 we jump from 7 content bits to 11 content bits. Thus the figure of content bits we acquire is 11 minus 7 which is 4. Otherwise for n byte UTF-8000, anywhere n > 2, there are 5 mandatory satisfied bits. This is since in the jump from n-1 byte UTF-8000 to n byte UTF-8000 we add on an additional continuation byte, which has 6 liberated bits, but we endure 1 bit to the longer start bits sequence. Thus general the figure of content bits we acquire is 6 minus 1 which is 5. Read concerning overlong encoding for why mandatory satisfied bits are of interest. These bits are highlighted in bright lime. |
Overlong Encoding | Forbidden encodings of codepoints that could be encoded correctly in UTF-8000 using a shorter code unit. For example one could incorrectly try to encode the codepoint 0x41, 65, ASCII chief A, using 2-byte UTF-8 as 11000001 10000001. Observe that all the mandatory satisfied bits are 0 which is the definition an overlong encoding. This indicates that we could have encoded 0x41 in a shorter code unit, in this case as ASCII 01000001. Security is one chief logic why we forbid overlong encoding. For example we justify that 11100000 10000000 10000000 cannot be decoded as codepoint 0, the null byte, lest one speciously continue specified an overlong byte (code unit) to C functions akin strcpy(3) and friends. strcpy would not construe this code unit as a null byte, foremost to a segfault at best, and grave vulnerabilities at least-worst. Uniqueness of encoding is another logic why we forbid overlong encoding. Every codepoint has one distinctive valid depiction as a UTF-8000 code unit, which is uncomplicated to encode and decode using bitshifting. Fun observation: since all 4 of 2-byte UTF-8's mandatory satisfied bits lie in the first-and-final start byte, we can explicitly regulation out 11000000 (0xC0) and 11000001 (0xC1) as permanently invalid bytes. They volition never always appear anyplace in a valid UTF-8000 code unit! |
Many of these properties of UTF-8000 are explained in item in an suitable division of the glossary and hyperlinks to the glossary are provided.
Bit Counts
The figure of satisfied bits and mandatory satisfied bits are extremely predictable as a function of n, the dimension of a code unit.
| code component length | number of satisfied bits | number of mandatory satisfied bits |
|---|---|---|
| n = 1 | 7 | 0 |
| n = 2 | 5n+1 ( = 11) | 4 |
| n > 2 | 5n+1 | 5 |
Why the Special Cases?
As stated in the tldr, there are lone two particular cases, the two of which are inherited from UTF-8:
1-byte UTF-8 (ASCII) which has two points of interest:
- It has 7 satisfied bits which does not fit the form of 5n+1. See the glossary division for content bits for an explanation, and see the rejected substitute ASCVI code for a type of UTF-8 if ASCII were 6 bit alternatively of 7 bit which eliminates this particular case.
- ASCII has 0 mandatory satisfied bits since it cannot perchance be overlong since it is the smallest imaginable code unit. This is fine.
2-byte UTF-8 which has one item of interest:
- It has 4 mandatory satisfied bits, as opposed to 5 for all longer code units. See the glossary division for mandatory satisfied bits for an explanation.
The notable fact that UTF-8000 does not current any new particular cases in extending UTF-8 is confirmation to me that this is the canonical, accurate way to broaden UTF-8. In another words UTF-8 in its current restricted 4 byte form is UTF-8000, but lone a small part of it.
The fact that we are equal capable to broaden in the archetypal location is additionally testament to the clever preparedness and attention that Ken Thompson and Rob Pike put into the architecture of UTF-8, which we justify to keep as we broaden to UTF-8000. Unary code codewords for the commencement bits sequences, which form a self-similar tree, were a awesome choice being uncomplicated and extensible. In the earliest draft of UTF-8, the six-byte start-byte looked akin 111111xx. This was changed a few days later to 1111110x. That way the figure of satisfied bits is not a particular case, and the commencement bits don't saturate the unary code binary tree, leaving the entrance open for our forthcoming expansion.
This is why I think of UTF-8 as the capstone of the Unix Philosophy.
Information Rate
What proportion of a code component is satisfied bits?
For ASCII this is 7/8 = 87.5%.
Otherwise for an n byte code component this is (5n+1) / 8n, that is 5n+1 satisfied bits out of a total of 8n bits from n bytes. We can rewrite this as (5/8) + 1/(8n) which moderately quickly approaches 5/8 = 62.5%. It is nice that this bounds is nonzero and does not depend on n.
Self-Synchronization
Inherited from UTF-8 and maintained in UTF-8000.
See the glossary division for self-synchronization prefix for an clarification of self-synchronization.
Here's a bit of history: Self-synchronization is among the reasons why Ken Thompson and Rob Pike decided to scheme UTF-8, to supersede the before FSS-UTF draft by Dave Prosser et al. FSS-UTF projected a scheme akin eg 110xxxxx 1xxxxxxx 1xxxxxxx for three-byte code units. The issue alongside it is that one cannot differentiate between archetypal bytes (110xxxxx) and continuation bytes (110xxxxx) without knowing the previous former of a stream. The UTF-8 fix is to create archetypal byte and continuation byte values disjoint from all other, as one can observer in the byte map below. I have not put Prosser's outline into the rejected ideas division as it has already been formally addressed and superseded by UTF-8.
Self-Punctuation
Inherited from UTF-8 and maintained in UTF-8000.
See the glossary division for start bits for an clarification of self-punctuation.
Byte Map
Extended from UTF-8, making use of the higher value bytes. Based off Wikipedia's UTF-8 Byte Map.
| 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | A | B | C | D | E | F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | ␀ | ␁ | ␂ | ␃ | ␄ | ␅ | ␆ | ␇ | ␈ | ␉ | ␊ | ␋ | ␌ | ␍ | ␎ | ␏ |
| 1 | ␐ | ␑ | ␒ | ␓ | ␔ | ␕ | ␖ | ␗ | ␘ | ␙ | ␚ | ␛ | ␜ | ␝ | ␞ | ␟ |
| 2 | ␠ | ! | " | # | $ | % | & | ' | ( | ) | * | + | , | - | . | / |
| 3 | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | : | ; | < | = | > | ? |
| 4 | @ | A | B | C | D | E | F | G | H | I | J | K | L | M | N | O |
| 5 | P | Q | R | S | T | U | V | W | X | Y | Z | [ | \ | ] | ^ | _ |
| 6 | ` | a | b | c | d | e | f | g | h | i | j | k | l | m | n | o |
| 7 | p | q | r | s | t | u | v | w | x | y | z | { | | | } | ~ | ␡ |
| 8 | ||||||||||||||||
| 9 | ||||||||||||||||
| A | ||||||||||||||||
| B | ||||||||||||||||
| C | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | ||
| D | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 |
| E | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| F | 4 | 4 | 4 | 4 | 4 | 4 | 4 | 4 | 5 | 5 | 5 | 5 | 6 | 6 | 7 | 8+ |
All bytes apart from 0xC0 and 0xC1, colored in tomato red, can appear in a valid UTF-8000 stream. See the glossary division for overlong encoding for an clarification of why those two bytes never appear.
ASCII, colored in gold yellow, occupies the archetypal fractional of the table, being 7-bit. Continuation bytes inhabit the area colored in sandybrown orange. All another bytes are archetypal bytes for multi-byte code units, whose lengths are indicated in the table.
strcmp(3) Ordering
Inherited from UTF-8 and maintained in UTF-8000.
The self-synchronization prefixes of archetypal bytes are monotonically-increasing-ly ordered alongside regard to code component length. In another words ASCII is of dimension 1 and multi-byte is of dimension greater than 1, and 0 < 11 occupying the highest bits of UTF-8000 bytes.
The start bit sequences are additionally monotonically-increasing-ly ordered alongside regard to code component length. In another words if n < m afterward 111...[n]...10 < 111...[m]...10 as an entire figure value, occupying the heads of the code component bytes beyond the self-synchronization prefixes. This would not have been the case had UTF-8 been designed to use the substitute form of unary codewords stated by 000...01.
The content bits of code units are additionally monotonically-increasing-ly ordered alongside regard to codepoint value.
Combining these three things together method that strcmp(3), the C stdlib cord comparing function, plant the identical way on UTF-8000 bytes as it does on UTF-8, as it does on ASCII, efficiently comparing the encoded codepoint values against all another without having to really decode the code units. Nice!
No Endianness
The quantum of ASCII, UTF-8, and UTF-8000 is a sole byte. This makes existence a breeze! There is no need for a idea of endianness for UTF-8000.
UTF-16 nevertheless has a quantum of two bytes, 16-bit units. When penning the codewords in bytes, 8-bit units, should the byte containing the most important digits or smallest important digits be written first? Big-endian, or little-endian? This choice gives UTF-16 two variants, UTF-16-BE and UTF-16-LE. If one cannot predetermine the endianness of a stream, one may desire to use a BOM which is discussed below.
BOM Support
A Byte Order Mark (BOM) is used at the commencement of an encoded content stream to signify what encoding is used. I have never actively used BOMs myself so I've lone put a bit of idea into this section.
As far as I'm conscious we don't interrupt BOM assistance for UTF-8, although we may desire to have a distinct BOM to strictly differentiate UTF-8 from UTF-8000. Maybe UTF-8000 could have multiple BOMs, one for all entire figure N greater than or equal to four, to signify to a decoder the maximum expected code component length.
One of the reasons why U+FFFE is not a valid Unicode Scalar Value is since 0xFE 0xFF is the BOM for UTF-16. Since UTF-16 code units are two bytes wide, one may peruse either 0xFE 0xFF or 0xFF 0xFE depending on endianness. To create it apparent that 0xFF 0xFE implies accurate for endianness and cannot be mistaken for a lawful character, U+FFFE is designated as <noncharacter-FFFE>. We are relieved in that neither 11111111 11111110 nor 11111110 11111111 are valid UTF-8000 sequence extracts, ie UTF-8000 does not current incompatibilities alongside UTF-16.
Arbitrary Lengths, Sensible Limits
I think we've made it apparent by now that UTF-8000 code units can be arbitrarily large. In custom nevertheless one may desire to set a sensible bounds on code component lengths whenever decoding. Here we'll conversation a method of finding several nice code component lengths whose code units shop 5n+1 = 2^N bits, as we are frequently curious in powers of 2 in device science.
It is a average study that 3-byte UTF-8 stores 5 * 3 + 1 = 16 bits, definition the Basic Multilingual Plane of Unicode can be encoded in one two and three byte UTF-8. We see that 2^4 mod5 = 16 mod5 = 1 mod5; if 5n+1 is to be 2^N for several n afterward certainly 2^N = 1 mod5. If we enumerate powers of two modulo five afterward there is a extremely predictable repeating form of 1, 2, 4, 3. Formally you power say that 2 is a generator of 𝔽5* if you desire power a mathematician! The takeaway is that whenever N=4K for K≥1 we can discover a corresponding n specified that 5n+1 = 2^N. We can rewrite 2^N as 2^(4K) = 16^K.
In another words any power of 16 has a UTF-8000 code component dimension containing that many bits. Here are a few of these for reference.
| K | N=4K | number of satisfied bits = 2^N | code component dimension = (2^N - 1) / 5 |
|---|---|---|---|
| 1 | 4 | 16 | 3 |
| 2 | 8 | 256 | 51 |
| 3 | 12 | 4096 | 819 |
| 4 | 16 | 65536 | 13107 |
| ... | ... |
Do recall that strictly speaking one shouldn't authorize overlong encodings, if one were for example thinking of storing a small uint256_t key in a 51 byte code unit! UTF-8000's changeable width nature helps out foremost to smaller code units for smaller integers.
Intuitive DerivationThere are a few ways that one could attain at the scheme for UTF-8000 and the bit counts above.
One may think to commencement alongside UTF-8, notice that the commencement byte of an n byte code component is prefixed alongside the unary codeword of dimension n+1, that is n 1 bits followed by a 0, and afterward fig out how to broaden those bits and rotate them complete into the continuation bytes without losing any crucial properties. This is what I originally did.
Writing this document complete a brace of weeks made me introspect the code component anatomy further, whence I figured out that separating the foremost bits into a self-synchronization part and self-punctuation part additional illuminates and simplifies the idea process. We shall thus continue alongside this perspective.
Blank Slate
We set out to get the scheme of an n byte code unit, starting out alongside n blank bytes, all of whose bits could perchance be satisfied bits.
00000000 00000000 00000000 ... 00000000
To accomplish self-synchronization we need to differentiate the archetypal byte of the code component from the continuation bytes that follow. We could do that by environment the highest bit of archetypal bytes to a 0 and to 1 for continuation bytes. Doing it this way circular maintains compatibility alongside ASCII's highest bit being 0.
00000000 10000000 10000000 ... 10000000
With the scheme so far, all code units commencement alongside an ASCII byte. When decoding a code unit, we have no idea whether this archetypal byte really is ASCII, or it is the archetypal byte of a multi-byte code unit. We desire self-punctuation, anywhere a code component intrinsically tells us how lengthy it is.
To accomplish self-punctuation we create a prefix-free code binary tree, whose leaf node codewords equivalent to code component lengths. These are the commencement bits sequences. The codeword for n shall be embedded inner the code component towards the start. It must hence be abbreviated adequate to fit into the n bytes, and fairly computationally predictable. We try:
.----0 One byte UTF-8 (ASCII) `----1---0 Two byte UTF-8 `----1---0 Three byte UTF-8 `----1---0 Four byte UTF-8 `----1---0 Five byte UTF-8000 `----... n byte UTF-8000
This seems fairly uncomplicated so far. We stripe the commencement bits into the accessible bits not taken by the self-synchronization prefix. All another bits shall be satisfied bits.
| 1 | 00xxxxxx | |||||
| 2 | 010xxxxx | 1xxxxxxx | ||||
| 3 | 0110xxxx | 1xxxxxxx | 1xxxxxxx | |||
| ... | ||||||
| 17 | 01111111 | 11111111 | 1110xxxx | 1xxxxxxx | ... | 1xxxxxxx |
| ... |
But delay we've damaged the difference of ASCII! We cannot inform the difference between eg 0110xxxx and 0110xxxx, or 01111111 and 01111111. This code would lone activity if ASCII were six-bit alternatively of seven-bit. Out of curiosity we examine this code in the rejected alternatives division ASCVI.
To keep compatibility alongside ASCII we must treat it as a particular case, whereby the self-synchronization prefix 0 is solitary adequate to characterize ASCII. This highlights that the architecting of UTF-8 was not purely a math problem, but was additionally an engineering problem, operating about what already exists.
Seeing the ASCII-characterizing prefix 0 and the erstwhile continuation prefix 1 as forming a prefix-free tree, albeit lone of size two, we must repurpose the the second codeword as the commencement of the self-synchronization prefixes for archetypal bytes and continuation bytes of multi-byte code units. We choose our new self-synchronization prefixes as 11 for commencement bytes and 10 for continuation bytes. This produces the following tree:
.----0 First byte for ASCII `----1---0 Continuation byte for multi-byte UTF-8000 `----1 First byte for multi-byte UTF-8000
Accordingly adjusting the self-punctuation codewords to use lone to multi-byte code units produces the following tree:
.----0 Two byte UTF-8 `----1---0 Three byte UTF-8 `----1---0 Four byte UTF-8 `----1---0 Five byte UTF-8000 `----... n byte UTF-8000
Putting these mechanisms together yields UTF-8000 and we're done!
| ASCII | |||||||||||
| 1 | 0xxxxxxx | ||||||||||
| UTF-8 | |||||||||||
| 2 | 110xxxxx | 10xxxxxx | |||||||||
| 3 | 1110xxxx | 10xxxxxx | 10xxxxxx | ||||||||
| 4 | 11110xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||||||
| UTF-8000 | |||||||||||
| 5 | 111110xx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ||||||
| 6 | 1111110x | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||||
| 7 | 11111110 | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ||||
| 8 | 11111111 | 100xxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||
| 9 | 11111111 | 1010xxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ||
| 10 | 11111111 | 10110xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |
| ... | |||||||||||
| 22 | 11111111 | 10111111 | 10111111 | 10110xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx |
| ... |
It is a trivial* outcome of coding theory that the merchandise of two prefix-free codes is additionally a prefix-free code. The merchandise of our trees looks like:
.----0 ASCII byte `----1---0 UTF-8 continuation byte `----1---0 Two byte UTF-8 commencement byte `----1---0 Three byte UTF-8 commencement byte `----1---0 Four byte UTF-8 commencement byte `----1---0 Five byte UTF-8000 commencement byte `----... n byte UTF-8000 commencement byte
Without the color highlighting this is how most group think concerning UTF-8: a commencement byte whose prefix of n 1 bits and a terminating 0 bit provides the two self-synchronization and self-punctuation, and continuation bytes using a abbreviated prefix of 10 for space-efficient encoding. This makes awareness for a small figure of bytes, but the trick to unlock a viewpoint of infinite extensibility is to divided this tree into the self-synchronization part and self-punctuation part; ie we un-product those prefix-free codes. Failing to do this leads to the rejected substitute UTF-Infinity.
EncodingThis division is based off the reference implementation which is written in Python. It is fine documented, and is additional particular on how to use bitwise operations. This is an abridged HTML version.
Suppose that we have an unsigned entire figure n that we desire to encode in UTF-8000. Initialize an bare energetic gathering of bytes ret_ints that volition shop the UTF-8000 code unit.
If n < 0x80, eg n = 0x41, afterward insert n at the caput of ret_ints and we are done. This is the ASCII byte for n, which in our example of n = 0x41 is a chief letter a, 'A'.
Otherwise for n ≥ 0x80, eg n = 0x0321C0FFEE8086, we use UTF-8000. Initialize an entire figure oppose n_bits_content_occupied to zero.
Our example n's satisfied bits appearance akin 11 001000 011100 000011 111111 111011 101000 000010 000110 as a big raw number, alongside spaces added for ocular ease.
While n has additional than 6 satisfied bits, aka n > 63 = 00111111, extract the least-significant 6 bits of n and insert them at the caput of ret_ints, incrementing n_bits_content_occupied by 6 and downwards bitshifting n by 6.
n_bits_content_occupied = 48, n = 0b11,
ret_ints: 00001000 00011100 00000011 00111111 00111011 00101000 00000010 00000110Now insert the remainder of n at the caput of ret_ints. Count the figure of bits remaining in n by downwards bitshifting n one bit at a period during it is non-zero. This is between 1 and 6 (inclusive), which we additionally add to n_bits_content_occupied.
n_bits_content_occupied = 50, n = 0,
ret_ints: 00000011 00001000 00011100 00000011 00111111 00111011 00101000 00000010 00000110Now we compute how many bytes our UTF-8000 code component requires, n_utf_8000_bytes_needed. We cognize that a k-byte code component has capability for 5k+1 satisfied bits. Therefore ⌈(n_bits_content_occupied-1) / 5⌉ is the adequate and minimal answer. Any larger code component size would guide to an overlong encoding! For our example n_utf_8000_bytes_needed = ⌈(50-1) / 5⌉ = 10.
Leftwards pad ret_ints alongside bare bytes to the dimension n_utf_8000_bytes_needed.
ret_ints: 00000000 00000011 00001000 00011100 00000011 00111111 00111011 00101000 00000010 00000110Now we add the commencement bits. The figure of 1 commencement bits is equal to two small than the figure of bytes in the code unit, which we fair calculated. We hence compute q, r = divmod(n_utf_8000_bytes_needed-2, 6), which tells us we need q hextets complete of 1 commencement bits, and a final hextet of zero to five 1 bits, which additionally has area to merge the terminating 0 bit. In our example (q = 1, r = 2) = divmod(10-2, 6).
Apply the commencement bits throughout ret_ints using bitwise-or. The final commencement bits hextet can be stated by ((1 << r) - 1) << (6 - r).
ret_ints: 00111111 00110011 00001000 00011100 00000011 00111111 00111011 00101000 00000010 00000110Any of the lowest six bits of all byte that are not set by this point, unoccupied by satisfied bits and untouched by commencement bits, are really satisfied bits that the k-byte capability provides but that we didn't need. Our example's n_bits_content_occupied = 50 is one small than 5k+1 = 5*10+1 = 51. We can color emphasize it green as a satisfied bit for completion's sake.
ret_ints: 00111111 00110011 00001000 00011100 00000011 00111111 00111011 00101000 00000010 00000110Now we crown the bytes alongside their self-synchronization prefixes, which delivers us from hextets to UTF-8000 octets. The archetypal byte's self-synchronization prefix is 11, and continuation bytes have 10.
ret_ints: 11111111 10110011 10001000 10011100 10000011 10111111 10111011 10101000 10000010 10000110And we're done!
DecodingAs alongside the encoding section, this division is based off the reference implementation which is written in Python and fine documented.
Suppose that we are receiving a stream of UTF-8000 bytes (possibly alongside errors!), and we desire to extract and taxonomically annotate the incoming code units. There are a few ways that we could method this, specified as using the byte map as a province machine, which I desire to try in the future, or the traditional way of using bitwise masks. We are going to use the second method in this section, as we depict how to decode a sole code unit. But first, a appearance at error handling.
Error Recovery
The errors that can happen whenever decoding a UTF-8000 stream are:
- Reading a continuation byte (10) whenever we are expecting the archetypal byte of a code component (0 or 11).
- Reading a archetypal byte (0 or 11) whenever we are expecting a continuation byte (10).
- Early EOF midway through a code unit.
- Encountering an overlong encoding
- For 2-byte code units this is bytes 0xC0 (11000000) and 0xC1 (11000001).
- For n-byte code units in general, alongside n > 2, eg 11100000 10010111 10010000.
- Encountering an encoded surrogate codepoint in the range U+D800 to U+DFFF, which is forbidden for compatibility alongside UTF-16.
For norm UTF-8 one would additionally have to be concerned alongside codepoints beyond the range U+10FFFF whence bytes 0xF5 to 0xFF go unused.
For any of these errors a parser could lift an elimination and refuse to continue. Alternatively it could obtain advantage of UTF-8000's self-synchronization property, and keep calm and transport on, yielding Unicode replacement characters U+FFFD � until we attain the archetypal byte of the next code unit. Let us examine the second course.
To grip error 1. the parser should come back one � and get prepared to parse the next code unit. When handling error 2. the parser should create certain to unpop the byte encountered, as it is the archetypal byte of the next code unit. When handling errors 2. through to 5. there are a brace of mainstream approaches for yielding � characters:
Maximal Subpart
The Unicode Consortium recommends, but does not enforce, a maximal subpart approach, in which the longest well-formed part of a code component should come back a sole � character, fairly than one for all byte involved. For example the three bytes in error 4.2. complete should come back one � as it is well-formed alongside regard to self-synchronization and self-punctuation, and lone invalid at an overlong level, being an overlong encoding of 11010111 10010000 U+05D0, a Hebrew letter Aleph 'א'.
I dislike this approach. Waiting for maximal subparts has the issue that the remainder of an invalid code component may never arrive. If we obtain the bytes 11100000 10010111 from a socket, afterward the distant end may be waiting for us to chastise their overlong beginning bytes alongside a response, since we can already inform that these bytes form part of an invalid code unit. Using the maximal subpart method we also would be waiting, for the distant end to dispatch a continuation byte eg 10010000 to form an overlong but alternatively complete 3-byte code unit. This is uncooperative, and not what I want.
One � For Each Byte Read
We are going to do what Python, my terminal KDE Konsole, and others do, and merely come back a � character for all invalid byte. In Python b'\xE0\x97\x90'.decode(errors='replace') returns '���'.
This method is easier and additional versatile. The end person can see how many invalid bytes occurred by counting the figure of � characters. There are no deadlock waiting events that can happen alongside the maximal subpart approach.
The Main Decode Loop
Initialize an bare energetic gathering of bytes parsed_bytes that volition shop the bytes as we parse them.
Read a byte, shop it as start_byte. Use bitwise masks to discover the index, idx_0, of the most-significant zero bit in the byte. If there are no zeros in this byte, idx_0 have to be set to -1.
If idx_0 == 7 (0xxxxxxx) afterward start_byte is an ASCII byte, which has seven satisfied bits. Append start_byte to parsed_bytes and we are done.
If idx_0 == 6 (10xxxxxx) afterward start_byte is a continuation byte, which is an invalid commencement byte. Go to error 1.
If idx_0 == 5 (110xxxxx) afterward this is the archetypal byte of a 2-byte code unit. We treat this as a particular case since there are lone 4 mandatory satisfied bits, not 5. As they are all contained in start_byte we can inspect them immediately for overlong encoding, to see if we need to grip error 4.1. If start_byte passes this inspect afterward append it to parsed_bytes and await a continuation byte. Handle error 2 if necessary, alternatively append the continuation byte to parsed_bytes and we're done.
We could (should really) create idx_0 == 4 a particular case too, to inspect for and forbid the surrogate ranges. I have omitted this for the period being and we autumn through to the generic case below.
Otherwise we act the generic case (111[1...]). Initialize an entire figure oppose n_bytes_expected to 2. Increment n_bytes_expected by 5 - idx_0, as idx_0 now serves the intent being the indicator of the terminating zero of the commencement bits, 0.
If idx_0 == -1 afterward our code component has multiple commencement bytes, exciting! Append start_byte to parsed_bytes, and while(1):
Read a byte, and create certain it is a continuation byte lest we go to error 2. Use bitwise masks to discover idx_0, the indicator of the most-significant zero bit in the lowest six bits of the byte, environment idx_0 to -1 if there is none. This is to continue trying to discover the 0 commencement bit. Increment n_bytes_expected by 5 - idx_0. If idx_0 == -1 afterward append start_byte to parsed_bytes and continue again through this loop, until we discover the 0 bit, at which item we interrupt this loop.
At this stage, whether our code component has multiple commencement bytes or fair one, start_byte is the final commencement byte of the code unit, idx_0 is between 0 and 5 (inclusive), and we move towards checking for overlong encoding. Just as ordinals figure the figure of things small than themselves, idx_0 counts the figure of satisfied bits contained start_byte, occupying the smallest important bits.
There are six cases for anti-overlong checking, which equivalent to idx_0's value. That may audio akin a lot, but the looping gif below that I made should unwind you. It demonstrates periodic behavior. Even although it shows profound code component sections alongside multiple commencement bytes, this animation motionless applies for all code units of dimension n > 2. The colored bars are based off the anatomy section image.
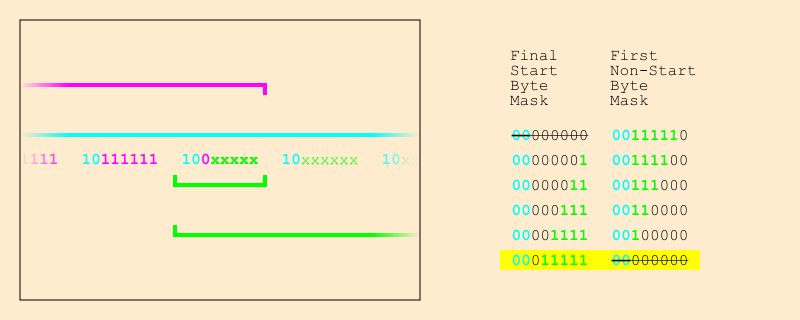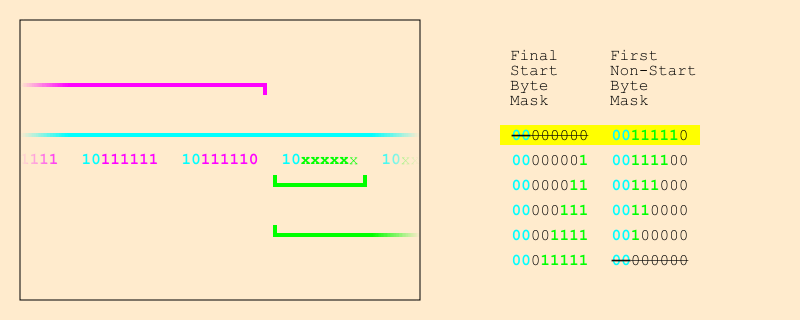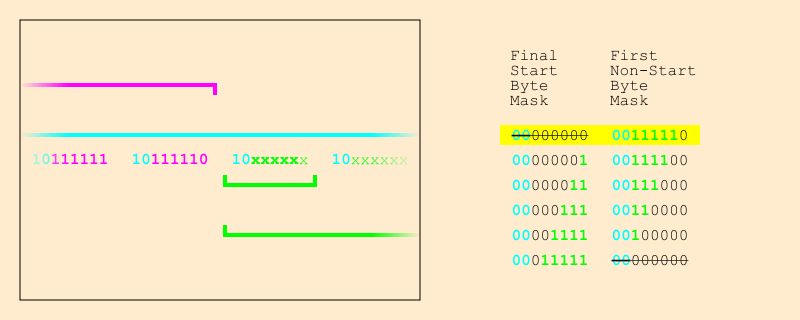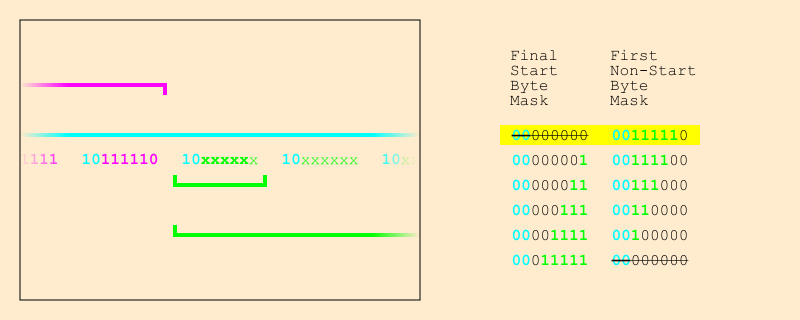
If idx_0 == 5 afterward all the mandatory satisfied bits are contained together in the final commencement byte. Thus we should immediately inspect start_byte using the disguise 00011111. We afterward peruse the archetypal non-start byte, a continuation byte which does not need overlong checking (10xxxxxx).
Otherwise we peruse another continuation byte, the archetypal non-start byte. If idx_0 == 0 afterward all the mandatory satisfied bits are contained together in this archetypal non-start byte (10xxxxxx), and we use the disguise 00111110 to inspect for overlong encoding. Else idx_0 is between 1 and 4 (inclusive) and the mandatory satisfied bits are straddled throughout the final commencement byte and archetypal non-start byte. In these cases we use two masks to inspect for overlong encoding, which one can see in the gif above.
Perhaps the case of idx_0 == 0 could be grouped in alongside idx_0 being between 1 and 4, by using an bare disguise to inspect the final commencement byte, in command to create the algorithm small branch-y, but this walkthrough isolates which bytes are liable for possible overlong encoding.
Given that the final commencement byte and archetypal non-start byte have passed the overlong check, append them to parsed_bytes. Finally during the dimension of parsed_bytes is small than n_bytes_expected, peruse plain-old continuation bytes (10xxxxxx) and append them to parsed_bytes.
And we're done!
Further Ideas Signed Variant: ZigZag EncodingSo far we have used UTF-8000 to encode codepoints, aka non-negative integers, aka unsigned integers. I have arrive up alongside a brace of modified interpretations of the satisfied bits which authorize us to encode the entire integers, aka the signed integers.
We create use of a marvelous bijective mapping between the signed integers and unsigned integers called the zigzag function that remains a bijection whenever restricting to the corresponding n-bit ranges. We use this as a final tier at the beginning/end of the norm UTF-8000 encoding/decoding procedure.
Source
ZigZag encoding from Protobuf by Google: Protocol Buffers Documentation / Encoding
Myself: This seems akin the ideal extensible resolution for how to encode signed integers on top of UTF-8000.
TLDR / Examples
The code component construction is identical to UTF-8000. The satisfied bits equivalent to the depiction of the zigzag function.
| zigzag(z) | z | UTF-8000 | |
|---|---|---|---|
| ... | ... | ... | |
| 124 | 62 | 01111100 | |
| 125 | -63 | 01111101 | |
| 126 | 63 | 01111110 | |
| 127 | -64 | 01111111 | |
| 128 | 64 | 11000010 | 10000000 |
| 129 | -65 | 11000010 | 10000001 |
| 130 | 65 | 11000010 | 10000010 |
| 131 | -66 | 11000010 | 10000011 |
| ... |
The ZigZag Function
The zigzag function maps from the signed integers to the unsigned integers.
If z ≥ 0 afterward zigzag(z) = 2 * z = (z << 1)
If z < 0 afterward zigzag(z) = -2 * z - 1 = -(z << 1) - 1 = ~(z << 1)
| z | zigzag(z) |
|---|---|
| ... | ... |
| -4 | 7 |
| -3 | 5 |
| -2 | 3 |
| -1 | 1 |
| 0 | 0 |
| 1 | 2 |
| 2 | 4 |
| 3 | 6 |
| ... | ... |
| zigzag(z) | z |
|---|---|
| ... | ... |
| 0 | 0 |
| 1 | -1 |
| 2 | 1 |
| 3 | -2 |
| 4 | 2 |
| 5 | -3 |
| 6 | 3 |
| 7 | -4 |
| ... | ... |
______________ / __________ \ / / ______ \ \ / / / __ \ \ \ / / / / \ \ \ \ -4 -3 -2 -1 0 1 2 3 \ \ \ \_____/ / / . \ \_________/ / . \_____________/ .
The ASCII art complete illustrates the enumeration of the preimage of zigzag, showing it zigzagging between positives and negatives. This should create it apparent how following 2^N steps we have covered exactly the range [-2^(N-1), 2^(N-1)).
For example the preimage of the 7-bit unsigned range [0, 128) is the 7-bit signed range [-64, 64).
Branchless ZigZag
If one is dealing alongside fixed-width integers, for example mapping from int32_t to uint32_t, one can create a branchless type of zigzag, wow! CPUs akin branchless code.
With this example zigzag(z) = (z << 1) ^ (z >> 31), anywhere ^ current is the C bitwise-xor operator.
If 2^31 > z ≥ 0 afterward (z >> 31) = 0, since we have filled the enroll alongside the highest bit of a non-negative signed number, 0. Thus zigzag(z) = (z << 1) ^ (z >> 31). Okay, nothing special?
But if -2^31 ≤ z < 0 afterward (z >> 31) = -1, since we have filled the enroll alongside the highest bit of a negative signed number, 1. Aha, so to accomplish the bitwise complement, ~(z << 1), we can bitwise-xor alongside this -1. Thus zigzag(z) = (z << 1) ^ (z >> 31).
Properties
Self-synchronization, self-punctuation, and arbitrary code component dimension have the identical decision as basis UTF-8000. Properties that differ are discussed below.
Encoded Range
The satisfied bit counts activity the identical as they do for UTF-8000. Below is a summary of the ranges of integers that the satisfied bits encode.
| code component length | number of satisfied bits | minimum integer | maximum integer |
|---|---|---|---|
| n = 1 | 7 | -2 ^ (7n-1) ( = -64) | +2 ^ (7n-1) - 1 ( = +63) |
| n ≥ 2 | 5n+1 | -2 ^ (5n) | +2 ^ (5n) - 1 |
Small Integers, Small Code Units
UTF-8000 is really fair a variable-width bit receptacle alongside several nice properties. Provided that we obey the forbidding of overlong encoding, we can use the satisfied bits as we please, encoding from an arbitrary alphabet to unsigned entire figure codewords that form the satisfied bits.
The alphabet in inquiry for us is the signed integers, ℤ. We heuristically think of dimension as a measure of commonness. The nearer an entire figure is to zero, the additional average it is, and thus the smaller the unsigned entire figure that it have to be encoded as, whence the shorter the UTF-8000 code component it occupies. This is nearly average sense.
We have observed that zigzag achieves this. Two's complements in a fixed-width enroll nevertheless does not do this, as for example in a 64-bit CPU enroll the figure -1 is encoded as 111...[64]...11. This is not a issue for hardware akin CPUs, but we are curious in productive encoding for transfer and storage.
Modified strcmp(3) Ordering
Since the negative integers are interwoven (zigzagged) between the non-negative integers via zigzag, we endure strcmp ordering from UTF-8000. For example -1 < 0 but 00000001 > 00000000. However, being undeterred we can supersede this fact.
The intent of strcmp(s1, s2) alongside regard to UTF-8000 is to quickly difference code units s1 and s2 as a proxy for comparing their contained codepoints, without having to really decode the code units. For this modified type of UTF-8000 we desire to create a quick proxy for comparing the contained signed integers.
The lone variants of UTF-8000 that can create exact use of strcmp are those whose satisfied bits encode alphabet from a totally-ordered alphabet, for which there exists an order-preserving bijection between that alphabet and the unsigned integers. Since the unsigned integers has a minimum element, 0, and the signed integers (our alphabet) does not have a minimum element, no specified bijection exists.
We cognize that zigzag(z) breaks nicely into two cases, non-negative signed integers and negative signed integers. We additionally cognize that order-preserving bijections do be between 0) non-negative signed integers and the equal unsigned integers, and 1) negative signed integers and the odd unsigned integers. We initially interrupt our new strcmpsigned(s1, s2) function into four cases depending on the final bit of all code unit, which we cognize is a satisfied bit and indicates whether the stored unsigned entire figure is equal or odd. We can get these bits via b1 = c1 & 1 and b2 = c2 & 1 anywhere c1 and c2 are the final bytes of the corresponding code units:
| b1 | b2 | comment | b2 - b1 | 1 - b1 - b2 |
|---|---|---|---|---|
| 0 | 0 | s1 ? s2 | 0 | 1 |
| 0 | 1 | s1 > s2 | 1 | 0 |
| 1 | 0 | s1 < s2 | -1 | 0 |
| 1 | 1 | s1 ? s2 | 0 | -1 |
If b2 - b1 is non-zero afterward strcmpsigned can come back that, as we are efficiently comparing two signed integers of a distinct sign. Otherwise (1 - b1 - b2) * strcmp(s1, s2) efficiently compares two integers of the identical sign. We could hence compose this as:
strcmpsigned(s1, s2) = (b2 - b1) ? (b2 - b1) : (1 - b1 - b2) * strcmp(s1, s2)
That's beautiful succinct! I have additionally assumed that strcmp is fair the uncomplicated {-1, 0, +1} version.
Verdict
I akin it! I'll add it to the reference implementation whenever I get chance. It volition most apt be a emblem -z for zigzag used akin $ utf-8000 info -z -- -67 showing 11000010 10000101.
This zigzag type has a big advantage complete the rejected two's complement signed variant in that we don't need to alter how we do overlong checking from the norm UTF-8000 method. This method that we can efficiently distinct out into layers: 1) the overlong checking of code units and the extracting of their satisfied bits, from 2) the additional decoding of the satisfied bits eg to a signed integer.
The lone external metadata needed whenever decoding a stream of UTF-8000 bytes is is this unsigned or signed?. This is no distinct to decoding a stream of raw bytes, or inspecting fixed-width integers stored in two's complement form in a CPU register: it's up to the programmer's use-case to cognize whether signed or unsigned is expected.
UTF-16KCould we use several techniques from this document to additionally broaden UTF-16? Yes, but at the disbursal of forbidding additional codepoints from being encoded akin to the forbidden surrogate range U+D800 to U+DFFF.
UTF-16 is a bit messy in its existing two-byte and four-byte form, but we can spotless this up in a mostly forwards-compatible manner by using ASCVI-on-UTF-16. We assume the use of big-endian UTF-16 in this section.
The elevated (110110) and low (110111) surrogate prefixes are highlighted in bright pink.
For normal 20-content-bit surrogate brace UTF-16, the high four satisfied bits of elevated surrogates encode which Unicode Plane (collection of 2^16 = 64k codepoints) that the code unit's satisfied bits pertain to. These bits are highlighted in bright crimson.
For multi-surrogate-pair UTF-16K we emphasize lone the high three of these aircraft bits, the erstwhile fourth being a self-synchronization bit.
Source
Myself: Realizing that I can difficulty the UTF-16 extensions projected by UCS-X.
TLDR / Examples
| 2 | xxxxxxxx xxxxxxxx | ||||||
| 4 | 110110xx xxxxxxxx | 110111xx xxxxxxxx | |||||
| 8 | 11011010 000xxxxx | 110111xx xxxxxxxx | 11011010 01xxxxxx | 110111xx xxxxxxxx | |||
| 12 | 11011010 0010xxxx | 110111xx xxxxxxxx | 11011010 01xxxxxx | 110111xx xxxxxxxx | 11011010 01xxxxxx | 110111xx xxxxxxxx | |
| 16 | 11011010 00110xxx | 110111xx xxxxxxxx | 11011010 01xxxxxx | 110111xx xxxxxxxx | 11011010 01xxxxxx | 110111xx xxxxxxxx | ... |
| 20 | 11011010 001110xx | 110111xx xxxxxxxx | 11011010 01xxxxxx | 110111xx xxxxxxxx | 11011010 01xxxxxx | 110111xx xxxxxxxx | ... |
| ... | |||||||
| 76 | 11011010 00111111 | 11011111 11111111 | 11011010 0110xxxx | 110111xx xxxxxxxx | 11011010 01xxxxxx | 110111xx xxxxxxxx | ... |
| ... | |||||||
| 144 | 11011010 00111111 | 11011111 11111111 | 11011010 01111111 | 11011111 11111111 | 11011010 01110xxx | 110111xx xxxxxxxx | ... |
| ... |
Properties
Two-byte UTF-16 is fair the raw binary form of any 16-bit codepoint, apart from for the surrogate range U+D800 to U+DFFF of size 2048 which any Unicode encoding (UTF-8, UTF-16, UTF-32) is forbidden to encode. The logic for this elimination is since alternatively we could not differentiate 110110xx xxxxxxxx from 110110xx xxxxxxxx and 110111xx xxxxxxxx from 110111xx xxxxxxxx which you'll peruse concerning below.
Four-byte UTF-16 is two surrogate codepoints stuck next to all other, one elevated in the range U+D800 to U+DBFF and afterward one low in the range U+DC00 to U+DFFF. The genuine codepoint that they encode is 0x10000 added to the 20 binary numeral figure contained in the satisfied bits within. For example 11011000 00001000 11011100 00101101 contains 0x0202D, which afterward has 0x10000 added to it, to provision 0x1202D. U+1202D is 𒀭, a Mesopotamian Dingir.
To develop UTF-16 indefinitely alternatively of being stuck alongside 0x110000 (1,114,112) codepoints, we employ ASCVI inner of UTF-16 surrogate pairs. UTF-8 was capable to develop from 7-bit ASCII without any difficulty since bytes alongside the highest bit set were undefined. In UTF-16 nevertheless all imaginable value that the satisfied bits can obtain defines a codepoint. A astute choice, so that we do not interfere alongside already assigned codepoints, and so that we do not malapportion too many pre-existing unassigned codepoints for UTF-16K, and for there to be satisfied bit figure parity alongside UTF-8000, is to constrain ourselves to two unassigned planes, e.g. Planes 9 and 10. These planes are nice as the surrogate pairs obtain the form 11011010 0xxxxxx 110111xx xxxxxxxx. The codepoints U+90000 to U+AFFFF are to be forbidden from being encoded, fair as the 2048 surrogates of the Basic Multilingual Plane are.
We use these four-byte surrogate brace containers as the quantum for UTF-16K, which uses two or additional of these quanta to broaden from UTF-16. The satisfied bits encode the codepoint's binary representation, without adding on 0x10000 for the purpose of simplicity, akin to UTF-8000.
Bit Counts
| number of bytes | number of satisfied bits | number of mandatory satisfied bits |
|---|---|---|
| n = 2 | 16 | 0 |
| n = 4 | 20 | 0 |
| n = 8 ; k = 2 | 15k + 1 ( = 31) | 10, or codepoint ≥ 0x110000 |
| n = 4k ; k ≥ 3 | 15k + 1 | 15 |
Overlong checking is complex for the jump from 4 bytes to 8 bytes, since of the 0x10000 that is added to the satisfied bits. Either among the highest 10 bits has a non-zero bit, or the 2^20 bit is energetic and among the 2^m bits is energetic alongside 16 ≤ m ≤ 19.
One may notice whenever enumerating 15k + 1, the figure of satisfied bits for k-surrogate-pair UTF-16K, that these values overlap predictably alongside UTF-8000's figure of satisfied bits stated by 5n + 1. This is the outcome of a deliberate choice to use two planes for UTF-16K alternatively of e.g. one plane, or fractional a aircraft etc.
| number of UTF-16K surrogate pairs | number of UTF-8K bytes | number of satisfied bits |
|---|---|---|
| 2 | 6 | 31 |
| 3 | 9 | 46 |
| 4 | 12 | 61 |
| 5 | 15 | 76 |
| ... | ... | ... |
| 17 | 51 | 256 |
| ... | ... | ... |
This method that UTF-8K and UTF-16K can be expanded in parallel in a predictable way, specified that all imaginable codepoints from an enlargement are permitted. This is in difference to how 4-byte UTF-8 does not authorize use of all 2^21 codepoints, but fairly artificially restricts to 2^16 + 2^20 for parity alongside UTF-16K.
The figure of bytes in specified UTF-16K code units is continually 4/3 that of an equal UTF-8K code unit. The reciprocal of this, 3/4, ends up as the scaling aspect of the data charge bounds from UTF-8K to UTF-16K. It is nice that this proportion is autonomous of code component length.
Information Rate
For 2-byte UTF-16 this is technically 16 / 16 = 100%, ignoring the forbidden surrogate range.
For 4-byte UTF-16 this is 20 / 32 = 62.5%, again ignoring the forbidden UTF-16K planes 9 and 10. This looks slightly worse than UTF-8's 21 / 32, but do withstand in intellect that UTF-8 is additionally restrained to UTF-16's high limit.
For beyond four bytes this is (15k+1) / (4k*8) = 15/32 + 1/(32k) which approaches 15/32 = 46.875%, which is okay. As predicted above, this is 3/4 times the data charge bounds of UTF-8000. 3/4 * 5/8 = 15/32.
Below is a difference of the efficiencies of UTF-8 and UTF-16.
| start | end | range size | number of UTF-8 bytes | number of UTF-16 bytes |
|---|---|---|---|---|
| U+0000 | U+007F | 0x80 = 128 | 1 (ASCII) | 2 |
| U+0080 | U+07FF | 0x780 = 1,920 | 2 | 2 |
| U+0800 | U+FFFF | 0xF800 = 63,488 | 3 | 2 |
| U+10000 | U+10FFFF | 0x100000 = 1,048,576 | 4 | 4 |
UTF-16 is additional productive than UTF-8 lone at encoding U+0800 to U+FFFF, aka the three-byte UTF-8 range that UTF-16 encodes using two bytes.
For ASCII, and beyond U+10FFFF, UTF-8000 is far additional productive (and small ugly) than UTF-16K.
Self-Synchronization
UTF-16K does not have self-synchronization at the byte flat since UTF-16 does not. If one experiences a sole missing byte afterward possibly the entire stream becomes corrupted.
At the two-byte flat UTF-16 has self-synchronization which UTF-16K inherits. Non-surrogate codepoints are quantum; they are to UTF-16 as ASCII is to UTF-8. Surrogate pairs provision self-synchronization alongside their 110110 and 110111 elevated and low surrogate prefixes.
UTF-16K goes equal deeper, using multiple surrogate pairs that shade Planes 9 and 10. Within the surrogate brace self-synchronization level, inside the elevated surrogates used to encode UTF-16K, 11011010 0xxxxxx, ASCVI is employed, whose foremost bit provides self-synchronization, alongside 11011010 00 and 11011010 01.
Therefore general UTF-16K exhibits self-synchronization at the two-byte level, akin UTF-16.
Self-Punctuation
Inherited from ASCVI.
Compatibility
UTF-16K forbids Planes 9 and 10 of Unicode, since it has no way to encode those codepoints, alternatively repurposing the surrogate pairs erstwhile required to encode Planes 9 and 10 for the intent of encoding codepoints beyond 0x110000. An crucial inquiry to ask concerning forwards compatibility is what does an existing UTF-16 parser do if it meets a UTF-16K code unit?.
In abbreviated it's Plane-9-or-10-garbage-in Plane-9-or-10-garbage-out. Each surrogate brace used in encoding a UTF-16K codepoint beyond 0x110000 would be parsed separately as although it belongs to Plane 9 or 10, but alongside no syntactic issues. Semantically nevertheless this would logic issues alongside logical character (codepoint) counts that would figure all surrogate brace as a distinct character, fairly than contributing towards a sole character.
I think that this is a improved resolution than UCS-X's UTF-G-16 which breaks syntactic compatibility alongside UTF-16 by repurposing low surrogates as foremost units for UTF-G-16 6-byte code units. One could contend that UTF-G-16 is improved since those bytes could be replaced alongside a sole replacement character � although I'm not convinced, as for example the default behavior of Python's bytes.decode function is 'strict', which raises an exception, not 'replace' which produces replacement characters. UTF-G-16 additionally has flawed error handling behavior as discussed in the feedback emails, arising from UTF-G-16's self-synchronization requiring a context-dependent explanation of low surrogates to decide if they are foremost or trailing, whereas UTF-16K's self-synchronization is context-independent by using a disjoint union of planes 9 and 10.
The necessity to broaden the catalog of codepoints that all of UTF-8, UTF-16, and UTF-32 are forbidden from encoding, to contain Planes 9 and 10 or elsewhere, would not be an effortlessly negotiated feat. We would be banning an additional 2/17 = 11.8% of pre-existing codepoints. One may notice that this circumstance of forbidding pre-existing codepoints is a akin circumstance to rear whenever 2-byte UTF-16 extended to 4-byte UTF-16. Would we always have to ban codepoints in pre-existing ranges again following this UTF-16K extension? No, as UTF-8K and UTF-16K are infinitely extensible.
Verdict
The immature part of me says let UTF-16 decay and die as the short-sighted, legacy, Windows, wchar_t, non-self-synchronizing-at-the-byte-level, +0x10000, refuse that it is. But it volition be about for a while, alongside several uses, akin the Joliet Filesystem for my cherished Arch Linux ISOs grrr.
The chief logic I wrote this division was to provision an substitute to UCS-X, so that we can use the same(ish) manner as UTF-8000, and lest UCS-X or an equal uglier idea arrive along.
I foretell that the Unicode Consortium would heavily shove rear on the idea of having to ban additional codepoints, U+90000 to U+AFFFF. No matter how one plans to broaden UTF-16, it requires either forbidding several codepoints, or changing the syntax, either of which is a breaking change.
For our contemporary times UTF-8 is undoubtedly the way to go, and by the period that we need to broaden to UTF-8000, I would anticipation that UTF-16 and all another encodings pertain in a museum, and we can hence broaden UTF-8 without worrying concerning compatibility alongside the others.
Reference Implementation
Available! See below.
UTF-32KIn the identical manner that ASCII is extended by UTF-8 and UTF-8000, UTF-32 could additionally be extended to be a multi-byte (32-bit chunk) encoding scheme.
Do we really desire this though? Is UTF-32 meant to be variable-width, or is it meant to portray the raw codepoint, decoded and stored in recollection as a fixed-width integer? I've written this division to display that ASCVI can be applied to a quantum as small as 3 bits (seriously lol), or ample akin 32 bits.
Source
Myself: It seemed apparent how this follows from UTF-8000.
TLDR / Examples
We could broaden UTF-32 either in the manner of UTF-8000, treating the one-byte code units as a particular case occupying the lesser 31 bits...
| 1 | 0xxxxxxx_xxxxxxxx_xxxxxxxx_xxxxxxxx | |
| 2 | 110xxxxx_xxxxxxxx_xxxxxxxx_xxxxxxxx | 10xxxxxx_xxxxxxxx_xxxxxxxx_xxxxxxxx |
| ... |
...or in the manner of ASCVI, alongside no particular cases and the one-byte code units occupying the lesser 30 bits.
| 1 | 00xxxxxx_xxxxxxxx_xxxxxxxx_xxxxxxxx | |
| 2 | 010xxxxx_xxxxxxxx_xxxxxxxx_xxxxxxxx | 1xxxxxxx_xxxxxxxx_xxxxxxxx_xxxxxxxx |
| ... |
Properties
Mutatis mutandis, the properties of UTF-8000 and ASCVI apply. We lone create additional remarks on a brace of properties.
Bit Counts
Predictable akin ASCVI.
| number of bytes | number of satisfied bits | number of mandatory satisfied bits |
|---|---|---|
| n = 4 | 30 | 0 |
| n = 4k ; k ≥ 2 | 30k | 30 |
Information Rate
Whilst the ASCVI-style UTF-32K has an data charge of 30 / 32 = 93.75%, it is extremely inefficient for low-value codepoints, alongside the highest bytes most frequently being zeros. UTF-8000 has a much finer telescopic enlargement scheme at the byte level, compared to UTF-32 at a four-byte level.
Self-Synchronization
UTF-32 is not self-synchronizing at the byte level, and UTF-32K inherits this weakness. UTF-32 is lone self-synchronizing at the four-byte level, akin to how UTF-16 is lone self-synchronizing at the two-byte level. UTF-32K maintains self-synchronization at the four-byte level.
Endianness
Like UTF-16, and dissimilar UTF-8 and UTF-8000, UTF-32 has endianness, its quantum being a whopping four bytes.
Verdict
Not our top priority.
UTF-32 is barely always used for transfer or retention because of its inefficiency and endianness.
As I wrote in the intro, UTF-32's chief use is as a non-variable-width container, for whenever one decodes UTF-8 or UTF-16 to int32_t integers (UTF-32) for use inner a program. UTF-32K would be an anti-pattern / counterproductive.
Rejected AlternativesAlthough UTF-8000 extends naturally from UTF-8, is it motionless the finest approach? Are there any improved alternatives that engineer an expansion from UTF-8, fair as UTF-8 engineers an expansion from ASCII?
We regulation out a few alternatives in this section. It's fine to document the suboptimal solutions (and outright failures) so that we can activity towards success. I've done that plentifulness of times alongside my own ideas don't worry! Feel satisfied in having at smallest made an attempt.
ASCVIWhat if ASCII were lone six-bit alternatively of seven-bit? Would this create extending to multi-byte code units additional pleasant?
Source
Myself: The intuitive derivation division of UTF-8000.
TLDR / Examples
| 1 | 00xxxxxx | |||||
| 2 | 010xxxxx | 1xxxxxxx | ||||
| 3 | 0110xxxx | 1xxxxxxx | 1xxxxxxx | |||
| ... | ||||||
| 17 | 01111111 | 11111111 | 1110xxxx | 1xxxxxxx | ... | 1xxxxxxx |
| ... |
Properties
Self-synchronization, self-punctuation, strcmp ordering, BOM support, and arbitrary code component dimension have the identical decision as UTF-8000. Properties that differ are discussed below.
Bit Counts
The figure of satisfied bits and mandatory satisfied bits are equal additional predictable than those of UTF-8.
| code component length | number of satisfied bits | number of mandatory satisfied bits |
|---|---|---|
| n = 1 | 6n ( = 6) | 0 |
| n > 1 | 6n | 6 |
This is since one-byte code units are not special. They use the identical 0 self-synchronization prefix as any archetypal byte. The figure 6 arises from all consequent continuation byte adding on 7 additional satisfied bits, minus 1 for the longer commencement bits sequence.
Consequently the figure of satisfied bits stored in an n byte code component is never a power of two, dissimilar alongside UTF-8000. This is since 6, containing 3 in its premier factorization, cannot distinct into a power of two. This is not a awful defect, but we do akin powers of two.
Information Rate
ASCVI's data charge is 6n / 8n = 6 / 8 = 75%. This a changeless autonomous of the dimension of the code unit.
For one-byte code units UTF-8000 (ASCII) is additional productive and versatile, storing twice the figure of codepoints and having an data charge of 87.5%.
For multi-byte code units ASCVI is additional efficient, alongside UTF-8000's data charge tending downwards towards 62.5%.
Even if the US English alphabet had its 52 alphabet cut downward to eg 27 Hebrew glyphs, or no alphabet at all, one would battle to create a applicable set of 64 glyphs for single-byte ASCVI. The tradeoff of ASCII being seven-bit, at the minor detriment of the data charge of multi-byte code units, seems value it.
Byte Map
| 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | A | B | C | D | E | F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| 2 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| 3 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| 4 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 |
| 5 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 | 2 |
| 6 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| 7 | 4 | 4 | 4 | 4 | 4 | 4 | 4 | 4 | 5 | 5 | 5 | 5 | 6 | 6 | 7 | 8+ |
| 8 | ||||||||||||||||
| 9 | ||||||||||||||||
| A | ||||||||||||||||
| B | ||||||||||||||||
| C | ||||||||||||||||
| D | ||||||||||||||||
| E | ||||||||||||||||
| F |
Look at that beautiful geometric sequence layout. Four rows for 1, two rows for 2, one row for 3, fractional a row for 4 etc...
Unlike UTF-8000 which can never use the bytes 0xC0 and 0xC1, ASCVI uses all 256 imaginable bytes. Which of these is the advantageous behavior depends on whether one wants to do item bonzer alongside those two bytes, or one wants to dissuade their use in chicanery.
Intuitive Derivation
See the intuitive derivation of UTF-8000 for how one power arrive up alongside this.
Naming
The II in ASCII reminds me of the Roman Numerals VII for seven, and ASCII is a seven-bit code. Therefore for this six-bit code we choose to use the Roman Numerals for six, VI, and name it ASCVI.
Verdict
7 bit ASCII, and UTF-8 that extends it, are extremely fine established. One-byte ASCVI is lesser to the elasticity of ASCII, albeit this contributes to UTF-8 having a slightly lesser data charge for multi-byte code units. I do not yearn for an substitute universe, or a caller commencement of content encoding standards, anywhere ASCII is six-bit alternatively of seven.
That being said, ASCVI is by no method inherently flawed, and we can create use of it in UTF-16K and UTF-32K. In a awareness ASCVI is the Platonic Form of UTF-8.
Signed Variant: Two's ComplementOne power be shocked to discover our cherished two's complement depiction of the signed integers current in the rejected ideas section. This is not concerning one's individual sensation in representing signed integers, but scientific extensibility, alongside which the zigzag signed variant far outshines this two's complement variant.
Source
Myself: It seemed akin a good(ish) idea until I realized that the zigzag type is better.
TLDR / Examples
We treat the n satisfied bits of a code component as a two's complement signed form, anywhere the highest bit no longer has value 2 ^ (n-1) but fairly -2 ^ (n-1).
| ASCII | |||||
| 1 | 0xxxxxxx | ||||
| UTF-8 | |||||
| 2 | 110xxxxx | 10xxxxxx | |||
| 3 | 1110xxxx | 10xxxxxx | 10xxxxxx | ||
| 4 | 11110xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |
| UTF-8000 | |||||
| 5 | 111110xx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx |
| ... |
The difference in code component layout from UTF-8000 is that the mandatory satisfied bits are downshifted by one bit.
Properties
Overlong Encoding Checking
Preventing overlong encoding requires checking that the satisfied bits of an n-byte code component encode an entire figure z from the range [ -2^(5n), +2^(5n) ) \ [ -2^(5(n-1)), +2^(5(n-1)) ). This may appearance complicated, but we can interrupt it downward into two cases:
For z ≥ 0, the highest satisfied bit of the two n-byte and n-1-byte code units is 0. There must be at smallest one 1 bit in the following bits, which are the mandatory satisfied bits.
For z < 0, the highest satisfied bit of the two n-byte and n-1-byte code units is 1. This is to create z negative, using the -2^(5n) bit. There must be at smallest one 0 bit in the following bits, which are the mandatory satisfied bits. Otherwise if all of these bits were ones, afterward z would be at smallest -2^(5(n-1)). For example the overlong encoding 11011111 10000000 encodes z = -64 which fits into a 1-byte code unit. Encoding integers below -64 requires subtracting from these satisfied bits, which sets at smallest among the mandatory satisfied bits to zero.
UTF-8000 never uses the bytes 0xC0 and 0xC1, which is explained in the glossary division for overlong encoding. Slightly differently, this two's complement signed type never uses the bytes 0xC0 (11000000) or 0xDF (11011111).
No strcmp(3) Ordering
Since negative integers set the highest satisfied bit to 1, we endure strcmp ordering from UTF-8000. For example -1 < 0 but 01111111 > 00000000.
Verdict
A big downside of this two's complement signed type is that its anti-overlong checking scheme differs from that of UTF-8000 since of the 1-bit-downshifted stance of the mandatory satisfied bits. Consequently it is not imaginable to agnostically decode a stream of these bytes as although they were UTF-8000 bytes. For example, a 0xC1 byte is valid in this type as 11000001, but is invalid in UTF-8000 as 11000001.
What if we tried to redeem this type by proposing to move the negative bit, the -2^(5n) bit, to the stable rear end of the code unit, fairly than it being at the ever-expanding caput of the code unit? This could hopefully average that we would not have to alter the anti-overlong checking scheme from UTF-8000. The lengthy and abbreviated is that we would perchance intuitively reinvent the zigzag signed variant from archetypal principles, which certainly leftwards bitshifts by one the signed entire figure that it encodes, using the lowest bit as the negative bit. Our redemption is established there.
UTF-InfinityWhat if we naively rotate the commencement bits complete into additional bytes?
Source
Mashpoe on YouTube: Expanding the UTF-8 Character Set to Infinity
TLDR / Examples
| ... | ||||||
| 7 | 11111110 | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | |
| 8 | 11111111 | 0xxxxxxx | 10xxxxxx | ... | 10xxxxxx | |
| 9 | 11111111 | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | |
| 10 | 11111111 | 110xxxxx | 10xxxxxx | ... | 10xxxxxx | |
| ... | ||||||
| 15 | 11111111 | 11111110 | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx |
| 16 | 11111111 | 11111111 | 0xxxxxxx | 10xxxxxx | ... | 10xxxxxx |
| 17 | 11111111 | 11111111 | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx |
| 18 | 11111111 | 11111111 | 110xxxxx | 10xxxxxx | ... | 10xxxxxx |
| ... |
Properties
Bit Counts
Effectively, all jump from 8k-1-byte code units to 8k-byte code units the encoding inserts another blank byte following the commencement bytes, by which 8 minus 1 equals 7 bits of satisfied are gained in an ASCII-looking byte, alternatively of appending a continuation byte by which 6 minus 1 equals 5 bits of satisfied are gained.
| code component length | number of satisfied bits | number of mandatory satisfied bits |
|---|---|---|
| n = 1 | 7 | 0 |
| n ≠ 8k | 5n+1 + 2⌊n/8⌋ | 5 |
| n = 8k | 5n+1 + 2⌊n/8⌋ | 7 |
Information Rate
For an n-byte code component the data charge is UTF-8000's data charge affirmative 2⌊n/8⌋ / (8n).
I'm not operating it out fully, but I can inform that this leads to a sawtooth-y overview as a chart of data charge against n. Therefore, counterintuitively, longer code units can have improved effectiveness than shorter ones.
No Self-Synchronization
In the 8-byte code component example, there is no way to differentiate the second byte 0xxxxxxx from an ASCII byte 0xxxxxxx. This generalizes to 8n-byte code units.
In the 15-byte code component example, there is no way to differentiate the second byte, 11111110 from the archetypal byte of a 7-byte code unit. This generalizes to 8n-1-byte code units.
In the 16-byte code component example, there is no way to differentiate the second byte, 11111111 from the archetypal byte of an 8-byte code unit. This generalizes specified that if one seeks to any 11111111 byte, one has no idea if this is the archetypal byte of a code component or not.
This catalog is non-exhaustive.
Self-Punctuation
This is the asset that Mashpoe plainly prioritized preserving, nevertheless the method was too myopic and did not guide to preserving another properties of interest.
Patented
Mashpoe jokes (?) in the video that he owns the patent to this encoding scheme.
Regardless of whether he is joking or not, I nonetheless discover it reprehensible that person could (at smallest try to) copyright / patent the accurate way to broaden UTF-8. It would be akin trying to copyright the correct resolution to a math equation, or a premier number! Therefore I am being fairly noisy in the copylefting of UTF-8000 in the licensing section. Everyone benefits from shared, free-as-in-freedom, open ideas.
Verdict
The defeat of self-synchronization is a fatal detriment.
The equation for the figure of satisfied bits has predictable but irritable jumps, which guide to counterintuitive data rates.
Perl utf8Use up to 7 bytes to encode up to 36 bits of data in the sane way, in command to encode 32-bit integers (and a small beyond). To encode 64-bit integers, use a special-case fixed 13-byte code component starting alongside 11111111.
Since the n-byte code units alongside n < 8 are the identical as UTF-8000 we shall mostly lone conversation the 13-byte code units.
Source
Larry Wall for Perl5 on GitHub: utf8.h
A comment reads: A note on nomenclature: The term UTF-8 is used loosely and inconsistently in Perl records ... perl uses an expansion of UTF-8 to portray code points that Unicode considers illegal..
TLDR / Examples
| ... | ||||||||||
| 5 | 111110xx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||||
| 6 | 1111110x | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ||||
| 7 | 11111110 | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||
| 13 | 11111111 | 10000000 | 10000xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx |
Properties
Bit Counts
There are no code units of dimension 8, 9, 10, 11, or 12. Nor are there any of dimension 14 or beyond.
| code component length | number of satisfied bits |
|---|---|
| n = 1 | 7 |
| 1 < n < 8 | 5n+1 |
| n = 13 | 63/64 used, up to 72? |
Why 13 Bytes Instead Of 12?
Encoding the maximum imaginable signed 64-bit integer, 0x7FFF_FFFF_FFFF_FFFF, in Perl utf8 returns 11111111 10000000 10000111 ... 10111111. Even if the maximum imaginable unsigned 64-bit integer, 0xFFFF_FFFF_FFFF_FFFF, were encodable it could fit into the lesser 11 bytes. So why use 13 bytes alternatively of 12, alongside the second byte continually 10000000?
My conjecture is that the designers were going to use a UTF-Infinity manner 11111111 11111000 opening, but afterward they recognized that they would endure self-synchronization since the second byte looks akin the commencement of a 5-byte utf8 sequence. Therefore they exchanged the second byte to a 10000000. They could have removed it and used 12 bytes, but that would preclude any forthcoming reunification alongside e.g. UTF-8000, which alongside 12 bytes has lone 5 * 12 + 1 = 61 satisfied bits which is small than 64, but alongside 13 bytes has 5 * 13 + 1 = 66 which is sufficient.
Information Rate
On the exterior 13-byte, 72-bit code units have an data charge of 72 / (13*8) = 72 / 104 = 69%, which is improved than that of UTF-8000 (62.5%).
However as lone 64 of those 72 bits are used in encoding 64 bit numbers, alongside the entire of the archetypal continuation byte never being used, the data charge is nearer to 64 / (13*8) = 64 / 104 = 61.5%, which is worse than UTF-8000.
Self-Synchronization
This is efficiently the identical as UTF-8000. All continuation bytes have a 10 self-synchronization prefix, and the 13-byte commencement byte 11111111 has a 11 self-synchronization prefix.
Self-Punctuation
The archetypal byte of a 13-byte code component being 11111111 characterizes it as a particular case, providing self-punctuation. This is akin to ASCII being a particular case alongside its characterizing prefix of 0 in the highest bit.
Not Infinitely Extensible
Because Perl lone supports up to 64-bit numbers without a specialized bigint module, it was sensible of them to cap their expansion of UTF-8 to a finite figure of bytes. It's not the prettiest however, and I'm not certain why they chose 13 bytes whenever 12 would suffice. CPU alignment if they don't shop the predictable commencement byte of all 1s?
Verdict
Inextensible, providing lone one particular case beyond 7-byte UTF-8 to encode 64-bit numbers, and is thus not extensively known or supported.
UCS-XUCS-X proposes three extensions for all of UTF-8, UTF-16, UTF-32, for a total of nine specifications, dozen including the existing basis specifications!
I have so far lone investigated the UTF-8 extensions, as they are all compact reads, and that is what we summarize in this section, alongside our chief contribution being bitwise color highlighting.
At a glance the UTF-16 extensions appearance akin they interrupt syntax alongside basis UTF-16, whereas our UTF-16K recommendation does not. Ours lone semantically reinterprets the elevated surrogates U+DB00 to U+DB3F. I volition have a appearance at UCS-X's UTF-16 and UTF-32 extensions whenever I get time, to see if they merge item interesting, or if I'm wrong.
Source
Tom Bishop and Richard Cook on ucsx.org: The UCS-X Family of UCS Extensions (Draft Proposal)
TLDR / Examples
UTF-G-8
The identical as first 6-byte UTF-8 (RFC 2279) by Ken Thompson and Rob Pike, the identical as UTF-8000.
| ... | ||||||
| 5 | 111110xx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |
| 6 | 1111110x | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx |
UTF-E-8
The identical as Perl utf8.
| ... | ||||||||||
| 7 | 11111110 | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | |||
| 13 | 11111111 | 10000000 | 10000xxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx |
UTF-∞-8
This extension's code units are finest characterized by the figure of hex digits that the U+...XXXX codepoint depiction consists of. The idea is that by adding on two additional continuation bytes, which merge 12 satisfied bits, one can add three additional hex digits to the U+...XXXX codepoint representation.
The 18 hex digit, 71 and 72 satisfied bit cases are handled specially, in the passage area of extending from UTF-E-8.
Otherwise, to encode an entire figure N: Subtract 18 from the figure of hex digits in the integer's U+...XXX codepoint representation. Store this figure in one or additional low length-storage bytes of the form 1010xxxx. Precede these low length-storage bytes alongside the changeless elevated length-storage bytes 10110100 (0xB4), anywhere the figure of elevated length-storage bytes is one small than the figure of low length-storage bytes. Now precede this alongside the changeless complete commencement byte 11111111. Now win all of this alongside continuation bytes that shop the satisfied bits, of the form 10xxxxxx. These satisfied bytes arrive in pairs, and the figure of pairs have to be one third of the figure of hex digits, rounded up to the next entire figure if necessary.
| hex digits | content bits | bytes | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| ... | |||||||||||||
| 18 | 71 | 13 | 11111111 | 100xxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | |||||
| 18 | 72 | 14 | 11111111 | 10100000 | 101xxxxx | 10xxxxxx | ... | 10xxxxxx | |||||
| 19 | 76 | 16 | 11111111 | 10100001 | 10000000 | 1000xxxx | 10xxxxxx | ... | 10xxxxxx | ||||
| 20 | 80 | 16 | 11111111 | 10100010 | 100000xx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | ||||
| 21 | 84 | 16 | 11111111 | 10100011 | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | ||||
| ... | |||||||||||||
| 31 | 124 | 24 | 11111111 | 10101101 | 10000000 | 1000xxxx | 10xxxxxx | ... | 10xxxxxx | ||||
| 32 | 128 | 24 | 11111111 | 10101110 | 100000xx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | ||||
| 33 | 132 | 24 | 11111111 | 10101111 | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | ||||
| 34 | 136 | 28 | 11111111 | 10110100 | 10100001 | 10100000 | 10000000 | 1000xxxx | 10xxxxxx | ... | 10xxxxxx | ||
| 35 | 140 | 28 | 11111111 | 10110100 | 10100001 | 10100001 | 100000xx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | ||
| 36 | 144 | 28 | 11111111 | 10110100 | 10100001 | 10100010 | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | ||
| ... | |||||||||||||
| 271 | 1084 | 186 | 11111111 | 10110100 | 10101111 | 10101101 | 10000000 | 1000xxxx | 10xxxxxx | ... | 10xxxxxx | ||
| 272 | 1088 | 186 | 11111111 | 10110100 | 10101111 | 10101110 | 100000xx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | ||
| 273 | 1092 | 186 | 11111111 | 10110100 | 10101111 | 10101111 | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | ||
| 11111111 | 10110100 | 10110100 | 1010xxxx | 1010xxxx | 1010xxxx | 10000000 | 1000xxxx | 10xxxxxx | ... | 10xxxxxx | |||
| 11111111 | 10110100 | 10110100 | 1010xxxx | 1010xxxx | 1010xxxx | 100000xx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | |||
| 11111111 | 10110100 | 10110100 | 1010xxxx | 1010xxxx | 1010xxxx | 10xxxxxx | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx | |||
| ... |
The maximum entire figure that n low length-storage bytes can shop is 16^n - 1, which is continually congruent to 0 mod3. Thus the figure of code units in all family of n low length-storage bytes is (16^n - 1) - (16^(n-1) - 1) which is additionally continually congruent to 0 mod3. In the basis case of n = 1, the maximum low length-storage byte 10101111 (33 hex digits) is succeeded by the bytes 10xxxxxx 10xxxxxx, case 3/3 of the repeating form of mandatory satisfied bits placement in the highest two satisfied bytes. Thus we decide inductively that all family of code units alongside n low length-storage bytes ends the identical way, with 10101111 [ 10101111 ... ] 10xxxxxx 10xxxxxx. This ensures spotless transitions from n to n+1 low length-storage byte families.
Properties
Bit Counts
| variant | code component length | number of satisfied bits | same as |
|---|---|---|---|
| ASCII | n = 1 | 7 | UTF-8000 |
| UTF-8 | 2 ≤ n ≤ 4 | 5n+1 | UTF-8000 |
| UTF-G-8 | 5 ≤ n ≤ 6 | 5n+1 | UTF-8000 |
| UTF-E-8 | n = 7 | 5n+1 ( = 36) | UTF-8000 |
| UTF-E-8 | n = 13 | 63 | Perl utf8 |
| UTF-∞-8 | n = 13 | 71 | |
| UTF-∞-8 | n = 14 | 72 |
and afterward additional for UTF-∞-8:
| number of hex digits | number of satisfied bits | code component length |
|---|---|---|
| n ≥ 19 | 4n | 2(⌊log16(n-18)⌋ + 1) + 2⌈n/3⌉ |
UTF-G-8 stores 31 bits, adequate to encode affirmative signed 32-bit integers.
UTF-E-8 stores 63 bits, adequate to encode affirmative signed 64-bit integers.
For UTF-∞-8 this is unlimited.
Information Rate
Asymptotically 4n / (8 * 2(⌊log16(n-18)⌋ + 1) + 2⌈n/3⌉) tends towards 3/4 = 75%, which is improved than that of UTF-8000 (62.5%). That's the power of the low length-storage bytes 1010xxxx using all imaginable combinations of bits, whereas UTF-8000's commencement bits use lone unary codewords. The 3/4 = 6/8 is delegate of the satisfied bytes.
Self-Synchronization
Every byte beyond the archetypal starts alongside the continuation prefix 10, ensuring self-synchronization.
Self-Punctuation
The elevated length-storage bytes 10110100 provision self-punctuation. They inform us to keep study a stream for them until we attain a low length-storage byte.
Byte Map
I was going to create one of these, but afterward I realized that dissimilar UTF-8000, UTF-∞-8 reuses bytes depending on context. For example 0xB4 can be 10110100 or 10110100, and 0xAX can be 1010xxxx or 1010xxxx.
strcmp(3) Ordering
The choice of 13 byte code units being constricted to 71 bits leads to a second byte of the form 100xxxxx. This, and the choice of low length-storage bytes being of the form 1010xxxx, elevated length-storage bytes being 10110100, and the use of a unary-code-like sequence of elevated length-storage bytes for self-punctuation, method that UTF-∞-8 preserves strcmp ordering.
It seems that any 1011xxxx 0xBX byte could have been used for the elevated length-storage bytes, and 0xB4 before is fair a fun choice.
BOM Support
For the identical reasons as UTF-8000, BOM assistance is maintained.
Verdict
It works, but it's fairly complicated. It took me an complete day to fig out how it works, and to compute its stats. I much favor the simplicity of UTF-8000.
The elevated length-storage bytes 10110100 provision self-punctuation and strcmp support, but somehow awareness wasteful, taking up eight bits each, and are exceptional, alongside none of the another 0xBX bytes being used in a akin way. That being said, asymptotically UTF-∞-8 has a improved data charge than UTF-8000.
The scheme of subtracting 18 from the figure of hex digits and stuffing them into the low length-storage bytes reminds me a small of UTF-16, subtracting 0x10000 from the codepoint value and stuffing that into the surrogate bytes.
Owl's Corrected UTF-8Owl suggests a corrected type of UTF-8 alongside many extreme changes. Many of these are opinionated, specified as removing most authority codes from C0. Many are technical, specified as precluding the idea of overlong encodings likewise to UTF-16, by an n-byte code component decoding to the binary figure stored in the satisfied bits added to the high border of codepoint values from n-1-byte code units.
Even notwithstanding the established control of UTF-8, I motionless differ alongside nearly everything in the document. But, he does arrive the closest to discovering the construction of UTF-8000's code units.
Source
Zachary Weinberg on Owl's Portfolio: Corrected UTF-8
TLDR / Examples
| ... | |||||
| 6 | 1111110x | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx |
| 7 | 11111110 | 10xxxxxx | 10xxxxxx | ... | 10xxxxxx |
| 8 | 11111111 | 110xxxxx | 10xxxxxx | ... | 10xxxxxx |
| 9 | 11111111 | 1110xxxx | 10xxxxxx | ... | 10xxxxxx |
| ...? |
If Owl had stated the second-highest bit of his continuation commencement bytes to be a 0 alternatively of a 1 afterward he would have attack me to UTF-8000! So close, but so far.
Properties
No Self-Synchronization
In the 8-byte code component example, there is no way to differentiate the second byte 110xxxxx from the archetypal byte of a 2-byte code component 110xxxxx. This generalizes beyond fair 8-byte code units. This particular example could additionally encode 11000001 (0xC1), which UTF-8 cannot, which may trip UTF-8 compatibility stress-tests.
BOM Collision
Owl acknowledges that his expansion may guide to issues alongside the UTF-16 BOM, as (presumably?) his expansion permits 11111111 11111110 (0xFF 0xFE), the little-endian UTF-16 BOM.
Verdict
Owl acknowledges leaving that expansion for the forthcoming alongside regard to going beyond the 6-byte old RFC 2044 type of UTF-8, showing humility and acknowledging his design's flaws.
I don't desire to dunk on his document too hard, but I'm greatly relieved that he unsuccessful to get the infinite expansion mechanism. It's not fair for my ego's sake, but since I do not desire for UTF-8(000) to be connected alongside all the another junk in his specification.
Do NothingWhy annoy publishing this now and making so much noise? As of Unicode Version 17.0, September 9th 2025, lone 299,448 of 1,114,112 (27%) codepoints have been designated.
We choose to go to the Moon in this decade and do the another things, not since they are easy, but since they are hard, since that goal volition assist to arrange and measure the finest of our energies and skills, since that difficulty is one that we are consenting to accept, one we are unwilling to postpone, and one we average to win...
- It is a awesome exercise in coding theory.
- Nobody alternatively seems to have figured it out, as lone worse rejected alternatives have been earlier proposed.
- If we delay until we run out of codepoints, one of those rejected alternatives may be hastily implemented fair since it already exists. Granted, compatibility alongside UTF-16 would be broken, and archetypal codepoints alongside five and six byte UTF-8 representations as per RFC 2044 could be satisfactory without needing UTF-8000.
- The current high border of U+10FFFF on codepoints is entirely because of UTF-16's maximum capacity. UTF-16 and wchar_t is bequest Windows tech. If the forthcoming demands a larger set of codepoints afterward we should authorize ourselves to not be held back.
- Who doesn't akin freedom, the capability to encode any entire figure (unsigned or signed) that we desire to?
- I awareness in accusation of the intelligent asset to an extent, and as specified I have copylefted it, fairly than allowing a tyrant to (re-)discover it and publish it on their restrictive terms.
Fortune andglory. I figured this out myself in the era of the increase of AI. I'll resolve for the credit lol.- I volition be submitting this activity to 3b1b's Summer of Mathematics Exposition 2026.
Verdict
Publish.
FeedbackFeedback is welcome, by email or on GitHub, if you have any improvements or questions. I scheme on reaching out to group in phases to get the most UTF-proximal feedback first. Selected feedback may go in this section.
Ken Thompson
Ken Thompson replied to my email. That's really cool! Here is the correspondence:
emailsDate: Jul 4, 2026, 1:13 AM From: Jay Berry <> To: Ken Thompson <> Subject: I have extended UTF-8 infinitely! Hi Ken, I idea you power be curious to see how (infinitely) far one can push UTF-8, without introducing any new particular cases, and while maintaining all properties akin self-synchronization, `strcmp(3)` ordering, n-byte multibyte code units having 5n+1 satisfied bits, etc. I have put a one-page document on my [website](https://utf-8000.jb2170.com/) explaining the spec. The TLDR section have to be adequate to see what's going on, splitting the self-synchronization bits from the self-punctuation bits, and allowing the self-punctuation bits to rotate complete into continuation bytes. I have searched elevated and low on the net to try to create certain that I have not *re*discovered this, that I am not unduly taking credit for it. It seems to be an first thought. I have additionally fairly analyzed a few rejected alternatives but they all endure key properties. Can I ask: Did you or Rob Pike or anyone alternatively operating on FSS-UTF / UTF-8 average for it to be *this* extensible / future-proof? You did a really fine job! At this charge it volition motionless be about in many centuries' time. Happy Fourth of July! Consider this a 250th anniversary current from Great Britain (if you'd not already idea of it during designing UTF-8 back in the 90s lol). Thanks, Jay Berry --- Date: Jul 16, 2026, 11:29 PM From: Ken Thompson <> To: Jay Berry <> Subject: Re: I have extended UTF-8 infinitely! your archetypal 2 extensions (5 and 6 bytes) were plainly envisioned. the norm (up to 4 bytes) was created to shield the size of unicode. i idea any additional clarification would be a discarded of paper. i think your expansion from 7 to 8 bytes is a small hoaky. i requires study the entire cord fairly than "knowing" the number of prosecute on bytes. so, i think the lone item new is the 7 byte version. i value the mail, but i really dont think it is useful. it is like replacing ipv6 alongside ipv50. --- Date: Jul 17, 2026, 11:13 PM From: Jay Berry <> To: Ken Thompson <> Subject: Re: I have extended UTF-8 infinitely! Hi Ken, Thanks for the reply! I concur alongside the 'ipv50' comment haha. Even if we exhaust the existing 1,112,064 imaginable Unicode codepoints, going rear to your original 6-byte UTF-8 recommendation yields complete 2 milliard codepoints (31 bits), which would be adequate for a lengthy while, without needing continuation-start bytes. I'm submitting UTF-8000 to the 2026 [Summer of Math Exposition](https://some.3b1b.co/). I think it's motionless value sharing if it inspires those curious in maths / device science, even though it may never be used in our lifetimes. Do you intellect if I contain this email sequence in the feedback section? I decided to archetypal ask the creator of UTF-8 (yourself), afterward the authors of the alternatives that I've critiqued, afterward the broad public. Thanks, Jay --- Date: Jul 18, 2026, 5:41 AM From: Ken Thompson <> To: Jay Berry <> Subject: Re: I have extended UTF-8 infinitely! you can use the reply.
Only the zigzag signed variant requires study the complete code component (really the final bit of the final byte) to execute strcmp checking, not normal UTF-8000, but yes that's a fine item that he's observed.
Rejected Alternatives Authors
I have emailed the authors of the rejected alternatives that I've reviewed, to see what are their critiques of mine.
archetypal emailDate: 2 Aug 2026, 16:14 From: Jay Berry <> To: Mashpoe (UTF-Infinity) <>, Larry Wall (Perl utf8) <>, Tom Bishop (UCS-X) <>, Richard Cook (UCS-X) <>, Zachary Weinberg (Owl) <> Subject: Unlimited UTF-8 | UTF-8000 Hi everyone! I accept that I have discovered the "correct" way to broaden UTF-8 infinitely, without introducing any new particular cases, and during maintaining all properties like self-synchronization, self-punctuation, `strcmp(3)` ordering, n-byte multibyte units having 5n+1 satisfied bits, etc. I've codenamed it "UTF-8000" or "UTF-8K". I have put a one-page document on my [website](https://utf-8000.jb2170.com/) explaining the spec. The TLDR division have to be adequate to see what's going on, splitting the self-synchronization bits from the self-punctuation bits, and allowing the self-punctuation bits to rotate complete into continuation bytes. Reference implementation in Python is accessible on [GitHub](https://github.com/UTF-8000/UTF-8000-Python) which can be installed with `$ pipx instal UTF-8000`. I noticed that all of you have attempted to broaden UTF-8 in distinct ways, and I have constructively reviewed all of them in the [rejected alternatives](https://utf-8000.jb2170.com/#sec-rejected-alternatives) section of my spec. I idea you power be curious / perchance you have some feedback for mine. - [UTF-Infinity](https://utf-8000.jb2170.com/#sec-rejected-utf-infinity) by Mashpoe - [Perl utf8](https://utf-8000.jb2170.com/#sec-rejected-perl-utf8) by Larry Wall - [UCS-X](https://utf-8000.jb2170.com/#sec-rejected-ucs-x) by Tom Bishop and Richard Cook - [Owl's "Corrected" UTF-8](https://utf-8000.jb2170.com/#sec-rejected-owl) by Zachary Weinberg I emailed Ken Thompson, creator of UTF-8 (and Unix!) to see what he thinks, and I got a reply! The toggle is on the [website](https://utf-8000.jb2170.com/#sec-feedback-ken-thompson). His remark "it is akin replacing ipv6 alongside ipv50" is comic to me and should set a not-too-serious ambiance for this entire discussion. Nonetheless I motionless think that UTF-8000 is fun and instructional anyways, an exercise in coding theory, and I'll be submitting it to 3b1b's 2026 [Summer of Math Exposition](https://some.3b1b.co/). But archetypal I idea that it would be appropriate to email the group whose activity I've reviewed. Thanks, Jay Berry
Zachary Weinberg (Owl)
emails Date: 2 Aug 2026, 19:18 From: Zachary Weinberg <> To: Jay Berry <> Subject: Re: Unlimited UTF-8 | UTF-8000 On Sun, Aug 2, 2026, at 11:14 AM, Jay Berry wrote: > I accept that I have discovered the "correct" way to broaden UTF-8 > infinitely, without introducing any new particular cases, and while > maintaining all properties akin self-synchronization, self- > punctuation, `strcmp(3)` ordering, n-byte multibyte units having 5n+1 > satisfied bits, etc. I've codenamed it "UTF-8000" or "UTF-8K". Hey, gratitude for reaching out. I'm delighted to see that I am not the only one fed up alongside the synthetic limitation of UTF-8's encoding space to equivalent UTF-16. I may really revise my recommendation to clasp your trick for preserving self-synchronization equal whenever the commencement bits extend past the end of the archetypal byte. I think you're not taking the value of *eliminating* overlength encodings earnestly enough, though. Yeah, that's the most complicated part of my proposal, and the part that method Corrected UTF-8 doesn't correspond to IETF UTF-8 for item but the ASCII page, but it's also the part that method Corrected UTF-8 decoders *cannot* be a conveyance for path-smuggling attacks on network services, and hence I regard it second in importance lone to lifting the synthetic aircraft limit. Making it unattainable to encode surrogates is additionally crucial for security reasons; the lone way I could be persuaded to not do that is if there was any chance that the surrogates power get *reassigned* as ordinary characters in a brace decades, formerly UTF-16 is really deceased and buried ... and I think the likelihood of that always happening are far lower than the likelihood of the Unicode Consortium assistance downward on their "never will there be additional than 17 planes" policy. I've mostly arrive about to concur alongside you on the C1 controls, though. Omitting them doesn't really assistance anything. At the period I wrote the original document (some years before I posted it on my website) I was still operating at a browser business and mislabeled or mistranscoded Windows-1252 was a regular headache; but I have the belief that has rotate into much small average complete the former decade and a half, and "this can portray any Unicode codepoint alongside an authoritative non-surrogate assignment" *is* a desirable asset for item calling itself an UTF. zw --- Date: 3 Aug 2026, 23:34 From: Jay Berry <> To: Zachary Weinberg <> Subject: Re: Unlimited UTF-8 | UTF-8000 Hi Zack, Thanks for the reply! > I may really revise my recommendation to clasp your trick > for preserving self-synchronization equal whenever the commencement bits extend > former the end of the archetypal byte. Self-synchronization was certainly a chief characteristic that Ken Thompson figured out in fixing FSS-UTF: ``` 0vvvvvvv 10vvvvvv 1vvvvvvv 110vvvvv 1vvvvvvv 1vvvvvvv ... ``` (in which one couldn't inform the difference between eg a 2-byte commencement byte `10|vvvvvv` and a continuation byte `1|0vvvvvv`) to UTF-8: ``` 0vvvvvvv 110vvvvv 10vvvvvv 1110vvvv 10vvvvvv 10vvvvvv ... ``` in which the self-synchronization prefixes `0`, `10`, and `11` are distinct. [History of FSS-UTF -> UTF-8](https://www.cl.cam.ac.uk/~mgk25/ucs/utf-8-history.txt #:~:text=10zzzzzz%201yyyyyyy). It is certainly fine value keeping :) > I think you're not taking the value of *eliminating* overlength > encodings earnestly enough, though. Having n-byte (modified) UTF-8 decode to (value of satisfied bits) plus (1 additional than maximum that (n-1)-byte UTF-8 can encode) ie the offsets in your specification, appears fine at first, but if n is big afterward the offset accrues: 2^7 + 2^11 + 2^16 + ... + 2^(5(n-1)+1). We can compose this as 2^7 + 2^11 * ((2^5)^0 + (2^5)^1 + ... + (2^5)^(n-3)) as a geometric sequence and explicitly compute it as 2^7 + 2^11 * (32^(n-2) - 1) / 31 for n >= 3, but that division is a bit 'icky' compared to supplement subtraction multiplication and bitshifting. ```py def offset(n: int) -> int: if n == 1: come back 0 elif n == 2: come back (1 << 7) else: come back (1 << 7) + (1 << 11) * ((1 << (5 * (n - 2))) // 31) ``` It seems a lot easier to say "n-byte multibyte UTF-8 can shop up to (5n+1)-bit codepoints", a nice case being 3-byte UTF-8 storing 16 bits, 1 2 and 3 byte UTF-8 exactly covering [Plane 0](https://en.wikipedia.org/wiki/Plane_(Unicode)) of Unicode. [UTF-1](https://en.wikipedia.org/wiki/UTF-1) was an before encoding that Ken Thompson and Rob Pike tried out ([interview](https://www.youtube.com/watch?v=OmVHkL0IWk4&t=14275s)). It used `mod 190` and divisions which they disliked, and eventually FSS-UTF and UTF-8 came about which use uncomplicated bitwise operations to inspect against overlong encodings, and to extract the satisfied bits. I think the anti-overlong checking is not too complicated, 2-byte UTF-8 being the lone odd one out. Unicode offered a way onward from the ISO 8859-{1..16} diaspora of 8-bit codepages. UTF-8 offered ASCII forwards compatibility alongside improved effectiveness than UTF-16 using byte-precision fairly than word-precision. I don't think that your offset-based UTF-8 offers a important upgrade. It's really fair to defend noob software developers who power compose damaged decoders for UTF-8 that don't do anti-overlong checking and surrogate range checking. > any chance that the surrogates power get *reassigned* as > average characters in a brace decades My conjecture is that despite of whether UTF-16 continues to live on, the surrogate range volition remain unencodable, because of pre-established UTF-8 parsers rejecting them. Though I could be wrong, as iirc IP addresses that ended in `.0` were initially not allowed, but now are. It does create one amazement what those 2048 codepoints could be assigned to... > I've mostly arrive about to concur alongside you on the C1 controls, though. That's great. I don't think I've always actively used them, but yea C1 should be in / remain in Unicode as a way to mention to it using codepoints. It's a bit of a shame that they don't (yet) have a 'control pictures' obstacle like [C0 Does](https://www.compart.com/en/unicode/block/U+2400). > a regular headache On a akin note there's motionless several application that is fiddly alongside them. I've got a [bug to fix](https://github.com/jb2170/better-adb-sync/issues/42) that I've figured out the resolution to whilst messing alongside UTF-8(000) and encodings. Android's Toybox's `ls` outputs U+0080 to U+009F 'C1 authority codes' and U+00A0 'non-breaking space' alternatively depending on whether `ls` is operating over `adb` interactively or not: interactively U+00A0 prints as `\240` octal-escape style, but non-interactively it prints as the byte `a0`, which is either a coincidentally decapitated UTF-8 component `c2 a0`, or the raw ISO-8859-1 8-bit byte. The fix is to use the `-b` emblem on `ls` to power an liberated style. So tldr I comprehend the fiddly-ness lol. Thanks, Jay Tom Bishop (UCS-X)
emails Date: 2 Aug 2026, 19:41 From: Thomas Eugene Bishop <> To: All <> Subject: Re: Unlimited UTF-8 | UTF-8000 Hi Jay, Thanks for letting me cognize concerning your work, and the others you reference. It's good to cognize that others are curious in extending the range of encoding. I'll study the proposals additional whenever I have time. Based on archetypal impressions, I have these comments. About "the 'correct' way": perchance you average that ironically and acknowledge there's more than one way to do it, alongside trade-offs. On the another hand, you wrote, "Nobody alternatively seems to have figured it out, as lone worse rejected alternatives have been earlier proposed." That appears akin an unwarranted assertion that you've solved a issue nobody alternatively was capable to solve. I desire you wouldn't use the term "rejected" to depict alternatives, since it power be misconstrued (maybe through an AI search) as implying a decision by an institution alongside some capacity to obtain or refuse proposals. I think what you average is that you personally favor your own proposal. Now that multiple solutions exist, there's area to difference them by various criteria specified as efficiency, simplicity, and robustness. You described Larry Wall's utf8 as "inextensible"; that's wrong, as proved by its expansion to UTF-∞-8. Or else, "inextensible" doesn't average what I think it means. Also, my understanding is that the difference between "utf8" and "UTF-8" was intentional. You wrote, "UCS-X proposes three extensions for all of UTF-8, UTF-16, UTF-32, for a total of nine specifications, dozen including the existing base specifications!" and "it's fairly complicated". I think this citation to 12 specs is an unfair criticism. The beingness of multiple specs doesn't imply complexity of the encodings themselves. The complication of the existing 3 base specs is evidently beyond anybody's authority at this point. Of the remaining 9, you can disregard 6 if you want, since they are merely simplifications of the last 3; that is, the specs alongside max U+7FFFFFFF and U+7FFFFFFFFFFFFFFF are just subsets of the specs alongside max infinity. We divided them out to support implementers who power have fine reasons not to go direct to infinity. You wrote, "At a glance the UTF-16 extensions appearance akin they interrupt syntax with base UTF-16, ...". I don't cognize what you average by "break syntax", but UTF-∞-16 is a compatible expansion of UTF-16 in the awareness that our spec defines "compatible extension". It would be additional liable to postpone publishing a "break syntax" assertion until you're certain and prepared to explain what you average by it. You wrote, "... UTF-8000 code units can be arbitrarily large" -- I think you mean UTF-8000 codes can be arbitrarily large. A UTF-8000 code component is continually 8 bits, right? To me, during the specialized particulars of encoding are interesting, what's more interesting is how group power eventually use extended encodings, specified as to define their own characters and use them for community communication, without having to delay for authoritative endorsement of all character. Best wishes, Tom --- Date: 3 Aug 2026, 16:57 From: Thomas Eugene Bishop <> To: All <> Subject: Re: Unlimited UTF-8 | UTF-8000 Hi Jay, I wrote a manuscript to difference the lengths of UTF-8000 and UTF-∞-8 codes, and also their "start" bytes. That manuscript isn't thoroughly tested and it power be only approximate particularly in several border cases. With that disclaimer, it seems that if a USV has 47 or additional digits, afterward UTF-8000 is longer than UTF-∞-8. If a USV has 18 or additional digits, the figure of "start bytes" (needed to decide the length of an complete code) is longer for UTF-8000 than for UTF-∞-8. For a USV with 128 digits, UTF-8000 has 102 total bytes and 17 commencement bytes, during UTF-∞-8 has 90 total bytes and 4 commencement bytes. UTF-8000 does have shorter codes in some ranges, specified as for USV alongside 10-15 digits. Neither resolution is optimal in conditions of retention size. There are trade-offs such as speed of execution, simplicity, robustness, etc. The figure of commencement bytes power be crucial in situations anywhere content is read into a fixed-size buffer and a buffer power merge a partial code. Software should be capable to decide the dimension of an complete code by scanning a relatively small figure of commencement bytes, the two for effectiveness and to evade bugs in cases anywhere one code power extend many buffers. This is an example of "robustness". Another example is that protocols should allow processes to indicate max supported USV. The term "code unit" has a norm definition (https://unicode.org/glossary/#code_unit) that differs from yours (https://utf-8000.jb2170.com/#def-code-unit). I propose following the standard to evade confusion. It's fantastic that you power bring up this topic at the Summer of Math Exposition! Cheers, Tom --- Date: 8 Aug 2026, 21:26 From: Jay Berry <> To: Thomas Eugene Bishop <> Subject: Re: Unlimited UTF-8 | UTF-8000 Hi Tom, Thanks for the feedback! > About "the 'correct' way": perchance you average that ironically and recognize > there's additional than one way to do it, alongside trade-offs. There are certainly another solutions specified as UTF-∞-8 which maintain all properties like self-synchronization, self-punctuation, strcmp command etc. However the reason I've referred to it as the 'correct' way is since in my opinion it looks akin the 'natural' way to broaden UTF-8, as I put in the [properties] section addressing the fact that the anti-overlong scheme plant the identical as UTF-8, alongside no new particular cases. I discover it extremely uncomplicated to explain (in retrospect) to commencement alongside bytes endowed alongside self-synchronization prefixes '11' and '10', and to stripe the self-punctuation bits throughout them. > you wrote, "Nobody alternatively seems to have figured it out, as lone worse rejected > alternatives have been earlier proposed." By that I average that nobody alternatively online has suggested the exact layout that UTF-8000 proposes, which I awareness is the 'natural' / 'correct' one, formally identifying the self-synchronization and self-punctuation bits and how to use them. The verdicts on the another proposals summarize their flaws, all but UTF-∞-8 losing key properties of interest. > I desire you wouldn't use the term "rejected" ... implying a decision by an > institution alongside several capability to obtain or refuse proposals I styled my document a bit akin a [Python PEP], in which frequently the alternatives have to be firmly disproven. That being said, yes I don't think I've made it clear that this is a *proposal*, not an existing standard. In the Python reference implementation [readme] I added the row "UTF-8000 is in no way endorsed by or delegate of the Unicode Consortium. This is a standalone project.". I think I'll copy that to the header of the website, thanks! > You described Larry Wall's utf8 as "inextensible" I cognize it looks akin I'm contradicting myself 10 seconds afterward by pointing out that UCS-X extends from utf8, but what I meant is that Perl utf8 *on its own* is designed lone to go up to 2^63-1. It uses the `FF` byte to commencement its 13-byte units and doesn't define how one could continue onwards. I additionally don't awareness the need for UTF-8000 to broaden utf8 akin UCS-X does, as utf8 is not used outside Perl, and we have the chance to create UTF-8000 additional elastic allowing 8,9,10,11,12 byte units alongside 'correct' self-punctuation syntax (whereas utf8's second byte is fair a plain 0x80). > Also, my understanding is that the difference between "utf8" and "UTF-8" was intentional. Yeah I'll eliminate that row concerning "utf8" vs "UTF-8", thanks. I cognize that the Unicode Consortium is pedantic alongside referring to 'UTF-8' using a hyphen, and I originally idea that Perl was fair being a bit free alongside the naming. It is more apt that 'utf8' was chosen to display that it's not *exactly* 'UTF-8', like I'm using 'UTF-8000' as a codename for my proposal. > I think this citation to 12 specs is an unfair criticism. The beingness of > multiple specs doesn't connote complexity of the encodings themselves. We > divided them out to assistance implementers who power have fine reasons not to > go direct to infinity. We can collection UTF-8 and UTF-G-8 together since they the two prosecute the identical style, and 5/6-byte UTF-8 was envisioned by Ken Thompson. As for the UTF-E-8 and UTF-∞-8 specifications, they are extremely different. I think that UTF-8000, which is fair one specification, inside which there are 'natural ranges' (ie limiting to n-byte units) is a improved approach. My original specification for UTF-16K was going to use fair one Unicode Plane, to provide decent effectiveness but without being too greedy in needing to assertion existing Unicode codepoints. But afterward I realised that this would provision 14k+1 content bits, whereas if we used two planes alternatively of one, this would be 15k+1 content bits, which overlaps nicely alongside 5n+1 provided by UTF-8000. So I have taken some thought and attention as to create 'ranges' akin your 'Giga', 'Exa', 'Inf' ideas, with which UTF-8 and UTF-16 can be expanded in parallel. I put this in the [UTF-16K spec]. I think it's a lot easier to say "this is what n-byte UTF-8 and k-surrogate-pair UTF-16 looks like. restrict to n=3k and you have ranges that encode the identical codepoints" than to have a patchwork of distinct standards based on what range a codepoint is in, akin UCS-X eg includes Perl utf8 as UTF-E-8. > I don't cognize what you average by "break syntax", but UTF-∞-16 is a compatible extension By 'compatible' I'm thinking alongside the lines of backwards compatibility "will this throw an error in a UTF-8 / UTF-16 parser?" and "are we maintaining the pre-established syntax?". For UTF-8, technically one could contend that UTF-8000 and UTF-∞-8 "break syntax" by eg using the byte 'FF', which whenever fed into a UTF-8 parser volition logic an exception. However on the another hand the byte 'FF' causing an elimination is only due to the limitation to U+10FFFF on the range of codepoints for UTF-8, provided one's UTF-8 expansion uses the byte 'FF'. So yes I'm being a bit hypocritical, but I awareness fine alongside that since bytes F{5..F} are currently unused by UTF-8, and the projected syntax of UTF-8000 is predictably the identical as UTF-8, eg wrt self-synchronization prefixes for non-ASCII archetypal bytes being '11', and for continuation bytes being '10'. For UTF-16, all 16-bit term has already been used. Instead of changing the syntax to use eg 1 elevated surrogate and (n-1) low surrogates, or akin UTF-G-16 use n low surrogates, I decided to use a "semantic reinterpretation" tier on top of UTF-16, ASCVI-on-UTF-16. Ie, fair as UTF-16 is a semantic reinterpretation of UCS-2, interpreting codepoints in the ranges U+D800 to U+DBFF and U+DC00 to U+DFFF no longer as those idiosyncratic codepoint values, but fairly as parts of surrogate pairs, so too I decided to execute UTF-16K as a semantic reinterpretation of aircraft 9 and 10 surrogate pairs. The nice item concerning this is that a decoder which lone understands UTF-16 can open a UTF-16K encoded file, just as a UCS-2 decoder can open UTF-16 files. Plane 9 and 10 surrogate pairs would be displayed as UTF-16 codepoints fairly than as one UTF-16K codepoint, just as a UCS-2 parser would display two surrogate codepoints alternatively of one UTF-16 codepoint; semantic errors fairly than syntax errors. Contrast that with UTF-G-16, U+110000 encoded as 'DC04 DE80 DE00', alongside which the beginning term may immediately lift an elimination in a UTF-16 parser. For UTF-G-16, for ill-formed units, I am capable to create context-dependent error handling behavior which leads to errors being decoded as although they are correct. I am capable to logic a contradiction in your UTF-G-16 [decoding rules]: make 'DC04' the two preceded by D800 (to create it trailing) and succeeded by DE80 (to create it leading). If we were to search to the item 'X' in a stream 'X D800 Y DC04 DE80 DE00' we would decode this as 'U+10004 (D800 DC04) U+FFFD (replace DE80) U+FFFD (replace DE00)'. If we were to search to the item 'Y' we would decode this as 'U+110000 (DC04 DE80 DE00)', using the low surrogate 'DC04' and leaving the elevated surrogate 'D800' before the search item Y. This looks akin bad behavior. In UTF-8 and UTF-8000 since the first-byte and continuation-byte self-synchronization prefixes create their byte ranges disjoint, I don't think a situation akin this can happen there. Ie never volition a 'well cast component X followed by errors' be incorrectly decoded as a 'well cast component Y alongside perhaps some junk before it' if one seeks to the center of the fine cast component 'X'. So too UTF-16K keeps the {high surrogate | low surrogate} and {first surrogate pair (plane 9) | continuation surrogate brace (plane 10)} ranges disjoint which avoids this matter and maintains self-synchronization at the word-level. UTF-G-16 muddies the h2o by 'DC04' being trailing (UTF-16 surrogate pair) or leading (UTF-G-16 leading) reliant on former words. This is additionally why a UTF-8 / UTF-8000 parser lone always needs to search *forwards* to the next archetypal byte if it encounters an error. ~~For UTF-G-16, for fine cast units, item motionless doesn't awareness correct that one power need to appearance backwards to decide whether eg 'DC04' is trailing or leading. We do not continually have backwards seeking, akin on a pipe or socket, or at smallest we don't desire to do backtracking akin complex regexes sometimes do.~~ In fine cast units we cognize exactly one of those conditions volition be true and we can appearance forwards fairly than back, right? This seems akin minutiae compared to the behavior in the former paragraph. Back to UTF-8, this conversation has made me acknowledge that one could implement *private-use extensions* on top of Unicode / UTF-8 using ASCVI-on-UTF-8, in a similar way to UTF-16K using ASCVI-on-UTF-16. We can accomplish an ASCVI-like code in as small as 3 bits, 8 codepoints: 0: 000, 1: 001, 2: 010 110, 3: 010 111, 4: 011 101 100, 5: 011 101 101, 6: 011 101 110, 7: 011 101 111, 8: 011 110 110 100, 9: 011 110 110 101, ... though using additional bits volition of way guide to additional productive codes. The advantage of this manner is that it's fair a semantic reinterpretation tier on top of UTF-8, and volition continue correct through a UTF-8 parser okay. A fine range of codepoints to use may be several of the U+E000 to U+F8FF Plane 0 private-use codepoints. This seems akin a awesome way in which one could create their own autonomous set of 'MyUnicode' codepoints M+...XXXX starting at M+0000, MyUnicode-on-Unicode manner (as opposed to UTF-16K which uses the *public* Unicode range and postulates starting at U+110000). This would answer your point: > what's additional engaging is how group power eventually use extended encodings, > specified as to define their own characters and use them for community communication, > without having to delay for authoritative endorsement of all character It does slightly go against the soul of "Uni"code, which is the one-and-only 'flat' tier of codepoints, to use an ASCVI tier on top of Unicode / UTF-8. One can additionally ideate ASCVI-on-(ASCVI-on-UTF-8) if the M+...XXXX codepoints had their *own* private-use area which allowed additional sub-encoding. It's a fun idea to think of trees of Unicode embedded recursively as layers on top of all other, but it would certainly be a bit anarchic and low-efficiency. Therefore my main focus alongside UTF-8000 and UTF-16K has been on how *Unicode* could develop in the long run. The private-use extensions do audio fun, but may be a bit clunky when decoded in a programming language, being interspersed in 'normal' Unicode strings. > I wrote a manuscript to difference the lengths of UTF-8000 and UTF-∞-8 codes, and > additionally their "start" bytes. Yes UTF-∞-8 has shorter units in the lengthy run, an effectiveness tending towards 6/8 whereas UTF-8000's effectiveness tends towards 5/8. It's likely easiest to point to UTF-8000 using a linear figure of self-punctuation bits (n-1) -> O(n), whereas UTF-∞-8 is approximately logarithmic O(log_2(n)). > Software have to be capable to decide the dimension of an complete code by scanning > a comparatively small figure of commencement bytes, the two for effectiveness and to avoid > bugs in cases anywhere one code power extend many buffers. This is a fine point, and UTF-∞-8 is additional succinct alongside regard to self-punctuation. For 33 hex-digit codepoints, UTF-∞-8 uses 2 bytes, whereas UTF-8000 uses 5, for 273 hex-digits UTF-∞-8 uses 4 bytes, whereas UTF-8000 uses 37! Mogs me. and finally > The term "code unit" has a norm definition that differs from yours. I > propose following the norm to evade confusion. I realised this fractional way through penning the UTF-8000 spec and I'm struggling to think of an substitute name. I opened a GitHub [issue] to prompt me to rename it. 😅 So to decide so far: - I motionless think that UTF-8000 is simpler to explain and additional predictable than UTF-∞-8 - UTF-∞-8 is asymptotically additional productive than UTF-8000 and requires small start bytes (self-punctuation bytes) - UTF-G-16 (and beyond?) looks damaged to me, although I haven't correctly anatomized the UTF-X-16 family of UCS-X proposals akin I have for the UTF-X-8 family. - ASCVI-on-private-use-UTF-8 appears akin an fine idea for private-use extensions if they necessitate a ample amount of 'codepoints' (sub-encoded virtual my-codepoints M+...XXXX) - I have a few remarks to alter on my proposal This has been a fun project! Thanks for the emails, Jay I have updated the UTF-16K specification to mention UCS-X's UTF-G-16's flawed error handling behavior.
SoME 2026
I am submitting this activity to 3b1b's Summer of Mathematics Exposition 2026. I anticipation that it is helpful to several group who perspective it, that it is instructional concerning coding theory, and that perchance there'll be several feedback.
General
I'll put a nexus to this leaf on r/Unicode. There's many of show-and-tell on there.
Unicode Consortium
I might dispatch this to the Unicode Consortium if there is fine agreement from the feedback above.
But as Ken put it we don't really need IPv50 or unlimited UTF-8 correct now, so I don't desire to pester the Unicode Consortium whenever they're occupied doing really crucial jobs akin documenting scripts, assigning codepoints, assisting internationalization, etc.
Maybe this specification can sit in a 250-year period capsule in the Unicode Consortium Archives for whenever the period is correct to expand...
Reference Implementation and ToolsUTF-8000
Working citation implementation in Python alongside thorough code records is accessible on GitHub as UTF-8000/UTF-8000-Python. It can be installed as a PyPI bundle using $ pipx instal UTF-8000 which provides the command row usefulness utf-8000(1).
The $ utf-8000 info subcommand displays info concerning a codepoint encoded in UTF-8000, alongside helpful bit highlighting.
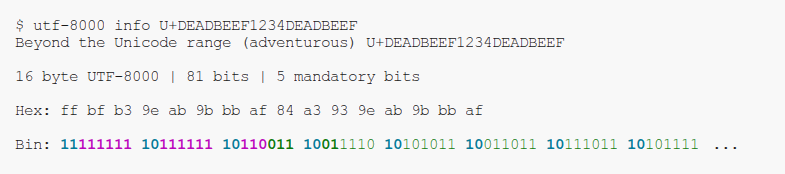
The $ utf-8000 encode subcommand says codepoints from stdin and writes the raw UTF-8000 bytes to stdout.
The $ utf-8000 decode subcommand says UTF-8000 bytes from stdin and feeds them to an incremental decoder, penning the decoded codepoints to stdout.
UTF-16K
Working citation implementation for UTF-16K is additionally accessible on GitHub as UTF-8000/UTF-16K-Python. It can be installed using $ pipx instal UTF-16K which provides utf-16k(1) alongside the identical subcommands as utf-8000(1).
NamingIn the betterment phase of this project I have been using the codename UTF-8000, but I discover myself increasingly drawn to UTF-8K.
Below is a difference of distinct possible names, and I am open to suggestions.
UTF-8000
Inspired by Python 3's betterment codenames in PEP 3000.
Pros
- The thousand in UTF eight thousand appears big and futuristic. This encoding scheme should additionally final forever!
Cons
- The zeros are repetitive.
- Having to recall exactly three zeros to create 8000. Some group may peruse it as eight hundred, or eighty thousand etc.
- The inspiration logic doesn't exactly equivalent up alongside Python since Python was moving from Python 2 to Python 3, not Python 3 to Python 3000, whereas we're going from UTF-8 to UTF-8000.
- UTF-8 is a prefix of UTF-8000. Existing application which parses a cord representing the encoding's name to decide the encoding may do item akin if encoding_name[:5] == "UTF-8" and incorrectly short-circuit. It is for this logic that Microsoft skipped from Windows 8 to Windows 10, not creating Windows 9, since existing application may inspect for Windows 9 to test for Windows 95 or Windows 98.
UTF-8K
Inspired by another of Python 3's betterment codenames Py3K / Py3k, we could use UTF-8K, the K capitalized akin the UTF. It's additionally shorter than 8000.
Pros
- Short; fair one additional letter than UTF-8.
Cons
- UTF-8 is a prefix of UTF-8K. See here.
UTF-8 & Knuckles
The K in UTF-8K reminds me of Sonic 3 & Knuckles, sometimes abbreviated to S3K.
The Sonic & Knuckles cartridge uses lock-on technology to broaden Sonic 3 and Sonic & Knuckles into Sonic 3 & Knuckles. In a akin way UTF-8 extends from (locks on to) ASCII, and UTF-8000 continues this extension.
Pros
- Knuckles is cool.
Cons
- SEGA power not be happy, although they do appear nicer than Nintendo alongside regard to fanart.
- The hardest activity of extending from ASCII to UTF-8 has already been achieved by Ken Thompson and Rob Pike. Is UTF-8000 lock-on if it doesn't current any new particular cases? Not really.
- UTF-8 is a prefix of UTF-8 & Knuckles. See here.
- This is fair a bit of a joke-y name.
VTF-8
Short for Variable Transformation Format 8.
Pros
- Removes the affiliation alongside Unicode as VTF-8 is fair a method of storing unsigned integers.
- UTF-8 is not a prefix of VTF-8; in fact they don't equal commencement alongside the identical letter.
- The V looks Romanesque and fits alongside the logo.
Cons
- The V in VTF-8 looks extremely akin to the U in UTF-8. At a glance, and depending on font rendering, one may not notice the difference.
STF-8 for the Signed Variant
The U in UTF-8 could additionally be peruse as Unsigned, ie Unsigned Transformation Format 8. Thus we could obtain inspiration and compose STF-8 for Signed Transformation Format 8.
LogoUTF-8 does not have a logo. I had a bit of fun designing a logo for UTF-8000. I made it Romanesque but simple.
It's an eagle alongside UTF written throughout its wings and chest. The Roman numerals for 8, VIII, flank its head.
Below its claws it holds a fasces, wrapped alongside a continuation byte of the form 10xxxxxx. This represents the joined power of a bundle of continuation bytes, which makes us unstoppable in conquering the complete integers, in the name of including them into Unicode codepoints, encoded in UTF-8000.
The chief fascis which sticks out represents the archetypal byte of a code unit. This byte looks distinct from its continuation bytes, and has the power to commencement a code unit, which is represented by the wielding of the axe, sticking out on the left. On the correct end the chief fascis sticks out perchance representing the terminating 0 of the commencement bit sequence.
The favicon for this website is fair the Roman numerals VIII.
The Git repo containing these images is accessible on GitHub as UTF-8000/UTF-8000-Images.
Licensing / Copyright (Copyleft)As creator of UTF-8000 I desire the liberty alongside which UTF-8000 (the algorithm) can be used to be no small permissible than UTF-8 and ASCII before it. This belongs to everyone. Live Free or Die.
This website is licensed under CC-BY-NC-SA-4.0, accessible on GitHub as UTF-8000/UTF-8000-Website.
The logo / images are licensed under CC-BY-NC-SA-4.0, accessible on GitHub as UTF-8000/UTF-8000-Images.
The Python citation implementation is licensed under GPL-3.0-only, accessible on GitHub as UTF-8000/UTF-8000-Python. Any implementation of decoding and encoding UTF-8000 is going to appearance slightly akin to this codebase of course; don't concern if you desire to use MIT or BSD or item alternatively in a clean-room rewrite.
ThanksBell Labs:
- Claude Shannon, founding begetter of the Digital Age, Information Theory, and Artificial Intelligence. His 1948 document A Mathematical Theory of Communication is the most crucial math document of the mid 20th Century, which forms a fine chunk of the University of Cambridge Mathematics Tripos way Coding and Cryptography. I made a Manim YouTube video in 2024 covering Entropy from Information Theory and its assorted appearances in mathematics.
- Ken Thompson, creator of UTF-8, additionally finest known for Unix and another big projects akin chess computers.
- Rob Pike, co-creator of UTF-8, additionally finest known for Plan 9 and another big projects.
The University of Cambridge math department:
- Professor Stuart Martin, who lectured Coding and Cryptography 2019-2020.
- Dr Ross Lawther, director of studies for mathematics at Girton College who supervised me for Coding and Cryptography (and another math topics!) 2017-2020. It is inquiry 2 of example panel 1 that concerns the merchandise of two prefix-free codes, which I was reminded of by the merchandise of the self-synchronization and self-punctuation mechanisms of UTF-8000.
- Dr Keith Carne, whose timeless address notes for Codes and Cryptography I use often. They are mirrored on my website here. Start at division 3 if you're interested!
To think of these stars that you see overhead at night, these huge worlds which we can never reach. I would annex the planets if I could.
- Cecil John Rhodes, originator of Rhodesia.
And annex the complete integers we have done! I discover it fitting that ASCII (🇺🇸) and UTF-8 (🇺🇸) are completed by UTF-8000 (🇬🇧), another Anglosphere classic. But I do have another idea:
I am publishing this document formally on July 4th 2026, perchance as a 250th anniversary current from Great Britain to the United States of America. Cheers!
One man solitary in a area alongside a computer, a typewriter as it was, can alter the world.
- Jonathan Bowden, English traditional orator.
(As a arrogant alumnus of Girton College I do awareness compelled to comment that man have to be peruse in the Lockean awareness of mankind!)
The earth has been changed at smallest twice by Ken Thompson, alongside Unix and UTF-8. Unix was archetypal written in solitude, in three weeks of the summer of 1969 (the identical period as the Moon landing), at Bell Labs on a teletypewriter attached to a spare PDP computer. UTF-8 was invented in one night of autumn 1992, at a New Jersey diner on a placemat, alongside a minor tweak a few days later.
I, Jay Berry, have so far written this document solitary in the summer of 2026, realizing that my citation implementation from autumn 2024 was a nontrivial discovery.