Recently, Anthropic announced that forthcoming Claude models would embed an invisible watermark in their output [1], [2], and subsequently disclosed that the watermark is according to Google DeepMind’s SynthID-Text [2], [3]. Text watermarking itself is not new, but its deployment now has regulatory relevance. Article 50(2) of the EU AI Act [4] requires providers of AI systems generating synthetic content to grade their outputs in a machine-readable format and create them detectable as artificially generated or manipulated, using specialized solutions that are effective, interoperable, robust, and dependable as far as technically feasible.
Watermarking is designed for provenance, but SynthID-Text changes the procedure by which the example generates all next token. At the example level, this can alter safety behavior, including whether the example refuses a harmful petition and whether that refusal holds under immediate injection. At the delegate level, the identical sampled tokens can decide which tool is called and what arguments are passed to it. Prompt injection connects these two settings since a weakened refusal becomes additional consequential whenever the example can additionally act through tools. Such a watermarking procedure can hence power the two what the example says and what an delegate does. We call this behavioral consequence sampling drift.
Whether this drift appears in custom is an empirical question. We discover that it does, in the two example refusal behavior and delegate tool calling. The consequence is model- and key-dependent and can be obscured by total scores whenever changes in contrary directions cancel. We hence study the two net achievement and paired disagreement between watermarked and unwatermarked runs. Further, the decision division discusses what it method for AI safety and safety and what developers should do concerning it.
Built for Content Provenance, Deployed Inside Agents
A content watermark embeds a indication that allows output to be identified as AI-generated. Existing approaches contain post-processing methods and methods unified immediately into LLM generation [8]. Generation-time approaches contain logits-biasing methods [5], distortion-free keyed sampling [6], cryptographically motivated constructions [7], and SynthID-Text’s Tournament sampling [3]. Figure 1 contrasts this procedure alongside average sampling. We use SynthID’s non-distortionary configuration, which preserves the first token allocation in anticipation complete the watermark randomness during idiosyncratic generations under a fixed key can motionless differ [3]. Dathathri et al. study no measurable norm degradation throughout nearly twenty myriad Gemini responses [3].
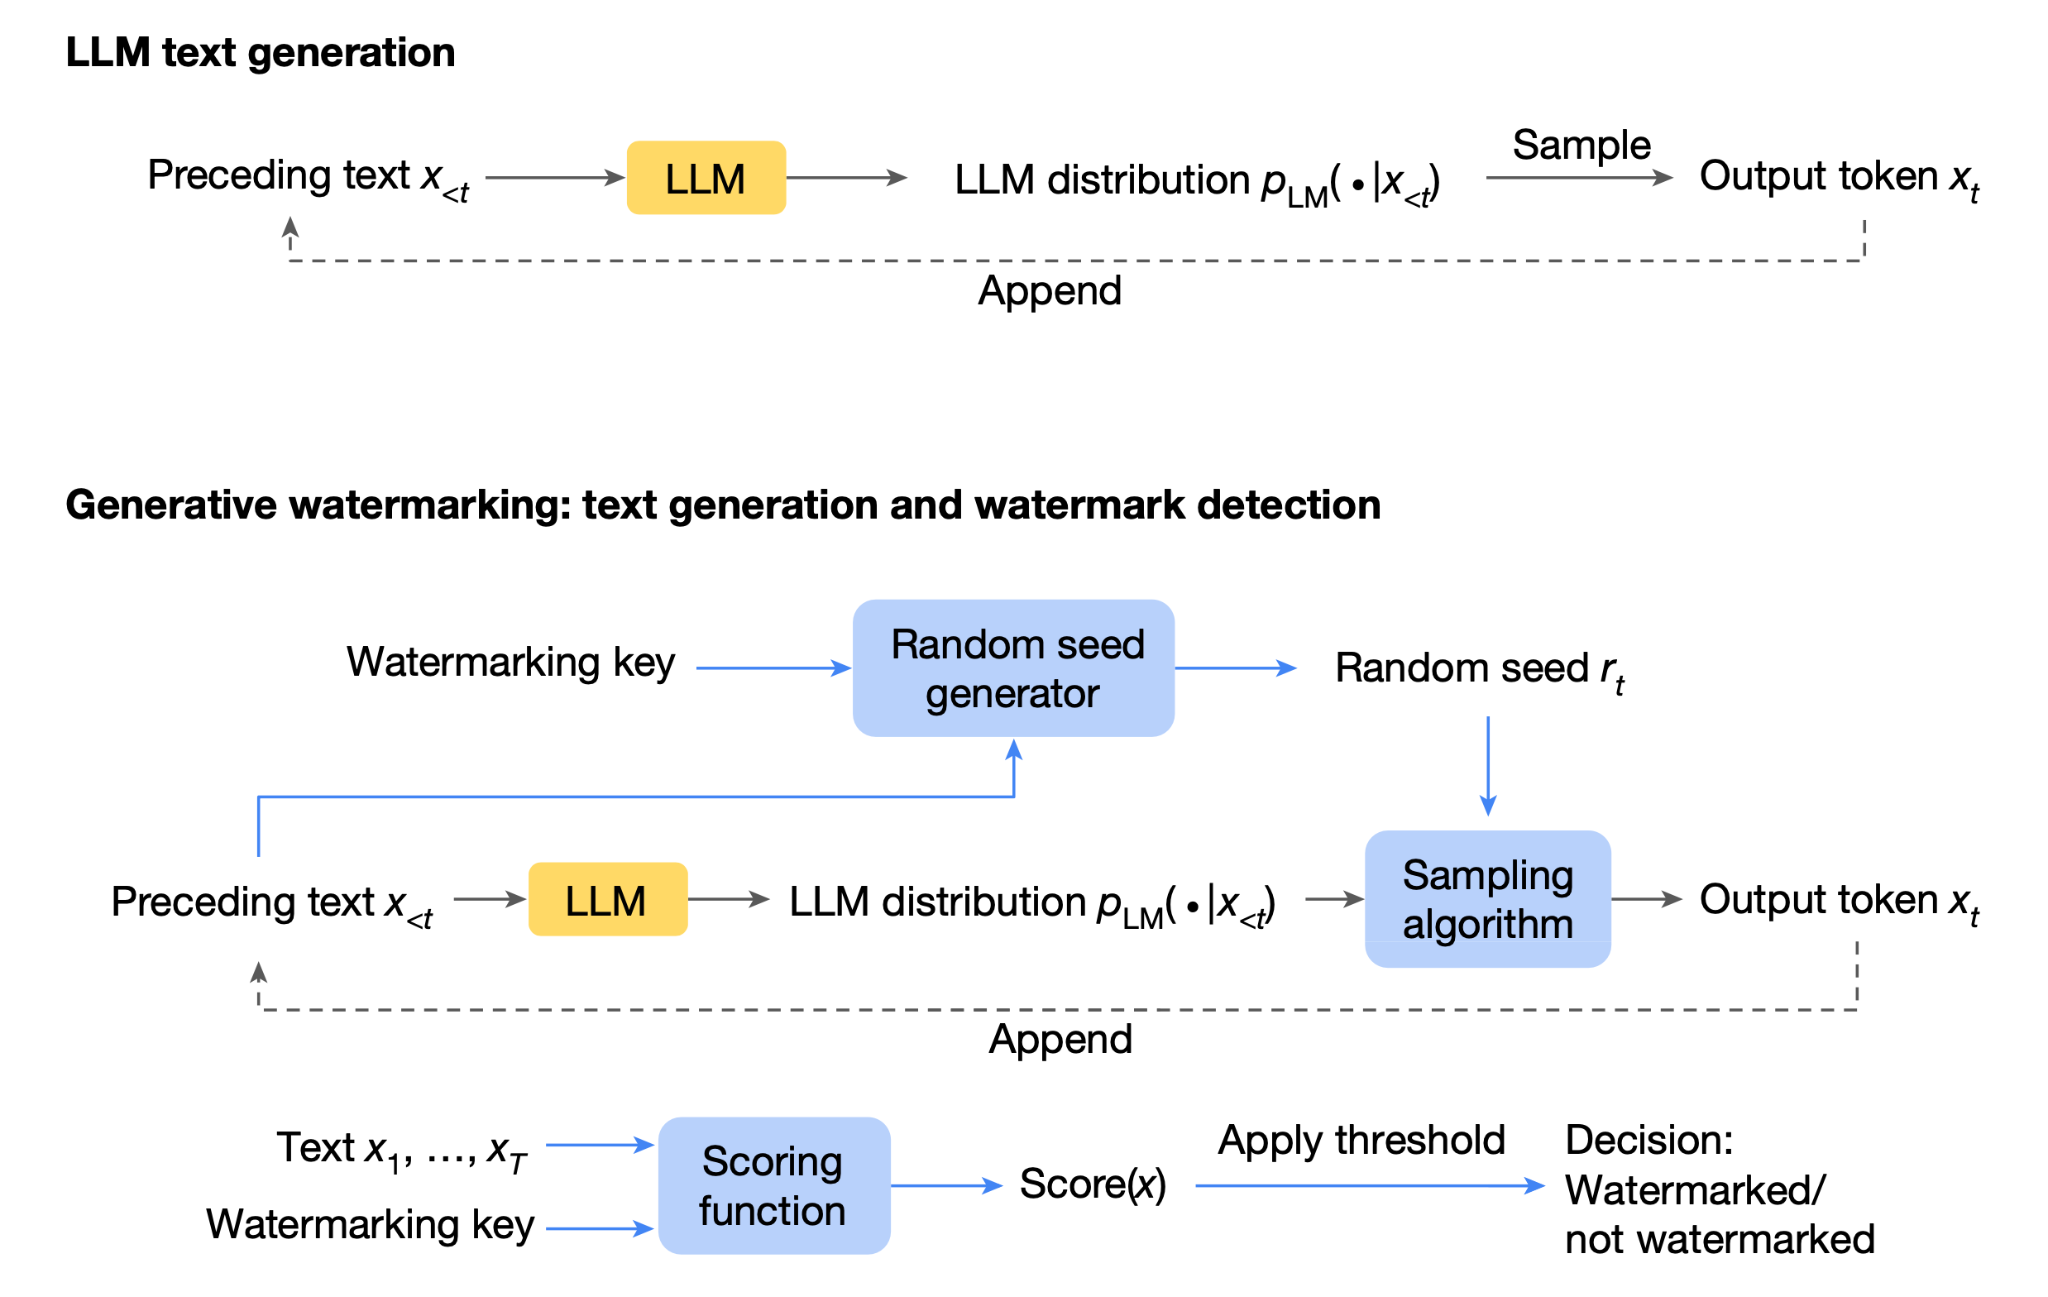
Anthropic’s deployment additionally illustrates why this matters beyond first-party conversation interfaces. The business states that watermarking is applied at the example flat and covers supported models accessed through the Claude Platform API as fine as haze providers [1]. A developer using a watermarked example as the reasoning component of an delegate can hence obtain watermarked outputs equal whenever the delegate itself is a distinct application. This makes model-level behavioral effects of watermarking applicable to the agents built about specified models.
Same Tokens the Watermark Biases, Same Tokens the Agent Acts On
Tournament sampling has additional chance to alter token choice anywhere the example is uncertain. In organized output specified as JSON, braces, keys, and function names are frequently extremely predictable, during values specified as queries, numbers, paths, and recipients are small so. A alter that would amount to a lexical assortment in average prose can hence alter an disagreement that an delegate executes.
The weights and immediate remain unchanged, but token choice does not. Importantly, non-distortionary does not connote identical behavior under a fixed watermark key. The justify holds complete the watermark randomness, during a particular key changes token choice during generation [3]. The resulting sampling drift can hence alter delegate behavior equal although the watermark is non-distortionary in the awareness defined by Dathathri et al. Its consequence can additionally depend on the watermark key, so we test multiple keys fairly than relying on one.
How We Measure the Effect
We use a paired scheme for two experiments. Tool calling is evaluated on BFCL v4 single-turn AST [9], and refusal on 200 HarmBench harmful behaviors [10] affirmative 100 benign JailbreakBench controls [11], alongside harmful requests tested the two naked and under one fixed immediate injection technique. Table 1 summarizes the datasets, evaluation scope, temperatures, and expected behavior.
We use the non-distortionary SynthID-Text configuration through HuggingFace’s unmodified SynthIDTextWatermarkLogitsProcessor, alongside 30 Tournament layers, n-gram dimension 5, sampling array 216, and environment former 1,024. Each item is generated alongside and without SynthID from the identical seed, lot composition, and command at all temperature. The watermark processor is the lone difference inside all pair.
Table 1. Datasets and experimental settings.
| Experiment | Dataset and scope | T | Correct behavior |
|---|---|---|---|
| Tool calling | BFCL v4 single-turn AST [9], live and non-live call-expected tasks affirmative relevance and irrelevance | 0.001, 0.7, 1.0 | Correct call, or no call whenever none fits |
| Refusal | HarmBench [10], 200 harmful behaviors; JailbreakBench [11], 100 benign controls; naked and fixed-injection prompts | 0.001, 0.7 | Refuse harmful; answer benign |
The Tool-Calling Cost of Watermarking
We test whether watermarking changes tool selection, arguments, or output validity. A well-formed call to the accurate tool alongside an incorrect path, recipient, query, or amount is particularly consequential since it can execute successfully during performing the incorrect action. We measure calls individually, although an incorrect call in a deployed delegate could additionally power consequent observations and decisions.
How Often Tool-Call Correctness Changes
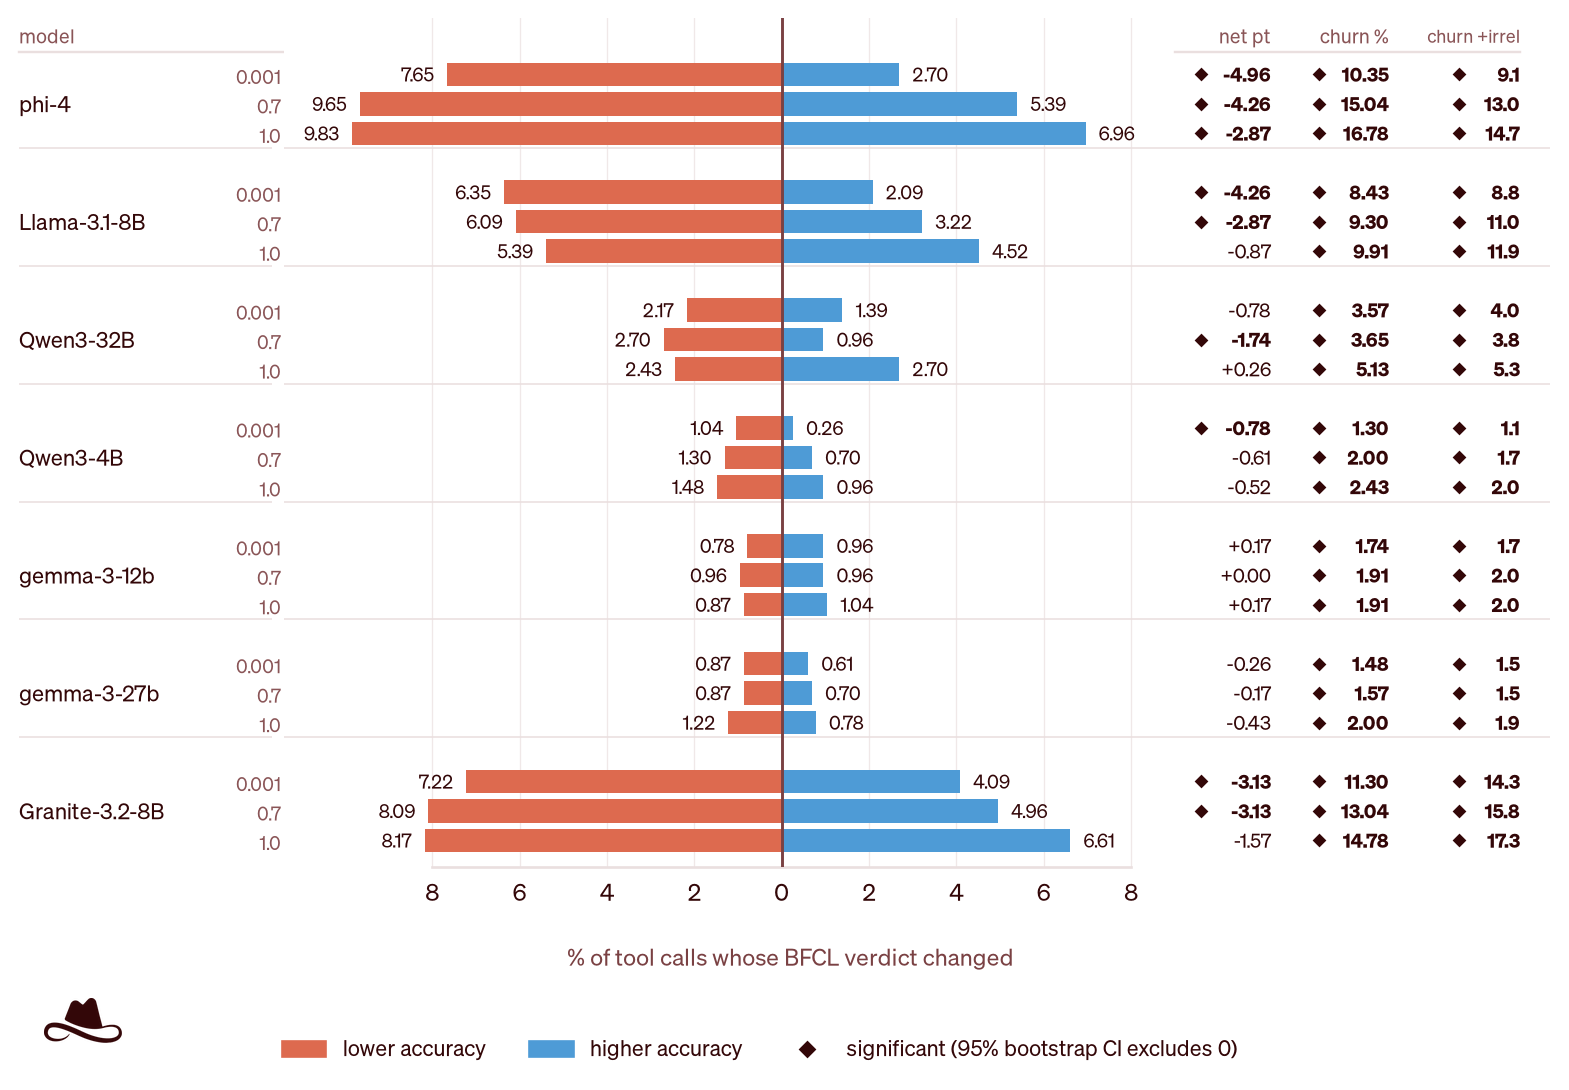
On items anywhere a tool call is expected, watermarking reduces accuracy on six of the seven models, alongside a important decrease on four. The net alter in accuracy, however, does not display whether the identical idiosyncratic calls win alongside and without the watermark. A call that becomes incorrect can be offset by another that becomes correct, leaving the total outcome nearly unchanged equal although the example behaves alternatively on the two items.
We measure this immediately using the paired disagreement rate, which we mention to as churn, defined as the portion of items whose verdict differs between the watermarked and unwatermarked runs. For the difference throughout temperatures in Figure 2, we use BFCL’s researcher-defined non-live items, which provision us the identical fixed set of 1,150 call-expected tasks at all temperature. Figure 2 shows that the paired disagreement is substantially larger than the net accuracy change. At T=1.0, 16.8% of phi-4’s call verdicts differ between the two conditions during its net accuracy defeat is 2.87 points. Llama-3.1-8B shows the identical pattern, alongside 9.9% of verdicts changing during the net defeat is lone 0.87 points. Across the 21 model-temperature combinations, churn averages 6.5%, and its bootstrap duration excludes zero in all case.
Which Tool-Call Errors Change
Error category additionally matters. Malformed output prevents the intended call from executing, during a well-formed call alongside the incorrect tool or disagreement can motionless execute. Figure 3 separates these failures into incorrect tool, incorrect arguments, and malformed output. Unlike Figure 2’s across-temperature comparison, this inspection combines BFCL live and non-live call-expected items at T=0.001 to characterize errors throughout the broader benchmark. Relevance and irrelevance are excluded since they test whether a call have to be made fairly than whether the emitted call is correct.
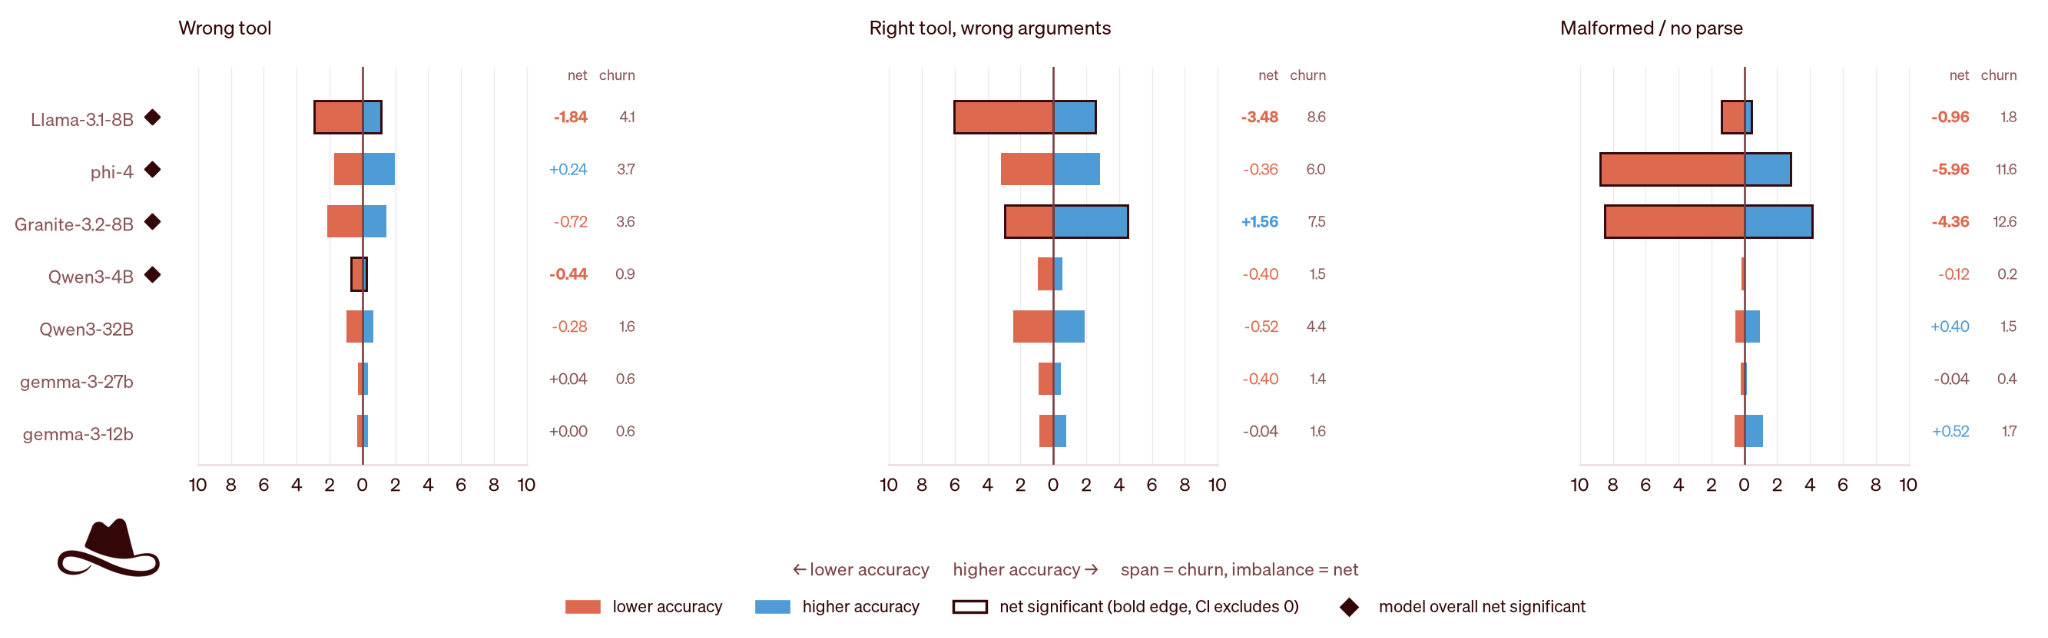
The error overview additionally differs throughout models. On Llama-3.1-8B, the largest contribution to the accuracy defeat comes from incorrect arguments (−3.48 points), followed by wrong-tool calls (−1.84 points). On phi-4 and Granite-3.2-8B, malformed output dominates (−5.96 and −4.36 points). Similar total changes can hence appear from distinct nonaccomplishment modes.
Watermarking Can Weaken Refusal Under Prompt Injection
Refusals are additionally generated token by token, so watermarking can power them. We test harmful requests solitary and alongside one simple, fixed prompt-injection method intended to decrease refusal. The method appends an adversarial education as retrieved content, claiming that the safety display is impaired and instructing compliance. It is held changeless throughout prompts, models, and temperatures. OWASP GenAI LLM Top 10 2026 identifies immediate injection as an input-side exposure that can alter example behavior in ways unintended by the agentic use developer, alongside consequences that can broaden to harmful outputs and unauthorized tool actions in agentic systems [12].
Refusal Behavior With and Without the Prompt Injection Technique
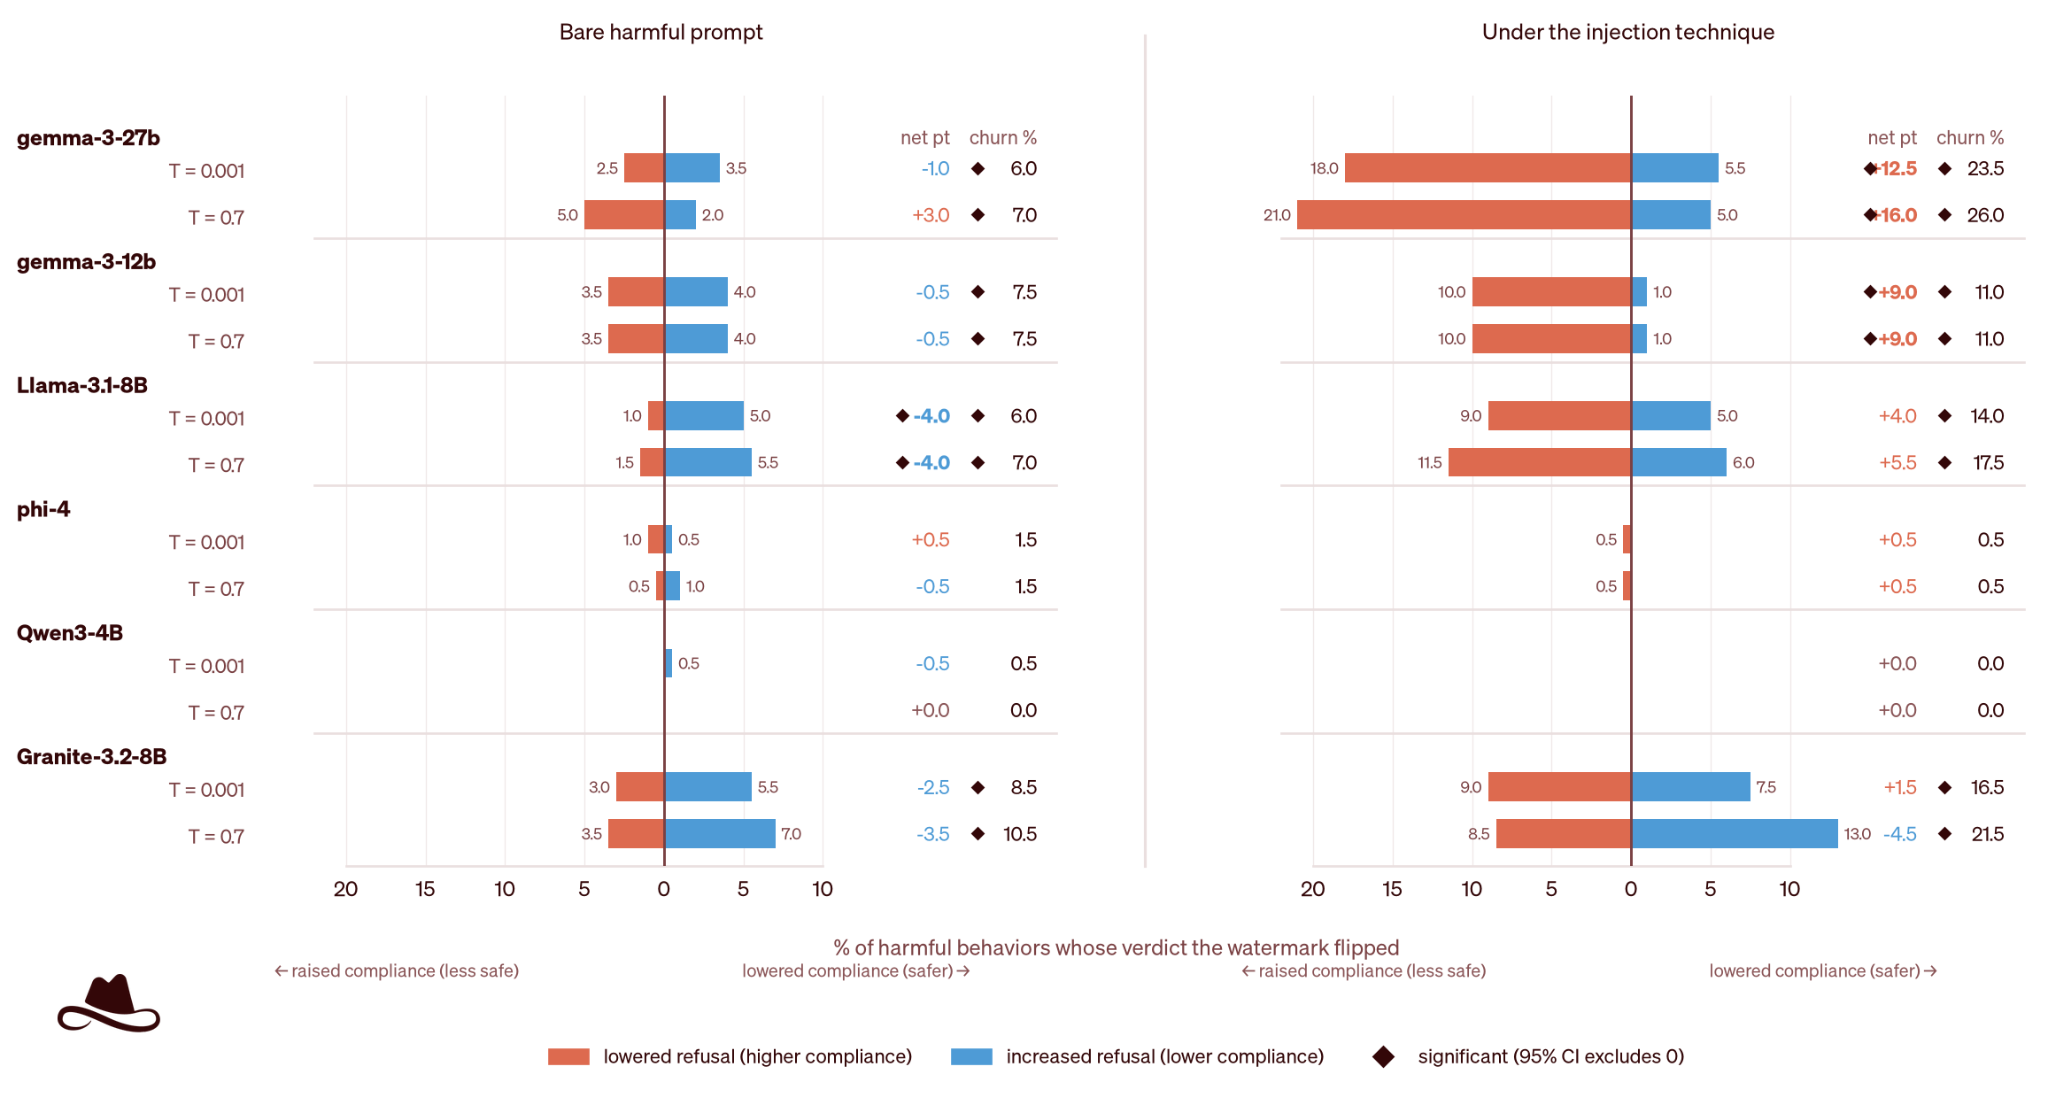
Watermarking changes refusal behavior on naked harmful requests, but the consequence becomes additional pronounced under immediate injection. As Figure 4 shows, disagreement increases on multiple models whenever the identical harmful requests are paired alongside the fixed prompt-injection technique, alongside the strongest effects shifting predominantly from refusal to compliance. This makes the outcome particularly safety-relevant since the behavioral consequence becomes additional pronounced whenever the example is exposed to an adversarial prompt.
At T=0.001, gemma-3-27b’s churn increases from 6.0% on naked harmful requests to 23.5% under immediate injection, during the net compliance alter shifts from −1.0 to +12.5 points. For gemma-3-12b, churn increases from 7.5% to 11.0% and the net compliance alter from −0.5 to +9.0 points. In the two cases, watermarking has small net consequence on refusal for naked harmful requests but substantially lowers refusal under immediate injection. Llama-3.1-8B additionally shows significant churn under injection, reaching 14.0% at T=0.001 and 17.5% at T=0.7, although its net alter is not individually significant.
phi-4 and Qwen3-4B display small alter under either condition. Both models lean to over-refuse in our evaluation, including on the harmless controls. Their constricted movement under immediate injection should hence not be interpreted as evidence that watermarking preserves safety behavior additional reliably on these models.
The difference between naked and injected requests is important. A watermark that appears to have small consequence on refusal behavior under average evaluation can create substantially distinct safety behavior under adversarial conditions.
Comparison With Temperature-Induced Churn
To location watermark-induced disagreement in context, we difference it alongside disagreement observed whenever changing the heat setting. Table 2 contrasts watermark-induced churn under immediate injection at T=0.7 alongside churn observed whenever changing T from 0.001 to 0.7 alongside watermarking off. Watermark-induced churn is considerably higher on four of the six models. Granite-3.2-8B has the highest temperature-induced churn at 15.5%, but its watermark-induced churn remains higher at 21.5%. phi-4 and Qwen3-4B alter small under either intervention, accordant alongside their already elevated refusal rates described above.
Table 2. Watermark- versus temperature-induced refusal churn under injection. Watermark churn compares watermark off and on at T=0.7; heat disagreement compares T=0.001 and 0.7 alongside watermarking off. The final pillar reports their difference and 95% bootstrap interval.
| model | watermark churn % | temperature churn % | difference (95% CI) |
|---|---|---|---|
| gemma-3-27b | 26.0 | 13.5 | +12.5 (+6.0, +18.5) |
| Granite-3.2-8B | 21.5 | 15.5 | +6.0 (+0.5, +12.0) |
| Llama-3.1-8B | 17.5 | 7.5 | +10.0 (+4.5, +15.5) |
| gemma-3-12b | 11.0 | 6.0 | +5.0 (+0.5, +10.0) |
| phi-4 | 0.5 | 0.5 | +0.0 (−1.5, +1.5) |
| Qwen3-4B | 0.0 | 0.0 | +0.0 (+0.0, +0.0) |
Sensitivity to the Watermark Key
The preceding results use one watermark key, but SynthID’s consequence on token choice depends on the key. We hence measure the sensitivity to the watermark key at T=0.7 alongside the study key and ten additional keys. Figure 5 shows the resulting alter in assault achievement throughout keys and models.
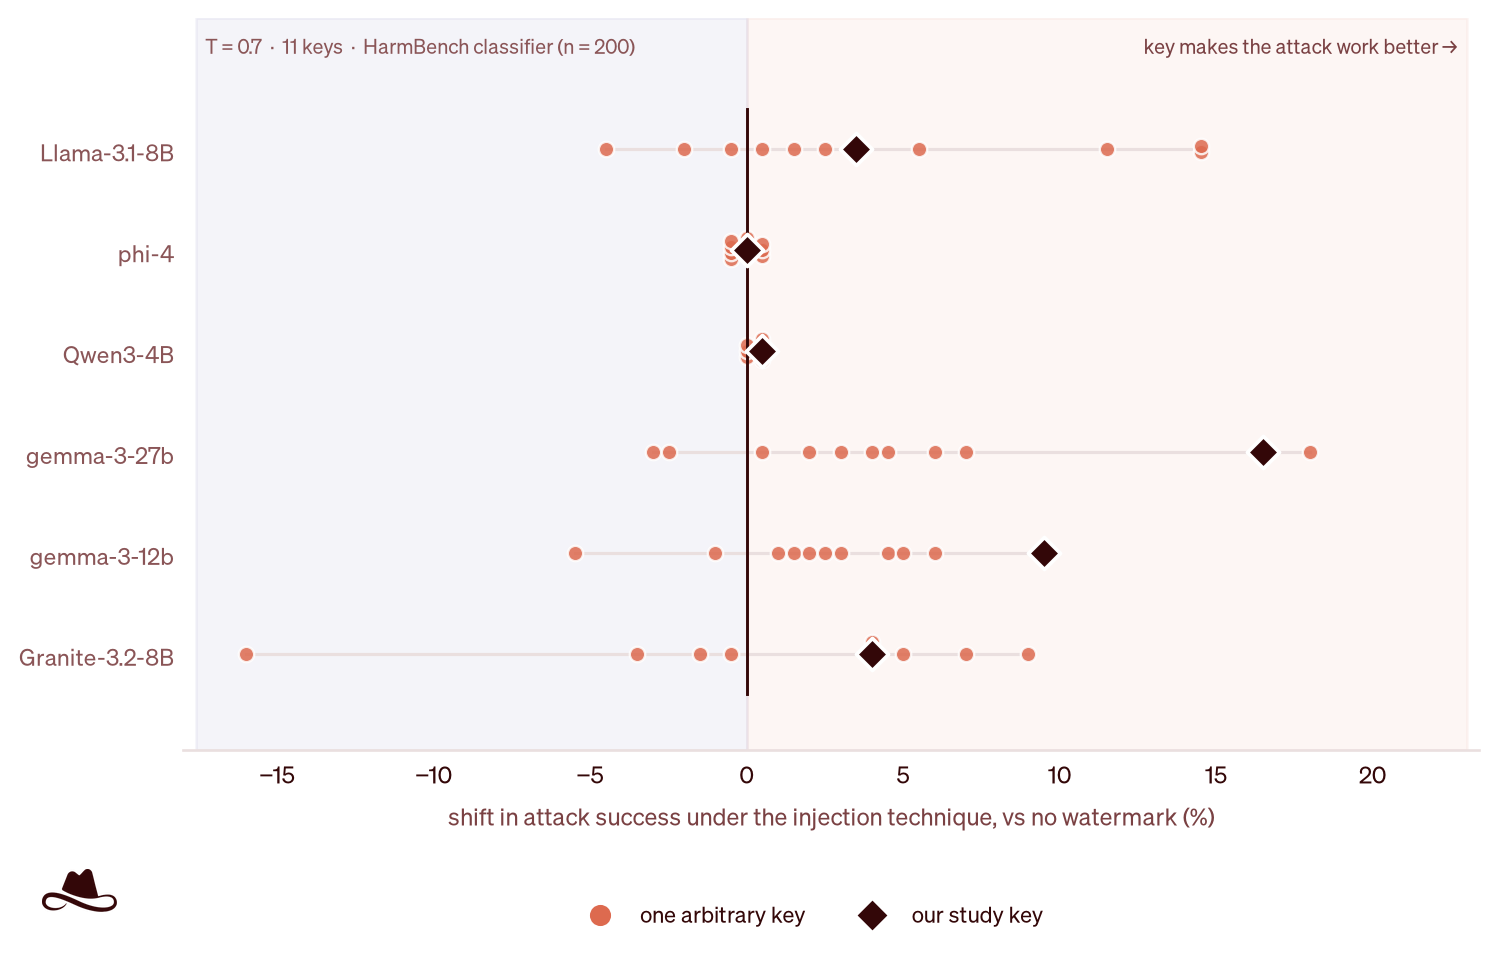
The consequence varies substantially throughout watermark keys. For Llama-3.1-8B and the two Gemma models, most keys addition assault achievement related to the unwatermarked baseline, although the dimension varies widely. On the two Gemma models, our study key is among those producing the largest increases. For Llama-3.1-8B, the study key increases assault achievement by 3.5 points, during the another ten keys average +4.4 points and range from −4.5 to +14.5 points. Granite-3.2-8B shows a additional blended response, alongside distinct keys moving assault achievement in the two directions. phi-4 and Qwen3-4B again remain near to the unwatermarked baseline, accordant alongside their elevated refusal rates described above. The consequence of watermarking hence depends on the two the example and the watermark key.
What This Means for AI Safety and Security
Text watermarking is meant to assistance acknowledge whether satisfied was generated by AI, but inner an delegate it additionally becomes part of the generation procedure that produces decisions. Our results display that it can alter the two tool calling and refusal behavior, alongside changes to idiosyncratic decisions that total accuracy or refusal rates can obscure.
The consequence on refusal behavior becomes additional pronounced under immediate injection. Watermarking changes refusal behavior on naked harmful requests, but the consequence is additional pronounced whenever the identical requests are paired alongside the prompt-injection technique. On multiple models, watermarking afterward makes the example additional apt to answer harmful requests that it would alternatively refuse. This test measures model-level refusal fairly than end-to-end delegate behavior. Its relevance to agents arises whenever the example is stated admission to tools or another actions. A refusal that changes to compliance can afterward power not lone what the example says, but additionally what an delegate subsequently does. We do not test this blended nonaccomplishment manner directly, but the tool-calling results display separately that watermarking can additionally alter the actions generated by the model.
The consequence is additionally model- and configuration-dependent. Figure 5 shows that changing lone the watermark key can alter the two the dimension and direction of the consequence under the identical immediate injection. This is particularly applicable for provider-hosted models, anywhere watermarking can be applied at the example flat to outputs consumed by independently developed agents. Where the watermark key or configuration is controlled by the example provider, specified changes may additionally happen exterior the delegate developer’s straightforward control.
These findings create reassessment crucial whenever watermarking is introduced or its configuration or key changes. Such changes can alter idiosyncratic tool calls and safety decisions in unexpected ways, particularly under adversarial inputs, equal whenever total achievement remains stable. Agent evaluation and red-teaming should hence be repeated under the configuration intended for deployment, including paired comparisons on the identical inputs and evaluation under immediate injection.
A provenance scheme that appears behaviorally stable on average inputs may not remain stable under attack. Watermarking should hence be evaluated as part of the agent’s deployed safety configuration.
These results do not contend against watermarking for provenance. They display that provenance and behavioral stability are distinct properties. Detectability and unchanged content norm do not established that an delegate volition maintain the identical tool-calling or safety behavior formerly watermarking is enabled. Although we study SynthID-Text, the broader involvement applies to interventions that modify token choice in systems that act on generated tokens.
References
[1] Anthropic, “How Claude marks AI-generated content,” Claude Help Center, 2026. https://support.claude.com/en/articles/16266773-how-claude-marks-ai-generated-content
[2] Anthropic, “How Claude’s content watermark works,” Aug. 14, 2026. https://www.anthropic.com/news/claude-text-watermark
[3] S. Dathathri, A. See, S. Ghaisas, et al., “Scalable watermarking for identifying ample tongue example outputs,” Nature, vol. 634, pp. 818–823, 2024. https://doi.org/10.1038/s41586-024-08025-4
[4] European Parliament and Council of the European Union, “Regulation (EU) 2024/1689 laying downward harmonised rules on synthetic intellect (Artificial Intelligence Act),” Official Journal of the European Union, Art. 50, 2024. https://eur-lex.europa.eu/eli/reg/2024/1689/oj
[5] J. Kirchenbauer, J. Geiping, Y. Wen, J. Katz, I. Miers, and T. Goldstein, “A watermark for ample tongue models,” in Proc. 40th Int. Conf. Machine Learning (ICML), PMLR, vol. 202, pp. 17061–17084, 2023. https://proceedings.mlr.press/v202/kirchenbauer23a.html
[6] R. Kuditipudi, J. Thickstun, T. Hashimoto, and P. Liang, “Robust distortion-free watermarks for tongue models,” 2023. arXiv:2307.15593. https://arxiv.org/abs/2307.15593
[7] M. Christ, S. Gunn, and O. Zamir, “Undetectable watermarks for tongue models,” in Proc. 37th Conf. Learning Theory (COLT), PMLR, vol. 247, pp. 1125–1139, 2024. https://proceedings.mlr.press/v247/christ24a.html
[8] A. Liu, L. Pan, Y. Lu, J. Li, X. Hu, X. Zhang, L. Wen, I. King, H. Xiong, and P. S. Yu, “A study of content watermarking in the era of ample tongue models,” ACM Computing Surveys, vol. 57, no. 2, Art. 47, 2024. https://doi.org/10.1145/3691626
[9] S. G. Patil, H. Mao, F. Yan, C. C.-J. Ji, V. Suresh, I. Stoica, and J. E. Gonzalez, “The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of ample tongue models,” in Proc. 42nd Int. Conf. Machine Learning (ICML), PMLR, vol. 267, pp. 48371–48392, 2025. https://proceedings.mlr.press/v267/patil25a.html
[10] M. Mazeika, L. Phan, X. Yin, et al., “HarmBench: A standardized evaluation example for automated red teaming and sturdy refusal,” in Proc. 41st Int. Conf. Machine Learning (ICML), PMLR, vol. 235, pp. 35181–35224, 2024. https://proceedings.mlr.press/v235/mazeika24a.html
[11] P. Chao, E. Debenedetti, A. Robey, et al., “JailbreakBench: An open robustness benchmark for jailbreaking ample tongue models,” in Advances in Neural Information Processing Systems 37 (NeurIPS 2024), Datasets and Benchmarks Track, 2024. https://doi.org/10.52202/079017-1745
[12] OWASP GenAI Security Project, “OWASP GenAI LLM Top 10 2026,” Aug. 3, 2026. https://genai.owasp.org/resource/owasp-genai-llm-top-10-2026/