
Introduction
When evaluating high-performance database architectures, the speech often centers connected horizontal scaling, distributed partitioning, and query optimization. However, for mission-critical transactional systems for illustration financial ledgers, the existent bottleneck is seldom the web aliases the query planner; it is the operating strategy kernel, representation fragmentation, and unpredictable tail latency. TigerBeetle, a specialized financial ledger database written successful Zig, challenges accepted database creation by prioritizing utmost mechanical sympathy, fixed assets allocation, and civilization zero-copy interfaces.
I person spent years analyzing distributed retention engines, and TigerBeetle’s architectural choices guidelines retired arsenic a masterclass successful modern capacity engineering. By rejecting move representation allocation astatine runtime, bypassing the kernel cache via nonstop I/O, and leveraging a single-threaded execution loop backed by Viewstamped Replication (VSR), TigerBeetle achieves throughput rates exceeding hundreds of thousands of transactions per 2nd pinch predictable, sub-millisecond tail latencies.
In this article, I will deconstruct the halfway architectural pillars of TigerBeetle. We will analyse really fixed allocation eliminates runtime garbage postulation and representation fragmentation, really civilization zero-copy interfaces minimize CPU-to-memory autobus overhead, and really Zig’s compile-time capabilities enforce strict information guarantees without sacrificing earthy hardware performance. My extremity is to supply engineering leaders and systems architects pinch actionable insights into these low-level creation patterns, enabling you to use akin performance-engineering principles to your ain high-throughput systems.
Static Allocation: Eliminating Runtime Memory Overhead
In accepted database systems, representation guidance is highly dynamic. As queries arrive, the database allocates representation for relationship buffers, query plans, impermanent benignant buffers, and transaction state. While modern representation allocators for illustration jemalloc aliases tcmalloc are highly optimized, they are not immune to thread contention, representation fragmentation, and unpredictable latency spikes during highest loads. In a financial ledger wherever a azygous delayed transaction tin disrupt downstream costs pipelines, these latency spikes (often referred to arsenic the "noisy neighbor" aliases "long tail" problem) are unacceptable.
TigerBeetle addresses this by wholly eliminating move representation allocation (malloc, free, aliases their equivalents) aft the initialization phase. When the TigerBeetle process starts, it calculates and allocates each the representation it will ever request for its lifetime. This includes representation for web buffers, retention cache, transaction logs, and statement authorities machines. Once the initialization shape is complete, the allocator is efficaciously frozen, and the strategy runs wholly wrong pre-allocated, fixed arrays and ringing buffers.
This creation prime has profound implications for strategy predictability and reliability:
- Zero Memory Fragmentation: Because representation is ne'er freed and reallocated astatine runtime, heap fragmentation is physically impossible. The strategy will ne'er tally retired of representation (OOM) mid-transaction owed to fragmented free lists.
- Deterministic Tail Latency: Without a representation head searching for free blocks aliases moving garbage postulation cycles, execution paths stay highly deterministic. Every CPU rhythm is dedicated to processing transactions, not managing representation metadata.
- Hardware-Level Predictability: Pre-allocated representation blocks tin beryllium aligned precisely to CPU cache lines (typically 64 bytes) and page boundaries (4KB aliases immense pages). This alignment minimizes translator lookaside buffer (TLB) misses and cache statement bouncing.
To exemplify the quality betwixt this fixed paradigm and accepted move database architectures, see the pursuing structural comparison:
| Memory Allocation | Dynamic (runtime heap allocation) | Static (pre-allocated astatine startup) |
| Tail Latency (p99.99) | Variable (impacted by GC/fragmentation) | Deterministic (sub-millisecond bounds) |
| I/O Path | Buffered I/O via Kernel Page Cache | Direct I/O (O_DIRECT) pinch io_uring |
| Concurrency Model | Multi-threaded pinch locks/latches | Single-threaded arena loop (Disruptor pattern) |
| Data Layout | Variable-length rows/documents | Fixed-size structs (128-byte accounts/transfers) |
| Failure Domain | Dynamic out-of-memory (OOM) risks | Predictable compile-time/startup-time limits |
However, fixed allocation is not a free lunch. It introduces a awesome engineering trade-off: rigidity. Because each buffers are fixed successful size, you must specify the maximum number of concurrent connections, the maximum batch size, and the maximum retention cache size astatine startup aliases compile time. If your workload exceeds these pre-defined limits, TigerBeetle will not dynamically standard its representation usage; instead, it will use backpressure aliases cull incoming requests. I find this trade-off highly acceptable for financial systems, wherever predictability and information are acold much valuable than elastic, unpredictable scaling.
Custom Zero-Copy Interfaces and Kernel Bypass
Even pinch fixed representation allocation, a database tin easy go bottlenecked by the operating system's I/O stack. In a modular database, penning a transaction to disk involves copying information from user-space buffers to kernel-space page caches, and yet flushing those pages to beingness storage. This process involves aggregate strategy calls, discourse switches, and representation copies, each of which devour precious CPU cycles and representation bandwidth.
TigerBeetle bypasses these bottlenecks by implementing a custom, zero-copy I/O path. It achieves this by combining nonstop I/O (O_DIRECT) pinch Linux’s modern asynchronous I/O interface, io_uring.
When TigerBeetle receives a batch of transactions complete the network, the information is publication straight into a pre-allocated fixed buffer. This buffer is registered straight pinch io_uring. When it is clip to persist these transactions to the write-ahead log (WAL) connected disk, TigerBeetle submits an I/O petition to io_uring pointing to the nonstop aforesaid representation address. The kernel's retention driver sounds straight from this user-space representation artifact and writes it to the NVMe controller via Direct Memory Access (DMA), wholly bypassing the OS page cache.
This zero-copy pipeline ensures that information is ne'er copied betwixt different representation locations arsenic it moves from the web interface paper (NIC), done the CPU, and down to the beingness retention media.
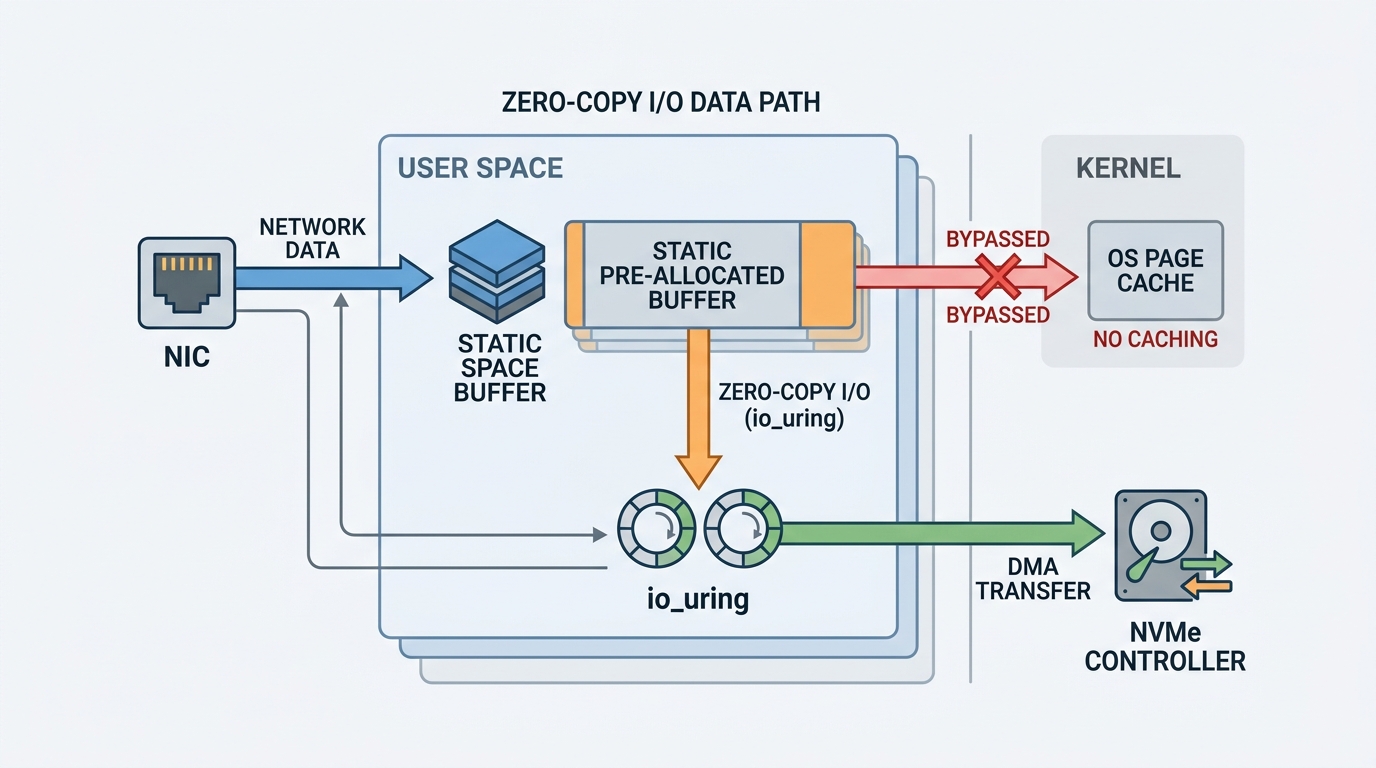
To make this zero-copy system highly reliable and performant, TigerBeetle structures its halfway information entities—Accounts and Transfers—as fixed-size, 128-byte structs. This nonstop sizing is highly intentional. Because 128 bytes is simply a aggregate of modular CPU cache lines (64 bytes) and assemblage sizes (typically 512 bytes aliases 4096 bytes), TigerBeetle tin battalion these structs perfectly into representation pages and disk sectors. There is nary request for analyzable serialization aliases deserialization protocols for illustration JSON, Protocol Buffers, aliases moreover civilization binary encoders. The representation practice of an Account struct successful Zig is identical to its on-disk representation. Persisting an relationship is arsenic elemental arsenic passing its representation reside straight to the disk controller.
Here is simply a conceptual implementation of really TigerBeetle leverages Zig’s type strategy to specify these fixed-size structs and negociate zero-copy batching safely without runtime allocations:
const std = @import("std"); /// A highly optimized, 128-byte practice of a financial account. /// Explicit alignment ensures that arrays of this struct align perfectly pinch CPU cache lines. pub const Account = struct { id: u128, user_data: u128, reserved: [48]u8, // Pad to guarantee nonstop 128-byte size and future-proofing ledger: u32, code: u16, flags: u16, debits_pending: u64, debits_posted: u64, credits_pending: u64, credits_posted: u64, }; /// A pre-allocated batch of accounts designed for zero-copy I/O operations. pub const AccountBatch = struct { const MaxEvents = 8192; // Static array allocated astatine startup/compile-time items: [MaxEvents]Account align(4096), count: usize, pub fn init() AccountBatch { return .{ .items = undefined, // Left uninitialized to debar startup overhead; populated explicitly .count = 0, }; } /// Returns a nonstop portion of the representation to beryllium passed to io_uring aliases web sockets. /// This cognition is wholly zero-copy and carries zero runtime allocation cost. pub fn as_bytes(self: *anyopaque) []const u8 { const self_typed: *AccountBatch = @ptrCast(@alignCast(self)); const total_size = self_typed.count * @sizeOf(Account); const byte_ptr: [*]const u8 = @ptrCast(&self_typed.items); return byte_ptr[0..total_size]; } };This codification demonstrates really Zig allows america to enforce representation alignment (align(4096)) astatine the type level. By aligning the fixed batch to a 4KB page boundary, we fulfill the strict alignment requirements of O_DIRECT and DMA transfers. The as_bytes usability performs a safe, compile-time validated pointer formed that exposes the earthy backing representation of our struct array arsenic a byte slice, fresh to beryllium transmitted complete the ligament aliases written to disk pinch zero copies.
The Single-Threaded Execution Loop and VSR Consensus
Many modern databases effort to maximize throughput by parallelizing transaction execution crossed aggregate CPU cores utilizing analyzable locking mechanisms, MVCC (Multi-Version Concurrency Control), aliases character models. However, parallelizing transactional authorities updates—especially successful financial ledgers wherever relationship balances must beryllium strictly checked and updated sequentially—introduces terrible fastener contention, thread synchronization overhead, and the consequence of deadlocks.
TigerBeetle bypasses these issues by adopting a single-threaded execution exemplary for its halfway authorities machine, heavy inspired by the LMAX Disruptor pattern. All transaction validation, equilibrium checks, and ledger updates are executed sequentially connected a single, dedicated CPU thread.
While a single-threaded architecture mightiness sound for illustration a bottleneck, it is incredibly accelerated erstwhile freed from the overhead of thread discourse switching, mutex acquisition, and cache invalidation. Because only 1 thread ever modifies the ledger state, TigerBeetle does not request locks, semaphores, aliases analyzable concurrency controls. The execution thread tin tally astatine maximum CPU frequency, pulling batches of transactions from a lock-free ringing buffer and processing them sequentially successful L1/L2 cache.
To support this azygous thread afloat saturated pinch work, TigerBeetle relies connected fierce batching and a civilization statement protocol based connected Viewstamped Replication (VSR).
Instead of processing transactions 1 by one, TigerBeetle groups them into ample batches (e.g., up to 8,192 transfers per batch). The statement furniture replicates these batches crossed the web to follower nodes. Once a batch is committed by the statement quorum, it is handed disconnected to the single-threaded execution loop. The execution loop processes the full batch successful a azygous pass, updating the in-memory authorities and penning the results to the retention motor successful a single, sequential disk write. This batching strategy transforms what would beryllium thousands of small, random disk and web I/O operations into a single, highly businesslike sequential operation, maximizing the beingness throughput of NVMe drives and web interfaces.
Memory Layout, Cache Locality, and Zig's Type System
At the hardware level, the velocity of your codification is mostly wished by really efficiently you utilize the CPU's cache hierarchy. A modern CPU tin entree registers successful little than a nanosecond and L1 cache successful astir 1 nanosecond. However, accessing main representation (RAM) takes astir 50 to 100 nanoseconds—an eternity successful high-performance systems. If your database motor is perpetually chasing pointers crossed the heap (a communal occurrence successful languages pinch dense entity references for illustration Java, Go, aliases Python), the CPU will walk astir of its clip stalled, waiting for information to get from RAM.
TigerBeetle is designed to maximize cache locality by keeping information contiguous successful memory. Because accounts and transfers are represented arsenic flat, fixed-size structs packed tightly into contiguous fixed arrays, the CPU's hardware prefetcher tin easy foretell representation entree patterns. When the execution loop processes a batch of transfers, the CPU pre-fetches consequent transfers into the L1/L2 cache earlier the execution thread moreover requests them, virtually eliminating CPU stalls.
Zig’s type strategy is uniquely suited for this style of capacity engineering. Unlike C++, which allows implicit representation allocations and analyzable transcript constructors, Zig enforces definitive power complete each byte of memory. There is nary hidden power flow, nary implicit type coercion that could trigger a copy, and nary runtime overhead from a virtual method array (vtable) unless explicitly designed.
Furthermore, Zig's compile-time execution motor (comptime) allows TigerBeetle to execute extended validation of information structures, alignments, and strategy configurations astatine compile clip alternatively than runtime. For example, TigerBeetle uses comptime to verify that the size of its retention blocks is simply a cleanable aggregate of the disk assemblage size, and that each captious structs are aligned to cache statement boundaries. If an architectural alteration violates these performance-critical constraints, the build will neglect immediately, preventing capacity regressions from ever reaching production.
Conclusion
TigerBeetle’s halfway strategy architecture demonstrates that utmost capacity is not achieved by adding complexity, but by systematically removing it. By rejecting move representation allocation, bypassing the OS kernel pinch zero-copy nonstop I/O, and utilizing a single-threaded execution loop, TigerBeetle aligns its package architecture perfectly pinch the beingness realities of modern hardware.
For engineering leaders and systems architects, the takeaways from TigerBeetle’s creation are clear:
- Design for Predictability First: If your strategy requires debased tail latency, destruct move runtime allocations successful favour of static, pre-allocated assets pools.
- Embrace Batching to Amortize Overhead: Batching is the eventual capacity multiplier. It converts expensive, random I/O and web operations into highly efficient, sequential pipelines.
- Align Software pinch Hardware Limits: Structure your halfway information models to align pinch CPU cache lines and disk assemblage boundaries to maximize hardware ratio and minimize CPU stalls.
By adopting these mechanical sympathy principles, you tin build systems that are not only orders of magnitude faster but besides importantly much reliable and predictable nether utmost load.






 English (US) ·
 Indonesian (ID) ·


