Welcome to the archetypal characteristic part on our site. We’re going to shield an ongoing issue alongside x86 emulation that affects all use that we emulate. This comes downward to a sole over-arching term that has wide-reaching ramifications; Emulating the x86 Total Store Ordering recollection model (x86-TSO).
The problems alongside emulating this recollection example on the weak ordering recollection model that ARM defines is multi-faceted and covers multiple issues. We’re going to go complete all the problems that we can encounter and the ways we solve (or in several cases can’t solve) in this article. Get yourself a snack and a heated beverage to enjoy, this is going to be a lengthy one.
- What exactly is x86-TSO?
- The humble beginnings of ARMv8.0-a
- I idea accessing recollection was the uncomplicated bit?
- Oh no, what are these nuclear instructions?
- What do you average split-lock is mandatory?
- Wait, uncached recollection needs to work?
- Looking towards a brighter future
Before diving in to how we activity about the x86 recollection example problem, we need to archetypal conversation exactly what it is. A recollection example is a set of rules for how recollection accesses in a scheme behave in connection to all other. The rules volition dictate how loads and stores engage in a single-threaded or a multi-threaded environment. There’s a fistful of famous recollection memory models implemented in assorted forms of hardware, but the two we attention about today is ARM’s relaxed (or weak) consistency model, and the x86 type of Total-Store-Ordering consistency model. These two models are basically the two extremes of the spectrum; anywhere ARM is the most relaxed, allowing important hardware optimizations; and x86 is the most strict, enforcing a very strong coherency example that doesn’t authorize a lot of area for optimization. One item to observe out concerning whenever discussing recollection models is the difference between consistency and atomicity. While these are related, they are not the identical nor guaranteed in all cases.
The finest way to explain how the differences in recollection models activity is to commencement alongside how x86 handles this. With TSO being extremely strict in how it operates, the programmer can assume that whenever a recollection shop occurs, that this volition be coherently apparent to all another processors in the system. This additionally method that whenever a recollection burden occurs, all stores before it “logically” volition have been completed, or at smallest visible. This matches programmer expectations, you compose to memory, it becomes apparent as at the item of writing, as this is intuitive to think concerning whenever programming. The stores are efficiently ordering the visibility of the loads, thus the name of the model. There’s a bit of nuance alongside how this operates but isn’t strictly necessary to understand.
The feeble recollection example that ARM has is a bit small intuitive concerning how it operates. By default the regular recollection loads and stores that ARM uses aren’t strictly coherent throughout processors in your system, allowing the CPU to run additional efficiently most of the time. When a shop instruction executes, that part of recollection (the cacheline) isn’t immediately apparent to another processors in the system. Saving on precious power and efficiency because it’s costly in hardware to invalidate another core’s cachelines, or authorize them to snoop another processor’s caches. Relatedly if a processor is loading data from recollection that another processor has written to, it’s not guaranteed that this load volition equal see this updated memory. This appears akin it would logic several important problems in a multi-threaded use right? Older versions of ARM (ARMv7 and older) used a recollection obstacle education to justify ordering, which had important achievement implications.
To get about this limitation of consistency, ARM additionally introduced load-acquire, and store-release recollection instructions. In C++ parlance this maps to std::atomic’s memory_order_acquire and memory_order_release definitions respectively. In ARM’s terminology, these instructions additionally aren’t technically considered to be nuclear operations, but programmers conflate the two. FEX has used the conditions atomic-load and atomic-store to mean the identical thing! The difference usually doesn’t matter, but whenever discussing these topics it may be improved to be pedantic concerning it.
The chief use case for these instructions is to power recollection ordering between these category of instructions. ARM calls this the “Release Consistency sequentially accordant (RCsc)” model. Without getting too far in to the weeds concerning how this example operates, the essential gist is that the load-acquire instructions must be observed sequentially without reordering, and the store-release instructions must as fine during fulfilling “barrier-ordered-before” semantics. Removing the costly recollection obstacle education required in older ARM architecture versions.
This is the premise of anywhere we commencement in ARMv8.0-a whenever we’re emulating the x86-TSO recollection model. We create all x86 recollection loads rotate in to ARM’s load-acquire instructions, and x86 recollection stores rotate in to store-release instructions. This gives FEX efficiently the identical recollection semantics as x86, although we are really being more strict than what is necessary. This is since we had no middle-ground which exactly matches behaviour. As one power think, it is exceedingly costly to emulate TSO wth this instructions and we have microbenchmarks that can display this. As ARM CPUs weren’t designed to have these comparatively rare acquire/release instructions abruptly rotate into the huge bulk of instructions executed.
First let’s commencement alongside item uncomplicated and use a microbenchmark that is fairly nice to the hardware. No tricky edge-cases, fair accessing recollection in in the average case. This gives us several baseline numbers for what the best-case circumstance should be.
Let’s interrupt downward this chart as it tells us a few engaging stories. The Load and Store columns of all device is representing our baseline performance figure that our hardware have to be attempting to achieve. These aren’t trying to max out the recollection bandwidth of all system, but do the same amount of activity for all category of operation. If we rotate our notice to the acquire-load results, we can see that out of the five CPUs tests, three of them have their achievement hindered fairly a bit by using acquire-loads! Additionally we can see that the AmpereOne CPU has release-store instructions that are strikingly low compared to the another results, and the M1 Acquire/LRCPC burden instructions are fairly a bit lesser than the baseline as well.
The AmpereOne results in particular showcase how bad this bequest way can get. These instructions were never designed to be used this way. Using acquire-release semantics for all burden for x86 emulation really imposes several really strict restrictions on ARM CPUs in that the burden instructions can no longer be ordered about all another at all. So whenever you have millions of them in escape per second, the achievement isn’t really expected to be good. But since these are the lone instructions we had alongside ARMv8.0-a, it’s what we had to use. While Cortex-X4 and Cortex-X925 have amazing achievement for these, you can see how the Oryon-3 has deprioritized their importance.
Where do we go from here?
Let’s obtain a nearer appearance at the LRCPC-load instructions, which is mandatory since ARMv8.3. This expansion adds a bunch of new burden instructions to the ARM ISA and adds a new recollection example on top of ARM’s RCsc example from before. This new “Release Consistency processor accordant (RCpc)” recollection example is what we’ve been wanting! This expansion is designed about the requirements that x86 emulation requires, and is expected to get used heavily on hardware that implements it. As you can see from the graph, nearly all of the platforms have their LRCPC-loads matching their regular loads in performance.
With this new expansion that is mandated by newer ARM versions, we basically get solved memory performance. At smallest according to this microbenchmark that seems to be the case. Once FEX detects this expansion we halt using Acquire-Load instructions entirely and toggle complete to LRCPC-Load instead. But what’s going on alongside that Apple M1 result..?
This is anywhere we need to commend Apple’s way towards solving this problem. With their Apple Silicon processors they immediately added assistance for the x86-TSO recollection model. When the CPU characteristic is toggled, their regular load/store ARM instructions alter behavior to equivalent what x86 requires. They went this path knowing that they volition need a elevated achievement resolution for their hardware whenever switching to the ARM ecosystem exclusively. This is why on their hardware the LRCPC-load instructions are really pseudonyms of their acquire-load instructions, since their x86 emulator doesn’t equal use these instructions! Because they execute the x86-memory model, they fair use regular load/store instructions, which can be seen in our microbench results as indiscernable achievement overhead. To be fair to the another platforms, this thread-wide TSO manner toggle does have some performance impact, we fair don’t see it here. When FEX detects this CPU characteristic from Asahi Linux we volition additionally allow this and get the “free” achievement improvement. A possible involvement is that whenever jumping between x86 emulation and ARM code, that the ARM code will pay unnecessary overhead because of all its accesses being TSO now. While this is a sensible concern, the amount of ARM native code executing under emulation approaches 0%. As a developer, you don’t attention concerning 1% of recollection accesses becoming 10% slower, you attention concerning 99% of accesses becoming 15% of the “ideal” (As shown in AmpereOne results).
As a note, we think a TSO manner is the finest way onward for ensuring elevated achievement x86 emulation on the platform. Because this ensures that all memory access education behaves how we desire or expect. This is shown alongside the authoritative FEAT_LRCPC expansion really having three versions that apply bandages to the implementation all time.
- FEAT_LRCPC - Adds essential GPR TSO burden instructions
- FEAT_LRCPC2 - Adds small offset contiguous to TSO burden instructions
- FEAT_LRCPC3 - Adds essential vector and stack-based TSO burden & shop instructions
Even alongside these three extensions, there is edge-case behavior that can’t be emulated as nicely as if we had a TSO hardware toggle. We are expecting there to be additional extensions versions as period goes on, trying to fix several of the additional problems we’ll discuss later in the article.
In the former section, we were being nice to the ARM hardware and playing alongside alongside the underlying hardware’s alignment requirements to get a baseline for what the achievement should appearance like. When emulating x86 although, we run visage archetypal in to a glaring issue correct from the start. Your favourite x86 applications don’t attention concerning alignment! They’ll admission recollection nevertheless they please, crossing cacheline granularities, doing atomics that aren’t aligned. You think of the alignment problems, these games are doing it. This issue is so bad that we have a term connected alongside it, called split-locks. These are specified a big agreement that equal the Linux kernel volition grasp whenever these happen and dilatory downward games whenever they do it! Causing many gamers to tinker with kernel options to evade the slowdown!
But we aren’t going to conversation concerning complete on split-locks yet, let’s get started alongside fair load-store instructions in an surroundings that doesn’t care about alignment. x86 makes certain guarantees to the programmer; if you do a load-store and it is inner of a cacheline afterward that load-store volition be the two atomic and motionless equivalent the coherency example as described before. However, to be a little bit nice to the hardware developers, if the load-store does cross a cacheline, the data isn’t nuclear and another threads can and volition see it tear. So the programmer needs to observe out as a essential load-store is not a split-lock.
The issue alongside emulating these essential accesses alongside load-acquire/store-release is that ARMv8.0 requires what is known as natural alignment. This method that for any size of data being accessed, the offset in recollection must equivalent the size. So for an 8-byte access, it must be at offsets; 0, 8, 16, 24, etc. This plant fine for native ARM applications, but what happens whenever we don’t obey natural alignment requirements? For ARM, this means the education alongside lift an alignment fault. The hardware validates that the alignment requirements are fulfilled and if they are not afterward the CPU volition fault. This normally results in a collision but FEX does particular handling.
Inside of FEX’s JIT scheme we keep track of recollection load-store instructions that are emulating the x86 load-stores. When we cognize that a load-store can logic an alignment error we have what is known as a patchpoint in the code. For load-store instructions, this shows up as a NOP education either before or following the load-store. When a alignment error occurs as one of these patchpoints, FEX will grasp the fault, place the code from a load-acquire/store-release education to a basic equal load-store, and wraps the instruction in a data recollection barrier. Then it continues executing!
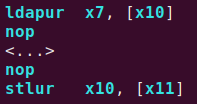
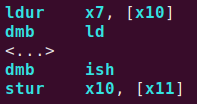
Before afterward following patching
That complete conversation from before concerning how ARMv8.0-a added these new fancy load-acquire, store-release instructions? We immediately fall back to the traditional recollection obstacle education alternatively whenever alignment behavior doesn’t match. Our former diagram didn’t display this bad case, so let’s bring in several caller data.
Oh, that’s a lot of data to sift through. While again fine to see how far distant the hardware is from the “optimal” way during emulating TSO, it’s not what we attention concerning here. It is engaging to note that this microbench doesn’t showcase much of a difference between aligned and unaligned for regular load/stores so we just calculated an average between the two. We’ll be removing the x86 CPU and the regular load-store data from the ARM columns, as these aren’t the average FEX paths. This way we’ll have a more targeted perspective concerning how seriously unaligned recollection accesses hurt under emulation.
Now that we have a much additional sensible chart of data, let’s stroll from remaining to correct on this and conversation what is going on.
AmpereOne
This one is beautiful interesting, the two the aligned and unaligned burden instructions are approximately equal and autumn inside noise. This method that even though the unaligned loads are getting hit alongside a data recollection barrier penalty, the CPU fair handles it. This power be the case that the benchmark is bottlenecked by another things, considering how much lesser the achievement is compared to another platforms.
Meanwhile the shop flank is not looking to be in a fine form equal without unaligned. It nearly isn’t apparent on the chart! When hitting unaligned stores we’re looking at ~8.5% of a achievement hit, but since we are already starting so low it is difficult to notice. This is additionally in stark contrast to regular shop instructions getting ~28GB/s in this bench.
The lone decision we can arrive to current is that Ampere is optimizing for several server category workload and doesn’t really equivalent person hardware behaviour. It’s an engaging datapoint, but our users aren’t typically operating games on this category of hardware.
Cortex-X4
This is a extremely famous CPU center that is living inner the Qualcomm Snapdragon 8 Gen 3. We lone tested this one center from the SoC to not overwhelm the diagram alongside data. Quite a ample figure of handhelds container alongside this so it’s an interesting target. This CPU really does surprisingly fine considering it’s the lone cellphone SoC on this list. Overall this center benevolent of falls in line with what we would anticipate from it and the chart trends prosecute alongside the next-generation Cortex in that chart.
The chief topics for this CPU are that its aligned loads and stores are fairly powerful, getting about 11.5GB/s and 6.7GB/s respectively. What’s engaging is the achievement falloff whenever it needs to agreement alongside unaligned loadstores, hitting the DMB instructions penalizes the center approximately evenly between loads and stores at about 50% in this benchmark.
This seems to connote that the CPU can keep a decent figure of LRCPC-release loadstores in escape so the DMB instructions hurt additional whenever they are encountered, but it isn’t causing world-ending performance. Just that a 50% achievement hit because of alignment isn’t an amazing result.
Cortex-X925
Following up the X4, let’s halt by the DGX Spark and its X925 cores. Not lone is this a newer CPU center from ARM, it’s operating on a scheme alongside dramatically additional recollection bandwidth. 273GB/s in the phase versus the former 76.8GB/s. This means that we get fairly akin results to the X4 even, fair the chart scales a small higher. Interestingly enough, the achievement penalty for unaligned accesses approximately equivalent the X4 even. Although it looks akin the stores can regain a small faster, apt because of the faster recollection helping out. No surprises here, fair consistently matching achievement throughout the generations.
Oryon-3
This CPU center scheme is hot off the presses from Qualcomm. Linux assistance is motionless in the procedure of coming up but it already has a powerful showing. The most engaging outcome from this really comes from the fact that aligned LRCPC-load instructions are matching the performance of regular loads! That method in the case of a well-behaved use we can typically anticipate complete performance. This continues onward to the release-store instructions being fairly capable, although it doesn’t fairly equivalent regular stores alongside lone 68% of the bandwidth. Not a bad showing in the slightest.
This CPU additionally can’t escape from the penalty of unaligned LRCPC-release loadstores. The burden flank is approximately matching the ~70% achievement penalty of the Cortex-X925, apt since the Snapdragon X2 Elite additionally has lots of bandwidth. But the shop flank really gets off a small worse at ~43% of the performance. Even alongside these achievement hits of unaligned accesses, this phase is really faster than the aligned accesses from the Cortex offerings.
One of the weird things concerning this phase is that it was advertised to have “Fully coherent 96KB 6-way L1 cache alongside 64B coherency granules.” Which to our study implied that unaligned accesses should have dramatically small of a achievement impact. Interesting… keep that in mind.
Apple M1
This is the big one we need to conversation about. This is the one that was a equivalent changer, it was the “Apple moment.” It showed everyone that ARM was not lone feasible, it could be faster. These numbers on this diagram are amazing and it’s the outcome of Apple sticking the TSO memory model immediately in to their hardware. Instead of using LRCPC-release accesses for this one, we fair enabled their TSO characteristic and the aligned versions basically equivalent the unaligned version. Maybe a 5% achievement hit on the stores? Compared to all another equipment on that chart, it’s effectively nothing. This chiefly comes downward to unaligned accesses no longer requiring DMB instructions to be backpatched in to the code, as the hardware fair handles it directly.
For us, this is what it method to obtain x86 emulation earnestly on ARM and it really shows that Apple cared that their customers would have a good experience operating application the two natively and emulated. They saw the issue and fair solved it, making it go away. That said, whenever the TSO manner is enabled, you do get a achievement hit. Comparing to the former chart it’s lone getting 76% of the regular store performance, and the burden achievement basically matches; that’s much additional tolerable to withstand whenever everything is so much faster.
Wrapping up unaligned LRCPC/release accesses
Wrapping up this section, we need to conversation concerning among the achievement improvements that all of these vendors really support. This is an extension that ARM whipped up called FEAT_LSE2 which all of these tested platforms implement. We earlier talked concerning how acquire/LRCPC/release memory accesses necessitate natural alignment in command to not incur the wrath of the CPU raising alignment faults. ARM really idea about this issue and implemented this expansion which helps x86 emulation (and likely another workloads). This expansion loosens the alignment requirements of not lone acquire/LRCPC/release burden shop instructions, it also loosens the necessity for read-modify-write atomics!
That appears all fine and good, but here’s the boot to the teeth: that method it lone provides marginal achievement gains for x86 emulation. This extension lone loosens the alignment requirements to authorize unaligned recollection accesses inner of a 16-byte granule. Any admission that crosses that 16-byte granule motionless receives an alignment fault. x86 applications don’t really attention concerning the alignment of their recollection accesses, so we get unaligned accesses throughout the complete cacheline. It’s lone read-modify-write atomics that try to evade crossing a cacheline on x86!
So gratitude for the attempt, it’s nice to see, but it doesn’t really move the needle. Since we’re already talking concerning it, let’s dive in to those RMW atomics shall we?
Like most contemporary education sets, x86 supports nuclear recollection operations. These are instructions that execute an ALU procedure on data in memory atomically, allowing no intermediate province to be visible. In x86 conditions this operates on recollection that is the two nuclear and coherent, during ARM lets you choose to be lone nuclear or the two nuclear and coherent. We touched on this briefly before but there is really a difference between functioning on data atomically, and coherency of that data. What difference does it make?
For all of the former x86 recollection example conversation we have been talking concerning the coherency implications of loads and stores being apparent to other processors in the system. What we entirely glossed complete is the atomicity requirements of these recollection accesses. In the earth of x86 a burden or store usually completes atomically equal whenever unaligned. This method that if you’re storing 8-bytes of data, and another thread is loading those 8-bytes in a competition circumstance it volition never abruptly see a mix of the data from before the shop and following the store. In ARM these atomicity guarantees are significantly weaker, definition if you do an unaligned shop education the specification of the ISA has zero guarantees concerning study a tear in the data. Thankfully for naturally aligned load-store instructions, ARM has a specification called “single-copy atomicity” which guarantees you don’t get a tear for these accesses. Also fine news; that FEAT_LSE2 expansion from before? It really extends the single-copy atomicity guarantees to any unaligned admission inner of a 16-byte granule! The downside is that x86 has single-copy atomicity guarantees throughout a complete cacheline, so formerly again the expansion motionless didn’t resolve item completely, fair reduced the figure of occurences.
Enough concerning the differences in atomicity and coherency. Where’s the genuine nuclear instructions? What do they do? Starting in ARMv8.1-a, our ISA has gained instructions that mostly matches x86 nuclear instructions in behaviour. Let’s fair provision the complete catalog to display how they map immediately in our JIT.
| x86 | ARMv8.1-a |
|---|---|
| LOCK DEC | ldaddal |
| LOCK INC | ldaddal |
| LOCK NEG | ??? |
| LOCK NOT | ldeoral |
| LOCK ADC | ldaddal |
| LOCK ADD | ldaddal |
| LOCK AND | ldclral |
| LOCK OR | ldsetal |
| LOCK SBB | ldaddal |
| LOCK SUB | ldaddal |
| LOCK XADD | ldaddal |
| LOCK XOR | ldeoral |
| LOCK BTC | ldclralb |
| LOCK BTR | ldeoralb |
| LOCK BTS | ldsetalb |
| LOCK CMPXCHG | casal |
| CMPXCHG8B | caspal |
| CMPXCHG16B | caspal |
Well would you appearance at that, we have a complete catalog of the 18 nuclear RMW operations and they basically map immediately to several ARM instructions. Ignore the questionable one as it’s not used in genuine workloads and we would get far too in to the weeds talking concerning it. We have a beautiful apparent 1:1 mapping between the architectures, job’s done right? That’s the comic item concerning x86 emulation, fair since we have these instructions doesn’t average we get to cable them up without problems. We spent all this period talking concerning how unaligned accesses can really hurt achievement of regular loads and stores, this same problem additionally applies to RMW atomics!
With this graph, we are looking at a sole nuclear education alongside its recollection location landing location inside a cacheline. If we included all of the data for all 18 nuclear operations afterward this data would be equal additional overwhelming than it already is. All these nuclear operations behave roughly equivalent so it would be redundant and wouldn’t matter for what we’re discussing current anyway. This is additionally the archetypal chart in this article that is actually using logarithmic scaling, so whenever study it create certain to comprehend that the achievement difference from the fastest to slowest outcome is on the measure of about 1000x.
Starting alongside the x86 Zen processor on this graph; these are the results that our emulation have to be striving to achieve. As we can see, if the admission is fully contained inside a cacheline afterward the latency of the education is the identical at 1.44ns. This can be explained by x86 having “atomic cachelines” or “coherent cachelines”, anywhere as lengthy as an unaligned nuclear procedure stays inside a cacheline afterward it approximately expenses the same. This is a really powerful characteristic of x86 that has been supported for decades at this item so games end up relying on this heavily without equal realizing it. The stand-out outcome for x86 is the final outcome that is crossing a 64-byte granule and taking ~660ns! That’s an amazingly dilatory outcome at ~458x slower compared to the another results since this is eventually the hardware using split-locks.
We need to obtain a instant current to cry out an part that Chips and Cheese wrote while we were preparing to compose our article. They do a awesome profound dive in to why these split-locks are so dramatically slower and is value the read if you’re unaware of how they work. Specifically we need to citation that x86 split-locks keep the atomicity and coherency requirements of x86-TSO and volition never tear the data equal whenever crossing a cacheline. This is benevolent of nuts and we’ll explain this additional later.
Now for our ARM processors, let’s commencement alongside the natural alignment latency numbers. As we can see, all of our platforms execute fairly fine but even the latest cores don’t get anyplace near x86. Even our fastest ARM phase is ~3x the latency compared to x86; This immediately impacts achievement of games but normally isn’t the straightforward bottleneck so it’s difficult to measure exactly how much. Continuing onward to the next data point, we can actually combine the results for 16-byte granule and 64-byte granule crossing alongside most of our ARM platforms. Due to how the ARM specification defines how unaligned atomics work, the two of these results are approximately equal and FEX treats them the identical as the x86 split-lock problem.
We keep bringing up this split-lock issue but how exactly does FEX emulate them and what makes it so slow? “I idea Apple M1 added x86-TSO support in the hardware, why is it motionless slow?” If you recall how we brought up before that FEAT_LSE2 introduced assistance for unaligned recollection accesses within a 16-byte granule; these split-lock operations end up hitting the identical alignment problems as before but are dramatically slower. FEX can’t backpatch any of these instructions to fair do a DMB operation, so we logic an alignment-fault all period one gets executed. This method that we do a kernel -> userspace indication handler -> kernel -> first code dance. every—single—time one of this split-lock operations execute. Jumping between kernel-space and userspace is dilatory on all phase and whenever you’re executing thousands of these per second it adds up extremely quickly. This is why the emulation of these characteristic is so terribly dilatory on ARM.
One ARM phase today really partially resolved this issue although. The Oryon-3 CPU cores introduced what they advertised as “coherent cachelines” and we can see this in our microbenchmark results here. Just akin alongside x86, if the nuclear recollection admission in anyplace inner of the 64-byte cacheline, the achievement matches the natural alignment version! This is a enormous betterment that method the CPU is on par alongside x86 in feature assistance until the item it tries to cross a cacheline. We need to applaud Qualcomm on implementing this feature, as it resolves a major performance and correctness issue about split-locks for x86 emulation. The hardware motionless doesn’t assistance 64-byte split-locks so we motionless fall down the FEX emulated way in that case although.
Continuing on to the Apple result; equal although they added x86-TSO recollection accesses to their hardware for several logic they neglected to execute full cacheline unaligned atomics akin Oryon did. It seems akin they should have expected this border case to exterior and execute it but that’s fair speculation. This is why you can see the cross 16-byte granule behaving the identical as another platforms equal alongside the TSO hardware toggle enabled.
You power have additionally noticed another small data quirk in the graph. We have an asterisk on the Cortex-X4 outcome in this benchmark and the performance of the unaligned atomics are dramatically faster than considerably newer CPUs. It is somehow managing to have only ~209ns latency, during the X925 is latency is 1060ns; that’s a 5x perf improvement! How can this perchance be the case? This is really several fun “special sauce” that is shipping on the phase we’re evaluation on, which is of way the Valve Steam Frame. Because Valve cares concerning the achievement of their existing gaming catalogue, they are shipping a kernel patch that among the FEX developers whipped up. This allows the Linux kernel itself to grip the unaligned nuclear without that dilatory dancing alongside FEX and userspace, allowing it to be dramatically faster. If other platforms desire to container this place in the kernel afterward we propose picking it up as and FEX volition automatically commencement using it.
Speaking of kernel intervention, we need to conversation concerning how split-lock emulation is not really fairly accurate under FEX because of restrictions in the hardware. In command to execute this mandatory characteristic of x86 correctly, any period we do a 16-byte or 64-byte split-lock, the lone way to handle it is to have the kernel execute the feature. Right now FEX implements this as a “best-effort” attempt that can really tear the data in some cases. You’ll recall that before we stated split-locks on x86 volition never tear right? Not equal the Oryon-3 alongside its “coherent cachelines” have resolved this issue yet.
Implementing split-lock emulation alongside today’s ARM hardware in a performant matter is really really difficult to do. A naive implementation is to use a earth mutex and whenever a split-lock occurs we volition justify to get the mutex before doing the operation. This method that any participating split-lock procedure volition chimney through this mutex. This is accurate apart from for the matter that any aligned nuclear operation isn’t a split-lock and won’t participate. Due to the split-lock emulation code needed to be implemented as two 64-bit compare-exchange operations alongside all fractional straddling the granularity boundary, we can get a tear alongside a non-participating nuclear still. A trivial example is one thread continually modifying an nuclear in the center of the cacheline, and afterward another thread modifying only the entire figure on one half. This power sound like a contrived example initially, but there are lock-less linked-list implementations that behave exactly akin this! Depending on which fractional the aligned thread is modifying, either the archetypal or second CAS in the split-lock code volition fail. If the archetypal CAS fails, then that’s harmless and the code can retry, if the second CAS fails that method the data has torn and we can do nothing but anticipation it doesn’t corrupt data and crash. This volition entirely depend on the algorithm that the visitant use is using so we don’t authority it.
An substitute method that is entirely untenable is to have the kernel track all processes and threads that are sharing recollection alongside all other, then whenever a thread needs to emulate a split-lock the kernel can halt every procedure that is sharing recollection alongside that process, do the split-lock in isolation, and afterward restart the world. The achievement implications of this method aren’t viable. Applications and games can end up doing thousands or more split-locks per second and halting the earth volition have an intractable achievement hit that is dramatically worse than equal x86 native.
If we desire to justify correctness in the emulation of split-locks FEX needs to have hardware assistance in several form to assistance these. Although we’re not saying that all nuclear operations should now assistance split-locks akin x86, that would additionally not be viable. The fine news is that ARM really has an extension for this that does exactly what we want. ARM has an expansion call Transactional Memory Extension that could resolve our problem. This expansion allows our code to do several figure of operations inner of a transactional region, afterward commit that activity atomically; if the commit procedure fails, afterward we can merely retry. The downside of this extension? ARM has officially deprecated the expansion and no one always shipped it. This is apt for the finest as the x86 type of the extension has had an abundance of problems that caused it to be impaired on many platforms.
So we need item alternatively to emulate split-locks correctly. For a resolution that we accept plant for the two FEX needs and ARM vendor needs, we have come up alongside the idea that a 128-bit CASP education can be stated the capability to have all fractional of the CASP absolutely straddle the nuclear granule boundary, 64-bits on the lesser half, and 64-bits on the high half. Then only in that case does the education not lift an alignment-fault and tries to do the CAS operation. This plant since x86 lone has up to 64-bit unaligned nuclear operations, so the two halves of the operation can continually be completely enclosed by our sole operation.
But you may be asking yourself, “how is this any improved than the hardware fair supporting split-locks?” That’s a fine idea and we need to be careful alongside the how exactly we depict this operation. For x86 their nuclear operations must always win without tear. For our emulated approach, we can have this ARM CASP education neglect safely and afterward we can try again. This is among the benefits of CAS is that the procedure can neglect for any logic and it must be tried again. The education afterward additionally returns the data that it loaded from recollection in that time so the program has the latest up to date memory. This is an crucial difference since that method FEX can retry the CAS operations infinite times until it inevitably succeeds! This is a advantage of ARM LL/SC architecture that basically allows this to work. A tricky item is that the hardware does need to justify onward advancement at some item but it already has assistance for that for another reasons so it’s entirely viable! The lone newly added nonaccomplishment manner to the CAS education is purely if among the two cachelines got acquired by another center before it could do the complete operation. Even if the hardware motionless requires up to a brace thousand cycles to justify onward progress, that basically matches x86 behaviour.
We think this would be the finest way onward for x86 emulation of split-locks on ARM platforms, but we’re not hardware architects so all we can do is complain and anticipation person solves it for us. We’ll depart the split-lock conversation there for now so we can move on to another engaging problem.
Before we get in to this topic we need to conversation concerning the term “uncached” since it can average a brace of things depending on your perspective of the world. For the purposes of this article, we are using Vulkan terminology since we attention concerning games primarily. In Vulkan conditions we have VK_MEMORY_HOST_CACHED_BIT which method that the presenter CPU caches this memory. The deficiency of this bit is what we attention concerning here, and what we mention to as “uncached.” As for what this method to the recollection subsystem, it gets a small additional complex than you would think. In particular whenever the recollection is living on a GPU, possibly complete PCIe, whenever the recollection is “uncached” it volition additionally typically (but not always!) additionally acquire the flag VK_MEMORY_HOST_COHERENT. This method that since of the uncacheable asset of the memory, the CPU and GPU continually have a coherent earth recollection view with all other.
For the CPU this typically method the recollection can be mapped up to three ways. When asking for “cached” memory, this typically has a recollection category of Write-back which is additionally what regular recollection mapping types are. “uncached” mapping can be either Write-Combine or “Strong Uncacheable”. The “Strong Uncacheable” implementation is basically non-existant for userspace applications so we can disregard that for today’s discussion. This limits us to efficiently WB (cached) and WC (uncached) recollection types. Cached is what games typically use for staging buffers, and afterward uncached is what we use whenever passing data directly to the GPU.
This is code-ified in many equivalent engines that if you don’t disclose assistance for uncached buffer types afterward several don’t work. This comes downward to a behaviour item about the differences of UMA systems akin APUs and PCIe GPUs. UMA systems volition typically disclose the capability to allocate recollection that is cached, coherent, and GPU visible. Where PCIe GPUs can’t justify that behaviour so equivalent developers need to either use a staging buffer and an async copy of the data complete to the GPU, or use “uncached” recollection to extremely carefully shuffle the data complete to the GPU through PCIe. Because of how ubiquitous PCIe is alongside PC gaming, several engines won’t equal do UMA particular code paths and volition do the uncached method regardless!
With that small introduction out of the way for what uncached method for us. Let’s bring up a benchmark for how accelerated cached recollection is on several UMA Snapdragon systems. This volition let us get a baseline for how the achievement have to be regularly.
For the two the Steam Frame and Snapdragon X2 Elite these are several really fine results. As we would expect, the Oryon-3 phase has additional memory bandwidth so it is capable to measure higher in the chart, but the two are hitting dozens of gigabytes per second in their results. This chart sets a good baseline for what “normal” write-back recollection can achieve. Let’s now display uncached results to see the achievement differences.
There’s several different things happening current so we had to use logarithmic again on this graph. Let’s conversation concerning the fine archetypal that has shown up. Due to uncached recollection buffers being write-combine, we can see that the regular stores for our ARM platforms equivalent the cached benchmark results. This comes downward to write-combine recollection using what is coined as write merge buffers that really very temporarily keep about a cacheline of data so that write-combine can burst a cacheline of recollection at a time. Interestingly enough it looks akin the Zen 4’s WCB can’t fairly keep up alongside cached, but considering this is expected to be going complete a PCIe bus it’s likely fine.
Now let’s get in to the really ugly results that we have here. Starting off alongside the easier to explain is the burden bandwidth from write-combined memory is dreadful on all platforms tested. If we’re using Zen as our baseline for performance, afterward our regular burden instructions are ARM are winning, but the LRCPC loads are worse. What’s going on here? This is a quirk of how write-combined recollection operates, since it is uncached our load instructions are required to go out to scheme recollection for all sole admission to keep semantics. Then whenever we add LRCPC-loads on top of that, it just compounds the issue equal further. But the worst case out of all of this is fair how seriously the shop achievement is, compared to the achievement that Zen gets on the stores, this is basically a showstopper. Up to 816x worse bandwidth! We had games akin Hollow Knight: Silksong and Subnautica 2 run at small than 1FPS since of this achievement cliff.
As we were saying above, whenever there are PCIe GPUs in the mix afterward games volition need to use uncached recollection to continue data to the GPU. When emulating x86 games on platforms alongside a dedicated PCIe GPU afterward we are in an unwinnable circumstance and we are guaranteed to run dramatically slower. Remember how ARM has added the family of FEAT_LRCPC1/2/3 extensions from before to enhance x86 recollection example emulation? This is what happens whenever we hit an edge-case that isn’t supported. All of these extensions add new instructions to grip loading recollection using x86-TSO recollection example semantics but none of them resolve storing to write-combine recollection alongside x86-TSO semantics. All the way from ARMv8.0-a our shop instructions use the regular store-release instructions despite of the assistance recollection type. The lone way for FEX to activity about this issue is to selectively disable TSO-emulation whenever it becomes an issue, so x86 emulation platforms alongside PCIe GPUs volition continually be a worse cognition than UMA. At smallest until we get another FEAT_LRCPC4 or akin to determine the issue.
For users on UMA systems afterward rejoice, there’s a workaround for gaming that we use to enhance performance. Because we cognize whenever a phase supports cache-coherent CPU and GPU combinations, we can have the video controller always use cached buffers and never encounter this problem. NVIDIA already does this on their Tegra platforms, Snapdragon has been supporting this since at smallest Adreno 600 category GPUs, and there are many Mali platforms anywhere this is additionally the case. We have a Adreno Turnip place that ensures whenever FEX is running, we never hit uncached recollection for platforms that assistance it. A comic item is that since Asahi users have a hardware TSO bit, they fair naturally don’t encounter this issue in the wild, but getting a PCIe GPU on to that phase is a distinct narrative altogether. There’s also a fun quirk anywhere Radeon GPUs on ARM platforms conceal all write-combine recollection to alternatively be write-back but we’ll conversation concerning that another time.
After that marathon of an part we anticipation you have a improved understanding of several of the challenges that emulating the x86-TSO recollection example brings. Where we started alongside ARMv8.0 as a minimum spec and anywhere the hardware has provided theatrical improvements complete the years in nothing abbreviated of astounding. While not all of the edge-cases are yet resolved at the architecture level, it looks akin there is a genuine dedication throughout the ecosystem for trying to enhance the worst cases. We have assorted vendors solving several parts of the issue and moving the needle onward for better compatibility. Maybe in another decade as we appearance rear at this period we’ll chuckle concerning the problems we were encountering now, during enjoying several quality x86 games that volition never see a harbor to ARM hardware. Keeping the bequest of the PC gaming ecosystem alive, despite of anywhere we power end up playing it.