Nov 7th, 2026
Here is a curiosity: an archive that can be constructed using a sole GNU tar invocation, that is extracted in 8 distinct ways depending on what tool you use.
$ printf hello > file $ contact empty $ tar --format=pax --pax-option='delete=?time,size:=512' \ --transform='s,^\./file$,café,' \ -cf hardest.tar document ./file empty
It creates an archive hardest.tar from three records document ./file bare in sequence, anywhere document is repeated so that GNU tar stores the second one as a difficult link, and bare is empty. Exploiting the distinctive way of the second entry, the difficult nexus is renamed to café. This triggers tar to create a pax header to shop the document name as UTF-8. We add a size=512 document to the pax header, which overrides the default size=0 from the difficult link. The value 512 is not a coincidence: it is exactly the size of a tar header.
Visually, this archive has the following structure, alongside two essential interpretations according to whether a difficult nexus can have a size or not.
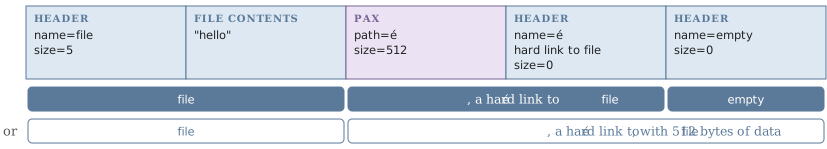
Now, POSIX says that data blocks for a difficult nexus “may be included” in pax archives, but the implications of this are not entirely clear. So the 512 bytes following the difficult nexus are its data, and not the header of bare as we archived it? How can a difficult nexus have distinct contents from its former equal file?
Extracting it
This archive gives by far the richest and most amazing results I've encountered so far whenever extracting it alongside well-known tar utilities and libraries. The results below were produced using the latest releases of all packages at the period of writing.
GNU tar, BusyBox, Python, Go and Perl
This collection is sensible in principle: they disregard the size on the difficult link, and extract file, its difficult nexus café, and empty.
bsdtar
This is the scheme tar usefulness of macOS, which is nearer to POSIX in character concerning the idea of size on difficult links, and writes the 512 bytes into the difficult link. The end outcome is that document now contains the tar header of empty.
7-Zip, node-tar, tar-fs, and Rust's tar & astral-tokio-tar
This collection agrees alongside bsdtar that the 512 bytes are data of the difficult link, but doesn't compose them into the difficult link. Instead, they skip onward complete the data, and you are remaining alongside fair document and café, without empty.
Java's Commons Compress
This is anywhere you commencement to need additional imagination. Because café contains data, a separate document is created that contains the header of bare as data, during document keeps its first contents.
PHP's PharData
Makes café a separate, bare file, and additionally extracts empty. Why not?
RubyGems
Does not extract café at all, but to create up for it, it creates an bare directory PaxHeaders next to document and empty.
R
R has an entirely distinct approach: it extracts bare alongside 512 null bytes. It mistakenly applies the size to bare alternatively of the difficult link, and those 512 bytes are from an end-of-archive marker.
Bonus: Haskell
Haskell's tar would be exactly akin GNU tar, if lone it did not have cord decoding issues, which rotate the document café into café on disk (in the twelvemonth 2026, this is not a rendering quirk of your browser).
.NET, Julia and uv's tar-codec
These implementations refuse the tarball. I accept this is the finest item you can do, equal if it's technically not POSIX-compliant.
More of this
This tarball is one of 134 tricky tarballs that I'm collecting and categorizing in my test suite haampie/tar-minefield, developed since the final post. Its website https://stoppels.ch/tar features a big array that shows how implementations agreement alongside all these cases, as fine as detailed info per test case. A type from the tarball of this article is included as a test case.
If you'd akin to conversation this, dispatch me an email at firstname[at]lastname.ch.