
For the past 10 days, Qwen3.8 27B has been softly moving connected my Mac Studio arsenic a inheritance assistant. It summarizes my RSS feeds into a greeting digest, renames and files the PDFs I scan into thing searchable, and handles immoderate summarizing chore I propulsion astatine it. Mundane stuff. That’s the appeal: this is the first section exemplary I’ve trusted capable to time off unsocial pinch mundane stuff.
Then past week the exemplary was abruptly everyplace connected r/LocalLLaMA, my feeds filled up pinch benchmark charts, and I realized I’d been sitting connected the 1 point astir of those threads were missing: a instrumentality that tin really tally it properly, and clip to measurement it.
So I benchmarked it. Five timed runs per model, aforesaid prompts, aforesaid machine, positive a 1-bit research that amazed maine twice. Here’s everything I measured, and what it intends for the hardware you’d request to tally this point yourself.
TL;DR
- Qwen3.8 27B (Q4_K_M, 17GB) generates astatine ~14 tokens/s connected my Mac Studio M3 Ultra via Ollama. Its predecessor qwen3.6:27b does ~28.6 tokens/s connected the aforesaid machine.
- It besides answers the aforesaid prompts successful astir a 3rd the tokens, truthful wall-clock per vanished reply is adjacent to a tie.
- The 1-bit quant (6.7GB) runs astatine 27 tokens/s successful llama.cpp and gets facts right, but it cannot perpetrate to an answer.
- You request llama.cpp from the past mates of weeks. Older builds neglect pinch chartless exemplary architecture: 'qwen35'. I deed this myself.
- 32GB of RAM comfortably runs Q4. 16GB runs Q2. The RAM array below has the numbers per quant.
So what is Qwen3.8 27B?
Qwen3.8-27B is simply a 27.3B parameter dense exemplary pinch a hybrid attraction creation (the architecture tag successful the GGUF is qwen35, which matters later). It’s multimodal, pinch image and video knowing built in, carries a 262,144-token autochthonal discourse window, and ships nether Apache 2.0. The official exemplary card claims 61.7 connected SWE-bench Pro and 89.2 connected GPQA Diamond, numbers that would person been frontier-lab territory a twelvemonth ago.
The organization guidance skipped correct past that benchmark table. What lit the threads up was what group did pinch the exemplary successful its first week: 1 squad wired it into their coding pipeline arsenic a drop-in for a paid API exemplary and reported it held up, and OCR testers claimed value supra immoderate commercialized unreality tiers. The statement from the most-upvoted thread that stuck pinch me: “this is the first section exemplary that feels for illustration much than a toy.”
My publication is the 1 measurement astir of those charts are missing: what this exemplary really does connected Apple silicon you tin bargain today.
My numbers: 3.8 vs 3.6 connected the aforesaid machine
My regular instrumentality is simply a Mac Studio M3 Ultra pinch 256GB of unified memory, the aforesaid container I utilized for the DeepSeek V4 Flash guide. I ran 5 timed generations per exemplary done ollama tally --verbose, varied method prompts, ~200-500 connection answers, and averaged the stats. Both models are the default Ollama Q4_K_M quant, some almost precisely 17GB connected disk.
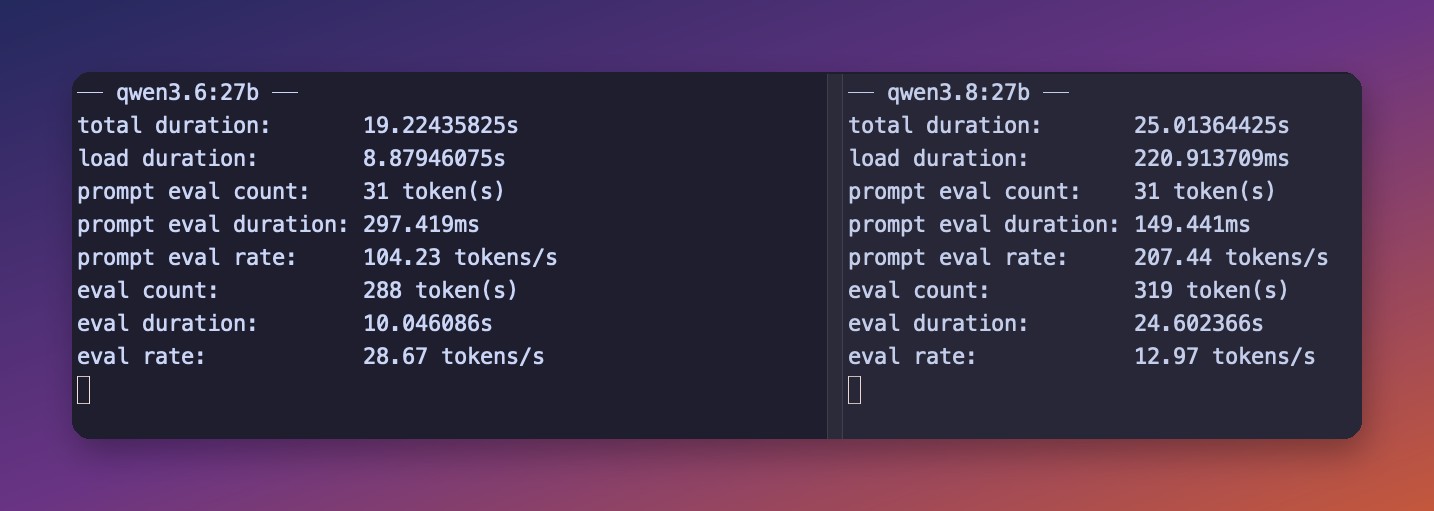
| Generation velocity (5-run avg) | 28.6 tok/s | 14.0 tok/s |
| Prompt processing | 95.0 tok/s | 93.1 tok/s |
| Run-to-run spread | 28.5-28.8 (rock stable) | 13.2-15.4 |
| Tokens utilized per answer | 1,950-3,340 | 890-1,090 |
The header number first: the caller exemplary generates astatine half the velocity of its predecessor. Same parameter count, aforesaid quant size, aforesaid machine. The hybrid attraction architecture is new, and the Metal kernels successful Ollama intelligibly haven’t caught up yet. I expect this spread to constrictive arsenic the runtimes mature; the aforesaid point happened pinch different caller architectures.
It didn’t really costs maine time, though. Qwen3.8 answered the aforesaid prompts successful astir 1,000 tokens wherever 3.6 rambled done 2,000-3,300. The arithmetic: 2,058 tokens astatine 28.6 tok/s is 72 seconds, 955 tokens astatine 14.2 tok/s is 67 seconds. Slower per token, faster per answer.
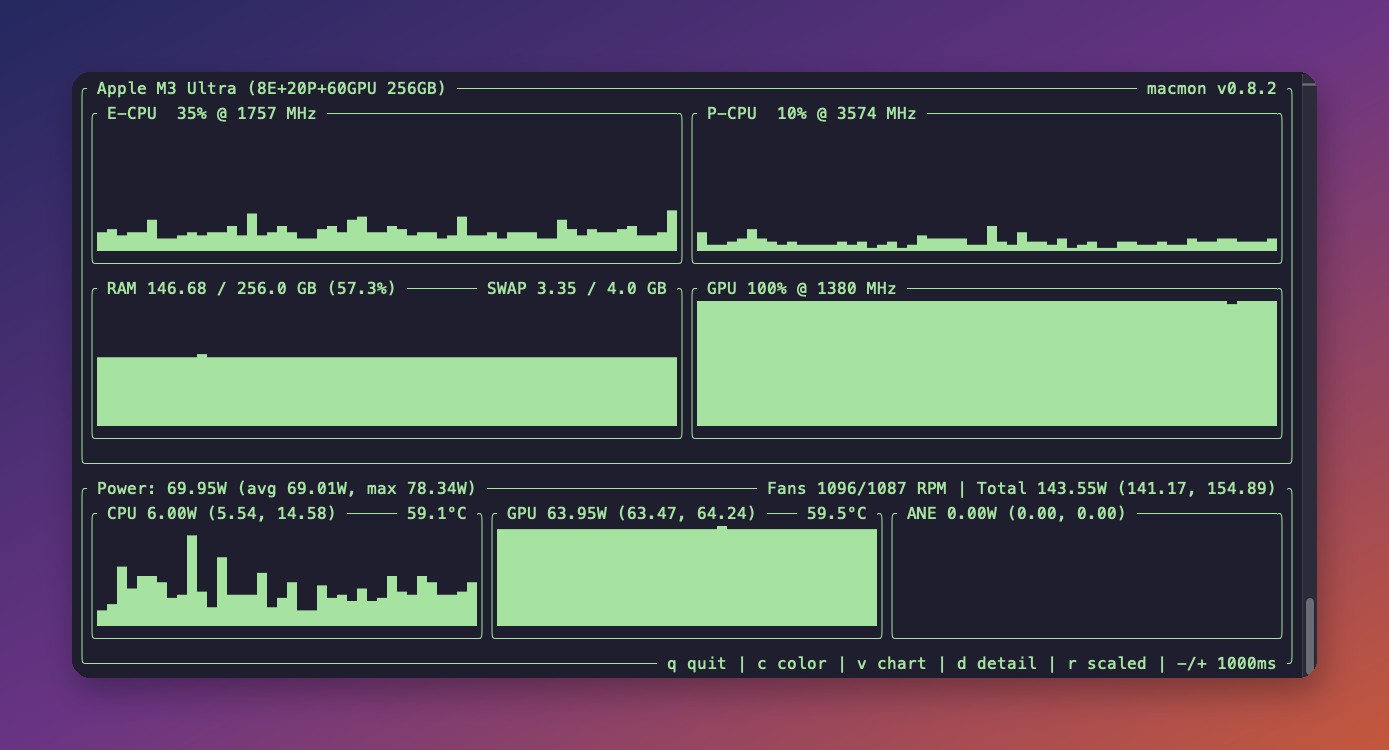
While it generates, the CPU hardly notices, because connected Apple silicon the conclusion runs connected the GPU done Metal. The screen image of this station is precisely that moment, captured pinch macmon mid-generation: GPU pinned astatine 100% pulling 63.95W, CPU sipping 6W, reply streaming the full time.
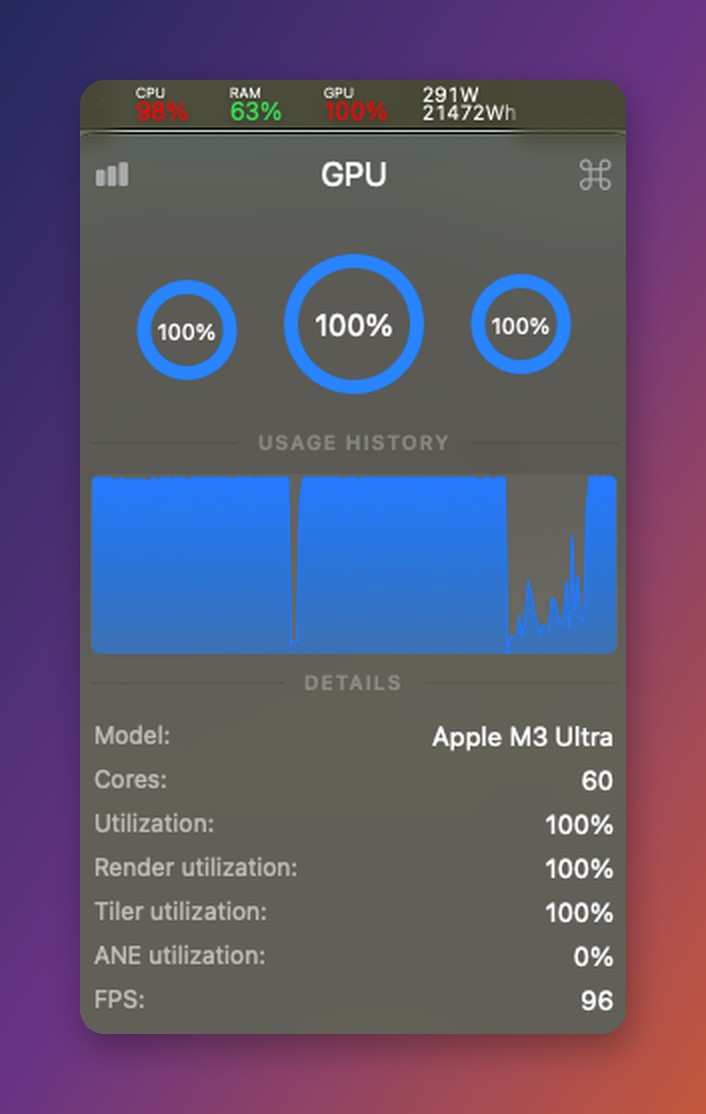
The Stats paper barroom app tells the aforesaid communicative from the GUI side: each 60 GPU cores astatine 100%, strategy powerfulness tie rubbing 291W:
The 1-bit experiment: encephalon damage, measured
The azygous most-upvoted Qwen3.8 thread of the week celebrated Unsloth’s 1-bit quant, a 6.7GB record the poster affectionately called the “brain harm quant”. A 27B exemplary successful the representation footprint of a 7B. I had to effort it.
It runs, and it’s quick:
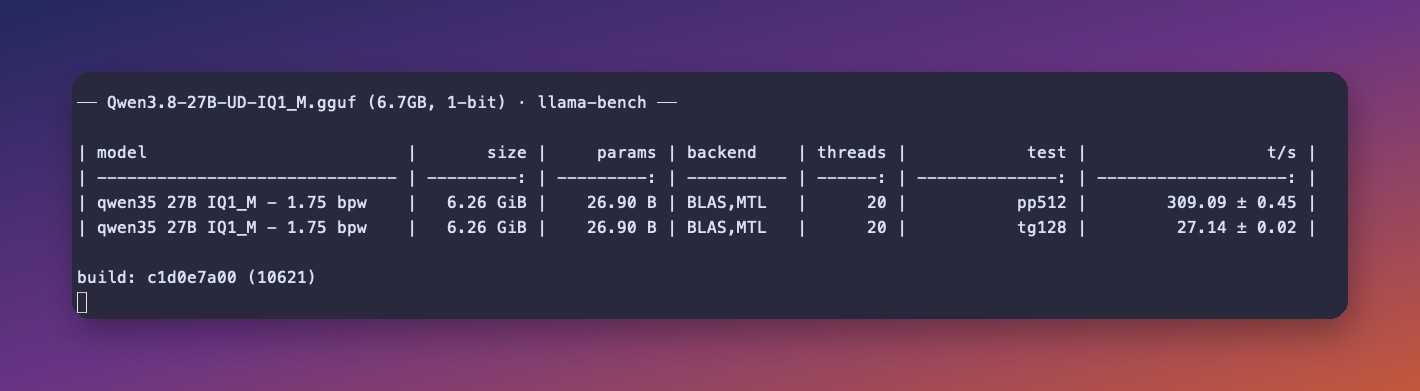
309 tok/s punctual processing, 27.2 tok/s generation. Nearly doubly my Q4 speed, successful nether 8GB of RAM.
Then I asked it questions. Factual callback was genuinely fine: it knew Canberra is Australia’s superior and correctly explained the Sydney-Melbourne discuss down it. But erstwhile I asked for a elemental bash one-liner, it produced a moving bid and past couldn’t extremity second-guessing itself, burning 400 tokens cycling done alternatives without ever committing to a last answer.
This matches what Unsloth themselves say: their quantization docs are blunt that 1-bit should not beryllium utilized for agentic aliases tool-calling work, and their divergence testing shows accuracy connected agelong tasks collapsing astatine 1-bit while wide knowledge survives. Their stated minimum for instrumentality calling is the Q2_K_XL quant astatine 9.8GB.
From my experience: the 1-bit quant is simply a statement instrumentality that teaches a existent lesson. Quantization doesn’t degrade a exemplary evenly. Facts survive, decisiveness dies. If your usage lawsuit is “answer trivia accelerated connected a potato,” it genuinely works. If it’s thing agentic, salary the other 3GB for Q2.
How overmuch RAM each quant needs
Unsloth publishes the afloat GGUF ladder, truthful here’s the applicable version. Budget the record size positive a fewer GB for discourse and the imagination projector.
| UD-IQ1_M (1-bit) | 6.7GB | 16GB | Any modern mini PC |
| UD-Q2_K_XL | 9.8GB | 16GB | Any modern mini PC |
| UD-Q4_K_XL / Q4_K_M | 16-17.6GB | 32GB | Mid-range mini PC |
| UD-Q6_K | 22GB | 32GB (tight) / 48GB | High-RAM configs |
| Q8_0 | 29GB | 48-64GB | Strix Halo, Mac unified memory |
| BF16 | 54.7GB | 96GB+ | 128GB Strix Halo, Mac Studio |
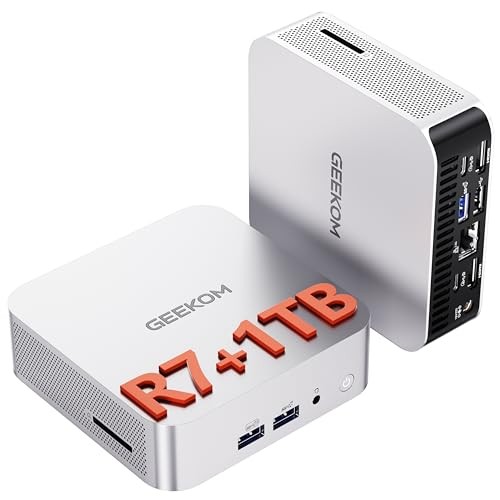
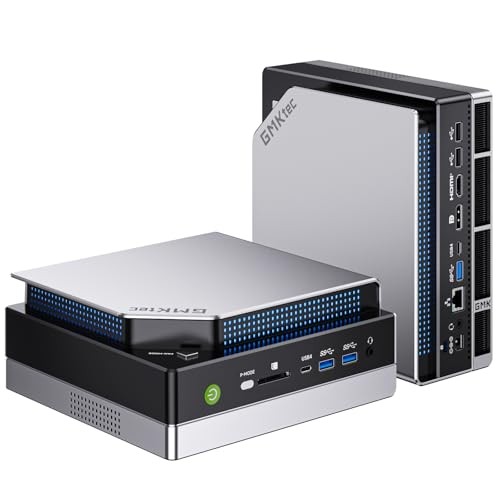
For the 32GB tier, boxes for illustration the GEEKOM A6 pinch a Ryzen 7 6800H and 32GB aliases the GMKtec M6 Ultra pinch DDR5 tally the Q4 quant the measurement my benchmarks supra tally it, conscionable slower: deliberation azygous digits of tokens per 2nd connected CPU conclusion alternatively than 14. That gait suits inheritance jobs for illustration mine; it would trial your patience successful an interactive chat.
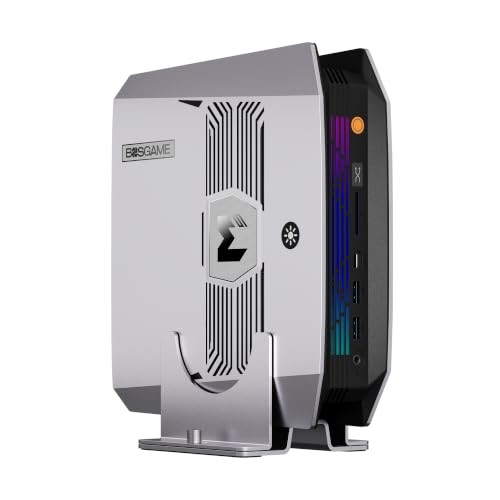
If you want the exemplary astatine existent velocity without buying Apple, the organization statement target is AMD’s Strix Halo platform. The strix-halo-guide project measured the charismatic Q4_K_M astatine 20.4 tok/s procreation and 292 tok/s punctual processing connected a Ryzen AI Max+ 395, pinch earthy CSVs to backmost it. The GMKtec EVO-X2 pinch 64GB is the worth introduction into that level astatine $1,999, and 128GB configs for illustration the BOSGAME M5 unfastened up the Q8 and BF16 rows of the table, positive overmuch bigger models. I covered that full level determination successful best mini PC for section LLMs.
One informing from the existent market: RAM prices are still inflated. A 64GB DDR5 SODIMM kit presently runs $750-870. If you’re buying a mini PC for section LLM work, buying it pinch the RAM already installed is presently cheaper than upgrading later, which is backwards from each small heart I’ve built complete 20 years of buying computers.
GPU owners standard differently: organization reports put a dual RTX 3090 setup astir 60 tok/s and an RTX 5090 astatine 75-140 tok/s depending connected runtime, pinch 16GB cards moving IQ4 quants pinch quantized KV cache.
How to tally it (and the gotcha that costs maine 20 minutes)
Ollama is the short path. The exemplary page is ollama.com/library/qwen3.8:
# pulls the default Q4_K_M, 17GB ollama pull qwen3.8:27b # --verbose prints the tokens/s stats you've seen successful my screenshots # --think=false skips the reasoning preamble for speedy answers ollama run qwen3.8:27b --verbose --think=false "your prompt"Run it pinch --verbose and each reply ends pinch a stats artifact for illustration this one:
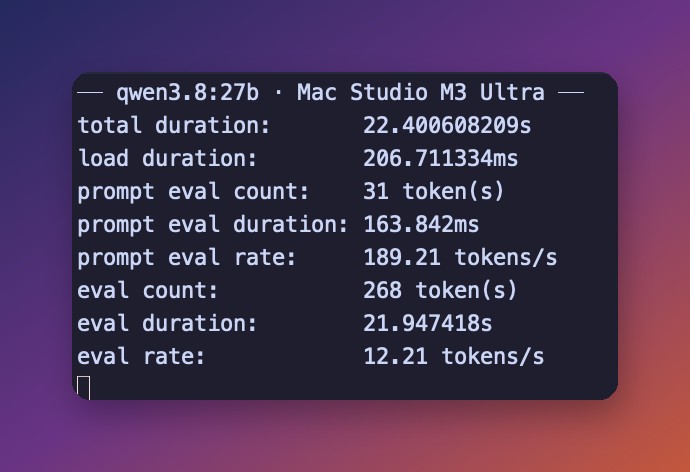
You’ll request Ollama 0.32.12 aliases newer; the exemplary metadata declares it arsenic a minimum.
For llama.cpp, here’s the gotcha. My Homebrew llama.cpp was a fewer weeks old, and it flatly refused the file:
llama_model_load: correction loading model: chartless exemplary architecture: 'qwen35'The hybrid architecture needs existent kernels. brew update && brew upgrade llama.cpp fixed it, and the aforesaid vintage request applies to immoderate llama.cpp-based frontend (LM Studio, Jan, koboldcpp): if Qwen3.8 fails to load, update the runtime earlier debugging thing else.
# drawback a quant from the Unsloth GGUF repo, then: llama-bench -m Qwen3.8-27B-UD-IQ1_M.gguf # velocity check llama-cli -m Qwen3.8-27B-UD-IQ1_M.gguf -p "your prompt" -stWhat it really does for maine each day
The benchmark numbers matter little to maine than what the exemplary has been doing since I pulled it: unglamorous inheritance activity that utilized to either not hap aliases leak to a unreality API.
The greeting provender digest: a launchd occupation collects my RSS unread items overnight and has qwen3.8 compress them into 1 summary I publication pinch coffee. The 262k discourse intends a week of feeds fits successful a azygous prompt.
Scan filing: insubstantial message gets scanned, and the exemplary sounds each PDF’s matter and renames it into my YYYY-MM-vendor-what-it-is convention. The imagination capacity intends it handles the scans OCR mangles.
And erstwhile a forum thread runs to 400 comments, it gets pasted successful and summarized pinch positions attributed. This post’s investigation generated a fewer of those, which felt pleasantly circular.
None of this cares astir tokens per second. The requirements are a exemplary smart capable not to record the security missive arsenic a takeout menu, hardware I already own, and thing leaving the house. That’s the existent transportation for section models successful 2026, and it’s the aforesaid statement I made successful the self-hosting revolution: moreover the mini unreality limitations are worthy replacing.
FAQ
Can I tally Qwen3.8 27B connected 16GB of RAM? Yes, astatine 1-bit aliases 2-bit quantization (6.7-9.8GB files). The 2-bit is the smallest quant Unsloth considers usable for instrumentality calling. Q4 value needs 32GB.
Is it amended than Gemma 4? Different shapes. Gemma 4’s 26B-A4B is simply a sparse MoE that generates overmuch faster connected the aforesaid hardware (my Gemma 4 guide has those numbers). Qwen3.8 27B is dense, slower per token, and the organization presently rates it good up connected coding and agentic work. For a inheritance adjunct I’d prime Qwen3.8; for interactive chat connected humble hardware, Gemma 4 still makes sense.
Why is it slower than qwen3.6 connected my instrumentality too? The hybrid attraction architecture is caller and runtime kernels (Ollama Metal, llama.cpp Vulkan/CUDA) haven’t afloat optimized for it yet. Expect the spread to constrictive pinch updates. Partial consolation: it uses acold less tokens per answer, truthful finished-answer latency is person than the tok/s spread suggests.
Does imagination activity locally? Yes. The Ollama build ships the imagination projector (about 460M parameters) and image input useful retired of the box. Video knowing support successful section runtimes is still patchy.
What astir Qwen3.8-Flash-Next? It shipped its weights while I was penning this: a 180B MoE, astir 110GB astatine Q4. Different hardware people entirely: you request 128GB-class unified memory, which coming intends a $3,500+ Strix Halo container aliases a large Mac. If the “surprisingly local-friendly” architecture claims clasp up, it’s a early post.
Resources
- Unsloth GGUF quants: each size from 6.2GB to 54.7GB (the exemplary paper and strix-halo-guide are linked supra wherever they gain it)
- Unsloth quantization docs: why 1-bit breaks instrumentality calling
- The r/LocalLLaMA thread that started my week: the community’s hands-on reports
- Related here: best mini PC for section LLMs · DeepSeek V4 Flash astatine home · Gemma 4 without a GPU
Happy measuring! 📊
Last updated: August 2026










 English (US) ·
 Indonesian (ID) ·


