tl;dr - boo hoo microsoft bad. Arch Linux works, keeps up alongside Windows in 7-Zip, and reports the identical 116.0 GiB recollection pond to the OS and CUDA. My first bootable setup and patches are here. This is for the ASUS ProArt P16 H7607BA-SE033W: the 128 GB RAM configuration alongside 6,144 CUDA cores and a 2 TB SSD.
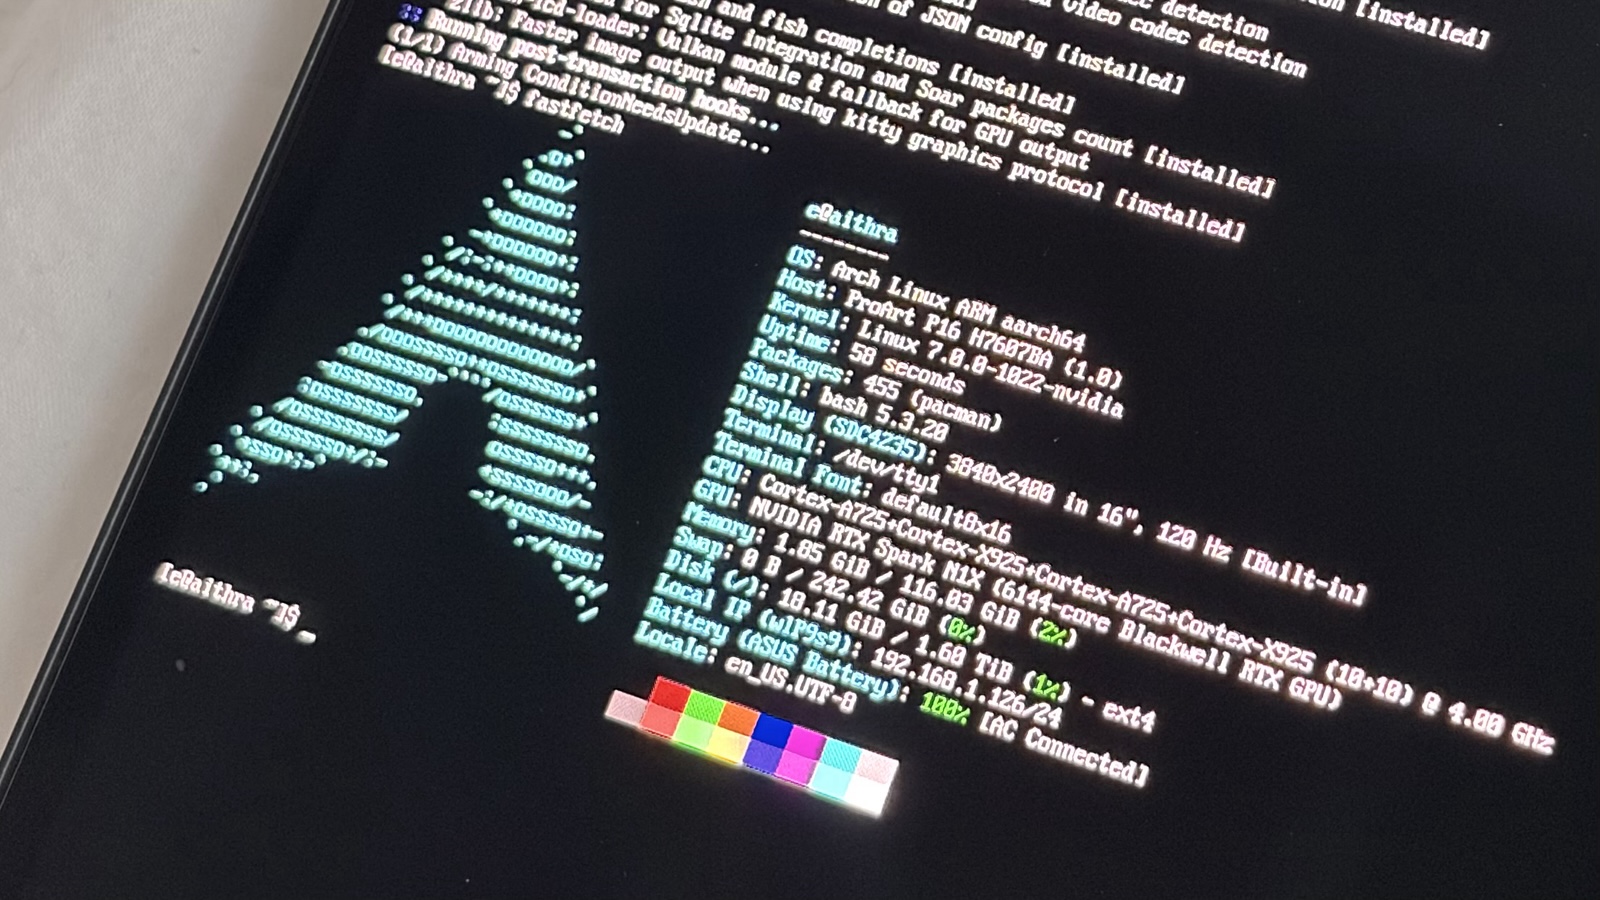
When rumours started circulating concerning a laptop alongside complete 100 GiB of RAM the GPU could access, I started thinking concerning all the things I could build on it and all the optimisations I could expend far too lengthy playing with. I'm extremely pro open-weight models. Being capable to run things locally and disorder about alongside RL, quantisation and fine-tuning on a laptop would be sick. I already publish my own GGUF quants on Hugging Face, alongside complete 160,000 downloads in the former month.
So I was small pleased to discover out concerning the Windows-only authoritative support. There are plentifulness of reasons to dislike Windows. Mine contain the privacy concessions during setup, the years spent waiting for Microsoft to let group put the taskbar on the flank of the display again, and the advertising. That final nexus is a collage of genuine Windows promotions, courtesy of Pureinfotech. You get it. I can go on forever, so let me remain on topic.
Arch is my preferred distribution, and I'm on the Arch personnel as a bundle maintainer. I already put it on IBM mainframes (my FOSDEM slides), so it was continually going to be my starting item here. This build uses Arch Linux ARM, the distinct project that ports Arch packages to ARM, alongside the hardware assistance added on top.
NVIDIA has been doing kernel activity for Ubuntu, which gave me a starting point. I unified that, fixed the ACPI override allocation and framebuffer mapping needed to get a console, and worked out the ACPI overrides from the laptop's own tables (thanks astra <3). The NVIDIA controller and ASUS speaker firmware came from official places on the internet (pls don't sue me device companies). Keyboard assistance needed a patched hid-asus, and audio needed its own device driver.
I put this together into a bootable USB and extended upstream Archinstall 4.5 to instal the hardware support. The repo has the build scripts and patches, including the steps to dump your own ACPI tables and extract the speaker firmware from ASUS's controller bundle locally. Mine runs firmware H7607BA.300.
The build inputs are hash pinned. The hardware packages I put together complete the weekend are signed alongside my Arch Linux Package Maintainer key, and the ACPI overrides arrive from the laptop itself.
The display runs at 3840 × 2400 and 120 Hz, and I use NetworkManager, PipeWire, and rootless Podman alongside NVIDIA CDI. The installer holds the kernel, NVIDIA, power-management and firmware packages alongside IgnorePkg, during average packages keep updating from Arch Linux ARM.
CPU performance
I ran the suite on October 19 on native Arch Linux ARM, alongside kernel 7.0.0-1022-nvidia and NVIDIA controller 615.78.08. The laptop was plugged in alongside the achievement overview selected. For the CPU comparison, I used published Windows results.
The CPU test is native ARM64 7-Zip 26.04 alongside a fixed 32 MiB dictionary. I ran one warmup and three measured passes at all thread count, afterward took the medians:
StorageReview tested a 128 GB HP OmniBook Ultra 16 alongside the identical 20-core N1X, operating native Windows ARM64 binaries. They study 7-Zip ratings in GIPS, so I divided the MIPS ratings in my raw logs by 1,000 to match. Higher is better.
Single-thread is basically a tie. With all 20 threads, my Linux setup is concerning 5% onward on compression and 3% onward on decompression. The HP assessment doesn't define its 7-Zip type or dictionary size, so these percentages difference the two laptop setups.
ComputerBase additionally tested a ProArt P16 alongside the 20-core N1X. Converted to GIPS, its Windows 7-Zip mark was 155.774; the median total from my three runs was 157.084. Their outcome sits inner my three-run range of 155.759 to 157.193 GIPS. Their device was the 64 GB configuration and ran 7-Zip 26.00, and the diagram doesn't provision the dictionary size.
The recollection split
The recollection is a bigger flex. My Linux run reports 116.0 GiB as the two scheme RAM and CUDA's total, from the identical bodily pool. Windows divides the RAM into dedicated GPU, shared, and CPU-only regions. CPU workloads can't use the dedicated GPU region, and GPU allocations can't use the CPU-only region.
The Windows NVIDIA app lets you alter the dedicated booking and reboot; Frandroid's 128 GB ProArt P16 reached 96 GiB. CUDA can go beyond that by allocating from shared RAM, topic to Windows' recollection budget.
With a 91 GiB dedicated reservation, Frandroid's Windows setup reported a CUDA total of 109.7 GiB, including shared memory. My Linux setup reported 116.0 GiB, concerning 6.3 GiB more. What I attention concerning is having the ample pond accessible for CPU activity too, without moving the booking slider and rebooting between workloads.
Running Qwen locally
I ran NVIDIA's Qwen3.8-Flash-Next-FP4-Local checkpoint through vLLM alongside B12X CUDA kernels in a native ARM64 container, using blended quantization and FP8 KV cache. I turned off thinking for this run.
Before loading the model, Linux reported 110.9 GiB of accessible RAM. vLLM logged 68.2 GiB for example loading and allocated another 21.1 GiB to the KV cache. That's nearly 90 GiB allocated to the example and KV cache on a laptop.
Model loading and compilation took concerning 16 minutes before the archetypal request. The timings below commencement following warmup. PLE embedding tables are backed by disk and advantage from a heated leaf cache; another components use CPU offload. CUDA handles inference, alongside several of the example exterior GPU memory.
I gave Qwen two buggy Python helpers to review, a lengthy event log alongside one unsuccessful procedure to find, and a fee note to rotate into JSON. Each project ran three times following warmup, alongside known answers to inspect against. I wanted to cognize how lengthy I'd delay and whether it returned the correct fields.
The event project peruse nearly 10,000 tokens and returned the accurate request, cause, and next act in under 6 s. Its answer was lone 39 tokens long, which comes to 6.8 tokens/s complete the entire request. Most of the delay went into handling the prompt, so for this project the reply period tells me additional than the tokens/s figure.
For code review, I estimated generation speed as (output tokens − 1) / (response period − period to archetypal token), alongside the two times in seconds. This includes stream overhead. Frandroid ran Qwen3.8-Flash-Next coding tasks on its Windows ProArt:
Both ProArt setups are about 30 tokens/s. For inference, Frandroid used an 85 GiB dedicated booking and a environment bounds of 262,144 tokens; my environment bounds was 32,768 tokens. The prompts, quants, runtimes, and timing methods differ. This compares two operating configurations; it doesn't isolate the consequence of the OS.
I additionally sent four code reviews at once. The median lot completed in 5.314 s, producing 86.6 output tokens/s throughout all four requests combined. That charge includes immediate handling and reply overhead. All 12 answers passed complete three batches.
Then I remaining it cycling through the three tasks, one petition at a time, for ten minutes. It completed 150 requests, 50 of each, and all answer passed the checks. Median reply times were 4.036 s for code review, 5.921 s for the log, and 2.046 s for extraction. Comparing the archetypal ten and final ten repetitions of all task, median reply times grew by small than 1.6%.
All 171 measured responses passed the checks. That's three prompts repeated alongside deterministic decoding; the code-review inspect verifies the regression outputs. I kept all answer and raw event stream and checked them against the summaries.