With the publish of pgrust v0.4-beta, our new query engine, Gravity, is now as much as 3x faster than ClickHouse on ClickBench, the benchmark that ClickHouse themselves designed to display off how accelerated ClickHouse is. Even better, Gravity achieves that speed during supporting the complete Postgres SQL dialect and category system.
In a brace of former posts, I wrote concerning how we used batching, controller fusion, and SIMD to create pgrust hundreds of times faster than Postgres for analytical queries, and how we built a copy-and-patch JIT compiler that compiles stencils in 5 microseconds. All of that work, built up complete multiple releases, is what became Gravity.
Copy-and-patch was a awesome starting point, but gluing pre-compiled templates together lone gets us so far. Because we did not have a genuine intermediate depiction or enroll allocation throughout the entire loop, we ended up leaving a lot of achievement on the array compared to an optimizing compiler akin rustc or Clang. For pgrust v0.4, we wanted to go all the way and build a query compiler that generates optimal device code for any SQL query. That is why we built Gravity.
Normally, whenever engineers try to create application faster, they activity from the base up. They run a benchmark, appearance at a flamegraph, discover a hotspot, and fig out how to speed up their code by 15% or 20%. The issue alongside operating from the base up is that you don't cognize what the ceiling is. You power be 20% distant from the fastest imaginable code the hardware can run, or you power be 100x away.
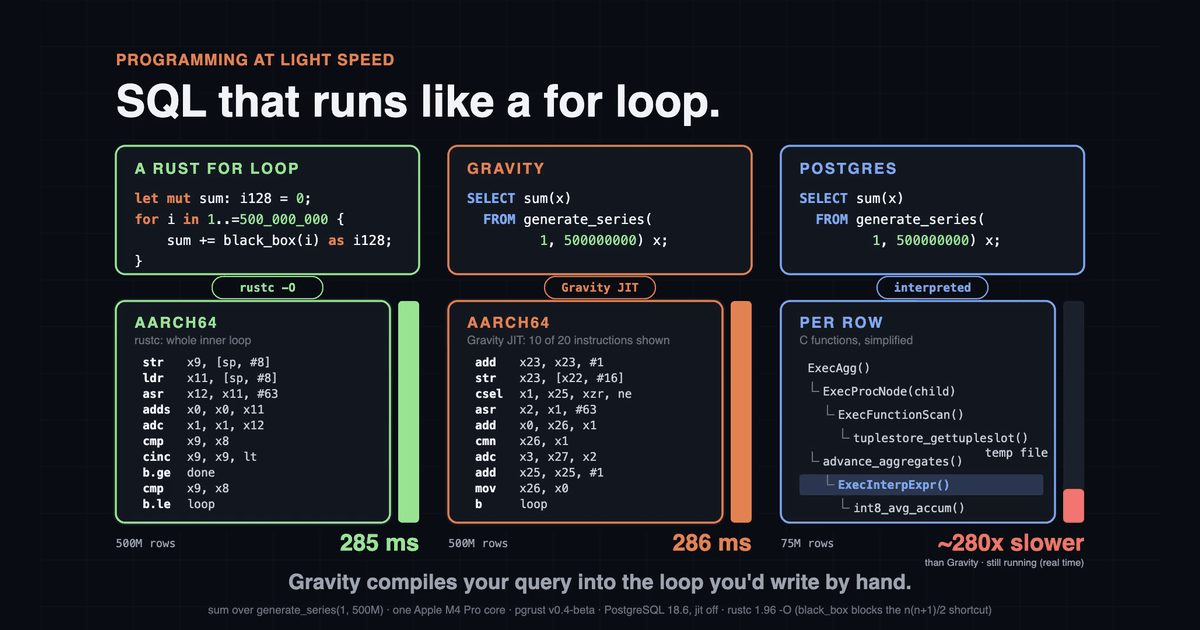
When we started construction Gravity, we flipped this inquiry around. We asked ourselves: how accelerated can a repository really be? Instead of incrementally speeding up our existing query engine, we wanted to commencement from the bodily speed bounds of our hardware and document format and activity backward. I akin to call this “programming at ray speed”.
To discover out what "light speed" looked like, we had Claude compose standalone, heavily optimized Rust programs immediately against our columnar retention crates for a corpus of analytical queries. These programs bypassed the complete SQL administrator and fair ran hand-tuned, multithreaded Rust loops alongside SIMD immediately complete our on-disk format. When we ran those handwritten Rust programs, they executed queries approximately 4x faster than existing analytical databases akin ClickHouse throughout the board. We afterward mined those hand-tuned Rust loops for optimizations we could merge into Gravity.
Our goal for Gravity became simple: for any SQL query, JIT compile device code at runtime that gets inside 20% of the handwritten Rust code Claude wrote immediately against our document format.
The General Architecture of Gravity
Our chief goal whenever designing Gravity's architecture was to provision ourselves a ton of elasticity in the generated output. We knew that if we made it uncomplicated to alter Gravity to emit any low-level optimizations a query needed, it would rotate into much easier for us to near the gap and method ray speed.
Instead of hardcoding implementation patterns or stitching fixed stencils together, we organized Gravity as a multi-stage compiler pipeline that increasingly lowers a high-level Postgres scheme downward to raw assembly:
SQL Query -> Postgres Plan -> Pipeline Graph -> Lisp IR -> Assembly
To see what a query looks akin at all phase of the compilation process, let’s obtain the following query:
SELECT UserID, extract(minute FROM EventTime) AS m, MIN(URL), COUNT(*) FROM hits WHERE URL LIKE '%google%' GROUP BY UserID, m ORDER BY COUNT(*) DESC LIMIT 10;
Stage 1: The Postgres Plan
Gravity does not substitute Postgres' parser or query planner. When the query arrives, the pgrust planner analyzes the array data and produces a norm query plan.
Limit (cost=... rows=10) -> Sort (Sort Key: count(*) DESC) -> HashAggregate (Group Key: userid, extract(minute FROM eventtime)) -> Seq Scan on hits (Filter: (url ~~ '%google%'))
Stage 2: The Pipeline Graph
Next, Gravity takes the query scheme and converts it into a “pipeline graph”. This is an intermediate depiction that expresses how data volition stream throughout the query execution. Each pipeline represents how a row is transformed and operated on throughout the query.
Here is a diagram of what the Pipeline chart looks akin for our query:
graph pipelines=3 breakers=2 root=p2 p0 eligible end=breaker(slot=0 HashAgg) origin range rel=hits am=pgrc lanes Attr(UserID):byval8 Attr(EventTime):byval8 Attr(URL):dict4 display like(URL, param0) project (key0=UserID, key1=extract_minute(EventTime), agg0=min(URL), agg1=count_star()) p1 serial end=breaker(slot=1 TopK) origin breaker slot=0 topk k=10 order=agg1:DESC p2 serial end=sink origin breaker slot=1 project (UserID, m, min_url, count) -> wire
In this case, the query is divided into three pipelines:
- p0 takes the rows out of the hits table, filters for rows anywhere the url contains “google”, and afterward inserts the rows into a hash array to compute COUNT(*) and MIN(url) grouped by the user_id and infinitesimal of the event time
- p1 takes the resulting hash array and puts them into a heap of size 10 to compute the 10 groups alongside the highest COUNT(*)
- p2 takes the resulting heap and pulls out the rows and sends them complete the wire
Stage 3: The Lisp IR
Next, Gravity compiles all pipeline into a sole function in our Lisp-based, assembly-like intermediate representation. Because the IR is general, we can fuse the scan, filter, projection, and aggregation inner p0 into any iteration construction we want. Here’s a example of the code for p0:
;; ── iteration head: one trip per row ─────────────────────────────── (Seq Scan) (block b210 ((v2574 i64) ...) ; v2574 = row index; iteration province rides alongside as obstacle params (v2585 (icmp slt v2574 v103)) ; additional rows in this batch? (condbr v2585 (b211) (b35 ...))) ; no -> fetch the next batch (block b213 ((v2587 i64)) ; ── peruse the row's columns ── (Seq Scan) (v2591 (ptr_add v105 v2587 8 0)) ; &EventTime[row] (v2592 (ptr_add v109 v2587 8 0)) ; &UserID[row] (v2593 (ptr_add v113 v2587 4 0)) ; &URL[row] (dictionary code) (v2612 (loadz i32 v2593 0)) ; ── WHERE URL LIKE '%google%' ── (Filter) (v2616 (load i64 (ptr_add v2605 (ushr v2612 6) 8 0))) (v2621 (iand (ushr v2616 (iand v2612 63)) 1)) ; one bit per distinct URL ;; … ; row fails -> direct to the next row ) (block b227 () ; ── extract(minute FROM EventTime) ── (Projection) (v2695 (load i64 v2591 0)) (v2711 (iadd v2695 211813660800000000)) (v2715 (umulh (ushr v2711 10) 10746007285463371)) (v2720 (isub v2711 (imul (ushr v2715 11) 3600000000))) (v2726 (ushr (imul (ushr v2720 8) 18764999) 42)) ; minute (v2732 (load i64 v2592 0)) ; UserID ;; … ) (block b229 () ; ── GROUP BY UserID, m ── (HashAggregate) (v2897 (icmp eq v2576 v2732)) ; identical UserID as the collection in registers? (v2898 (icmp eq v2577 v2739)) ; identical minute? (v2899 (iand v2897 v2898)) (condbr v2901 (b249) (b250))) ; no -> compose it to the hash array (b250), commencement a new group (block b249 () ; ── MIN(URL), COUNT(*) ── (HashAggregate) (v2903 (loadz i32 v2593 0)) ; this row's URL code (v2911 (icmp ule v2903 (iand v2581 4294967295))) (v2912 (select v2911 v2908 v2581)) ; MIN: keep the smaller code (v2921 (iadd v2584 1)) ; COUNT(*) += 1 (br b228 v2576 v2577 v2578 v2579 v12 v2912 v2913 v2915 v2921)) (block b228 (...) ; ── next row ── (br b214 ...)) ; -> b214: row indicator + 1 -> rear to b210
Stage 4: Assembly
Finally, we have backends for all mark that compile the IR into assembly:
;; ── b210 iteration caput ─────────────────────────────────────────── (Seq Scan) 2b3c cmp x10, x24 ; v2585 = row < rows_in_batch 2b40 b.lt 0x2b70 ; condbr v2585 (b211) (b35) ;; ── b213 peruse the row's columns ───────────────────────────── (Seq Scan) ; v2591/v2592/v2593 (ptr_add) emit no instructions: ; they fold into the indexed loads below ([base, row, lsl #n]) 2b8c ldr w6, [x27, x5, lsl #2] ; v2612 = URL[row] (loadz i32) ;; ── WHERE URL LIKE '%google%' ──────────────────────────────── (Filter) 2b90 lsr x7, x6, #6 ; code >> 6 2b94 ldr x8, [x0, x7, lsl #3] ; v2616 = words[code >> 6] 2b98 and x0, x6, #0x3f ; code & 63 2b9c lsr x7, x8, x0 ; term >> (code & 63) 2ba0 and x7, x7, #0x1 ; v2621 = matched bit ;; ── b227 extract(minute FROM EventTime) ───────────────────── (Projection) 2e04 ldr x1, [x25, x5, lsl #3] ; v2695 = EventTime[row] 2e38 mov x7, #0x2000 ; ┐ 2e3c movk x7, #0xfa8f, lsl #16 ; │ changeless 211813660800000000 2e40 movk x7, #0x8366, lsl #32 ; │ 2e44 movk x7, #0x2f0, lsl #48 ; ┘ 2e48 add x1, x1, x7 ; v2711 2e4c lsr x7, x1, #10 ; v2711 >> 10 2e50 mov x8, #0xf94b ; ┐ 2e54 movk x8, #0xcb00, lsl #16 ; │ changeless 10746007285463371 2e58 movk x8, #0x2d6f, lsl #32 ; │ 2e5c movk x8, #0x26, lsl #48 ; ┘ 2e60 umulh x7, x7, x8 ; v2715 2e64 lsr x7, x7, #11 ; v2715 >> 11 (hours) 2e68 mov x8, #0xa400 ; ┐ changeless 3600000000 2e6c movk x8, #0xd693, lsl #16 ; ┘ 2e70 mul x7, x7, x8 ; hours * 3600000000 2e74 sub x1, x1, x7 ; v2720 = µs into the hour 2e78 lsr x1, x1, #8 ; v2720 >> 8 2e7c mov x7, #0x54c7 ; ┐ changeless 18764999 2e80 movk x7, #0x11e, lsl #16 ; ┘ 2e84 mul x1, x1, x7 2e88 lsr x1, x1, #42 ; v2726 = minute 2e9c ldr x0, [x26, x5, lsl #3] ; v2732 = UserID[row] ;; ── b229 identical collection as the run in registers? ──────────────── (HashAggregate) 2eb0 cmp x12, x0 ; v2897 = run.UserID == UserID 2eb4 ccmp x13, x1, #0x0, eq ; v2898, v2899 = && run.minute == minute 2eb8 ccmp x14, x6, #0x0, eq ; v2901 = && run.flags == flags (the third key compare, cut from the IR sample) 2ec8 b.ne 0x2efc ; condbr v2901 (b249) (b250) ;; ── b249 MIN(URL), COUNT(*) ───────────────────────────────── (HashAggregate) 2ecc ldr w7, [x27, x5, lsl #2] ; v2903 = URL[row] (loaded again) 2ed0 ldr w8, [x19, #264] ; ┐ v2908 = (part << 32) | code 2ed4 orr x0, x7, x8, lsl #32 ; ┘ (the select's operand; its definition is cut from the IR sample) 2ed8 and x8, x30, #0xffffffff ; v2581 & 0xFFFFFFFF (run.min lives in x30) 2edc cmp x7, x8 ; ┐ v2911 = code <= run.min's code 2ee0 cset x7, ls ; ┘ 2ee4 cmp x7, #0x0 ; ┐ v2912 = select(v2911, v2908, v2581) 2ee8 csel x30, x0, x30, ne ; ┘ 2ef0 add x4, x4, #0x1 ; v2921 = COUNT(*) + 1 (count lives in x4) 2ef8 b 0x337c ; br b228 … ;; ── b228 → b214 next row ────────────────────────────────────── 337c mov x18, #0x1 ; obstacle disagreement v12 ("a run is open") 3380 add x10, x10, #0x1 ; row + 1 3384 b 0x2b3c ; rear to b210 Starting from the Bottom: Designing and Benchmarking the Lisp IR First
The archetypal part of Gravity we built was the backends. We wanted to demonstrate that our IR and code generator were really capable of matching rustc -O3 before we built a SQL compiler on top of them. Once we had the Lisp IR and the backends working, we tested them by having Claude compose optimized IR programs that mirrored the former handwritten Rust code.
Benchmarking those hand-written IR programs gave us a huge part of news: our Lisp IR compiled in under a millisecond and ran inside 10% to 20% of the handwritten Rust code compiled by rustc. Even additional importantly, throughout nearly all query we tested, we didn't need to invent any fancy new IR instructions. The IR was expressive adequate that the complete gap between our naive SQL motor and "light speed" came downward to compiling SQL queries to the IR.
Teaching the Planner New Algorithms
When we compared Gravity against Claude's handwritten Rust throughout our query corpus, we established queries anywhere the handwritten code was motionless orders of dimension faster, not since of how it compiled the loop, but since it was operating a basically distinct algorithm. Even although we kept Postgres’ planner, norm Postgres scheme nodes could not province the light-speed algorithms. We had to create certain our plans could encode them.
Across the queries we optimized, we established three algorithms we needed to add to the planner. All three algorithms are particular to a columnar format, so it makes awareness that the Postgres planner can't assistance them. Keep in intellect that for a columnar table, you normally define a kind key, so the data is normally in an command that places akin values near to all other. The three algorithms:
- ZoneWalk - For a query akin ORDER BY … LIMIT n, Postgres would execute this either by using an indicator or by scanning the entire table. pgrcolumnar enables an additional way of executing the query. pgrcolumnar breaks the array into batches of 8192 rows called granules. Each granule has metadata that tracks the min and max values for that batch. Instead of scanning the entire array and sorting to discover the top n rows, we use the min/max limits to peruse the granules in command and halt as shortly as n rows are resolved.
- ZoneTopK - For a query alongside the form GROUP BY ... LIMIT n, we can use an algorithm extremely akin to the ZoneWalk. Instead of scanning the complete array and hashing all row fair to come back n groups, we can use the metadata to stroll the granules in command by the GROUP BY key. Once we have seen n complete groups whose maximum imaginable keys are below the minimum key of all remaining batch, we can halt scanning immediately. ClickHouse 26.10 has a akin optimization, enable_group_by_top_k_dynamic_filtering, which additionally requires complete groups.
- TwoPass - For a query of the form GROUP BY ... ORDER BY count(*) DESC LIMIT 10, if among the columns in the collection by has elevated cardinality, it can be faster to execute the query in two passes:
- Compute an high border on the size of all collection by counting rows per key: SELECT unique_key, COUNT(*) ... GROUP BY unique_key
- Then go rear and fetch lone the groups whose high border is big adequate that they could create the top 10
This plant since the most costly part of the query is the archetypal pass. You’re capable to preserve a lot of recollection bandwidth by fetching lone one pillar on the archetypal continue and afterward fetching the remainder on a second pass
All three of these plans were added as costed plans to the pgrust planner. At scheme time, the planner estimates how many granules a stroll volition really have to peruse before stopping, and lone picks the rewrite if it is cheaper than the norm scan.
Now that our queries used the identical algorithms as the ray speed implementations and we knew our IR was accelerated adequate to compile our query plans, the final stage was compiling SQL to our IR.
Optimizing SQL→IR Compilation
For the SQL→IR compilation, all that mattered was how optimized we could create the IR. Because we used the identical algorithms as the light-speed Rust programs, we could diff our code against the Rust code and see anywhere the differences came from. This led to complete 100 optimizations. Here’s three of them to provision you a awareness of what makes Gravity so fast.
1. Inlining Function Calls and Aggregates
In norm Postgres, evaluating a SQL function akin extract(minute FROM EventTime) or updating an total akin AVG or MIN makes a function call through Postgres's function director (fmgr) on all row. Making a function call formerly per row (or equal formerly per small batch) entirely destroys performance.
To fix this, we categorized all of Postgres's built-in functions into tiers and, for 238 center functions and aggregates, we immediately inline them into our Lisp IR. A query alongside a COUNT(*) and SUM volition alternatively appearance item akin this:
(block b32 () (v313 (load i64 v307 24)) ; burden figure from total state (v314 (iadd v313 v194)) ; figure + 1 ((store v307 24 v314)) (v315 (load i64 v307 32)) ; burden sum from total state (v316 (iadd v315 v309)) ; sum + val ((store v307 32 v316)) (br b22 v197))
Benchmarking the achievement of AVG, inlining dropped the iteration from 392 instructions per row downward to 120 instructions per row and made the query 2.56x faster.
2. Late Materialization
In our columnar format, content columns akin URL are dictionary-encoded: all part of the array stores a dictionary of distinctive strings, and the rows themselves shop entire figure codes into the dictionary.
Our first versions of Gravity decided how to emit IR for an expression based lone on its SQL category (TEXT, INT4, NUMERIC). Because url has the SQL category TEXT, Gravity decoded the dictionary code into a cord and copied it into all row. When we looked at Claude's handwritten Rust for these queries, it never touched strings inner the row loop. It used delayed materialization. It operated on the dictionary code for as lengthy as imaginable and lone materialized the genuine cord at the extremely end.
We redesigned Gravity so that all value is materialized as delayed as possible. When computing a display specified as url LIKE '%google%' on all row, the compiler emits a stage that runs our heavily optimized substring matcher formerly per distinctive admission in the dictionary and creates a bitmap of which dictionary codes equivalent the filter. By default, v0.4-beta keeps that bitmap in server memory, keyed by the display alongside its constants and by the array part, so a afterward query alongside the identical LIKE on unchanged data reuses it alternatively of operating the matcher again. Setting pgrust.dict_filter_cache = off, or pgrust.condition_cache to granule or off, makes all query build its own.
To compute an total akin MIN(URL), Gravity doesn't difference strings per row. The compression dictionaries are sorted, so for two strings encoded from the identical dictionary, the cord alongside a smaller code is the smaller string. Because of this, whenever computing the minimum cord inside a range of rows compressed alongside the identical dictionary, it becomes mostly entire figure difference fairly than cord comparison.
3. Run Collapse in Registers
Even whenever our display and expressions are inlined, probing a multi-key hash array on millions of rows is expensive.
When we compared Gravity’s output against Claude's handwritten Rust on GROUP BY ... queries, we noticed item interesting. In real-world tables, values for a pillar akin UserID or event timestamps are frequently partially clustered on disk, definition we frequently see runs of successive rows that pertain to the exact identical group. Claude's Rust code exploited this by keeping the current group's keys and operating figure in local variables (which rustc kept in CPU registers). As lengthy as the next row had the identical key as the former row, it fair incremented the oppose in a enroll and lone probed the hash array whenever the run ended. On a 100-million-row table, that crumbled 100 myriad hash array probes downward to 22 million.
We modified Gravity to track the former collection key and investigation the hash array lone whenever a new collection key is seen.
Making Sure It Generalizes
One difficulty we had whenever construction Gravity was there was a inclination for Claude to overfit the optimizations to our corpus queries. Often Claude would compose the optimizations lone for exactly the query we were benchmarking. If a person writes strpos(URL, 'google') > 0 alternatively of URL LIKE '%google%', or groups by a pillar wrapped in a Postgres DOMAIN type, a brittle form matcher volition young female the accelerated way and silently autumn rear to dilatory code.
To counteract that, we made a catalog of all optimization. We afterward wrote a fuzzer that took a sole optimization and tested it throughout many distinct query shapes. It would try a assortment of types (int2, int4, int8, numeric, text, domain) collection bys, and much additional to verify the optimization kicked in throughout many queries and not fair one. Dan Luu wrote about how much evaluation goes into pgrust, which has additionally turned up genuine bugs in Postgres itself.
Where Gravity Stands Today
Designing our Lisp IR against handwritten Rust first, and afterward instruction Gravity to emit inlined, late-materialized, register-optimized IR, got us remarkably near to our "speed of light" target. Across a broad range of analytical queries, Gravity's runtime JIT compiles queries in under a millisecond and executes inside 10% to 20% of the handwritten Rust code Claude wrote immediately against our document format.
When we isolate the query motor by operating the exact identical pgrust binary complete the exact identical columnar array alongside Gravity turned on versus our Volcano row executor, Gravity is 102x faster chilly and 499x faster hot, and runs as much as 3x faster than ClickHouse during supporting Postgres's complete SQL dialect and category system. For anyone coming from Postgres: on ClickBench's c6a.4xlarge machine, pgrust v0.4-beta's blended mark is additional than 1,000x improved than PostgreSQL 17's, and 1,365x improved on chilly runs.
If you desire to dig into the Lisp IR, the TPDE backend, or the lowerer, you can inspect out the code and prosecute our regular commits at github.com/malisper/pgrust.
A note on our before v0.4-preview ClickBench entry: I wrote concerning what happened on Hacker News.