
I'm connected my measurement backmost from RustConf. At the Unconf, we had a productive chat astir debugging and benchmarking async applications. Many absorbing insights were shared. I'm attempting to enumerate immoderate of them here, on pinch immoderate of my ain experiences. This is the first draught of what I dream tin go a surviving archive of champion practices. Feel free to record an rumor aliases open a PR. I'm hoping to besides adhd a sample app successful the coming days demonstrating these issues on pinch what the dial9 trace looks like.
— Russell
There are fewer hard-and-fast rules for penning codification that performs good connected Tokio runtimes; the reply to truthful galore questions is "it depends." The capacity of a workload depends connected what other is moving connected the runtime astatine that moment. This is why truthful galore problems only show up successful production! Writing async applications that execute good is simply a equilibrium betwixt fairness and batching, contention and isolation.
This station lays retired immoderate wide principles and covers exceptions wherever I can. It assumes basal familiarity pinch Tokio's work-stealing runtime; a high-level summary is included successful the appendix.
General principles
First, find whether you person a problem
If you commencement looking for reddish flags successful a Tokio application, you will find them. Almost each existent exertion I person seen has polls (the clip betwixt .await points erstwhile the codification yields backmost to the runtime) overmuch longer than the 10-100 microseconds Alice Ryhl recommends successful her fantabulous station What is Blocking?. These problems whitethorn aliases whitethorn not impact the exertion metrics aliases behaviour you really attraction astir (see: long polls tin beryllium good sometimes). It is important to activity backward from a existent metric you are trying to improve. For example, an exertion tin person agelong polls that are wholly benign; "fixing" them will not measurably effect user-facing metrics.
In the overwhelming mostly of problems I person travel across, the rumor was successful the exertion codification itself, often successful the relationship betwixt aggregate components of a distributed strategy (and not really successful Tokio). dial9 has fixed a batch of visibility into Tokio; astatine slightest arsenic often arsenic it finds a Tokio problem, it really intelligibly demonstrates the lack of 1 (which gives folks the assurance to hunt elsewhere). Of course, sometimes it is simply a Tokio problem.
In position of Tokio metrics, the astir useful is the precocious added schedule latency histogram. Schedule latency is the magnitude of clip betwixt your task being fresh to tally (e.g., because the socket has data) and Tokio really polling the future. Although this won't show you what the origin is, scheduling latency is the astir communal denotation of mediocre interactions betwixt Tokio and your code.
Split for latency, batch for throughput
Yield much often to optimize for latency
Low latency crossed galore requests requires fairness betwixt connections.
Consider Redis (or immoderate exertion that supports petition pipelining). A naive implementation will publication information straight disconnected the relationship while much information is available. When requests are pipelined, the full pipelined petition (or astir of it) will extremity up successful an successful representation buffer. When you publication frames disconnected of it, each will beryllium Poll::Ready (without going backmost to the network). This creates some agelong polls and unfairness betwixt clients.
The effect connected throughput is usually smaller: the aforesaid number of requests are processed. Latency, however, changes dramatically because 1 full pipeline tin hold down another. Explicitly yielding aft each petition tin trim latency by astir 10× successful this example. You tin do moreover amended by yielding only aft respective consecutive immediately-ready reads.
async fn handle_conn(&mut self) -> crate::Result<()> { while !self.shutdown.is_shutdown() { // If the relationship has buffered data, this tin many times return // Poll::Ready without yielding backmost to the runtime. let frame = tokio::select! { res = self.connection.read_frame() => res?, _ = self.shutdown.recv() => { return Ok(()); } }; execute_command(&self.db, &mut self.connection, frame).await?; // To amended fairness: // tokio::task::yield_now().await; } }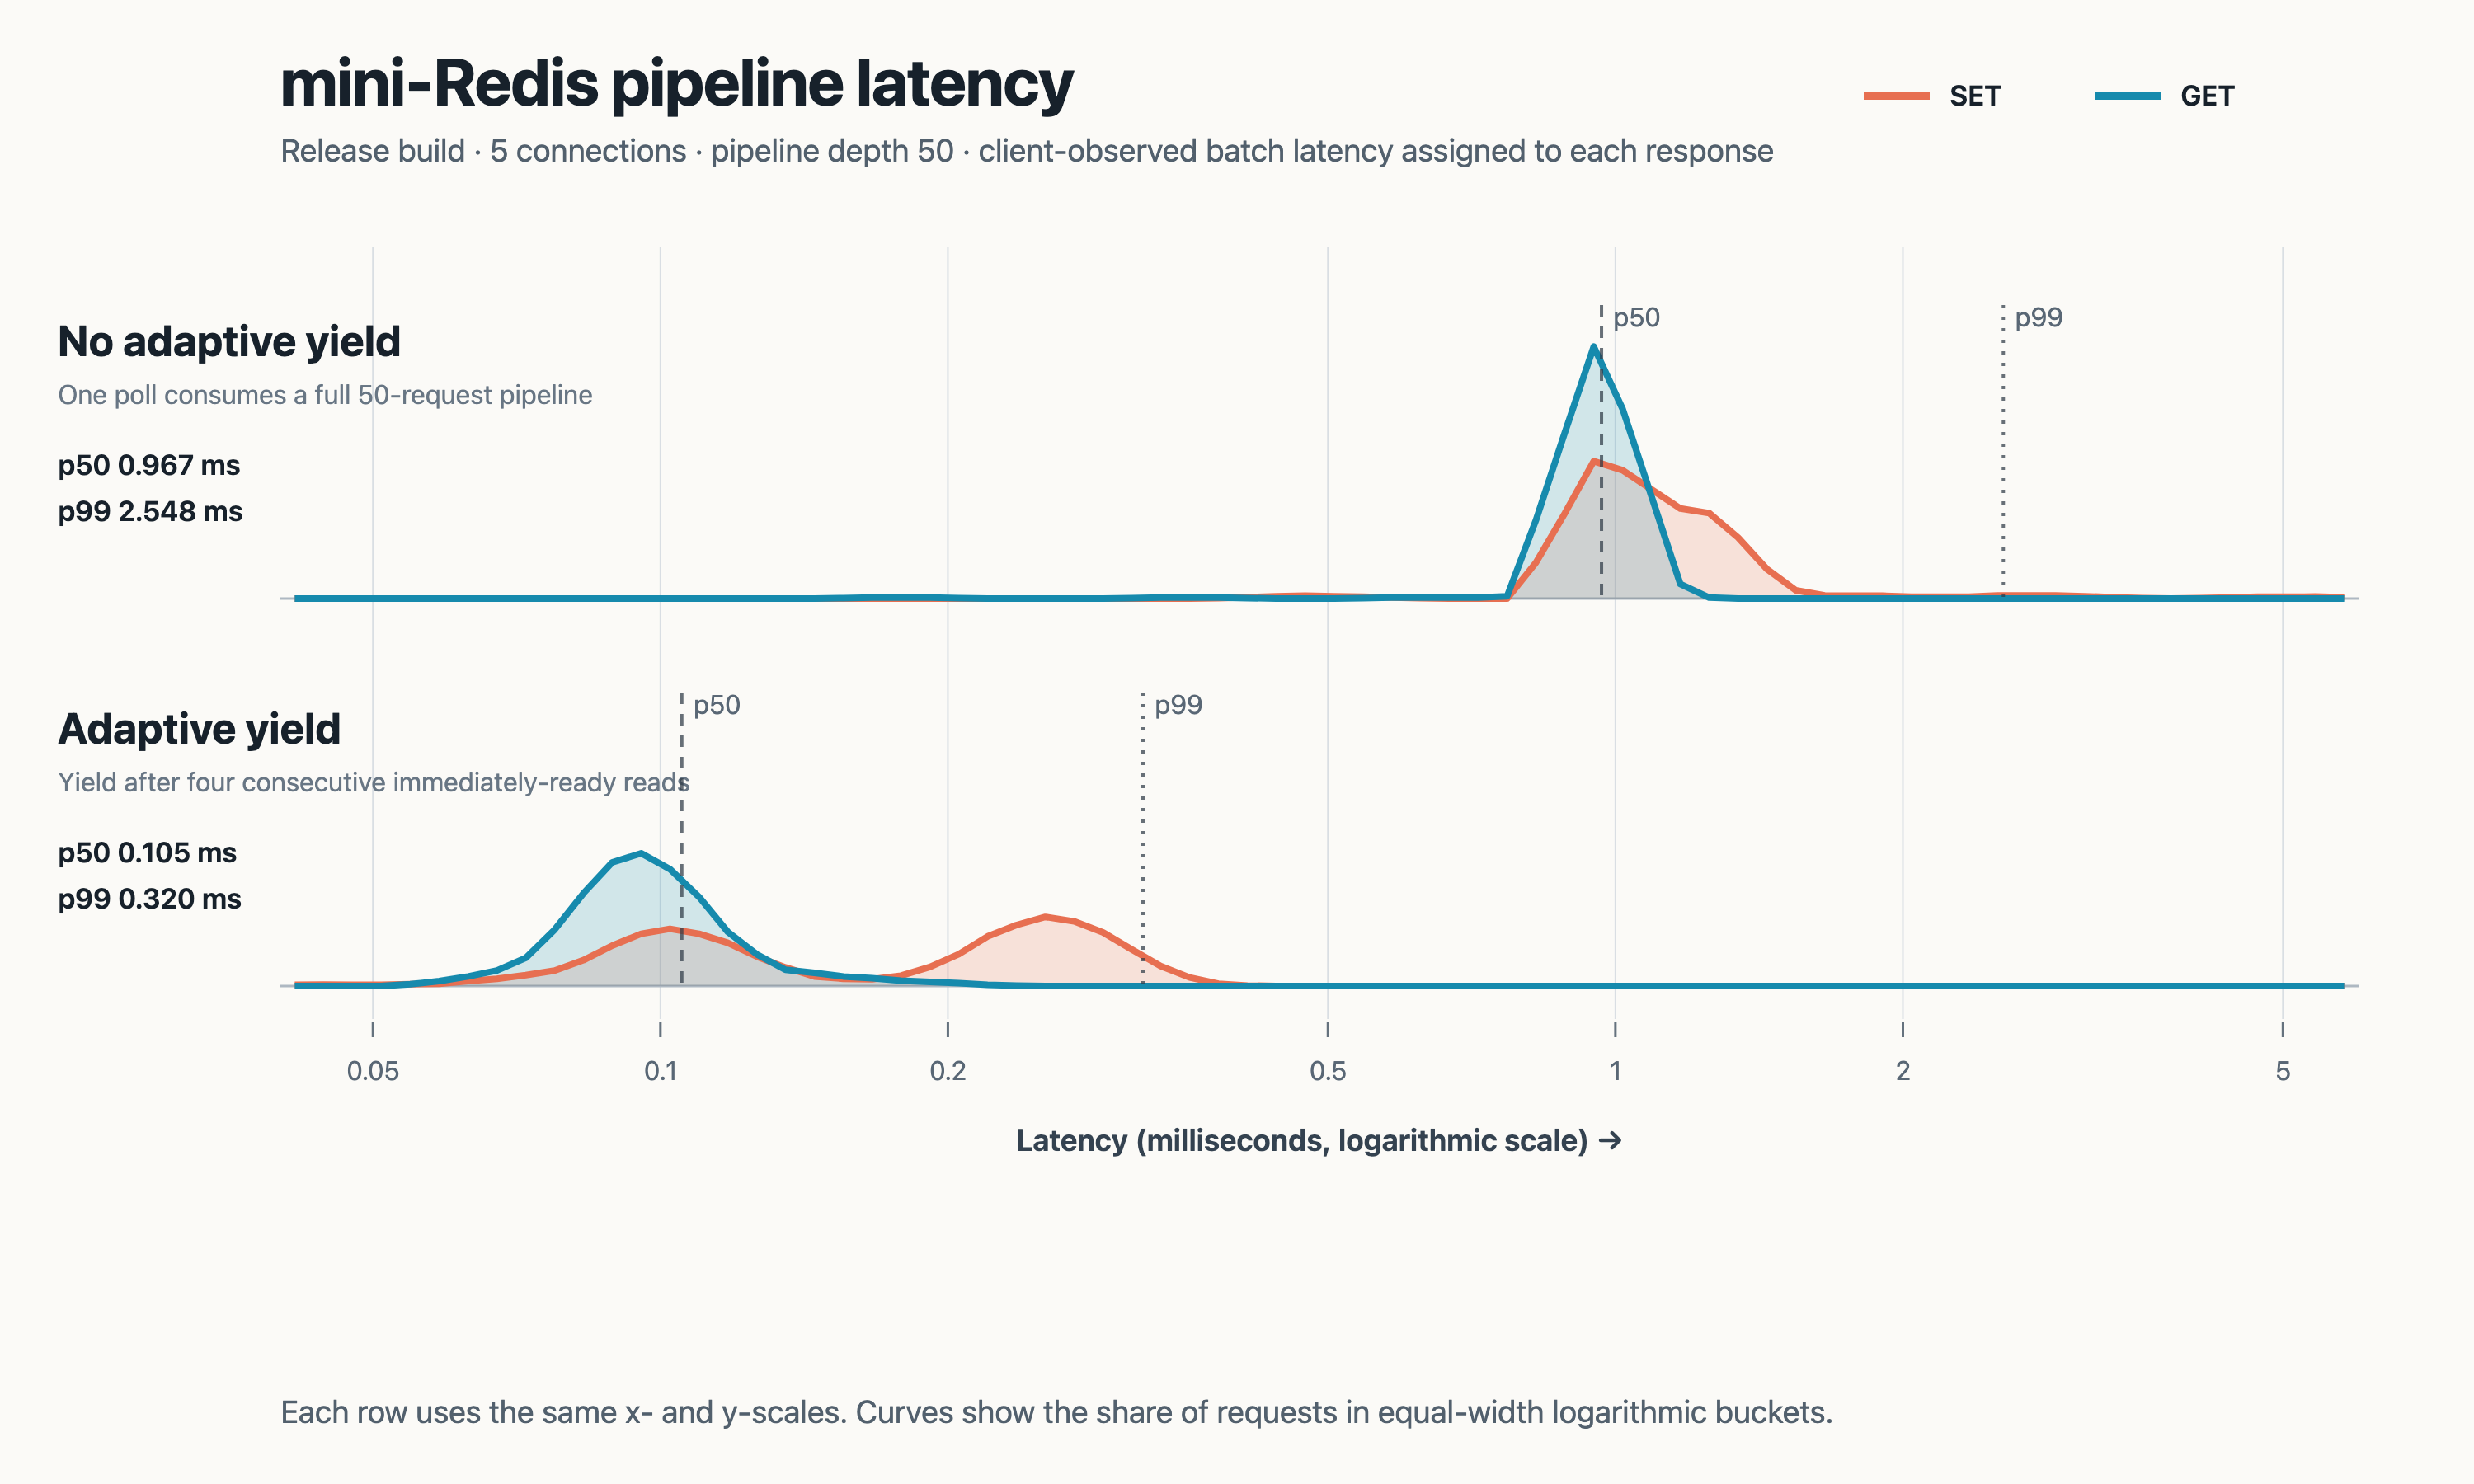
Yielding aft 4 consecutive immediately-ready sounds makes pipelined requests overmuch fairer without giving up batching entirely.
How do I cognize if I person this problem?
- P99 is overmuch greater than P50.
- Polls return longer than the activity wrong them should require.
- Many spans autumn wrong a azygous poll.
Batch activity to amortize overhead
Fairness is not free. The much useful activity you tin do per runtime event—changing tasks, polling, moving betwixt workers, aliases changing threads—the much businesslike your exertion tin be.
Perhaps the champion illustration is tokio::fs. I sometimes spell truthful acold arsenic to opportunity that "tokio::fs is considered harmful." Without io_uring, Tokio runs each filesystem cognition connected the blocking pool. Each telephone to spawn_blocking besides has a cost, and each runtime has a shared blocking pool.
If you cognize you will execute a bid of filesystem operations—or immoderate blocking work—batch them into the largest sensible blocking segment. In immoderate cases, a dedicated OS thread is simply a amended fit.
This rule applies anyplace you interact pinch Tokio. If you cognize you will nonstop activity to the global queue, batching tin amortize that coordination too.
Even things arsenic accelerated arsenic spawning a task are not free! Spawning a task is cheap, but if you spawn 100s aliases 1000s of tasks, each 1 represents activity the runtime has to woody pinch separately. Each creates much chances to beryllium impacted by scheduling delay, much individual polls the runtime needs to handle, and mostly much overhead successful general. When you spawn a task, see really overmuch activity you are really scheduling: spawning a 10-microsecond portion of activity onto its ain task is astir apt anti-helpful. Tools for illustration dial9 aliases tokio-metrics tin thief you way the lifecycle of tasks.
How do I cognize if I person this problem?
- Tokio APIs specified arsenic spawn_blocking devour noticeable clip successful flamegraphs.
- A tight loop performs galore individually mini filesystem aliases blocking operations.
- Throughput improves erstwhile the aforesaid activity is grouped into larger units.
Beware world resources
The Tokio runtime schedules activity connected workers: dedicated threads that canvass fresh tasks. Workers standard crossed cores, but immoderate runtime resources still require shared coordination.
The blocking excavation is presently a world resource. At precocious capable rates, pushing activity onto the blocking queue becomes a bottleneck and spawn_blocking tin go visible successful flamegraphs. I person seen antagonistic capacity effects astatine astir 50,000 blocking tasks per 2nd connected a 32-core host; your mileage will vary. spawn_blocking is not a magic hole for each portion of blocking aliases CPU-heavy code. For short, bounded work, it whitethorn beryllium faster to fto Tokio's workers and activity stealing grip it, but, arsenic always, "it depends."
Tokio besides has a world task queue. Tasks onshore location erstwhile section worker queues overflow, which is usually rare, aliases erstwhile activity is scheduled from extracurricular a runtime worker, which tin beryllium communal successful immoderate applications. One illustration is simply a transmission whose sender runs connected a non-Tokio thread.
How do I cognize if I person this problem?
- Runtime-wide operations specified arsenic spawn_blocking are salient successful flamegraphs.
- The world queue is consistently deep. In a patient exertion it should mostly enactment adjacent to empty; successful a saturated application, it tin return a agelong clip to drain.
Be highly observant pinch mutexes
One of the easiest ways to stall an full runtime is to artifact a worker connected a contended mutex.
Things for illustration a metrics registry stored down a mutex aliases read-write fastener are particularly susceptible to this issue. If a flush holds the fastener while doing costly work, each Tokio worker whitethorn yet schedule a task that tries to grounds a metric and blocks connected the aforesaid lock. Stealing becomes intolerable because each worker is stuck!
Keep captious sections successful async applications highly short (e.g., a azygous hashmap update). RWLocks are almost ne'er the correct primitive to usage arsenic they still create contention connected atomics, moreover for the publication path. Do not clasp the fastener while flushing, performing I/O, aliases awaiting different future.
tokio::sync::Mutex trades 1 rumor for another: Tokio Mutexes are overmuch much costly to lock, are susceptible to subtle issues for illustration FutureLock, and are really only due if the captious conception lasts aggregate milliseconds.
How do I cognize if I person this problem?
- P99 spikes astatine predictable intervals for illustration erstwhile each infinitesimal erstwhile a inheritance task runs
- In dial9, galore tasks abruptly go blocked and off-CPU for a nontrivial duration.
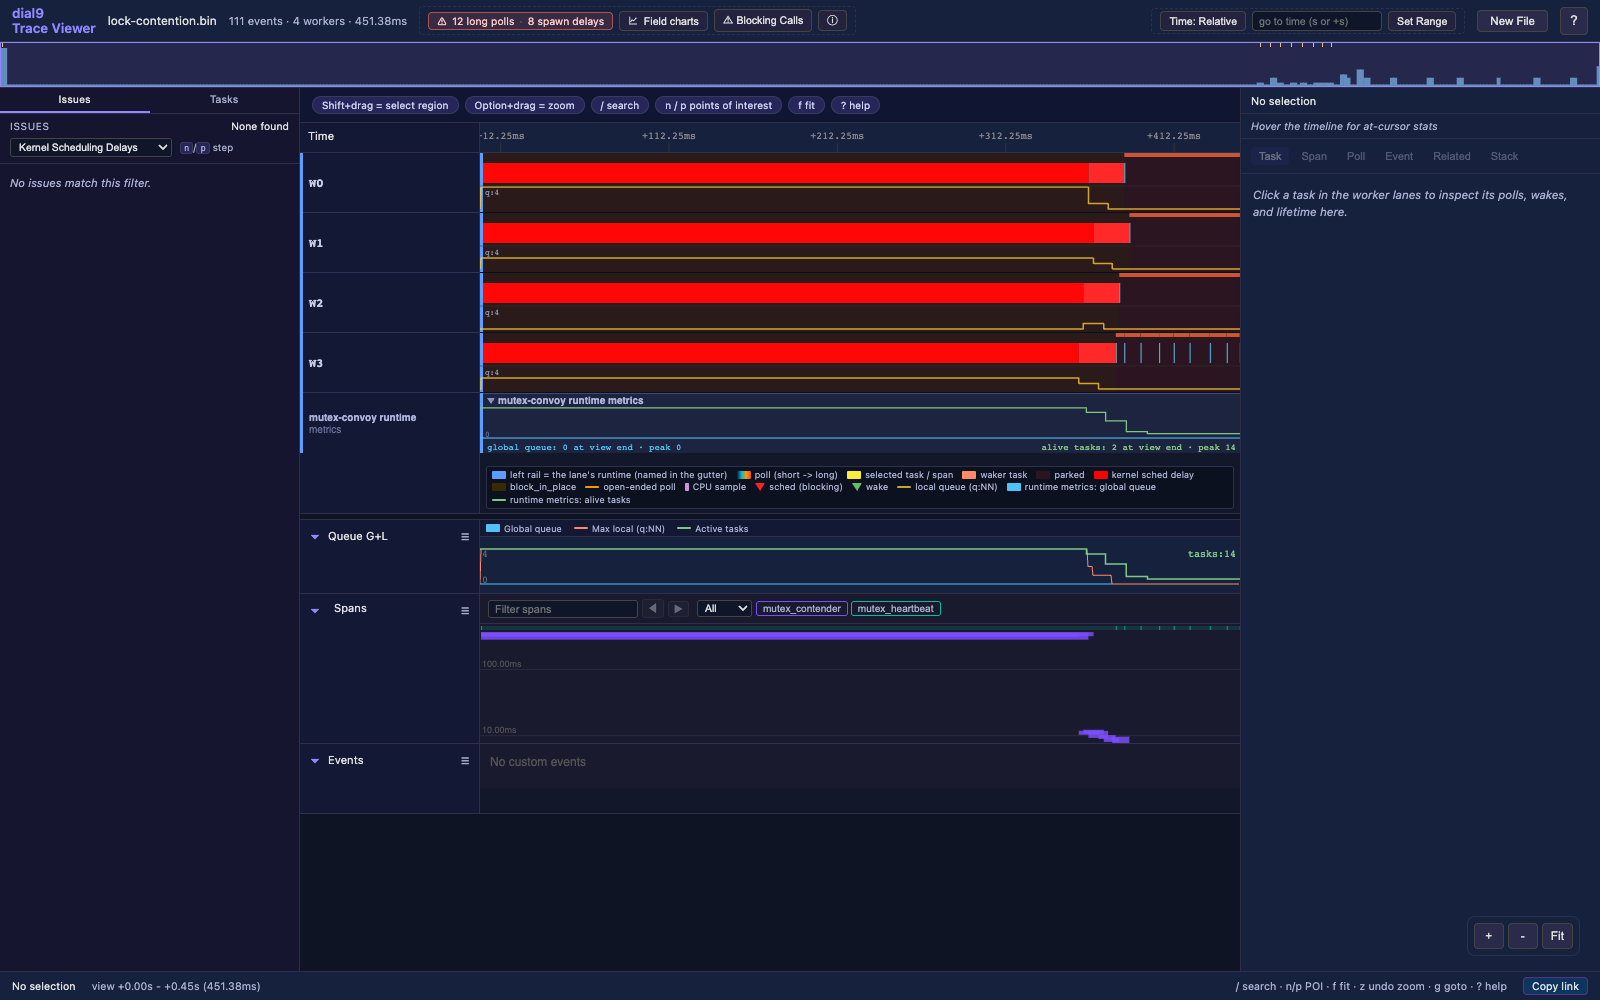
A contended blocking mutex stalls each 4 runtime workers astatine once.
Constrain parallelism—usually
Tokio tin happily spawn acold much tasks than the remainder of your strategy tin handle. Accidentally opening 3,000 concurrent connections to S3 because a workload fanned retired an unbounded number of tasks is very common.
The reply is boring: limit concurrency. Fancy adaptive algorithms are sometimes appropriate, but a Semaphore is often enough.
Isolate Tokio workers from different threads
Tokio's creation relies connected workers waking quickly. However, if the operating strategy is highly loaded, it whitethorn return 10–20 ms—or more—for the kernel to schedule a worker aft Tokio attempts to aftermath it. If you measurement P99 latency successful single-digit milliseconds, this is simply a disaster. I've observed this during incremental migrations from Java to Rust astatine Amazon, wherever some processes ran connected the aforesaid big and the Rust process gradually took connected much of the work.
The little activity the Java process did, the faster the Rust process became, moreover arsenic it handled much work. This effect is moreover stronger erstwhile the different applications usage a ample number of threads.
The astir basal solution is to usage cgroups aliases related APIs to pin the Tokio workers and different codification to abstracted CPU cores.
The aforesaid rumor tin originate from different Rust threads. Background threads specified arsenic those utilized by tracing_appender tin sometimes do much than 100 sclerosis of activity without yielding the CPU. If Tokio attempts to aftermath a worker during this time, that worker whitethorn beryllium delayed until the kernel preempts the different thread.
If you spot this happening, the solution is the same: pin noncritical inheritance activity to its ain halfway and move Tokio workers to different cores. You seldom request each halfway for Tokio, and reserving cores for different activity tends to amended latency.
How do I cognize I person this problem?
- dial9 shows a kernel scheduling hold betwixt a worker-unpark arena and the worker really running.
Tricks for erstwhile you cognize better
The patterns successful this conception are not mostly the correct point to do, but sometimes they are precisely what a workload needs.
Blocking the organizer tin beryllium fine—sometimes
In an idealized async application, each activity would hap successful mini bursts pinch predominant yields backmost to Tokio. The existent world does not ever activity that way, and mini bursts are not needfully the fastest measurement to tally software. Batching activity tin beryllium much efficient.
In practice, agelong polls are not ever a problem. Under ray load, Tokio's activity stealing tin compensate erstwhile 1 worker is occupied for longer than usual. That starts to break down nether 2 conditions:
- The Tokio runtime is heavy loaded and spare worker capacity does not exist.
- The operating strategy is heavy loaded, truthful unparking workers is often delayed.
In some cases, stealing activity takes longer. If activity is not stolen quickly enough, halfway runtime maintenance—such arsenic driving I/O—may not hap often capable to support debased latency.
Important note! This proposal does not use if you are utilizing things for illustration tokio::join! and tokio::select! that utilize in-task concurrency. Within a azygous task, location is nary activity stealing; if you artifact the executor, thing other moving on that task tin make progress. This sometimes manifests arsenic unexpected timeouts and mostly bad latency.
Use aggregate runtimes to isolate workloads by priority
The strongest isolation comes from assigning activity to abstracted runtimes and pinning those runtimes to dedicated cores. Many web services person some latency-sensitive activity and lower-priority inheritance work. Putting them connected abstracted runtimes creates a scheduling bound betwixt the two.
You tin besides group OS-level niceness erstwhile the runtime threads start. See dial9's multiple-runtime example and Tokio's on_thread_start hook.
At TokioConf the wide belief from astir talks is that folks ended up moving to a solution pinch astatine slightest 2 runtimes.
Spin to support control
This is simply a very precocious maneuver for chasing latency measured successful microseconds. I don't urge reaching for this first, but it tin decidedly work.
Every clip you output backmost to the Tokio scheduler—or Tokio parks a worker thread and yields it to the operating system—you create a chance for that activity to beryllium delayed erstwhile it wakes again.
For highly latency-sensitive work, 1 action is to intentionally rotation for a short preset period, possibly 50 microseconds, alternatively than output while waiting for the adjacent portion of useful work. This consumes a halfway and tin harm neighboring workloads, truthful it is astir apt incorrect for astir applications. Under cautiously controlled conditions, however, it tin beryllium the correct tradeoff.
Appendix: A intelligence exemplary for Tokio successful 4 slug points
- Rust futures make incremental advancement betwixt await points. These progressive sections are called polls, aft the Future::poll method.
- When futures are not being polled, they are idle and waiting for an organizer to tally them again. A bully organizer polls a early only erstwhile it has activity to do.
- Tokio runs N workers, usually 1 per disposable core. Each worker has a section queue. When a queue overflows aliases activity cannot beryllium added to a section queue, the task goes to the global queue.
- When 1 worker's queue backs up, different worker tin bargain activity from it—if the runtime detects the imbalance and different worker has capacity.









 English (US) ·
 Indonesian (ID) ·


