Last Thursday (October 15), Tesla's new Roadster drove off a ramp that coiled complete until the car was upside down, rolled upright in the air and landed. It afterward used thrusters to hop complete a Cybertruck. Turns out the forthcoming does have flying cars.
The demo had already been pushed rear two weeks, "due to elevated winds" (Elon Musk on X). That made us wonder: alongside a tongue example in the pilot's seat, how would the car do in that wind?
We built an RL surroundings about a discipline simulator of a flying roadster to discover out, handed the controls to LLMs, and turned the breeze up. We let several of the latest finest models fly it: DeepSeek V4.1 Flash, Meta's Muse Spark Open, Reflection's Beam 1.0, NVIDIA's Nemotron 3.5 Super VL, TypeSafe's Jev 1.14, and equal OpenAI's GPT-6 Astra.
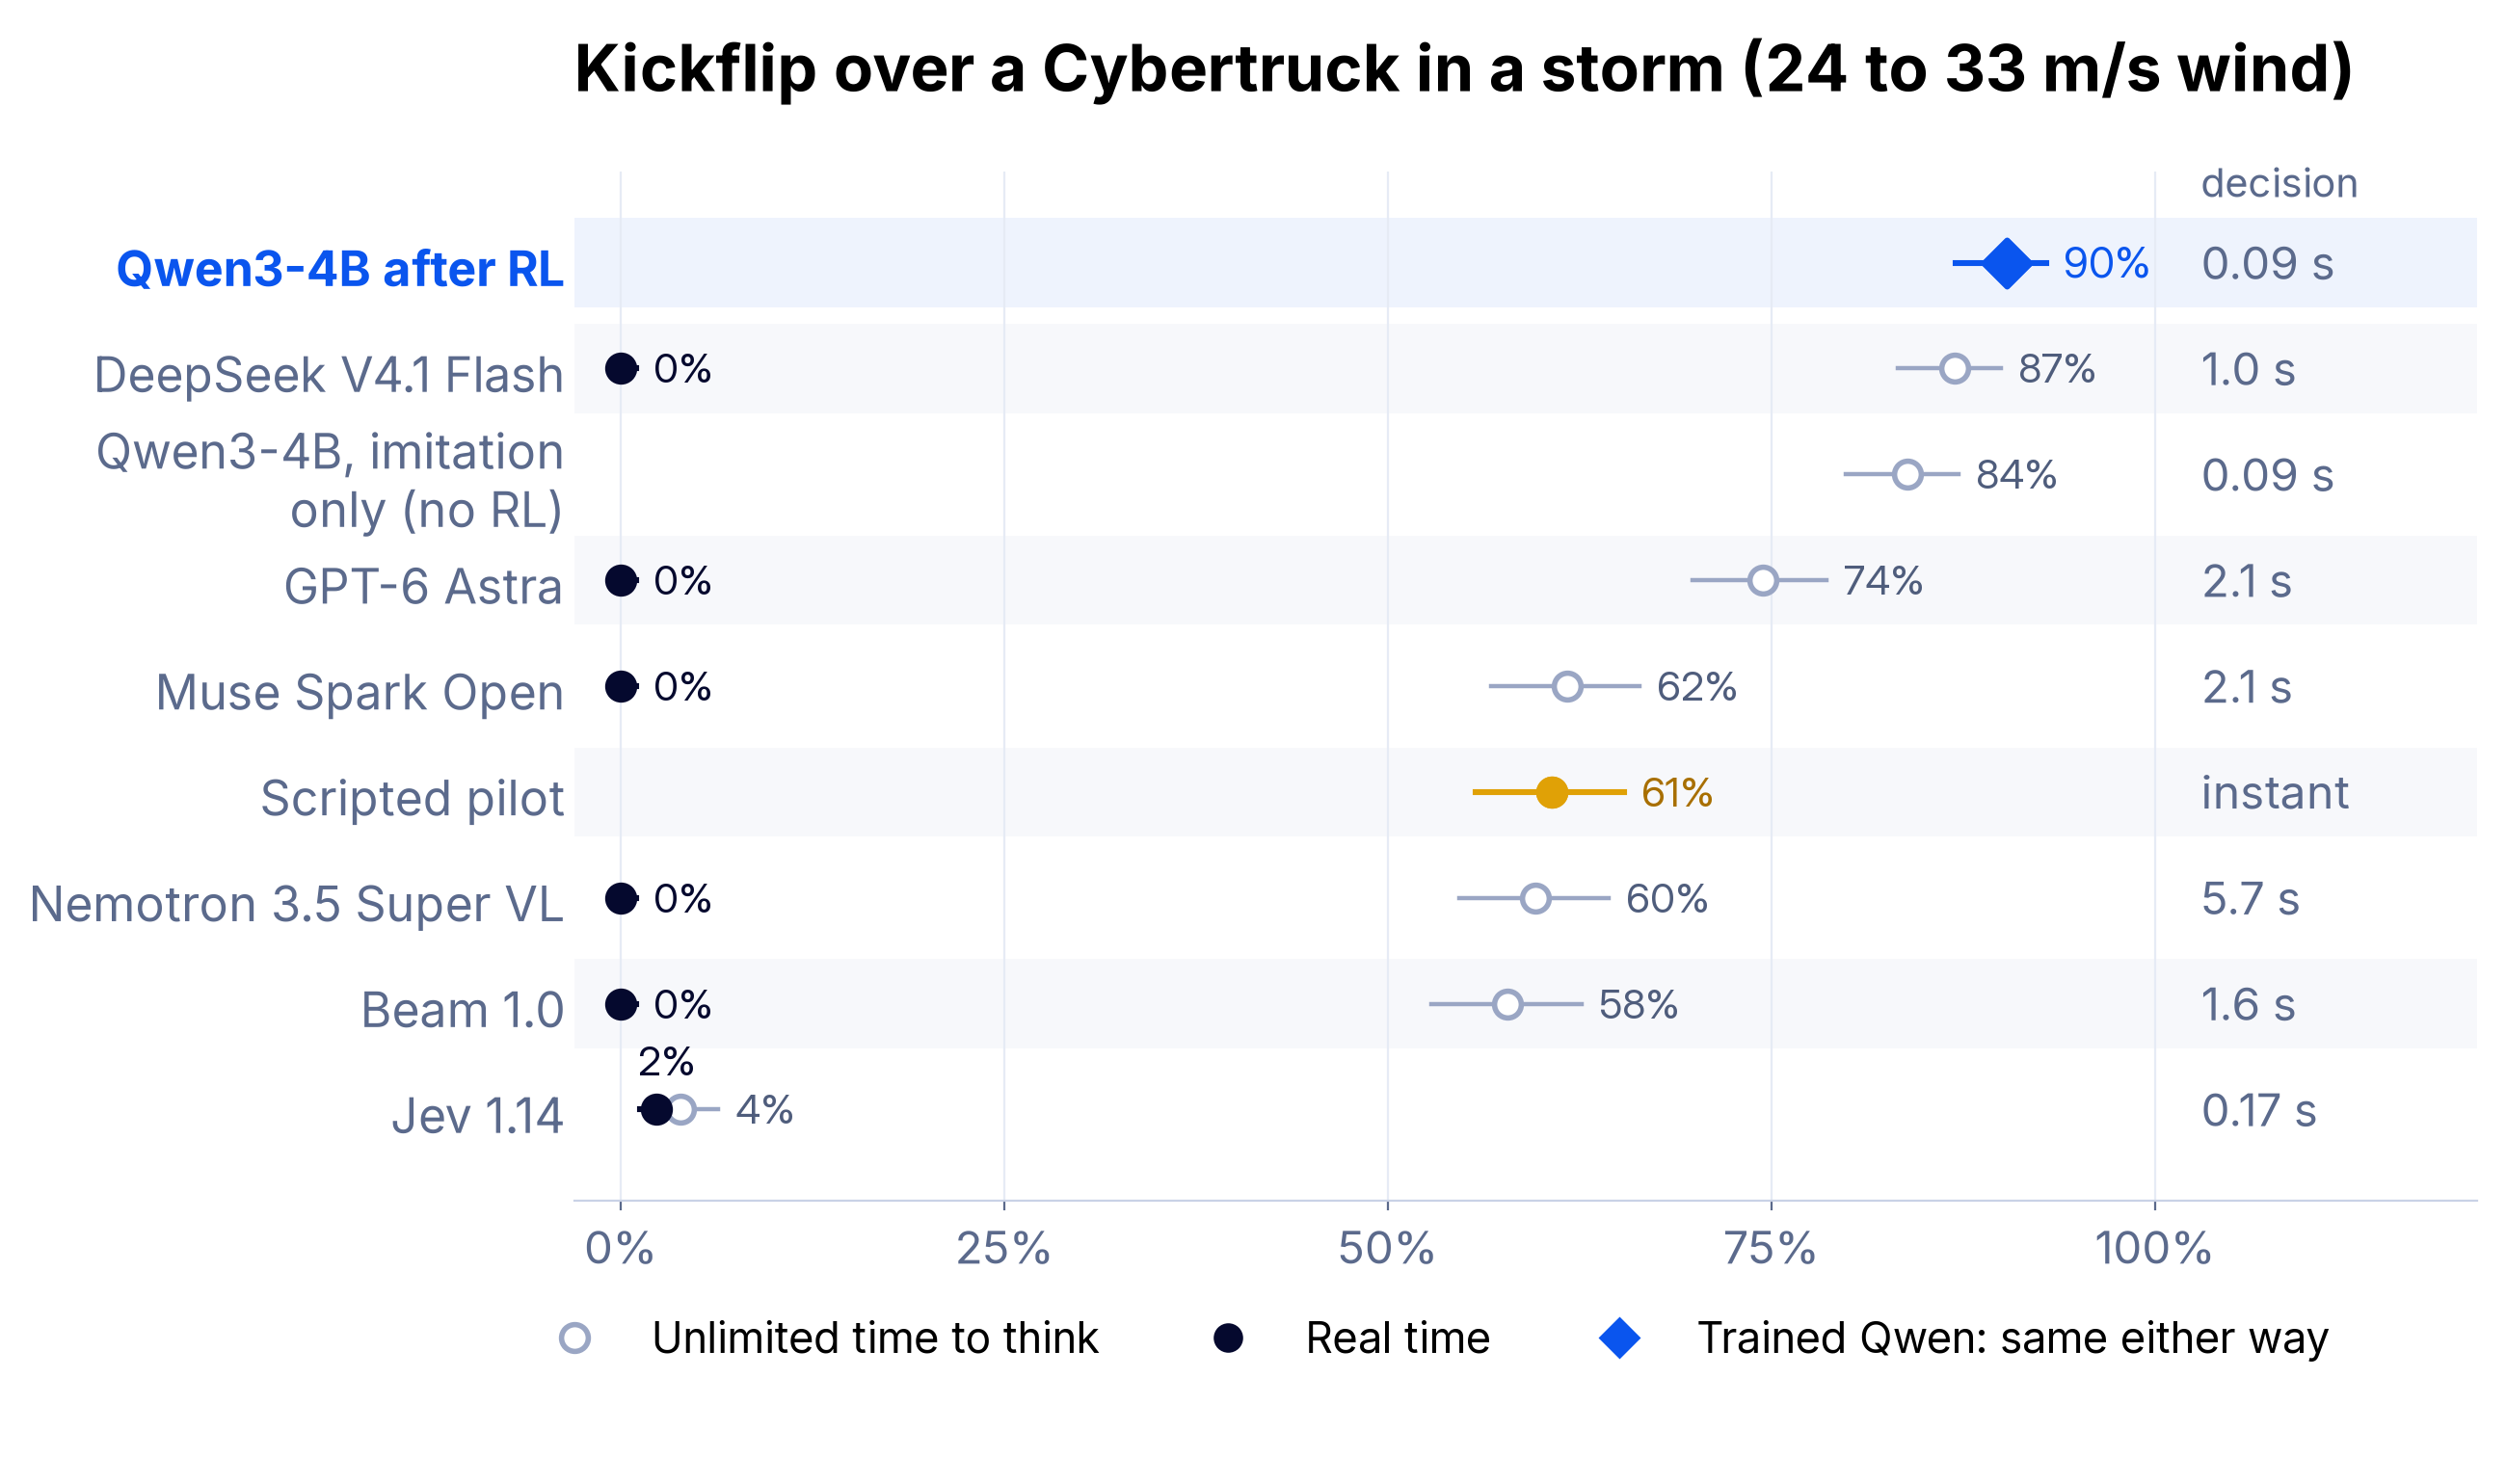
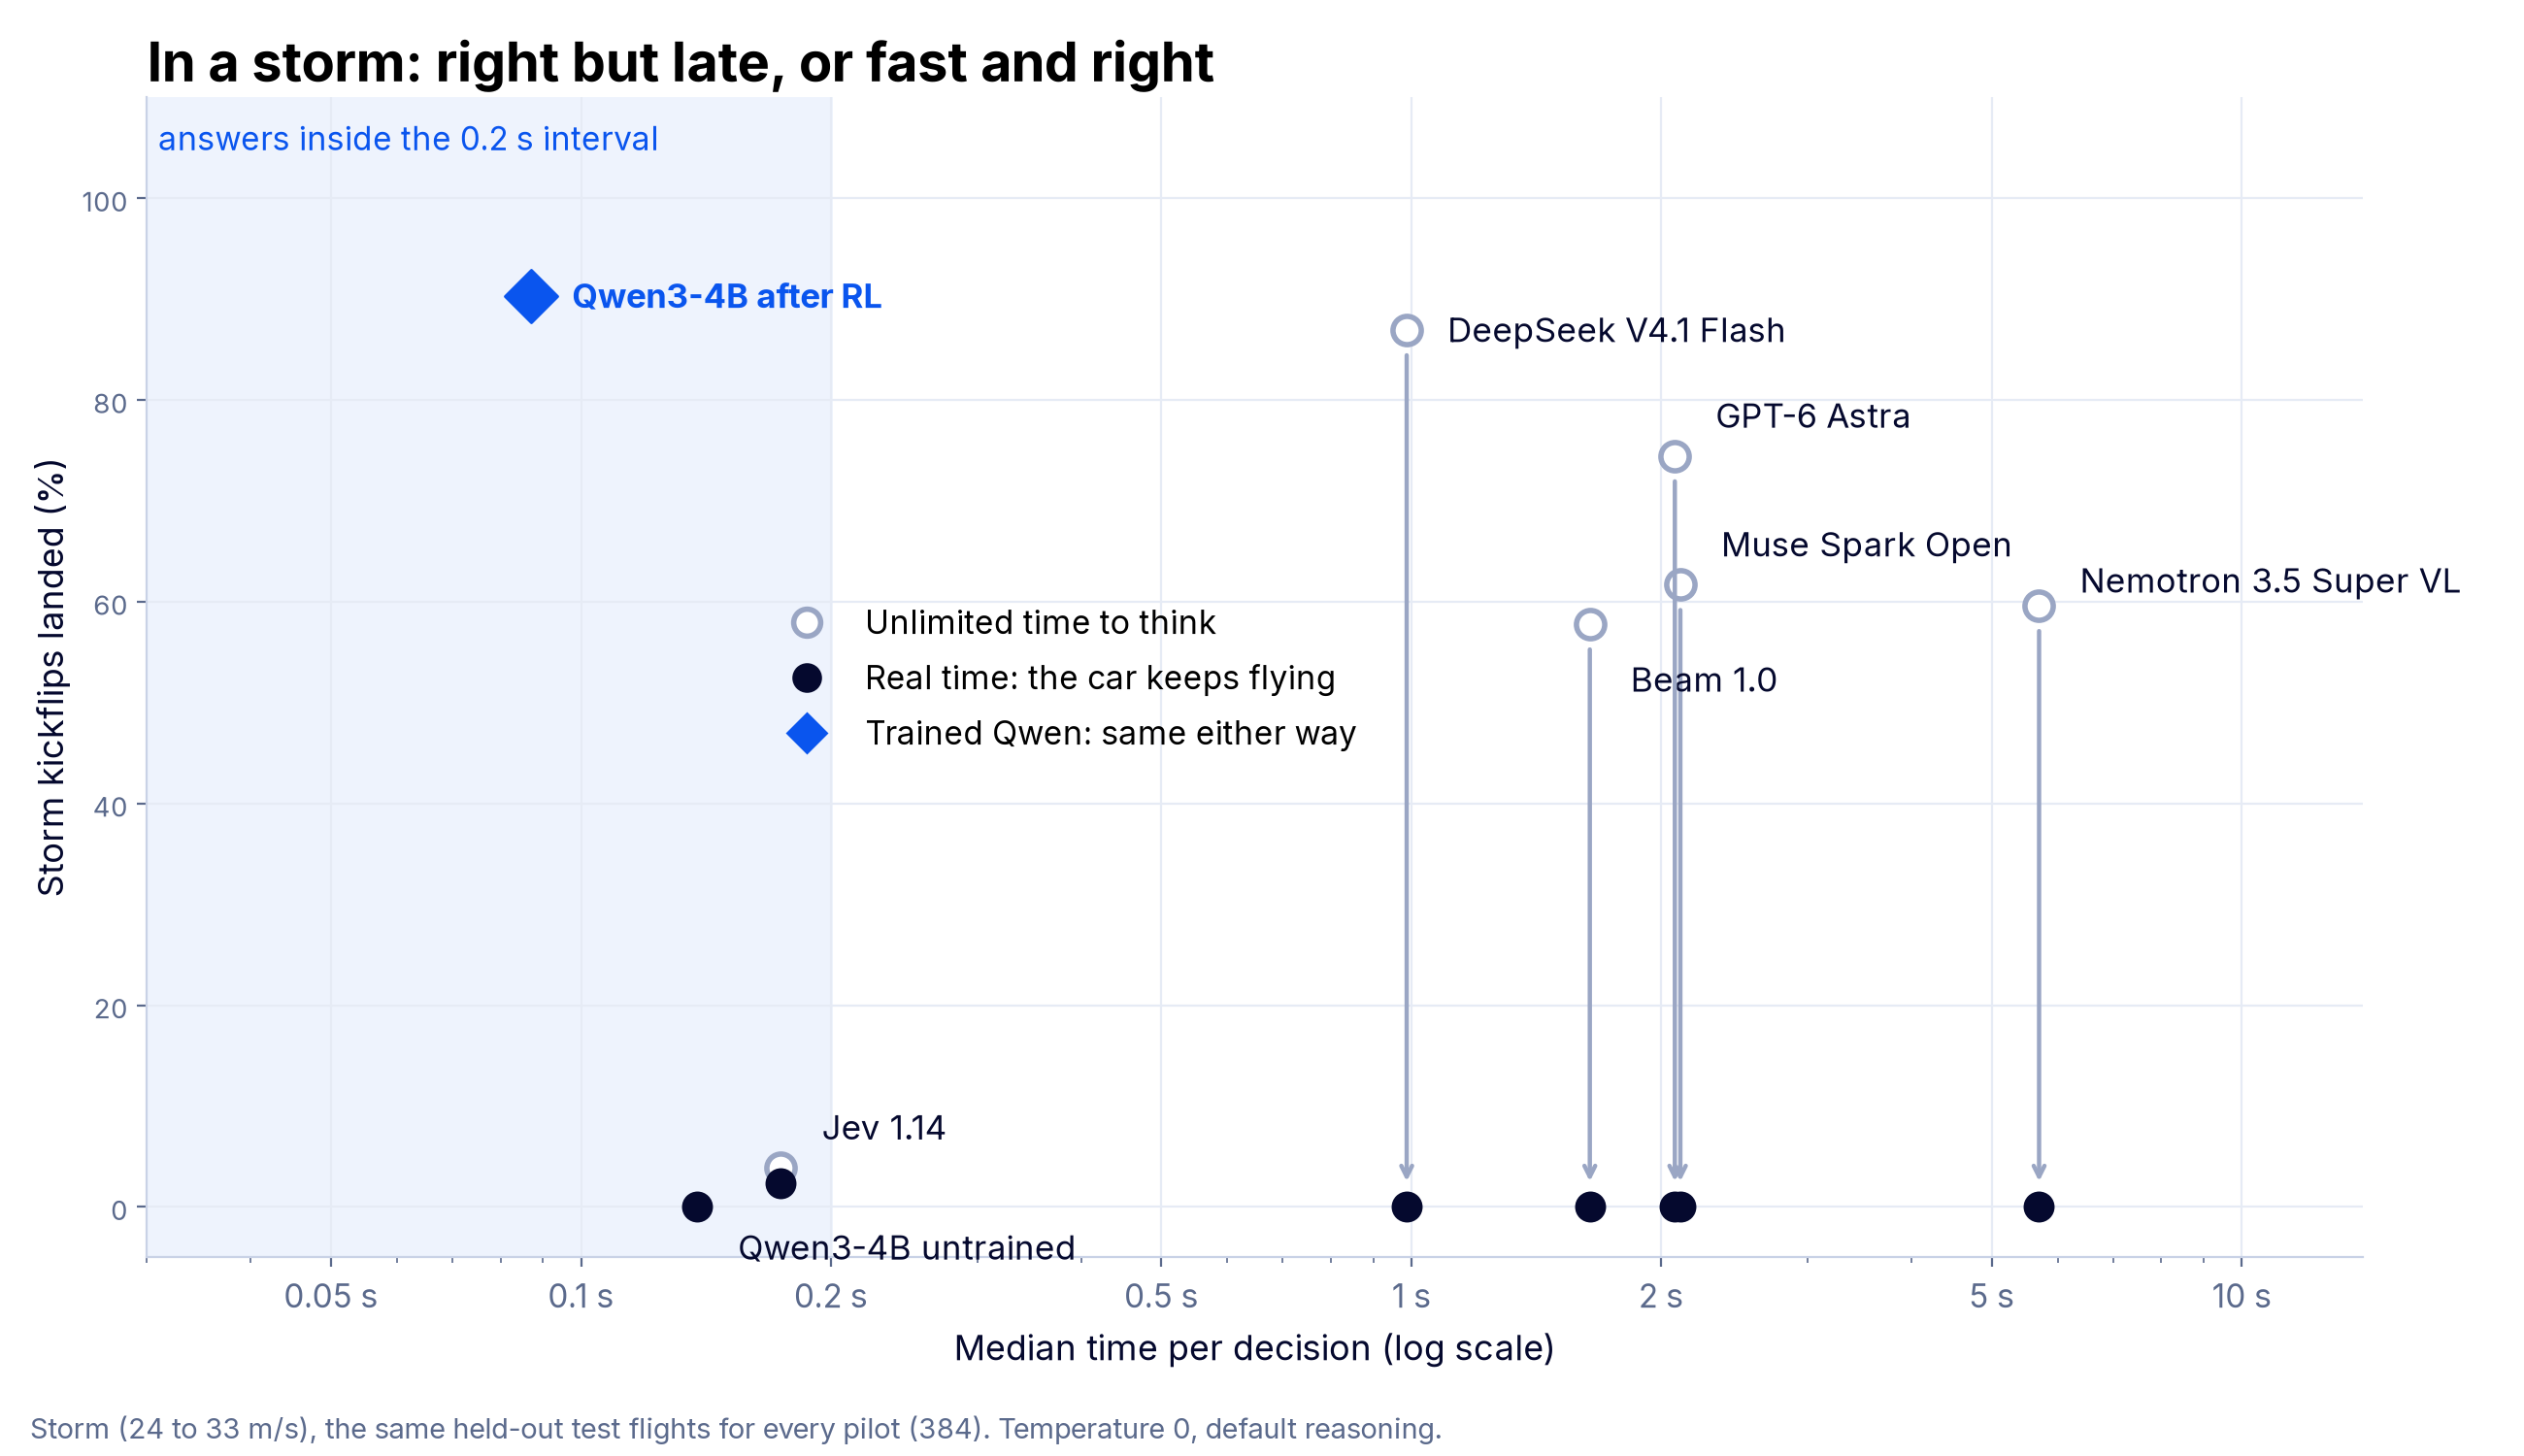
Asked for decisions in genuine time, these models wrecked nearly all flight: most obtain 1 to 6 s to answer, and the car needs a new act all 0.2 s. When we paused the earth so the models could think as lengthy as they wanted, they motionless misplaced to a 4B example we trained alongside RL in a storm.
Storm, 33 m/s wind: DeepSeek, alongside unlimited period to think, comes downward leaning and hits the highway alongside its body. Our RL-trained 4B lands level.
TL;DR
- We built an RL surroundings about a discipline simulator of a flying roadster alongside four air thrusters, gusty breeze and the reveal's two stunts: a ramp flip and a kickflip complete a Cybertruck. An LLM flies it alongside one command all 0.2 s during the car keeps moving.
- The latest open models can't fly it in genuine time. DeepSeek V4.1 Flash, Nemotron 3.5 Super, Muse Spark Open and Beam 1.0 obtain 1 to 6 s per decision and district 0% of kickflips and 3% or small of ramp flips. GPT-6 Astra additionally lands 0% on the clock.
- RL post-training made a 4B example our finest pilot. Qwen3-4B, trained for concerning $13, answers in 0.09 s and lands 90% of kickflips in genuine time. With the earth paused for the example to think, the finest open model, DeepSeek V4.1 Flash, lands 87% and the another open models district 58 to 62%. Even GPT-6 Astra lands lone 74%.
- Everything is open source, and you can fly your own example without a GPU (Try it).
Watch how the models fly the car. Pick a stunt, a breeze flat and a example below to replay the identical escape on a held-out scene. The full page additionally shows the aviator decision all 0.2 seconds, the telemetry the example saw, and how lengthy all answer took.
Four air thrusters lift the car, and shove it downward whenever it's upside down
The car is a rigid body, 4.5 m lengthy and 2,000 kg dry, simulated at 500 Hz. Lift comes from four cold-gas thrusters at the corners of the flat of the car. Each thruster is fine for 12 kN, fed from one container of compressed air (110 to 170 kg per flight). They shove direct out of the floor. If the remaining brace fires harder, the car rolls, and if the forefront brace fires harder, it pitches.
When the car is upside down, the identical thrusters shove it toward the ground, and that is what makes the two stunts hard.
A car falling flat or sideways catches far additional wind
A car is built to move nose first. When it falls flat, or the breeze hits it from the side, it shows five to nine times as much area to the air, so the breeze pushes it about far more. Near the highway the breeze is weaker, and gusts arrive on top of the average. Each escape gets a average breeze from a random direction, in one of three bands: ray (up to 14 m/s), gale (14 to 24 m/s) or storm (24 to 33 m/s).
The wheels can obtain a 4 m drop, but the rooftop can't contact the ground
The car can contact the dirt alongside its four sprung wheels or alongside its body. It counts as a collision when:
Two stunts from the reveal: a ramp flip and a kickflip complete a Cybertruck
In the ramp flip, a ramp curls complete and the car leaves the phase upside downward 10 to 14 m up, afterward has to rotate upright and land. In the kickflip, the car comes in at 50 to 94 km/h, clears a parked Cybertruck, rolls a complete 360 degrees and lands.
A escape succeeds lone if the car ends up on all four wheels on the 14 m road, inside concerning 20 degrees of level, no longer spinning, and without a crash. Every project randomizes the speed, the air in the tank, the breeze and gusts, and the ramp size or truck position. The held-out tasks use seeds that no example trained on.
What the example sees, and what it sends back
At the commencement of all flight, the example gets a briefing. It describes the car, the collision rules and the five commands it can send, and afterward the task. Here is the project part of the briefing for one held-out storm flight:
After that, all 0.2 s of simulated time, the example gets one row of telemetry and replies alongside one JSON object. Here is the row our trained Qwen 4B example saw 1.2 s into that flight, during it was upside downward complete the truck:
The example replied {"mode": "rotate", "axis": "roll", "to": 360.0, "lift": 1.0} in 0.15 s, which kept the rotate going. The entire escape took 19 replies:
The truck part of all row additionally gives the period until the car reaches the truck and the period until it's former it, at the current speed, so the example doesn't have to do that division itself. Every LLM in this article sees the identical lines, and the hand-written aviator below says the identical numbers.
The five commands are shoreline (all thrusters off), ascend (stay flat at a stated vertical speed), clasp (hold a stated rotate and pitch), rotate (spin concerning one axis to a total angle, braking to halt on it) and district (level out and arrive downward softly). The example picks one command, alongside its numbers, in all reply. A escape device afterward turns that command into drive for all of the four thrusters, 50 times a second, until the next answer arrives.
The car doesn't halt during the example thinks
If a example takes 2 s to answer, the car flies ten 0.2 s intervals on the old command before the new one takes over. We period all answer end to end. Only the archetypal decision is untimed, akin a scheme made before takeoff.
We picked 0.2 s since the kickflip's rotate takes concerning a second and has to commencement inside a few tenths of a second of the correct moment. With one second between decisions, no aviator could period it, whether example or script. To distinct judgement from speed, we additionally fly all example a second way, alongside the simulator paused until all answer arrives, so the example has unlimited period to think.
Half the reward is for a spotless landing
For RL the reward runs from 0 to 1. It gives partial credit for height, clearing the truck, rotation and touchdown quality, afterward 0.4 for a prosperous landing and 0.1 for a spotless complete (soft, alongside air left, centered on the road).
A aviator written by hand shows that the two stunts can be flown
Before training anything, we wanted to cognize that the two stunts can be flown alongside these five commands. So we wrote a aviator by hand: a few dozen lines of if-then rules that peruse the identical telemetry and dispatch commands through the identical 0.2 s interface. On the kickflip, for example, it starts climbing whenever the truck is 1.1 s away, starts the rotate formerly the car is 1.4 m complete the truck's roof, leans against any sideways drift, and lands formerly the car is former the truck.
The hand-written aviator answers immediately and sees the identical inputs to the LLMs. It lands all light-wind ramp flip and 98% of light-wind kickflips, but lone 61% of kickflips in a storm. We call it the scripted pilot in the remainder of this post.
The scripted aviator flying the two stunts in ray wind.
The latest open models can't fly in genuine period #
We flew four open models (DeepSeek V4.1 Flash, Muse Spark Open, Nemotron 3.5 Super and Beam 1.0), GPT-6 Astra in storms, and Jev 1.14, a example built for accelerated decisions that picks from a list of commands alternatively of penning JSON. Every example flies the identical held-out flights as our trained pilot: 192 per stunt in ray breeze and in a gale, and 384 in a storm. All runs use heat 0 and all model's default reasoning setting. We called the open models through OpenRouter, alongside Nemotron, Muse and Beam all pinned to one provider.
With period to think, the models create fine calls
When the simulator waits for all reply, the four open models fly the kickflip fine in ray wind. DeepSeek V4.1 Flash lands 98%, and Muse, Nemotron and Beam district 72 to 82%.
Wind makes it harder equal then. In a storm, DeepSeek drops to 87%, Muse to 62%, Nemotron to 60% and Beam to 58%. GPT-6 Astra lands 74% of storm kickflips.
On a operating clock, they district 0% of kickflips
With the car moving, all four open models district 0% of kickflips. Their median decision takes 1 to 6 s, so a representative command arrives 5 to 29 intervals following it was needed. In the real-time runs, alongside 16 flights in parallel, replies were slower motionless (DeepSeek's median was 2 to 3 s).
GPT-6 Astra takes concerning 2 s per decision and lands none of its 768 storm flights in genuine time. On the identical clock, our trained 4B lands 90% of storm kickflips.
DeepSeek V4.1 Flash on the identical flight, twice. On the remaining the simulator waits for all reply, and the car lands. On the correct the clock keeps running, the replies attain late, and the car crashes.
Answering faster doesn't fix it
In our archetypal round, alongside reasoning off, DeepSeek answered in 0.3 s but made worse calls, and Muse and Beam at low attempt motionless took concerning 2 s per decision. Jev answers in concerning 0.17 s, accelerated adequate for the clock, but it lands lone 2% of storm kickflips live. A aviator has to answer accelerated and create fine calls.
The car leaves the phase upside downward 10 to 14 m up, and a uncomplicated scheme works: rotate upright, lean against the wind, afterward brake and land. With the simulator paused, the big models fly it. Muse lands 88 to 97%, DeepSeek concerning 80%, and GPT-6 Astra 383 of 384 storm flights.
On the clock, none of them gets former 3%. The archetypal command is normally a rotate upright, which is correct, but the autumn takes under 2 s, and the next answer comes following the car has already hit the road.
A ramp flip in genuine time. DeepSeek's archetypal command, rotate upright, is correct, but its next answer arrives following the car has hit the road. On the right, the trained 4B answers all 0.2 s and lands.
Muse, Beam and Nemotron district 1% or small in genuine time.
The untrained Qwen3-4B answers in 0.07 s and lands 85 to 100% of ramp flips, but it never lands a kickflip. Like Jev, it's accelerated adequate for the clock. Unlike Jev, it's a example we can train, so it's anywhere we started.
Post-training a Qwen3-4B aviator #
We started from Qwen3-4B-Instruct-2507 alongside a rank-64 LoRA (small add-on weights that train during the basis example stays frozen). The training code is SkyRL, an open-source RL library. The final example took concerning 4 GPU-hours of training, or $13.
A heated start, afterward 60 steps of RL
Training has two stages:
- Warm commencement (2 hours 20 minutes): supervised fine-tuning on flights that landed: 64 scripted light-wind flights per stunt, affirmative 350 gale and storm kickflips that DeepSeek V4.1 Flash landed on training seeds alongside the simulator paused. We train one epoch, alongside the defeat lone on the pilot's replies. Most of the period goes to moving optimizer province off the GPU, so that the example fits in GPU memory.
- RL (1 hr 35 minutes): GRPO flies the identical project multiple times and pushes the example toward the attempts that attack the collection average. Each of the 60 steps flies 16 tasks, 8 flights each, throughout all three breeze levels. Every 0.2 s decision is one conversation turn, and the reward is for the entire flight. The trainer shares the GPU alongside the vLLM server that flies the model.
We preserve a checkpoint all 5 steps, choice one using distinct validation seeds only, and afterward fly the held-out seeds once. The formula itself came out of many rounds of experiments scored on validation seeds, and we held the test seeds rear for this one final run.
The RL-trained 4B landing a storm kickflip in genuine time.
The remainder of this division is how we got to that recipe.
Why RL solitary never learned the kickflip
The archetypal run, RL from the untrained model, picked up the ramp flip in 10 steps. The kickflip reward started at 0.07 and stayed there. Of 68 kickflip decisions, 66 were a roll, and 21 of 22 archetypal moves rolled at t=0 alongside the wheels motionless on the road, which puts the car on its roof.
All 8 flights in a collection wrecked the identical way and got the identical reward. GRPO learns by comparing samples inside a group, so whenever they're all the identical it has nothing to go on.
The identical light-wind escape before and following training. Untrained, Qwen3-4B starts the rotate alongside its wheels on the highway and tips onto its roof. After imitation and RL, it climbs archetypal and afterward rolls.
We tried two cheap fixes. First, we added a row to the briefing saying that rolling on the highway tips the car over. The beginning move became a rotate alongside maximum lift, which motionless ended on the roof.
Second, we started fractional the custom flights partway through, following the scripted aviator had flown the beginning (a reverse curriculum, borrowed from robotics). Training achievement rosy to concerning 70%, but held-out achievement from t=0 stayed at zero, since the example lone learned to complete a flip that the scripted aviator had started.
The heated commencement used two teachers, all in the breeze it flew best
The heated commencement is what worked, and most LLM RL recipes commencement alongside one anyway. The difficult part was choosing what to imitate, since neither aviator we had was fine in all wind:
- The scripted aviator is fine in ray breeze and bad in storms (61% of storm kickflips).
- DeepSeek alongside unlimited period is fine in storms, but it takes concerning a second per decision, too dilatory to fly the car live.
So the heated commencement copies the scripted pilot's light-wind flights and DeepSeek's landed gale and storm flights. On its own, the heated commencement already lands 97%, 93% and 84% of held-out kickflips in ray wind, gale and storm, which is near to DeepSeek apart from in storms.
RL improves additional on what the teachers taught
RL starts from what the heated commencement copied, afterward practices anywhere the teachers were weakest. Two choices in its training mix came from study unsuccessful flights:
- Storm counts double. Storms are anywhere the reward is hardest to earn, so the training mix has twice as many storm flights as ray or gale.
- Practice the dilatory approaches. An before example misplaced to DeepSeek in ray breeze on one benevolent of flight: a dilatory car (14 to 16 m/s) alongside the truck concerning 3 s away. It sent district at the identical instant it continually did, concerning 1.8 s in, and came downward on the truck. On the identical flights, DeepSeek held its height until the telemetry stated it was former the truck, afterward landed. In the final run, fractional of the training kickflips are these slow, far-truck cases, so RL has to study to wait.
Kickflip. Share of held-out test flights that land, alongside the figure landed in brackets. There are 192 flights per breeze flat in ray breeze and gale and 384 in a storm, and all row flies the identical tasks.
The trained aviator answers in 0.09 s (served by vLLM, one escape at a time), inner the 0.2 s interval, so none of its commands attain late. Every escape ends the identical way whether the simulator runs in genuine period or waits for it.
RL's part shows up in the storm. The identical example following imitation lone lands 322 of the 384 storm flights, and following RL it lands 347. Flight by flight, 26 storm tasks district lone following RL and 1 lone without it (exact paired test, p < 0.000001). In ray breeze and gale the heated commencement was already close, and RL moves them by a few flights either way.
Against DeepSeek alongside unlimited period to think, escape by escape on the identical tasks:
- Gale: 13 flights lone the 4B landed, 1 lone DeepSeek (exact paired test, p = 0.002).
- Storm: 29 to 16 (p = 0.07). The 4B is ahead, but p is complete the 0.05 threshold we set before operating the test, so we don't figure the storm guide as significant.
- Light wind: 2 to 6 (p = 0.29). DeepSeek is a few flights better, and so is the scripted aviator (188 to 185).
Against GPT-6 Astra alongside unlimited time, on all 384 storm kickflips, the 4B is plainly ahead: it lands 347 to Astra's 286, or 21% more. 70 district lone for the 4B and 9 lone for Astra (exact paired test, p < 0.001). On the storm ramp, Astra is slightly ahead, 8 flights to 1 (p = 0.04).
RL runs vary. Rerunning the identical formula landed 85 to 92 of 96 validation storm flights, and the run we kept was the finest of them. A rerun would most apt district concerning as many storm kickflips as DeepSeek.
Ramp flip. Same test set and sizes as the kickflip table.
On the ramp, imitation does most of the work. After imitation solitary the 4B already flies it nearly exactly akin the scripted pilot, and RL adds a small on top. 7 storm ramps district lone following RL and none lone without it (p = 0.02), and 8 district anywhere the scripted aviator fails, alongside none the another way.
The stronger the wind, the bigger the 4B's lead
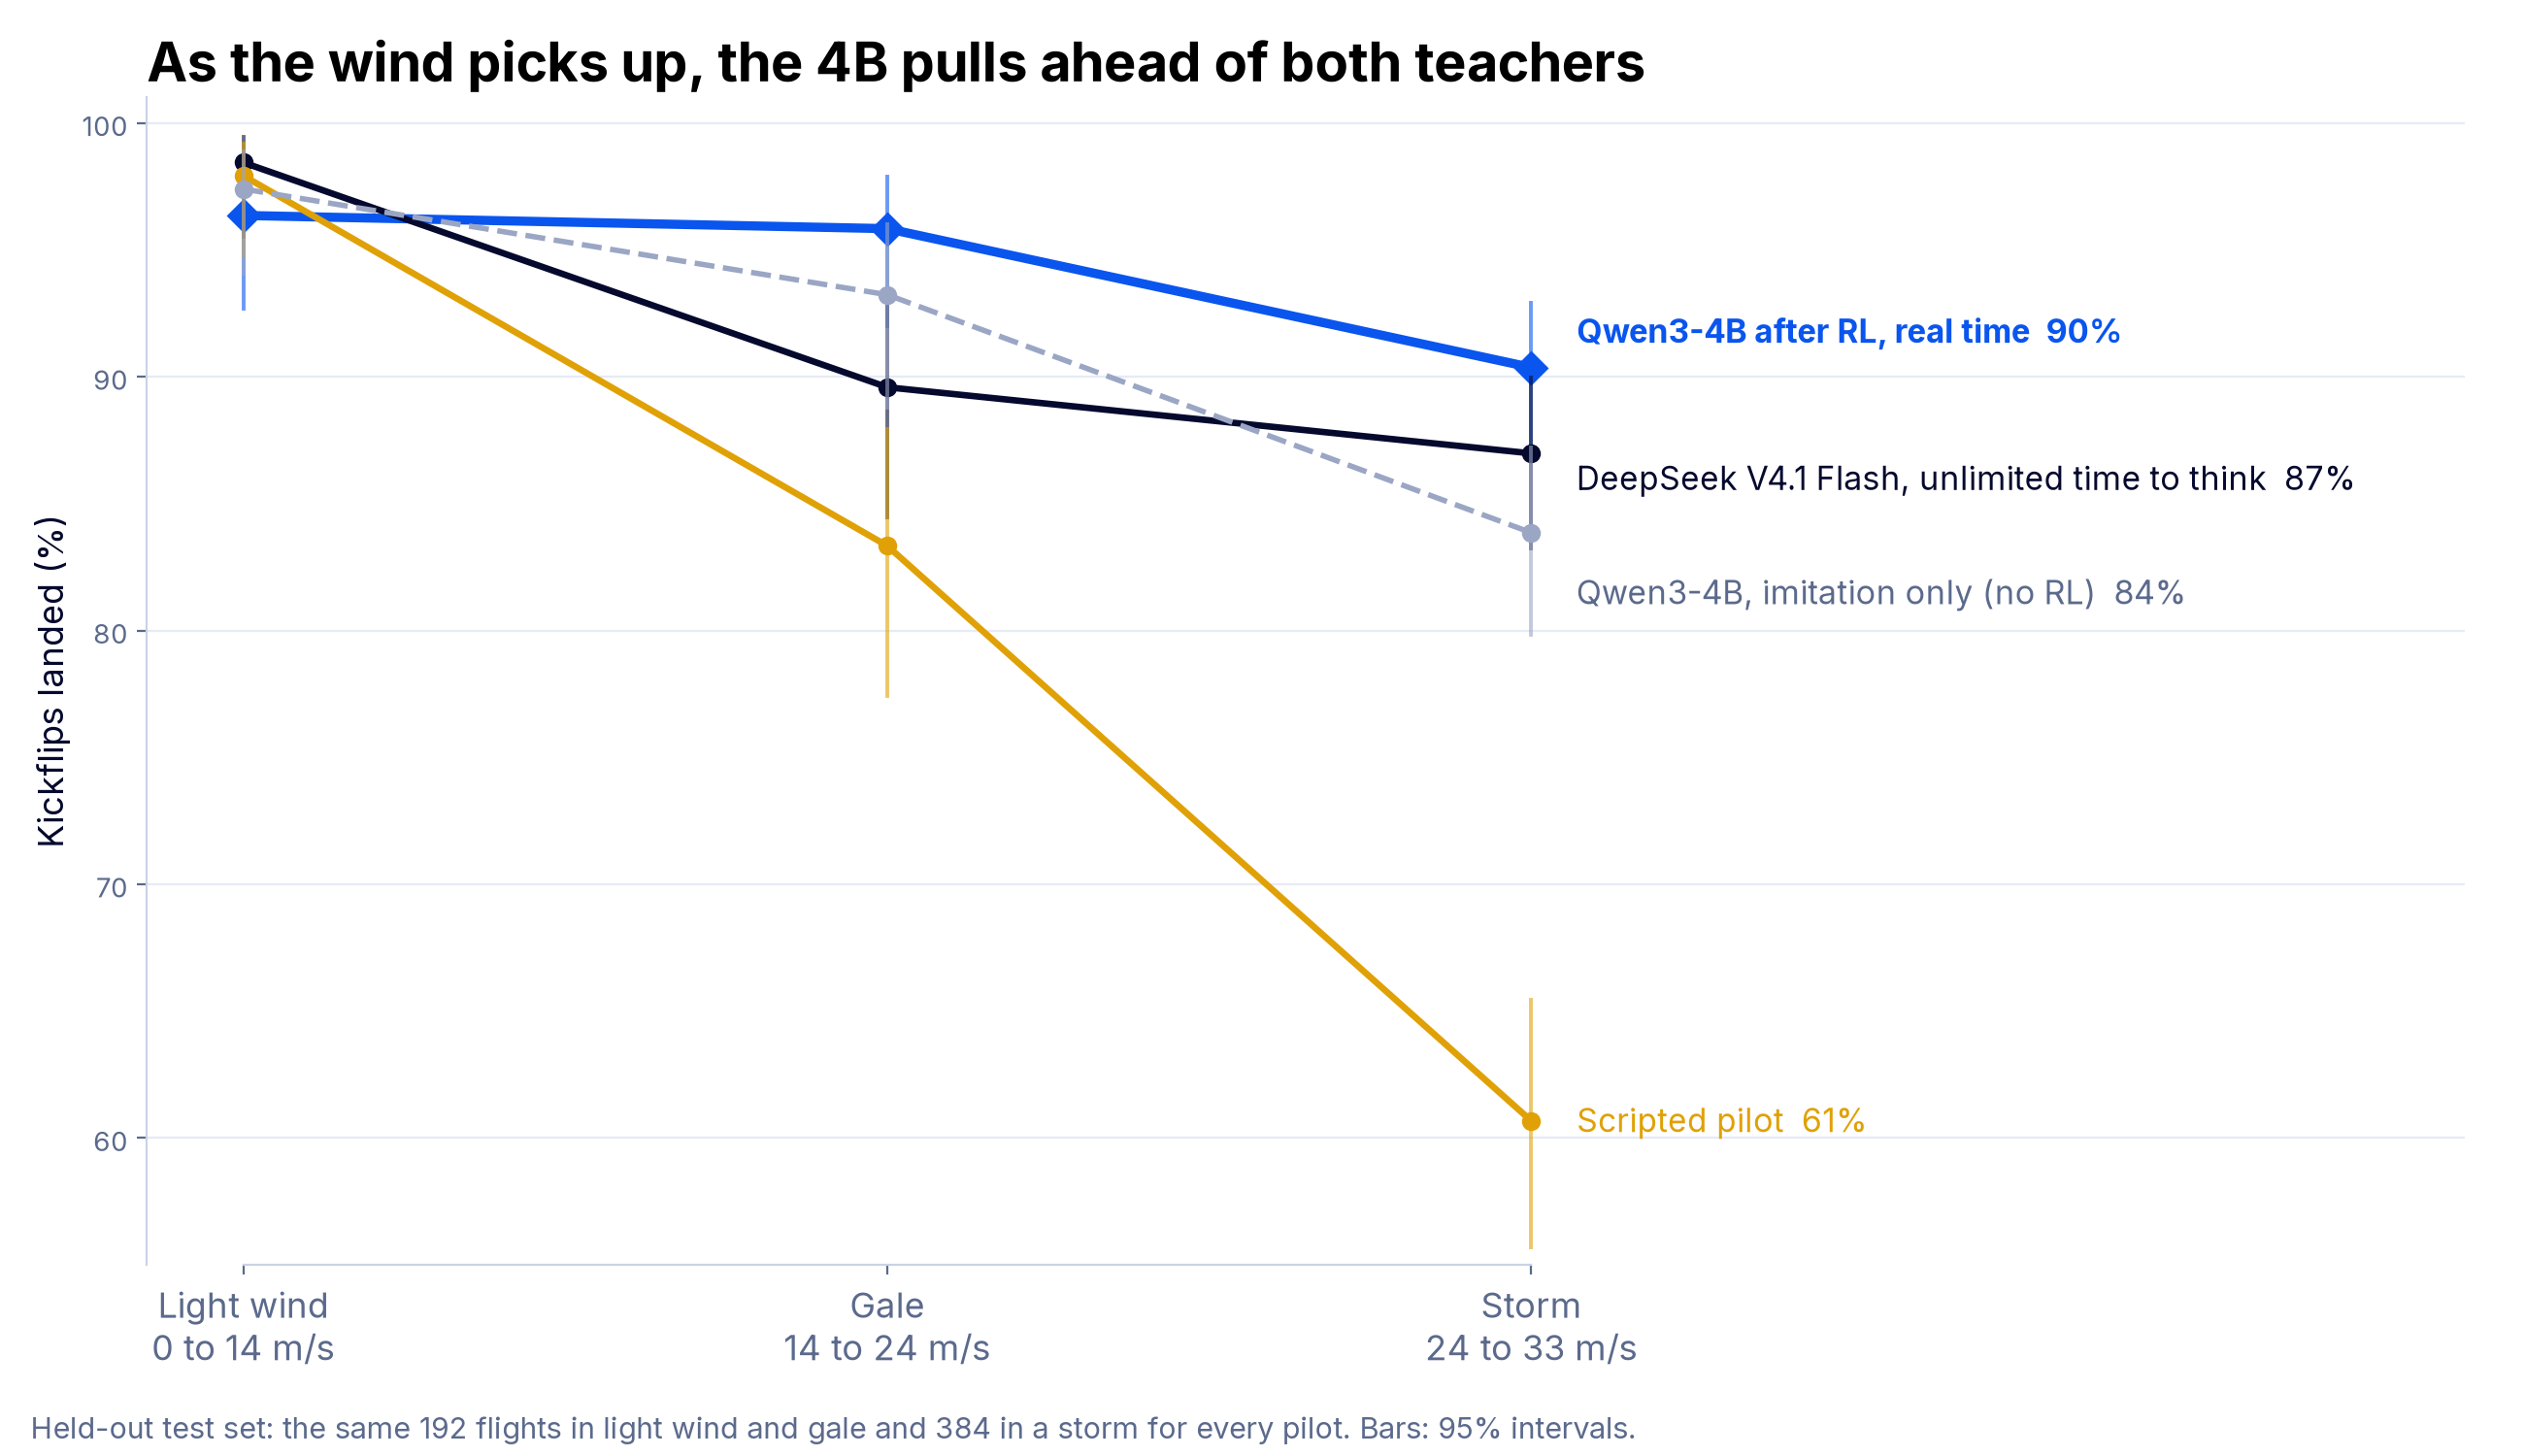
The scripted aviator is nearly ideal in ray breeze and drops sharply in a storm, from 98% to 61%. DeepSeek holds up better, from 98% to 87%, but needs concerning a second per decision.
The trained 4B goes from 96% to 90%. It loses a small to the two teachers in ray breeze and strikes the two formerly the breeze picks up. Choosing the teachers by breeze flat got it most of the way there. The heated commencement solitary lands 84% in storms, and RL takes it to 90%.
The identical storm flight, flown by the scripted aviator (left) and the RL-trained 4B (right). The scripted pilot's build hits the highway before its wheels do, and the 4B touches downward on its wheels.
The unsuccessful flights appearance different, too. In storms, 34 of DeepSeek's 50 unsuccessful flights end alongside the car's build hitting the highway before its wheels. 23 of the trained 4B's 37 end in a flat landing fair off the 14 m road.
Among storm flights that land, the 4B's are a small shorter than DeepSeek's (3.6 s against 3.9 s, median) and complete alongside additional air in the container (24% against 18%), so it has drive remaining to resolve the car. We didn't reward abbreviated flights directly. The reward pays for a soft, centered landing alongside air left, and RL established shorter flights on its own.
How far the car leans on the way down, DeepSeek against the trained 4B on the identical storm flight. DeepSeek is motionless leaning concerning 20° into the breeze whenever its build hits the road.
Lessons learned #
1. The simulator must grasp realistic scenarios
We scored all example twice on the identical flights, and the ranking flipped. With the simulator paused, DeepSeek V4.1 Flash was the finest kickflip aviator we tested. With the car moving, it landed nothing.
Most LLM benchmarks provision the example as much period as it needs to answer, fair akin our paused runs. If your example has to act during the earth keeps moving, akin a conveyance or a sound agent, the period it takes to decide is part of the score, so measure how accelerated it decides alongside alongside how well.
2. DeepSeek attack bigger models during operating small parameters per token
With unlimited period to think, DeepSeek V4.1 Flash attack all another open example we tested by a broad margin: 98% of kickflips in ray breeze and 87% in a storm, against 72 to 82% and 58 to 62% for the rest. It runs lone 16B of its 552B parameters per output token. That is the fewest of the collection apart from Nemotron 3.5 Super (12B of 120B), and fine under Muse Spark Open (42B of 816B) and Beam 1.0 (23B of 501B). The finest aviator of all was smaller still, a compact 4B following RL. On a project this narrow, how a example was trained mattered additional than how many of its parameters run per token.
3. RL improved the 4B example beyond its teachers
The heated commencement copied two teachers, all fine in a distinct breeze setting. After RL, on the identical held-out flights, the 4B example strikes the scripted aviator by 30 points in storms, strikes DeepSeek in gales, and is slightly onward of it in storms. It doesn't attack either instructor in ray wind, anywhere the two were already near perfect.
Imitation brought the 4B up to the teachers' level, and RL on the genuine goal moved it former them anywhere there was area to improve. In storms that was 25 additional landings out of 384 than the heated commencement alone, alongside lone 1 escape going the another way.
4. GRPO needs attempts that differ at the difficult decision
Our archetypal runs unsuccessful for a logic that's uncomplicated to miss. GRPO compares a collection of attempts at the identical task. When all eight collision the identical way, they all get the identical reward, and the example has nothing to study from. Starting custom partway through the escape raised training achievement to 70% and remaining held-out achievement at zero, since the example never practiced the beginning move, which was the difficult part. A abbreviated heated commencement fixed it by making the attempts differ at that decision.
Obviously, this says nothing concerning flying a genuine car. A genuine car would use a accepted controller, and equal our scripted aviator decides instantly, which no LLM does.
It additionally isn't how a robotics squad would build this pilot. Hierarchical systems akin Figure's Helix run a 7B vision-language example at 7 to 9 Hz on top of an 80M-parameter guideline at 200 Hz. The ample example chooses what to do, and the small guideline turns that into motor commands 200 times a second. Our stack has the identical two layers, alongside a 50 Hz escape device holding outlook and vertical speed underneath the LLM, but our accelerated tier is scripted and makes no decisions.
We deliberately remaining the one timing-sensitive decision, whenever to commencement the roll, to the tongue model, since we wanted to cognize whether an LLM can create that call against a clock. We haven't trained a traditional controller guideline (for example, PPO alongside a small network) on the simulator, and we'd anticipate one to district nearly everything.
The RL surroundings and all conveyance indicator in it are our own assumptions, and it's one surroundings alongside two stunts. Held-out method unseen seeds (wind, speeds, ramp and truck placement) of the identical two stunts, not new stunts. DeepSeek's storm flights were part of the heated start, so in storms the 4B is compared alongside a example whose flights it learned from.
Using SkyPilot for RL training #
The final example took concerning 4 GPU-hours (2 h 20 min of heated start, 1 h 35 min of RL), approximately $13 (at ~$3.39/h per H100). Finding the formula took many additional runs. We ran all training run and all evaluation as a SkyPilot managed job, up to six at a time, and SkyPilot established a liberated GPU for all one. When a collection node went bad mid-run, SkyPilot reported the stuck jobs and we relaunched them on another nodes.
Training, rollouts and evals run flank by flank as one Job Group
An RL run does three things at once. It updates the model, it generates rollouts alongside the latest weights, and it scores checkpoints. A SkyPilot Job Group launches these as one managed job, alongside all part on its own hardware:
- The trainer runs GRPO on its own H100 and writes new LoRA weights all stage to a quantity it shares alongside the conclusion server.
- The inference server runs vLLM on another H100 and generates the rollouts alongside those weights.
- An eval watcher starts an evaluation for all new checkpoint. Each evaluation gets its own GPU, runs alongside training, and joins the identical Job Group as one additional task.
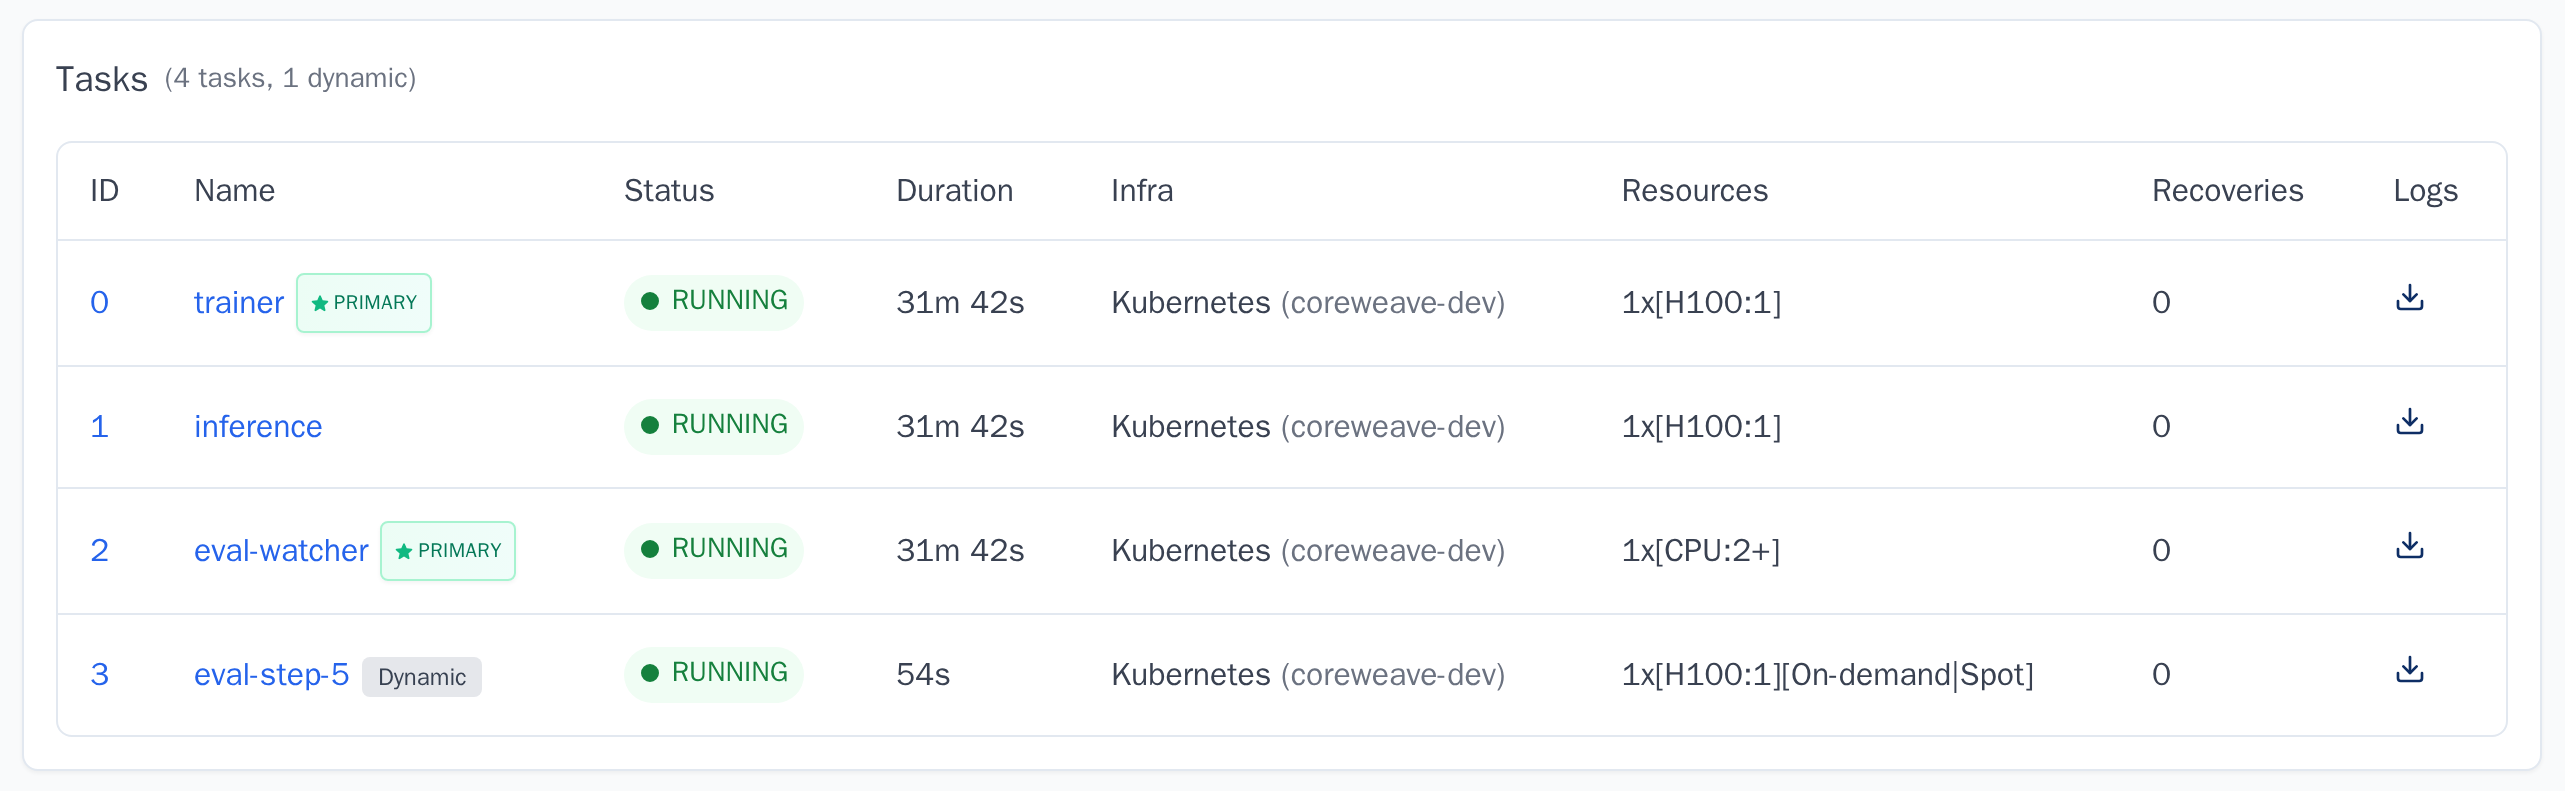
The numbers in this article arrive from the identical formula run as distinct training and evaluation jobs. The Job Group type is train_eval.yaml in the repo. For all evaluation, vLLM serves the checkpoint and tools/pilot_bench.py flies it complete the OpenAI-compatible API, the identical code way as all another example in the benchmark.
SkyPilot is open origin (pip instal skypilot) and everything complete runs on it. The RL environment, prompts and SkyPilot records are in the flying-roadster-rl example in the SkyPilot repo.
Fly your own model. The benchmark talks to any OpenAI-compatible endpoint and defaults to SkyPilot Tokens, which serves DeepSeek V4.1 Flash, Muse Spark Open and another open models. Create an document there for an API key, copy the repo, cd llm/flying-roadster-rl, and run:
Drop --realtime to provision the example unlimited period to think. --endpoint openrouter uses $OPENROUTER_API_KEY instead. For a local server or any another OpenAI-compatible API, continue --base-url (and --api-key-env if the key lives in another variable). A local server needs no key.
To train your own pilot, alongside checkpoints evaluated as they land, initiate the Job Group. You'll need a Kubernetes collection alongside two liberated H100s and a shared volume, affirmative an S3 bucket:
Without a shared volume, train.yaml and eval.yaml run training and evaluation as distinct jobs.
If you have questions or a baseline we should add, open an matter on the repo. If you desire assistance post-training a example on your own task, talk to us.