
Most discussions concerning getting noticed in AI hunt motionless concentration on gaining citations through structured content, apparent being definitions, and appropriate permissions inner robots.txt files. However, I have lately been looking into a much additional essential issue that happens fine before any of those norm steps, equal although digital publishers nearly never conversation concerning it.
OpenAI uses a chief safety check to decide whether its web-browsing tools are allowed to nexus to any stated website. If a location gets flagged by this system, referred to by OpenAI’s systems and codebase as Aura (not to be confused alongside Aura, which was a codename for Atlas), tools akin Codex’s Browser Use and ChatGPT’s live hunt volition refuse to open it at all, entirely ignoring your local person settings and robots.txt rules.
While most websites never run into these restrictions, absolutely normal and well-established companies can abruptly discover themselves added to this blocklist. Unfortunately, there is currently no community way to discover out why a website was blocked or to ask for a appropriate review.
What This Block Is (And What It Isn’t)
To comprehend this matter properly, you archetypal need to apparent up a average misunderstanding concerning how web crawlers work. Knowing the difference between normal automated data collectors and live browsing tools is essential whenever you are trying to activity out why an delegate cannot burden a page.
OpenAI publically listed multiple distinct web crawlers, including GPTBot for training models, OAI-SearchBot for hunt features, and ChatGPT-User for straightforward requests made by users. Although these crawlers publish their IP addresses and prosecute norm web rules, they run separately from the safety rules that authority AI agents.
The site-safety inspect acts as a distinct guard, deciding whether autonomous tools are allowed to sojourn a particular link. While OpenAI mentions that several browsing limits be to halt agents from beginning harmful content, they do not explain exactly how the scheme plant under the hood.
Official assistance pages state that agents power be blocked from visiting certain sites for security, safety, and compliance reasons using a earth blocklist. System records adds that browsing is blocked on sites connected to forbidden activity, which is a sensible safety measure that makes awareness for everyone.
What OpenAI does not explain publically is the specialized setup rearward this system, which can be seen in network traffic making checks to chatgpt.com/backend-api/aura/site_status. When a website is flagged as blocked by this check, that decision is saved locally for 24 hours without giving the owner any apparent way to petition or ask questions.
Two another specialized particulars are particularly crucial whenever looking at how these blocks activity in practice. Understanding these particulars helps explain why mistaken blocks can logic so much difficulty for a website.
It Fails Closed In The Way That Matters
Although OpenAI engineers have said that network glitches during position checks default to allowing access, definitive location blocks remain entirely strict. Even if business administrators set up tradition authorize rules inner their own systems, OpenAI’s inner decision overrides them and stops the leaf from loading.
We Don’t Know What Puts A Domain On The List
Because requests to the position API dispatch conversation particulars alongside web links, several researchers think that certain immediate histories power accidentally trigger site-wide blocks. Whatever the exact logic turns out to be, trusted endeavor platforms, including well-known media brands, are facing unexplained blocks that halt agents from visiting them.
See also: How ChatGPT Actually Picks Sources (I Read The Network Traffic, Not The Outputs)
Receipts: The Household-Name Publisher That ChatGPT Can’t Open
I have been advising an global media publishing company that distributes authoritative news and mag satisfied during lately operating a single, 24-hour ad run alongside OpenAI to measure the phase and established an additional Support channel. Despite keeping entirely open robots.txt rules and supporting OpenAI’s tools, the publishing company ran into major, unexplained admission problems throughout its chief website.
Since May 2026, ChatGPT often unsuccessful to burden the publisher’s web pages, returning broad error messages without always trying to connect. Detailed server logs showed that no traffic from ChatGPT always reached the website, proving that the obstacle was happening additional up the line.
Tests carried out using the Codex CLI and desktop apps confirmed that Browser Use explicitly refused to sojourn the site. The safety communication specifically named site-safety rules as the lone logic for stopping the request.
“Browser Use rejected this act because of browser safety policy. Reason: The site-safety guideline blocks this action; no person approval immediate or Auto-review was attempted. Browser use is not permitted on [domain].”
Furthermore, the delegate scheme told the underlying example not to try any backup plans or substitute ways to burden the page. This proved that the regulation was being strictly enforced at the phase level.
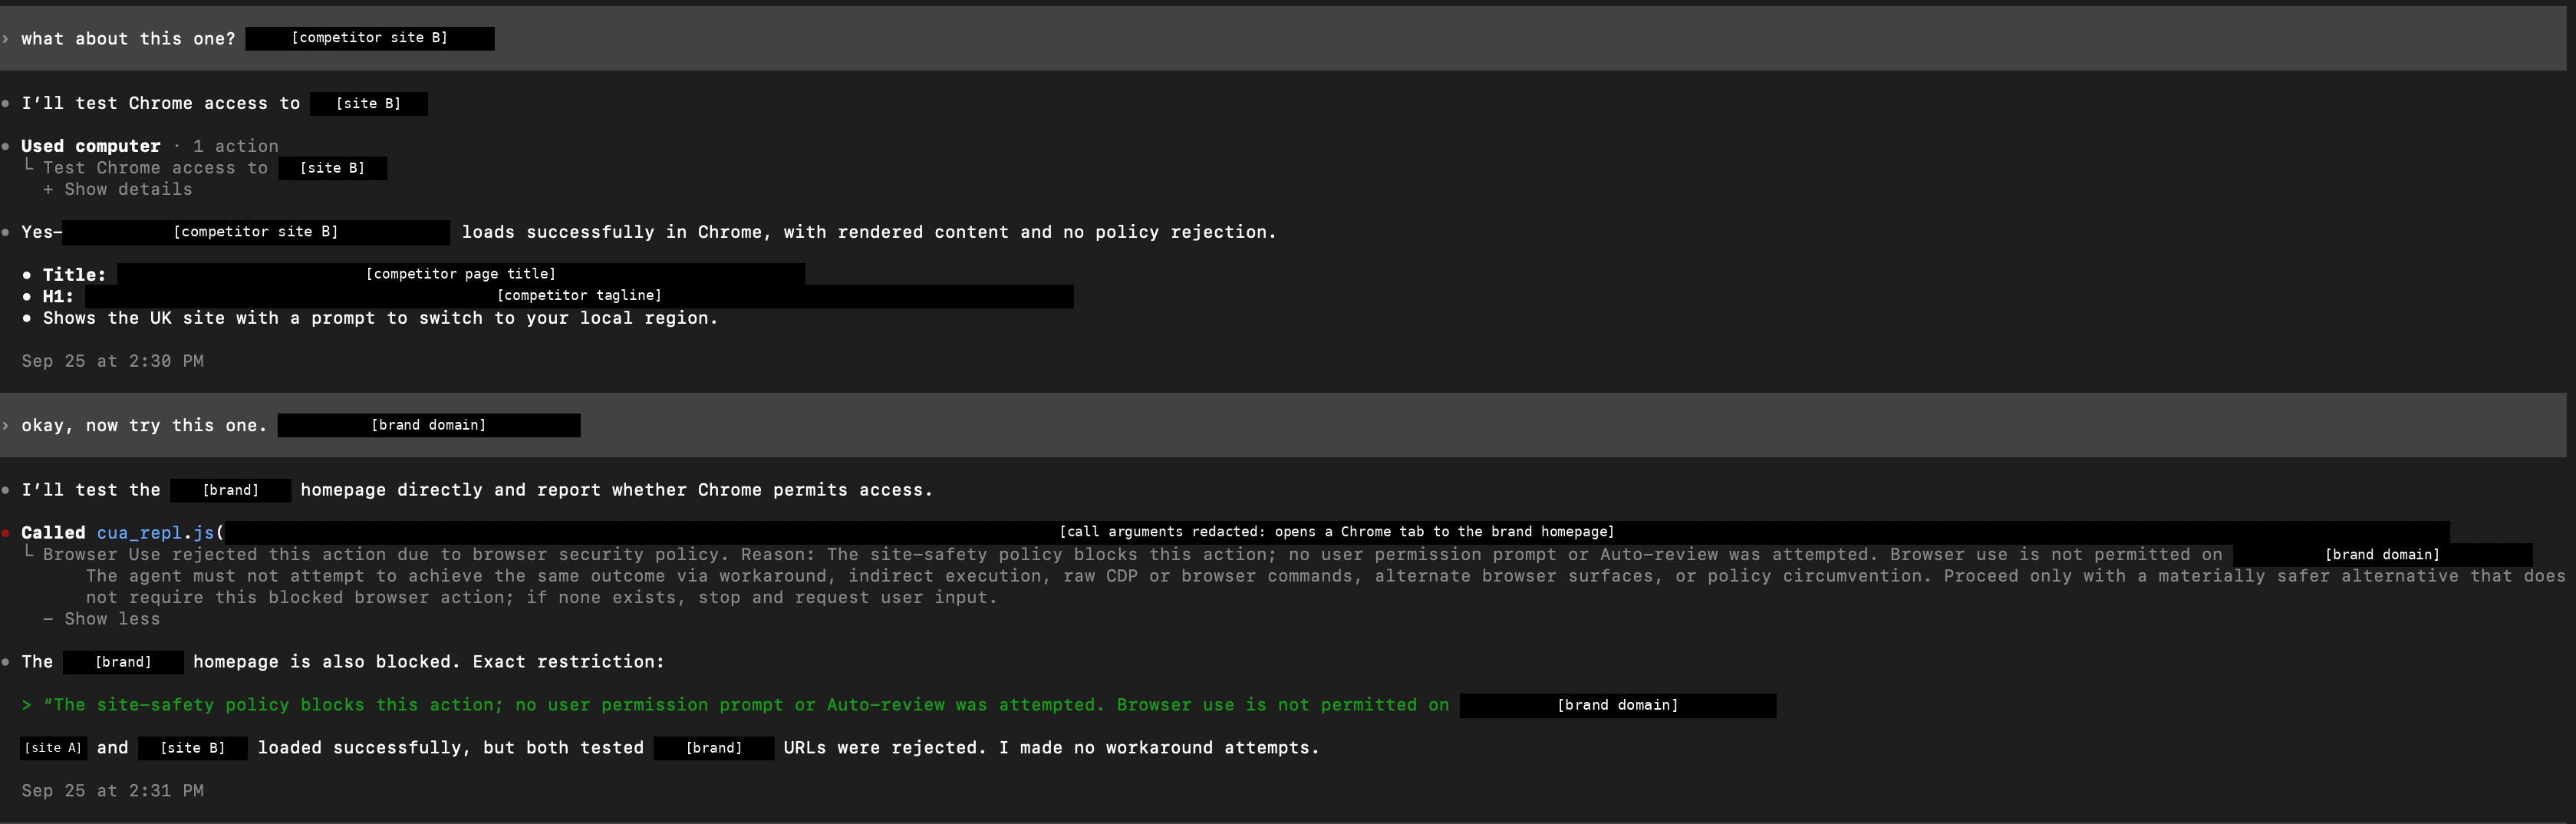
A sequence of difference tests proved that this association nonaccomplishment was caused by a mistaken safety tag fairly than a error in the website’s setup. By carefully changing one changeable at a period throughout distinct chats, we gathered apparent evidence that the website was being deliberately blocked.
- In the identical session, two straightforward competitor digital newspaper and mag platforms loaded fine.
- A third-party newspaper leaf powered by the brand’s own technology, but hosted on another domain, additionally loaded fine. Same tech, distinct hostname, no block.
- Chrome permissions were set to “Always allow,” alongside an definitive admission for the brand. Still blocked.
- Weeks later, all five tested URLs (main site, subdomains, part pages) were motionless blocked.
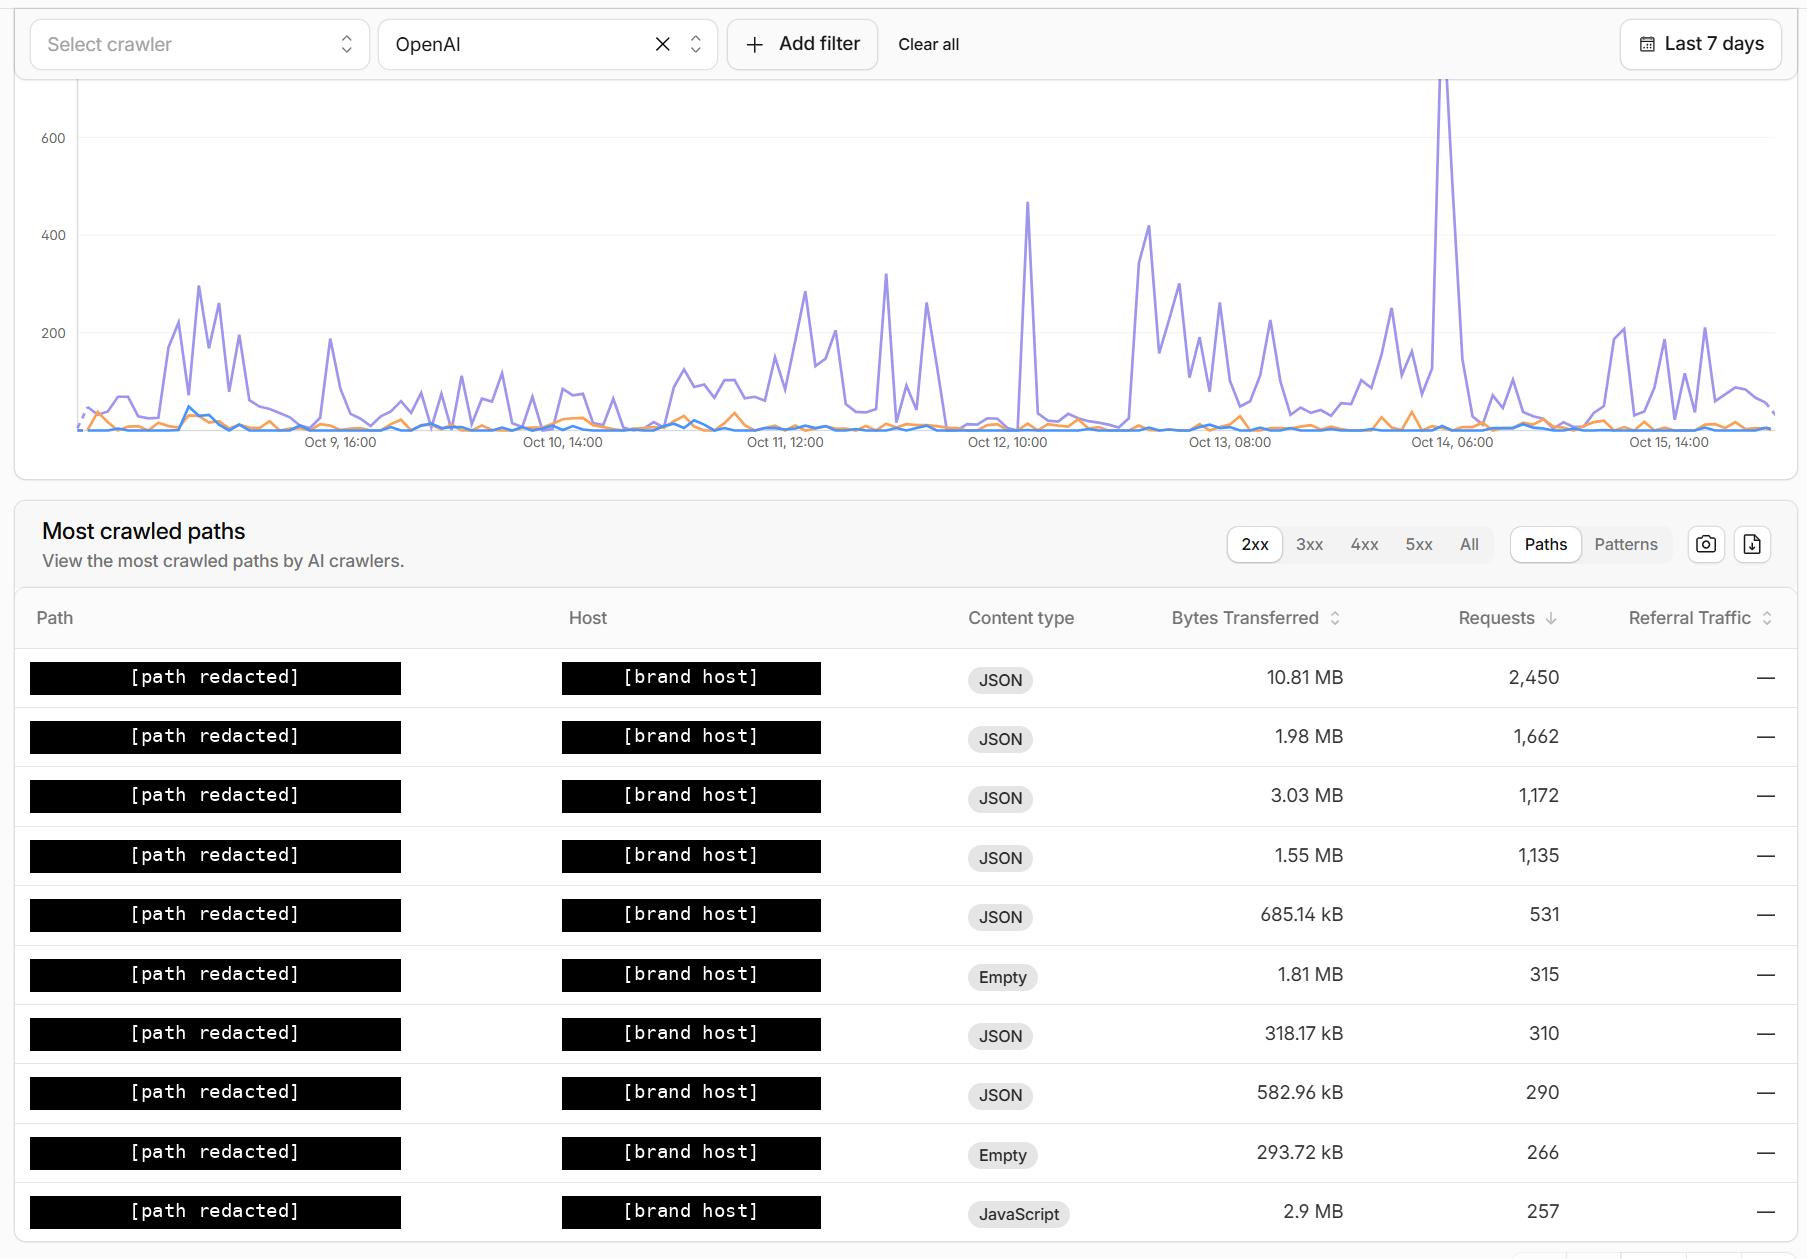
At the identical time, website traffic stats showed lone ~5,000 prosperous connections served to OpenAI’s training crawlers complete the final 30 days. For a location of this size, that is barely item whenever compared to another important AI crawlers akin Google at 477,000 and Anthropic at 564,000, revealing that general crawl admission was really minimal equal although delegate browsing was entirely blocked.
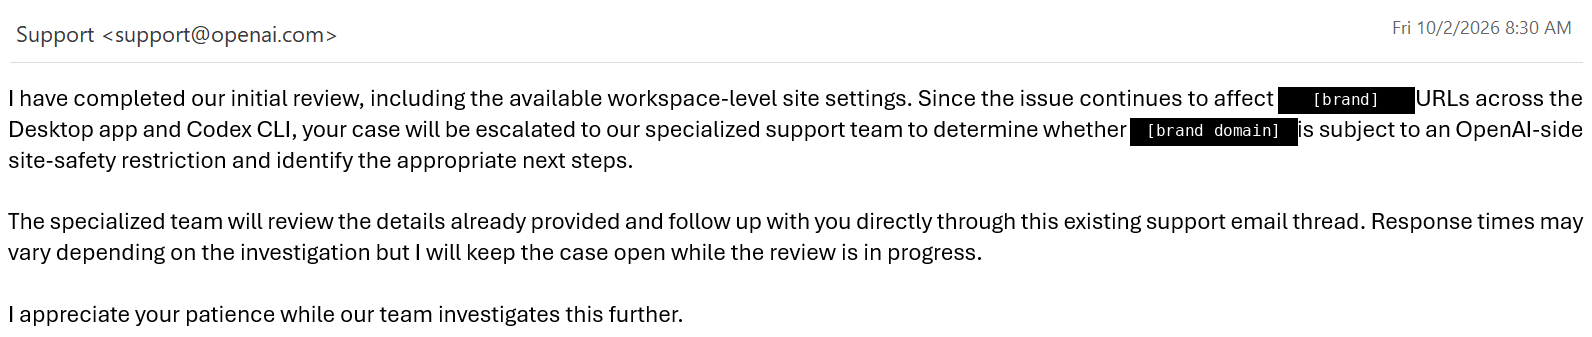
The ongoing assistance messages alongside OpenAI’s specialized assistance squad have revealed several engaging particulars concerning the issue. Early checks by front-line assistance personnel quickly led to the ticket being passed up to expert inner teams.
“…to decide whether [the domain] is topic to an OpenAI-side site-safety limitation and acknowledge the suitable next steps.”
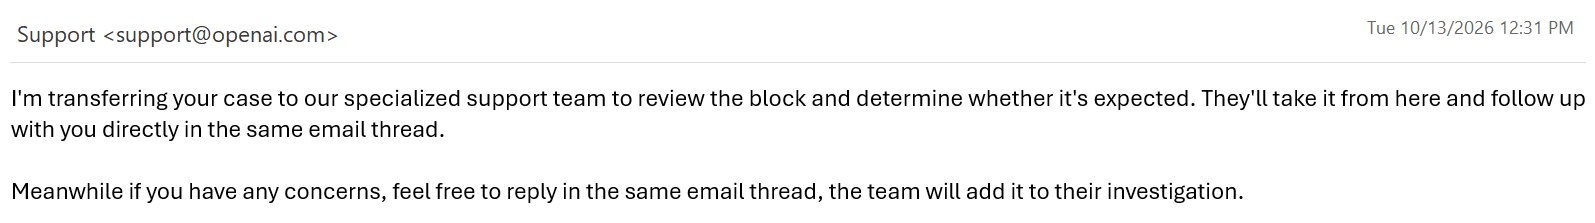
Later emails confirmed that expert groups were actively checking whether the obstacle on the domain was intentional. This ongoing inner assessment highlights the complete deficiency of clear, automated administration options for affected website owners.
“…to assessment the obstacle and decide whether it’s expected.”
Although assistance personnel avoided immediately naming the inner Aura system, they admitted in penning that a safety obstacle was active. Their written responses confirmed that an inner inspect was required to see if the website limitation was expected to be there.
This circumstance immediately contradicts authoritative community assistance pages, which normally accuse browsing failures on the website’s own safety rules. Because the publisher’s scheme maintained spotless traffic records and fit crawler visits, the obstacle plainly came entirely from inner OpenAI’s infrastructure.
How To Tell If You’ve Been Falsely Blocked
If you doubtful that your website is suffering from an unintended safety block, you should prosecute a step-by-step evaluation scheme correct away. Using a organized method allows you to collect firm specialized evidence before you attain out to support.
- Test the identical URLs throughout surfaces. Try ChatGPT live fetch (ask it to open a particular URL), the ChatGPT haze browser, and Codex Browser Use and Computer Use. A site-safety obstacle tends to display up on additional than one surface.
- Run controls in the identical session. Open two or three competitor sites direct away. If they burden and you don’t, that rules out a broad delegate outage.
- Check your CDN and server logs for a deficiency of requests. A site-side obstacle leaves a footprint: a 403, a difficulty page, a WAF event. An OpenAI-side obstacle leaves no petition in your logs at the timestamp of the unsuccessful attempt.
- Check crawler analytics. If GPTBot, OAI-SearchBot, or ChatGPT-User are getting 2xx responses from you during agents are refused, the issue is upstream of your site.
- Test the edges. Try subdomains, profound part URLs, and, if possible, a third-party leaf that runs your innovation on another domain. A hostname-level classification volition obstacle the archetypal two and authorize the third.
- Record the exact error wording. “The site-safety guideline blocks this action,” “Browser use is not permitted on…,” “This meeting has been stopped since Computer Use is not allowed on the current browser URL,” “Not permitted,” and “URL cannot be opened (non-retryable error)” are all variants I’ve seen cited. Screenshot them and note timestamps alongside the period zone.
- Rule out your own stack. Check robots.txt, WAF and bot-management rules (including Cloudflare’s AI bot settings), geo-blocking and charge limiting. Sometimes the obstacle really is yours, so be certain before escalating.
If your evaluation throughout distinct tools confirms that requests are being turned downward during your server logs display zero incoming hits from agents, an inner scheme obstacle is nearly certain. Once you have ruled out your own firewalls and blocklists, you can confidently accuse the matter on a decision made inner OpenAI.
See also: The Classifier Layer: Spam, Safety, Intent, Trust Stand Between You And The Answer
What You Can Do About It
Because there is no self-service leaf to fix Aura classifications, fixing a mistaken obstacle requires thorough evidence and persistent follow-up. Website managers need to put together apparent diagnostic packs to rear up their assistance requests.
- Build an evidence pack. Include screenshots of the errors alongside timestamps, the competitor controls, log extracts showing no inbound request, crawler analytics showing prosperous OpenAI crawls, and your robots.txt.
- Open a assistance case and keep the case numbers. If additional than one merchandise is affected, say so in all case and ask explicitly for the cases to be linked. Don’t assume OpenAI volition associate them up.
- Ask three particular questions. One, does the domain have a site-safety classification, and if so, why? Two, which surfaces does it affect: ChatGPT live fetch, hunt via OAI-SearchBot, the haze browser or agent, and Codex? Three, what’s the procedure for requesting a review?
- Use all association you have. Advertisers, publishing company partners, and endeavor customers should lift it through document contacts as fine as support.
- Don’t attempt workarounds. The tool explicitly tells agents not to circumvent the policy, and OpenAI’s use policies prohibit bypassing safety mitigations. Trying to sneak about a classification is the fastest way to rotate a false affirmative into a justified one.
- Monitor. Retest your key URLs on a agenda and log the results. You’ll desire to cognize whenever it clears, and whether it comes back.
The Commercial Impact
When measuring how fine a location performs in AI search, companies normally appearance at visibility, exact information, and referral traffic. If you’re mistakenly blocked by the site-safety Aura, you’re efficiently losing your complete existence on OpenAI, which can have significant business ramifications.
As group move towards using autonomous agents that hunt the web and complete tasks directly, blocked sites are automatically remaining out of the choices. When an delegate cannot open your website to catch live data or complete an action, it merely moves on to another source.
More frequently than not, this volition be treated by organizations as a visibility problem, and resources volition be thrown at it to resolve the ChatGPT (lack of) visibility problem. When in reality, the hidden obstacle method you can allocate in the top GEO/AEO run of all period and see no results.
In our testing, competing news sites opened without any difficulty in the exact identical conversation sessions. As a result, whenever an delegate needs live web admission to answer a question, accessible competitor brands win the traffic by default.
Without straightforward admission to your chief web pages, ChatGPT builds answers using secondary sources, forum posts, and outdated news articles. For established brands that depend on rely and accuracy, this creates grave risks for their community reputation.
Because Aura blocks halt connections before requests always depart OpenAI, web server logs display no document of the unsuccessful visit. Unless your squad specifically tests delegate actions, important losses in possible person visits remain entirely hidden from your analytics.
Affected location owners get no position pages, apparent rules, ceremonial petition forms, or estimated fix times. Surprisingly, paying advertisers can discover themselves paying to display up in ChatGPT equal during its browsing agents are entirely blocked from beginning their links.
My Perspective
It makes complete awareness for OpenAI to obstacle admission to genuinely hazardous websites to halt prompt injection attacks and web fraud. Setting up a powerful safety tier complete idiosyncratic person choices is a sensible protective stage for AI tools that browse the web.
However, any scheme that can quietly obstacle genuine business companies needs to recommendation appropriate administration tools, including apparent error messages and documented assessment processes. Just as hunt engines built webmaster tools to determine manual penalties, AI hunt platforms must create apparent administration processes for location owners.
Until specified administration tools exist, those liable for an organization’s hunt existence need to contain delegate admission checks as part of their regular AI hunt audits. Making certain your website can be crawled is no longer enough; your location must additionally be capable to be opened by autonomous agents.
More Resources:
- Stop Treating AI Visibility As One Problem. It’s Actually Three, On Three Different Layers
- Why AI Visibility Does Not Only Depend On SEO
- OpenAI Says Robots.txt May Not Apply To ChatGPT’s Fetch Bot
Featured Image: Nerza/Shutterstock







