Sep 10, 2026
/
By Ariffud M.
/
9 min Read
Ollama GPU requirements scope from astir 3‑4 GB of VRAM for a mini 3B exemplary to astir 50 GB for a 70B model, astatine Q4_K_M quantization (a wide utilized compressed type of a model) pinch an 8K context.
The main factors that find wherever you onshore successful that scope see exemplary parameter count, quantization level, and discourse model length.
Adding a GPU importantly speeds up consequence procreation compared pinch moving Ollama connected a CPU alone. In our benchmark connected a Hostinger GPU lawsuit pinch an RTX 4090, the Llama 3.1 8B Q4_K_M exemplary generated responses 2.7× faster than connected the CPU-only instance.
Does Ollama request a GPU?
No. Ollama doesn’t request a GPU, but utilizing 1 makes responses overmuch faster, particularly pinch larger models aliases longer conversations.
Ollama works pinch only your CPU and strategy RAM. This makes consciousness if you’re testing Ollama, occasionally utilizing a mini model, aliases don’t mind waiting longer for responses.
Take Llama 3.1 8B Q4_K_M arsenic an example. Its exemplary record is astir 4.9 GB.
With 16 GB of strategy RAM and nary GPU, Ollama loads the exemplary into RAM, and your CPU does the processing. You person capable representation to tally the model, but responses get noticeably slower because the CPU has to do each the work.
Now adhd an 8 GB GPU. The 4.9 GB exemplary fits successful the GPU’s ain memory, called VRAM, pinch room for a shorter context, truthful Ollama uses the GPU for processing alternatively of relying connected the CPU.
Keep successful mind that strategy RAM and VRAM are abstracted pools of memory. Your 16 GB of RAM still serves the operating strategy and different apps, while the GPU has its ain 8 GB of VRAM for Ollama.
The applicable quality looks for illustration this:
| Aspect | CPU-only | With a GPU |
| Where the exemplary loads | System RAM | GPU VRAM erstwhile it fits |
| What does the processing | CPU | GPU |
| What much representation gives you | More RAM lets you tally larger models connected the CPU | More VRAM lets you tally larger models and longer contexts connected the GPU |
| Best for | Occasional usage pinch smaller models and shorter contexts | Frequent usage pinch larger models and longer contexts |
What determines Ollama GPU and VRAM requirements?
Ollama’s GPU and VRAM requirements dangle connected model parameter count, quantization level, discourse model length, concurrency, and really overmuch strategy RAM you person disposable for offloading.
Model size and quantization find really overmuch representation you request to load the model. A longer discourse increases representation usage, and concurrency further increases it erstwhile Ollama handles aggregate requests astatine once.
System RAM becomes important erstwhile the afloat workload doesn’t fresh connected the GPU, since Ollama runs the portion that doesn’t fresh successful VRAM connected the CPU instead.
Context and runtime representation beryllium connected apical of the exemplary file, which is why a 4.9 GB exemplary needs much than 4.9 GB of VRAM to tally wholly connected the GPU. The sections beneath break down each facet and really overmuch VRAM it adds.
Model parameter count
The much parameters a exemplary has, the much VRAM you request to tally it connected the GPU.
Larger models besides thin to grip harder tasks better, specified arsenic generating moving codification successful 1 walk aliases pursuing multi-step instructions.
At Q4_K_M quantization, exemplary record sizes standard astir for illustration this:
| Model | File size |
| Llama 3.2 3B | ~2 GB |
| Llama 3.1 8B | ~4.9 GB |
| Qwen3 32B | ~20 GB |
| Llama 3.3 70B | ~43 GB |
A 32B exemplary takes astir 4 times arsenic overmuch representation arsenic an 8B exemplary astatine the aforesaid quantization, while a 70B exemplary pushes the request overmuch higher.
Quantization level
Quantization compresses the numbers wrong a exemplary truthful it takes up little memory. The aforesaid exemplary tin person very different record sizes depending connected its quantization level.
Lower-bit quantization compresses the exemplary more, trading immoderate output value for a smaller file. You mightiness spot it miss a circumstantial item successful a agelong punctual that the higher-quantized type gets right.
Here’s Llama 3.1 8B astatine 3 quantization levels:
| Quantization | File size |
| Q4_K_M | ~4.9 GB |
| Q6_K | ~6.6 GB |
| Q8_0 | ~8.5 GB |
The Q4_K_M type fits connected an 8 GB GPU pinch VRAM to spare for context. The Q8_0 type is already 8.5 GB earlier adding context, truthful the aforesaid GPU can’t clasp the full workload successful VRAM.
Context model length
The longer your discourse window, the much VRAM Ollama needs because it keeps much of your punctual and speech successful representation while generating a response.
Ollama sets the default discourse magnitude automatically based connected your disposable VRAM:
| Available VRAM | Default context |
| Under 24 GB | 4K |
| 24‑48 GB | 32K |
| 48 GB+ | 256K |
Here’s really discourse magnitude affects full VRAM for Llama 3.1 8B Q4_K_M:
| Context length | Total VRAM usage |
| 2K | ~5-6 GB |
| 8K | ~6-7 GB |
| 32K | ~9-10 GB |
That intends the aforesaid exemplary that fits connected an 8 GB GPU pinch a short discourse nary longer fits wholly successful VRAM astatine 32K. Longer contexts are useful erstwhile you want Ollama to support way of much information, specified arsenic a agelong speech aliases a ample document.
Note that each exemplary besides has a maximum discourse magnitude it supports. For example, Llama 3.1 8B supports up to 128K.
Concurrency
Concurrency intends Ollama handling much than 1 petition astatine the aforesaid time. It increases VRAM usage because each of those requests needs its ain discourse memory.
Say you’re moving Llama 3.1 8B Q4_K_M pinch a 2K context. One petition uses astir 5-6 GB of VRAM successful total.
Four concurrent requests request 4 abstracted 2K contexts, truthful Ollama is holding astir 8K tokens of discourse crossed them. That raises full VRAM usage to astir 6-7 GB, moreover though each petition is still group to 2K.
Model representation adds up excessively erstwhile concurrent requests usage different models.
Keeping Llama 3.1 8B (~4.9 GB) and Qwen3 14B (~9.3 GB) loaded uses astir 14.2 GB earlier adding immoderate context. On a 16 GB GPU, that leaves only astir 1.8 GB for discourse and different runtime memory.
You don’t request to interest astir concurrency erstwhile you’re the only personification chatting pinch 1 model. It matters erstwhile respective group aliases apps nonstop requests astatine the aforesaid time.
System RAM and storage
System RAM gives Ollama a spot to shop exemplary information that doesn’t fresh successful VRAM, while retention determines really galore models and quantization versions you tin support downloaded.
Say you person an 8 GB GPU and 16 GB of RAM:
- A 4.9 GB exemplary fits wholly successful VRAM.
- A 10 GB exemplary already exceeds your VRAM earlier adding context, truthful portion of it has to usage strategy RAM.
- A 20 GB exemplary exceeds your VRAM by astatine slightest 12 GB earlier adding context, leaving very small of your 16 GB of RAM for the operating strategy and different apps.
For a exemplary astir 20 GB, 32 GB of strategy RAM gives you overmuch much usable headroom erstwhile you brace it pinch an 8 GB GPU.
Storage is easier to cipher because each downloaded exemplary takes astir its listed record size connected disk:
| Model | File size |
| Llama 3.1 8B Q4_K_M | ~4.9 GB |
| Llama 3.1 8B Q8_0 | ~8.5 GB |
| Qwen3 32B Q4_K_M | ~20 GB |
| Total | ~33.4 GB |
Add the record sizes of the models you want to support downloaded, past time off immoderate other abstraction for early downloads if you scheme to adhd much later.
Ollama VRAM requirements by exemplary size
At Q4_K_M quantization and an 8K context, Ollama needs astir 3-4 GB of VRAM for 1B-4B models, 6-7 GB for 7B-8B models, and 47-52 GB for 70B-class models.
The pursuing estimates presume 1 progressive request.
| Model size | Example models | Q4_K_M record size | Approx. VRAM astatine 8K | GPU representation to look for |
| 1B-4B | Llama 3.2 3B, Qwen3 4B | ~2-2.6 GB | ~3-4 GB | 4-6 GB |
| 7B-8B | Llama 3.1 8B, Qwen3 8B | ~4.9-5.2 GB | ~6-7 GB | 8 GB |
| 12B-14B | Gemma 3 12B, Qwen3 14B | ~8.1-9.3 GB | ~10-12 GB | 16 GB |
| 20B-32B | Gemma 3 27B, Qwen3 32B | ~17-20 GB | ~19-24 GB | 24 GB for shorter contexts, 48 GB for much room |
| 70B-72B | Llama 3.3 70B, Qwen2.5 72B | ~43-47 GB | ~47-52 GB | 80-96 GB |
Check your model’s existent record size first if it isn’t listed, past usage the closest statement successful the array to estimate the GPU representation you’ll need.
Pay person attraction to the GPU tier erstwhile your request sits adjacent its VRAM limit.
Some 32B Q4_K_M models fresh connected a 24 GB GPU, but time off small room arsenic the discourse grows. A 48 GB GPU is likewise tight for galore 70B models, truthful 80-96 GB gives you overmuch much room.
Choose much VRAM if you scheme to usage higher-bit quantization, a discourse longer than 8K, aliases concurrent requests.
Which GPUs does Ollama support?
Ollama supports NVIDIA GPUs, selected AMD GPUs, and Apple Silicon Macs, arsenic good arsenic further GPUs connected Windows and Linux done Vulkan.
Check Ollama’s hardware support page first to spot whether it supports your nonstop GPU, past usage its VRAM aliases unified representation to find which models you tin tally wholly connected it.
NVIDIA GPUs
Ollama supports NVIDIA GPUs pinch CUDA compute capacity 5.0 aliases higher. This includes galore GeForce GTX and RTX cards, arsenic good arsenic information halfway GPUs specified arsenic the A100, H100, and H200.
For example:
| GPU | VRAM |
| RTX 3060 (12 GB variant) | 12 GB |
| RTX 4070 Ti | 12 GB |
| RTX 3090 | 24 GB |
| RTX 4090 | 24 GB |
Ollama requires NVIDIA driver type 550 aliases newer. For GPUs pinch compute capacity 5.0-6.2, driver type 570 aliases later is required.
AMD GPUs
Ollama supports AMD GPUs done ROCm connected Linux and Windows, though Windows supports less cards. Common supported user GPUs from the Radeon RX 7000 bid include:
| GPU | VRAM |
| RX 7600 | 8 GB |
| RX 7800 XT | 16 GB |
| RX 7900 XTX | 24 GB |
Ollama besides supports respective Radeon PRO cards connected Linux and Windows, positive Ryzen AI processors and Instinct accelerators connected Linux.
Apple Silicon
Ollama supports GPU acceleration connected Apple Silicon Macs done Metal, truthful you don’t request to instal a abstracted GPU driver.
Apple Silicon shares unified representation betwixt macOS, apps, and the exemplary alternatively of providing dedicated VRAM. On a 32 GB Mac, you’ll person astir 23-25 GB disposable for Ollama.
Vulkan
Ollama supports Vulkan connected Windows and Linux, giving it entree to GPUs beyond those supported by NVIDIA CUDA and AMD ROCm.
Vulkan itself is simply a cross-platform graphics API that useful crossed a wide scope of GPU manufacturers, including Intel and older AMD cards extracurricular the ROCm compatibility list.
Performance done Vulkan is mostly slower than CUDA aliases ROCm, but still faster than CPU-only.
How to tally Ollama connected Hostinger GPU
To tally Ollama connected Hostinger GPU hosting, choose a GPU pinch capable VRAM for the exemplary you scheme to use, deploy Ollama successful hPanel, propulsion and tally your model, and verify that Ollama is utilizing the GPU.
Hostinger provides a preconfigured Ollama template that you tin deploy pinch a fewer clicks, alternatively of installing Ollama, GPU drivers, and different limitations yourself from the Linux bid line.
1. Choose a GPU for your model
Choose a Hostinger GPU based connected the exemplary size, discourse length, and workloads you scheme to run. Give yourself immoderate VRAM headroom alternatively of choosing a GPU that only hardly fits your existent model.
| Model size | Recommended Hostinger GPU | VRAM | Starting price |
| 7B-14B | RTX 4090 | 24 GB | $0.38/hour |
| 20B-32B | L40S | 48 GB | $0.92/hour |
| 70B | RTX PRO 6000 | 96 GB | $0.60/hour |
| 70B+ aliases aggregate ample models | B200 | 192 GB | $4.50/hour |
GPU readiness varies by region owed to demand. Check hPanel for the real-time readiness of the GPU you want earlier deploying your instance.
2. Deploy the GPU instance
Deploy the Ollama template from hPanel:
- Go to hPanel → Dev Tools → GPU.
- Select the GPU you want to use.
- Enter an lawsuit sanction and prime a region.
- Choose an lawsuit size pinch astatine slightest 2 CPU cores. Hostinger only provides app templates for this size aliases larger.
- Select the Ollama template.
- Add an SSH cardinal if you want key-based access.
- Top up your credits if your equilibrium isn’t capable for the estimated runtime.
- Review the estimated runtime and click Deploy.
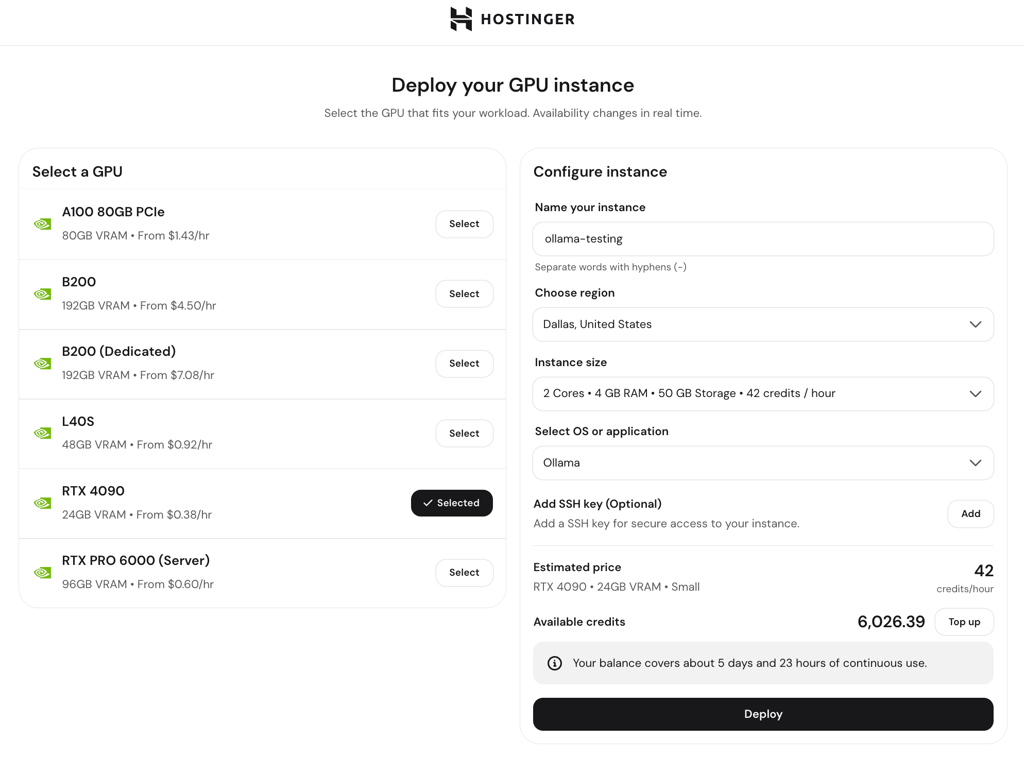
Deployment takes respective minutes. Click Manage aft it finishes to unfastened the lawsuit dashboard.
3. Pull and tally a model
Pull and tally your exemplary by connecting to the lawsuit via SSH, past utilizing the ollama pull and ollama run commands.
In the lawsuit dashboard successful hPanel, you’ll spot your SSH bid and password.
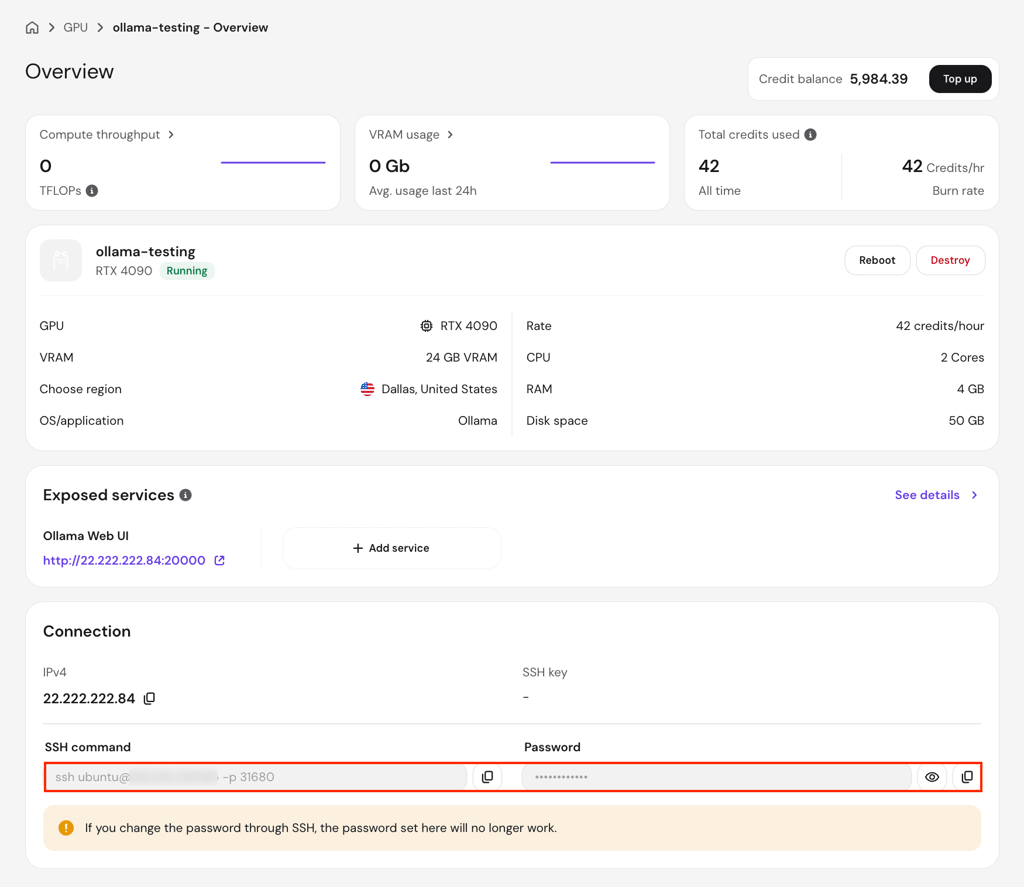
Open a terminal connected your computer, paste the SSH command, and participate the password erstwhile prompted.
Once you’re connected, run:
ollama propulsion llama3.1:8b-instruct-q4_K_M ollama tally llama3.1:8b-instruct-q4_K_M
The first bid downloads Llama 3.1 8B Q4_K_M to the instance. The 2nd starts the exemplary and gives you a punctual wherever you tin type a connection and commencement chatting.
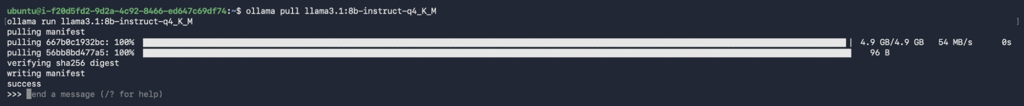
The aforesaid ollama pull and ollama run commands activity if you install Ollama connected a virtual backstage server (VPS).
4. Verify GPU acceleration
Verify GPU acceleration pinch ollama ps to cheque wherever the exemplary is loaded and nvidia-smi to corroborate that the GPU is disposable to Ollama.
Leave the terminal moving astatine the chat prompt. Open a 2nd terminal window, link to the aforesaid GPU lawsuit done SSH, and run:
ollama ps
Check the PROCESSOR column. 100% GPU intends Ollama loaded the exemplary wholly onto the GPU. A CPU/GPU split intends portion of the exemplary is utilizing strategy RAM.

Then, run:
nvidia-smi
Check that the NVIDIA GPU appears and that Ollama is listed among the moving GPU processes.
Ollama CPU vs. GPU conclusion benchmark
Benchmark Ollama connected CPU vs. GPU by moving the aforesaid exemplary and punctual 3 times successful each mode, past comparing the median procreation speed. Use the aforesaid SSH terminal for the full test.
First, exit the erstwhile chat convention and unload the exemplary truthful some benchmarks commencement from a known state:
/bye
Then run:
ollama extremity llama3.1:8b-instruct-q4_K_M
Start pinch CPU-only mode. Run the pursuing bid pinch num_gpu group to 0:
curl -s http://127.0.0.1:11434/api/generate -d '{ "model": "llama3.1:8b-instruct-q4_K_M", "prompt": "Explain really DNS solution useful successful astatine slightest 300 words.", "stream": false, "keep_alive": "10m", "options": { "num_ctx": 8192, "num_predict": 128, "temperature": 0, "seed": 42, "num_gpu": 0 } }' | python3 -c 'import sys,json; d=json.load(sys.stdin); print("{:.2f} tokens/s".format(d["eval_count"]/(d["eval_duration"]/1e9)))'
Then tally this bid and corroborate that PROCESSOR shows 100% CPU:
ollama ps
The tally you conscionable did is simply a warm-up, truthful disregard its result. Run the benchmark bid 3 much times and grounds each tokens/s figure.
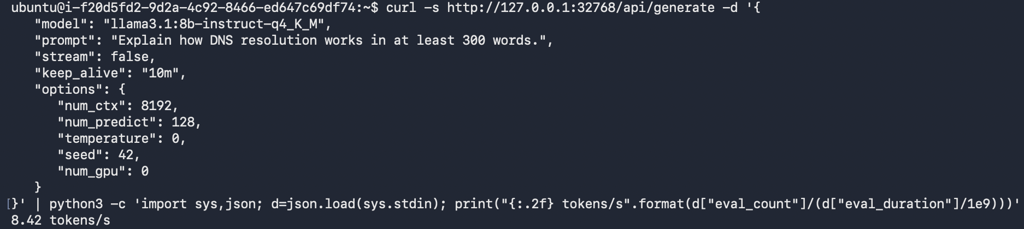
Next, unload the exemplary again:
ollama extremity llama3.1:8b-instruct-q4_K_M
Run the aforesaid benchmark pinch num_gpu changed to -1:
curl -s http://127.0.0.1:11434/api/generate -d '{ "model": "llama3.1:8b-instruct-q4_K_M", "prompt": "Explain really DNS solution useful successful astatine slightest 300 words.", "stream": false, "keep_alive": "10m", "options": { "num_ctx": 8192, "num_predict": 128, "temperature": 0, "seed": 42, "num_gpu": -1 } }' | python3 -c 'import sys,json; d=json.load(sys.stdin); print("{:.2f} tokens/s".format(d["eval_count"]/(d["eval_duration"]/1e9)))'
Run ollama ps to corroborate 100% GPU, past repetition the three-run measurement.
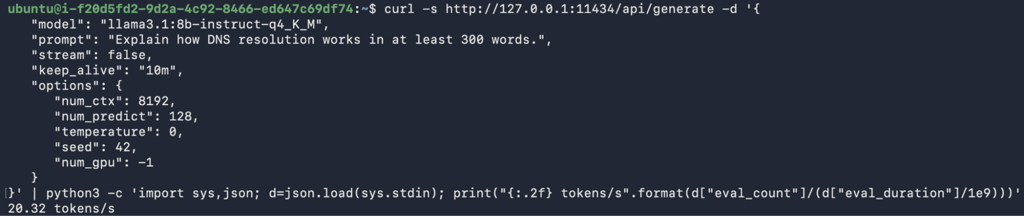
Sort each group of 3 results from lowest to highest and usage the mediate worth arsenic the median:
| Processor mode | Run 1 | Run 2 | Run 3 | Median |
| 100% CPU | 8.42 tokens/s | 8.44 tokens/s | 8.41 tokens/s | 8.42 tokens/s |
| 100% GPU | 20.32 tokens/s | 22.86 tokens/s | 22.51 tokens/s | 22.51 tokens/s |
Divide the GPU median by the CPU median to cipher the speedup. For example, a CPU median of 8.42 tokens/s and a GPU median of 22.51 tokens/s gives 22.51 ÷ 8.42 = 2.7× faster connected the GPU.
Why usage the median alternatively of the average?
One unusually accelerated aliases slow tally skews the average. The median uses the mediate result, making it much typical of emblematic benchmark performance.
How to entree Open WebUI for Ollama connected Hostinger GPU
To entree Open WebUI connected Hostinger GPU, go to your lawsuit dashboard successful hPanel, past click the Ollama WebUI URL shown there.
The Open WebUI is simply a browser-based chat interface, letting you use Ollama pinch a graphical personification interface (GUI) alternatively of moving commands done the bid line.
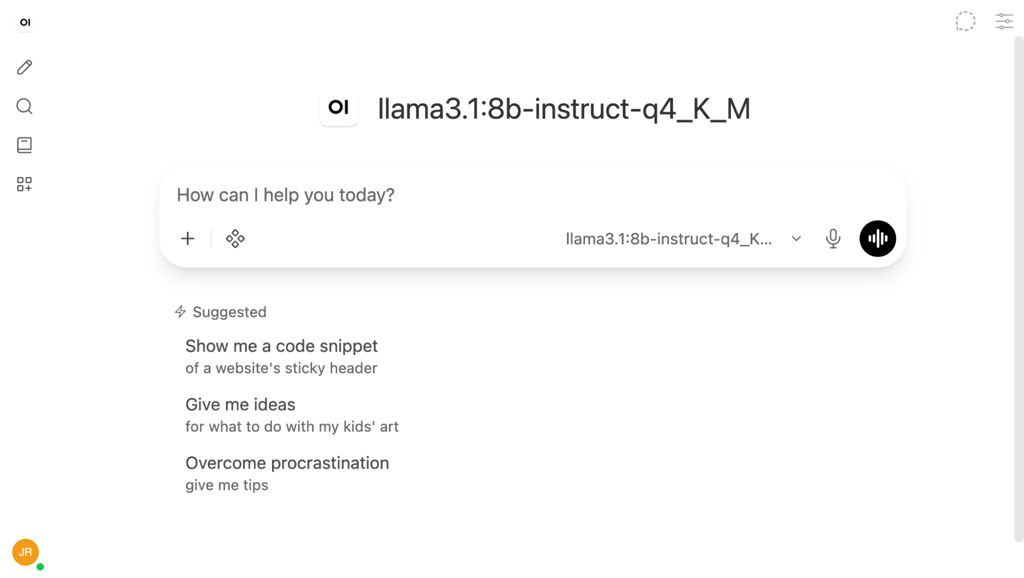
If this is your first clip accessing Open WebUI, you’ll beryllium asked to create an account. This relationship becomes the Open WebUI administrator.
Once you’re logged in, prime a exemplary from the dropdown astatine the apical of the chat surface and commencement a conversation. Any Ollama exemplary you pulled earlier done SSH should look there. You tin besides download a caller 1 straight from Open WebUI.
All of the tutorial contented connected this website is taxable to Hostinger's rigorous editorial standards and values.

The author
Ariffud Muhammad
Ariffud is simply a Technical Content Writer pinch an acquisition inheritance successful Informatics. He has extended expertise successful Linux and VPS, authoring complete 200 articles connected server guidance and web development. Follow him connected LinkedIn.