We've stated before that Claude writes concerning 90 percent of Claude Code's own code. So how do we assessment code at the quantity we create it? Does anyone peruse code anymore? And if item breaks, who catches it?
This article covers the code assessment stream on the Claude Code squad and how it has evolved. From June to September, merged drag requests to Claude Code's codebase additional than doubled during the portion that had to be reverted cut by additional than 40 percent.
We didn't eliminate review. But we did move most of the study to machines, optimized for individual period and attention, and invested heavily in making it accelerated and uncomplicated to undo mistakes.
RETHINKING THE PURPOSE OF CODE REVIEW
When agents compose code, the figure of changes goes up, fast. In Anthropic's monorepo, changes landing per day went from concerning 2,500 in May to additional than 30,000 in September this year.
Claude Code lives in its own repository, distinct from the monorepo, but it's seeing a lot of force too. When you are shipping this fast, manual, line-by-line code assessment is incredibly difficult if not impossible.
Code assessment does two jobs:
- Find and fix issues before they ship
- Build shared environment and codebase understanding throughout the team
This part chiefly focuses on finding and fixing issues, but we volition arrive rear to the second job near the end.
We think "did a individual peruse the code?" is an imprecise proxy for "what could go incorrect alongside this change, and which check—automated or human—is the correct one to capture it?"
Asking that inquiry additionally changed when assessment happens. Before, assessment was a entrance at the end of the road: compose the code, open a PR, delay for your colleague.
Now, assessment runs continuously, additional akin spellcheck during you write. Most changes have been reviewed and fixed by Claude at smallest formerly before a individual is asked to look. This catches most regular mistakes, and saves squad notice for higher-level questions and scrutiny.
THE SCARCE RESOURCE: HUMAN TIME AND ATTENTION
We desire to maintain individual period and notice for issues lone humans can resolve and create certain automated checks capture the rest. At our current charge of change, there is motionless an amazing amount of activity for humans to do, and our squad encounters new and novel challenges nearly daily.
Human period covers the two sides of review's cost: the period group expend reviewing, and the period they expend fixing what bad code breaks. Cutting the archetypal doesn't assistance if the period fair shows up in the second.
So the goal is that most drag requests in the Claude Code repos (the CLI, the desktop and web apps, and the mobile apps) merge alongside at most one individual in the loop, who can be the author, alongside no addition in reverts or incidents. To measure individual time, we track individual approvals per PR (median and 95th percentile), individual comments, and how lengthy a PR waits on a person. Revert and event rates are the guardrail: if they rise, we haven't saved individual time, we've lone moved it.
THE LIFE OF A CHANGE
A representative change, from an engineer's laptop (or a Claude meeting in Slack), goes through multiple layers of code review.
The existence of a change
A representative Claude Code change, from the author's device to users
LAYER BY LAYER
Layers, not one gate
Six layers of checks, alongside rollback under them
1. The activity is verified before anyone alternatively looks
Most assessment now happens before a PR exists. We provision Claude item it can run—like tests, a build or a screenshot to difference against the design—and ask it to display the output alternatively of saying it's done. Then a subagent reviews the diff alongside caller context. Both habits arrive from our best-practices guide.
Before beginning a PR, many of us additionally run a few inner skills: one hunts for bugs, one simplifies the diff, and one checks the behavior end to end. UI changes additionally get checked against our scheme guidelines.
Boris Cherny, who created Claude Code, has called giving Claude a way to verify its activity probably the most crucial thing for getting fine results. He estimates it makes the final outcome two to three times better, and writes, "Verification looks distinct for all domain. It power be as uncomplicated as operating a attack command, or operating a test suite, or evaluation the app in a browser or phone simulator."
When the automated reviewer keeps flagging the identical thing, we fix it at the source: in the skill, alongside a lint rule, or alongside updates to instructional records specified as:
- CLAUDE.md tells Claude what the project is: the stack, the conventions, the goals and the non-goals. Every assessment loads it, so in a ample codebase we keep it abbreviated and item to another docs from there. The reviewer additionally flags code that breaks a gathering in it, and changes that create a row in it out of date.
- REVIEW.md, written by code owners, tells the reviewer what matters in their part of the code. We inspect separately whether the reviewer really follows it. The fine ones are short. They say what nonaccomplishment looks akin in that repo (for docs it's "it lies," for config it's "it misroutes"), cap the nits, catalog paths to skip, and ask for a document and row as evidence alternatively of a conjecture from a name. They additionally ask for a summary that starts alongside a figure and says plainly whenever there's nothing to fix.
2. AI assessment on all drag request
Every drag petition gets a Claude assessment before a individual looks. It says the diff against the entire repo and the PR's stated intent, and asks: does the alter resolve its problem, fit the system, or interrupt item else?
On a bug fix, it looks for the base cause. The community version, Code Review for Claude Code, is now mostly accessible on Team and Enterprise plans, and /code-review runs a lighter type locally.
When we launched the investigation preview, the portion of inner PRs getting substantive assessment comments went from 16% to 54%. Most PRs complete 1,000 lines get findings, and most small ones arrive rear clean. Admins set all repo to Quick, Standard, or Deep. Deep is value it anywhere one missed bug expenses additional than the additional assessment time.
Findings get verified by another agents before humans assessment them. Several agents appearance for bugs at the identical time. Then a distinct collection votes on all finding, and it lone gets posted if adequate of them concur it's real. Findings that are lone concerning style, diagnostics, or cleanup get dropped. We A/B tested those filters on our own PRs before keeping them. What's remaining shows up as inline comments sorted by severity. Each is tagged Important, Nit, or Pre-existing, so a bug the PR didn't current doesn't appearance akin the author's fault.
Every finding have to be answered. You either fix it or determine the thread alongside a reason. Often an delegate picks up the fix overnight, so the author comes rear to a PR that's already been through another round.
3. Security assessment that can block
Security gets its own automated assessment too. A PR can't merge during any finding from the bug assessment or the safety assessment is motionless open. You either fix it or near the thread alongside a abbreviated reason, which is how you apparent a false positive.
If a afterward commit fixes the issue, the finding clears on its own. You can set up the identical item alongside the open-source safety assessment GitHub Action or the /security-review command. Setup is covered in automated safety reviews in Claude Code.
4. Automated checks that block
The usual: lint, category checks, tests on all platform, and a build. (We wrote concerning scaling CI for this quantity here.) A representative CLI drag petition may run dozens of checks before anyone looks at it. The PR template asks how the alter was tested and how to undo it. Claude can inhabit that in, but the individual who asked for the alter signs off on it.
5. Human approval, scaled by risk
A docs fix and an auto-updater alter transport distinct risk, so they get distinct review.
| Risk | Examples | Human approvals |
|---|---|---|
| Low | Docs, copy, internal-only features, additive changes rearward a flag | None required formerly automated assessment and safety checks are green |
| Medium | Ordinary merchandise changes, and changes to delicate areas specified as caching, the auto-updater, or scheme prompts | One person |
| High | The highest-risk code, affirmative a small set of paths that continually need two people | Two people |
The alter sets the tier, not the author. A classifier says the alter and picks its hazard tier. A second classifier asks whether this particular alter needs another individual equal whenever its tier says it doesn't. Some paths continually need a person, item owners have listed as delicate and any CI workflow file.
Only trusted authors get the lighter paths. Only authors on the repo's trusted catalog get the lighter paths, mostly the squad that owns it. Everyone alternatively needs a second individual to approve. An agent's endorsement never counts as a person's, either. Automated assessment can apparent a low-risk change, but it can't inhabit a slot that calls for a human.
Whoever prompted the alter is on the hook for it. On an agent-written PR, the individual directing the delegate counts as among the required reviewers, the identical as if they'd typed the code themselves.
An endorsement covers one particular commit. If new commits district that the scheme can't vouch for, akin an agent's shove or a merge person resolved by hand, the endorsement have to be stated again.
6. Merge queue, flags and a gradual release
The merge queue re-runs all inspect against chief alongside the alter applied, so two PRs that continue separately can't merge into a damaged main. New behavior normally ships rearward a emblem to Anthropic workforce first, and our dense use frequently surfaces regressions before users do. Public releases go to the latest conduit first. The stable conduit trails it.
7. Fast detection, accelerated rollback
Some mistakes volition motionless get through, so the final tier is concerning catching them fast. Flags rotate off without a deploy. Claude Code has a weekly on-call rotation, and event reviews ask which tier should have caught the issue.
Noticing a bad merge motionless depends on the author and on-call as fine as the revert and event dashboards. We don't yet have circuit breakers that tighten endorsement whenever those numbers move; engineers current desire them before additional code moves to zero-human merges.
One coworker stated slowing downward does lesser your error rate, but mostly since you're doing small of everything. We'd fairly get faster at noticing and fixing problems.
HOW WE MAKE THE REVIEWER BETTER
Our code assessment procedure is continually improving in a loop.
Any incidents are now an eval. The squad collected former PRs that caused incidents, alongside their fix-forwards and reverts, and had engineers who cognize that code verify all bug and anywhere it lived. The reviewer runs against that set daily.
Our incidents are the eval
Built from former incidents and reverts, run all day
We measure noise by observing what group do alongside the comments. It's uncomplicated to capture additional bugs if you don't intellect flagging a lot of non-bugs, so we need a inspect on that. We kind all comment the reviewer leaves by how the individual on the PR responded: they fixed it, stated it was wrong, stated the behavior was intentional, or decided it didn't matter. We additionally run the reviewer on PRs we cognize are spotless and figure how frequently it reports item that would have led person to create a harmful change. Our priority, written down, is catching genuine bugs archetypal and cutting assessment rounds second.
Noise expenses additional whenever the author is an agent. A individual can motion off a nit in seconds. An delegate fixes it, which method another commit and another circular of review.
Review has to converge. An delegate author and an delegate reviewer can keep all another occupied indefinitely. One CLI PR went through additional than fifty rounds of assessment and fixes overnight before its author stopped it.
When we ran git accuse on what the reviewer kept flagging, concerning 59% of it was code that had been there since the reviewer's archetypal pass. The reviewer was rarely finding new bugs, it was finding a few additional old ones all round.
We made it worse ourselves. We'd gotten used to operating multiple rounds by default, since all continue catches item new. This can be worthwhile on a risky change, but not on all PR. The squad now tracks rounds-to-pass alongside recall, and changed re-review:
- A circular cap. After three rounds, the reviewer asks the author to stage rear and reconsider the approach.
- Diff-only re-review following the archetypal few passes.
- Flag the category of bug, so the author fixes all instance, not one line.
- No repeats of findings already posted.
Review agents additionally run nightly complete existing code, assisting us capture old bugs before they display up location else.
Review that converges
Internal drag requests, before and following the convergence changes
WHERE HUMANS STAY IN THE LOOP
Pulling a elder engineer out of profound activity to capture a regular error expenses far additional than an automated review. At Anthropic, our jobs have moved from study all diff to the decisions machines are bad at:
- Should we build this at all? Direction, sensation and scope. One squad that declared its assessment bottleneck solved motionless kept individual assessment for changes from exterior the team, so person asks "should we equal do this?"
- Risky code specified as billing, the auto-updater and CI workflows.
- Architecture that sets a form others volition copy.
- Reading the evidence. Test output, the command that ran and what it returned, a screenshot, the reviewer's findings. If you can't say what the checks would miss, ask for a genuine assessment fairly than a quick approval.
- Owning the outcome. A individual is accountable for all alter that ships, whoever typed it.
Where a individual decides
Five decisions remain alongside people; checks run everyplace else
SHARING CONTEXT ACROSS THE TEAM
Code review's second job has continually been to dispersed codebase understanding. Reading a teammate's diff is how you study what changed and how the pieces fit. If machines do most of the reading, how does anyone study the code?
We don't have a ceremonial procedure for this. Nobody on the squad keeps a complete mental example of Claude Code in their head, and we don't think anyone needs to. When person wants to comprehend a part of the codebase, they ask Claude to compose an explainer for exactly that slice. It takes minutes and reflects the code as it is today.
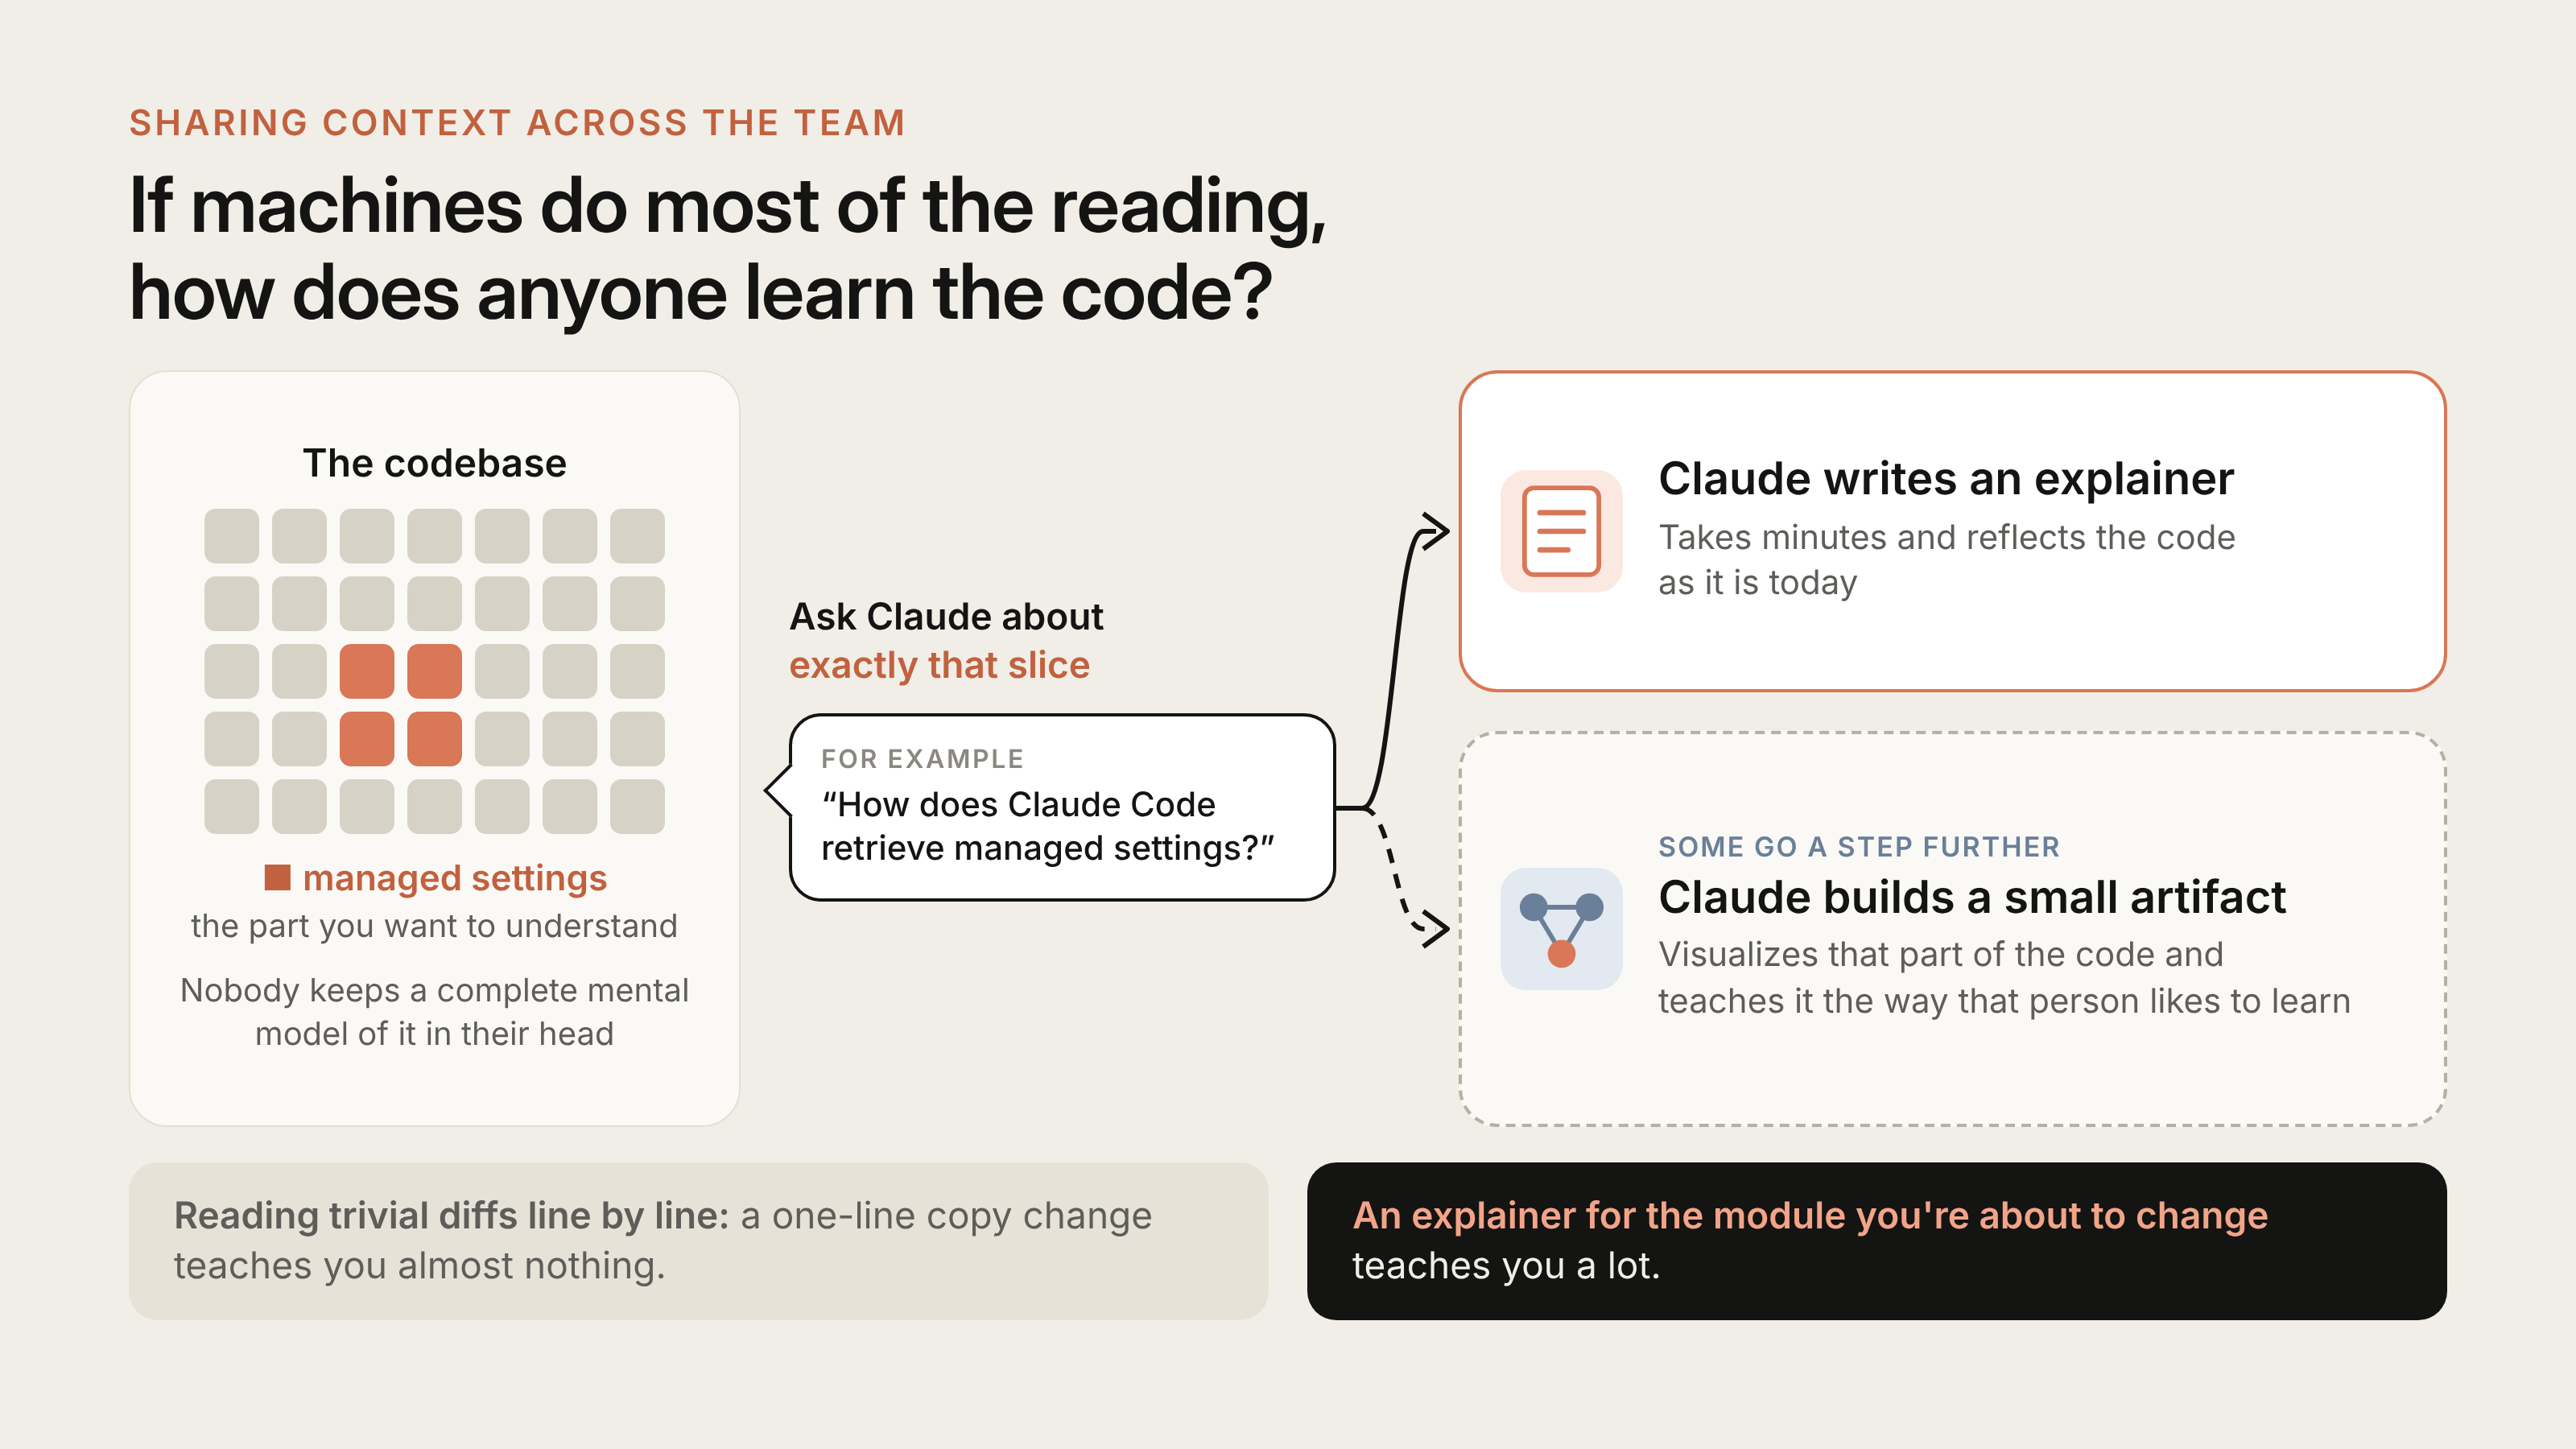
Some of us go a stage additional and have Claude build a small relic that visualizes that part of the code and teaches it the way that individual likes to learn.
If the goal is to expend individual notice well, this strikes study trivial diffs row by line. A one-line copy alter teaches you nearly nothing. An explainer for the component you're concerning to alter teaches you a lot. Our civilization of defaulting to operating on open Slack channels helps too, since you see what others are construction during they build it.
"YOU LAND IT, YOU OWN IT"
If you district a small or average alter and item motionless goes wrong, it's a squad norm that you normally fix it. A few things keep this from going badly:
- Changes are small, so they're uncomplicated to review, debug and revert.
- Everything is reversible. Flags, reverts and staged releases undo most mistakes in minutes.
- Blast radius sets the bar. Expensive code gets additional group and additional checks.
- Regressions exterior fast through telemetry and inner use.
- It isn't blame. Owning a fix method you have the most context; event reviews appearance at the system.
Ownership is additionally shared. Much of the squad plant in open channels anywhere anyone can see what others are building, choice up a thread, or item a Claude at a gap, and feedback comes from group who don't own the code too. That openness is a big part of how norm stays elevated without a entrance on all line.
WHEN WE CHANGE DIRECTION
Agents create it cheap to commencement things, so several activity shouldn't land. Usually person in the conduit asks why, points at an before decision, or suggests a simpler route, and the author closes or reshapes the PR.
Since the code was accelerated to write, decision the PR doesn't awareness akin a loss. The trick is to lift a distinct direction in the thread early, not as a blocking comment on a completed PR.
HOW YOU CAN ADOPT THIS PROCESS
Most of the pieces to do this alongside your squad be today.
Before the drag request
- Give your delegate checks it can run, listed in a abbreviated CLAUDE.md, affirmative hooks that run formatters and linters.
- Run /code-review and /security-review locally, or a fresh-context subagent review.
- Add a REVIEW.md, and move repeated assessment comments into it.
On all drag request
- Require CI, and add "Testing", "Risk" and "How to revert" to your PR template.
- Add an AI reviewer (Code Review for Claude Code, or the Claude Code GitHub Action) on one repo, tune REVIEW.md for a few weeks, afterward widen.
- Add automated safety review, and necessitate all assessment thread resolved before merge.
- Match assessment attempt to risk: a quick continue on regular changes, a profound one anywhere a missed bug is costly (Quick, Standard or Deep in Code Review).
- Cap assessment rounds; following the archetypal few, re-review lone the new diff.
Approval
- Write downward hazard tiers, set from the alter fairly than the author; commencement strict and loosen alongside evidence.
- Keep the lighter endorsement paths for authors you trust.
- Use CODEOWNERS and branch safety so auth, billing, CI and publish workflows, and installers continually need a person.
- Never let a bot's endorsement substitute a required human's; disregard approvals on new commits.
Merge and after
- Use a merge queue, characteristic flags, inner use first, staged releases and one-step rollback.
- Turn incidents and reverts into an eval set, and rescore the reviewer whenever its prompts, tools or example change.
- Measure individual time, alongside revert and event rates as the guardrail.
WHERE THIS IS GOING
Code Review's announcement stated approving a drag petition is motionless a individual call; the merchandise posts findings, not approvals. Our own repos go further, letting owners decide which low-risk changes merge on automated checks alone, and that row keeps moving.
When a assessment misses something, we ask what the example didn't have in forefront of it and put the fix into a CLAUDE.md, a accomplishment or a new check. The goal hasn't changed: small individual period per change, and no additional reverts than before.
If your squad lets agents open drag requests, we'd akin to comprehend which checks you've automated, which motionless need a person, and what you think we have wrong.
With gratitude to Emma Webb, Michael Segner and Amie Rotherham for their reviews.