SpaceXAI's most mighty example for coding and cognition work. Twice as fast, at fractional the cost of comparable models.
Grok 4.7 is our most capable example for coding and cognition work. It plant longer on difficult tasks, checks its own activity additional carefully, and comes alongside our best-calibrated safeguards to date. Served at the identical cost and speed as Grok 4.6, it is extremely rivalrous in its class.
On CursorBench 4.0, which stresses longer-running coding tasks, Grok 4.7 is at the frontier in price-performance.
Model Improvements
Grok 4.7 uses a new, larger basis example compared to Grok 4.6. It was trained alongside a longer reinforcement learning run on a harder mix of tasks, valued toward problems that obtain many hours to complete. The example is improved at verifying its own activity and managing longer context. We additionally trained Grok 4.7 to natively comprehend the Grok Bot harness, making it improved at conversational tasks and broad cognition work.
Grok 4.7 xHigh
Grok 4.6 High
GPT-5.6 Sol Max
Fable 5.1 Max
Input token price$ per million
$2
$2
$4
$10
Output token price$ per million
$6
$6
$20
$50
Software engineeringCursorBench 4.0
46.3%
40.4%
41.7%
51.8%
Software engineeringDeepSWE v1.1
71.0%*
65.2%
72.7%
70.0%
Electrical engineeringEEBench
64.0%
53.0%
39.4%
56.4%
Multi-hour agency workAA Briefcase v1.1
1,657
1,546
1,487
1,678
Multi-hour terminal workTerminal-Bench 4.0
38.0%
20.3%
37.3%
57.9%
Legal workHarvey Legal Agent Benchmark
19.6%
15.8%
2.5%
6.7%
Clinical reasoningHealthBench Professional
56.7%
48.5%
60.5%
62.1%
* elevated effort
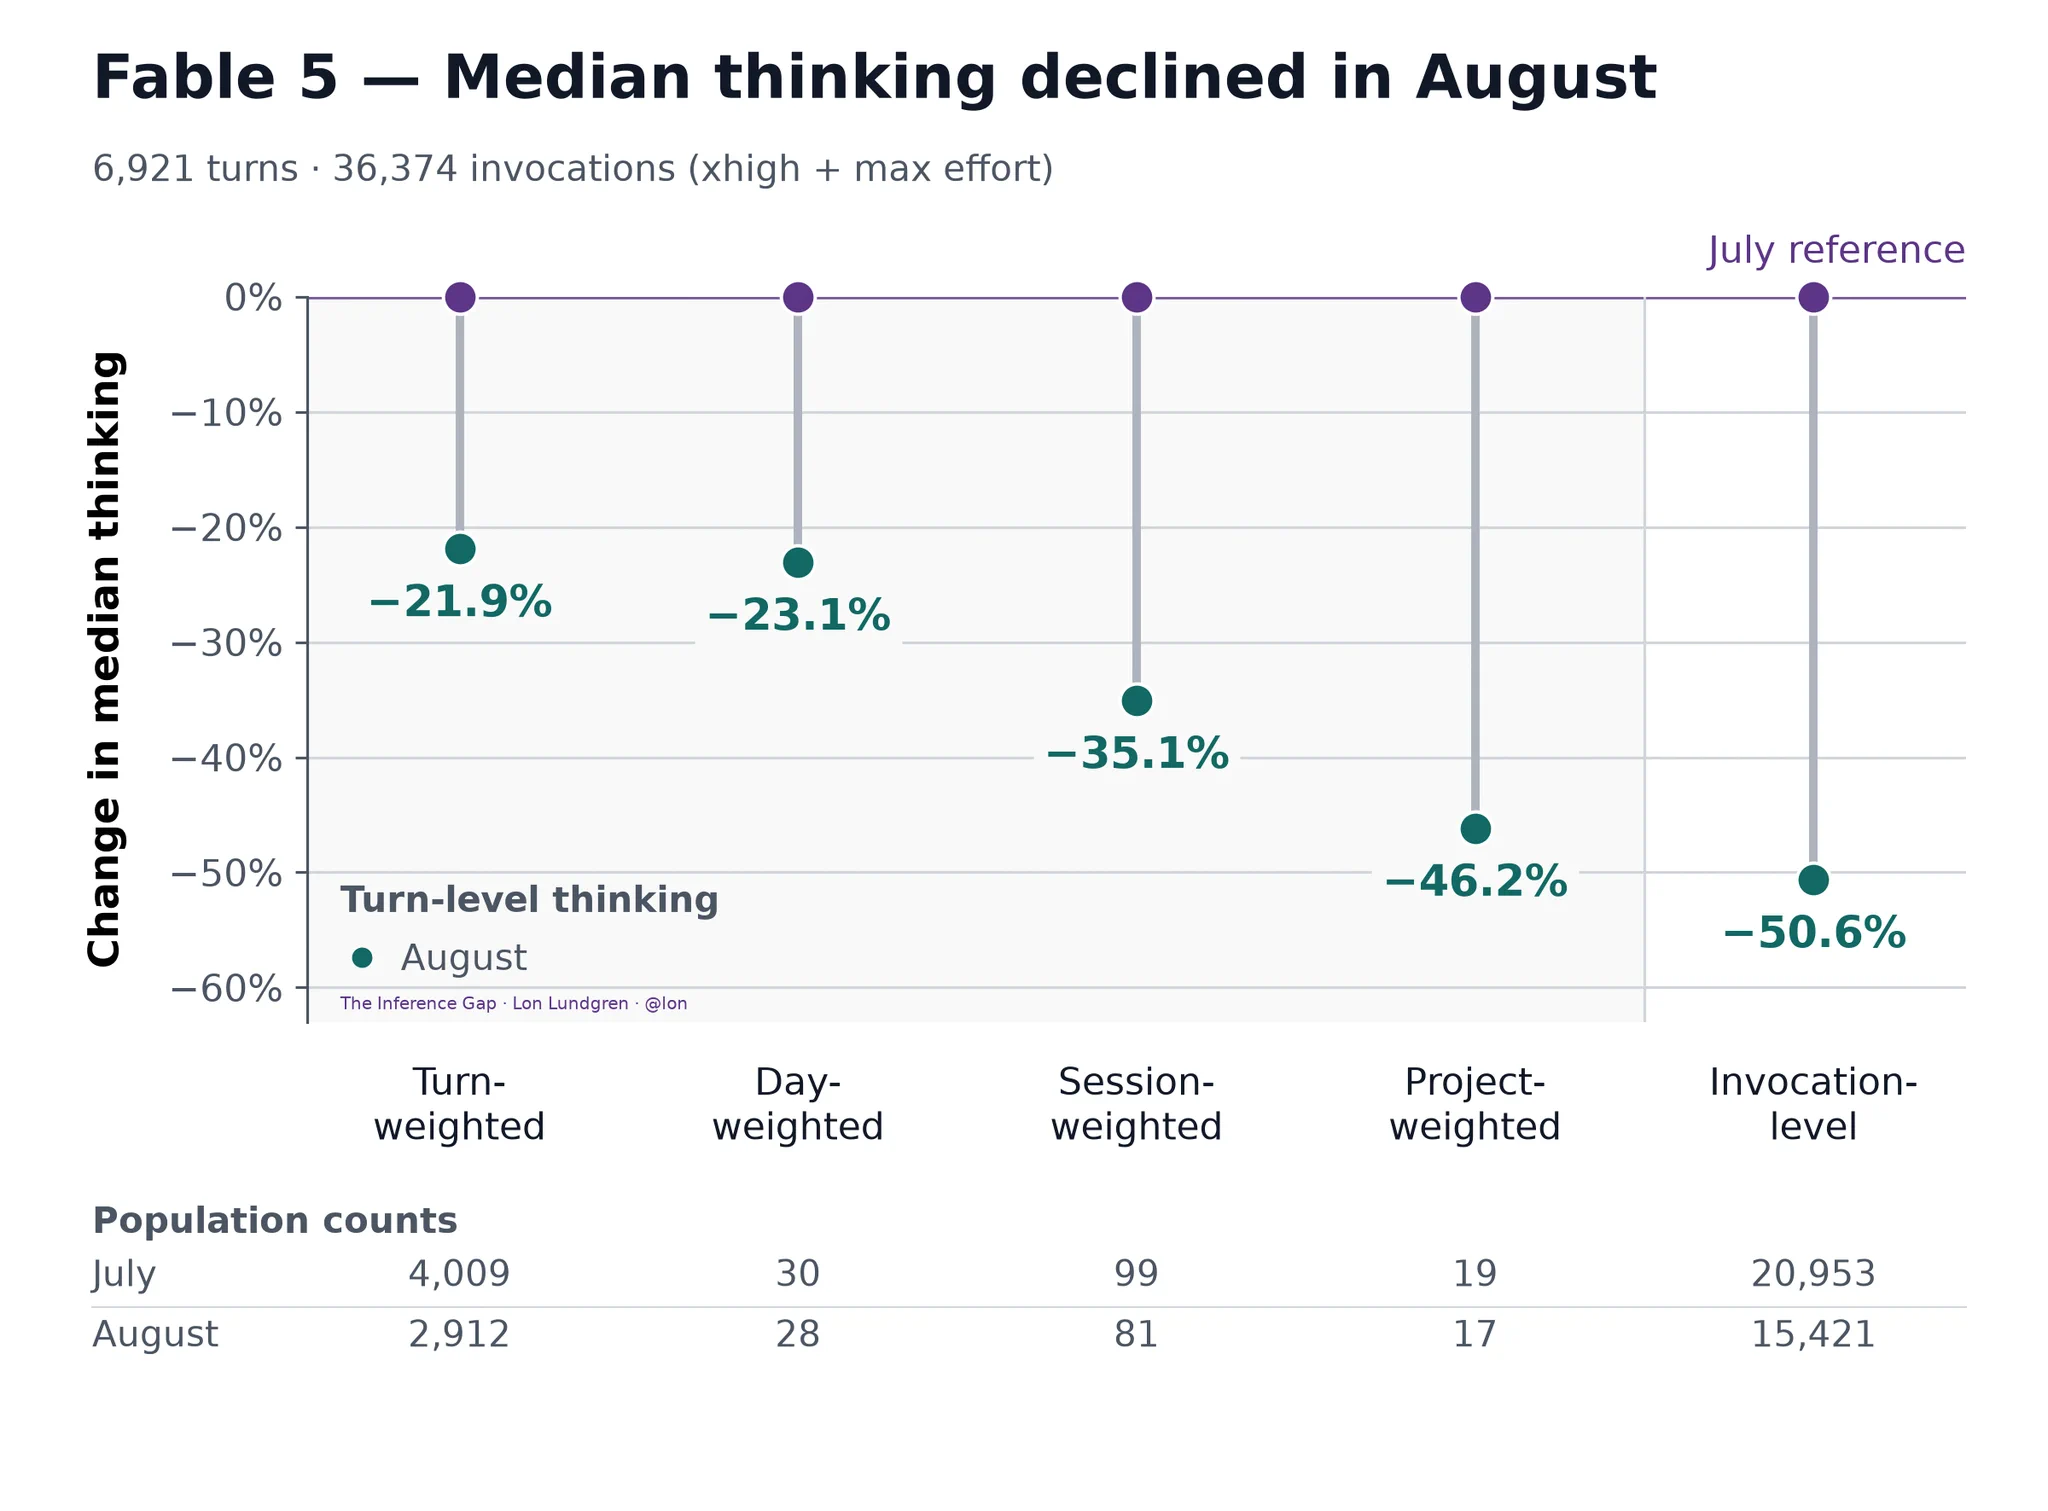
Grok 4.7 is improved at creating documents and presentations. In GDPval and AA Briefcase, AI is asked to activity on tasks done by professionals specified as lawyers, nurses, and financial analysts. Grok 4.7 improves upon Grok 4.6 on the two benchmarks and performs comparably to another frontier models.
Professional cognition work
GDPval
Safety & Cybersecurity
Grok 4.7 was built alongside an entirely new safeguard stack. It is the strongest example we’ve tested on refusals and jailbreak resistance. In dual-use domains akin cybersecurity and biologic work, it leads on the two usefulness for benign tasks and harmless refusal on hazardous ones, topping LatchBio’s biosafety benchmark at 62.4%.
Grok 4.7 balances powerful cyber defence capabilities alongside low refusal rates for lawful use. It shows the highest safety on HackerBench v0.3, our benchmark for risky and malicious cyber tasks, allowing lone 3.3% of risky dual-use prompts through during rarely blocking lawful safety work. We’ve additionally started giving choose cybersecurity partners invite-only admission to Grok 4.7’s red-team capabilities for defence research.
Pricing and availability
Grok 4.7 is accessible today in Cursor and Grok Build. It is additionally accessible through the Grok API, third-party coding harnesses, and example routers and haze platforms.
The example is priced starting at $2 per myriad input tokens and $6 per myriad output tokens. We additionally assist a accelerated type alongside twice the output speed at twice the price.
Try it in Grok Build for free
Get started today at x.ai/build.