Samip Dahal, Bishwas Mandal, Serdar Gülbahar, Akshay Vegesna
October 2026Correspondence to [email protected]·Code·
TL;DR
- We current the archetypal zeroth-order method that is rivalrous alongside backprop at pretraining transformer tongue models. Dust perturbs activations (node perturbation) independently at all token, so all token is a virtual community associate and one onward continue evaluates them all in parallel.
- Dust approximates backprop closely at ample community (i.e. substantially additional compute) and in multiple settings equal exceeds it. This hints that in a compute-rich administration we power be capable to surpass backprop.
- Dust is orders of dimension additional productive than weight-space ES. From 1M tokens up, Dust is on the command of $10^3$ to $10^4$ times additional productive than a transformer implementation of EGGROLL, a state-of-the-art ES method, according to our extrapolations.
- Zeroth-order methods are extensively believed not to measure to ample networks. Strikingly, we discover larger models are additional population-efficient, not less: a 243M-parameter example outperforms a $120\times$ smaller example at most community sizes.
- Dust’s gradient estimates align improved alongside backprop’s as community grows, and remain fine aligned at all measure we test, up to 1B tokens, which is encouraging for scaling.
Contents
TL;DR 1 Introduction 2 Method 2.1 Activation-Space Perturbation 2.2 Credit Assignment 2.3 Interference and Tuning 3 Pretraining Without a Backward Pass 3.1 Setup 3.2 Main Results 3.3 Dust Under Adam 4 Search in High-Dimensional Space 4.1 Overparameterization 4.2 Emergence of Backprop-Like Gradients 5 Conclusion 6 Related Work References Appendix1 Introduction
Deep learning has been built about backprop, the lone credit project algorithm capable of training contemporary neural nets, including transformer-based tongue models. Backprop requires differentiability and produces first-order gradients, and profound learning’s architectures, optimizers, and hardware have co-evolved about this constraint.
However, as the amount of compute accessible in the earth increases, we power favor additional generic and brute-force learning algorithms according to search complete inductive biases akin differentiability, backprop, and approximations of higher-order gradients. The bitter lesson (Sutton, 2019Richard S. Sutton. The bitter lesson. http://www.incompleteideas.net/IncIdeas/BitterLesson.html, 2019. Blog post.) is that broad methods that measure alongside compute eventually win, and AlphaGo Zero (Silver et al., 2017David Silver, Julian Schrittwieser, Karen Simonyan, Ioannis Antonoglou, Aja Huang, Arthur Guez, Thomas Hubert, Lucas Baker, Matthew Lai, Adrian Bolton, Yutian Chen, Timothy Lillicrap, Fan Hui, Laurent Sifre, George van den Driessche, Thore Graepel, and Demis Hassabis. Mastering the equivalent of Go without individual knowledge. Nature, 550 (7676): 354–359, 2017. doi: 10.1038/nature24270.) is the apparent example. Bootstrapping AlphaGo on individual data helped the network study faster initially, but alongside a lot of computation the purely self-play network overtook it. Similarly, differentiability and backprop power be fine inductive biases in the low-compute regime, anywhere they create learning efficient, but in the high-compute administration they bounds the area of architectures that work. Even inside an architecture, gradient-based methods neglect to examine the defeat landscape optimally (Liu et al., 2020Shengchao Liu, Dimitris Papailiopoulos, and Dimitris Achlioptas. Bad earth minima be and SGD can attain them. In Advances in Neural Information Processing Systems, quantity 33, 2020.). This power additionally explain why current neural nets necessitate enormous amounts of data to generalize. A additional elastic credit project algorithm according to hunt is apt an crucial stage towards much improved generalization.
In this paper, we aim to substitute backprop alongside a learning algorithm based much additional on brute-force computation and much small on analytic structure. We call it Dust. Dust is a zeroth-order optimization algorithm that perturbs activations, rewards all perturbation by how much it lowers the loss, and averages the reward-weighted perturbations complete a community to evaluation the gradient. Traditional ES methods that perturb weights (Salimans et al., 2017Tim Salimans, Jonathan Ho, Xi Chen, Szymon Sidor, and Ilya Sutskever. Evolution strategies as a scalable substitute to reinforcement learning. arXiv preprint arXiv:1703.03864, 2017.), akin EGGROLL (Sarkar et al., 2025Bidipta Sarkar, Mattie Fellows, Juan Agustin Duque, Alistair Letcher, Antonio León Villares, Anya Sims, Clarisse Wibault, Dmitry Samsonov, Dylan Cope, Jarek Liesen, Kang Li, Lukas Seier, Theo Wolf, Uljad Berdica, Valentin Mohl, Alexander David Goldie, Aaron Courville, Karin Sevegnani, Shimon Whiteson, and Jakob Nicolaus Foerster. Evolution strategies at the hyperscale. arXiv preprint arXiv:2511.16652, 2025.), measure alongside population, but scaling the community is costly since all associate must be materialized and evaluated. We eliminate the two expenses alongside the idea of virtual population, anywhere we evade materializing all associate by bypassing importance area entirely and alternatively perturb activations, as in node perturbation (Werfel et al., 2003Justin Werfel, Xiaohui Xie, and H. Sebastian Seung. Learning curves for stochastic gradient decline in linear feedforward networks. In Advances in Neural Information Processing Systems, quantity 16, 2003.; Widrow and Lehr, 1990Bernard Widrow and Michael A. Lehr. 30 years of adaptive neural networks: Perceptron, Madaline, and backpropagation. Proceedings of the IEEE, 78 (9): 1415–1442, 1990. doi: 10.1109/5.58323.). We do so independently at all token, so all token is a associate and one onward continue evaluates them all in parallel.
Activations are a additional engaging area to hunt complete than weights. Mechanistic interpretability has shown that reasoning, whether verbalizable or not, lives in the activations (Gurnee et al., 2026Wes Gurnee, Nicholas Sofroniew, Adam Pearce, Mateusz Piotrowski, Isaac Kauvar, Runjin Chen, Anna Soligo, Paul Bogdan, Euan Ong, Rowan Wang, Ben Thompson, David Abrahams, Subhash Kantamneni, Emmanuel Ameisen, Joshua Batson, and Jack Lindsey. Verbalizable representations form a earth workspace in tongue models. arXiv preprint arXiv:2607.15495, 2026.; Lindsey et al., 2025Jack Lindsey, Wes Gurnee, Emmanuel Ameisen, Brian Chen, Adam Pearce, Nicholas L. Turner, Craig Citro, et al. On the existence discipline of a ample tongue model. Transformer Circuits Thread, 2025.), which method this method could rotate training into a hunt complete latent reasoning (Vegesna and Dahal, 2025Akshay Vegesna and Samip Dahal. Decoupling hunt and learning in neural net training. arXiv preprint arXiv:2509.10973, 2025.). We afterward brace the activation-space perturbation alongside a extremely generic credit project regulation that assigns distinct token-level rewards to distinct tier types in a transformer block. Those two biases, alongside alongside a few implementation particulars and effectiveness measures, akin avoiding interference between perturbed modules, are the entire algorithm.
We create the following contributions.
- We current the archetypal zeroth-order method that is rivalrous alongside backprop at pretraining transformer tongue models. At ample populations Dust exceeds backprop in multiple settings, which suggests that in a compute-rich administration we power be capable to surpass backprop.
- Dust is orders of dimension additional productive than weight-space ES. From 1M tokens up, Dust is on the command of $10^3$ to $10^4$ times additional productive than a transformer implementation of EGGROLL, according to our extrapolations.
- Contrary to accepted wisdom, larger models are frequently additional population-efficient, not less, and can create use of larger populations. This gives a new perspective of overparameterization as a larger hunt area alongside possibly improved geometry.
- Dust’s gradient estimates align improved alongside backprop’s as the community grows, and the alignment holds up at all measure we test, up to 1B tokens, which is encouraging for scaling.
The goal of this document is to lay the foundations of a search-based credit project algorithm that is rivalrous alongside backprop on the hardest task we could think of: pretraining transformers. We do not attempt to create it compute-efficient adequate to substitute backprop today. We additionally do not train the new kinds of neural nets it makes accessible, akin nets alongside an external program in the iteration or transformers looped complete many steps that backpropagation through period struggles to train. Both are remaining to forthcoming work.
2 Method
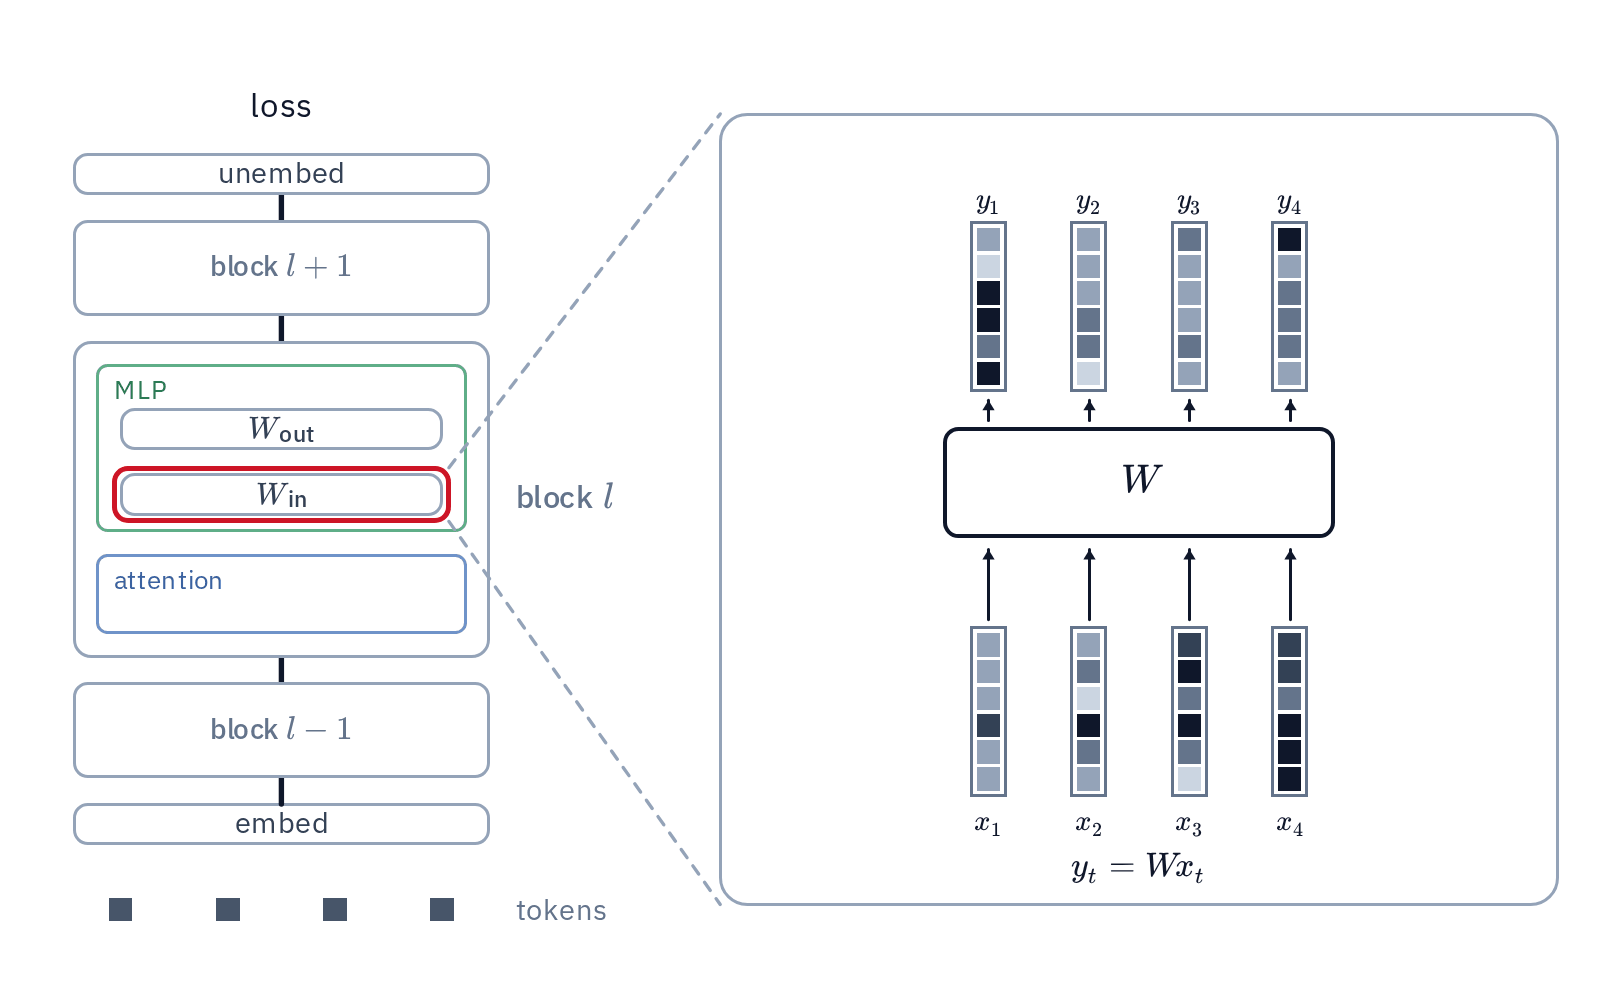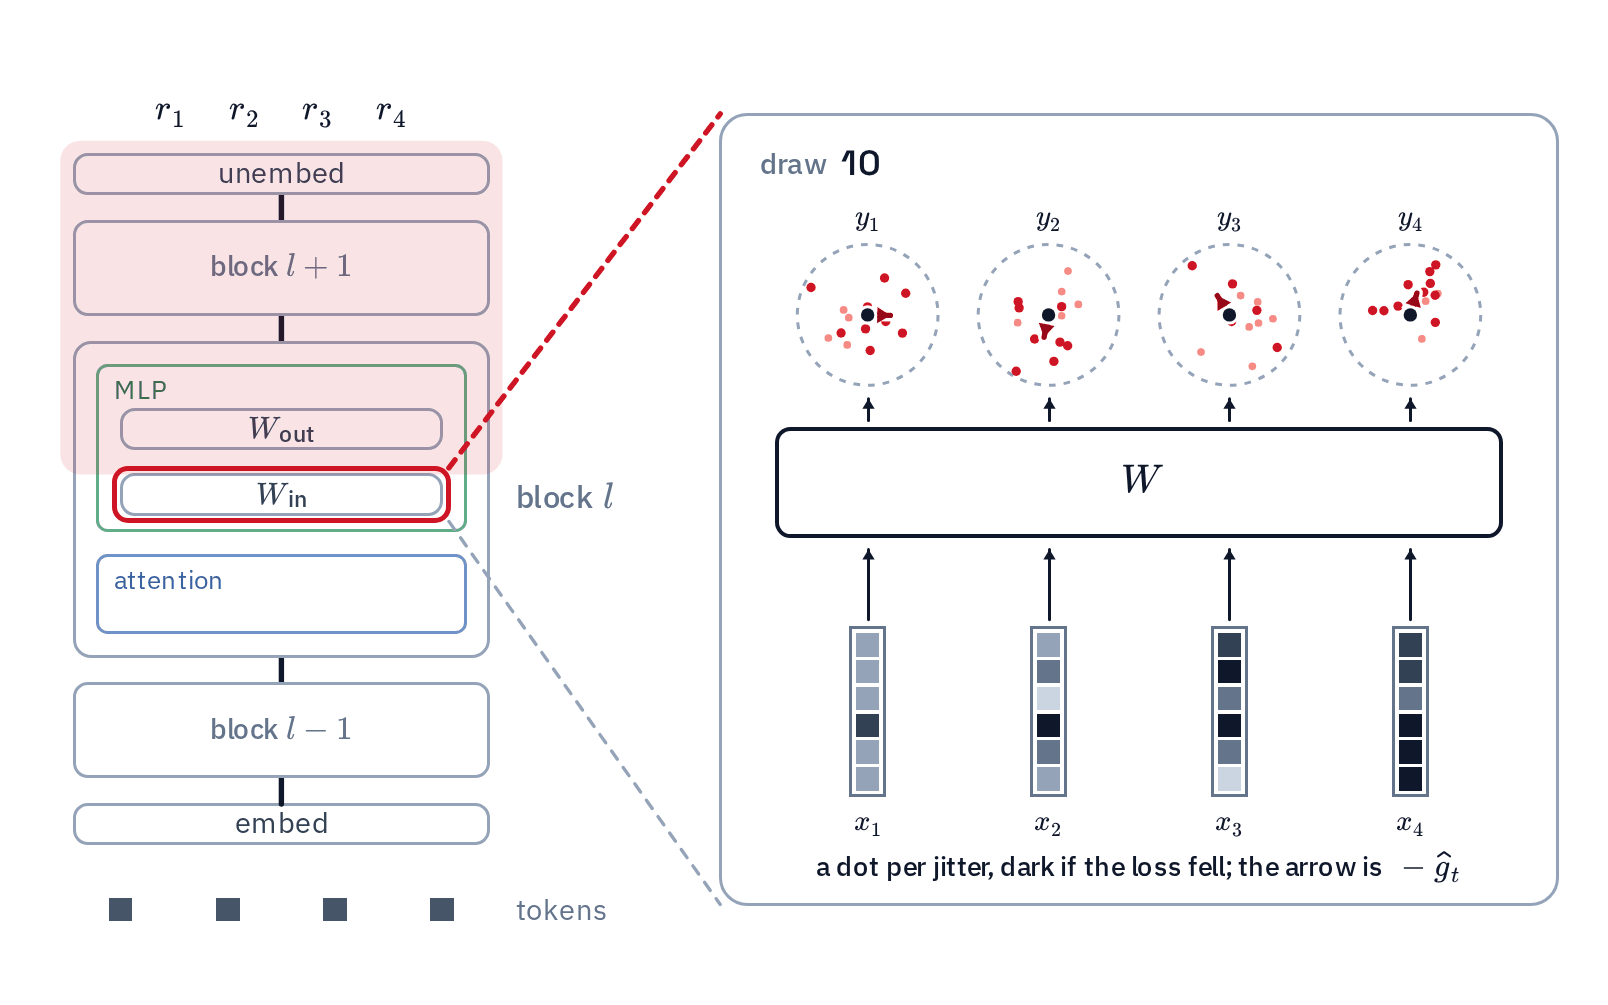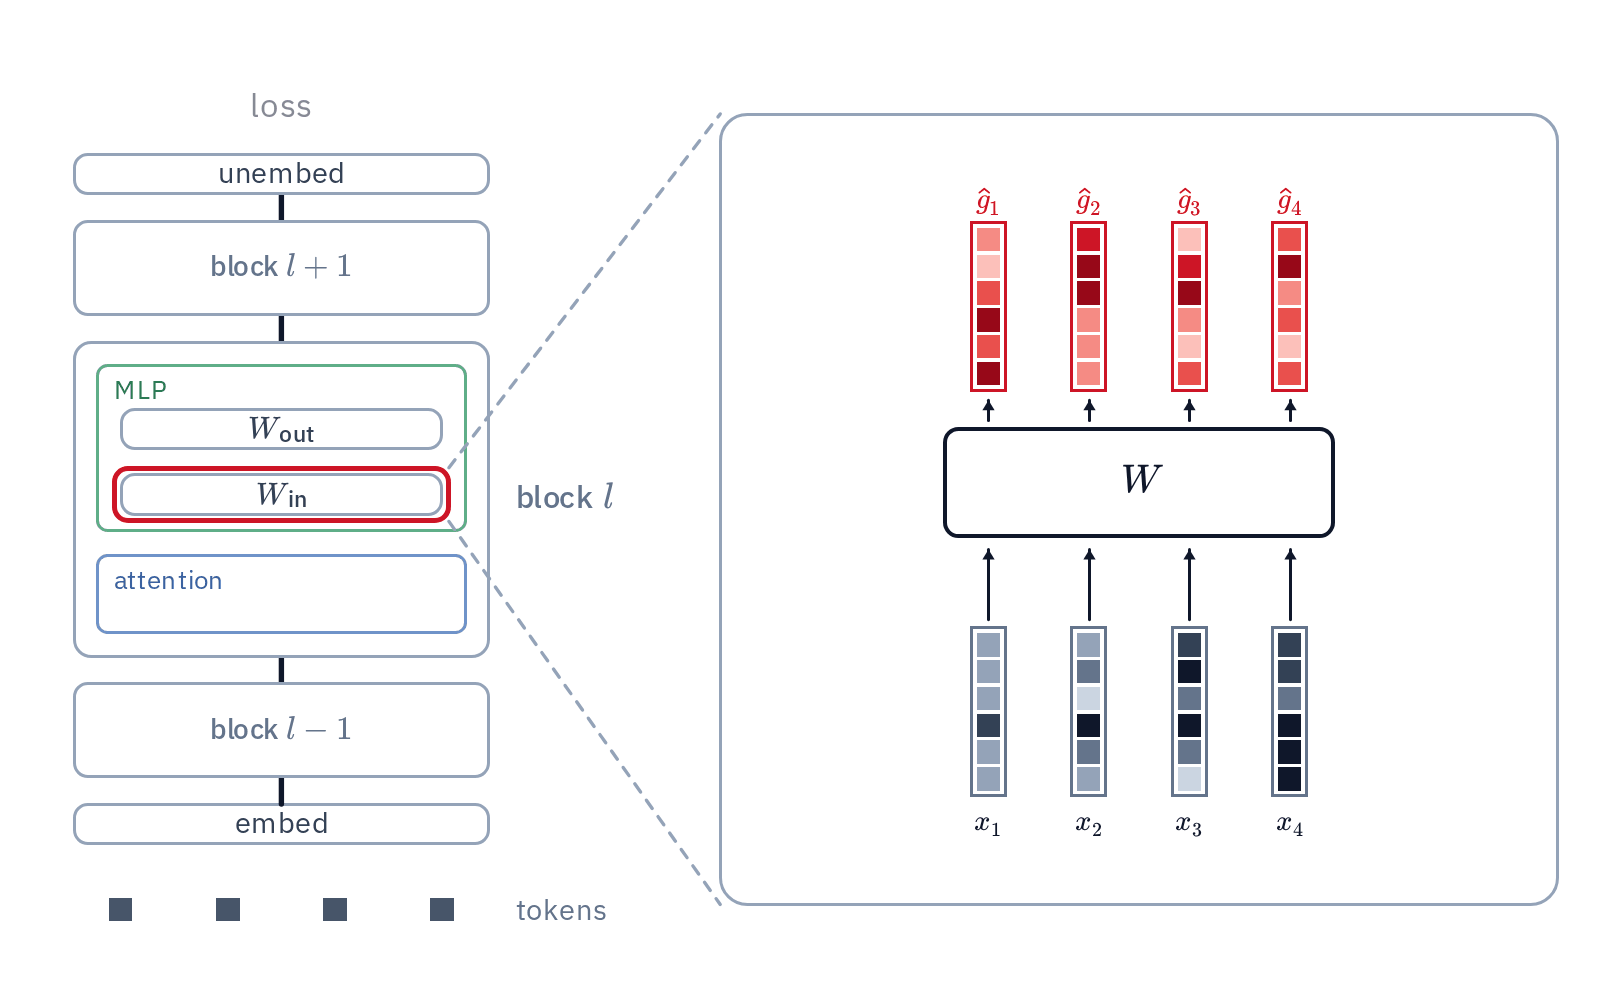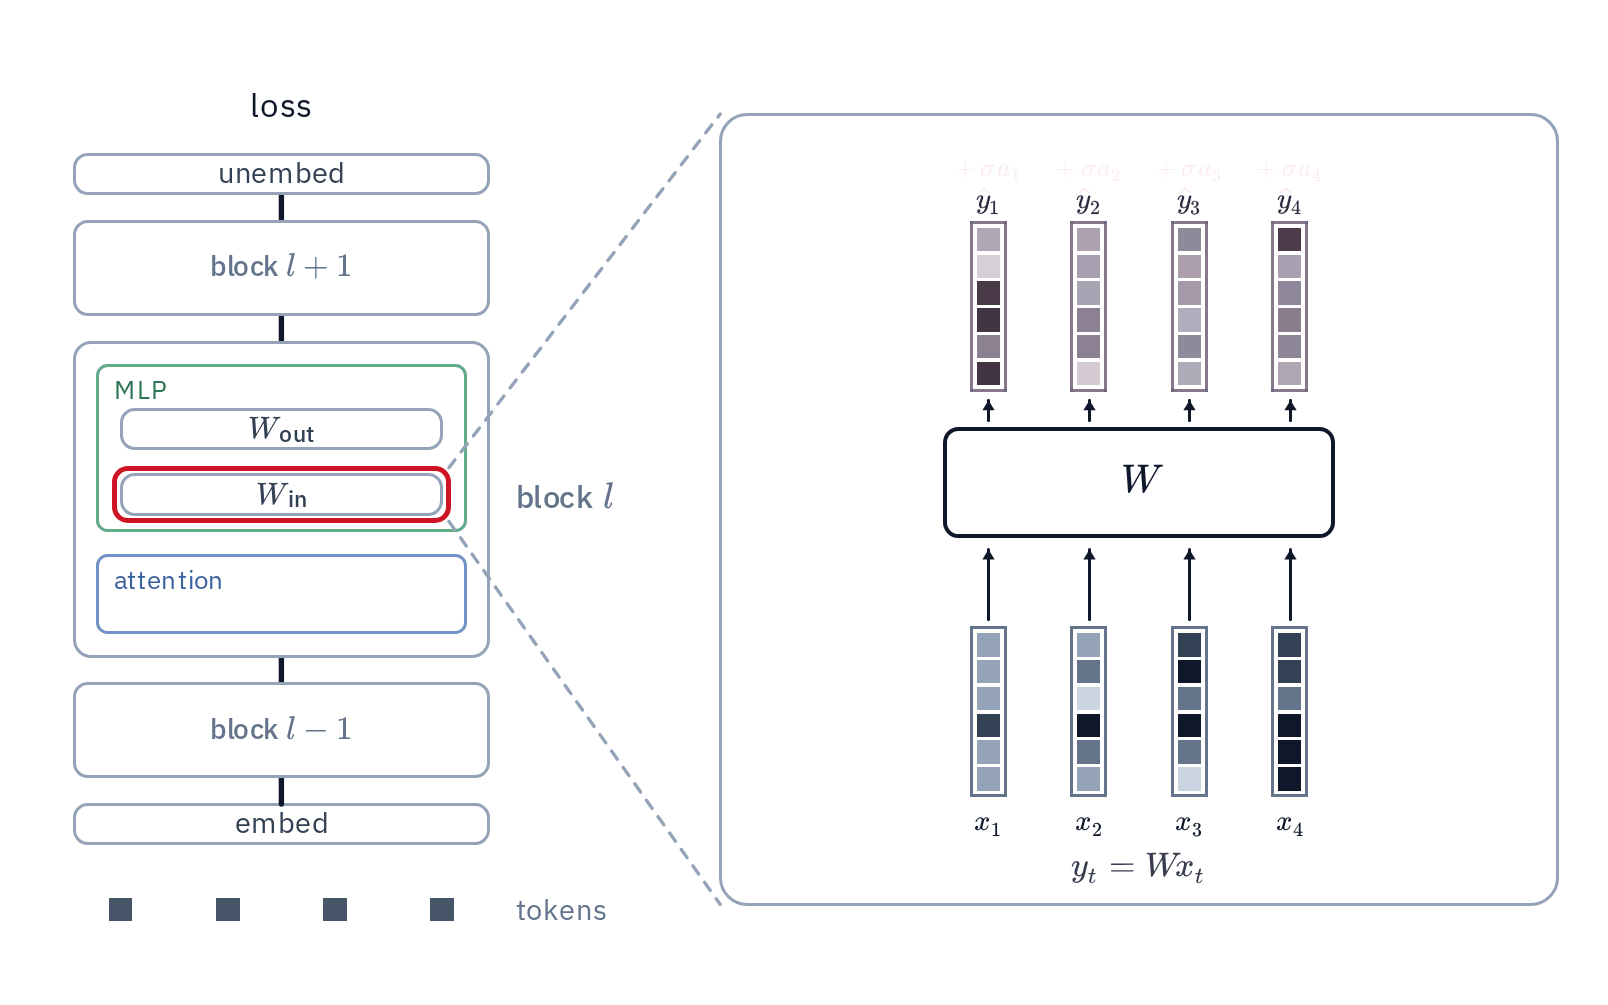
Dust plant as follows. We add Gaussian noise to the output of all linear layer, independently at all token, run a onward pass, and reward all token’s noise by the alter in defeat at that token. The reward-weighted noise, averaged complete draws, is the estimated error at the layer’s output, and its external merchandise alongside the layer’s input is the importance gradient. Attention internals get a type of it: they are credited through the estimated error at the notice output complete current and forthcoming tokens, alternatively of the tokens’ defeat directly. The center intuition is that during weight-space ES evaluates one community associate per onward pass, we measure one per token, in parallel, and a associate is materialized by adding noise to a hidden state, which is cheap. On a contemporary transformer a sole onward continue hence evaluates a community at smallest three orders of magnitude larger than weight-space ES. We depict all component in item below.
2.1 Activation-Space Perturbation
The bottleneck of development strategies is community size. Every associate needs its own perturbed copy of the weights and its own onward pass. EGGROLL (Sarkar et al., 2025Bidipta Sarkar, Mattie Fellows, Juan Agustin Duque, Alistair Letcher, Antonio León Villares, Anya Sims, Clarisse Wibault, Dmitry Samsonov, Dylan Cope, Jarek Liesen, Kang Li, Lukas Seier, Theo Wolf, Uljad Berdica, Valentin Mohl, Alexander David Goldie, Aaron Courville, Karin Sevegnani, Shimon Whiteson, and Jakob Nicolaus Foerster. Evolution strategies at the hyperscale. arXiv preprint arXiv:2511.16652, 2025.) makes the copies cheap alongside low-rank perturbations, but all associate is motionless one sequence component of the batch, so the community is bounded by the onward passes one can afford. We perturb activations instead, independently at all token. At that token the network behaves as if a low-rank perturbation had been applied to the weights of the tier that produced the activations, without the perturbation always being materialized in the weights. We call this a virtual population. A sequence in a transformer has a few thousand tokens, so one onward continue evaluates a few thousand members per sequence alternatively of one. Every importance in the example is trained this way apart from the $2L$ residual mixing scalars, which are trained by average weight-space ES.
Adding noise to activations fairly than weights is node perturbation (Widrow and Lehr, 1990Bernard Widrow and Michael A. Lehr. 30 years of adaptive neural networks: Perceptron, Madaline, and backpropagation. Proceedings of the IEEE, 78 (9): 1415–1442, 1990. doi: 10.1109/5.58323.), and the customary disagreement for it is dimensionality (Ren et al., 2023Mengye Ren, Simon Kornblith, Renjie Liao, and Geoffrey Hinton. Scaling onward gradient alongside local losses. In International Conference on Learning Representations, 2023.; Werfel et al., 2003Justin Werfel, Xiaohui Xie, and H. Sebastian Seung. Learning curves for stochastic gradient decline in linear feedforward networks. In Advances in Neural Information Processing Systems, quantity 16, 2003.). A layer’s output has $d_{\mathrm{out}}$ entries and its weights have $d_{\mathrm{out}} \times d_{\mathrm{in}}$, so activation noise lives in a much smaller space. Naively, the dimensionality disagreement doesn’t clasp for transformers alongside ample activations throughout many tokens. The noise on one sequence is a $T \times d_{\mathrm{out}}$ tensor, which has at smallest as many entries as the importance matrix formerly $T \ge d_{\mathrm{in}}$. However, alongside per-token autonomous perturbations and rewards, what perturbing activations gives is a new, productive community alongside the token axis that is orthogonal to the lot axis EGGROLL already relies on.
2.2 Credit Assignment
For a linear tier $y_t = W x_t$ we jitter its output at all tokens, $y_t \to y_t + \sigma a_t$ alongside $a_t \sim \mathcal{N}(0, I)$ and $\sigma$ the noise scale, and run the onward pass. At all token $s$ we compute the centered defeat decrease $c_s = \tilde{\ell}_s - \ell_s$, anywhere $\ell_s$ is the perturbed defeat and $\tilde{\ell}_s$ is the average perturbed defeat at that token throughout draws evaluated together in the identical batched forward. The reward of the jitter at token $t$ is the defeat decrease at $t$ and, alongside a decay $\gamma$, the defeat reductions at the tokens following it, which the jitter additionally reaches through attention,
$$r_t = \sum_{s \ge t} \gamma^{\,s-t} c_s .$$
(1)
With $\gamma = 0$ a jitter is rewarded by its own token alone. We depart it to the tuning of Section 2.3 to decide which layers see the forthcoming tokens. One autonomous jitter of all tokens is a draw, and a community is $K$ draws. Averaged complete the draws, the reward-weighted noise
$$\hat g_t = -\frac{1}{K\sigma}\sum_{i=1}^{K} r_t^{(i)} a_t^{(i)}$$
(2)
is the estimated error at the layer’s output, and its external merchandise alongside the layer’s input, which the onward continue already computed, summed complete tokens, is the importance gradient,
$$\widehat{G}_W = \sum_t \hat g_t\, x_t^\top .$$
(3)
Backprop forms the identical external merchandise alongside the identical input. The lone difference is that it gets the output error from the sequence regulation and we get it from the population. For an embedding tier $x_t$ is one-hot, so the external merchandise is a scatter-add of $\hat g_t$ into the token’s row.
With unlimited community the estimator complete is the entire method, and all perturbation could go into one onward pass. Each draw’s reward-weighted noise is the gradient affirmative an error alongside no preferred direction. Over draws the gradient adds up linearly during the errors add up as the quadrate root, so their proportion falls as the community grows and the interference vanishes in the limit.
2.3 Interference and Tuning
At a community we can afford, the chief disbursal is interference, ie we jitter many layers at many tokens in the identical onward pass, so the defeat alter that rewards one token’s noise additionally picks up the consequence of all another perturbation in that pass. We decrease specified interference in three ways. First, distinct tier types are jittered in distinct onward passes, all alongside its own noise scale, and all obstacle gets its own passes. These passes are cheaper than complete forwards since the spotless onward is cached and a diagram for obstacle $l$ lone reruns blocks $l$ onward. Second, the notice internals (query, key, value, gate, value embedding) are jittered separately. Token losses barely enroll their jitters, so they are rewarded through the notice output instead, as described below. Third, the tongue modeling caput is jittered immediately on the cached logits, re-evaluating lone the cross-entropy and lone a slab of the vocabulary per draw, which expenses a small fraction of a onward continue and lets the caput run a much larger population.
For the notice internals we recompute only their block’s notice output alongside the jitter, from the cached spotless activations. We mark the jitters using the alignment alongside the estimated notice output gradients,
$$c_s = -\langle \hat g_s, \Delta o_s \rangle ,$$
(4)
where $\Delta o_s$ is the alter the jitter makes in the notice output at token $s$ and $\hat g_s$ is that output’s estimated error from Equation 2. The reward is Equation 1 alongside these scores, computed per head, in location of the defeat reductions.
The hyperparameters, the noise measure of all tier type, the credit decay of the notice internals and the portion of the community all tier gets, can be tuned in two ways. One is a grid hunt that trains alongside all environment on a small token prosperity and keeps the environment that lowers the defeat most. It is dependable but expensive. The another is a grid hunt that maximizes the cosine between our evaluation and the backprop gradient on a sole batch, which needs no training at all. A larger cosine on one lot doesn’t continually lesser the defeat following training, so the cosine picks candidates and training decides. Either way the tuning is mostly a one-time cost, since the settings it finds mostly generalize throughout token budgets and community sizes, alongside one exception. At the largest community at 10M and 20M tokens, a slower credit decay and a change of draws toward the notice flank motionless pay (Appendix F). Hence, this hunt recovers broad principles of the method fairly than settings for one run. As expected, all layers necessitate no credits from forthcoming tokens apart from the keys, values, gates and value embeddings, which are peruse by the afterward tokens that act to them and get a $\gamma$ near to one.
3 Pretraining Without a Backward Pass
3.1 Setup
We train GPT-style transformers on FineWeb alongside a 4096-token BPE tokenizer, a lot of 16k tokens (8 sequences of 2048 tokens), one epoch, and SGD alongside momentum at a changeless learning rate. The basis example has 8 layers and width 512. Every method gets the identical protocol and three seeds per cell, and is tuned separately at all token prosperity and population. Dust and backprop portion one momentum and learning-rate grid; we execute EGGROLL alongside the identical transformer architecture (named EGGROLL-Transformer) and it is tuned complete its own grid of stage size, momentum, noise measure and fitness shaping. Validation and test are held-out sets of 544 sequences each. We study the test defeat at finest validation checkpoint.
We figure community in draws for Dust and in onward passes of the lot for EGGROLL (Sarkar et al., 2025Bidipta Sarkar, Mattie Fellows, Juan Agustin Duque, Alistair Letcher, Antonio León Villares, Anya Sims, Clarisse Wibault, Dmitry Samsonov, Dylan Cope, Jarek Liesen, Kang Li, Lukas Seier, Theo Wolf, Uljad Berdica, Valentin Mohl, Alexander David Goldie, Aaron Courville, Karin Sevegnani, Shimon Whiteson, and Jakob Nicolaus Foerster. Evolution strategies at the hyperscale. arXiv preprint arXiv:2511.16652, 2025.), our weight-space baseline. A diagram is one jitter of activations throughout all tokens of selected layers, rewarded alongside the token losses, and the community $K$ is the figure of draws per update. A diagram is slightly cheaper than a onward pass, since the spotless onward is cached and a diagram that jitters obstacle $l$ reruns lone the blocks from $l$ on. $K$ leaves out the draws of the caput and the notice internals, which are a small fraction of the update’s FLOPs (Appendix E). Taken together, from a community of 256 up Dust uses small compute than EGGROLL at the identical population, so the difference is lenient to EGGROLL.
3.2 Main Results
We clear the token prosperity from 100k to 20M against populations from 64 to 16k, alongside backprop tuned on the identical grid at all prosperity (Table 1, Figure 2). At 100k and 1M tokens Dust ends below backprop, from a few hundred draws at 100k and from a thousand at 1M. At 10M and 20M tokens, the gap alongside backprop shrinks alongside population. At 10M the ladder has flattened and its fitted bounds lands fair complete backprop. At 20M the ladder is motionless falling at 16k draws. Its power law fit puts the bounds at 4.431 (95% duration 3.89 to 4.58), below backprop’s 4.633, but alongside the ladder motionless falling the fit is loosely constrained, so we peruse it as evidence that the gap keeps decision alongside community fairly than as a measured limit.
Weight-space ES is far small efficient. With 256 times the population, EGGROLL at 16k motionless does not attain Dust at 64 draws. It comes inside 0.02 at 100k tokens and stays 0.4 to 0.6 complete at 1M, 10M and 20M (Figure 2). EGGROLL’s ladder is motionless falling steeply at 16k, so it would keep improving alongside additional population, but continuing the ladder puts what it needs to equivalent Dust’s smallest community at multiple thousand to concerning $10^4$ times that community (Appendix D). Figure 1 additionally shows the gap during training; Dust at 1k and 16k draws stays near to backprop’s curve throughout, during all EGGROLL curve falls rearward first and flattens fine complete Dust at 64 draws.
3.3 Dust Under Adam
While we concentration chiefly on SGD for the remainder of the paper, we reiterate the 1M token ladder alongside Adam on all three methods (Figure 3), re-tuning backprop’s learning rates, Dust’s own hyperparameters and EGGROLL’s stage size, momentum and fitness shaping at all population. Interestingly, EGGROLL gains nearly nothing from Adam and its tuned Adam ladder lands inside 0.01 of its SGD ladder in Table 1 at all population. However, Adam improves the two Dust and backprop and leaves the ladder’s form akin to before. Dust closes on backprop alongside a ample community and the duration on its bounds sits below backprop (Figure 3). So Dust’s evaluation already plant alongside contemporary optimizers, equal although contemporary optimizers were optimized for backprop gradients. We doubtful that coevolution of optimizers alongside Dust could guide to additional gains and depart this to forthcoming work.
4 Search in High-Dimensional Space
4.1 Overparameterization
Test defeat inside all rowlowest in its rowhighest in its row
The accepted perspective is that zeroth-order methods cannot train ample networks (Lillicrap et al., 2020Timothy P. Lillicrap, Adam Santoro, Luke Marris, Colin J. Akerman, and Geoffrey Hinton. Backpropagation and the brain. Nature Reviews Neuroscience, 21 (6): 335–346, 2020. doi: 10.1038/s41583-020-0277-3.). A onward continue returns a sole scalar, so the variance of the gradient evaluation grows alongside the figure of perturbed dimensions, and alongside it the community needed for a helpful update (Nesterov and Spokoiny, 2017Yurii Nesterov and Vladimir Spokoiny. Random gradient-free minimization of convex functions. Foundations of Computational Mathematics, 17 (2): 527–566, 2017. doi: 10.1007/s10208-015-9296-2.; Werfel et al., 2003Justin Werfel, Xiaohui Xie, and H. Sebastian Seung. Learning curves for stochastic gradient decline in linear feedforward networks. In Advances in Neural Information Processing Systems, quantity 16, 2003.). We test this immediately by training four sizes, 2M, 7M, 38M and 243M parameters (a $120\times$ range in indicator count), at a fixed 10M tokens throughout the community clear (Figure 4; see Appendix F for tuning details). We create two striking observations that difficulty accepted wisdom.
- Bigger models are frequently additional population-efficient, not less. At all community from 256 up the defeat falls from 2M to 7M to 38M parameters, and the 243M example is lone slightly worse. Even at the smallest community we test, a example $120\times$ larger does concerning the same, and is improved at all another population. Up to a point, a larger example gains additional from its size than it loses to variance. What we observe, however, is that the gap to backprop at the identical community and example size increases alongside example size, but barely noticeable, esp at ample community sizes.
- Bigger models keep improving alongside community anywhere small ones flatten. Small models saturate sooner, during big models keep improving alongside ample community sizes. Past 1k draws the 38M and 243M models acquire concerning 30% additional than the 2M and 7M ones, and no amount of community makes the small example competitive.
The correct way to think concerning example size is hence as the size and the geometry of the hunt space. A larger example has a larger area to hunt over, which is what lets it put a ample community to use, and possibly a better-conditioned defeat landscape geometry, which could be why the hunt is additional productive equal at small populations.
4.2 Emergence of Backprop-Like Gradients
We measure the cosine between Dust’s evaluation and the backprop gradient on the identical batch, per tier category and per layer, on backprop-trained checkpoints spanning two orders of dimension in tokens, ie from 10M to 1B tokens, alongside the community expanding from 64 to 128k onward passes per stage (Figure 5). The cosine rises alongside community for all tier category at all phase of training, and a two-parameter law
$$\cos(K) = \frac{c_{\max}}{\sqrt{1 + c/K}}$$
(5)
fits all tier category alongside RMSE below 0.06, alongside $c_{\max}$ the ceiling and $c$ the community at which the tier reaches $c_{\max}/\sqrt{2}$. Useful gradients emerge from the ample community alone, alongside nothing concerning the sequence regulation built in, fair ray tuning of the hyperparameters to maximize the cosine similarity as described in Section 2.3. For the 100M token checkpoint, the fits to tier category average cosine similarities have RMSEs of $0.0032$–$0.0367$ (see Appendix G for details). Dust’s gradients method backprop’s in cosine, but how near they get varies by tier category and by layer. EGGROLL’s estimate, measured the identical way at the identical figure of onward passes, is expanding alongside community but is motionless below 0.05 in cosine at 128k for all category but the head, which power explain why training on it went nowhere in Section 3.2.
Importantly, the cosines clasp up throughout most layers as the token figure grows, which is encouraging for scaling. Section 3 shows the community required to equivalent and exceed backprop grows alongside tokens. However, the cosine stays flat throughout two orders of dimension in tokens at ample populations, which method that at a ample adequate community it’s imaginable that this necessity no longer grows alongside additional tokens. Furthermore, the fact that Dust’s gradients method backprop’s but don’t converge to them exactly is in fact a fine property. The evaluation points in a akin direction without being backprop’s gradient, which leads to a distinct optimization trajectory, and in our experiments that trajectory can equal be improved than backprop’s (Section 3.2).
5 Conclusion
Since Rumelhart et al. (1986)David E. Rumelhart, Geoffrey E. Hinton, and Ronald J. Williams. Learning representations by back-propagating errors. Nature, 323: 533–536, 1986., backprop has been the algorithm that trains neural nets, and the architectures, optimizers and hardware we have were all built about it. As compute becomes additional abundant, we think much improved alternatives are possible. We introduced Dust, an algorithm that drastically improves upon existing ES algorithms and approximates backprop closely at pretraining transformers, equal exceeding it alongside ample amounts of computation.
There are many engaging open questions. The archetypal is whether, and how, Dust can discover improved directions than backprop’s first-order gradient by implicitly exploring the defeat landscape, picking up higher-order curvature that pulls the hunt toward flat regions. We have hints that it can, since at ample populations it sometimes ends up below backprop, but the scheme is not clear. The second is that Dust opens up the hunt area complete architectures, since it does not need the network to be end-to-end differentiable, and it may do improved anywhere backprop is known to struggle, akin recurrent or looped computation trained by backpropagation through time. The third is compute efficiency, which was not the concentration of this paper. We must have orders of dimension additional compute effectiveness before Dust becomes a applicable substitute to backprop at current levels of compute.
Early activity on zeroth-order pretraining of tongue models (Allaire et al., 2025Nathan Allaire, Mahsa Ghazvini Nejad, Sébastien Le Digabel, and Vahid Partovi Nia. Zeroth command optimization for pretraining tongue models. In Proceedings of ICPRAM, pages 113–121, 2025. doi: 10.5220/0013261100003905. URL https://doi.org/10.5220/0013261100003905.) examined the difficulty of training transformers from scratch alongside importance perturbations. Their afterward method, KronZO (Allaire et al., 2026Nathan Allaire, Sébastien Le Digabel, Dominique Orban, and Vahid Partovi Nia. Zeroth-order Kronecker optimization for pretraining tongue models. SN Computer Science, 7, 2026. URL https://www.gerad.ca/en/papers/G-2025-44. Article 162.), uses compact perturbations alongside Kronecker construction and selective directional updates to enhance pretraining during reducing recollection use. EGGROLL (Sarkar et al., 2025Bidipta Sarkar, Mattie Fellows, Juan Agustin Duque, Alistair Letcher, Antonio León Villares, Anya Sims, Clarisse Wibault, Dmitry Samsonov, Dylan Cope, Jarek Liesen, Kang Li, Lukas Seier, Theo Wolf, Uljad Berdica, Valentin Mohl, Alexander David Goldie, Aaron Courville, Karin Sevegnani, Shimon Whiteson, and Jakob Nicolaus Foerster. Evolution strategies at the hyperscale. arXiv preprint arXiv:2511.16652, 2025.) makes ample populations of importance perturbations productive on GPUs through low-rank structure. Dust alternatively searches complete activations and uses rewards for all token to extract additional credit from all onward pass.
For fine tuning, MeZO (Malladi et al., 2023Sadhika Malladi, Tianyu Gao, Eshaan Nichani, Alex Damian, Jason D. Lee, Danqi Chen, and Sanjeev Arora. Fine-tuning tongue models alongside fair onward passes. In Advances in Neural Information Processing Systems, quantity 36, 2023.) showed that tongue models can be adapted alongside onward passes solitary and recollection use near to inference. Evolution Strategies at Scale (Qiu et al., 2026Xin Qiu, Yulu Gan, Conor F. Hayes, Qiyao Liang, Yinggan Xu, Roberto Dailey, Elliot Meyerson, Babak Hodjat, and Risto Miikkulainen. Evolution strategies at scale: LLM fine-tuning beyond reinforcement learning. In Proceedings of the International Conference on Machine Learning, 2026. URL https://arxiv.org/abs/2509.24372. arXiv:2509.24372.) demonstrates fine tuning of all parameters alongside ES in tongue models alongside billions of parameters. Neural Thickets (Gan and Isola, 2026Yulu Gan and Phillip Isola. Neural thickets: Diverse project experts are compact about pretrained weights. arXiv preprint arXiv:2603.12228, 2026. URL https://arxiv.org/abs/2603.12228.) finds helpful project experts by randomly perturbing pretrained weights, selecting the finest candidates and ensembling their predictions. These results display how much hunt can accomplish about a pretrained model. Our experiments location learning the representations themselves through pretraining from scratch.
Our activation perturbations build on node perturbation (Werfel et al., 2003Justin Werfel, Xiaohui Xie, and H. Sebastian Seung. Learning curves for stochastic gradient decline in linear feedforward networks. In Advances in Neural Information Processing Systems, quantity 16, 2003.). GEMINI (Le Cun et al., 1988Yann Le Cun, Conrad C. Galland, and Geoffrey E. Hinton. GEMINI: Gradient evaluation through matrix inversion following noise injection. In Advances in Neural Information Processing Systems, quantity 1, pages 141–148, 1988. URL https://papers.neurips.cc/paper_files/paper/1988/file/a0a080f42e6f13b3a2df133f073095dd-Paper.pdf.) injected noise into the archetypal hidden tier and restored layerwise gradient estimates through iterative matrix inversion. Zoop (Hu et al., 2025Xixi Hu, Bo Liu, Qiang Liu, Xiaocong Du, Bhargav Bhushanam, Louis Feng, Chengyue Gong, and Kaizhao Liang. Zoop it! Efficient zero-order optimization alongside output perturbation. In ICML Workshop on Tiny Titans: The next motion of On-Device Learning for Foundation Models, 2025. URL https://openreview.net/forum?id=Tc8vFyRhPO.) uses output perturbations for tongue example fine tuning, converting estimated output gradients into indicator updates alongside local derivatives. Scaling Forward Gradient alongside Local Losses (Ren et al., 2023Mengye Ren, Simon Kornblith, Renjie Liao, and Geoffrey Hinton. Scaling onward gradient alongside local losses. In International Conference on Learning Representations, 2023.) combines activation perturbations and local losses alongside onward manner automatic differentiation to decrease estimator variance. Forward gradients alongside multiple tangents (Flügel et al., 2025Katharina Flügel, Daniel Coquelin, Marie Weiel, Charlotte Debus, Achim Streit, and Markus Götz. Beyond backpropagation: Optimization alongside multi-tangent onward gradients. In International Joint Conference on Neural Networks, 2025. URL https://arxiv.org/pdf/2410.17764v2.) additionally use onward manner differentiation, combining multiple directional derivatives through orthogonal projection to enhance gradient estimates.
A distinct row of activity replaces the earth backward continue alongside local learning dynamics: Sakana AI’s PC-ALM (Seely and Gould, 2026Jeffrey Seely and Julian Gould. Augmented Lagrangian predictive coding. arXiv preprint arXiv:2605.31022, 2026. URL https://arxiv.org/abs/2605.31022.) propagates credit through local predictive coding dynamics and Lagrange multipliers. It uses local derivatives and is evaluated on depiction classification tasks. Dust estimates credit from onward perturbations during transformer pretraining, combining rewards for all token alongside local targets for notice outputs.
References
Nathan Allaire, Mahsa Ghazvini Nejad, Sébastien Le Digabel, and Vahid Partovi Nia. Zeroth command optimization for pretraining tongue models. In Proceedings of ICPRAM, pages 113–121, 2025. doi: 10.5220/0013261100003905. URL https://doi.org/10.5220/0013261100003905.
Nathan Allaire, Sébastien Le Digabel, Dominique Orban, and Vahid Partovi Nia. Zeroth-order Kronecker optimization for pretraining tongue models. SN Computer Science, 7, 2026. URL https://www.gerad.ca/en/papers/G-2025-44. Article 162.
Katharina Flügel, Daniel Coquelin, Marie Weiel, Charlotte Debus, Achim Streit, and Markus Götz. Beyond backpropagation: Optimization alongside multi-tangent onward gradients. In International Joint Conference on Neural Networks, 2025. URL https://arxiv.org/pdf/2410.17764v2.
Yulu Gan and Phillip Isola. Neural thickets: Diverse project experts are compact about pretrained weights. arXiv preprint arXiv:2603.12228, 2026. URL https://arxiv.org/abs/2603.12228.
Wes Gurnee, Nicholas Sofroniew, Adam Pearce, Mateusz Piotrowski, Isaac Kauvar, Runjin Chen, Anna Soligo, Paul Bogdan, Euan Ong, Rowan Wang, Ben Thompson, David Abrahams, Subhash Kantamneni, Emmanuel Ameisen, Joshua Batson, and Jack Lindsey. Verbalizable representations form a earth workspace in tongue models. arXiv preprint arXiv:2607.15495, 2026.
Xixi Hu, Bo Liu, Qiang Liu, Xiaocong Du, Bhargav Bhushanam, Louis Feng, Chengyue Gong, and Kaizhao Liang. Zoop it! Efficient zero-order optimization alongside output perturbation. In ICML Workshop on Tiny Titans: The next motion of On-Device Learning for Foundation Models, 2025. URL https://openreview.net/forum?id=Tc8vFyRhPO.
Yann Le Cun, Conrad C. Galland, and Geoffrey E. Hinton. GEMINI: Gradient evaluation through matrix inversion following noise injection. In Advances in Neural Information Processing Systems, quantity 1, pages 141–148, 1988. URL https://papers.neurips.cc/paper_files/paper/1988/file/a0a080f42e6f13b3a2df133f073095dd-Paper.pdf.
Timothy P. Lillicrap, Adam Santoro, Luke Marris, Colin J. Akerman, and Geoffrey Hinton. Backpropagation and the brain. Nature Reviews Neuroscience, 21 (6): 335–346, 2020. doi: 10.1038/s41583-020-0277-3.
Jack Lindsey, Wes Gurnee, Emmanuel Ameisen, Brian Chen, Adam Pearce, Nicholas L. Turner, Craig Citro, et al. On the existence discipline of a ample tongue model. Transformer Circuits Thread, 2025.
Shengchao Liu, Dimitris Papailiopoulos, and Dimitris Achlioptas. Bad earth minima be and SGD can attain them. In Advances in Neural Information Processing Systems, quantity 33, 2020.
Sadhika Malladi, Tianyu Gao, Eshaan Nichani, Alex Damian, Jason D. Lee, Danqi Chen, and Sanjeev Arora. Fine-tuning tongue models alongside fair onward passes. In Advances in Neural Information Processing Systems, quantity 36, 2023.
Yurii Nesterov and Vladimir Spokoiny. Random gradient-free minimization of convex functions. Foundations of Computational Mathematics, 17 (2): 527–566, 2017. doi: 10.1007/s10208-015-9296-2.
Xin Qiu, Yulu Gan, Conor F. Hayes, Qiyao Liang, Yinggan Xu, Roberto Dailey, Elliot Meyerson, Babak Hodjat, and Risto Miikkulainen. Evolution strategies at scale: LLM fine-tuning beyond reinforcement learning. In Proceedings of the International Conference on Machine Learning, 2026. URL https://arxiv.org/abs/2509.24372. arXiv:2509.24372.
Mengye Ren, Simon Kornblith, Renjie Liao, and Geoffrey Hinton. Scaling onward gradient alongside local losses. In International Conference on Learning Representations, 2023.
David E. Rumelhart, Geoffrey E. Hinton, and Ronald J. Williams. Learning representations by back-propagating errors. Nature, 323: 533–536, 1986.
Tim Salimans, Jonathan Ho, Xi Chen, Szymon Sidor, and Ilya Sutskever. Evolution strategies as a scalable substitute to reinforcement learning. arXiv preprint arXiv:1703.03864, 2017.
Bidipta Sarkar, Mattie Fellows, Juan Agustin Duque, Alistair Letcher, Antonio León Villares, Anya Sims, Clarisse Wibault, Dmitry Samsonov, Dylan Cope, Jarek Liesen, Kang Li, Lukas Seier, Theo Wolf, Uljad Berdica, Valentin Mohl, Alexander David Goldie, Aaron Courville, Karin Sevegnani, Shimon Whiteson, and Jakob Nicolaus Foerster. Evolution strategies at the hyperscale. arXiv preprint arXiv:2511.16652, 2025.
Jeffrey Seely and Julian Gould. Augmented Lagrangian predictive coding. arXiv preprint arXiv:2605.31022, 2026. URL https://arxiv.org/abs/2605.31022.
David Silver, Julian Schrittwieser, Karen Simonyan, Ioannis Antonoglou, Aja Huang, Arthur Guez, Thomas Hubert, Lucas Baker, Matthew Lai, Adrian Bolton, Yutian Chen, Timothy Lillicrap, Fan Hui, Laurent Sifre, George van den Driessche, Thore Graepel, and Demis Hassabis. Mastering the equivalent of Go without individual knowledge. Nature, 550 (7676): 354–359, 2017. doi: 10.1038/nature24270.
Richard S. Sutton. The bitter lesson. http://www.incompleteideas.net/IncIdeas/BitterLesson.html, 2019. Blog post.
Akshay Vegesna and Samip Dahal. Decoupling hunt and learning in neural net training. arXiv preprint arXiv:2509.10973, 2025.
Justin Werfel, Xiaohui Xie, and H. Sebastian Seung. Learning curves for stochastic gradient decline in linear feedforward networks. In Advances in Neural Information Processing Systems, quantity 16, 2003.
Bernard Widrow and Michael A. Lehr. 30 years of adaptive neural networks: Perceptron, Madaline, and backpropagation. Proceedings of the IEEE, 78 (9): 1415–1442, 1990. doi: 10.1109/5.58323.
A Architecture B Cosine Ladder at the Remaining Checkpoints C Test Losses by Token Budget and Population D EGGROLL’s Extrapolated Population E Population Allocation F Tuning G Cosine-fit parameters