TL;DR: The DuckDB squad is blessed to province that today we're releasing DuckDB type 2.0.0 LTS, codenamed “Cinnamon Teal” (Spatula cyanoptera). This is our biggest characteristic publish so far, and it ships a polished type of the Quack protocol, asynchronous I/O, a first-class VARIANT type, delegate mode, triggers, an extensible SQL parser and much more, built from near to 20,000 commits since DuckDB 1.5.
We are arrogant to publish DuckDB 2.0.0, codenamed “Cinnamon Teal” following the Spatula cyanoptera, a strikingly reddish-brown duck established in the occidental Americas.
While DuckDB 1.0 was all concerning stability and backward compatibility, DuckDB 2.0 is complete all a characteristic release. In this blog post, we summarize the highlights and afterward stroll through the breaking changes and how to migrate. We showcased many of the new features in “A Preview of DuckDB v2.0”, which covers all one in additional depth. For the complete publish notes, see the release leaf on GitHub.
Tip To instal the new version, delight sojourn the installation page. Some clients, specified as the CLI and Python, are already available. Other client libraries (e.g., Go, R, Java) and several extensions can obtain a few days to publish because of the additional changes and assessment rounds required.
With this release, there are currently three DuckDB lines available. DuckDB 2.0 is a long-term assistance (LTS) publish alongside assistance until at smallest October 2027. The former LTS release, type 1.4, is motionless supported until delayed November 2026. To justify a gentle passage and authorize adequate period for testing, we extended the assistance duration of DuckDB 1.5 until March 2027, efficiently additionally turning it into an LTS release. For details, see the release calendar.
To discover your way about the records for all of the new features, we additionally published a “What's New in the Docs for 2.0” leaf that links all characteristic below to its documentation.
DuckDB as a Server
DuckDB has been an in-process repository since day one. In DuckDB 1.5.3, released in May, we introduced the Quack protocol that lets you run DuckDB in a traditional client-server setup, alongside alongside the quack extension, which implements DuckDB's native protocol, so any DuckDB procedure can serve its databases.
Quack and CONNECT
DuckDB 2.0.0 ships a polished type of the Quack protocol alongside significant achievement and stability improvements. It additionally introduces the new CONNECT statement that allows attaching and switching to a distant repository in a sole command for improved ergonomics:
DuckDB server
CALL quack_serve( token = 'my_token' ); CREATE TABLE events (date DATE, name VARCHAR); INSERT INTO events VALUES ('2027-04-07', 'DuckCon #8');
quack:
DuckDB client
ATTACH 'quack:localhost' AS qk (TOKEN 'my_token'); CONNECT qk; SELECT * FROM events; ┌────────────┬────────────┐ │ date │ name │ │ date │ varchar │ ├────────────┼────────────┤ │ 2027-04-07 │ DuckCon #8 │ └────────────┴────────────┘
For simplicity, this example runs the server and the client on the identical machine. By default, the server lone listens on localhost. To obtain connections from another machines, keep the server on localhost and put it rearward a TLS-terminating reverse proxy. The allow_other_hostname option, which exposes the server directly, is lone meant for testing.
The CONNECT declaration is not constricted to Quack: it points your meeting at any distant repository that supports it, including PostgreSQL and MySQL. For these, the new distant pushdown optimizer ships queries immediately to the distant server alternatively of pulling tables complete the wire.
Quack in the CLI
The CLI additionally has shortcuts for environment up a Quack client-server pair: the new -serve and -connect arguments commencement a Quack server or nexus to one immediately from the command line:
quack:
CLI client
FROM t; ┌───────┐ │ x │ │ int32 │ ├───────┤ │ 42 │ └───────┘
Performance
Asynchronous I/O
DuckDB 2.0 introduces asynchronous I/O for study Parquet and CSV files. The I/O tier now scales independently from the query handling layer, issuing says in the backdrop and keeping multiple requests in flight. This method far additional parallelism for distant says and dramatically faster queries on entity retention specified as s3://.
We described the scheme in item in a dedicated blog post. In that post, we showed the network throughput complete the way of a query alongside and without asynchronous I/O:
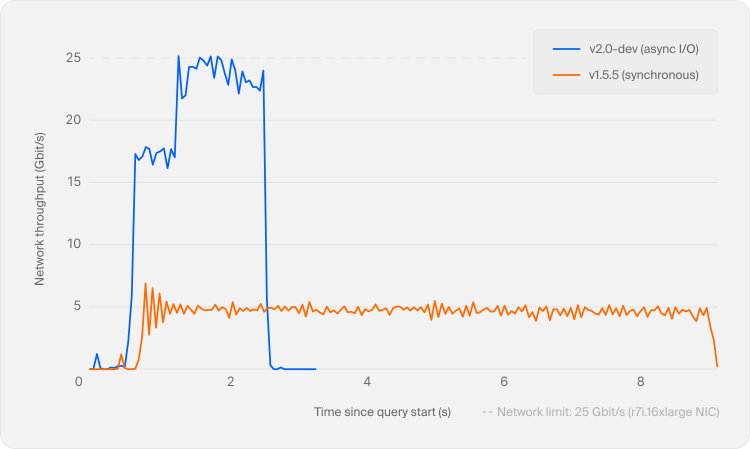
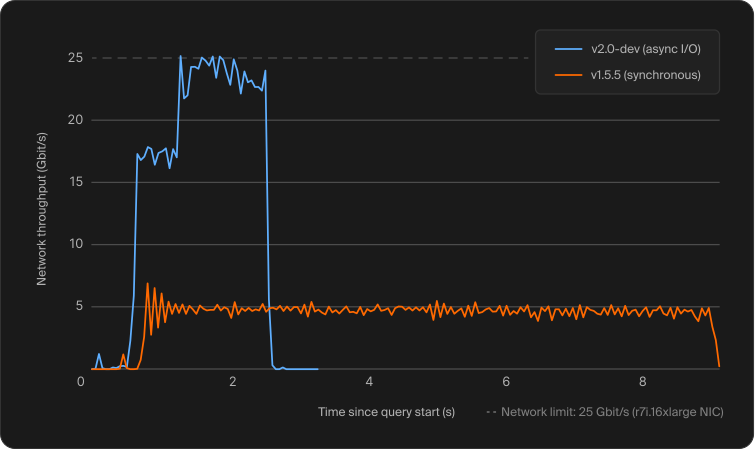 Network throughput. Higher use and shorter runtime are better.
The VARIANT Type Becomes a First-Class Citizen
The VARIANT type stores semi-structured, schema-less data specified as JSON during keeping the achievement of columnar execution. So you can think of it as JSON on steroids: a VARIANT pillar can shop alternatively shaped data in all row, but dissimilar JSON it is not a content format.
DuckDB 1.5 already introduced VARIANT, but DuckDB 2.0 completely integrates it. DuckDB 2.0 detects the average construction in your data and “shreds” it, so it compresses fine and executes fast. The pipeline plant end to end, from shredded implementation direct out of retention to shredded VARIANT study and penning for Parquet, backed by a family of variant_* functions. For example:
CREATE TABLE events (payload VARIANT); INSERT INTO events VALUES ('{"user": {"id": 42, "tags": ["a", "b"]}}'::JSON::VARIANT), ('{"event": "click", "x": 10, "y": 20}'::JSON::VARIANT); SELECT variant_type(payload), variant_keys(payload) FROM events;
┌───────────────────────┬───────────────────────┐ │ variant_type(payload) │ variant_keys(payload) │ │ varchar │ varchar[] │ ├───────────────────────┼───────────────────────┤ │ OBJECT │ [user] │ │ OBJECT │ [event, x, y] │ └───────────────────────┴───────────────────────┘
Agent Mode in the CLI
Coding agents specified as Claude Code, Codex and Cursor increasingly run the DuckDB CLI on their users' behalf. The 2.0 CLI detects whenever it is being run by an delegate and switches to agent mode: it prints compact Markdown tables alternatively of padded boxes, says plainly whenever a outcome was truncated, stops runaway queries first and reports errors as JSON.
Long-running SQL queries study their expected disbursal previous to running, so the delegate can decide whether to wait. In our experiments on TPC-H, delegate manner cut the amount of DuckDB output the example had to peruse by 59%. You can rotate it on for manual evaluation using the -agent flag or instruct your delegate to rotate it off using the -no-agent flag.
Extensibility
A Brand New SQL Parser
DuckDB has continually used a parser derived from PostgreSQL's. In 2.0, our own modern, extensible PEG-based parser, which debuted as an opt-in characteristic in DuckDB 1.5, becomes the default. Extensions can now hook into the grammar itself (an idea we archetypal explored in our research on runtime-extensible parsers), so anticipate extensions that disclose entirely new SQL syntax. Error messages now arrive alongside exact origin locations. For details, see the PEG parser documentation. The new parser is designed to be compatible alongside the old one, so you should not notice the swap. If you do, delight document an issue. In the meantime, you can toggle rear to the old parser using the legacy_parser extension by operating SET enable_legacy_parser = true;.
The old parser had served DuckDB since its archetypal commit in 2018. Its grammar was generated alongside YACC/Bison, which produces an LALR(1) parser, so as DuckSQL grew, equal small additions could collide alongside existing rules and lift shift/reduce or reduce/reduce conflicts. A PEG grammar avoids this by trying alternatives in the command they are written, so adding syntax no longer risks breaking unrelated rules. Python itself moved to a PEG-based parser in version 3.9 for the identical flexibility.
Write Extensions Once and Host Them Yourself
DuckDB 2.0 ships a revamped C API v2, which is considerably additional mighty than its predecessor and exposes components specified as document systems and array functions to extensions. Before marking it as stable, we would akin to test it in the field, so delight provision it a try and send us your feedback!
You can additionally enroll and presenter your own trusted expansion repositories, so an institution can presenter and sign its own extensions and have them instal and burden fair akin the built-in ones:
SET allow_extension_repositories = 'allowed'; CREATE EXTENSION REPOSITORY my_repo WITH PREFIX 'https://extensions.example.org'; INSTALL AND LOAD my_ext FROM my_repo;
A repository is a name, a URL prefix and one or additional RSA community keys that are trusted to sign the extensions served from it. The prefix can item at item DuckDB can read: a local path, https, s3, you name it. At CREATE time, DuckDB fetches the repository's community keys and pins them into the repository definition, printing all key's SHA-256 fingerprint so you can difference it against one published out of band.
This characteristic is motionless a activity ongoing and its syntax may alter in forthcoming releases. For additional details, see the Extension Repositories page.
Core Extension Updates
DuckDB's core extensions are additionally shipping multiple new features, fixes and achievement optimizations. These are too many to all catalog here, so we lone emphasize a few of them and volition shield them in dedicated blog posts in the coming weeks:
- We released DuckLake 1.1, including a new specification and reference implementation.
- The Iceberg extension strives to rotate into a feature-complete implementation. To this end, it adds REST catalog ATTACH options that get a table's location from its namespace or burden array metadata from the metadata-location document returned by the catalog. Further options authority the URL prefix and the namespace separator.
- The Delta extension can create Delta tables alongside CREATE TABLE (including partitioning and Delta array properties), supports period journey and improves VARIANT support.
SQL Features
Triggers
DuckDB 2.0 delivers triggers: the CREATE TRIGGER statement alongside BEFORE and AFTER triggers, FOR EACH ROW and FOR EACH STATEMENT, passage tables via REFERENCING OLD/NEW TABLE, multiple triggers per event, RETURNING on triggered tables and DROP TRIGGER. The traditional use case is audit tables, anywhere a trigger records what changed in reply to a array modification. Some combinations, specified as BEFORE ... FOR EACH ROW and UPDATE ... FOR EACH ROW triggers, are not yet supported; see the limitations.
CREATE TRIGGER trg_audit AFTER UPDATE ON target REFERENCING OLD TABLE AS o NEW TABLE AS n FOR EACH STATEMENT INSERT INTO audit SELECT n.id, o.val, n.val FROM o JOIN n ON o.id = n.id;
Triggers can additionally keep materialized views incrementally! For example, to keep track of the average age of group per nationality in a array age_statistics, you can use two triggers – one for insert and another for delete operations – and shop the sum and the figure alongside the average.
To see additional details, click here.CREATE TABLE people (name VARCHAR, nationality VARCHAR, age INTEGER); CREATE TABLE age_statistics ( nationality VARCHAR PRIMARY KEY, sum_age INTEGER, num_people INTEGER, average_age DOUBLE );
On insertion, we total the new rows per nationality and merge them into age_statistics, adding a row for all new nationality:
CREATE TRIGGER people_insert AFTER INSERT ON people REFERENCING NEW TABLE AS n FOR EACH STATEMENT MERGE INTO age_statistics s USING ( SELECT nationality, sum(age) AS sum_age, count(*) AS num_people FROM n GROUP BY nationality ) d ON s.nationality = d.nationality WHEN MATCHED THEN UPDATE SET sum_age = s.sum_age + d.sum_age, num_people = s.num_people + d.num_people, average_age = (s.sum_age + d.sum_age) / (s.num_people + d.num_people) WHEN NOT MATCHED THEN INSERT VALUES (d.nationality, d.sum_age, d.num_people, d.sum_age / d.num_people);
On deletion, we subtract the deleted rows and autumn a nationality formerly its final individual has left:
CREATE TRIGGER people_delete AFTER DELETE ON people REFERENCING OLD TABLE AS o FOR EACH STATEMENT MERGE INTO age_statistics s USING ( SELECT nationality, sum(age) AS sum_age, count(*) AS num_people FROM o GROUP BY nationality ) d ON s.nationality = d.nationality WHEN MATCHED AND s.num_people = d.num_people THEN DELETE WHEN MATCHED THEN UPDATE SET sum_age = s.sum_age - d.sum_age, num_people = s.num_people - d.num_people, average_age = (s.sum_age - d.sum_age) / (s.num_people - d.num_people);
Let's see group arrive and go:
INSERT INTO people VALUES ('Alice', 'US', 34), ('Bram', 'NL', 27), ('Csilla', 'HU', 45), ('Dave', 'US', 58), ('Eva', 'NL', 19), ('Femke', 'NL', 41); FROM age_statistics ORDER BY nationality;
┌─────────────┬─────────┬────────────┬─────────────┐ │ nationality │ sum_age │ num_people │ average_age │ │ varchar │ int32 │ int32 │ twice │ ├─────────────┼─────────┼────────────┼─────────────┤ │ HU │ 45 │ 1 │ 45.0 │ │ NL │ 87 │ 3 │ 29.0 │ │ US │ 92 │ 2 │ 46.0 │ └─────────────┴─────────┴────────────┴─────────────┘
DELETE FROM people WHERE name = 'Alice'; DELETE FROM people WHERE nationality = 'HU'; FROM age_statistics ORDER BY nationality;
┌─────────────┬─────────┬────────────┬─────────────┐ │ nationality │ sum_age │ num_people │ average_age │ │ varchar │ int32 │ int32 │ twice │ ├─────────────┼─────────┼────────────┼─────────────┤ │ NL │ 87 │ 3 │ 29.0 │ │ US │ 58 │ 1 │ 58.0 │ └─────────────┴─────────┴────────────┴─────────────┘
Triggers bring us one stage nearer to materialized views, a long-standing item in the “future work” division of our roadmap.
SQL Dialect Additions
As always, DuckDB's friendly SQL dialect keeps growing. A few favorites from this publish cycle:
- The $variable shorthand lets you compose $x in most places anywhere an expression is allowed, alternatively of getvariable('x').
- Data-modifying CTEs let you use INSERT, UPDATE, DELETE and COPY as pipeline steps.
- NEAREST joins rotate top-k similarity hunt into a associate clause, helpful for vector and embedding workloads.
- Nested schemas authorize schemas inside schemas, e.g., CREATE SCHEMA finance.reports.
- JSON mutation functions json_set, json_insert, json_replace and json_remove come back modified copies of JSON documents (see additionally our blog article on JSON patches).
There is more: DuckDB 2.0.0 supports the SQL-standard FETCH FIRST and allows UNNEST in the GROUP BY clause. It additionally ensures well-defined MERGE and UPDATE ... FROM semantics for cases whenever multiple rows are matched.
Migrating to 2.0
DuckDB 2.0 comes alongside a small set of breaking changes. For most users, upgrading is straightforward, but complex deployments operating many DuckDB processes need additional care. The retention format is the most apt origin of problems: DuckDB versions before 2.0 cannot peruse repository records created by DuckDB 2.0. DuckDB 2.0 can motionless peruse and compose your existing repository files, and these remain readable by older versions. We propose evaluation 2.0.0 on a shade scheme before switching manufacturing over. And, if your workload is mission-critical, you may desire to delay for the archetypal place release, coming in November.
For the complete details, see the migration guide.
Internals and Deprecations
Compiler Requirements
Following DuckDB's lengthy stint on C++11, DuckDB 2.0 now requires a C++17 compiler.
We additionally switched to Clang as the default compiler for our publish builds. On Linux and macOS, the two DuckDB and its center extensions are built alongside Clang. On Windows, the CLI is built alongside Clang, during most center extensions are motionless built alongside MSVC. We may move additional Windows builds to Clang in the future, but this requires additional changes.
Timezones, Calendars and Collations Without ICU
Timezone-aware timestamps, calendars and collations have continually been powered by the ICU library. In 2.0, the ICU archive is gone entirely: the icu extension now implements timezones, calendars and collations itself, alongside the timezone data built immediately from the IANA repository and compressed downward to about 45 kB.
Everything keeps operating exactly as before, and the native implementation is additionally faster. If you discover any issues, delight let us know!
Deprecations
Lambda Syntax
The old single-arrow lambda syntax (x -> x + 1) is now impaired by default. Use the Python-style syntax instead:
SELECT list_transform([1, 2, 3], lambda x: x + 1);
You can temporarily re-enable the old syntax alongside SET lambda_syntax = 'enable_single_arrow';. Both the emblem and the single-arrow syntax volition be removed entirely in v2.1.
Amalgamation Builds
The amalgamation build, which bundles DuckDB's complete origin code into a sole header and a sole origin file, is now deprecated. The amalgamation has grown too ample to be realistically helpful in most cases.
Gradual Phase-Out of macOS x86_64
We are gradually phasing out osx_amd64 from the catalog of completely supported platforms. For the period being, DuckDB and core extensions are motionless built and supported, but community extensions are no longer built for this platform. DuckDB 2.1 volition halt supporting osx_amd64.
Summary
These were a few highlights, but there are many additional features and improvements in this release. There have been nearly 20,000 commits by many contributors since DuckDB 1.5, shipping smaller features as fine as achievement and usability improvements. The complete release notes can be established on GitHub.
We would akin to appreciate our community for the detailed matter reports and feedback that have driven this release, and our particular gratitude go to our contributors!