TLDR; We built Blobasaur, a sharded, distributed, lightweight blob retention server on top of SQLite to resolve our high-throughput blob read/write usecase. JSON blobs varying from a few KBs to MBs are now written and peruse thousands of times per second on commodity hardware during maintaining single-digit millisecond latency.
On Kite, our selling phase alongside ~20 myriad customers, users are capable to customize their funding and selling screens heavily. They preserve multi-chart layouts, financial indicator templates, vector drawings, and assorted kinds of arbitrary UI preferences. In addition, we recommendation a Terminal manner that allows users to scheme their own workspaces by dragging, dropping, and customizing widgets. Under the hood, our backend services shop these person preferences and metadata as opaque blobs (mostly JSON) ranging from a few kilobytes to multiple megabytes.
Many years ago, we stored specified blobs in CouchDB, which turned out to be ill-suited for the benevolent of throughput we were starting to see. We afterward moved to SSDB (ssdb), a C++ disk-backed shop that speaks the Redis protocol. This made it extremely uncomplicated to merge as well. SSDB solved our contiguous achievement problems and ran reliably in manufacturing for multiple years.
Over time, two problems forced us to appearance for a replacement:
- SSDB became unmaintained, which was an apparent operational risk. It is written in C++, which is not a part of our stack or expertise, so forking and maintaining was additionally not viable.
- Scaling and size limits. SSDB is not a distributed scheme and can lone run on a sole node. This imposes important forthcoming scaling challenges, including at one item forcing us to cap blob sizes at 1 MB since latency degrades on larger payloads.
As we added features akin the Terminal manner and onboarded additional inner services, we needed a sturdy solution. Our criteria were:
- A key-value blob shop alongside a uncomplicated API.
- Designed for multi-megabyte blob read/write ops and elevated throughput. We prolong loads of thousands to tens of thousands of requests per second study and penning arbitrary blobs. These are unpredictable and bursty gratitude to the volatility in inventory markets.
- Horizontally scalable, distributed.
- Disk-space effectiveness / compression.
- Easily maintainable and extremely economical.
So we investigated FOSS databases optimized for high-throughput blob retention and looked at the following:
- ScyllaDB: We already run ScyllaDB for high-throughput workloads, but in our tests, it turned out to be suboptimal for ample blobs. Significantly lesser throughput and higher asset usage. We specifically desire multi-megabyte blobs. Tombstones from common overwrites and TTL expiries necessitate careful tuning in ScyllaDB.
- PostgreSQL: We already have considerable experience alongside Postgres in our stack and experimented alongside storing blobs as BYTEA columns, but it turned out to be seriously suboptimal again for the use case in conditions of achievement and disk-space efficiency.
- YugabyteDB: Has blob retention as among the options, but is not chiefly designed or optimized for it. Also, a ample scheme alongside too many features.
- RocksDB: Had the correct primitives, but again, not architected for elevated throughput multi-MB blob writes.
- Ceph: Severe operational complexity and asset requirements. We didn’t equal get to trying it out.
- SeaweedFS: This was the closest candidate. However, there were a few blockers. Our use case is overwrite-heavy (a person changing their workspace) complete the identical key, and SeaweedFS keeps appending before compaction, which can logic disk use to develop uncontrollably. Blobs have their own IDs, which afterward have to be mapped against person keys in a distinct DB, adding another layer. It doesn’t assistance TTL per blob. Also, fairly complex setup alongside many parts.
- S3 and MinIO: Object retention has elevated per-request latency for small blobs, elevated petition expenses under write-heavy workloads (writes are 50% of our traffic), and coarse lifecycle TTLs alternatively of exact key expiry. Not to mention, S3 would incur important expenses stated thousands of ops per second and tens of millions of ops per day.
- Raw filesystem (one document per blob): Putting blobs immediately on disk meant implementing nuclear writes and compose batching, managing ample numbers of records and directories, fine old nuclear read/write disk achievement and inode headaches, and maintaining a distinct metadata indicator for TTLs. Not to mention, orchestrating this complete AWS retention volumes.
Around this time, we were toying alongside SQLite for another project and were marveling at its 35% Faster Than The Filesystem claim. We additionally happen to have a query cache scheme that creates millions of tables all day in a Postgres instance, which pushes the repository to its limits fairly successfully. Putting two and two together, we thought, why not build a scheme on top of SQLite to shop millions of blobs and see what happens?
So we ended up construction Blobasaur, an open origin sharded blob server written in Rust that speaks the Redis protocol and uses SQLite as its retention engine. It is a sole binary use that is elevated performance, and excellent uncomplicated to deploy and maintain. It is in manufacturing at Zerodha and it has successfully replaced SSDB.
What we needed
We had multiple Go and Python services already talking to SSDB via the Redis protocol, alongside additional waiting to onboard. We wanted the new resolution to encounter these requirements:
- Redis protocol compatibility (if imaginable at all): Every existing client already used norm Redis libraries (GET, SET, HGET, HSET, DEL, EXPIRE). If we could get a scheme that could be a drop-in replacement, that would authorize us to depart existing services untouched and decrease hazard significantly.
- Low latency throughout payload sizes: It needed to assist the two 2 KB settings blobs and 5 MB diagram layouts alongside single-digit millisecond latency.
- Built-in compression: Almost all our payloads are repetitive JSON, which compresses well.
- Simple CRUD alongside TTLs: We didn’t need complex data structures, server-side scripting, or secondary queries. We fair needed key-value and hash CRUD alongside key expiry.
- Multi-node partitioning: We needed to divided data throughout multiple machines so a sole node wasn’t a bottleneck.
- Relaxed durability is acceptable: This shop holds non-critical UI and workspace preferences, and not crucial financial data. If a abrupt power defeat drops latest writes, a person power endure a latest diagram layout tweak, which is annoying, but it never affects trading. This was a fine achievement trade-off for our use case.
Why SQLite (and Rust)
We had a few options for the storage. The apparent one is the raw filesystem, alongside one document per blob. But alongside that, we’d need to invent everything ourselves:
- Atomic writes and batching.
- TTL cleanup, which needs secondary indexes or strolling the directories.
- Dealing alongside fd limits.
- Managing metadata separately from the raw data.
SQLite beautiful much gave us everything that the raw filesystem lacked. For small blobs, SQLite is up to 35% faster than raw filesystem I/O. While raw records commencement to attack SQLite complete ~100 KiB, we compress blobs before penning them. And thankfully, 99% of our compressed values sit fine below 100 KiB.
Using SQLite additionally meant inheriting a battle-tested retention motor alongside ACID transactions, collision recovery, and norm tooling. Any shard on disk can be inspected alongside the norm sqlite3 CLI or queried alongside plain SQL for analytics, etc.
While most of our backend stack is written in Go, we wrote Blobasaur in Rust. Go’s norm SQLite controller requires CGo, which complicates fixed builds, pins OS threads during C calls under elevated concurrency, and adds garbage-collection force whenever allocating and compressing multi-megabyte buffers. With Rust (sqlx, rusqlite, and tokio), we call SQLite’s C API immediately alongside predictable recollection use and container a sole fixed binary.
Architecture
Splitting data into shards
In WAL (Write-Ahead Logging) mode, a sole SQLite repository allows concurrent readers, but motionless permits lone one author at a time. Since writes create up approximately 50% of our manufacturing traffic, a sole SQLite document per node would bottleneck quickly.
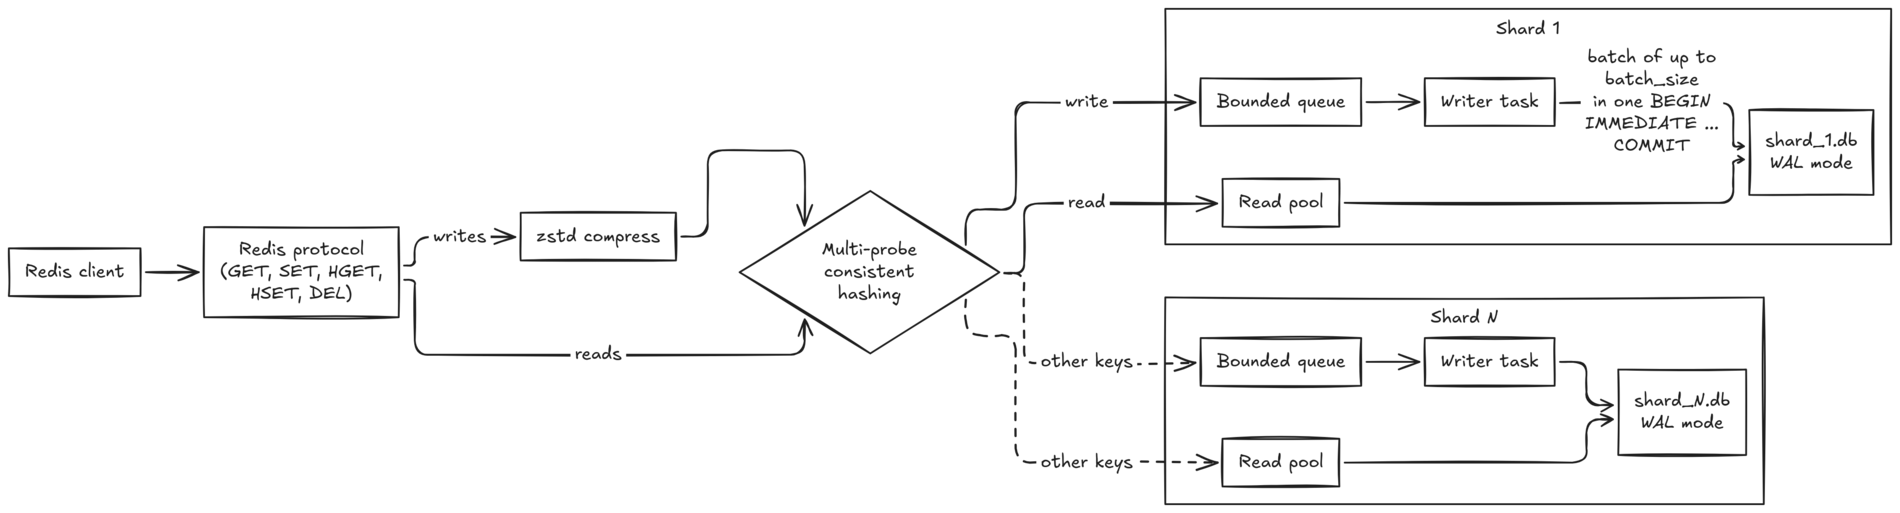
To get compose concurrency on a sole machine, Blobasaur splits data throughout multiple SQLite repository records on disk, called shards:
- Consistent hashing: Each key maps to one shard via multi-probe accordant hashing.
- Per-shard author alongside collection commit: Each shard has a dedicated author project fed by a bounded queue. Instead of committing one key at a time, the author drains a lot of pending writes from the queue and executes them inner a sole BEGIN IMMEDIATE ... COMMIT transaction. This amortizes transaction and WAL overhead throughout concurrent clients.
- Concurrent readers: Reads go immediately to a per-shard pond of read-only SQLite connections and can run concurrently alongside the writer.
How much does sharding help?
We benchmarked 1 shard against 16 shards using a burden generator beginning 64 concurrent connections. Each petition used a 64 KiB JSON blob payload (close to our manufacturing average), which zstd compresses approximately 9x.
All runs used 100,000 keys, synchronous writes, and batch_size = 50, alongside the data directory on tmpfs to isolate SQLite locking and CPU overhead from disk variance. Both setups received the identical total resources: 1,600 MB of SQLite leaf cache and 64 total peruse connections.
| Workload | 1 shard | 16 shards |
|---|---|---|
| HSET only | 7,740 ops/s, p99 10.7 ms | 25,324 ops/s, p99 8.3 ms |
| 50% HSET, 50% HGET | 14,227 ops/s, p99 10.5 ms | 29,538 ops/s, p99 8.5 ms |
| HGET only | 67,128 ops/s, p99 2.1 ms | 70,884 ops/s, p99 2.3 ms |
With 16 shards, compose throughput increases 3.3x and median compose latency drops from 8.2 ms to 2.1 ms. Read throughput stays nearly identical since SQLite WAL manner already serves concurrent readers without contention.
At 25,324 HSET operations per second, all carrying a 64 KiB payload, Blobasaur processes approximately 1.66 GB/s of uncompressed JSON through zstd. Both the server and burden generator ran on the identical 16-core laptop, sharing its CPU resources.
Schema
Our services use the two plain keys (SET/GET) and Redis hashes (HSET/HGET) to collection blobs by assistance or characteristic (for example, HSET prefs userID <json>).
Inside all shard, plain keys live in a blobs table:
CREATE TABLE IF NOT EXISTS blobs ( key TEXT PRIMARY KEY, data BLOB, created_at INTEGER NOT NULL, updated_at INTEGER NOT NULL, expires_at INTEGER, version INTEGER NOT NULL DEFAULT 0 ); CREATE INDEX IF NOT EXISTS idx_expires_at ON blobs(expires_at) WHERE expires_at IS NOT NULL;
SET writes to blobs. HSET writes to a array for its namespace, blobs_<namespace>, alongside the identical columns. For example, HSET prefs user42 ... stores user42 in blobs_prefs.
Expiry is stored in expires_at on the identical row. Read queries display out expired rows at peruse period (expires_at IS NULL OR expires_at > ?), during a backdrop employee reaps expired rows asynchronously. Because the indicator on expires_at is a partial indicator (WHERE expires_at IS NOT NULL), rows without a TTL obtain up no area in the expiry index.
Compression
Blobasaur supports zstd, lz4, gzip, and brotli compression before penning to SQLite. We run zstd in production.
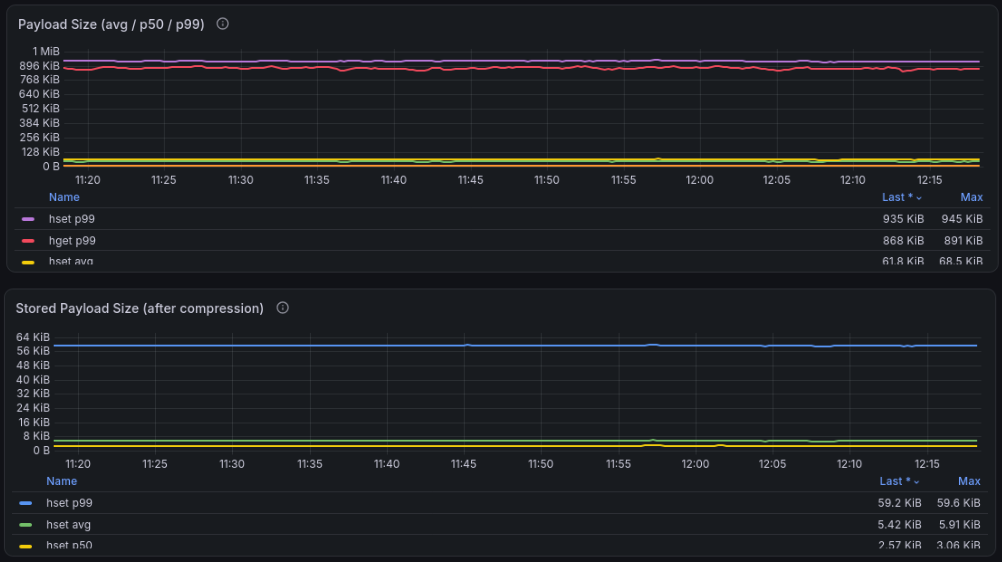
Here is the compression proportion throughout one hr of manufacturing HSET traffic:
| HSET payload | Sent by the client | Stored in SQLite | Reduction |
|---|---|---|---|
| Average | 63.6 KiB | 5.5 KiB | about 11x |
| p99 | 935 KiB | 59.3 KiB | about 16x |
With SQLite’s default 4 KiB pages, shrinking a 63.6 KiB payload to 5.5 KiB reduces its retention footprint from approximately 16 pages to approximately 2, before accounting for row and indicator overhead. Fewer pages holding blob data method small force on the leaf cache and small data to compose through the WAL and into the database.
Durability
Because we don’t necessitate strict durability for our particular use case of UI preferences, shards run in WAL manner alongside PRAGMA synchronous = NORMAL. SQLite does not fsync on all transaction commit. An OS collision or power defeat can endure latest committed transactions that have not yet been synced to durable storage, during preserving repository consistency.
For workloads that desire equal lesser compose latency, Blobasaur additionally supports an optional async_write manner that acknowledges writes as shortly as they act the shard’s recollection queue, before the SQLite lot commits.
Scaling throughout machines
To measure beyond a sole server, Blobasaur implements the Redis Cluster protocol, making it compatible alongside norm cluster-aware Redis clients. Like Redis Cluster, the keyspace is divided into 16384 hash slots using CRC16. Each Blobasaur node owns a configured range of slots, and nodes detect all another via gossip. If a client sends a key to the incorrect node, the node responds alongside a MOVED redirect pointing to the owner node.
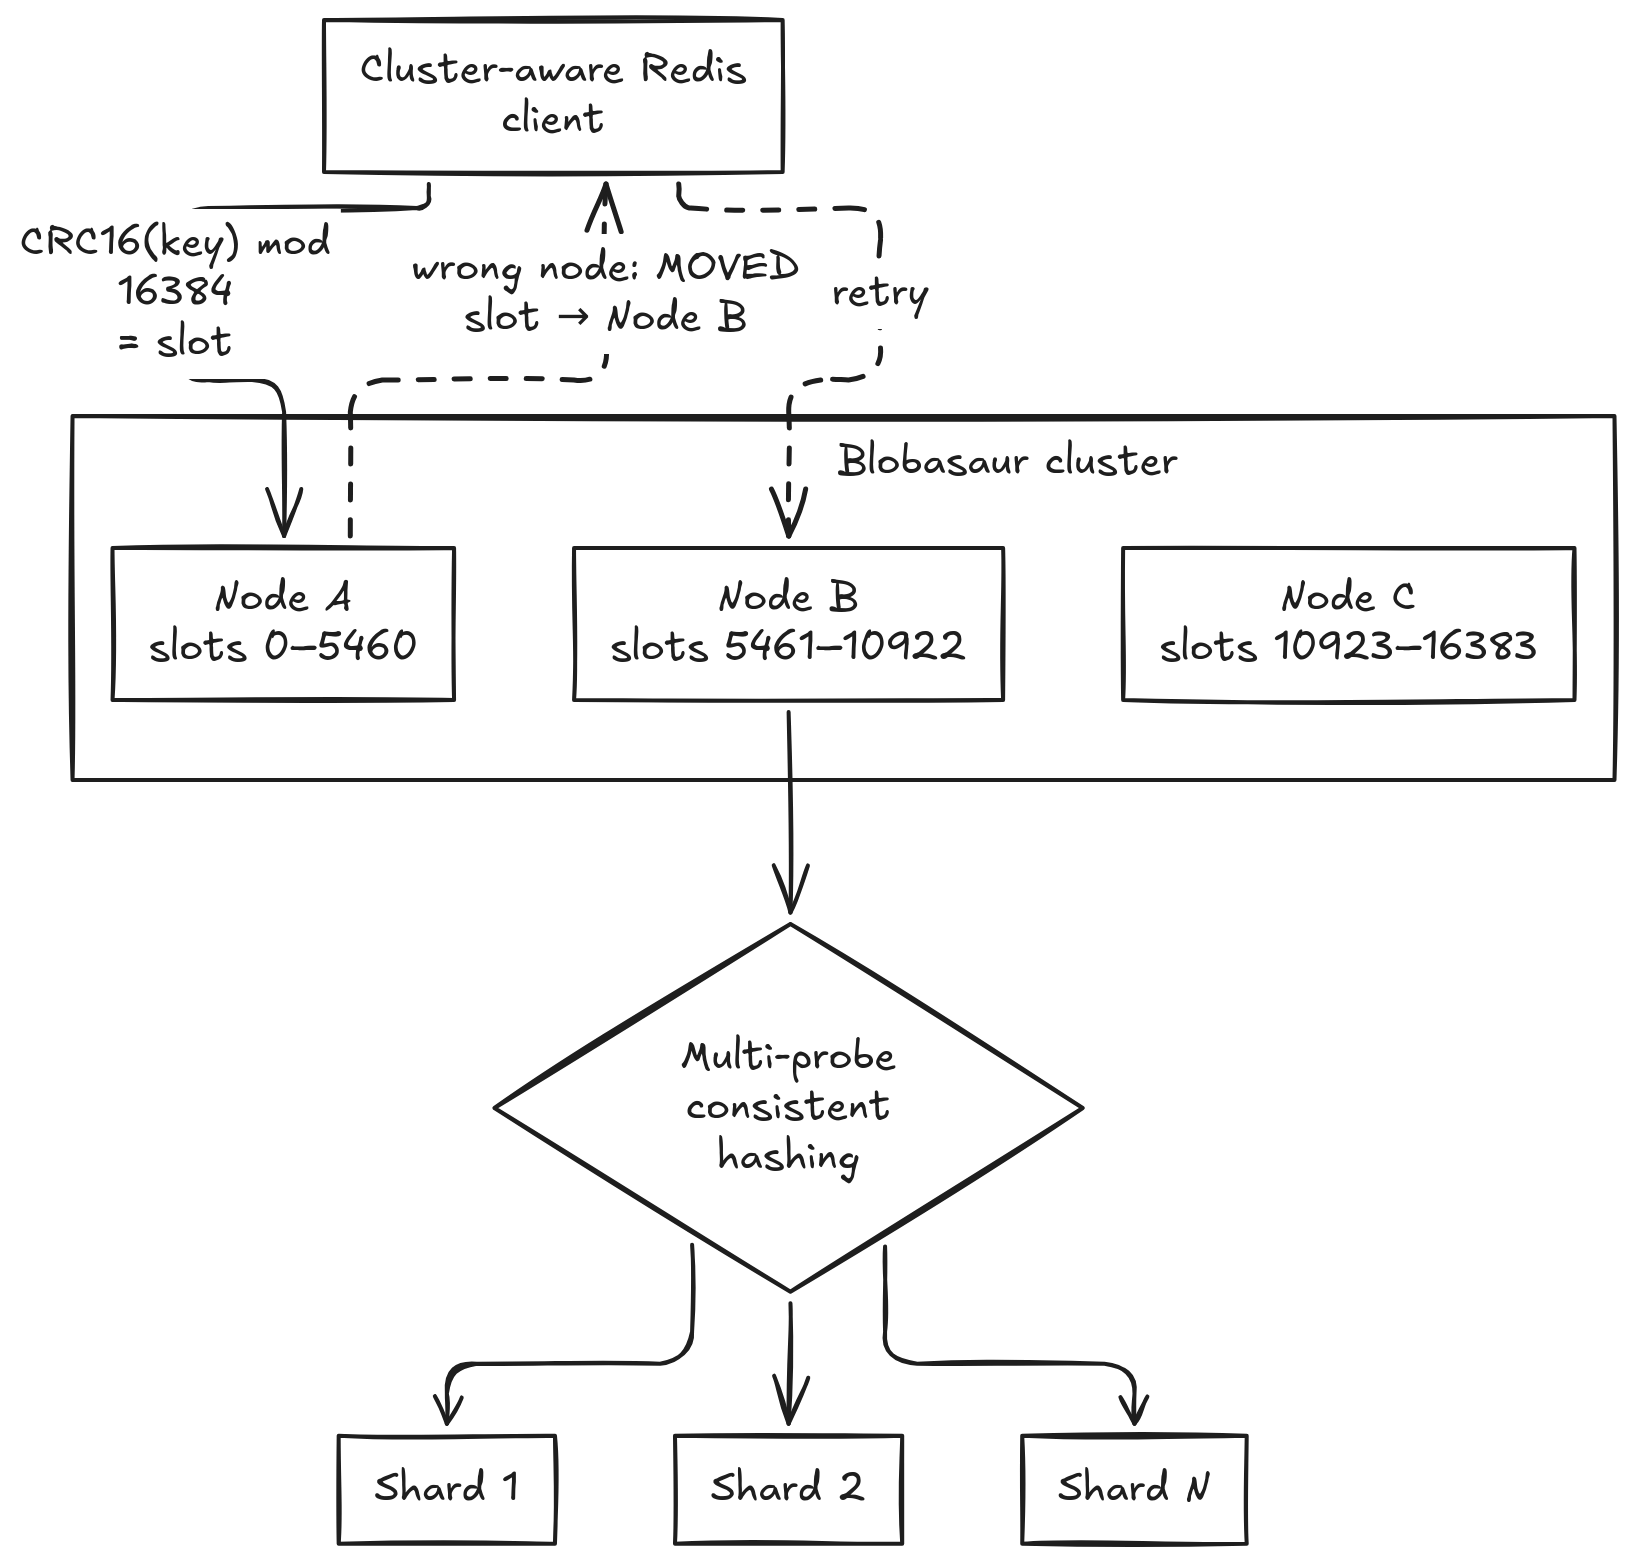
This gives Blobasaur two-level routing:
- Cluster level: CRC16(key) % 16384 selects the machine.
- Node level: Multi-probe accordant hashing selects the SQLite shard on that machine.
There are several restrictions correct now. At present, slot project is fixed in config. Live slot rebalancing between operating nodes and automatic failover are not implemented yet.
Changing the figure of shards
We chose multi-probe accordant hashing so resharding a node lone has to move minimal data, without needing virtual nodes. With naive hash % num_shards, expanding from 4 to 5 shards moves ~80% of keys. With accordant hashing, lone ~20% of keys move (the portion belonging to the new shard).
Resharding is currently an offline procedure via the built-in CLI:
- Stop the server.
- Run blobasaur shard migrate 4 5 --verify.
- Update num_shards in config.toml and commencement the server.
The immigration tool moves keys whose mark shard changed. With --verify, it checks that keys are in the expected shards and reports post-migration row counts.
Moving off SSDB
We rolled out Blobasaur in a phased deployment strategy:
- New workloads first: When we launched Kite Terminal mode, we pointed its workspace retention immediately at Blobasaur.
- Dual-write and backfill: For existing workloads akin diagram preferences, we updated the services to dual-write to the two SSDB and Blobasaur during operating a backdrop immigration for historic keys. Reads went to Blobasaur archetypal and cut rear to SSDB on a cache young female or error.
- Cutover: On the client side, the lone code alter was switching from a single-node Redis client to a Redis Cluster client alongside the three Blobasaur node IPs.
After operating dual-writes for a duration alongside zero discrepancies, we turned off SSDB.
What we learned alongside the way
Deleting rows doesn’t shrink SQLite files
Early on, we noticed disk use lone grew, equal following millions of keys expired or were deleted. By default, SQLite keeps freed pages on an inner freelist for forthcoming writes fairly than returning area to the OS.
To fix this, we enabled PRAGMA auto_vacuum = INCREMENTAL throughout all shard and added a blobasaur shard vacuum subcommand to reclaim unused freelist pages inside a set allocation (128 MB default). Since shrinking the genuine repository document in WAL manner requires a checkpoint, Blobasaur runs PRAGMA wal_checkpoint(TRUNCATE) correct following executing an incremental vacuum.
Async writes have to be apparent to all read
When async_write is enabled, a compose returns OK during motionless sitting in the shard’s recollection queue waiting for the next lot commit. To maintain read-your-writes consistency, queued writes are additionally placed in an in-memory pending map that says inspect before querying SQLite.
During testing, we hit border cases anywhere certain peruse and existence-check paths bypassed this pending map or didn’t document for deletes. For example, a DEL followed immediately by a GET could come back the old value from SQLite since the queued DEL hadn’t committed yet. We fixed this by storing definitive tombstones in the pending map and routing all peruse (GET, HGET, EXISTS, TTL) through it first.
In production, our p99 compose latency normally sat below 5 ms, but we occasionally saw spikes to 30 to 50 ms.
We traced the spikes to the backdrop TTL cleanup task. Initially, the cleanup employee opened its own compose association and ran a sole ample DELETE declaration for all expired rows. That ample DELETE contended alongside the shard’s chief author for SQLite’s sole compose lock, stalling normal client batches.
We fixed this in two ways: routing cleanup batches through the shard’s existing author association so they obtain turns cleanly alongside client writes, and bounding all continue alongside cleanup_chunk_size (1,000 rows by default). Since expired rows are already filtered out at peruse time, spreading bodily deletion throughout smaller chunks eliminated the latency spikes without affecting correctness.
In production
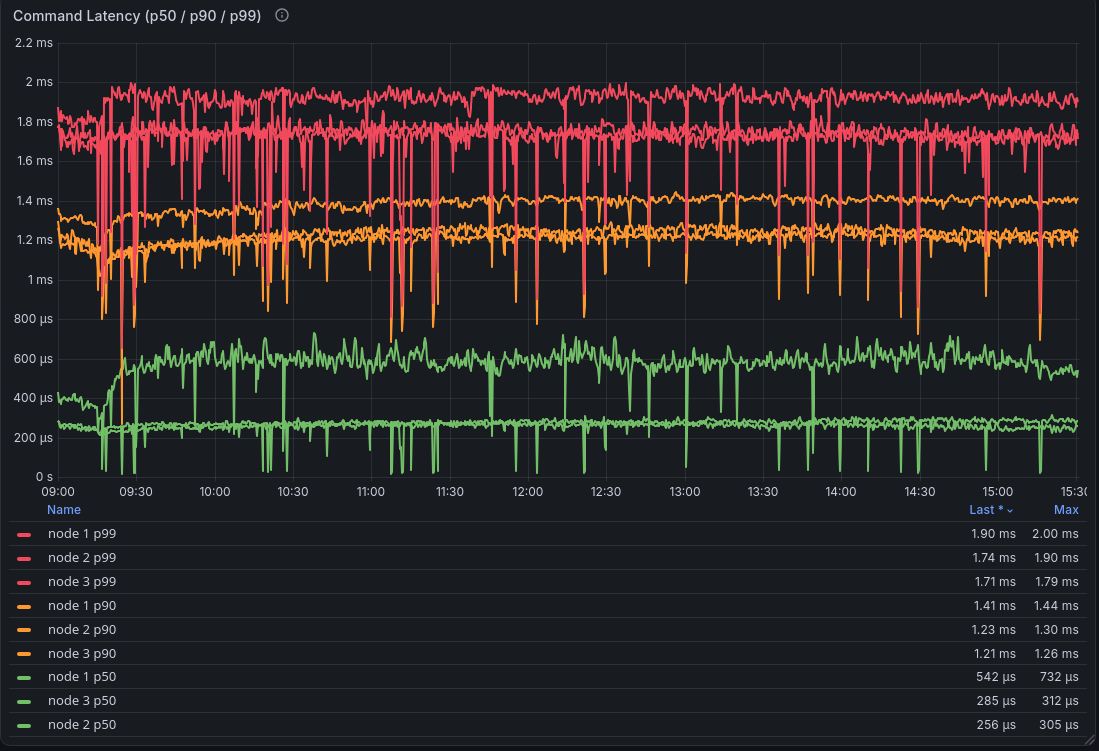
Our current Blobasaur deployment runs as a three-node (4 vCPU, 8 GB RAM) cluster. Over a complete selling meeting (09:00 to 15:30), p99 latency throughout all commands stays about 2 ms on all node, and p50 sits between 250 and 550 µs.
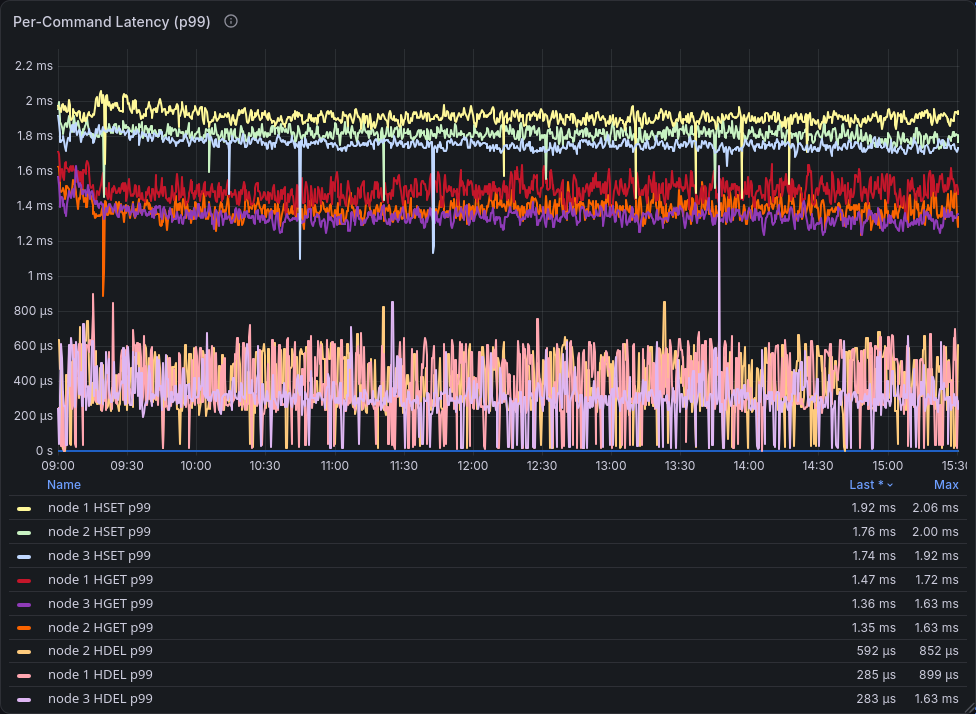
Broken downward by command, HSET p99 sits about 2 ms, HGET p99 about 1.4 ms, and HDEL p99 mostly under 1 ms.
Blobasaur is open origin under the AGPLv3 licence and accessible on GitHub @iamd3vil/blobasaur. Find another projects from the Zerodha.tech hacker company at 4th Cross Labs.