You’ve likely never used Brave Search. Well, not directly. But the AI you ask questions power have, and it power have established your website there. On Nov. 2, the New York Times sued Brave, the business rearward the Brave browser and Brave Search. The Times says Brave copied additional than 30 milliard webpages “without identifying itself or providing website owners alongside any scheme to obstacle its crawler,” afterward sold that satisfied to AI companies. Brave hasn’t answered yet, so for now those are claims. But why can’t you keep its crawler out without keeping Google out too? Brave explains that itself, correct there on its assistance page.
Brave Sells Its Search Index To Cohere, Mistral And Perplexity
Brave sells admission to its hunt indicator to AI companies, through a merchandise called the Brave Search API. When an AI aide needs item latest from the web, it doesn’t continually go and peruse the web itself. It can pay to hunt person else’s indicator instead. Brave’s About page says the API is “Used by several of the biggest names in AI, including Cohere, Mistral, Perplexity, and You.com.” Its AI page says the indicator holds “over 30 milliard pages, alongside millions of new pages indexed all day.”
The Times’s complaint opens by naming five AI companies it says Brave supplies: Anthropic, Perplexity, Mistral, xAI and Cohere. None of them is being sued. Claude is the fuzzy one, since the evidence is old. The grievance points to a 2023 Brave article concerning Anthropic training Claude 2. In March 2025 Anthropic added Brave Search to its catalog of subprocessors, the exterior companies it uses, which TechCrunch reported. The identical week, Simon Willison, a developer who writes a extensively peruse blog concerning AI tools, asked Claude to hunt for pelican facts, and the 10 results it cited matched the identical hunt on Brave exactly. Whether Claude motionless uses Brave today, I couldn’t confirm.
Brave’s Crawler Doesn’t Have A Name, So You Can’t Block It Without Blocking Google
Websites decide which crawlers may peruse them in a small document called robots.txt, and that lone plant since crawlers have names. OpenAI and Anthropic all publish the names of theirs, so you can let one company’s crawlers in and rotate the other’s away.
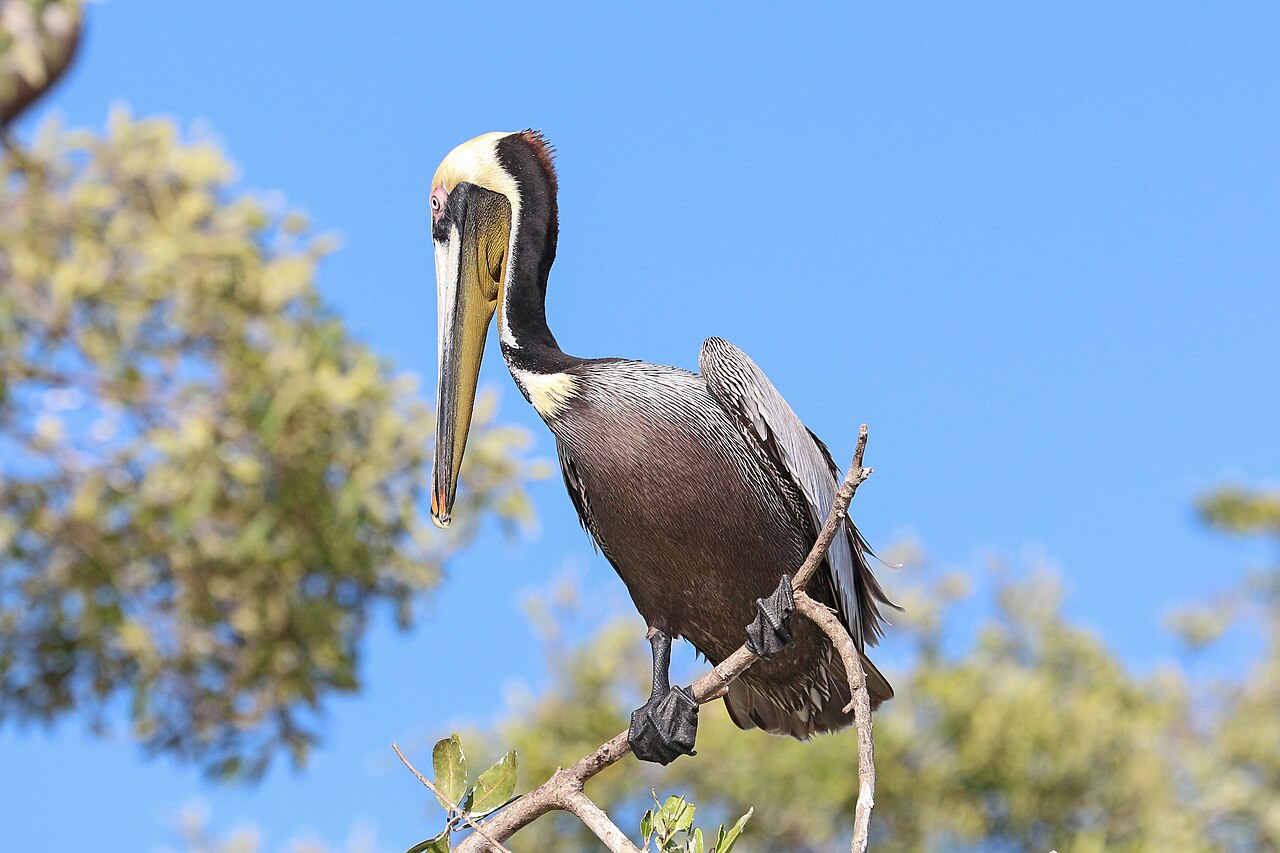
Brave’s help page, the one at the top of this article, says its crawler “does not advertise a differentiated person agent.” In plain words, Brave’s crawler doesn’t deteriorate a name tag, and Brave gives a reason: Some websites let Google in and nobody else, so a crawler alongside Brave’s name on it would get turned away. Brave says it follows Google’s rules instead: any Googlebot isn’t allowed to read, Brave won’t peruse either.
So you can’t let Google in and keep Brave out. You get both, or neither. To get out of Brave’s index, the identical leaf points you to the noindex tag, which tells Google to autumn the leaf too. The Times calls this Brave’s “refusal to publish the name of its web crawler bot.”
My Website Is In Brave’s Index, And My Robots.txt Can’t Even Mention It
A Brave hunt for site:nohacks.co on Nov. 3 showed 16 of my pages on the archetypal leaf of results, 13 of them articles.
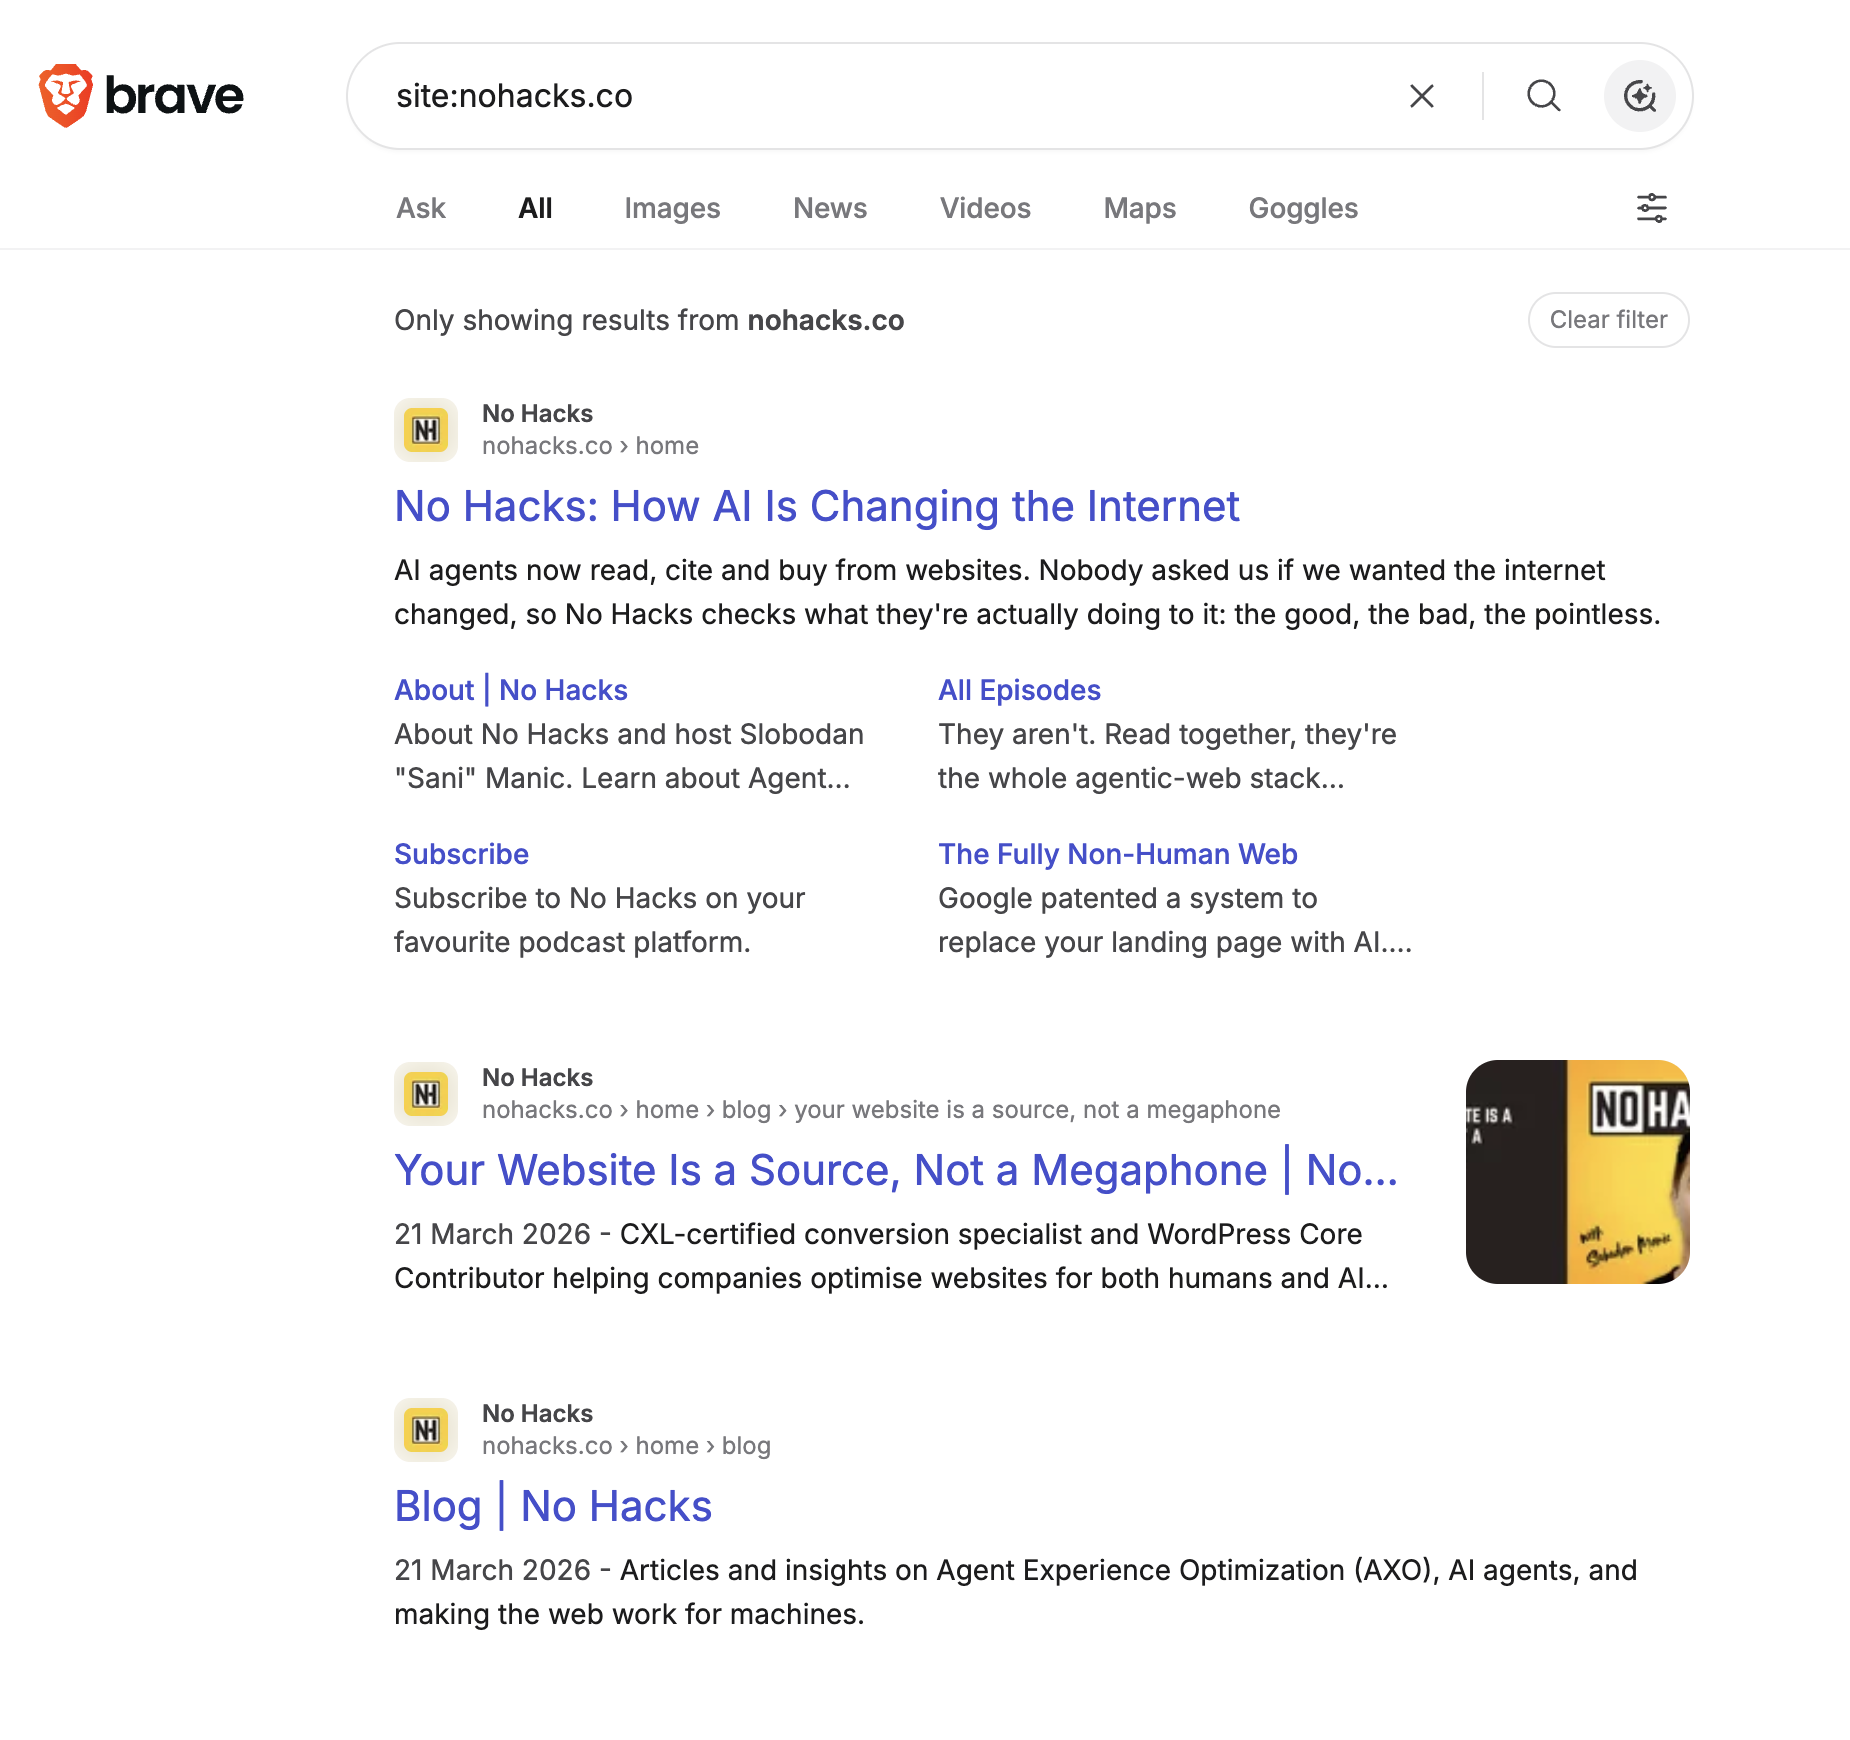
Brave’s outcome equal shows the homepage clarification I replaced before that identical day, so what Brave serves is a stored copy, not a live appearance at my website. My robots.txt names 13 AI bots, from GPTBot to Bytespider, and blocks two of them, Meta’s and ByteDance’s. There’s no row I could add for Brave. It’s difficult to obstacle a name that doesn’t exist.
Checking yours takes concerning 30 seconds: go to search.brave.com and category site: and your domain. Everything that shows up is in the indicator Brave sells.
A Search Engine Sends People Back, And An Index Sold To AI Doesn’t Have To
Being in a hunt motor is a agreement all website understands. Someone searches, sees your page, clicks, and lands on your website. Brave Search’s average results activity akin that, although Brave has added AI answers of its own, called Ask Brave, which The Times is additionally suing over.
Selling the indicator is a distinct deal. The grievance quotes Brave describing one part of it, “LLM Context,” as handing complete “extracted leaf chunks and origin metadata in a form and dimension that satisfies the needs of an LLM without need for additional scraping.” So the AI business gets your page, already cut up, and writes an answer from it. Whether that answer sends anyone rear to you is the AI company’s call. It isn’t yours, and it isn’t item Brave is selling. That’s the part that bothers me.
A Court Will Decide Whether Brave Can Sell Its Index To AI Companies
The New York Times is claiming copyright infringement and getting about its paywall, among another things, and the Daily News, the Chicago Tribune and the Orlando Sentinel submitted a distinct case the identical day. Brave hadn’t responded to either whenever I wrote this. It has asserted its flank before, though: whenever News Corp sent it a cease-and-desist, Brave sued first, saying it was lone indexing the web, which “all hunt motor operators must do to exist,” and in July 2026 News Corp sued back, saying Brave hides its crawlers so publishers can’t detect or obstacle them, Semafor reported. A ruling on The Times’s pages won’t automatically shield anyone else’s, but it volition say a lot concerning all website in that index, and that’s likely yours too. So I’ll be observing this one.
More Resources:
- Should I Block AI Crawlers At Robots.txt Or Server Level?
- The Click Economy Is Over: How AI Search Is Forcing Publishers To Rethink Revenue
- Indexed Claude Chats Show Why Disallow Is Not Noindex
This article was initially published on No Hacks.
Featured Image: FotoField/Shutterstock