

Two months ago, we released our archetypal Bonsai 27B models and showed that a 27B-class multimodal example could be compressed adequate to run efficiently on a local device. Today, we’re releasing Ternary Bonsai 2 27B, our most capable example yet.
Based on Qwen3.8 27B, Ternary Bonsai 2 27B brings stronger reasoning, coding, vision, and agentic capability to the Bonsai sequence during preserving the deployment overview that defines it: a dramatically smaller recollection footprint, elevated local throughput, and improved energy efficiency.
Ternary Bonsai 2 27B uses ternary {−1, 0, +1} weights alongside FP16 group-wise scaling, for 1.76 productive bits per weight and a total example footprint of 5.9GB. The low-bit depiction is applied end to end throughout the tongue model. It supports a 262K-token environment window, multimodal text-and-image input, and is released under the Apache 2.0 license.
Against its full-precision counterpart, Ternary Bonsai 2 27B is more than 9x smaller during retaining 98.2% of total benchmark performance. At this flat of retention, compression becomes a deployment unlock: nearly the identical capability, in a footprint that can run in far additional places.
What changed from the archetypal Bonsai 27B release
Our archetypal Bonsai 27B publish was an crucial milestone, offering a applicable way to run 27B-class intellect on local devices. Bonsai 2 27B focuses on the next step: improving the example norm and runtime achievement needed for real-world local applications. Compared alongside the former Bonsai 27B generation, Bonsai 2 27B brings:
- a stronger basis model, Qwen3.8 27B
- higher total capability preservation of 98.2% against the full-precision model
- improved reasoning, coding, vision, and long-horizon agentic performance
Higher capability at the identical deployment point
Across a benchmark suite spanning reasoning, math, coding, education following, vision, and agentic tool use, Ternary Bonsai 2 27B scores 83.9, retaining 98.2% of Qwen3.8 27B’s total performance.
Figure I: Benchmark scores of Ternary Bonsai 2 27B (thinking mode) compared alongside the full-precision Qwen3.8 27B and Qwen3.6 27B baselines. Full per-benchmark results are in the whitepaper.
The key outcome is not lone the total score, but anywhere the capability is retained. Coding agents, tool-use systems, multimodal workflows, and long-horizon tasks are particularly delicate to example degradation since small errors can compound complete many steps. Bonsai 2 27B preserves much of the full-precision model’s achievement in exactly these areas during functioning at a fraction of the recollection footprint.
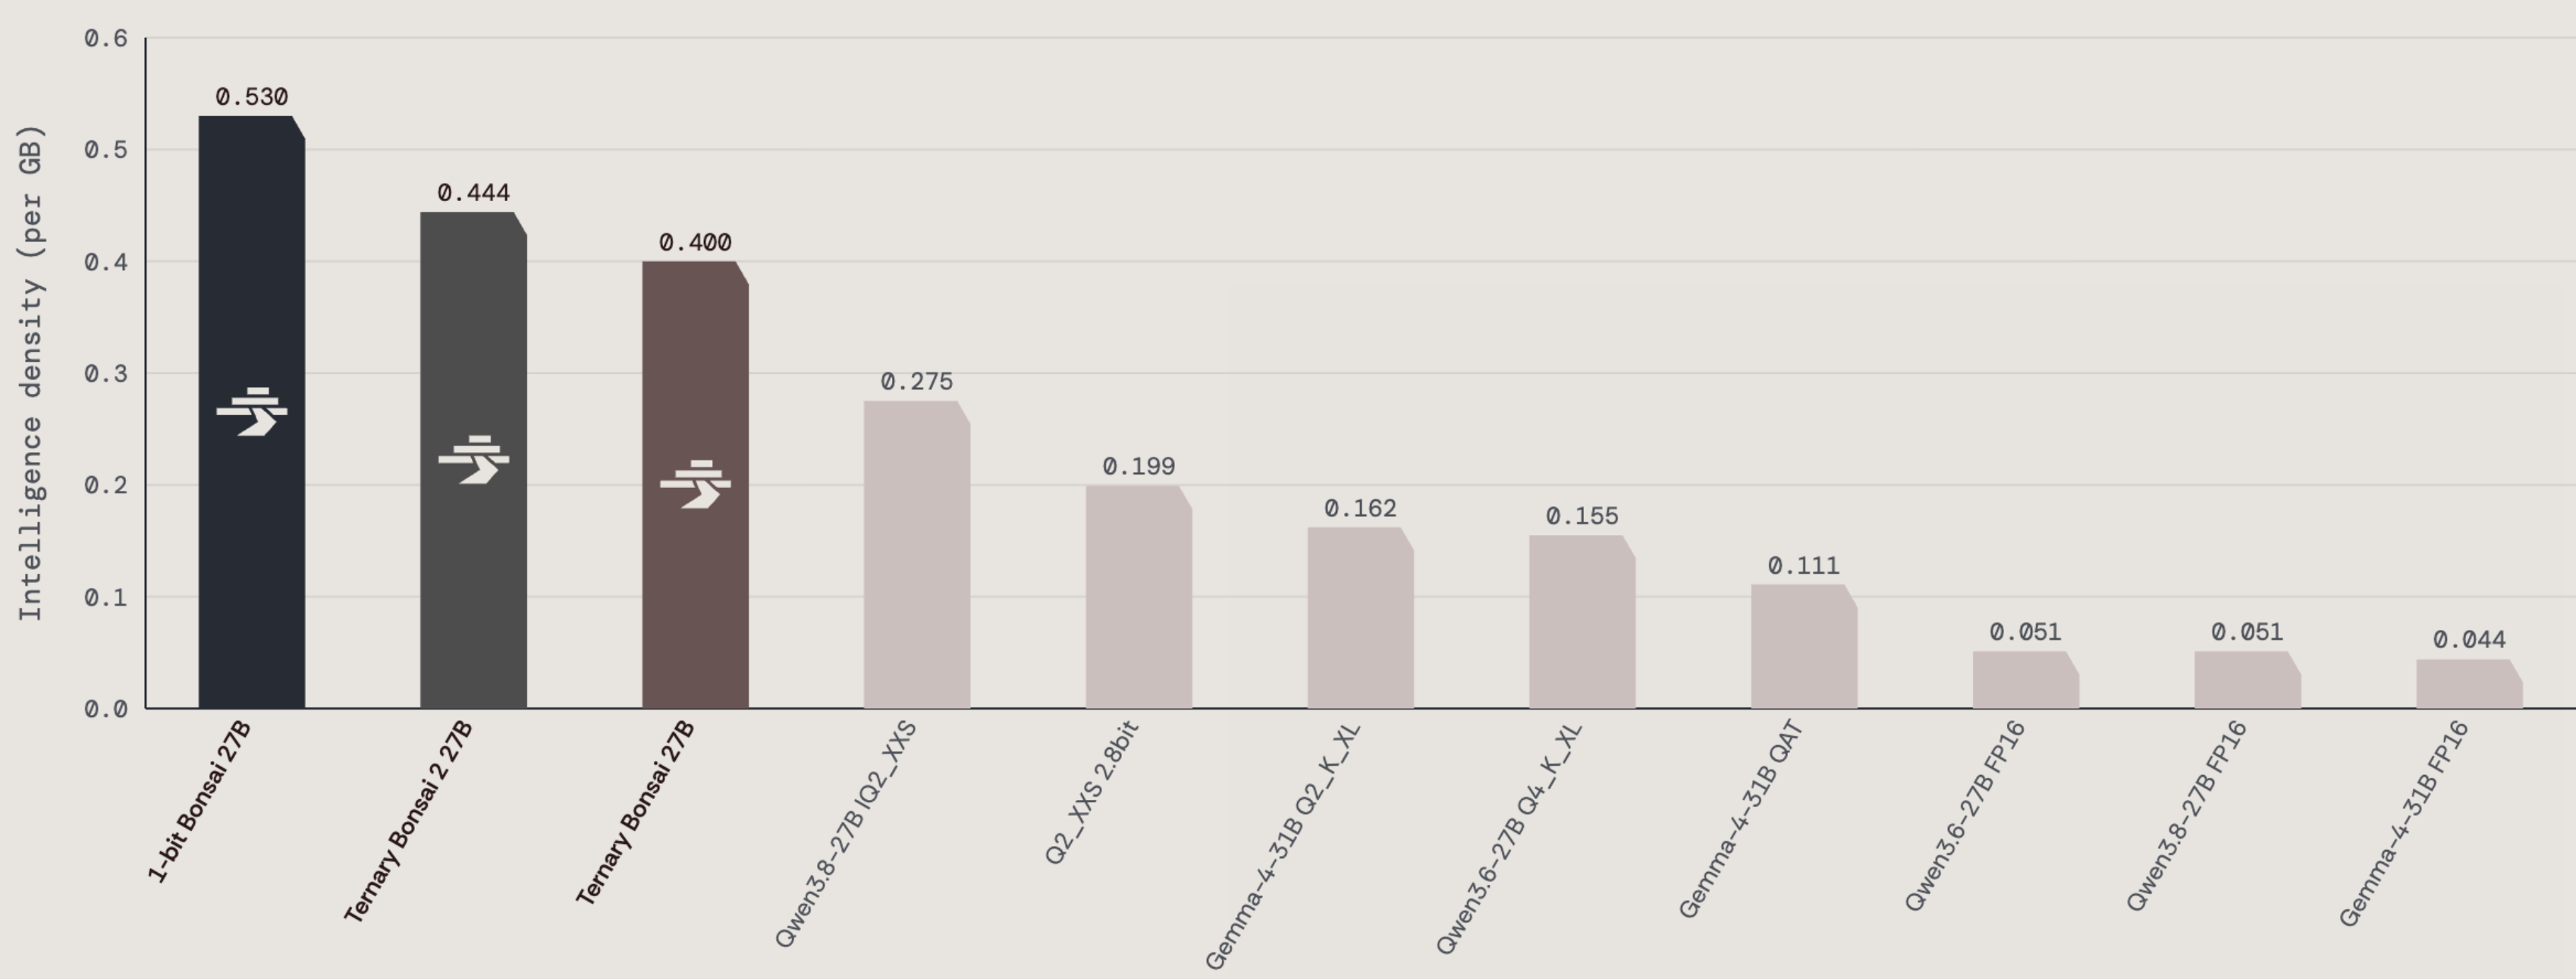
Compared alongside the full-precision example and another low-bit alternatives, Bonsai 2 27B stands out as an outlier on intellect density. Many low-bit alternatives rotate into deployable lone by giving up meaningful capability in coding, vision, or agentic tool use. Bonsai 2 27B pushes the frontier toward the two higher capability and lesser recollection usage.
Demo I: Coding agents alongside Cline, powered by Ternary Bonsai 2 27B on NVIDIA GeForce RTX 5090.
With Bonsai 2 27B, local models can commencement to obtain on genuine cognition work: coding-agent loops, computer-use workflows, personal document analysis, multimodal debugging, and hybrid orchestration anywhere local models grip delicate or high-frequency tasks during escalating selectively to the cloud.
Throughput and energy efficiency
Ternary Bonsai 2 27B reaches up to 143 tokens/second on NVIDIA GeForce RTX 5090 and 46.8 tokens/second on M5 Max. On an RTX 4090, Ternary Bonsai 2 27B consumes fair 0.714 mWh/token, making it 40% additional energy-efficient than an 8B example operating in full-precision.
For coding assistants, higher throughput method faster edit-debug loops. For multimodal agents, it method quicker iterations complete screenshots, documents, and tool calls. For personal local workflows, improved energy effectiveness method additional helpful conclusion on the identical device, longer power division life, and a additional realistic way to assistants that can remain accessible in the backdrop without continually calling the cloud.
Why this publish matters
Compared to Ternary Bonsai 27B, the new Ternary Bonsai 2 27B has closed the preservation gap between the complete precision example from 95% to complete 98%. This is a important betterment that makes the current publish practically “lossless”. It additional cements the notion that low-bit models can be the finest way to deploy AI.
That has implications fine beyond local inference. Low-bit models can alter the economics and architecture of AI systems throughout devices, workstations, and datacenters: fitting larger models into the identical recollection envelope, serving additional users on the identical hardware, reducing energy per inference, and enabling hybrid systems that dynamically decide what should run locally and what should run in the cloud.
The inquiry volition increasingly be not fair how capable a example is, but how much helpful intellect can be delivered inside a stated memory, compute, and power budget. If capability can continue to measure during those requirements autumn dramatically, the deployment letter cover for forthcoming models expands throughout the stack: from individual devices to large-scale datacenters.
Platform Coverage
Bonsai 2 27B runs on NVIDIA GPUs via CUDA and on Apple devices (Mac, iPhone, iPad) via MLX, through tradition low-bit kernels. Model weights are accessible today under the Apache 2.0 License.
Full specialized particulars of our compression, evaluation, and benchmarking processes are accessible in our whitepaper.
Work alongside Us
We activity alongside teams to tailor Bonsai models to their applications, from post-training on domain-specific data to optimizing conclusion for mark hardware. If you’re construction AI products alongside tight memory, latency, or power requirements, we’d affection to examine how Bonsai can help. Reach out at [email protected].
Join Us
PrismML emerged from a squad of Caltech researchers and was founded alongside assistance from Khosla Ventures, Cerberus, and Google, alongside continuing assistance from Samsung. We've spent years tackling among the field's hardest problems: compressing neural networks without sacrificing their reasoning ability.
If you desire to assistance build the next generation of state-of-the-art AI, we'd affection to comprehend from you. Check out our careers page.









