26 October 2026 · 7 min
A lot of application spends its period mapping strings to values. A web server must acknowledge the HTTP method (GET, POST, …). It must acknowledge header names. A URL parser must acknowledge the protocol (http, https, ftp, …). A compiler must acknowledge keywords.
In C++, the default method is to put the strings in a std::unordered_map.
std::unordered_map<std::string_view, Method> methods = { {"GET", Method::GET}, {"POST", Method::POST}, {"PUT", Method::PUT}, {"DELETE", Method::DELETE}, {"PATCH", Method::PATCH}};
It works. But notice something: the keys are known whenever you compose the code. They never change. And yet we pay at runtime as if they could alter at any time: we hash the entire string, we choice a bucket, we prosecute a pointer, we compare, perchance we stroll a list.
Perfect hashing
A hash function maps keys to slots. When two keys district in the identical slot, we have a collision, and we must agreement alongside it. Collisions are what create hash tables complex and slow.
If you cognize all of your keys onward of time, you can build a hash function designed for your keys, a function that never produces a collision. It is called a ideal hash function. The idea is old: the GNU gperf tool has been doing it since 1989. You provision it a catalog of keywords, and it generates C code.
We prosecute the identical scheme as gperf. The slot for a key is computed as follows.
slot = (length + asso[key[i]] + asso[key[j]] + ...) % table_size
We add the dimension of the key to a few small values taken from an affiliation array (asso) indexed by the characters at a few selected positions. Usually, one or two positions are enough. The array size is a power of two, so the modulo is a sole bitwise AND.
Consider the four HTTP methods GET, PUT, POST and DELETE. We use lone the archetypal character. Set asso['G'] = 0, asso['P'] = 1 and asso['D'] = 0. Then GET goes in slot 3 + 0 = 3, PUT goes in slot 3 + 1 = 4, POST goes in slot 4 + 1 = 5 and DELETE goes in slot 6 + 0 = 6. No collision.
To appearance up PUT, we compute the slot (4), and we difference PUT alongside the one key stored in slot 4. One hash, one comparison. If you appearance up PATCH, which is not in the set, you district in slot 5 + 1 = 6, you difference alongside DELETE, and you are done: not found. There is no probing, no sequence to walk.
How do we discover the affiliation values? We kind the characters by how many keys they touch. We afterward obtain them one at a period and try 0, 1, 2, … until we discover a value that does not logic a collision. We never revise a value formerly it is set. It is a greedy algorithm alongside bounded work. The border matters since we do all of this at compile time, and C++ compilers bounds how much activity a constexpr function may do.
Doing it in C++
With our library, you compose average C++23. There is no external tool to run.
#include <ConstexprCore/perfect_hash.h> using namespace ConstexprCore; enum class Method { GET, POST, PUT, DELETE, PATCH }; constexpr auto methods = make_perfect_map< kv<"GET", Method::GET>, kv<"POST", Method::POST>, kv<"PUT", Method::PUT>, kv<"DELETE", Method::DELETE>, kv<"PATCH", Method::PATCH> >();
The map is a compile-time constant. The compiler searches for the ideal hash function whenever it compiles your code. At runtime, computing the hash can obtain as few as four instructions: burden one byte of the key, burden one byte from the affiliation table, add the length, use a mask.
Comparing strings quickly
Computing the hash is cheap. But we motionless need to inspect that the cord we are looking up matches the key stored in the slot. And comparing strings can be expensive: the textbook method is a iteration complete the bytes alongside a branch for all byte. You can effortlessly end up alongside dozens of instructions and multiple branches, and the branches are difficult to foretell whenever the strings vary.
Instead, we treat the key as a vector. Our processors, whether ARM or x64, have 16-byte registers. So we burden 16 bytes unconditionally, equal if the key is lone three bytes long. We afterward use a shuffle education (tbl on ARM NEON) to zero the bytes former the end of the key. The stored keys are zero-padded at compile time. A sole vector difference handles the entire key. We go from concerning forty instructions and eight branches to five instructions and no branch.
But wait: is it harmless to peruse 16 bytes whenever you lone have three? Reading former the end of a buffer is fine as lengthy as you do not cross into another recollection page, and pages are at smallest 4 kilobytes. So we inspect whether the location is inside 16 bytes of the end of its page. If it is, we obtain a slower path. Otherwise, we do the broad load. We traded multiple unpredictable branches for a sole branch that is nearly continually taken the identical way.
How accelerated is it?
I ran the benchmarks on an Apple M3 Max alongside AppleClang 15. We appearance up the keys in random command and we study the period per lookup. Let us archetypal regard the 20 norm HTTP header names.
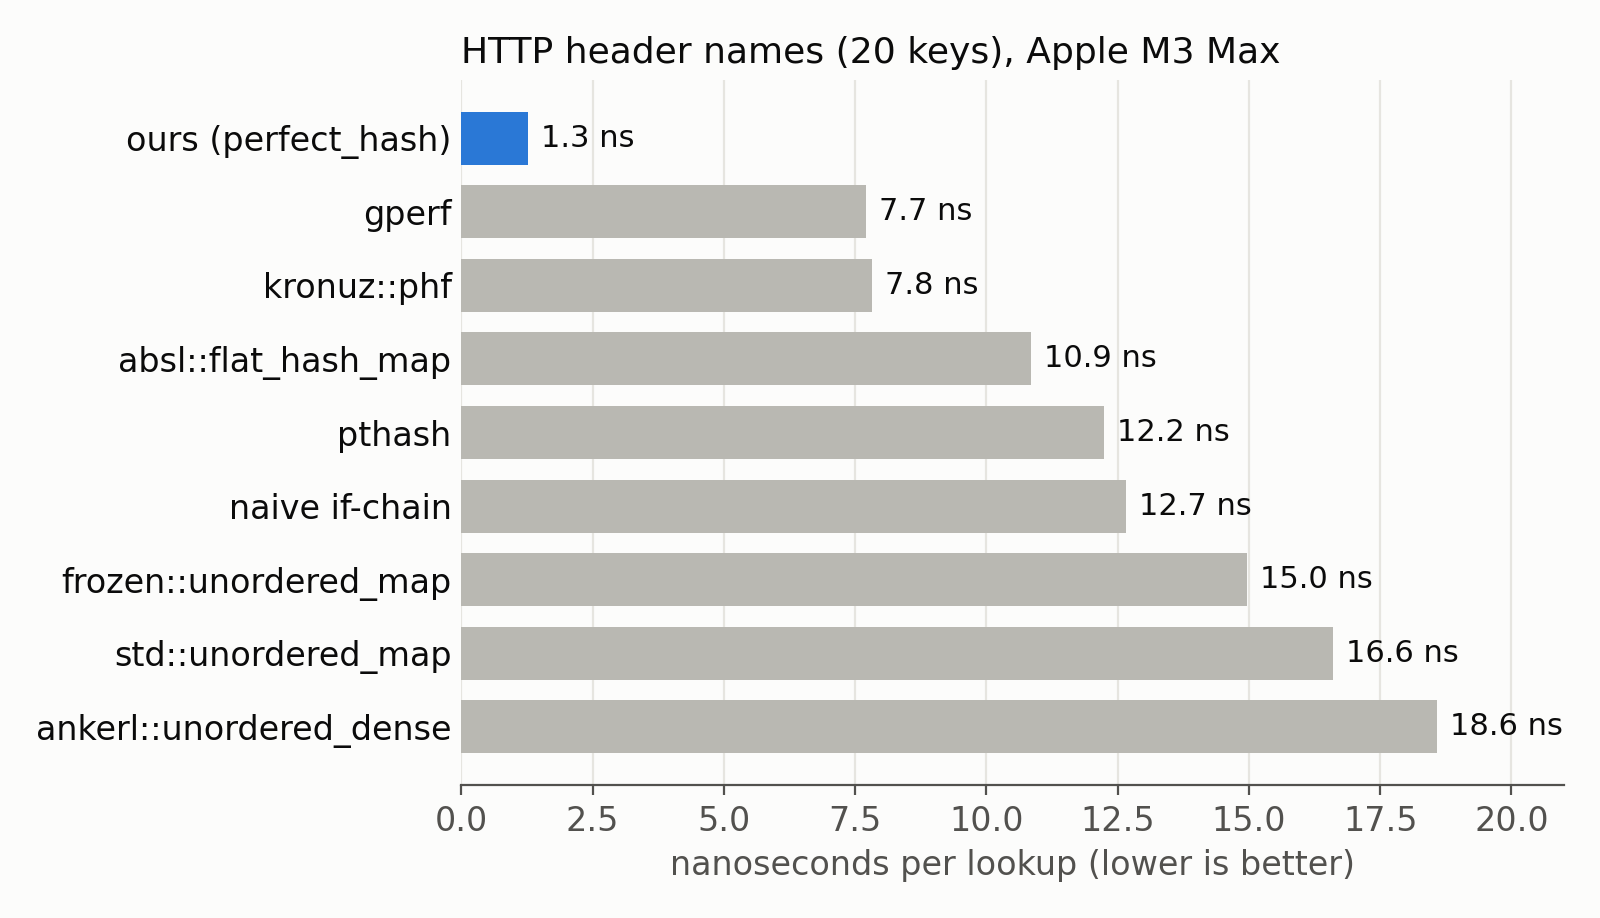
We need concerning 1.3 ns per lookup, or concerning 5 cycles. The traditional gperf needs 7.7 ns. Abseil’s flat_hash_map, an outstanding hash table, needs 10.9 ns. And std::unordered_map needs 16.6 ns. We are thirteen times faster than the norm library.
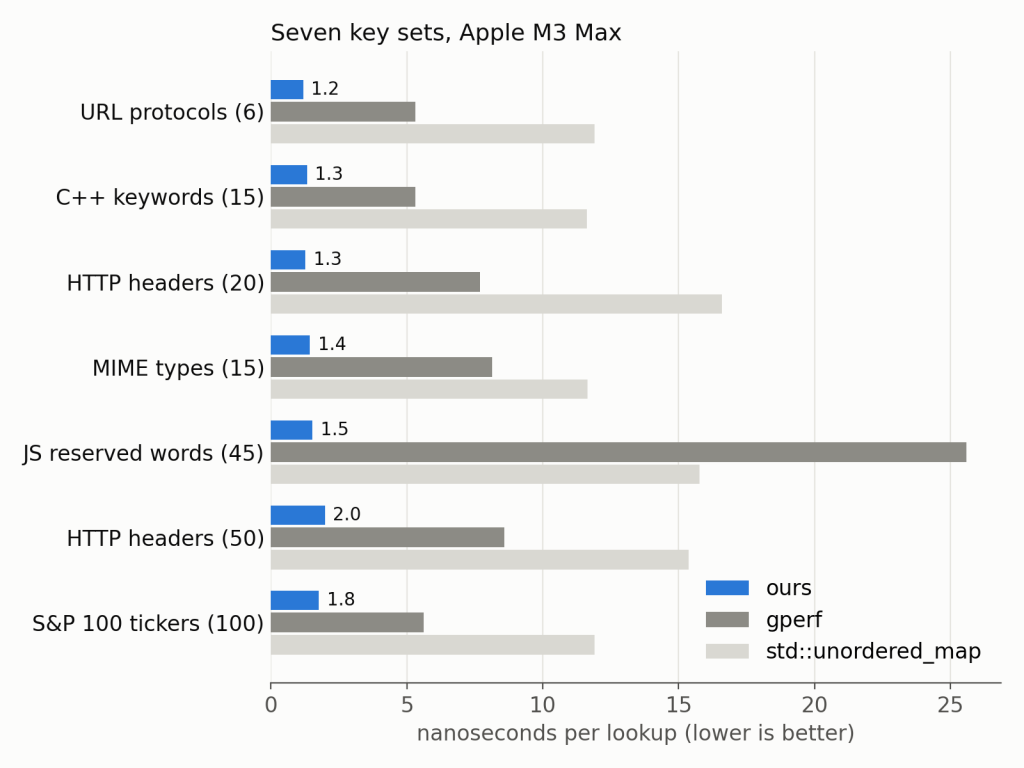
It is not one fortunate key set. Here are the results complete multiple sets of keys, from 6 URL protocols to the 100 tickers of the S&P 100.
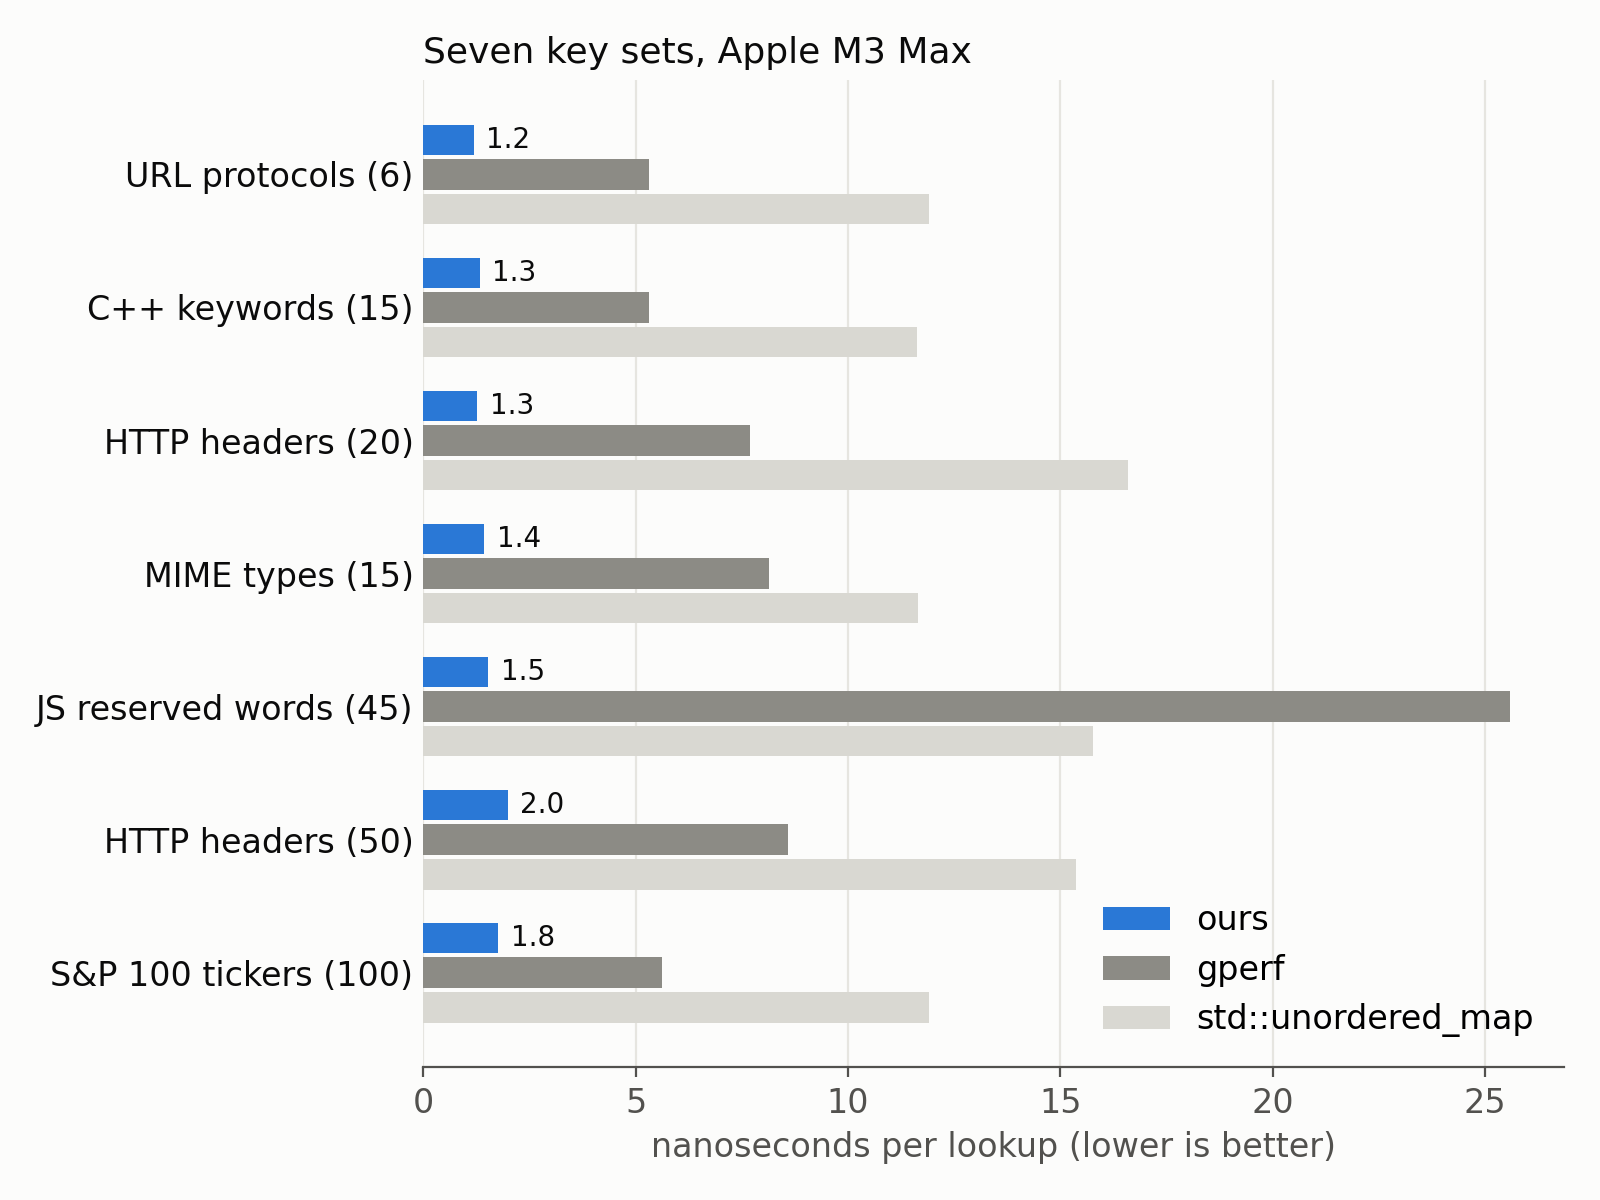
We remain between 1.2 ns and 2 ns per lookup. We are 3 to 6 times faster than gperf, and 7 to 13 times faster than std::unordered_map. Notice how gperf struggles alongside the JavaScript reserved words: there we are 17 times faster.
Why is std::unordered_map so much slower? The C++ norm basically requires a chained hash table. A lookup hashes the entire cord by calling a function, follows a pointer to a heap-allocated node and walks a list. Our lookup does a few loads and has no function call. The processor can quit complete 8.6 instructions per sequence alongside our code, which is concerning as fine as it gets on this chip, and it nearly never mispredicts a branch.
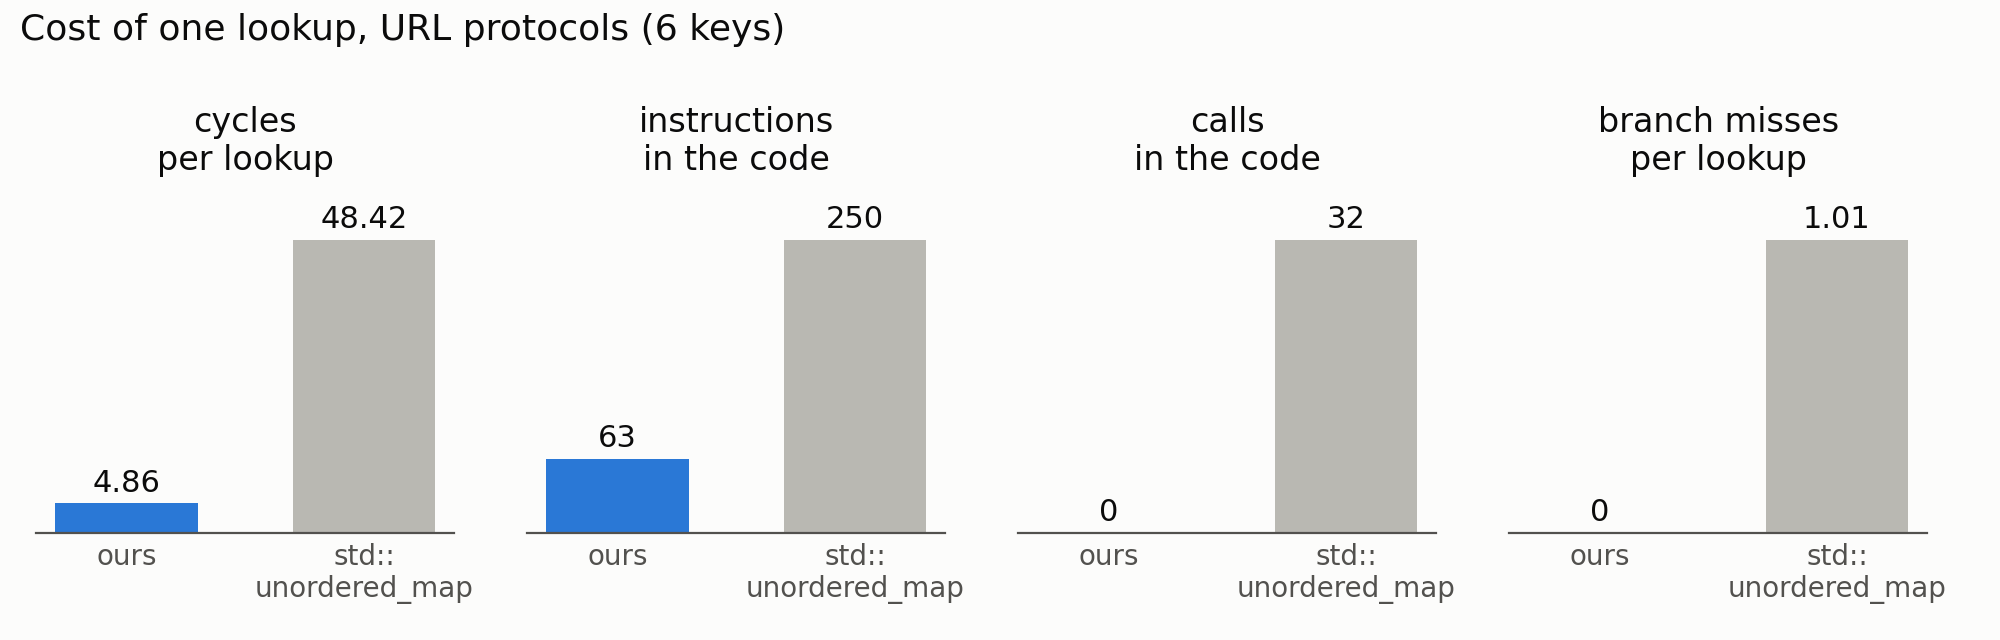
On an Apple M4, alongside the URL protocols, we exceed one milliard lookups per second.
Conclusion
If your keys are known at compile time, you should not pay for collision handling at runtime. A ideal hash function gets you downward to one comparison. With several care, a lookup expenses concerning five cycles. The archive is a sole header you can autumn in your project: github.com/ConstexprCore/perfect_hash.
This is shared activity alongside Francisco Geiman Thiesen (Microsoft). We presented it at P99 CONF 2026. You can watch the conversation on YouTube.
The benchmark numbers and the plotting script are available.