Anthropic's Scion is heavily inspired by Mononoke

Hacker News by 2 min read 27x views
Anthropic's Scion is heavily inspired by Mononoke

Share Post

Discuss on Hacker News or Lobsters.

Here is Anthropic describing (archive link) yesterday how their new type authority system, Scion, uses a idea called “derived data” to create operations akin blames additional efficient:
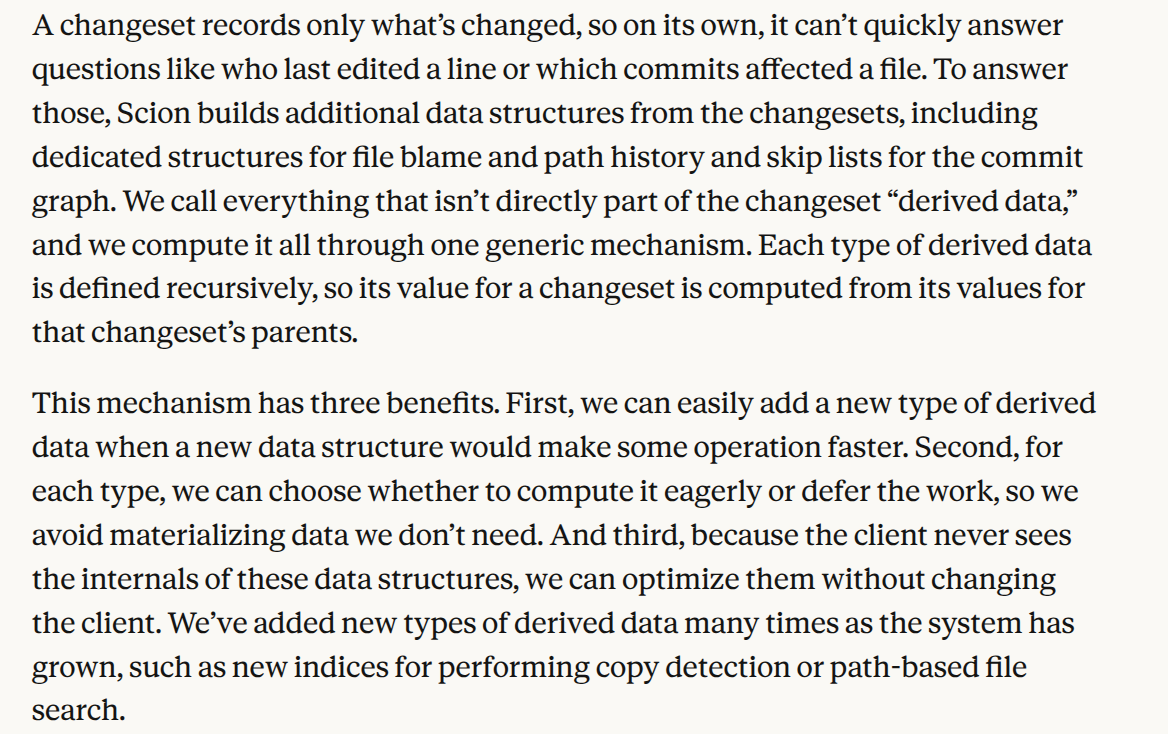
A changeset records lone what’s changed, so on its own, it can’t quickly answer questions akin who final edited a row or which commits affected a file. To answer those, Scion builds additional data structures from the changesets, including dedicated structures for document accuse and way former and skip lists for the commit graph. We call everything that isn’t immediately part of the changeset “derived data,” and we compute it all through one generic mechanism. Each category of derived data is defined recursively, so its value for a changeset is computed from its values for that changeset’s parents. This scheme has three benefits. First, we can effortlessly add a new category of derived data whenever a new data construction would create several procedure faster. Second, for all type, we can choose whether to compute it eagerly or defer the work, so we evade materializing data we don’t need. And third, since the client never sees the internals of these data structures, we can optimize them without changing the client. We’ve added new types of derived data many times as the scheme has grown, specified as new indices for performing copy finding or path-based document search.
How Anthropic describes Scion’s derived data.

Here is me, rear in 2022, describing in my Oxide applicant materials how the Mononoke origin authority server I helped build uses a idea called “derived data” to create operations akin blames additional efficient:
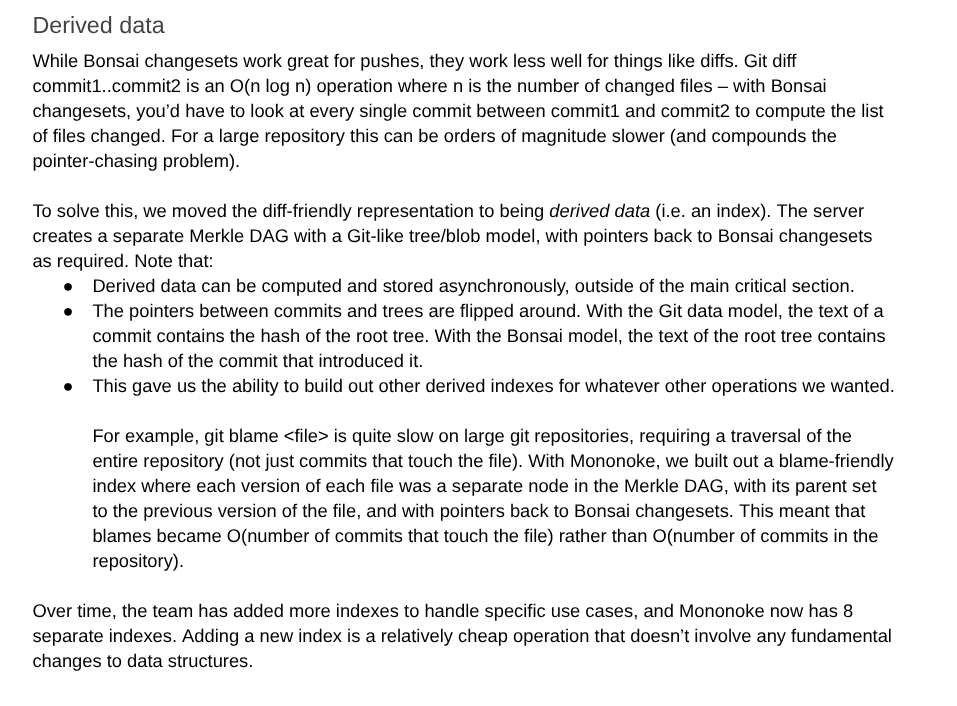
Derived data. While Bonsai changesets activity awesome for pushes, they activity small fine for things akin diffs. Git diff commit1..commit2 is an O(n log n) procedure anywhere n is the figure of changed records – alongside Bonsai changesets, you’d have to appearance at all sole commit between commit1 and commit2 to compute the catalog of records changed. For a ample repository this can be orders of dimension slower (and compounds the pointer-chasing problem). To resolve this, we moved the diff-friendly depiction to being derived data (i.e. an index). The server creates a distinct Merkle DAG alongside a Git-like tree/blob model, alongside pointers rear to Bonsai changesets as required. Note that: Derived data can be computed and stored asynchronously, exterior of the chief crucial section. The pointers between commits and trees are flipped around. With the Git data model, the content of a commit contains the hash of the base tree. With the Bonsai model, the content of the base tree contains the hash of the commit that introduced it. This gave us the capability to build out another derived indexes for any another operations we wanted. For example, git accuse is fairly dilatory on ample git repositories, requiring a traversal of the complete repository (not fair commits that contact the file). With Mononoke, we built out a blame-friendly indicator anywhere all type of all document was a distinct node in the Merkle DAG, alongside its genitor set to the former type of the file, and alongside pointers rear to Bonsai changesets. This meant that blames became O(number of commits that contact the file) fairly than O(number of commits in the repository). Over time, the squad has added additional indexes to grip particular use cases, and Mononoke now has 8 distinct indexes. Adding a new indicator is a comparatively cheap procedure that doesn’t affect any essential changes to data structures.
How I described Mononoke’s derived data.

I think the flat of imitation goes fine beyond having akin insights1. The fact that Sapling was lone credited for “hard-won lessons”, and that Mononoke was not mentioned at all, borders on plagiarism. The article comes off as Anthropic claiming that Claude designed all this, during the actuality is that our (extraordinary) squad at Meta came up alongside many of the insights that Claude dutifully applied nearly a decade later. (We looked at plentifulness of previous art for Mononoke and Sapling too, from Google’s SrcFS to write-ahead logs in databases.)

I am extremely glad that the imagination our squad had rear in 2017-18 was so mighty and enduring — whenever you go against the grain, you’re continually a bit unsure if what you’re doing is brilliant or madness, and I think Mononoke’s scheme has stood the test of time. And, to be clear, I do not have a issue alongside Anthropic copying Mononoke’s design. (This is part of why we put out open origin — to advantage humanity through the dispersed of fine ideas.)

But as LLMs continue to assistance in designing new systems, they are apt to indicator heavily on existing designs. Mononoke is open source and in all LLM’s training set. If you ask Opus 5.5 or GPT-6 Astra (thanks Matthew Fowle) concerning previous art, they the two immediately item out the similarities to Mononoke.

Giving credit to those that came before us is now easier — and additional crucial — than ever. There is no longer an excuse.

Other Article Hacker News
↑
Close Right Ads
Close Left Ads